Genie
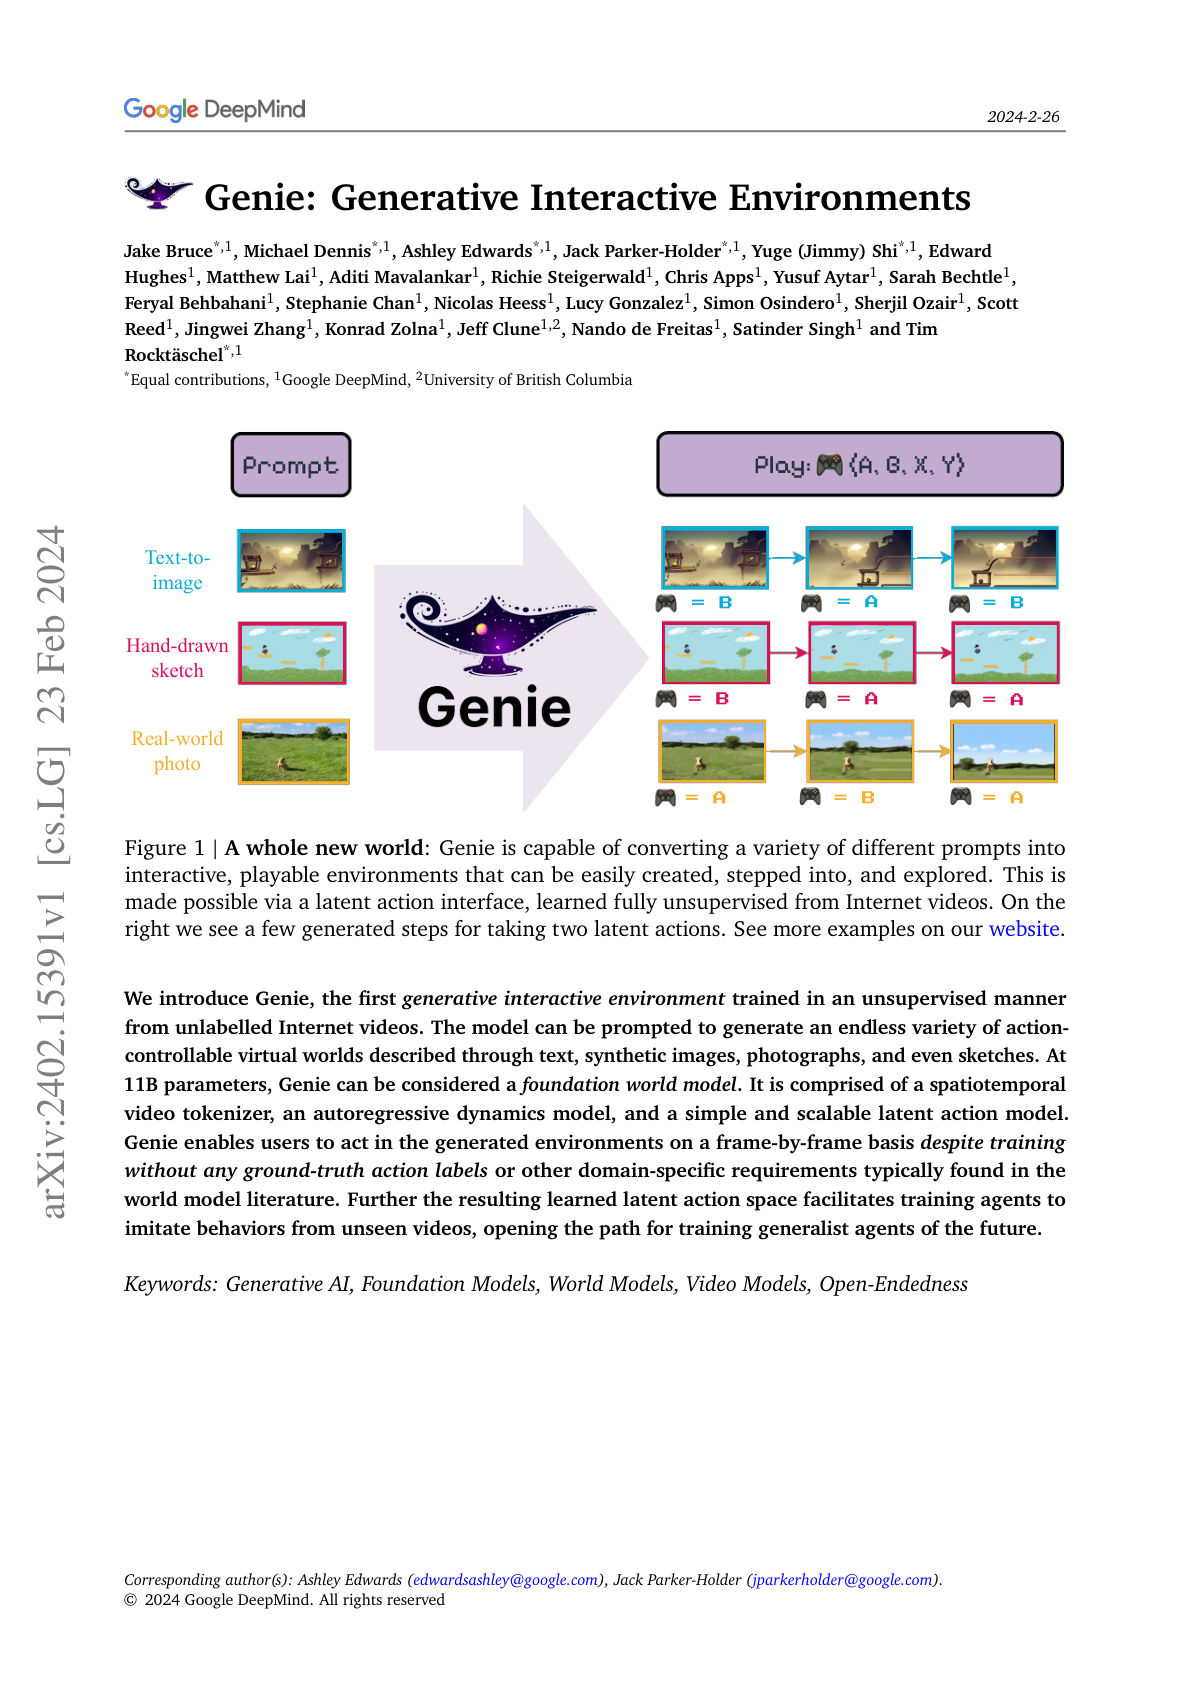
DeepMind's Genie is an 11B-parameter foundation world model trained unsupervised on internet gameplay videos that generates action-controllable 2D worlds from a single image prompt.
Ask this paper
Three-component architecture: A spatiotemporal video tokenizer, an autoregressive dynamics model, and a scalable latent action model together learn to roll out playable worlds without any explicit action labels in training.
Prompt-conditioned worlds: Given a single image (photo, sketch, or video frame), Genie produces an interactive 2D environment the user can "play" frame-by-frame with inferred action controls.
Latent action space: The learned action embedding lets an agent imitate behaviors demonstrated in unseen videos, turning internet video into a generic source of demonstrations for training embodied policies.
Generalist-agent implication: Suggests a path toward training generalist agents entirely from observational video, without needing action-labeled datasets or curated simulators.