Instruct-Imagen
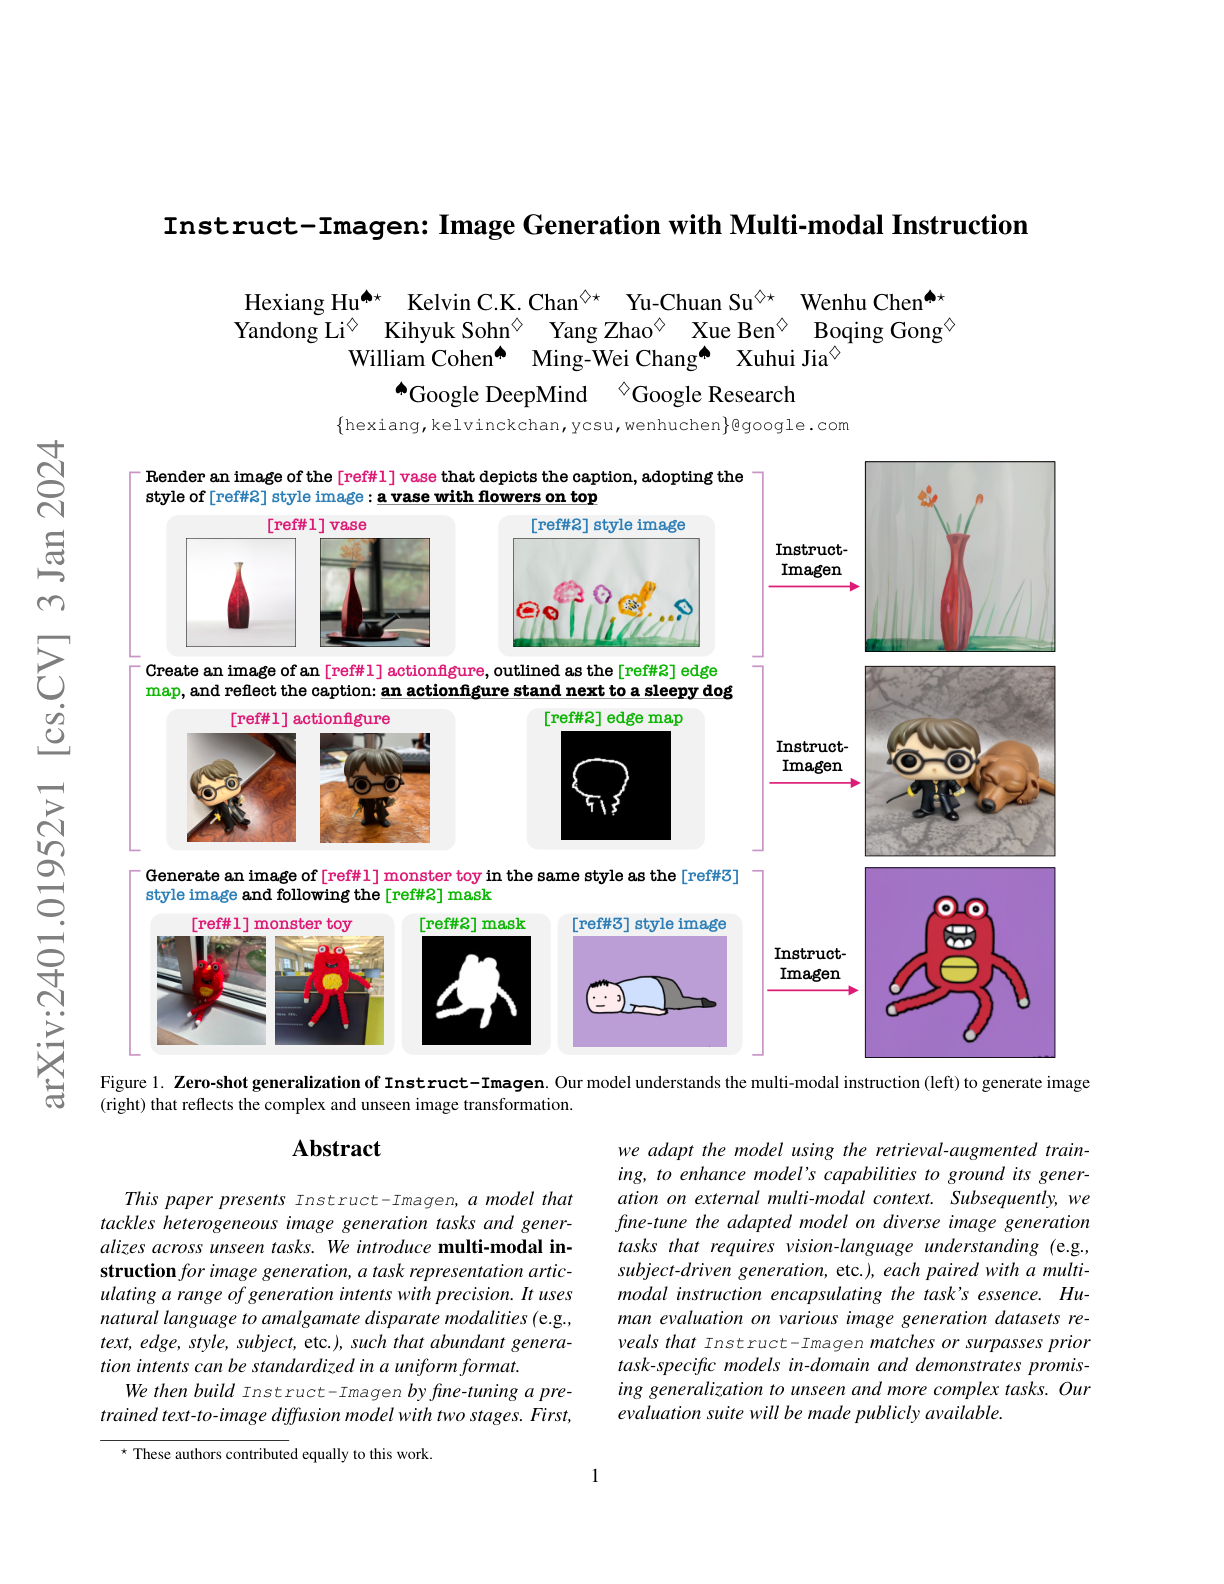
Google's Instruct-Imagen is a multimodal instruction-tuned image generation model that generalizes across heterogeneous generation tasks, including unseen ones.
Ask this paper
Multimodal instructions: Instructions can mix text with reference images (for style, subject, or control), letting users specify complex generation intent without task-specific prompting templates.
Two-stage training: First enhances the base model's ability to ground generation on external multimodal context, then fine-tunes on a diverse set of image-generation tasks formulated as multimodal instructions.
Unseen-task generalization: Generalizes to novel task combinations (e.g., "style of A, subject of B, pose of C") that weren't in the training distribution.
Unified interface: Replaces per-task pipelines (ControlNet, DreamBooth, InstructPix2Pix) with a single model driven by natural-language multimodal instructions.