KOSMOS-G
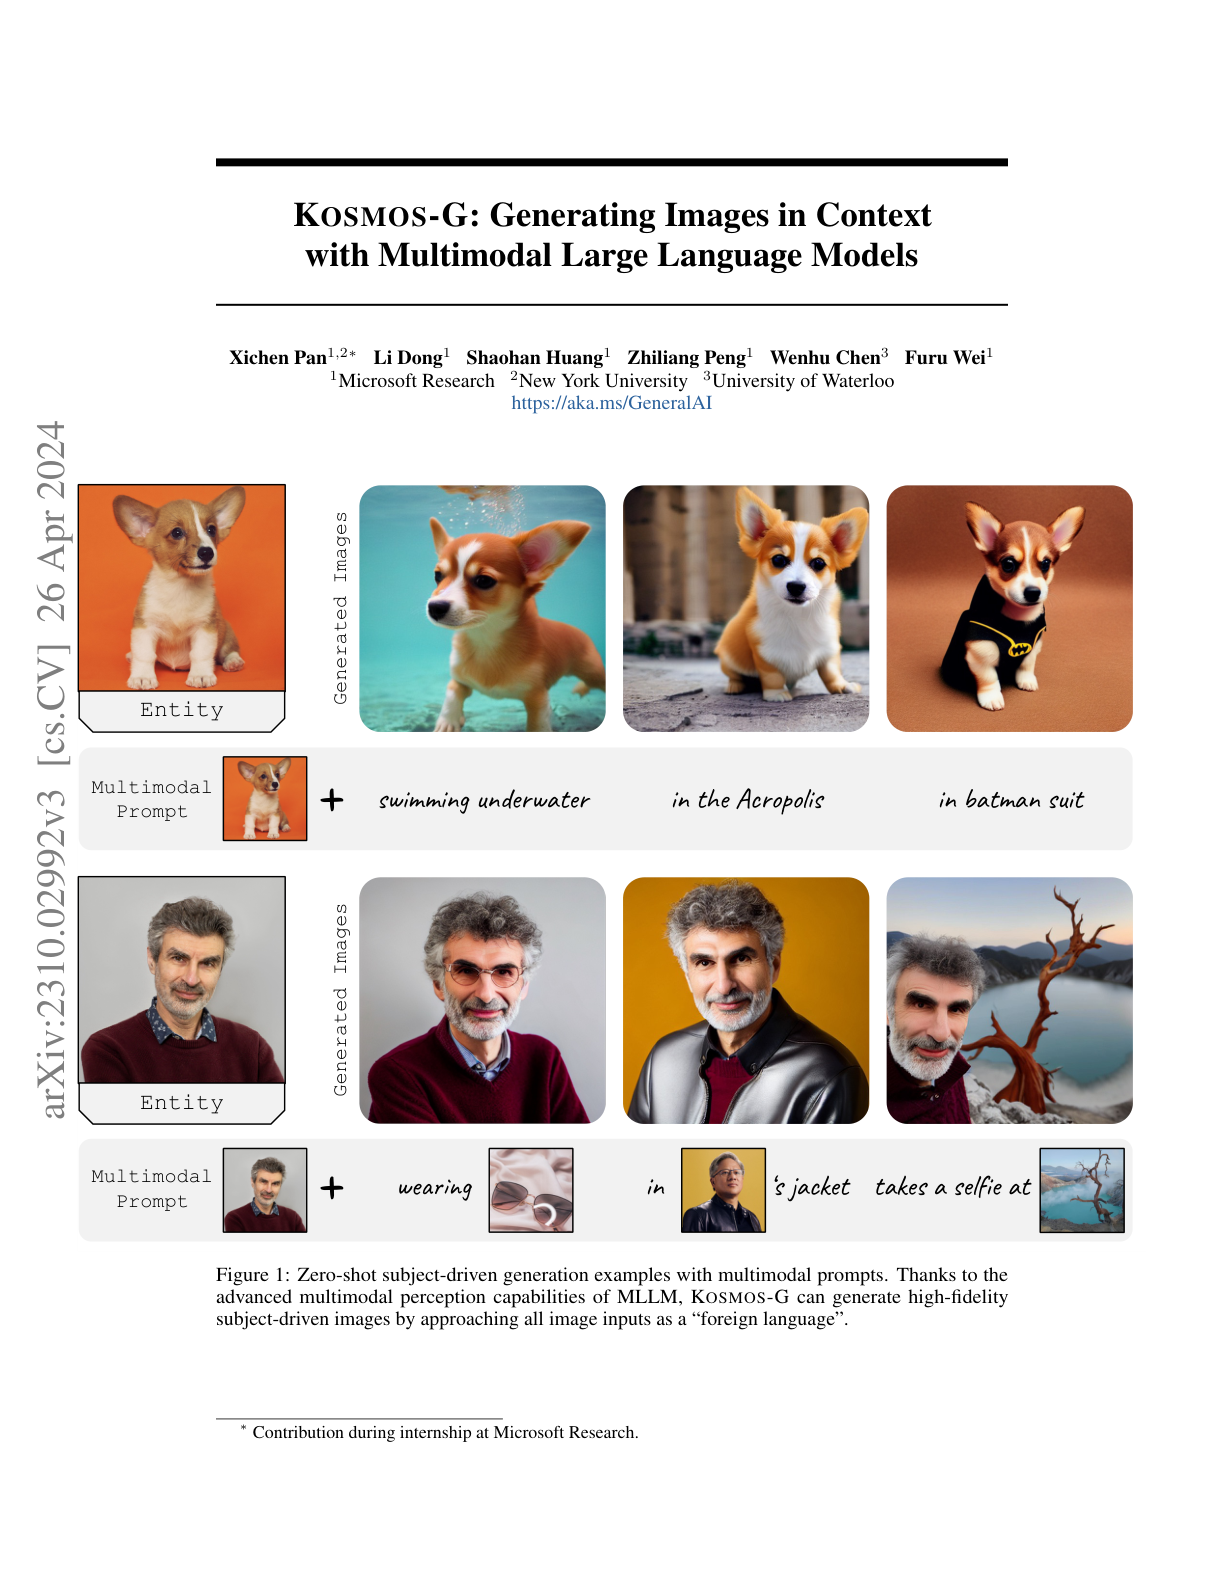
Microsoft's KOSMOS-G extends zero-shot image generation to multi-image vision-language input.
Ask this paper
Generalized VL input: Generates images from a vision-language prompt that can include multiple reference images, unlike typical single-reference setups.
Multi-entity scenarios: Extends zero-shot subject-driven image generation to scenarios with multiple subjects - e.g., generating a scene where A is doing X to B, preserving each identity.
CLIP-replaceable: Allows replacing CLIP in downstream image-generation pipelines, unlocking new applications with U-Net techniques like ControlNet and LoRA.
Unified generation interface: Positions itself as a unified vision-language input interface for controllable image generation, rather than a new diffusion backbone.