Leave No Context Behind (Infini-attention)
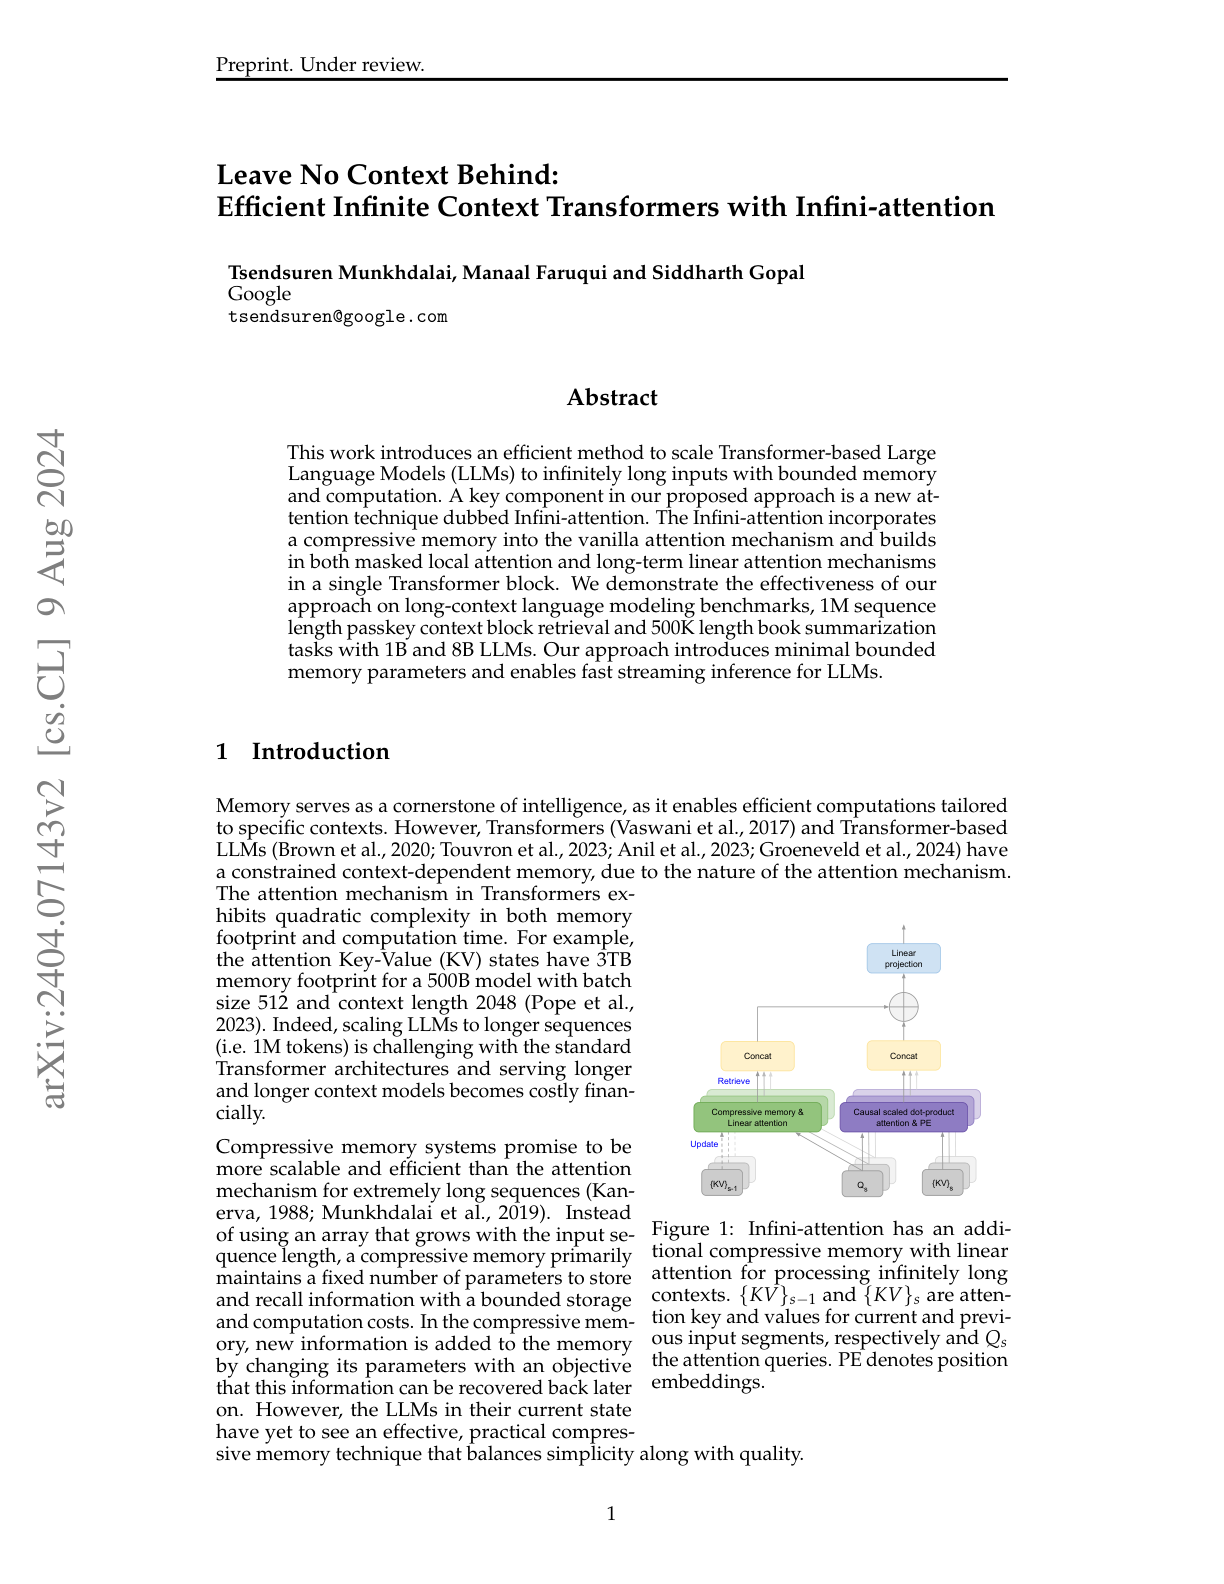
Google's Infini-attention extends Transformer LLMs to effectively infinite context with bounded memory and compute. It blends a compressive memory module with both masked local attention and linear long-term attention inside a single Transformer block.
Ask this paper
Unbounded context, bounded memory: The compressive memory stores historical key-value statistics in a fixed-size matrix, so token streaming does not grow memory over time and enables true long-form inference.
Dual-attention block: Each Infini-attention layer combines local windowed attention for recent tokens with long-term linear attention over the compressive memory, giving the same block access to short- and long-range dependencies simultaneously.
Empirical results: 1B and 8B Infini-Transformers outperform baseline long-context models on book summarization (500K tokens) and 1M-token passkey retrieval, while achieving a 114x memory compression ratio on long-context language modeling.
Streaming implication: Because the memory footprint is bounded, Infini-Transformer is a clean fit for streaming inference, document-flow agents, and any setting where the input grows indefinitely.