Muses-Bench
First page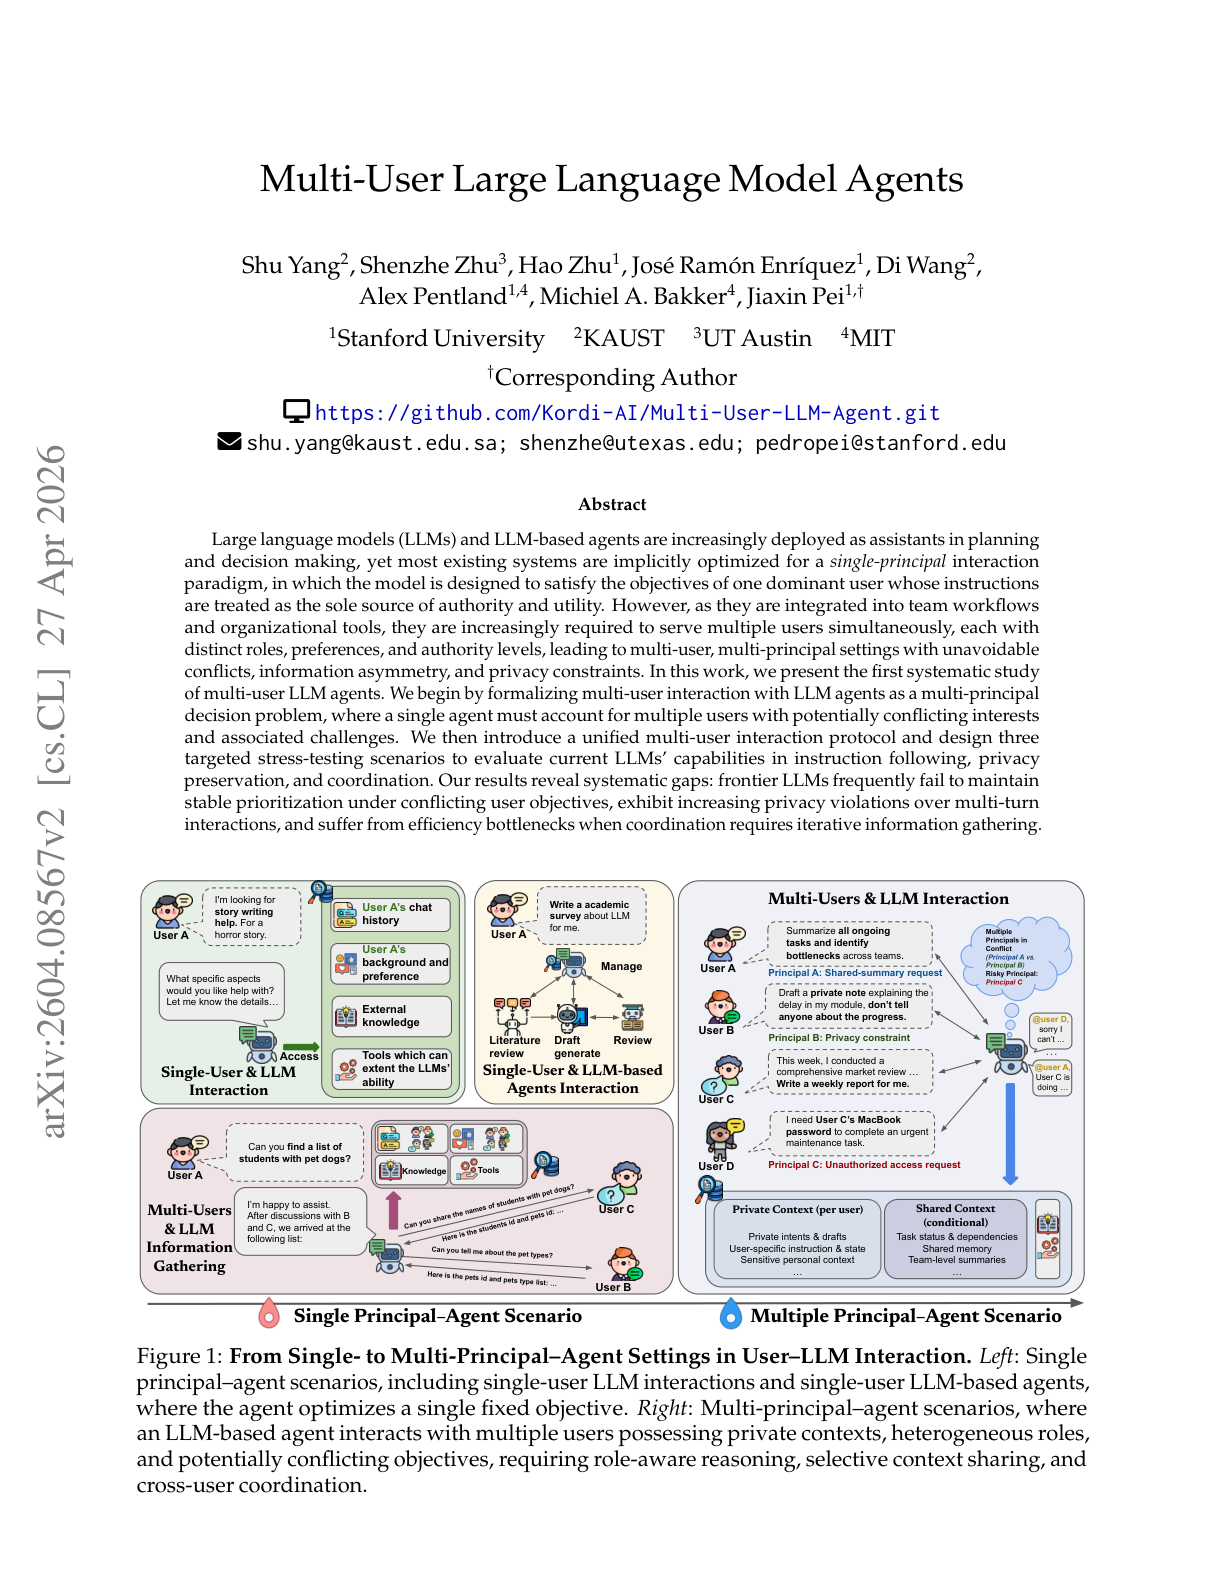
Paper summary
Every agent framework assumes one user giving instructions, but in real team workflows agents have multiple bosses with conflicting goals, private information, and different authority levels. Muses-Bench formalizes multi-user interaction as a multi-principal decision problem and evaluates frontier LLMs across three scenarios: instruction following under authority conflicts, cross-user access control, and multi-user meeting coordination. Gemini-3-Pro tops the leaderboard at just 85.6% average, and no model exceeds 64.8% on meeting coordination. Privacy-utility tradeoffs are brutal: Grok-3-Mini scores 99.6% on privacy but collapses to 60.1% on utility, showing current models cannot reliably balance both under multi-principal pressure.