OmniHuman-1: Scaling One-Stage Human Animation
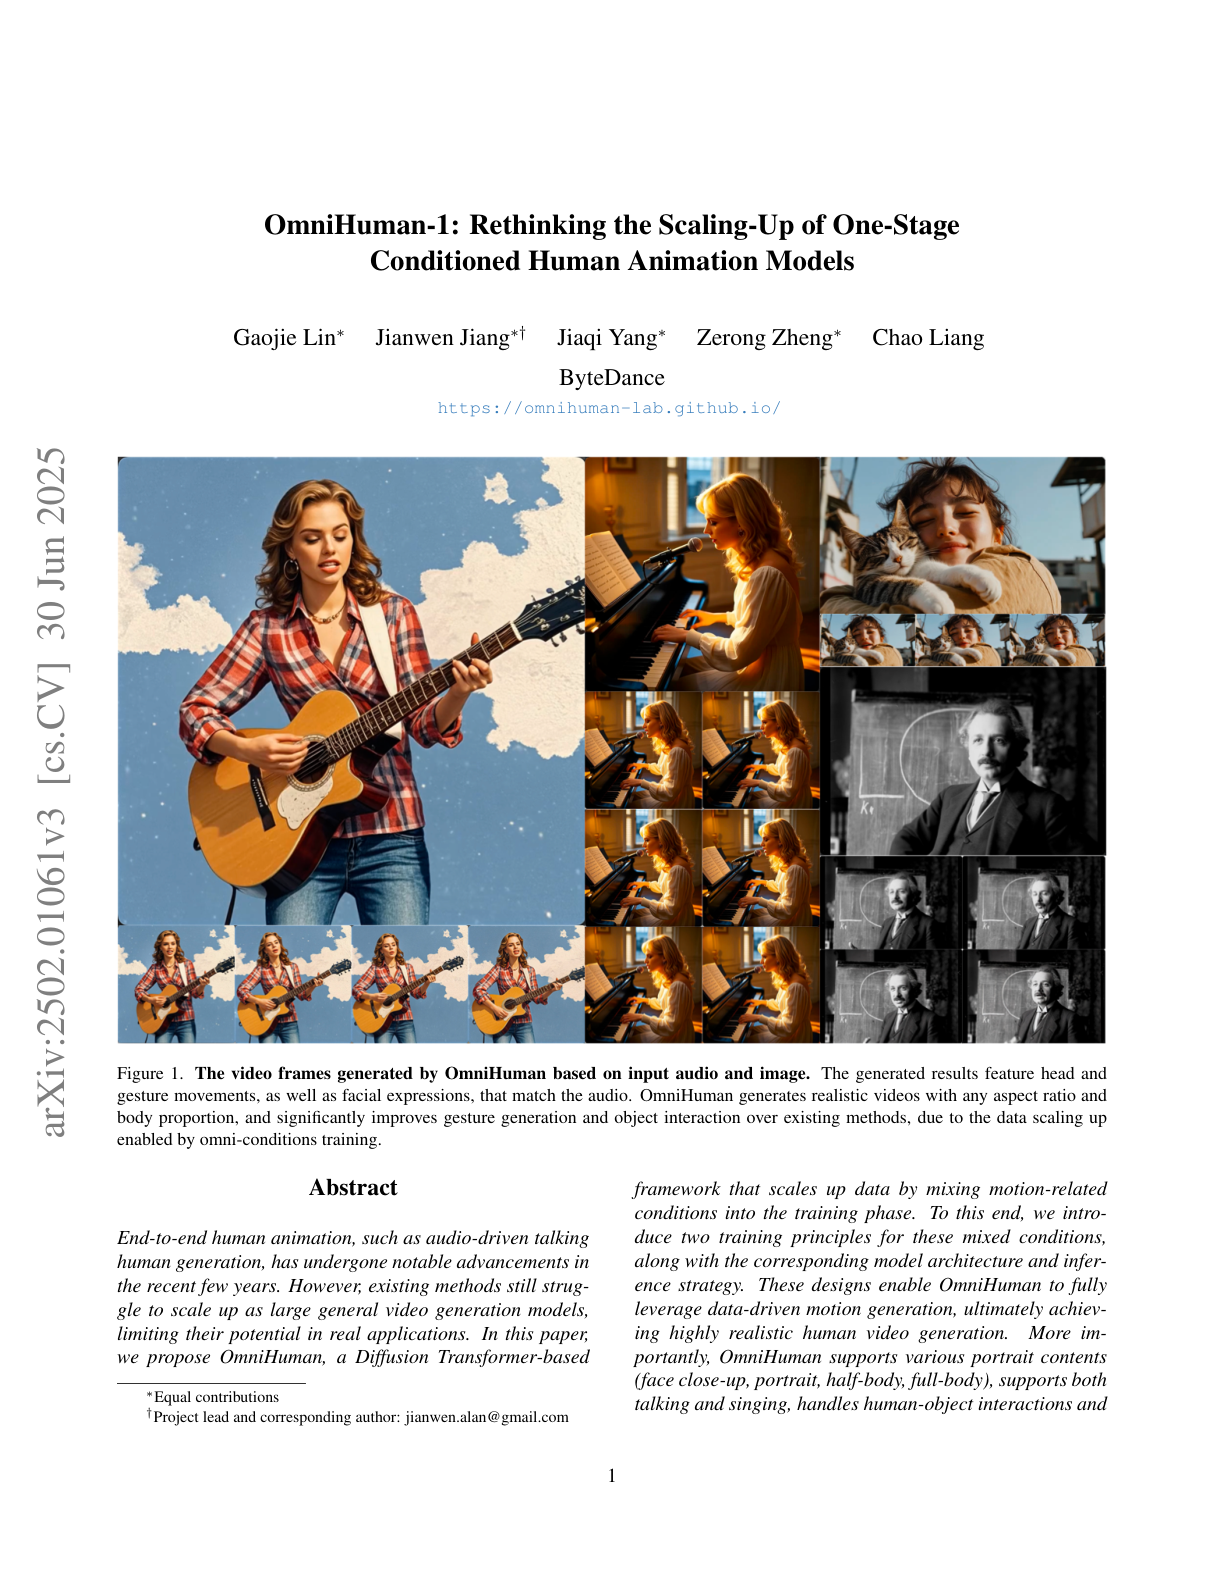
A team at ByteDance AI Lab unveiled OmniHuman-1, a diffusion-transformer model that can generate highly realistic human videos from just a single image plus motion input (audio or video). Highlights:
Ask this paper
End-to-end human video generation – OmniHuman takes one image (any aspect ratio, from face only to full-body) and an audio clip or video motion and produces a lifelike video of that person speaking, singing, or performing actions. The outputs are remarkably realistic in motion, lighting, and texture detail.
Mixed modality training – A key innovation is Omni-Conditions Training: mixing various motion modalities during training (audio-driven, video-driven, pose, etc.). This greatly expands the training data and overcomes the usual scarcity of high-quality talking-head video data. The model learns to handle diverse inputs (speech, song, instruments) and challenging poses.
Outperforms prior methods – Compared to earlier one-stage models (e.g. audio-driven talking heads), OmniHuman generates more realistic videos and is more flexible in input types. It can even handle cartoons or animal figures as input, transferring motion naturally to each style.
Broader support – The approach supports any portrait content (face close-up, half-body, full-body) and multiple driving signals simultaneously. This generality is a first for end-to-end human animation models.