One-Minute Video Generation with Test-Time Training
First page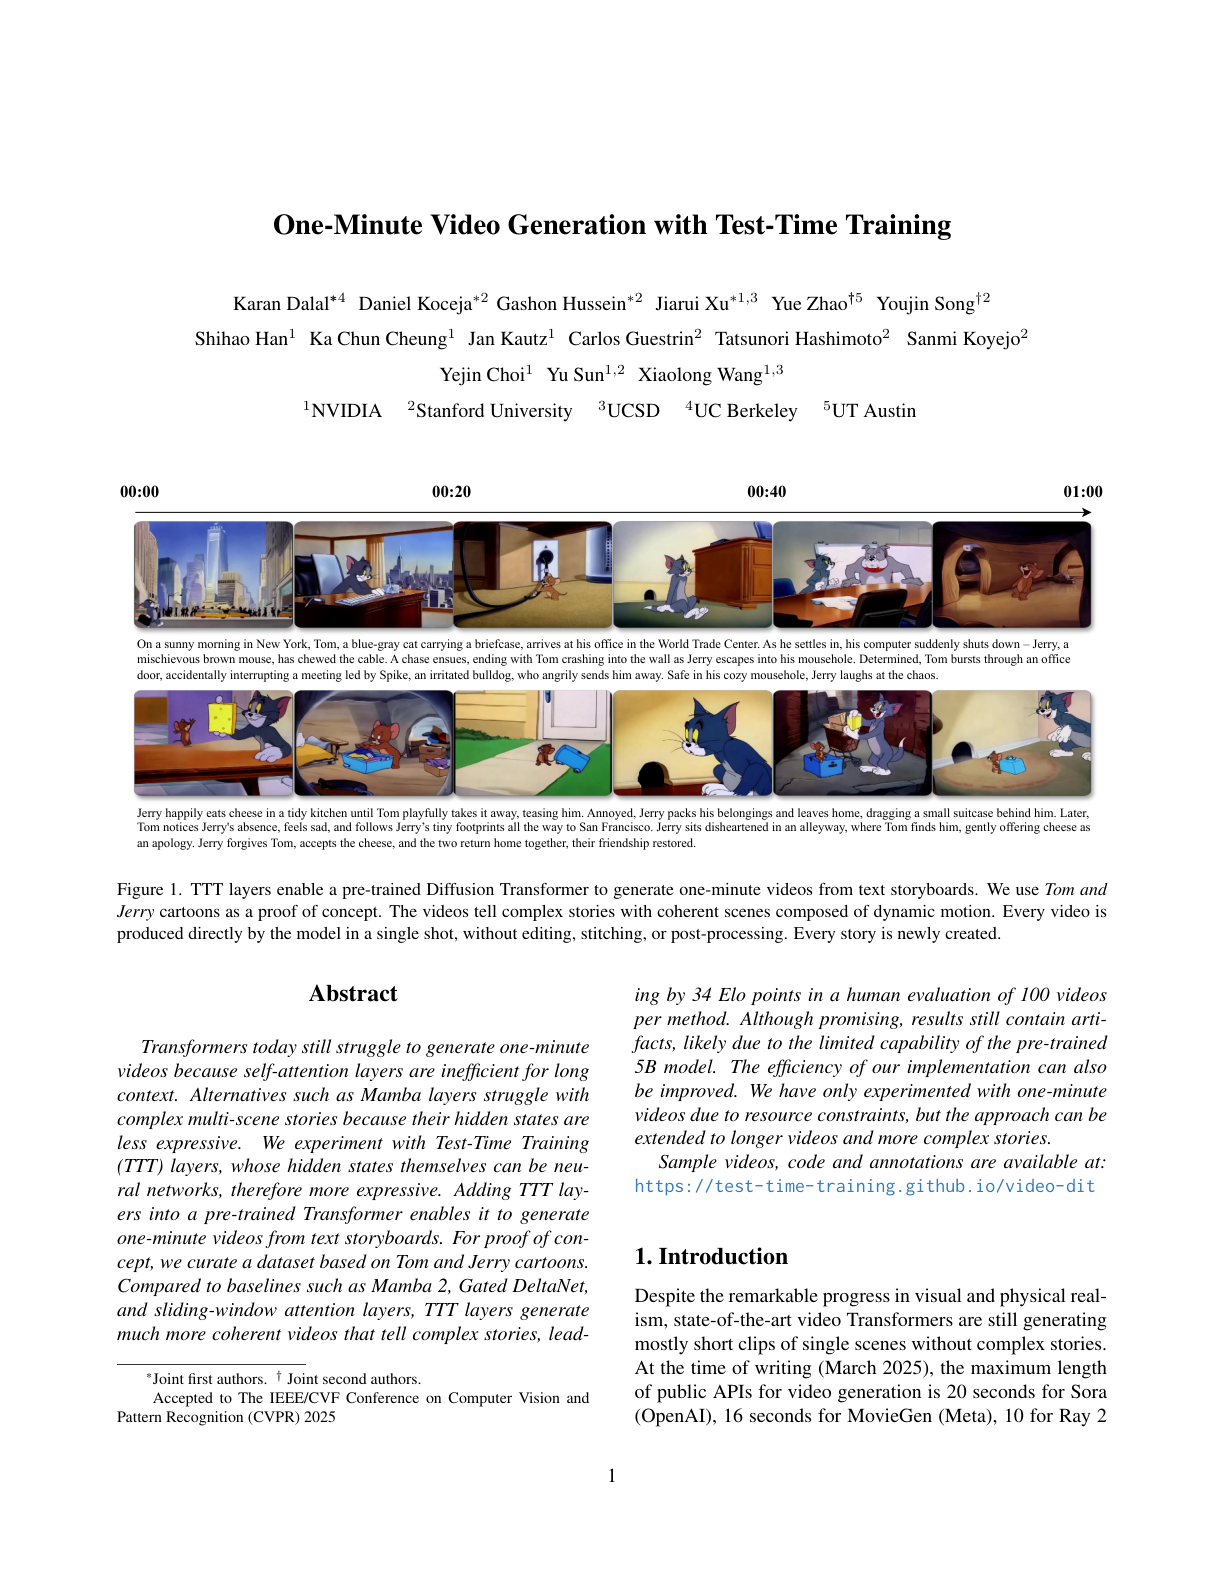
Paper summary
One-Minute Video Generation with Test-Time Training introduces TTT layers, a novel sequence modeling component where hidden states are neural networks updated via self-supervised loss at test time. By integrating these into a pre-trained diffusion model, the authors enable single-shot generation of one-minute, multi-scene videos from storyboards, achieving 34 Elo points higher than strong baselines like Mamba 2 and DeltaNet in human evaluations