Practical Efficiency of Muon for Pretraining
First page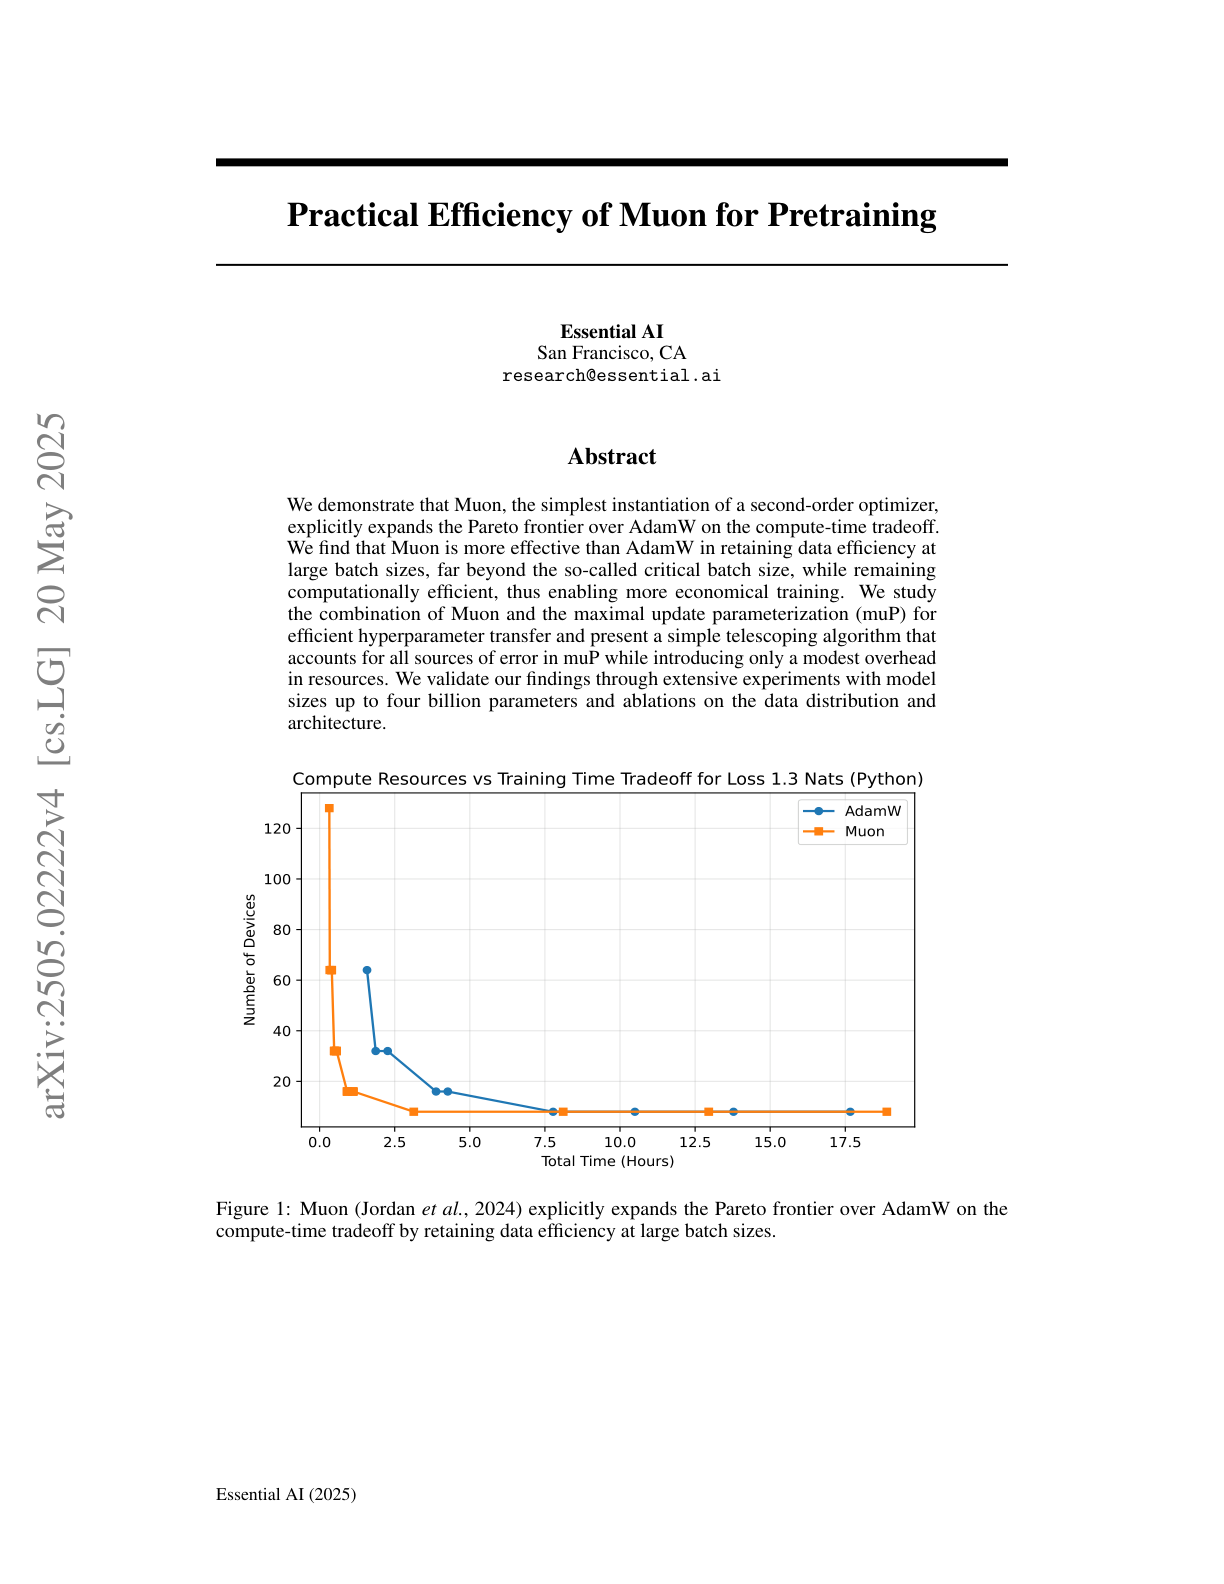
Paper summary
Discusses how Muon, a simple second-order optimizer, outperforms AdamW in large-batch pretraining by expanding the compute-time Pareto frontier and maintaining better data efficiency. Combined with muP scaling and a novel telescoping algorithm for hyperparameter transfer, it enables faster training with minimal tuning overhead up to 4B parameter models.