QwenLong-L1
First page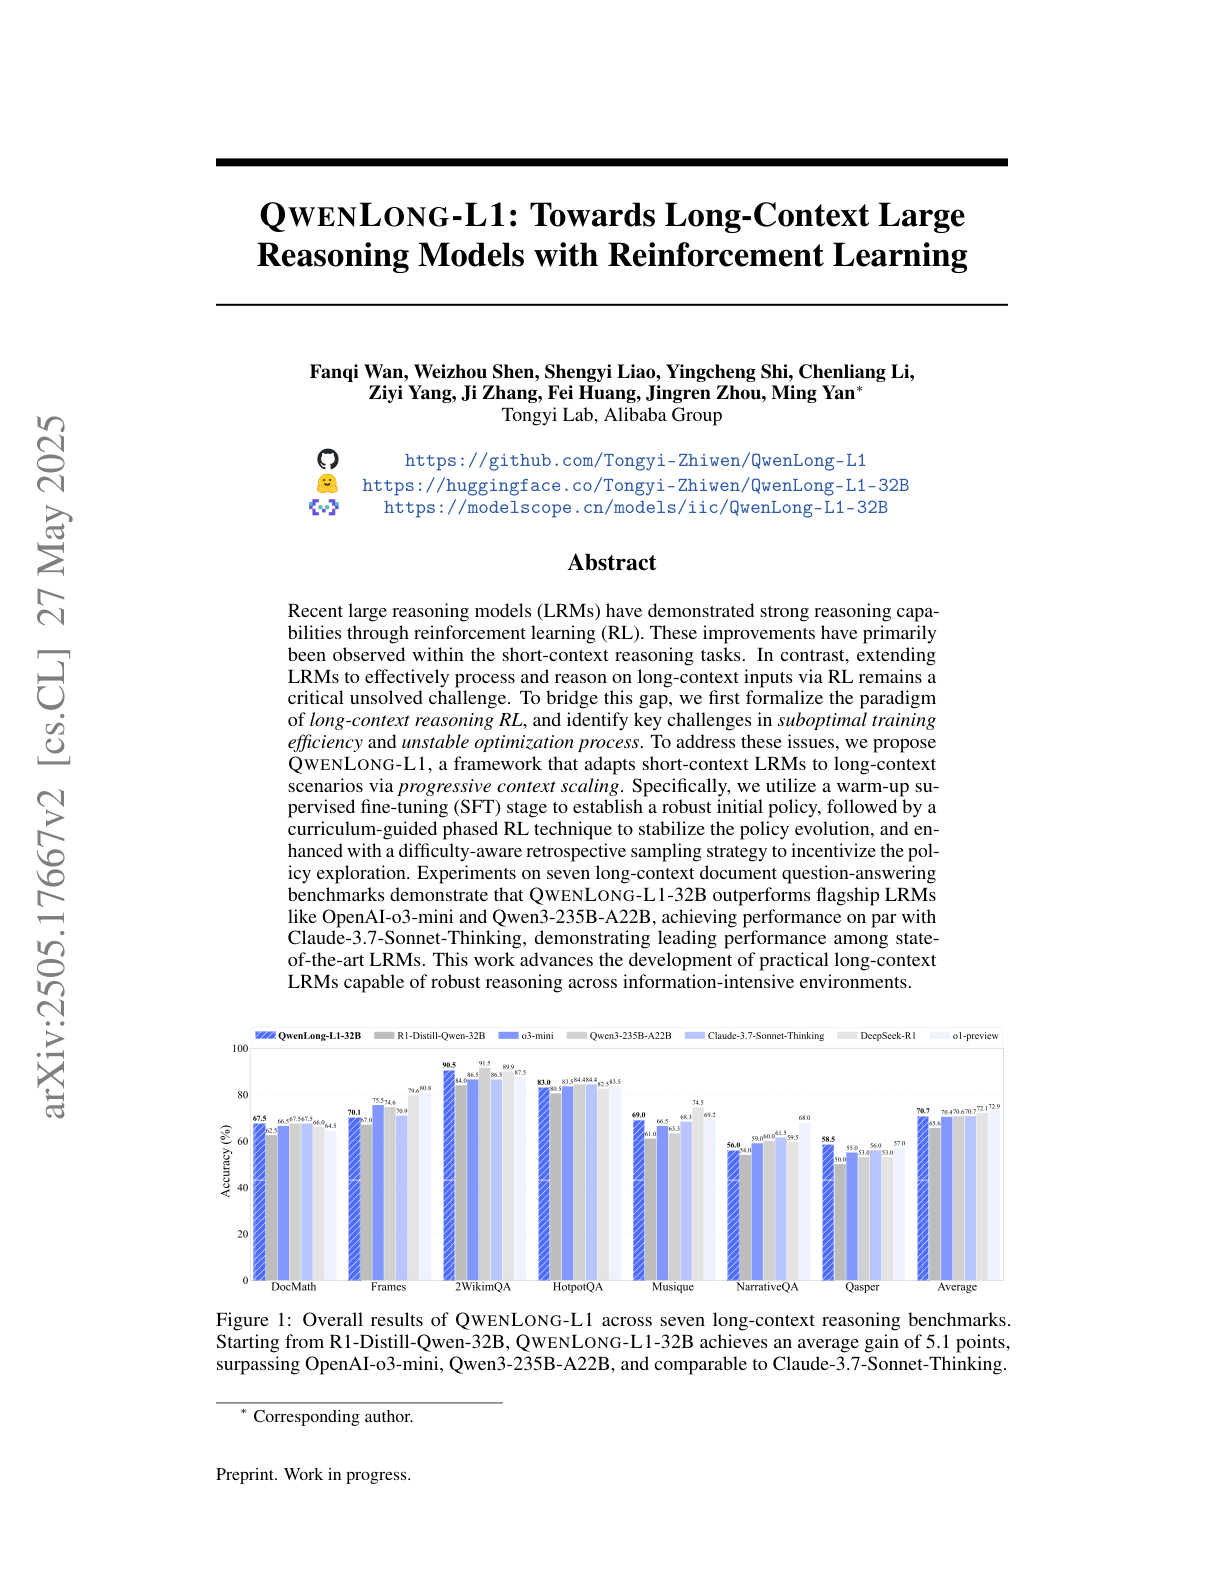
Paper summary
A new reinforcement learning framework that scales large reasoning models (LRMs) from short to long contexts using progressive context scaling and hybrid rewards. It achieves top performance on seven long-context benchmarks, surpassing models like OpenAI-o3-mini and Qwen3-235B-A22B, and matching Claude-3.7-Sonnet-Thinking, demonstrating strong reasoning with up to 120K token inputs.