RoboTTT
First page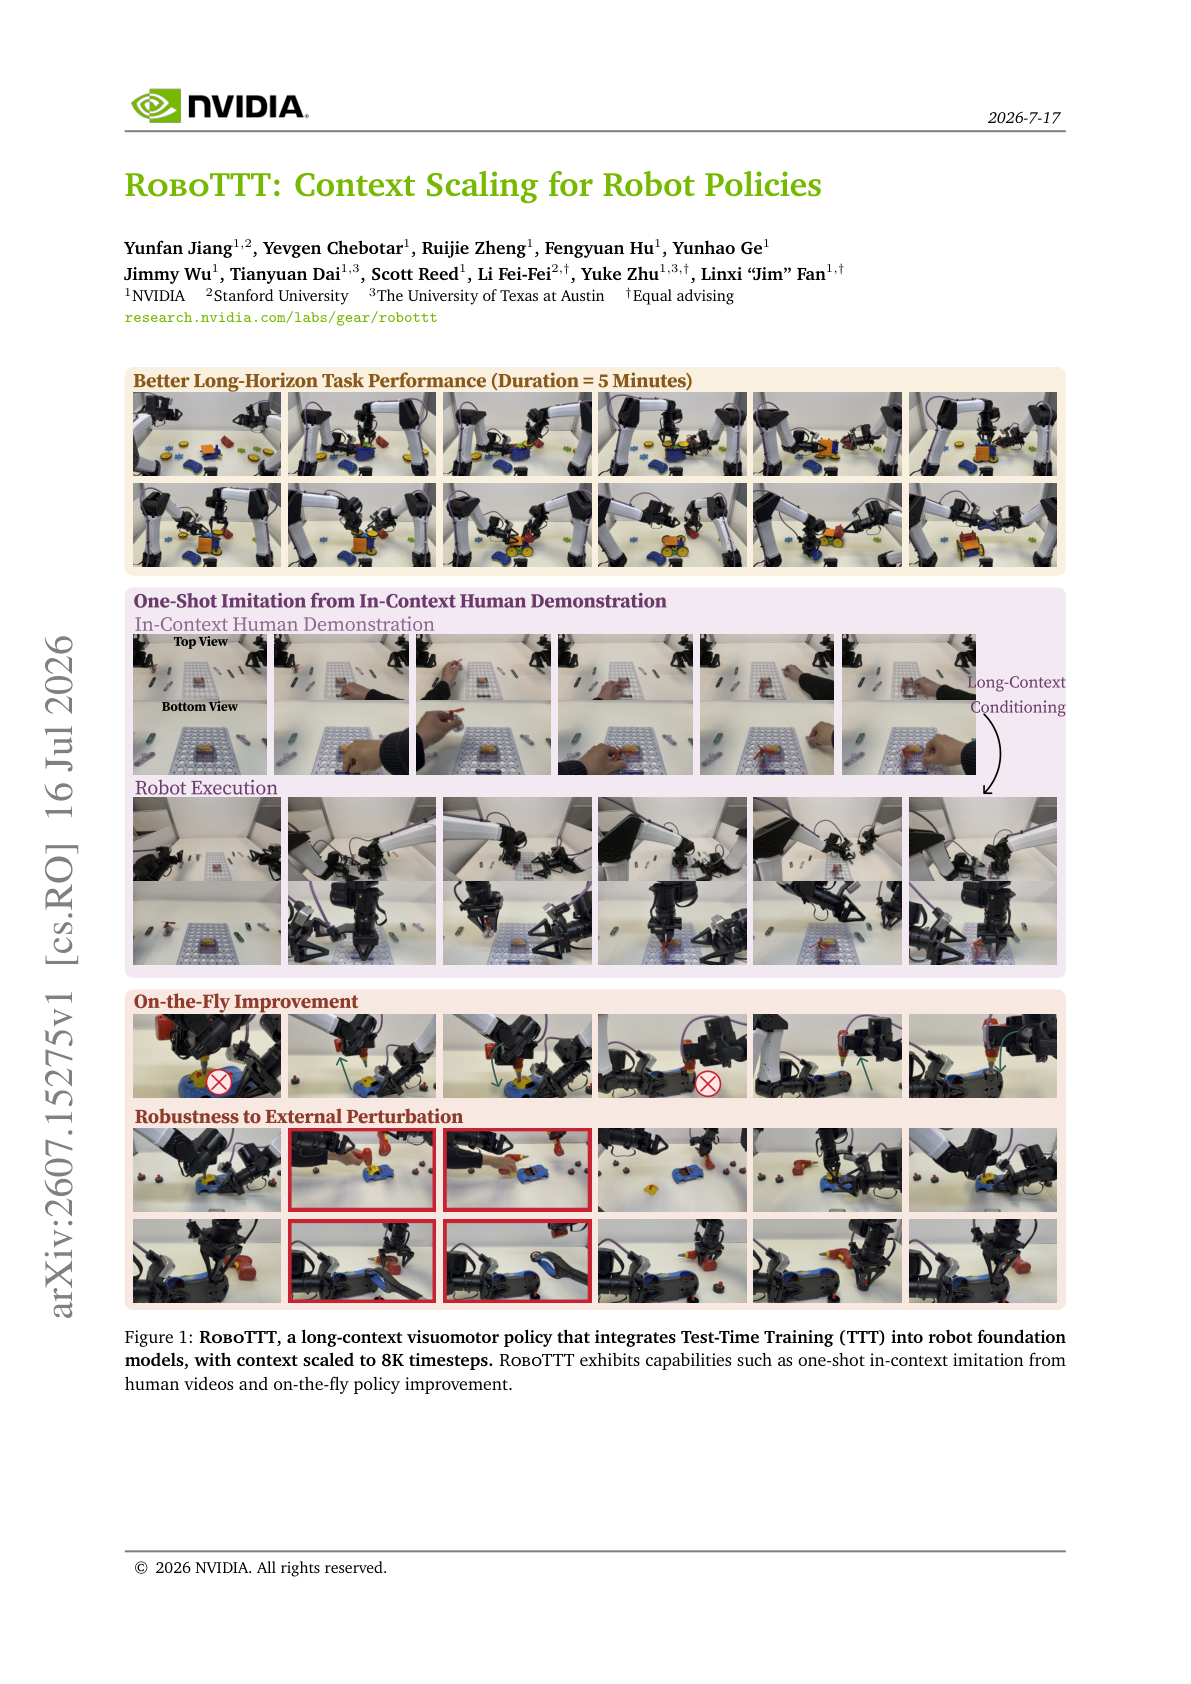
Paper summary
Recent robot foundation models run on single-step or short-history context, a strange way to attempt a five-minute assembly task. RoboTTT, from NVIDIA with Stanford and UT Austin, integrates test-time training into vision-language-action policies to scale visuomotor context to 8K timesteps, three orders of magnitude past prior policies, without growing inference latency. The longer context unlocks one-shot in-context imitation from human video, on-the-fly policy improvement, and robustness to perturbations. It improves overall performance by 87% over a single-step baseline, fully completes a ten-stage assembly task that no baseline finishes, and gains 62% from pretraining with 8K rather than 1K timesteps.