INTELLECT-3
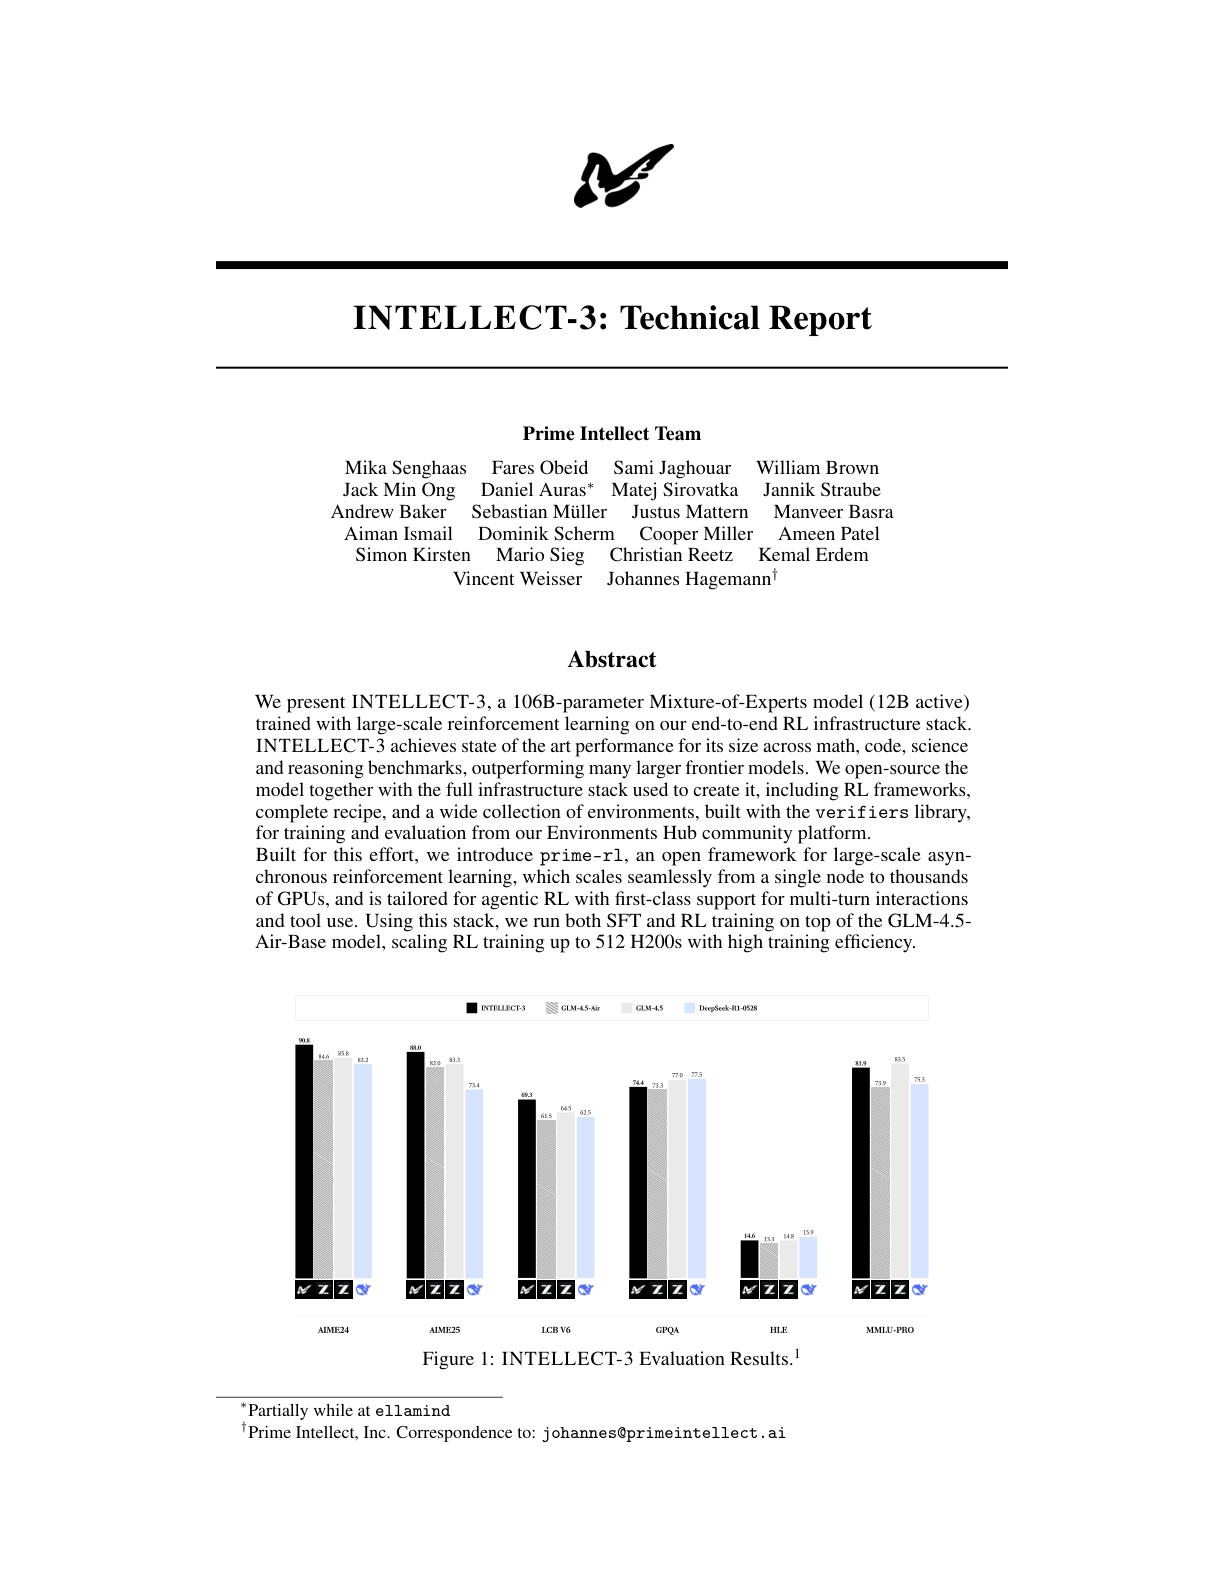
INTELLECT-3 is a 106B-parameter Mixture-of-Experts model (12B active) trained with large-scale reinforcement learning, achieving state-of-the-art performance for its size across math, code, science, and reasoning benchmarks. Built on top of GLM-4.5-Air base, it outperforms many larger frontier models, including DeepSeek R1-0528, and matches GLM-4.6 (which has over 3x the parameters) on key benchmarks.
Ask this paper
Frontier benchmark results: Achieves 90.8% on AIME 2024 and 88.0% on AIME 2025, outperforming DeepSeek R1-0528. Scores 69.3% on LiveCodeBench v6, beating GLM-4.5-Air by 8%. Competitive on GPQA Diamond (74.4%), HLE (14.6%), and MMLU-Pro (81.9%).
prime-rl framework: Introduces an open-source asynchronous RL framework with disaggregated trainer and inference, continuous batching with in-flight weight updates, and native support for multi-turn agentic rollouts. Scales seamlessly from single node to 512 H200 GPUs.
Two-stage post-training: Combines supervised fine-tuning on over 200B tokens of reasoning traces (from datasets like OpenReasoning-Math/Code/Science) with large-scale RL across diverse environments, including math, code, science, logic, deep research, and software engineering tasks.
Verifiers and Environments Hub: Open-sources the complete training infrastructure, including the verifiers library for environment design, an Environments Hub with 500+ contributed RL environments, and Prime Sandboxes for high-throughput secure code execution supporting over 4,000 concurrent sandboxes.
Full reproducibility: Releases model weights, complete training recipe, RL framework, and all environments used for training and evaluation. Training ran on 512 H200s over two months with a batch size of 256 prompts and 16 rollouts per prompt at 65K context length.