ReMamba
First page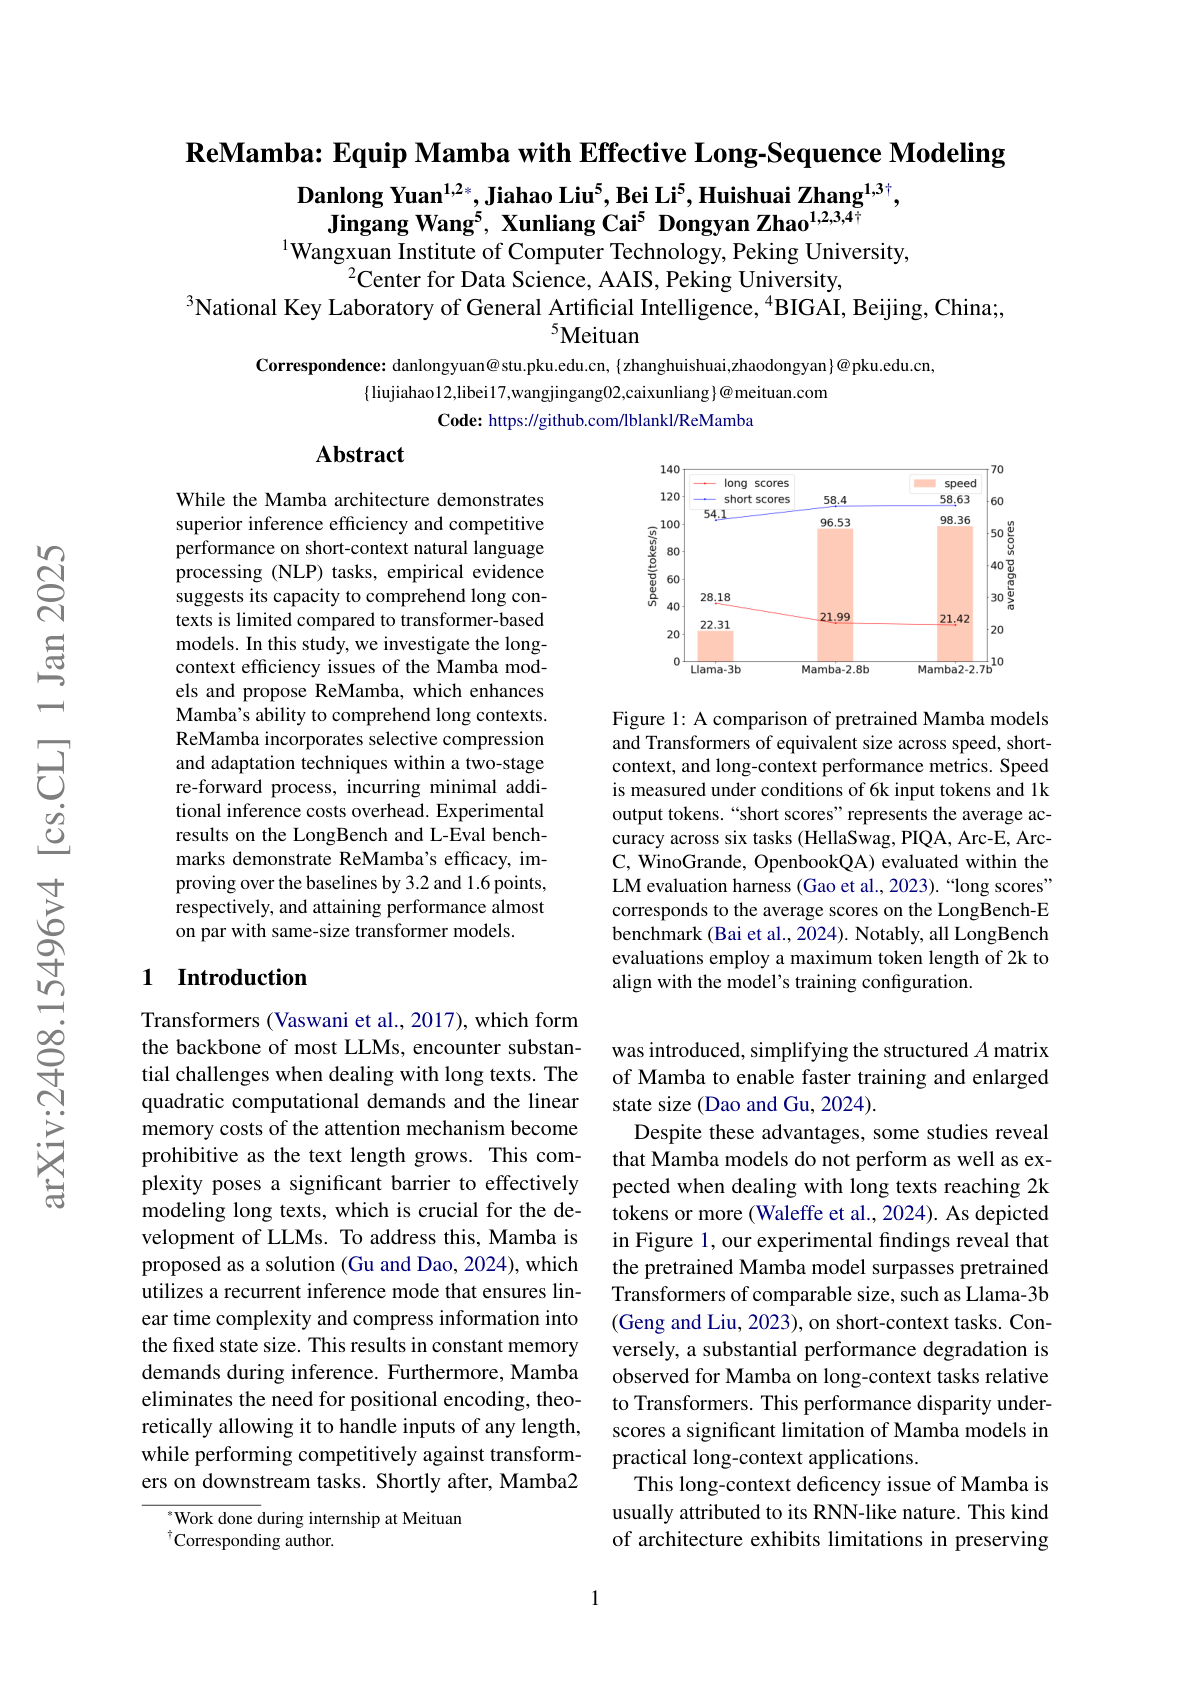
Paper summary
investigates the long-context capabilities and efficiencies of Mamba models; the long-context deficiency issues are due to Mamba's RNN-like nature; it achieves this by condensing information via the following compression strategy: the top-k hidden states during the first forward pass and leverages Mamba’s selective mechanism to incorporate them into the state space during the second forward pass; achieves a 3.2 improvement over the baseline on LongBench and 1.6 improvement on L-Eval; the strategy seems to also transfer to Mamba 2.