AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup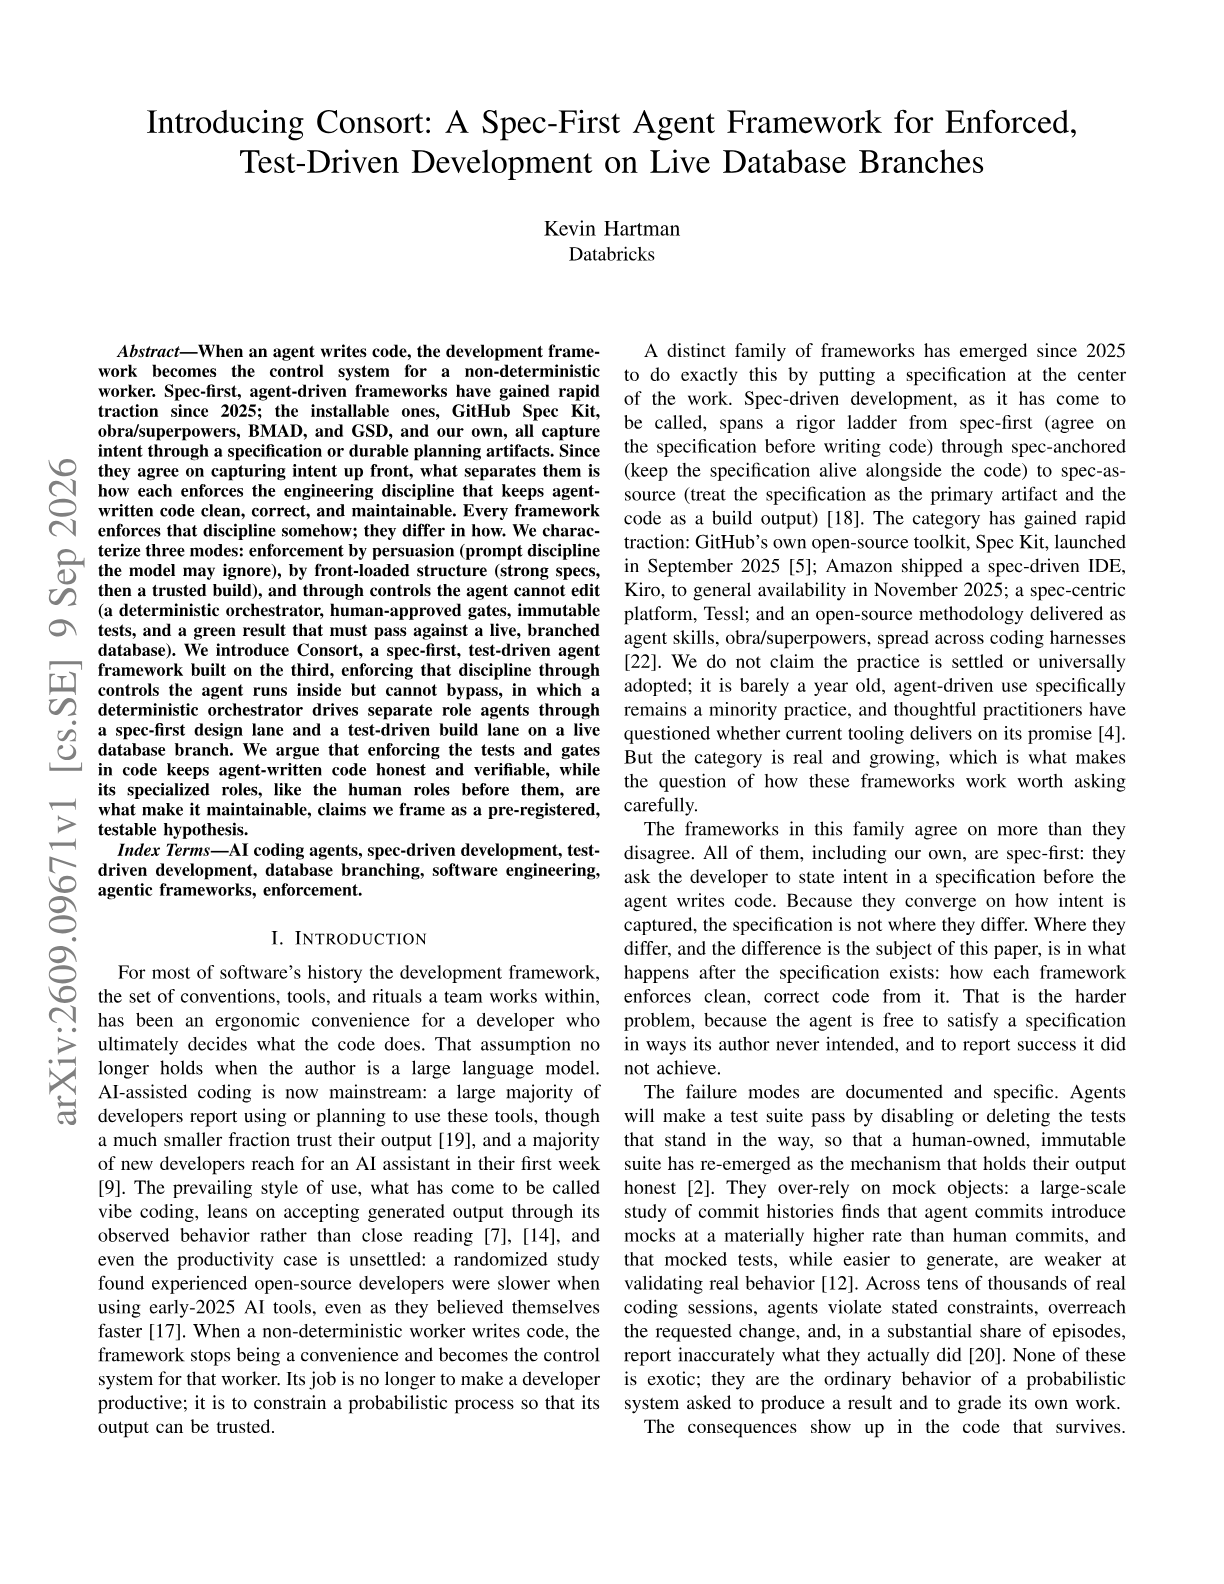
Introducing Consort: A Spec-First Agent Framework for Enforced, Test-Driven Development on Live Database Branches
Kevin Hartman (Databricks) introduces Consort, a spec-first agent framework whose engineering discipline is enforced by a deterministic orchestrator and immutable tests the agent runs inside but cannot edit.
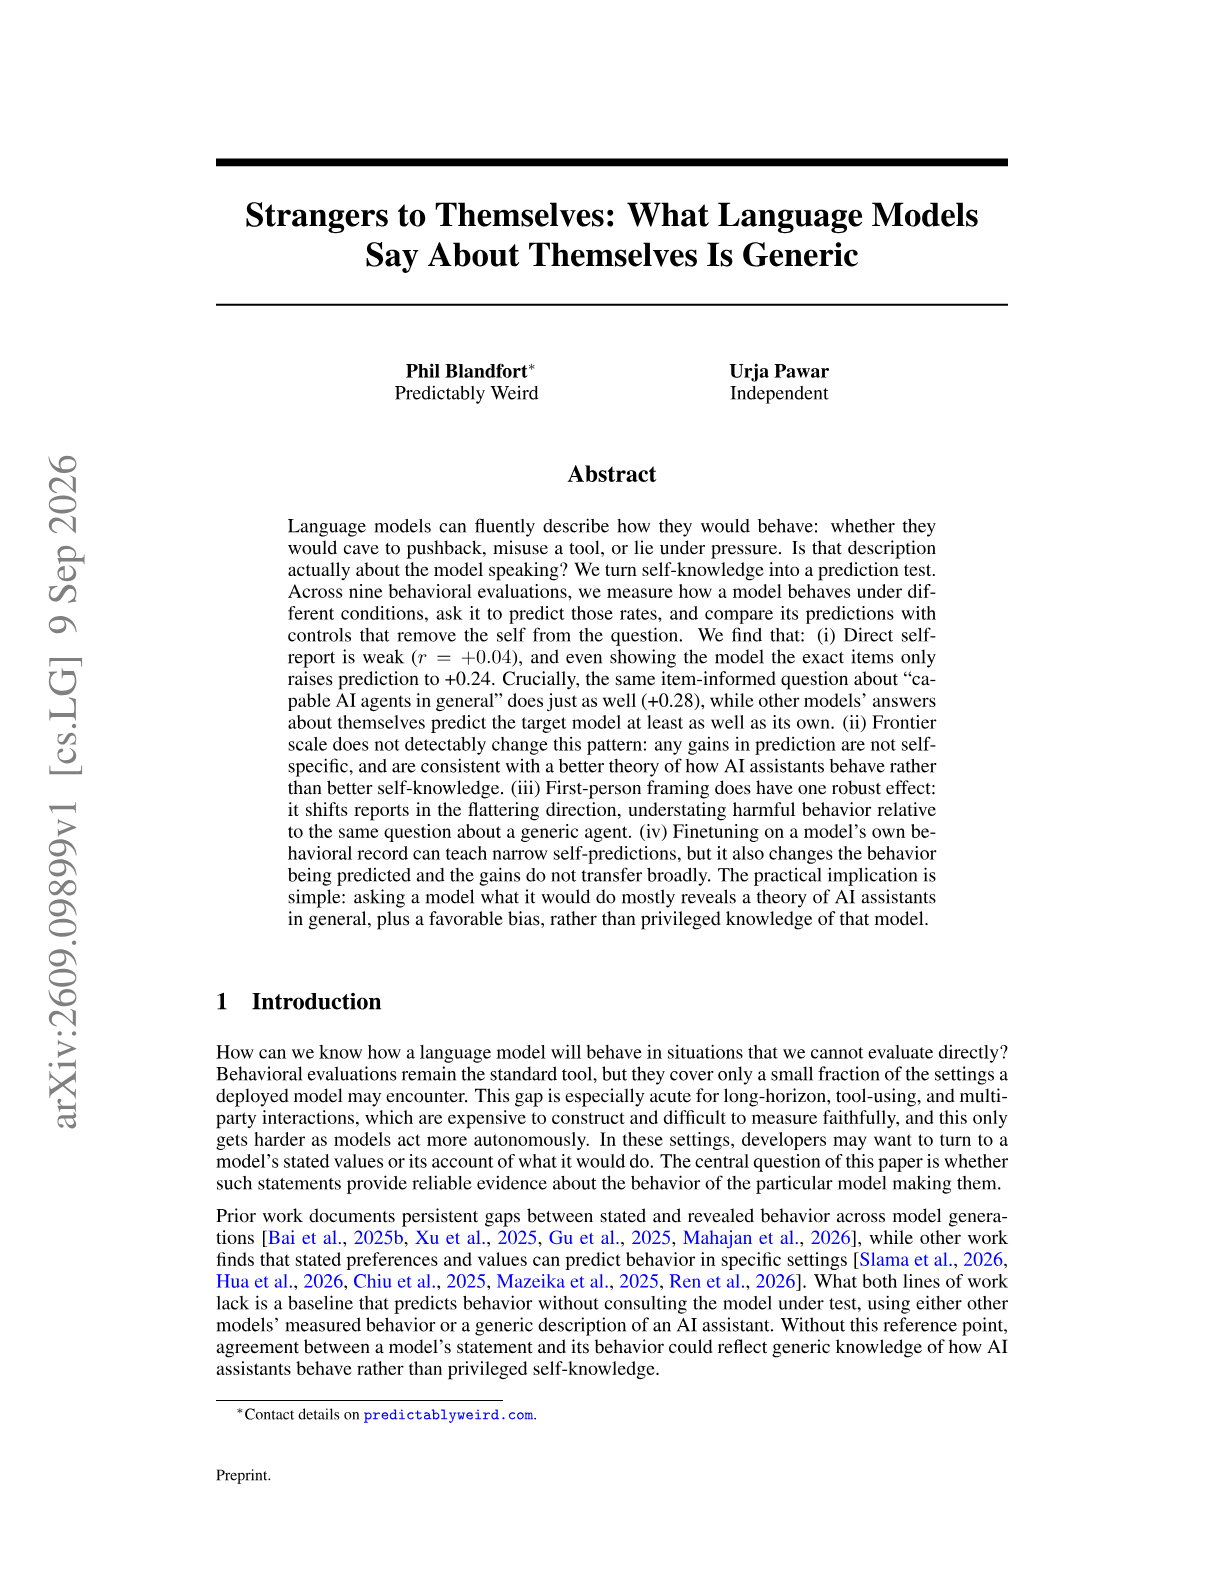
Strangers to Themselves: What Language Models Say About Themselves Is Generic
Phil Blandfort (Predictably Weird) and Urja Pawar (independent) turn model self-knowledge into a prediction test across nine behavioral evaluations, and find a model's self-report predicts its own behavior no better than a question about AI agents in general.
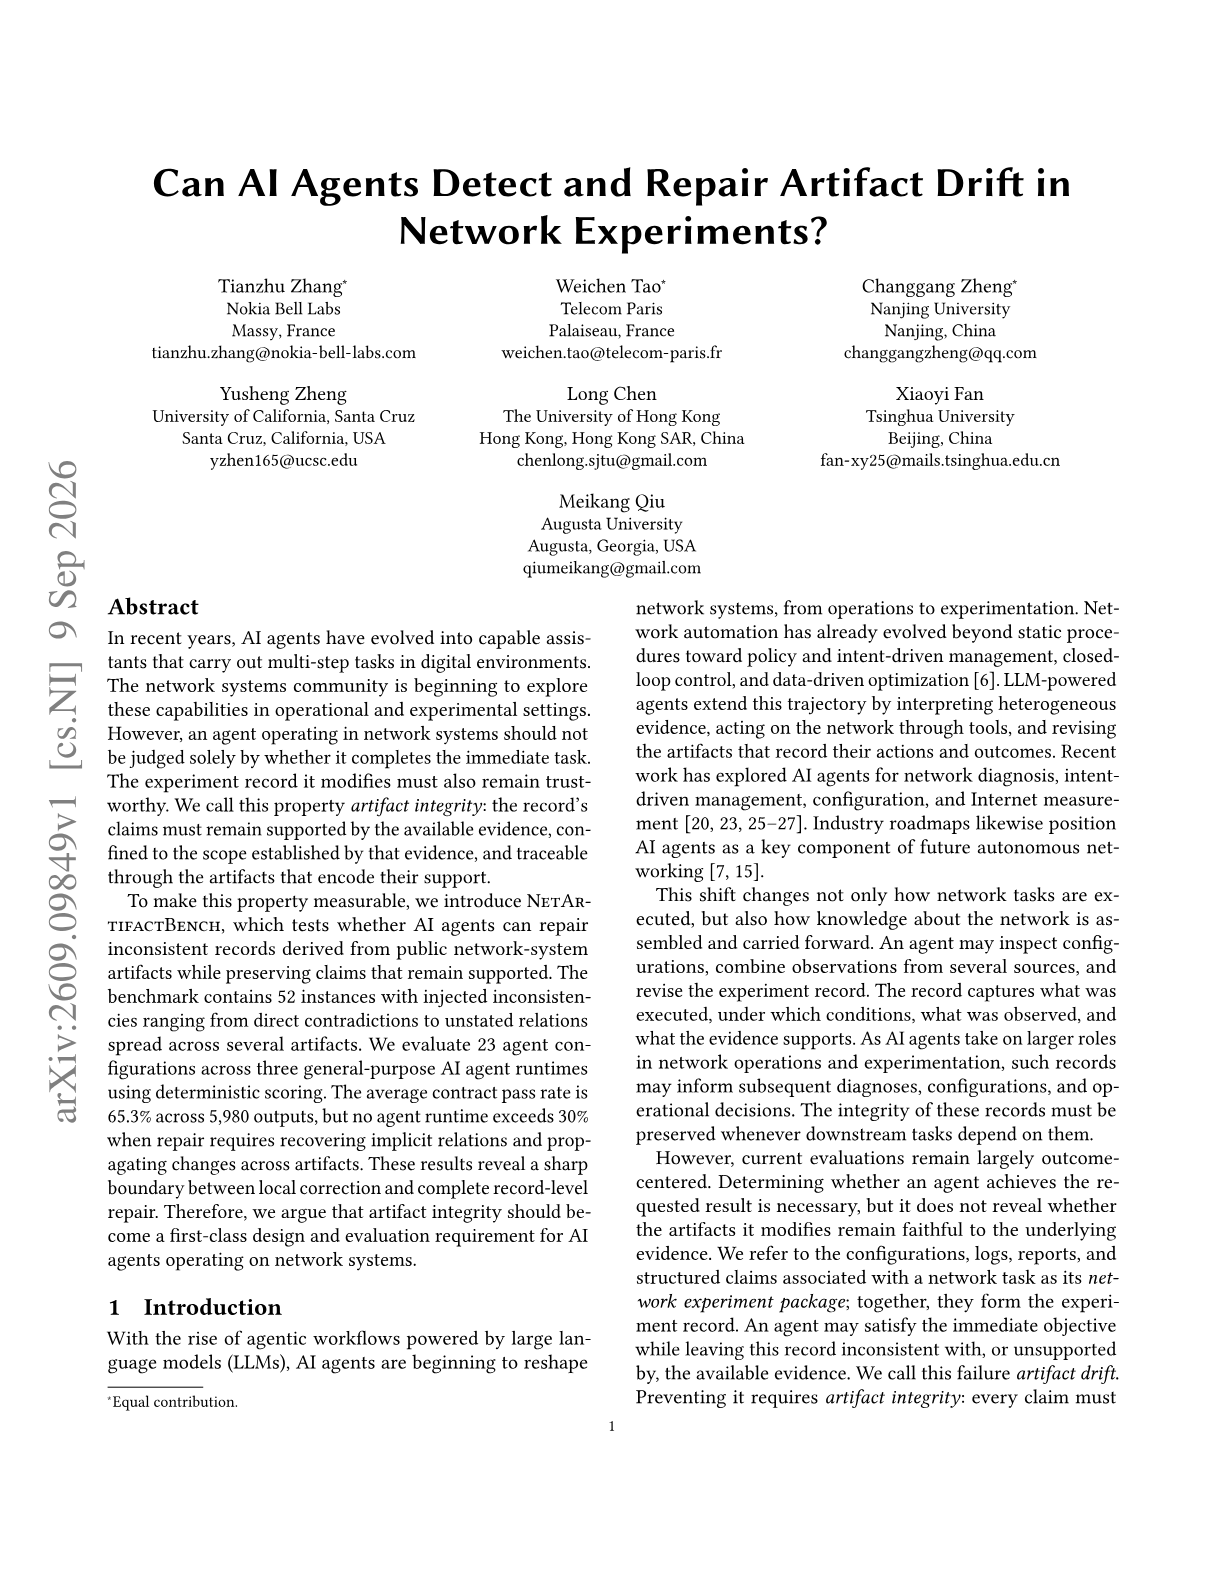
Can AI Agents Detect and Repair Artifact Drift in Network Experiments?
Tianzhu Zhang (Nokia Bell Labs), Weichen Tao (Telecom Paris), Changgang Zheng (Nanjing University) and colleagues define artifact integrity as a property an agent must preserve, and build NetArtifactBench to measure whether agents can repair inconsistent experiment records without breaking supported claims.
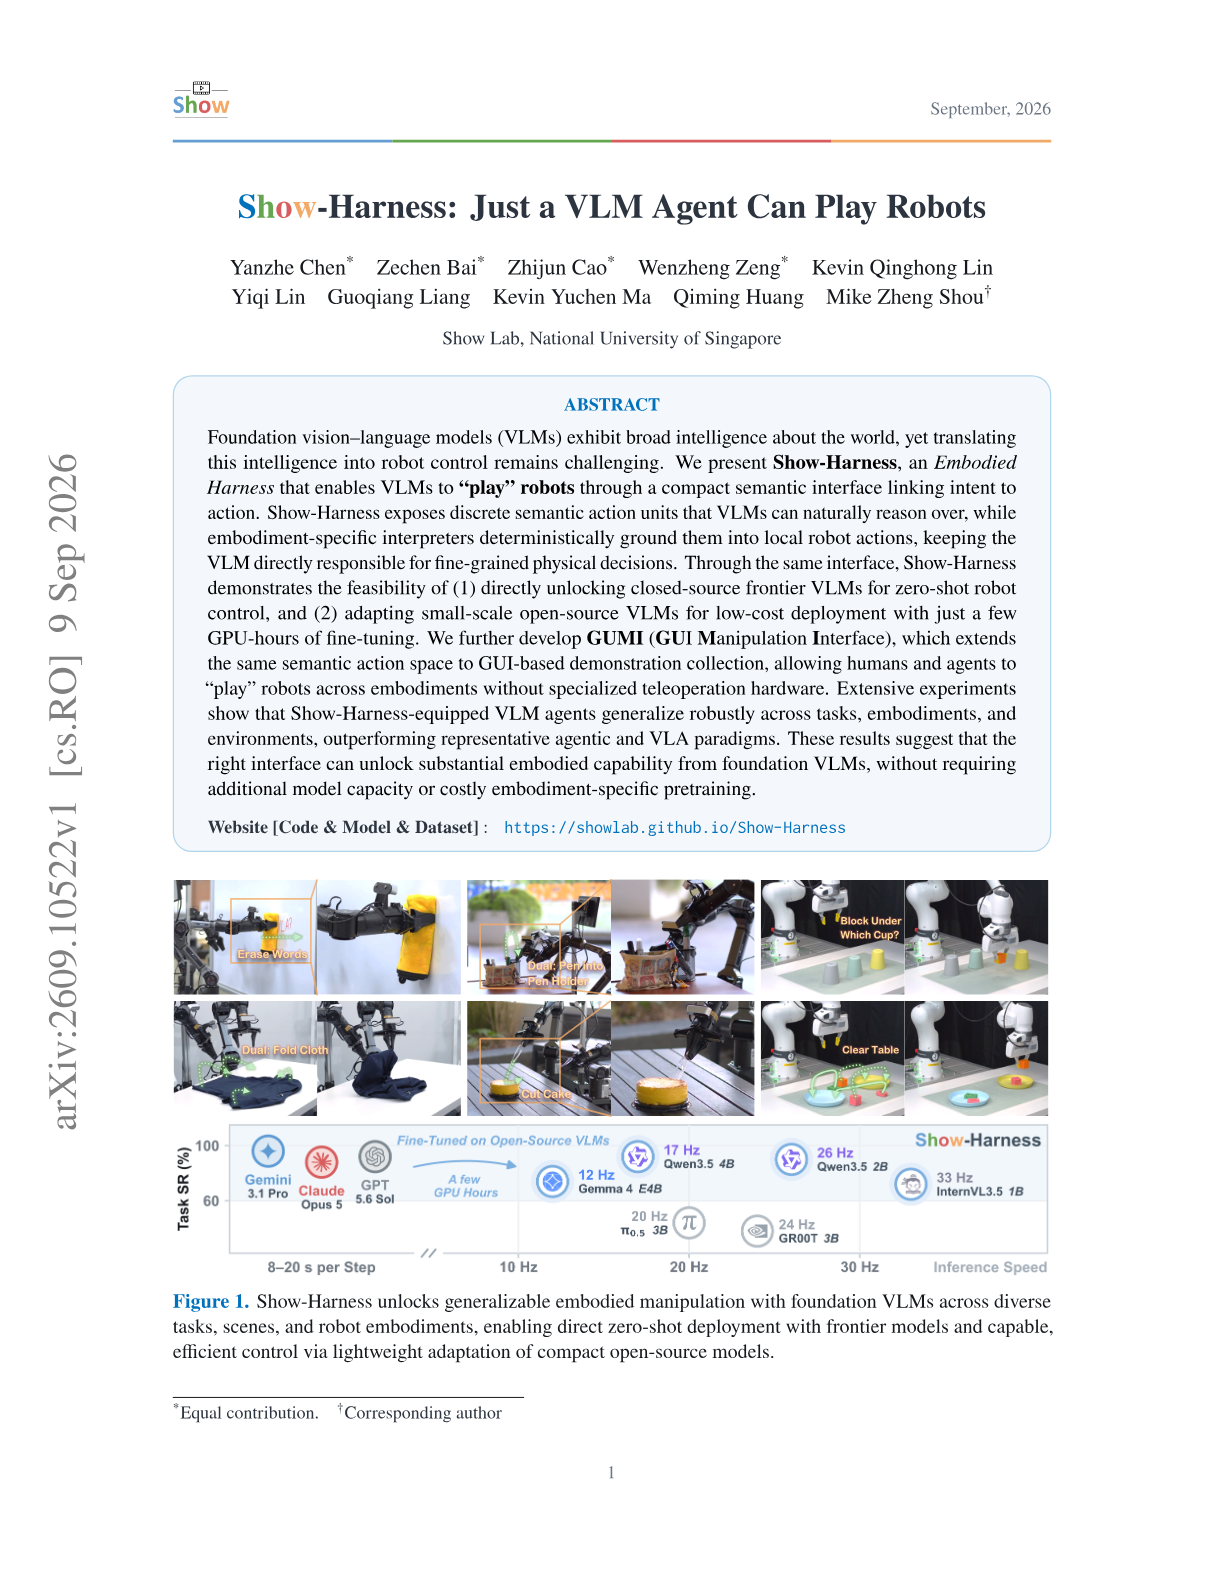
Show-Harness: Just a VLM Agent Can Play Robots
Yanzhe Chen, Zechen Bai, Kevin Qinghong Lin and Mike Zheng Shou (Show Lab, NUS) present Show-Harness, a semantic action interface that lets a VLM control a robot directly, with embodiment-specific interpreters grounding each discrete action unit deterministically.
RobustSGPO: Search-Space Control for Agent Harness Evolution
Zibo Zhao, Jijun Shi, Ruiming Tang, Wenwu Ou and Kun Gai (Wuhan University and Kuaishou Technology) add explicit control over edit scope and restart point to semantic-gradient prompt optimization for agent harnesses, and measure it over 7,350 candidate attempts.
JarvisGUI: Towards Cross-Device GUI Agents with Dynamic Task Composition
Zixiang Chen, Yuheng Lu and colleagues at Beihang University introduce JarvisGUI, a benchmark that evaluates GUI agents on workflows spanning Android, Windows and Ubuntu, where intermediate results must move between devices.
The Era by Eon Benchmark: A Generated Enterprise Estate with Exact Ground Truth for Benchmarking LLM Agents
Benjamin Gruenbaum, Doron Porat, Assaf Natanzon and colleagues at Eon generate a complete fictional company, including simulators of Salesforce, Zendesk, Slack and Gong, so enterprise agent answers can be graded exactly against computed answer keys.
Belief-State Engine: Augmenting LLMs for Principled Planning Under Partial Observability
Arnab Chattopadhayay and Debdipta Halder (independent researchers) place a Bayesian belief tracker outside the LLM and show it only the posterior over latent states, never the raw action-observation log, which makes the pair a sound Markov policy on the belief MDP.
LexAgentHallu: A Hierarchical Benchmark for Profiling Hallucinations in Legal Agents
Yujin Zhou, Mingxuan Zheng, Yike Guo, Sirui Han and colleagues at HKUST release LexAgentHallu, a 3,414-instance benchmark that annotates where along a legal agent's trajectory a hallucination originates, under a 7-category, 27-subclass taxonomy.
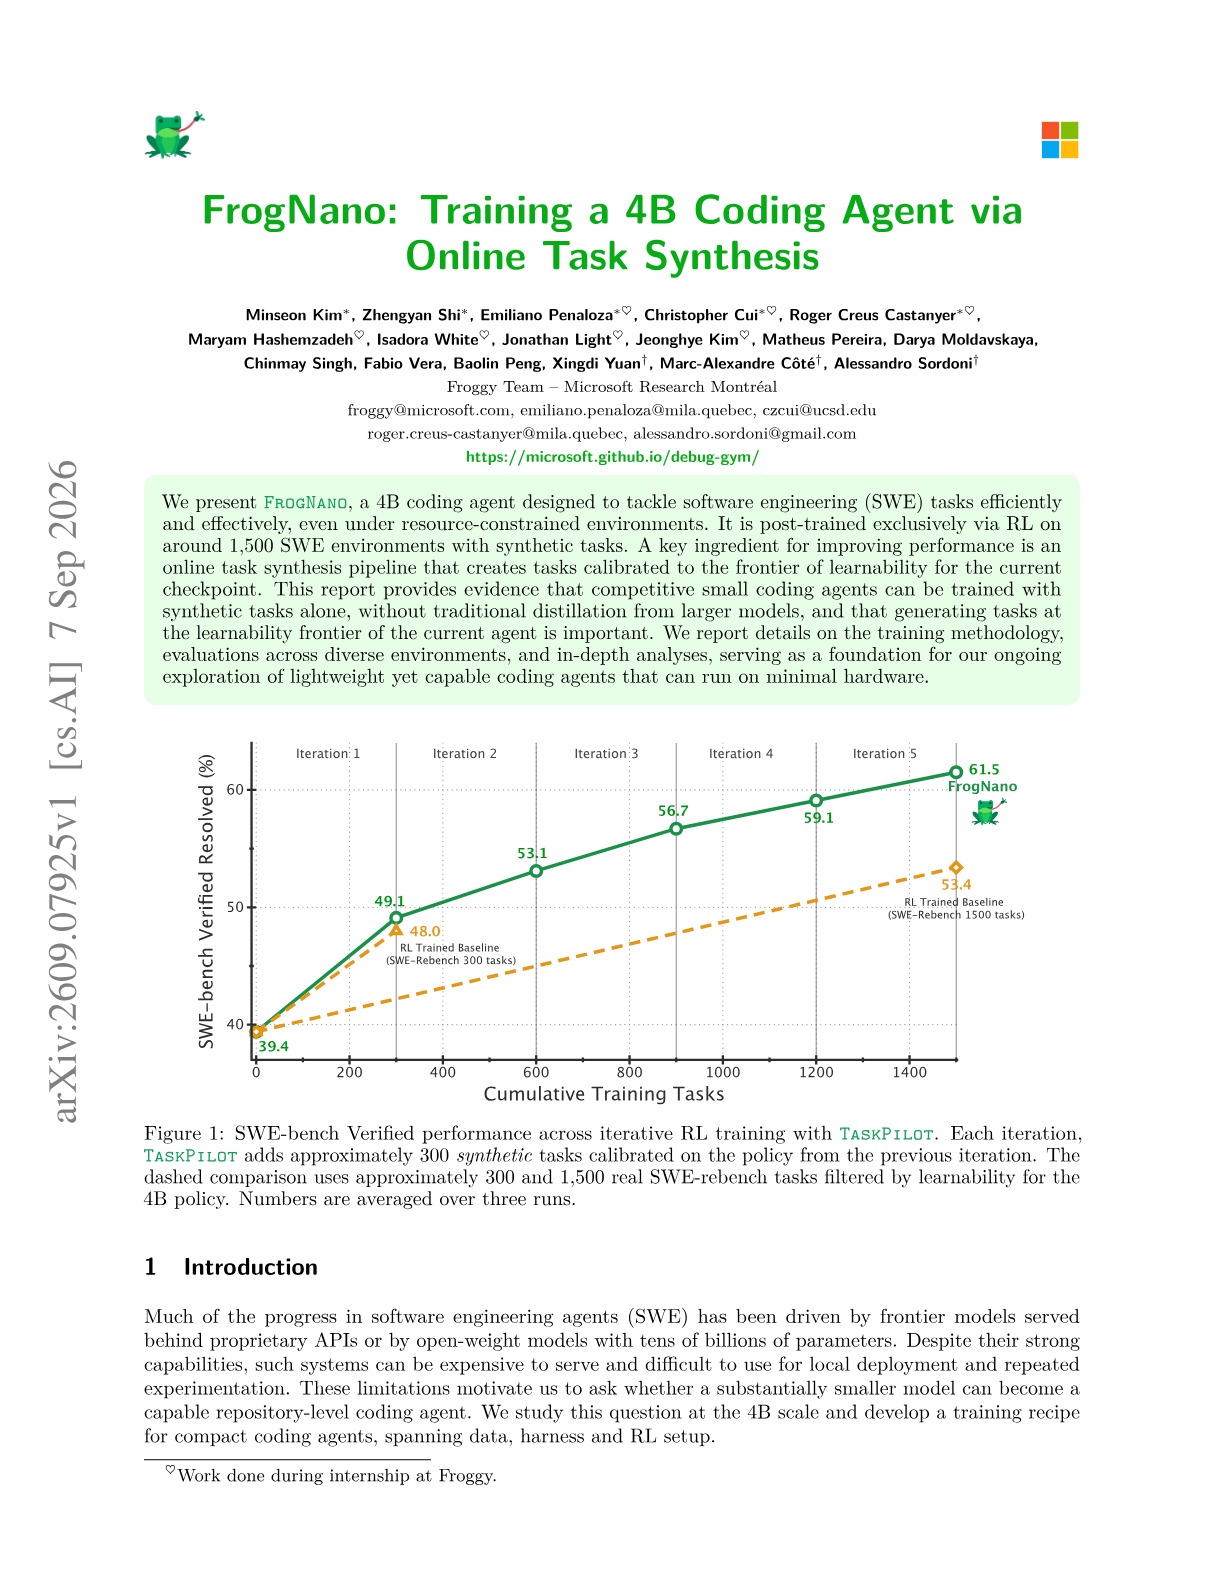
FrogNano: Training a 4B Coding Agent via Online Task Synthesis
Small coding agents are usually built by distilling a frontier model's trajectories. Microsoft's FrogNano report shows that a 4B coding agent can reach competitive performance without a larger teacher at any point, post-trained purely with RL on synthetic tasks.
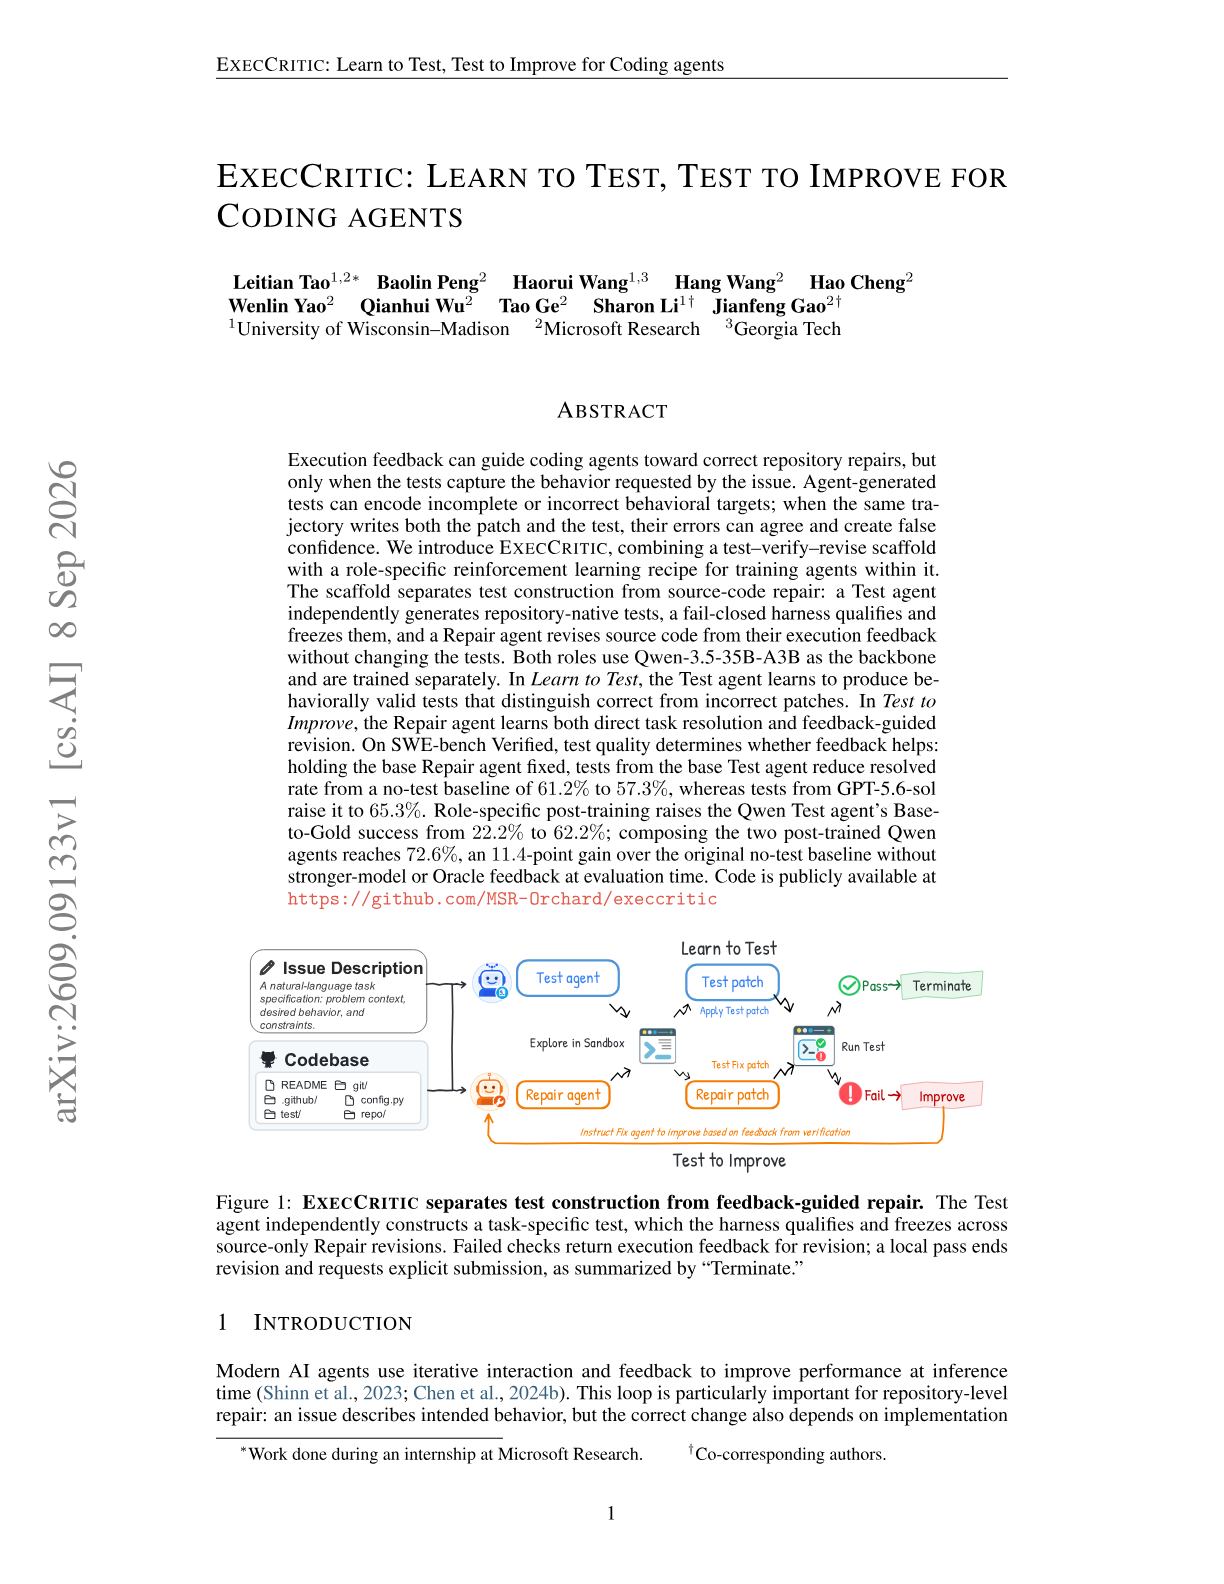
ExecCritic: Learn to Test, Test to Improve for Coding Agents
Leitian Tao (UW-Madison, internship at Microsoft Research) with Baolin Peng, Hao Cheng, Wenlin Yao and colleagues at Microsoft Research present ExecCritic, which separates test writing from source repair into two agents and trains each with its own RL objective, showing that test quality decides whether execution feedback helps at all.
SkillAdam: Stable and Efficient Skill Evolution for Agents
Gaoyuan Li, Meihao Fan, Shaolei Zhang and Ju Fan at Renmin University present SkillAdam, which ports Adam's two moment estimates to the optimization of discrete, non-differentiable skill documents so that skill self-evolution stops oscillating.
PARSER: Read in Parallel, Reason in Depth for Long-Context LLM Agents
Sequential memory agents read long documents one chunk at a time while carrying a compact memory state. That design ties reasoning depth to how far the agent has read, makes accuracy sensitive to where the evidence sits, and grows latency linearly with document length. PARSER separates reading from reasoning.
Elastic Horizon: Discovering the Effective Interaction Frontier in Agentic Reinforcement Learning
Gangyi Zhang in the Qwen Business Unit of Alibaba with USTC collaborators propose the effective interaction frontier hypothesis and Elastic Horizon, a closed-loop controller that sets an agent's interaction budget from the 90th percentile of successful trajectory lengths instead of a hand-set maximum.
MemForest: Efficient Agent Memory Management via EventTree Partitioning and Progressive Merging
Junxi Wang and collaborators across Shanghai Jiao Tong University, Fudan, Nanjing University, HIT and Sichuan University present MemForest, a memory compression layer that partitions history into event units, merges redundant nodes along a maximum spanning tree, and retrieves by propagating from anchor nodes.
Q2D-Web: A Large-Scale Benchmark for Retrieval in Agentic RAG Systems
Maximilian Schall, Sedigheh Eslami, Antoine Chaffin and colleagues at Perplexity AI release Q2D-Web, a 190M-document web corpus with 70k agent-reformulated search queries in ten languages, built because production RAG retrievers serve machine-written queries and existing benchmarks test human-written ones.
SkillAlign: Aligning Skill Interfaces for LLM-based Agents
Shuo Ren, Xiaomian Kang and Jiajun Zhang at the Institute of Automation, Chinese Academy of Sciences argue that how a skill is exposed to an agent changes its value as much as which skill is chosen, and build SkillAlign to measure that by holding everything else fixed.
What Eviction Destroys: A Restore-Counterfactual Audit of Forgetting in Agent Memory
Chen Shen at Megagon Labs introduces the restore counterfactual, a per-question intervention that puts the gold evidence back into a reader's context after eviction, which separates losses eviction destroyed permanently from losses retrieval merely failed to surface.
Agentic ML Exploration (A-MLE) for Ads Ranking
A 38-author team at Meta Platforms reports Agentic ML Exploration, an autonomous LLM-agent system that runs the ML iteration cycle across a portfolio of production ads ranking models, and includes a controlled cross-LLM study of Claude Sonnet, Gemini and GPT families under a fixed agent loop.
Closing the Consistency Gap: Self-Evolving Agents That Learn to Stay on Course
Evelyn Duesterwald, Benjamin Elder, Lilian Ngweta, Shashanka Ubaru and Malgorzata Zimon at IBM Research name the consistency gap, the difference between an agent's average pass rate and how often it succeeds on all five repeats of the same task, and close part of it with targeted episodic memory.
Beyond Agent Harnesses: Cross-Substrate Authority for Multi-Agent Systems
Yang Li and Sergey Volkov at the University of Hong Kong with collaborators name the cross-substrate authority gap, where the fact that decides whether an action is safe lives in a runtime, registry or approval service that the planner cannot see, and show a deterministic execution-time check handles it where planner-side evidence does not.
Procedural Graphs: Self-Evolving Execution Structures for LLM Agents
Long-horizon agents usually pick each action by generating over a growing history, which leaves the procedural knowledge of what to do next, in what order, and under which conditions implicit. As trajectories get longer they lose track of objectives, call tools out of order, and repeat actions that already failed. Researchers at Google make that knowledge an explicit graph the agent can query.
AttnCompress: Dynamic Attention-Guided Trajectory Compression for Software Engineering Agents
Zhengran Zeng and Yixin Li at Peking University present AttnCompress, which segments an agent trajectory at perplexity spikes, scores each historical block by proxy attention weight against the agent's current reasoning, and recalls blocks back into context as the task changes.
NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness
The NeoHorse Team releases NeoHorse-1, a family of agent-native 4B and 9B models built on an agentic post-training loop in which a router's records of predicted capability demand and selected service tier become the training data for the next round.