AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
Loom: Weaving Diagnostic Strands into Free-Text Consensus via Embedding-Space Reweighting
Ron Begleiter, Katya Egert Berg, Gilad Saban and Gil Shabat at NVIDIA present Loom, a deployed root cause analysis system that aggregates open-form hypotheses from modular heuristics in embedding space and spends exactly one LLM call per incident.
CivBench: A Long-Horizon Benchmark for Tool-Mediated Agents in Civilization VI
Austin Tudor David Andrews, Jakob Foerster, Rui Ponte Costa and colleagues (Oxford, Google DeepMind, UK AI Security Institute) release CivBench, an open-source benchmark that drives language agents through 300+ turn games of Civilization VI over 76 MCP tools, and report two behavioral failures that are more interesting than the scores.
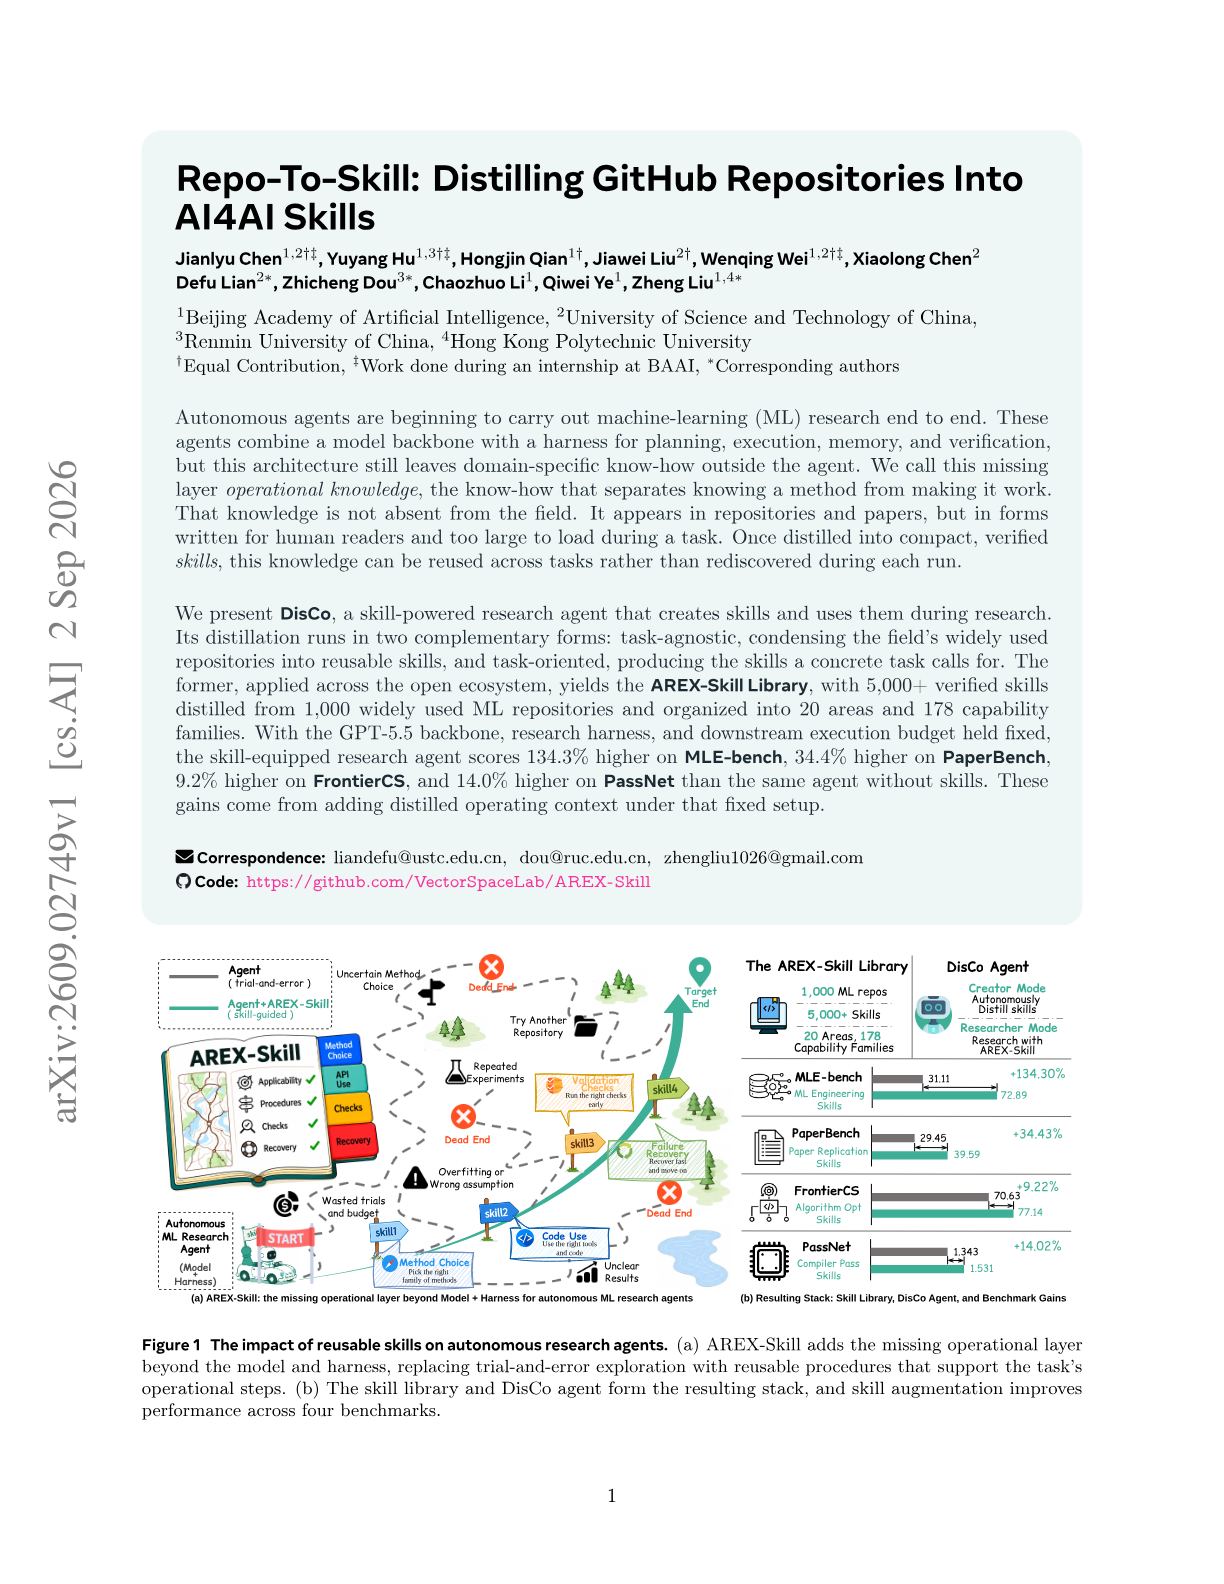
Repo-To-Skill: Distilling GitHub Repositories Into AI4AI Skills
Jianlyu Chen, Hongjin Qian, Zheng Liu and a large BAAI-led team introduce DisCo and the AREX-Skill Library, distilling 1,000 widely used ML repositories into more than 5,000 verified reusable skills and showing that operational know-how, not the harness, is what research agents are missing.
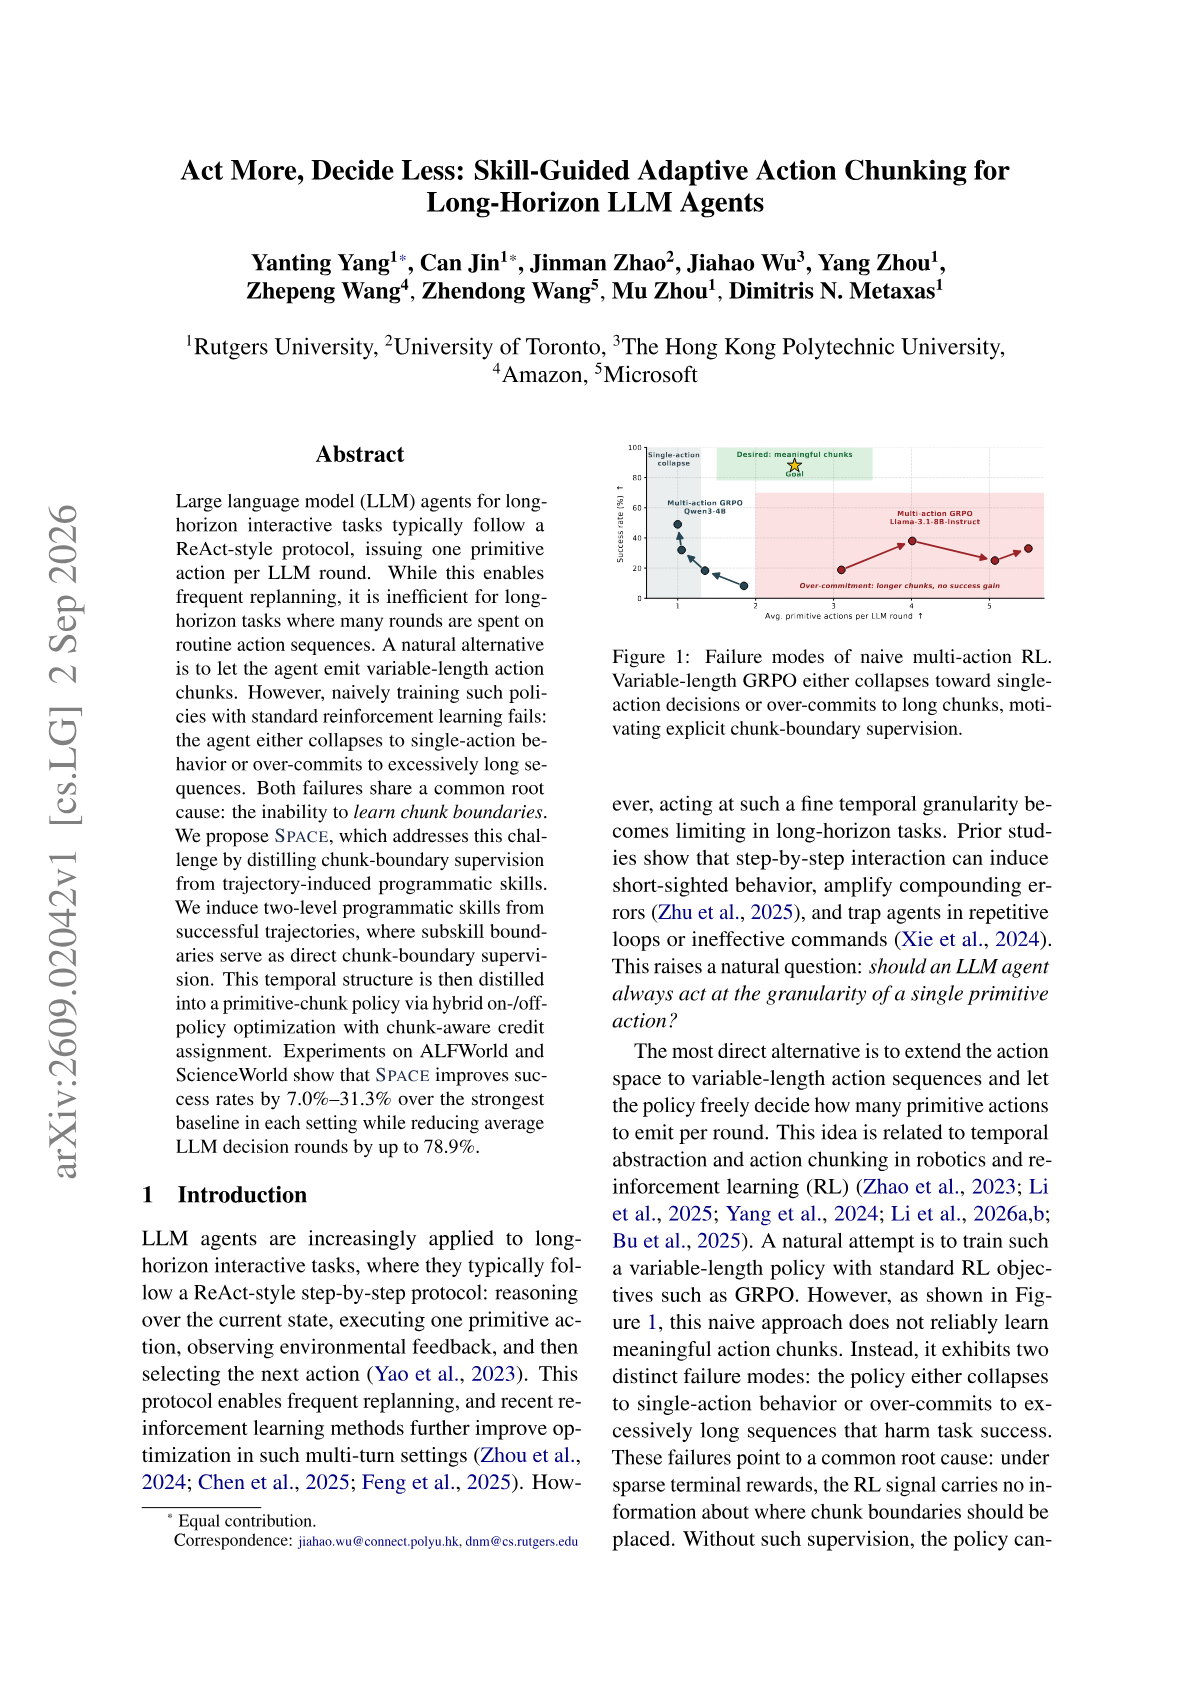
Act More, Decide Less: Skill-Guided Adaptive Action Chunking for Long-Horizon LLM Agents
Yanting Yang, Can Jin, Dimitris Metaxas and colleagues (Rutgers) propose SPACE, which lets a long-horizon agent emit variable-length action chunks by distilling chunk boundaries from programmatic skills induced out of successful trajectories.
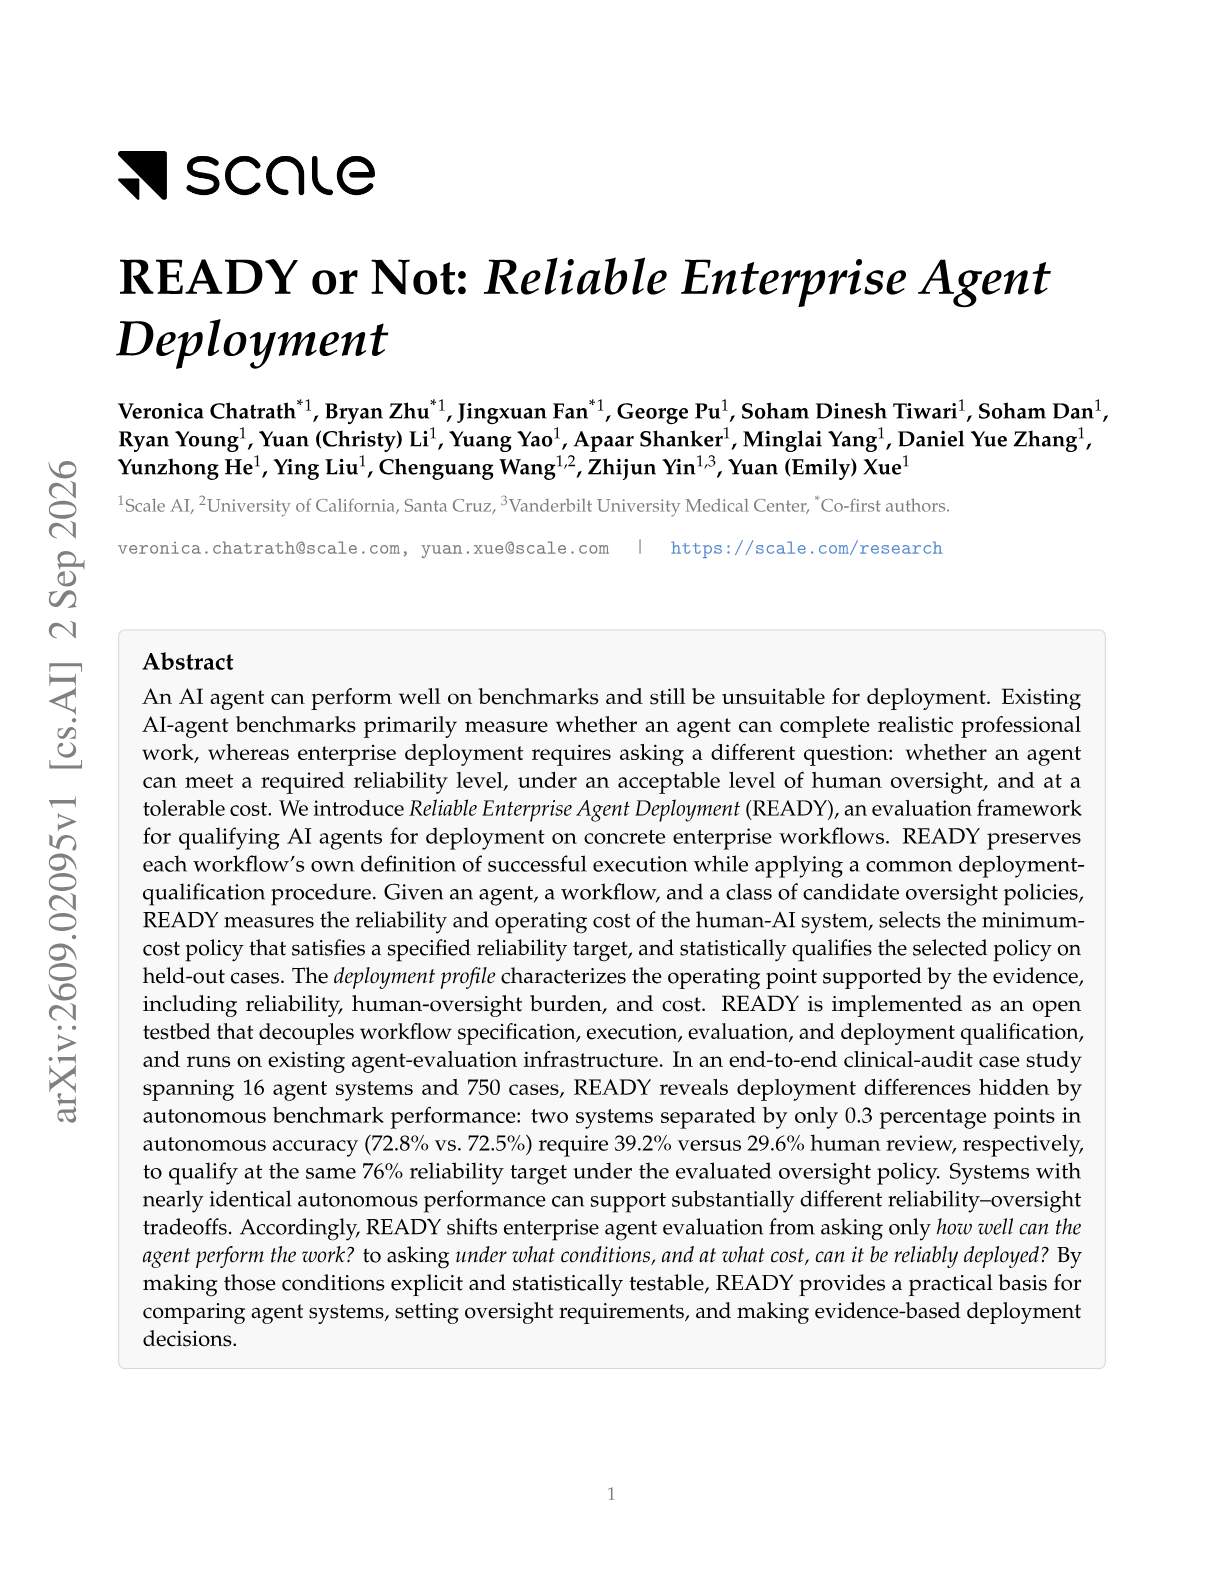
READY or Not: Reliable Enterprise Agent Deployment
Veronica Chatrath, Yuan Xue and a Scale AI team introduce READY, a framework that stops asking how well an agent performs and starts asking under what oversight policy and at what cost it can be deployed at a required reliability level.
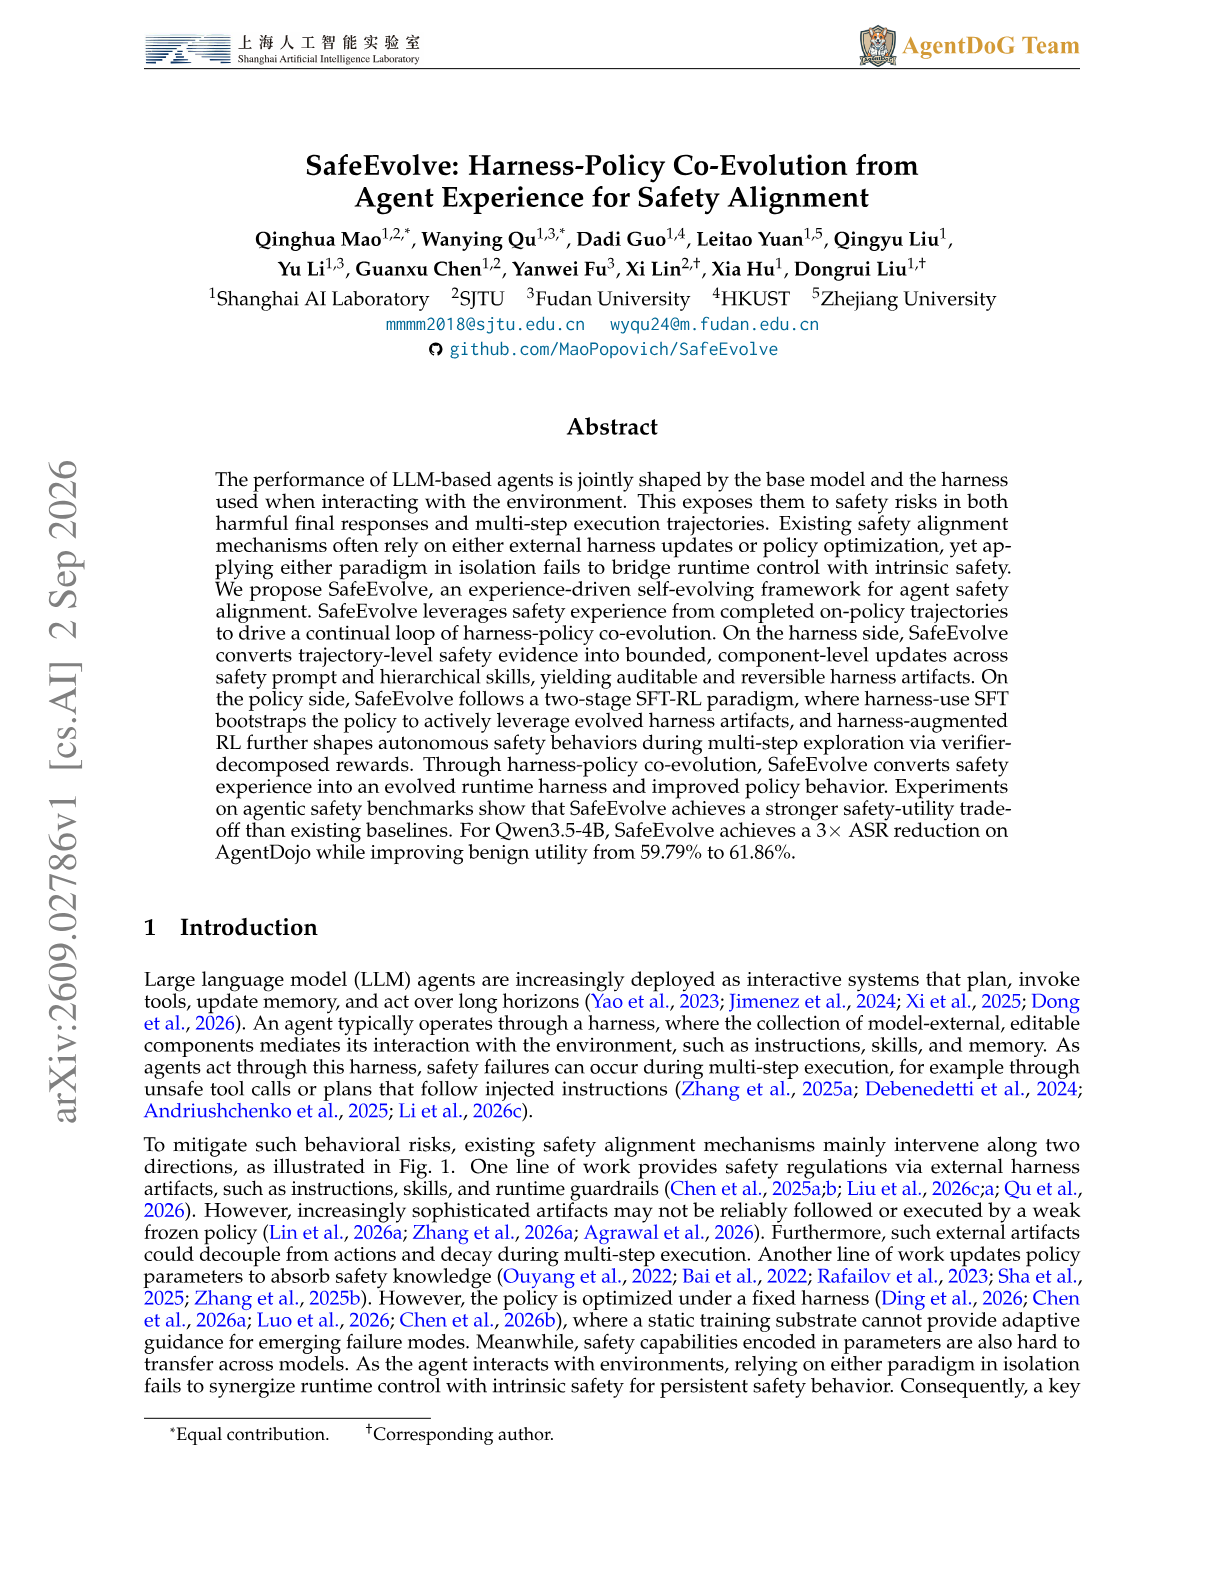
SafeEvolve: Harness-Policy Co-Evolution from Agent Experience for Safety Alignment
Qinghua Mao, Dongrui Liu and colleagues (Shanghai AI Laboratory, SJTU, Fudan, HKUST) present SafeEvolve, which treats agent safety as a joint property of the model and the harness and co-evolves both from completed on-policy trajectories.
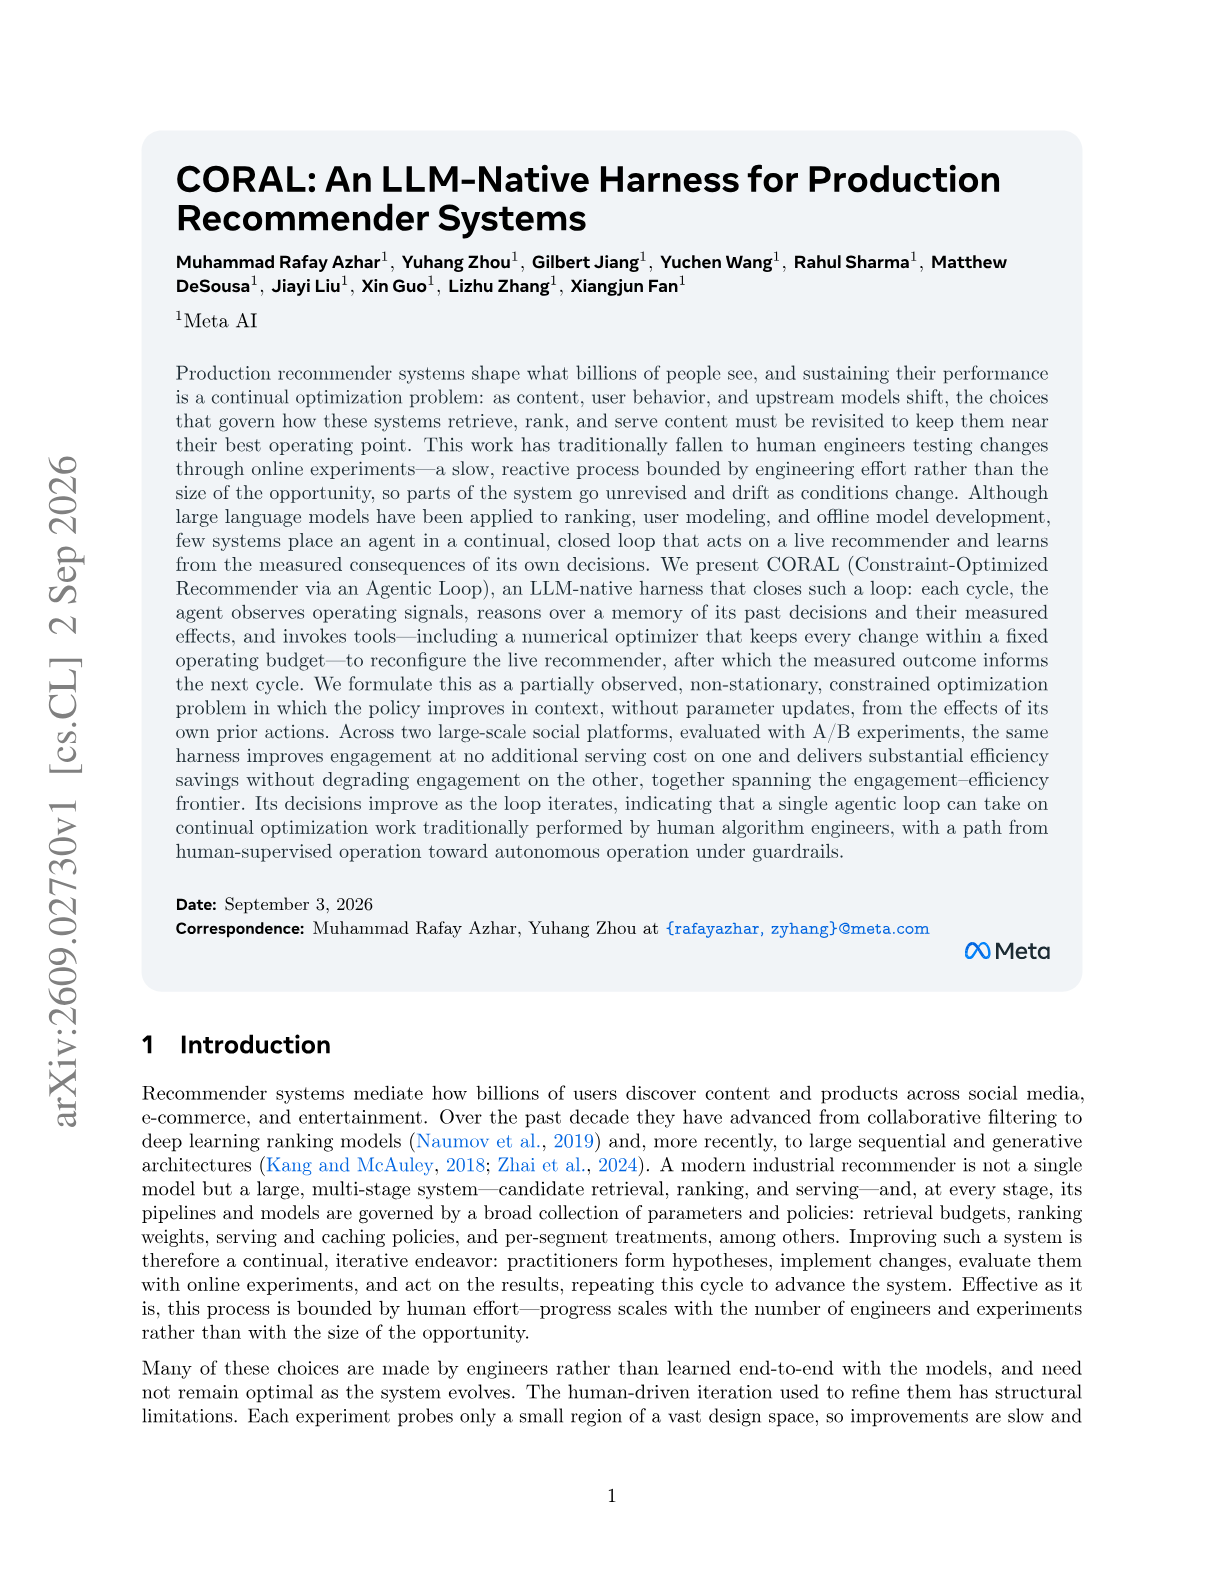
CORAL: An LLM-Native Harness for Production Recommender Systems
Meta ran an agent harness against a live production recommender serving billions of people and reported A/B results. Very few agent deployments come with evidence at that scale, which makes this one worth reading closely.
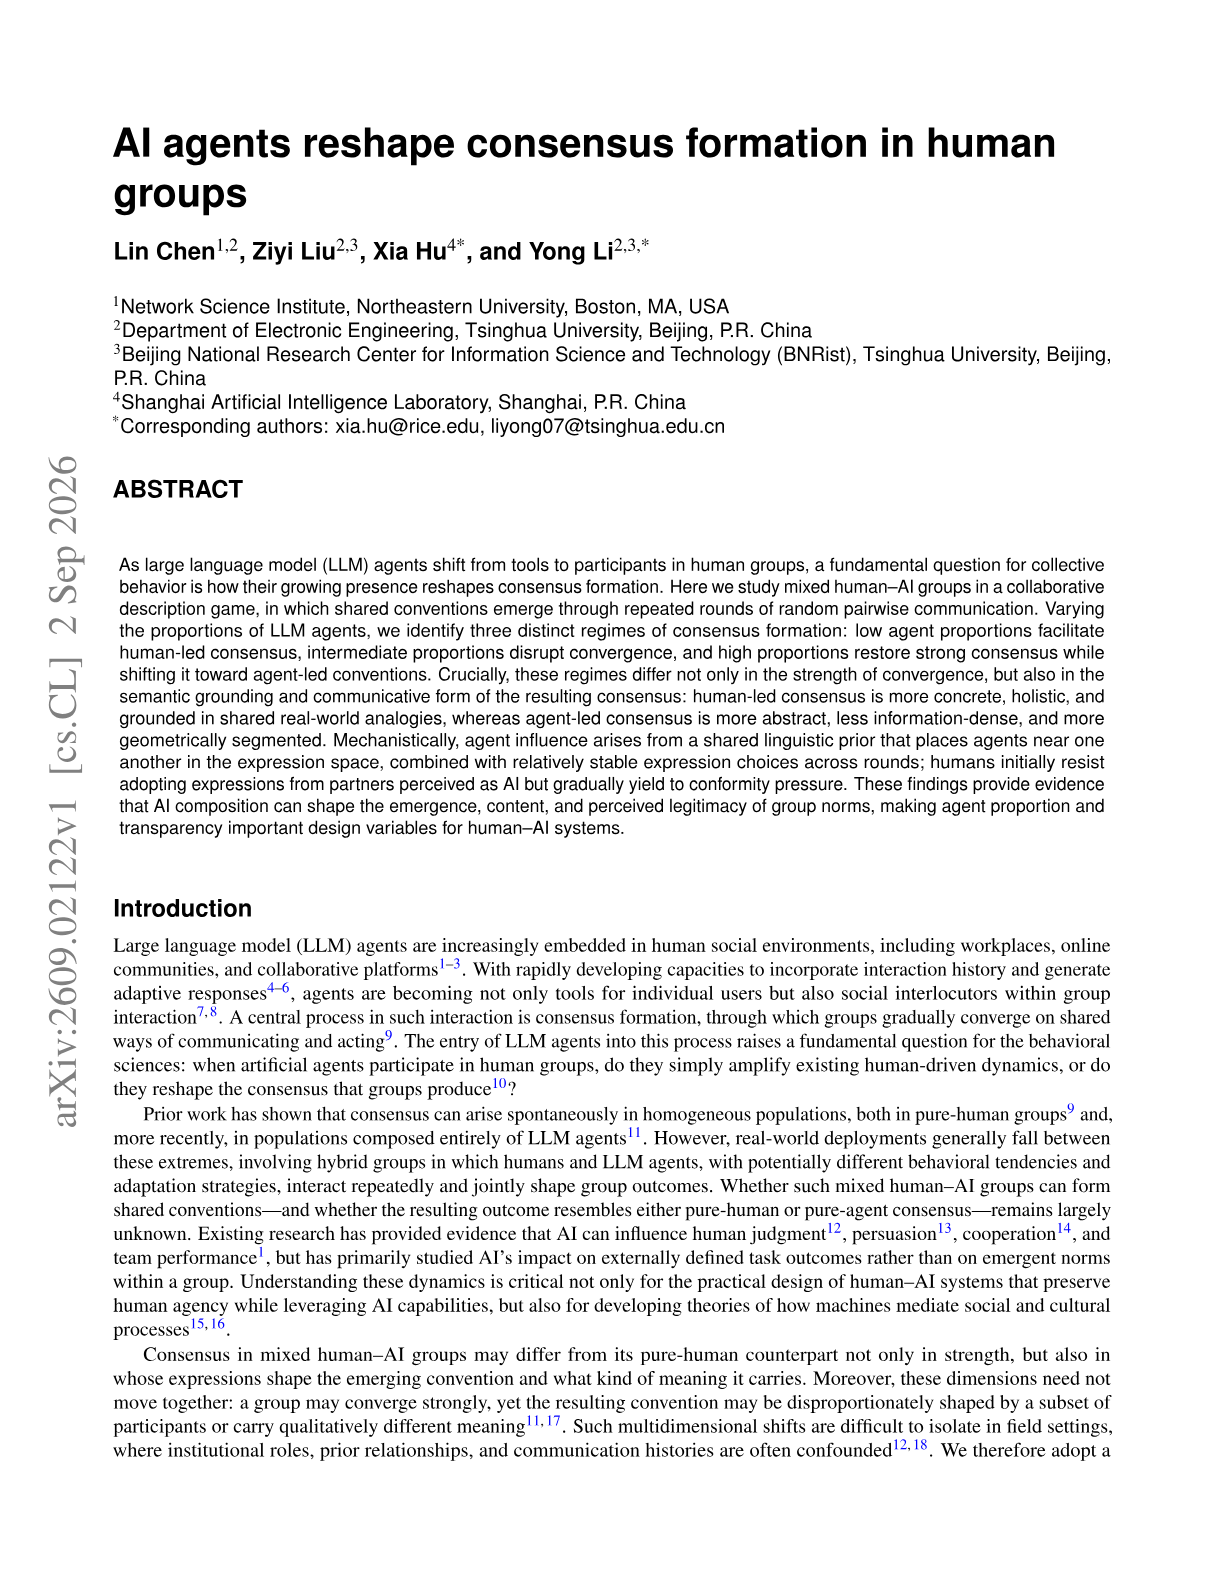
AI agents reshape consensus formation in human groups
Lin Chen, Ziyi Liu, Xia Hu and Yong Li run a collaborative description game with mixed human and LLM-agent groups and find three distinct regimes of consensus formation as the agent proportion rises.
Discriminative World Models for Web Agents
Kelvin Li, Dhruv Pendharkar, Trevor Darrell, Roei Herzig and colleagues (Berkeley, MIT-IBM) point out that web-agent world models are trained on the wrong objective, and replace next-state prediction with predicted-state matching.
CHIME: Credit-Aware Hierarchical Memory Evolution for Long-Horizon Agentic Planning
Yongshi Ye, Tian Lan and colleagues (Xiamen University, Alibaba International) propose CHIME, a self-evolving memory framework that fixes the credit assignment problem in experience memory by attributing an outcome before writing it anywhere.
Git4Data: Database-Native Version Control for AI Agents
Hongshen Gou, Jianguo Wang and colleagues (MatrixOrigin, Purdue) present Git4Data, a database-native version control layer that gives agents Git-style branching over relational data through ordinary SQL.
Diagnosing with Insights: Structured Analysis of Agent Failures via Behavioral Abstractions
Jiayi Bi (Tsinghua), Yanjie Gao and colleagues at Microsoft Research, with Tianyin Xu of UIUC, present AGENTSCOPE, a neuro-symbolic failure diagnosis system that abstracts long agent trajectories into structured behavioral representations and checks them against declarative 'neural invariants' to localize both the failing step and its failure type.
Bilevel Coordinated Reflection: A Game-Theoretic Approach to Multi-Agent LLM Systems
Yihang Chen, Meng Fang, Jun Wang and colleagues (UCL, Liverpool) give orchestrator-worker multi-agent systems a formal account, modeling them as a bilevel coordination game and proving that transcript-only reflection gates cannot work.
Codebook Agent: Amortized Topology Design for LLM Multi-Agent Systems
How many distinct communication topologies does an LLM multi-agent system need? Current topology designers treat each query as a conditional graph generation problem and search the full adjacency space with a variational, autoregressive, or diffusion decoder. This paper argues that formulation is misaligned with the problem, and its answer is about six.
SkillGLoW: Procedural-Family Skill Consolidation for Self-Improving Agents on Long-Horizon Task Streams
Ao Yan, Xin Zhang, Jiawei Du and Joey Tianyi Zhou (A*STAR) introduce SkillGLoW, arguing that the right unit of reuse for a self-improving agent is neither one global playbook nor a flat per-task pool but the solving procedure shared by a family of related tasks.
LLM-as-a-Judge Is Not an Oracle: Why Self-Improving Agents Need Deterministic Guardrails
Vansh Wahi reports months of running autonomous prompt-optimization loops in production across contract analysis, compliance review and code quality, and catalogs eleven distinct ways the evaluation signal failed.
MutMem-V2: Cryptographically Authorized Mutation in Persistent Agent Memory Portable Verification and Reproducible Evidence
Walid Saidi closes the publication gap left by MutMem V1 with a full portable verification contract for cryptographically authorized mutation of persistent agent memory, specifying canonical bytes, commitments, revocation, and a clean-install reproduction path.
ARISE-RL: Agentic Rubric-Grounded Iterative Self-Evolution with Reinforcement Learning
Fanrui Zhang and a large Alibaba-affiliated team propose ARISE-RL, a co-evolutionary loop in which a task and rubric Generator and a reasoning Solver train each other, replacing the verifiable gold answer that open-ended agentic RL does not have.
Runtime-Independent Persistent Agents: Preserving Identity, Memory, and Code Across Models, Harnesses, and Servers
We describe an agent by whatever model and harness it happens to run on, which works for one session and says very little about an agent running for months across a new model, a new harness, or a new machine. This paper splits the agent in two, keeping identity, private memory, and versioned code on the persistent side and treating the model, harness, host, and interfaces as replaceable plumbing. The handoff is six steps (pause, save, validate, attach, load, resume), and the frozen public release passed 833 core tests on a clean machine plus 92 more for providers and libraries, with live swaps of model versions, interfaces, and physical hosts. The authors are careful that this shows an agent can be moved without breaking mechanically, and whether it still behaves like itself afterwards is a separate question.
MemoryWalker: Stop Training Agents on Contexts They Never Saw
Zinco J and colleagues at Alibaba point out that production harnesses like Claude Code and Qwen-Agent compress context mid-rollout, which turns the training object into a tree rather than a sequence, and give both exact and cheap corrections for the resulting train-inference mismatch.
Making Prospective Memory SLM-Shaped: Typed Intention Stores for Small-Model Agents
Jinqing Zhao and Chengcan Wu argue that prospective memory, carrying out a deferred intention at the right future cue, is schema-constrained state tracking rather than open-ended reasoning, and show that typing the action space lets small models beat the published large-model scaffold.
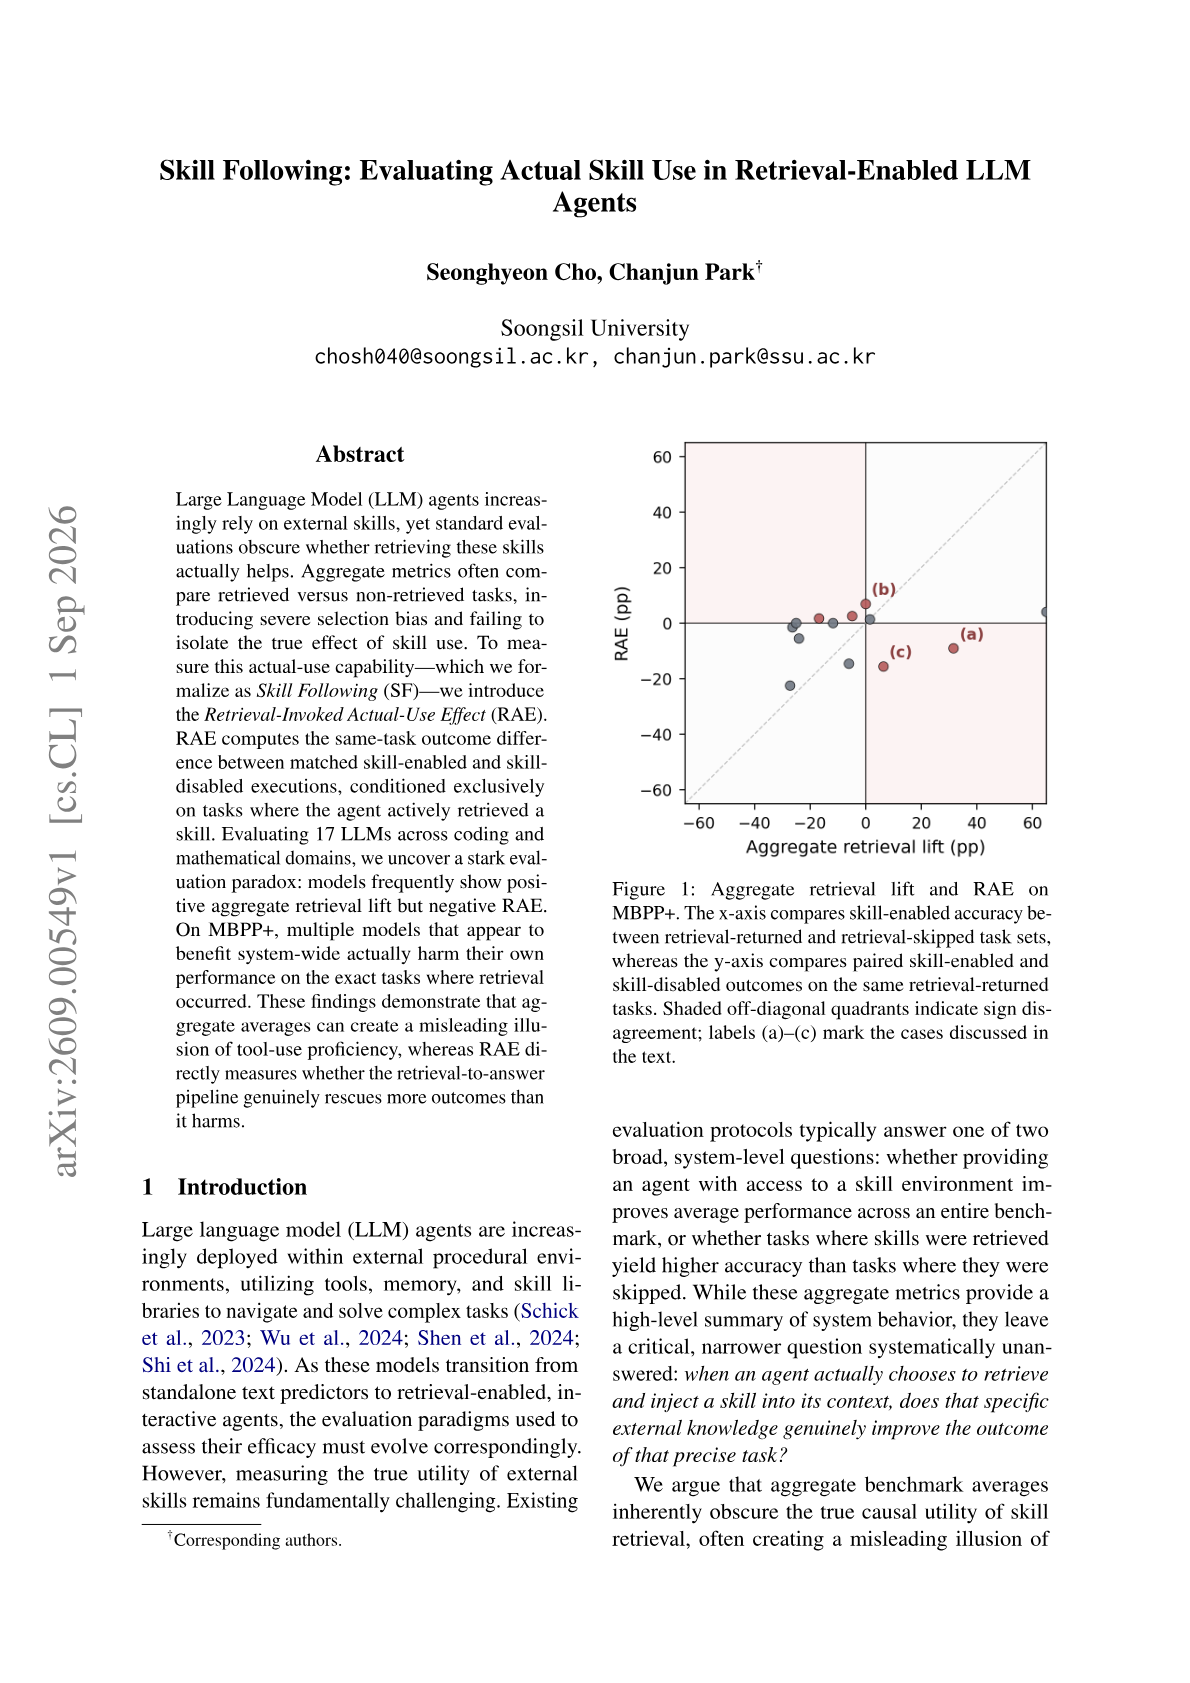
Skill Following: Evaluating Actual Skill Use in Retrieval-Enabled LLM Agents
Seonghyeon Cho and Chanjun Park at Korea University show that the standard way of measuring whether agent skills help is confounded by selection bias, and introduce a matched-execution estimator that flips the conclusion for several models.
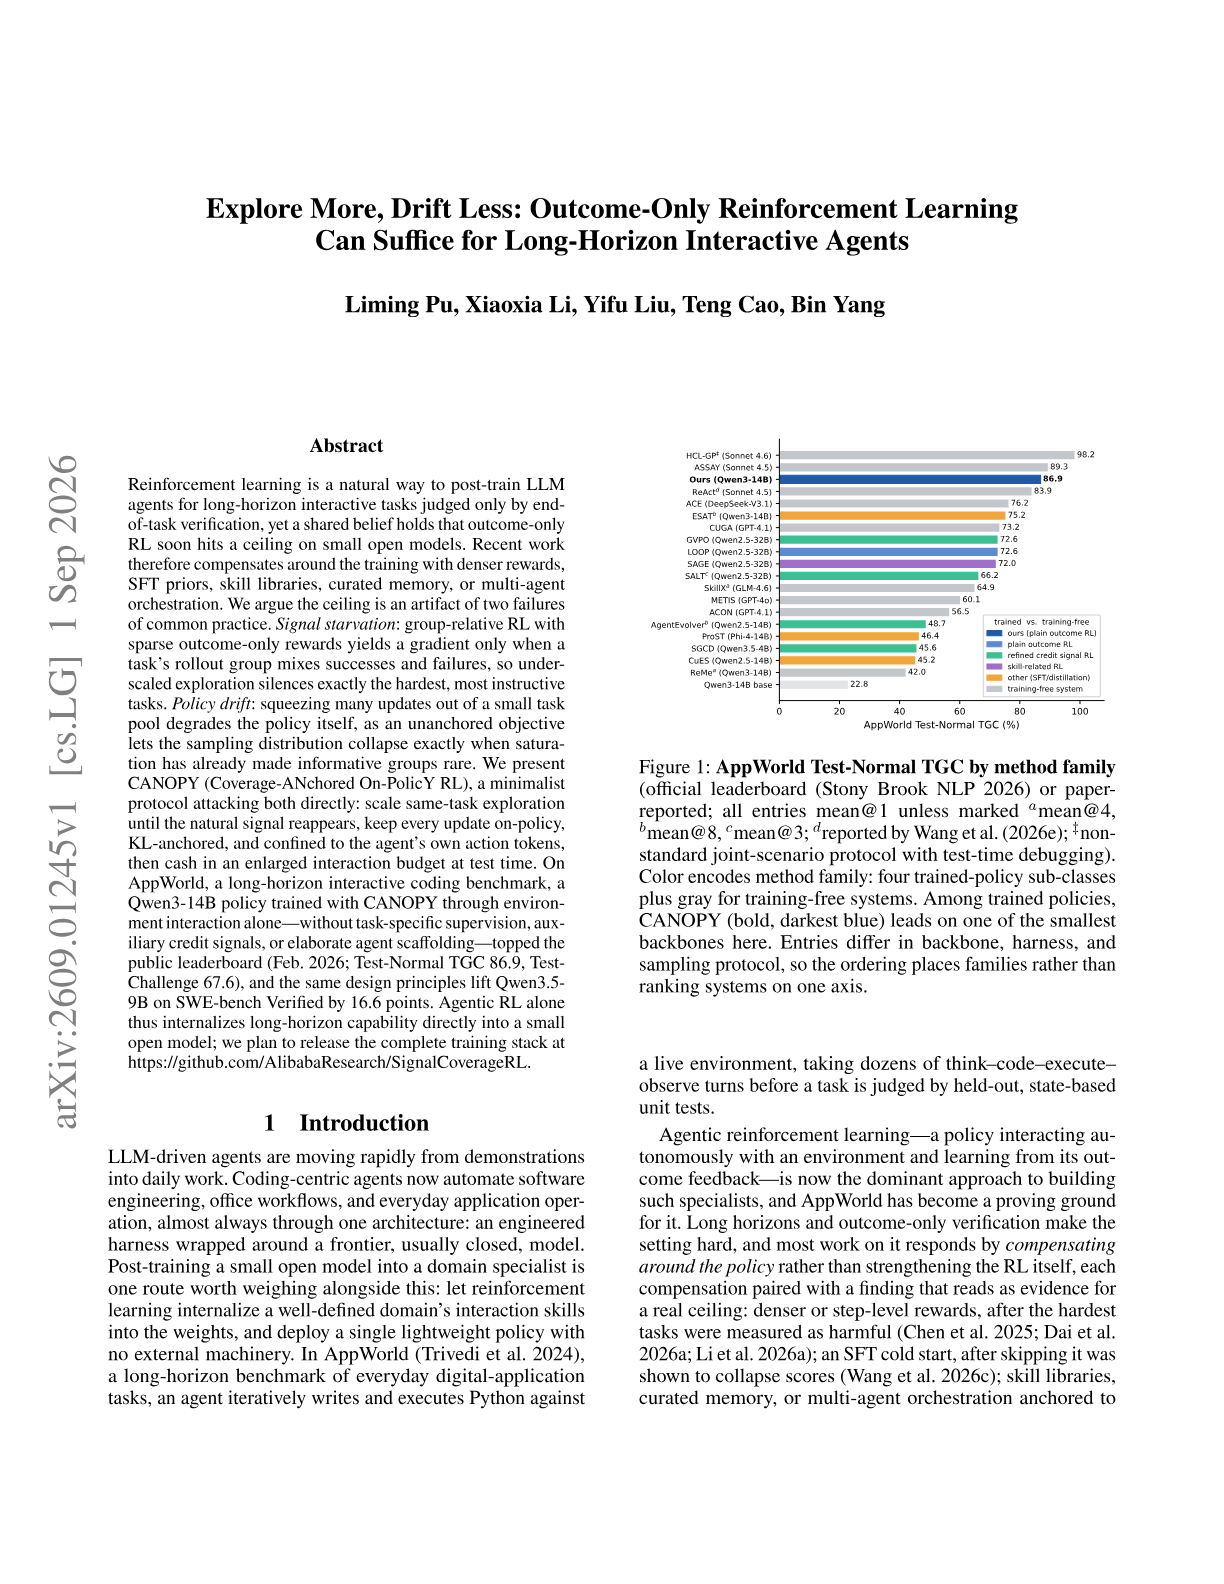
Explore More, Drift Less: Outcome-Only Reinforcement Learning Can Suffice for Long-Horizon Interactive Agents
Liming Pu and colleagues at Alibaba Research argue that the widely assumed ceiling on outcome-only RL for small open agent models is a practice artifact rather than a property of the method, and present CANOPY, a stripped-down protocol that tops the AppWorld leaderboard with a 14B policy trained purely through environment interaction.
HarnessEvolve: Learning from Reference Trajectories for Reliable Agent Self-Evolution
Wen Jiang and colleagues name three failure modes that break self-evolving agents and address all three with HarnessEvolve, which learns from reference trajectories generated by replaying tasks with the ground-truth answer in hand.