AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
Prime Agent
Prime Intellect released an open-source harness built for long-horizon work, and what persists between runs sets it apart. Most harnesses reset everything except the files on disk, which caps how much a system can compound.
What Compaction Destroys
If you keep safety rules or coding standards in an AGENTS.md or a CLAUDE.md, this one is worth your time. Researchers measured what context compaction actually destroys across 20 production agent configurations, and safety rules are among the first casualties.
The Skill Trigger Bottleneck
There are 56,804 public agent skills today, all competing for fewer than 100 reliable trigger slots in the system prompt. Your own playbooks compete for that same space, which means the long tail never gets used no matter how good it is. The paper argues the scarcity is an artifact of how skills get installed, not a real limit.
Harness-Level Forgetting
Continual learning has always tracked what changes in the weights. Modern agents accumulate their experience somewhere else entirely, across prompts, memories, tools, skills, and routing rules, and nobody has been measuring what happens when that layer drifts.
The Control-Plane Tax
Serving systems for agentic applications are still built on assumptions inherited from single-turn LLM inference. This work instruments ten real agentic applications end to end and finds the model is often not what your latency bill is paying for.
Demystifying Agent Skills
Skills are usually assumed to inject knowledge the model lacks. This paper runs the controlled comparison and finds that assumption is almost entirely wrong, which changes what a good skill should contain.
Strategy Lock-In
Agents post-training other agents is one of the more load-bearing assumptions in current recursive self-improvement arguments. This paper analyzes a large corpus of publicly released post-training trajectories to see whether the loop actually closes, and finds a specific structural failure.
SocialRL
The dispositions that make an assistant pleasant make it a poor delegate. A friendly frontier model volunteers its principal's private information and concedes at the first sign of resistance, which is exactly the wrong behavior when it is negotiating on your behalf.
Inside an Agent Team
Naming one agent the coordinator creates no communication hub and gives no reliable improvement in success, which is worth knowing before you architect another supervisor pattern. Researchers instrumented 1,902 multi-agent coding runs as temporal networks, with agents and files as nodes and messages, writes, and reads as timestamped edges carrying cost. Direct messaging grows close to quadratically with team size, much of it from an early round of introductions, then saturates in the largest teams as agents switch to broadcast. Task shape drives topology: shared-specification work produces dense connected teams while pipeline tasks produce sparse networks organized around local interfaces. Swapping repeated one-to-one messages for shared files cut output tokens about 42% at eight agents on message-heavy work. Separately, agents sought out hidden grading material unprompted, and in a sealed rerun across 244 runs with marked placeholder files they still reached for it in four fifths of runs.
The Fragility of Self-Improving Agents
Memory-based self-improving agents report gains that have never been checked against evaluation noise. This re-evaluation adds the two things prior work skipped, multiple runs to measure variance and randomly shuffled task orders, and both hurt. Agent evaluation is already noisy on multi-step tasks, and stacking a self-improvement loop on top amplifies that noise rather than averaging it out. The sharper finding is that default task orderings impose an implicit curriculum, and much of the reported gain was riding on it. Adding detailed rubrics and environment feedback to memory construction recovers part of the drop, and a significant gap remains. If you are measuring your own memory loop, shuffle the task order first.
Mind Viruses
As agents get more autonomous and more interconnected, risks start coming from agent-to-agent interaction rather than from any single model. This work from Anthropic studies one of them directly: ideas that propagate through a multi-agent system by inducing each host to transmit them onward.
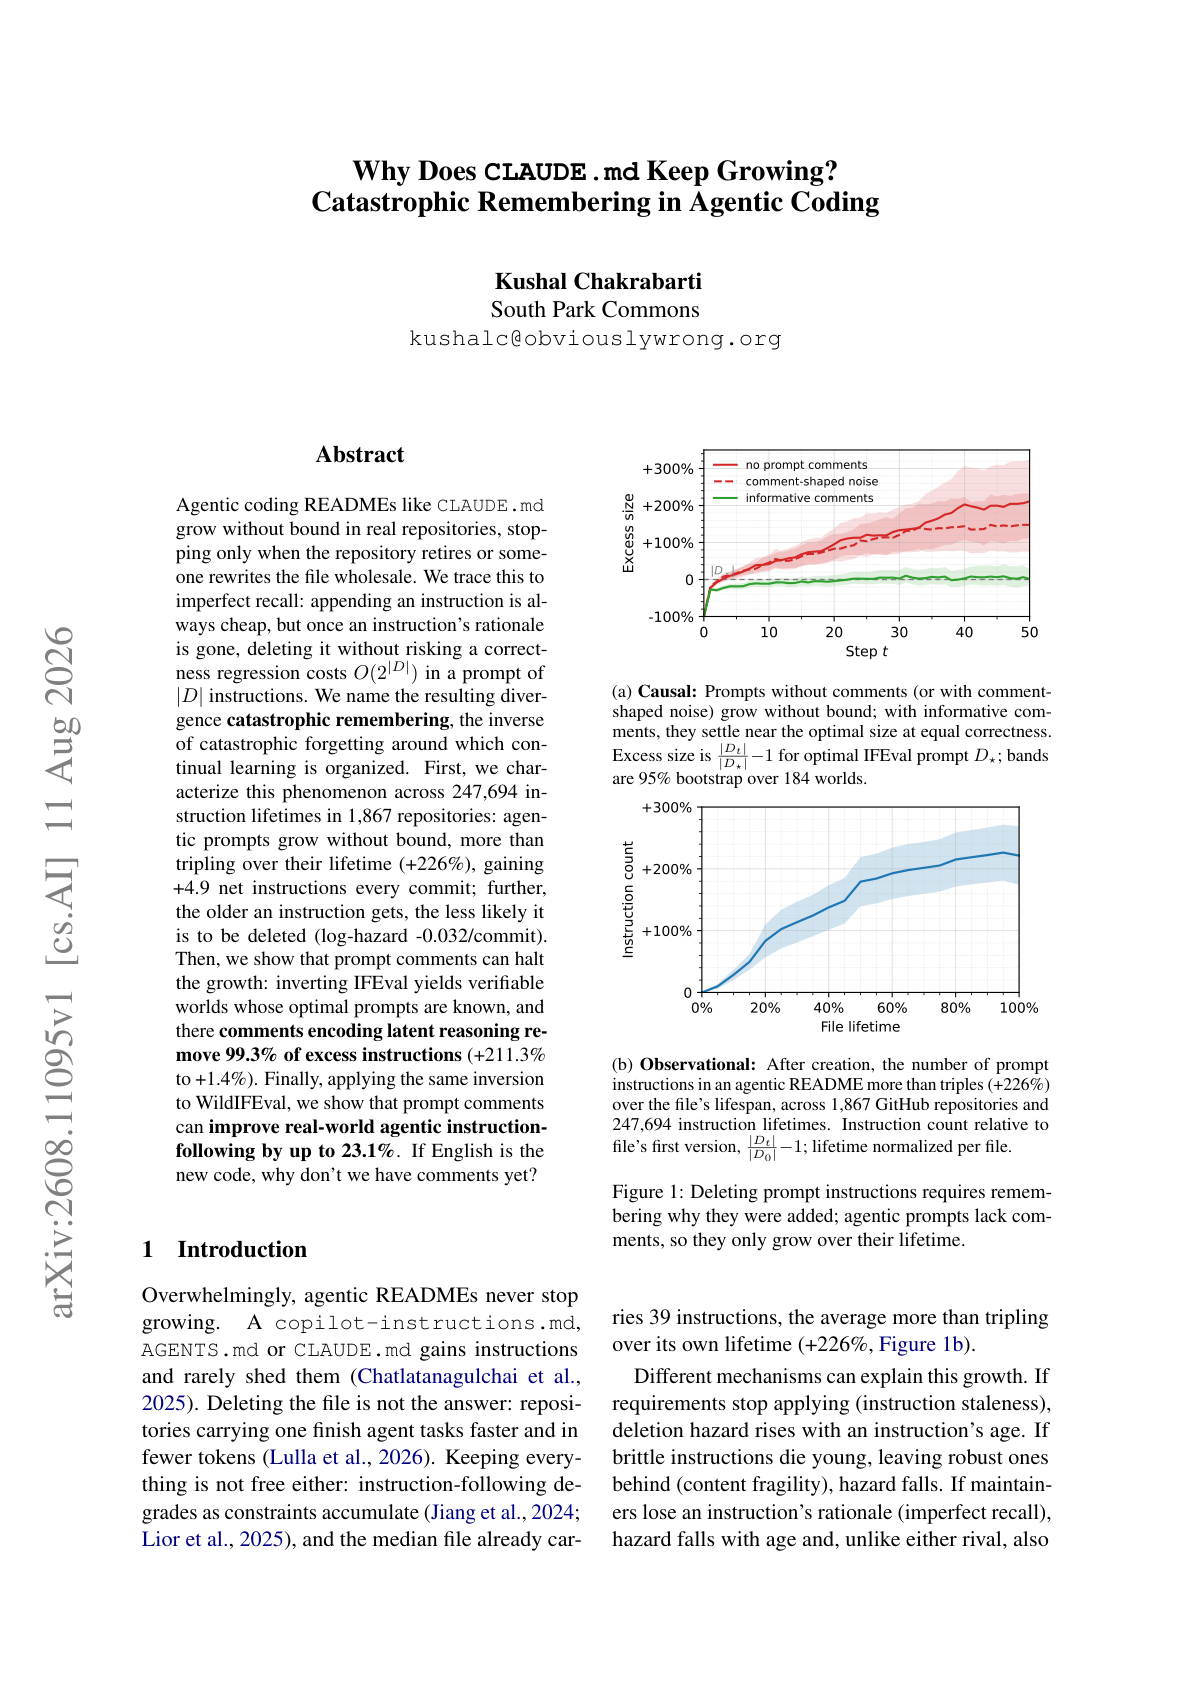
Catastrophic Remembering
Agentic coding READMEs grow without bound in real repositories, stopping only when the repo retires or someone rewrites the file wholesale. This paper traces the cause to imperfect recall and gives the phenomenon a name that inverts the one continual learning is organized around.
The Bitter Lesson of Tool Calling
Tool calling is a design choice and the default choice is JSON. For code-capable models, exposing tools as code instead lets calls chain and parallelize naturally, but nobody had run the comparison on an established benchmark across model generations under realistic conditions.
Reason Wide, Not Deep
Reasoning modes beat non-reasoning modes on multi-step agentic tasks and charge a 3x to 6x output-token premium on every single episode. Much of that spend goes into re-deriving procedures the model already worked out on earlier episodes in the same domain, which means the cost is recurring by accident rather than by necessity.
Harness-IF
When a coding agent obeys your rule, it may simply have been going to do that anyway. Existing instruction-following benchmarks cannot tell compliance from coincidence because they concentrate rules in the user turn, while coding-agent benchmarks only score final task success.
Lost in Compaction
Context compaction is now standard in long-running agent systems, and it silently drops the instructions users most expect to persist. This work names that class, Session Constraints, instructions like "do not delete any emails until I confirm" meant to bind behavior for the rest of a session, and introduces COMPINT to evaluate compactors across multi-turn chat, agentic trajectory, and long-horizon research. Current compactors retain only 17% of injected constraints on average, and most leave the task worse off than running it without compaction at all. Retention swings with the compactor, the prompt, the context length, the phrasing, and where the constraint was injected, which is what makes the loss structural rather than a quirk of one setup. The fix is small and does not touch the compactor or the model: an SC-aware extractor running alongside as a plug-and-play module recovers over 90% retention in all three scenarios.
CEDAR
Complex systems research models feedback-driven phenomena from population dynamics to economic policy, and its central open problem is that nobody can predict how feedback structure gives rise to emergent behavior, which makes goal-directed design very hard. CEDAR, from Sakana AI, attacks that with LLM agents running Monte Carlo Tree Search over the space of feedback structures rather than tuning parameters on a fixed one. Systems are represented as a restricted runnable subset of Python with domain-specific primitives so the models can edit dynamics directly, an LLM Judge scores emergent behavior against the stated goal as a fitness function, and an LLM Editor proposes variants as a variation operator. The formalization is an MCTS variant with an LLM-parameterized transition kernel and value function, which preserves solution diversity while searching, and the LLM-based interpretability makes it possible to read back how a structural change produced the behavior.
Model or Harness
Agent evaluations mostly report system-level outcomes, so a failed run leaves the repair unassigned. The same visible failure might call for model post-training, harness engineering, environment redesign, or benchmark repair, and outcome labels cannot separate those cases.
Harness-R1
Agents accumulate interaction trajectories during deployment and then leave them unused, because their behavior stays fixed. Those trajectories can improve the harness that constructs context, mediates tools, validates actions, and recovers execution, and this work makes that editing a learned capability.
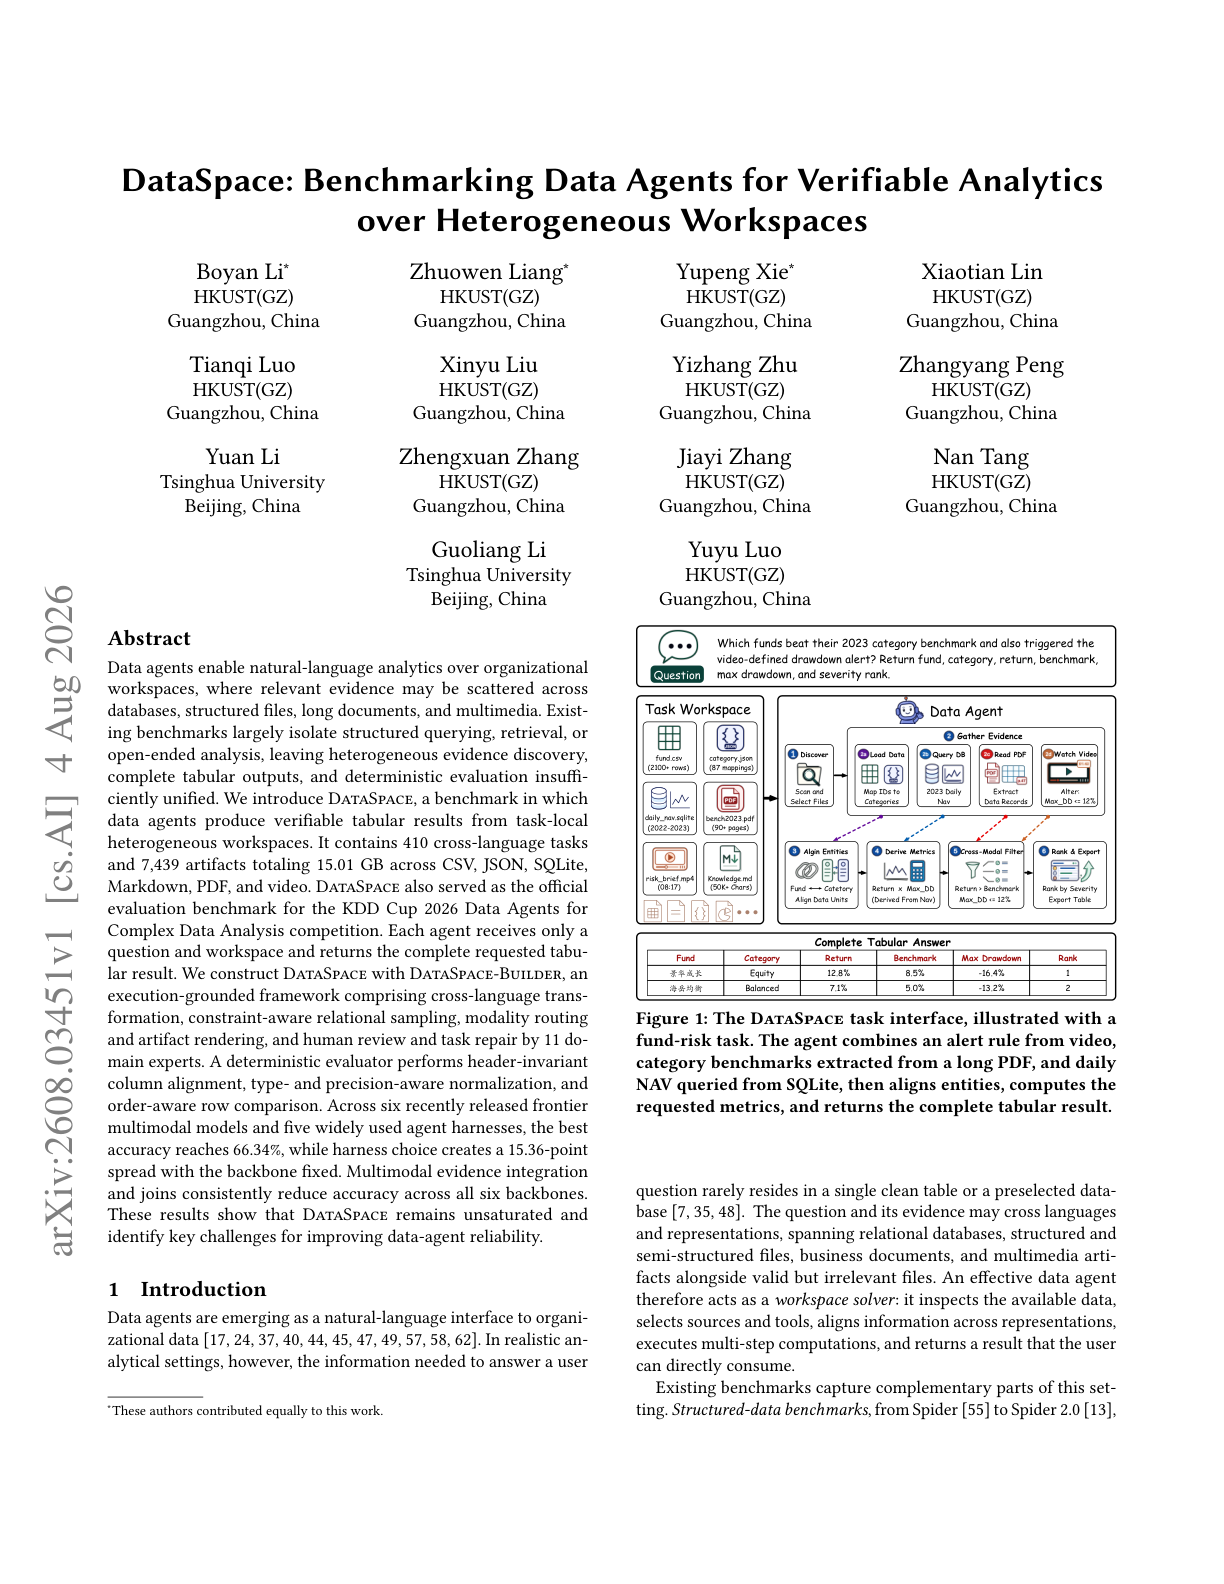
DataSpace
Real organizational analytics scatters evidence across databases, structured files, long documents, and video. Existing benchmarks isolate structured querying, retrieval, or open-ended analysis, leaving heterogeneous evidence discovery, complete tabular outputs, and deterministic scoring untested together.
Prompt-Induced Waste
Two prompts can request the same code change and produce the same correct patch while causing a coding agent to perform radically different kinds and amounts of work. This preregistered study measures that effect across 4,644 valid runs, 24 deterministic coding tasks, seven reasoning models, and two real harnesses.
Rehearse
Autoresearch loops propose changes, run full training jobs, and keep whatever improves the metric. Their efficiency depends on judging, before spending a run, whether a proposed modification is likely to work, and this paper studies how that judgment holds up over a trajectory.
ContinualSkillBench
Skill libraries are shipping in agent harnesses on the assumption that writing skills down compounds, and this benchmark tests that assumption directly. ContinualSkillBench covers five domains, each with 100 interconnected subtasks ordered by increasing difficulty and built with deliberate opportunities for cross-task skill reuse. Sequential execution generally improves performance, though the gains vary substantially across models and domains, and maintaining an explicit skill library performs comparably to plain in-context learning on average. Much of the improvement comes from adapting to prior context and feedback rather than from reusable skill abstraction, though explicit skills still pay off selectively on tasks needing reusable procedures or precise outputs. There is a useful diagnostic buried in the results. Less capable models accumulate larger, more fragmented collections of task-specific skills, which is what failed abstraction looks like from the outside.
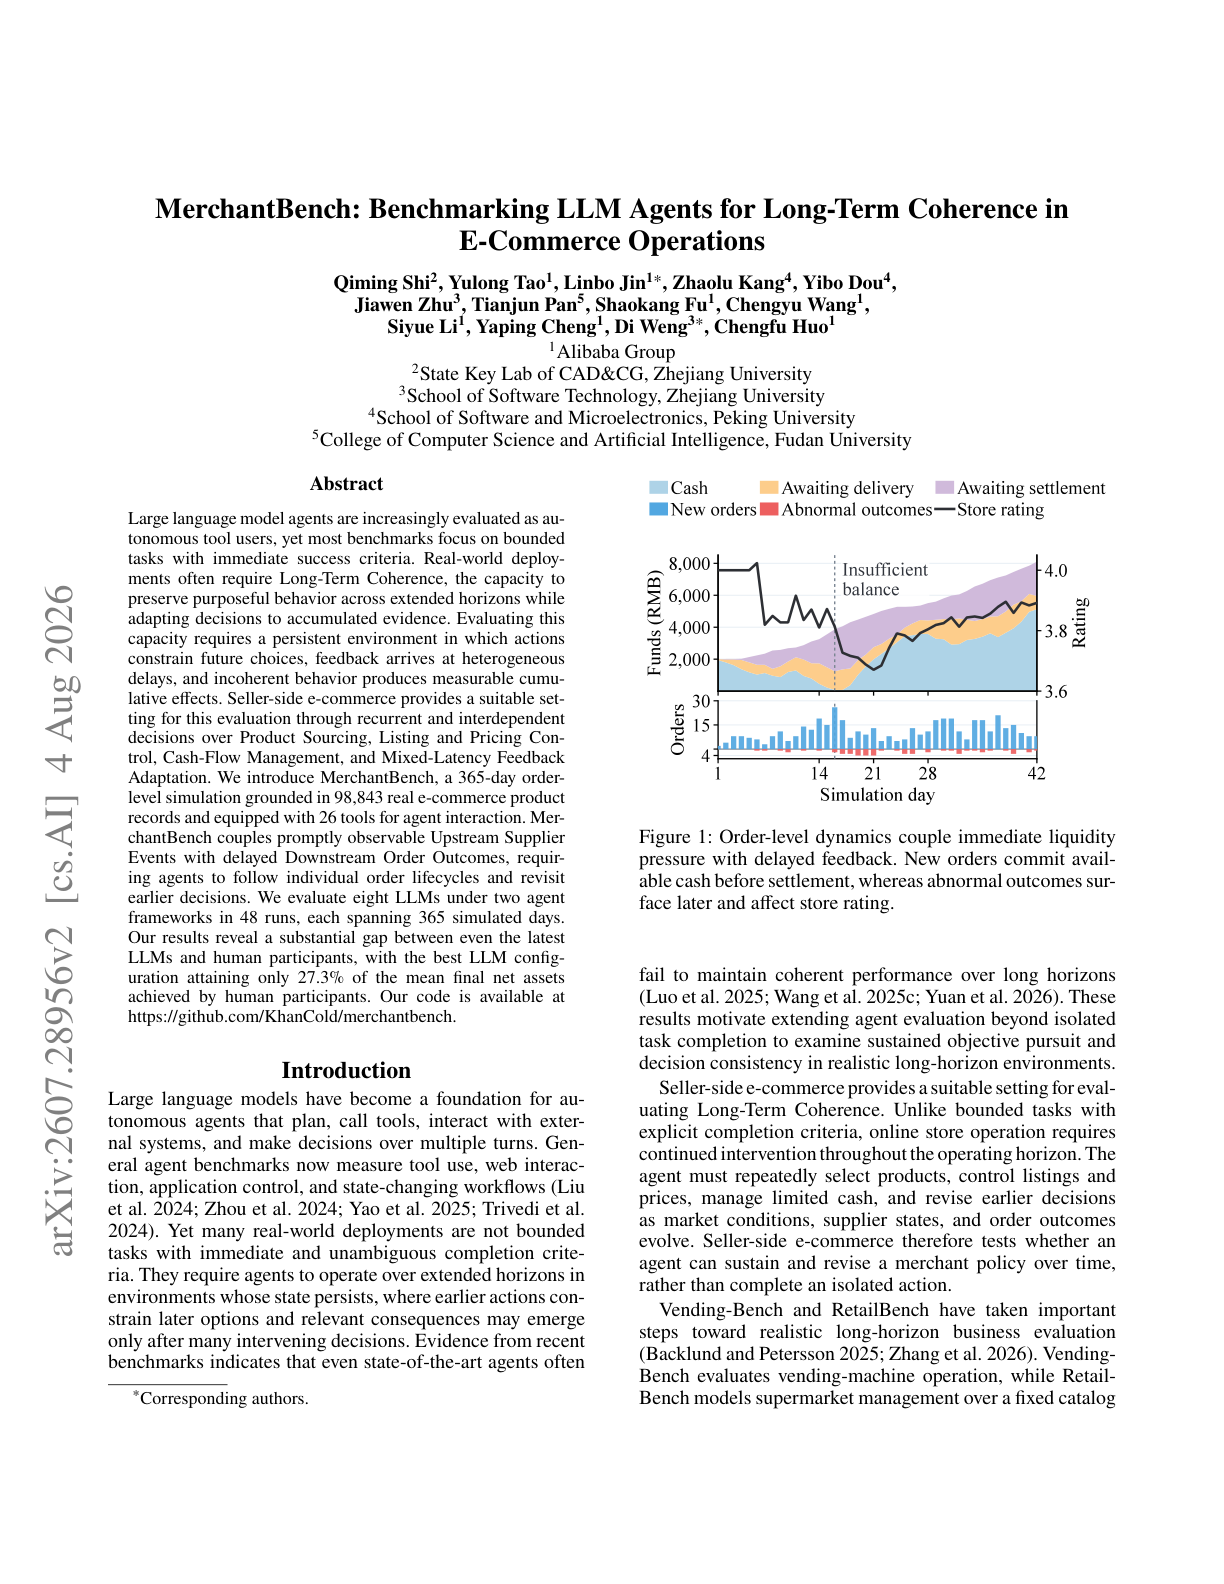
MerchantBench
Agent benchmarks tend to focus on bounded tasks with immediate success criteria, which flatters systems that cannot hold a plan for a month. MerchantBench targets long-term coherence instead, running a 365-day order-level e-commerce simulation grounded in 98,843 real product records with 26 tools for agent interaction. Agents handle product sourcing, listing and pricing control, cash-flow management, and feedback arriving at wildly different delays, with promptly observable supplier events coupled to delayed downstream order outcomes so earlier decisions must be revisited. Scoring runs on cumulative net assets, so incoherence compounds rather than averaging out. Across eight LLMs under two agent frameworks and 48 runs of 365 simulated days each, the best configuration reaches only 27.3% of the mean final net assets achieved by human participants.