AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup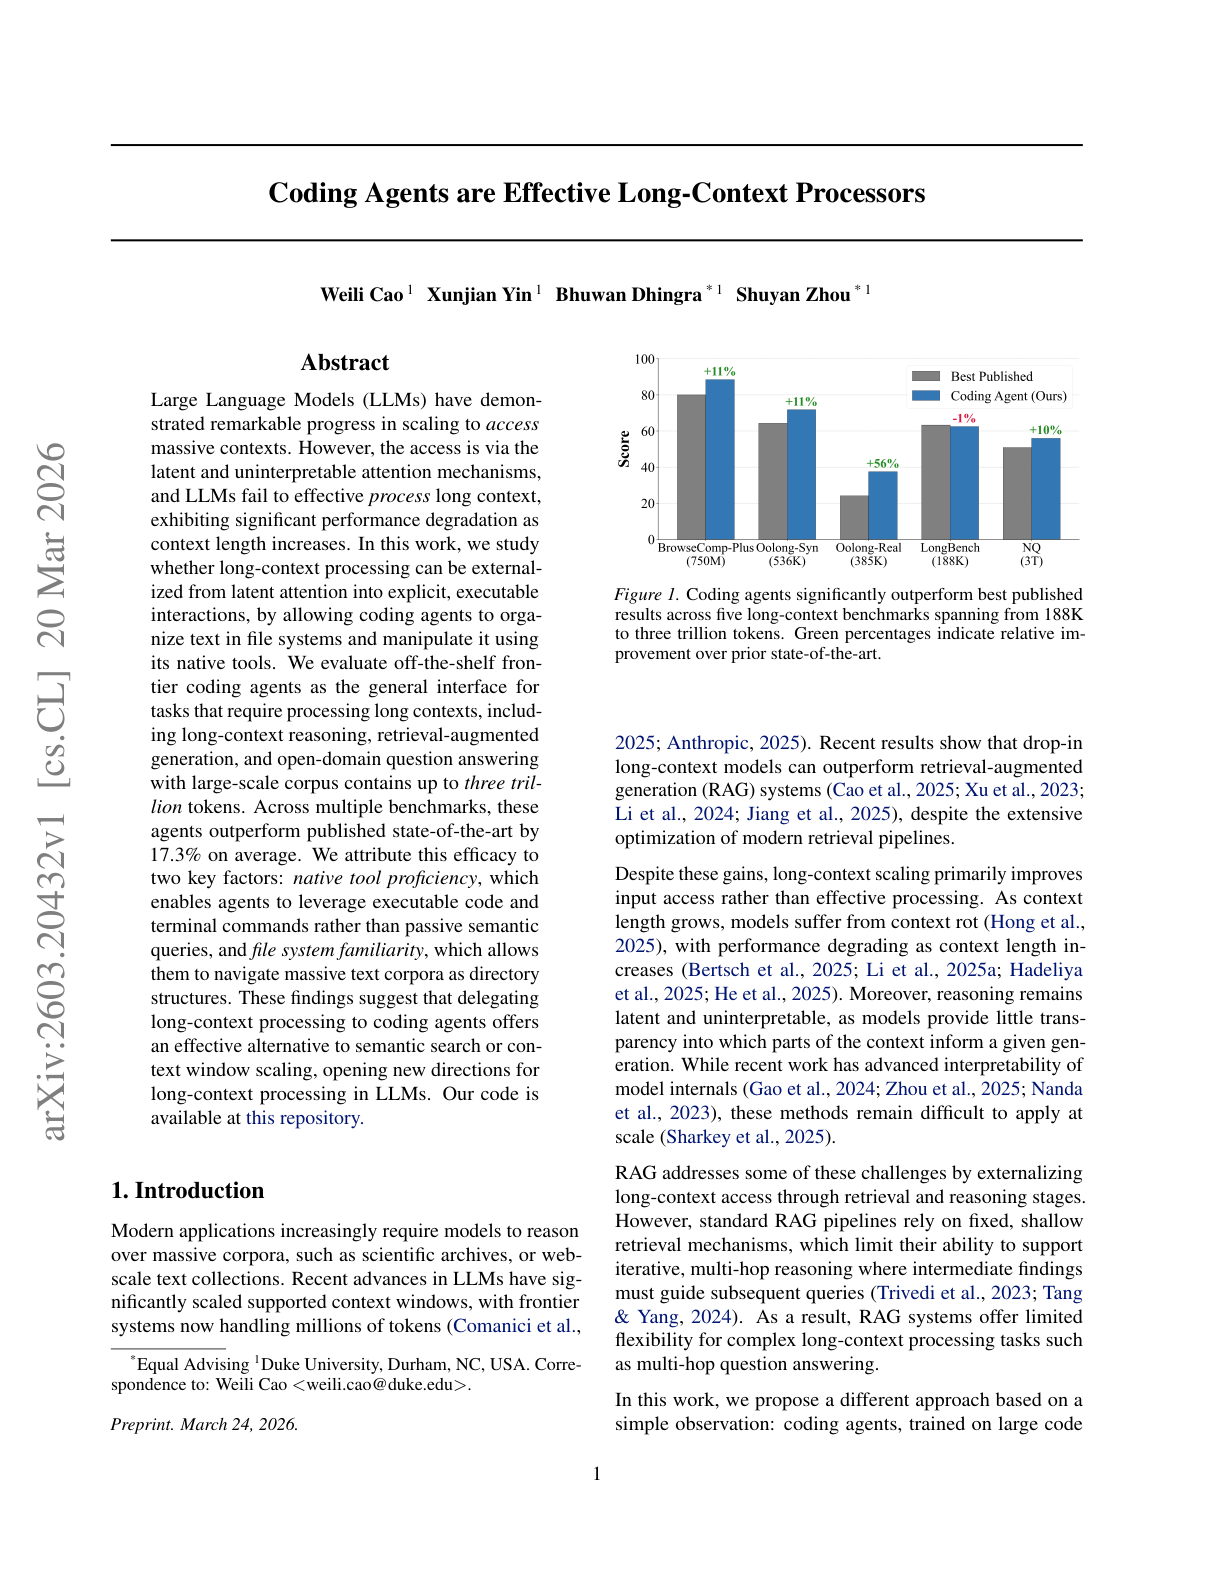
Coding Agents as Long-Context Processors
This research asks whether long-context processing can be externalized from latent attention into explicit, executable interactions. Instead of scaling context windows, the authors let coding agents organize text in file systems and manipulate it using native tools, evaluating them on tasks spanning long-context reasoning, retrieval-augmented generation, and open-domain question answering with corpora containing up to three trillion tokens.
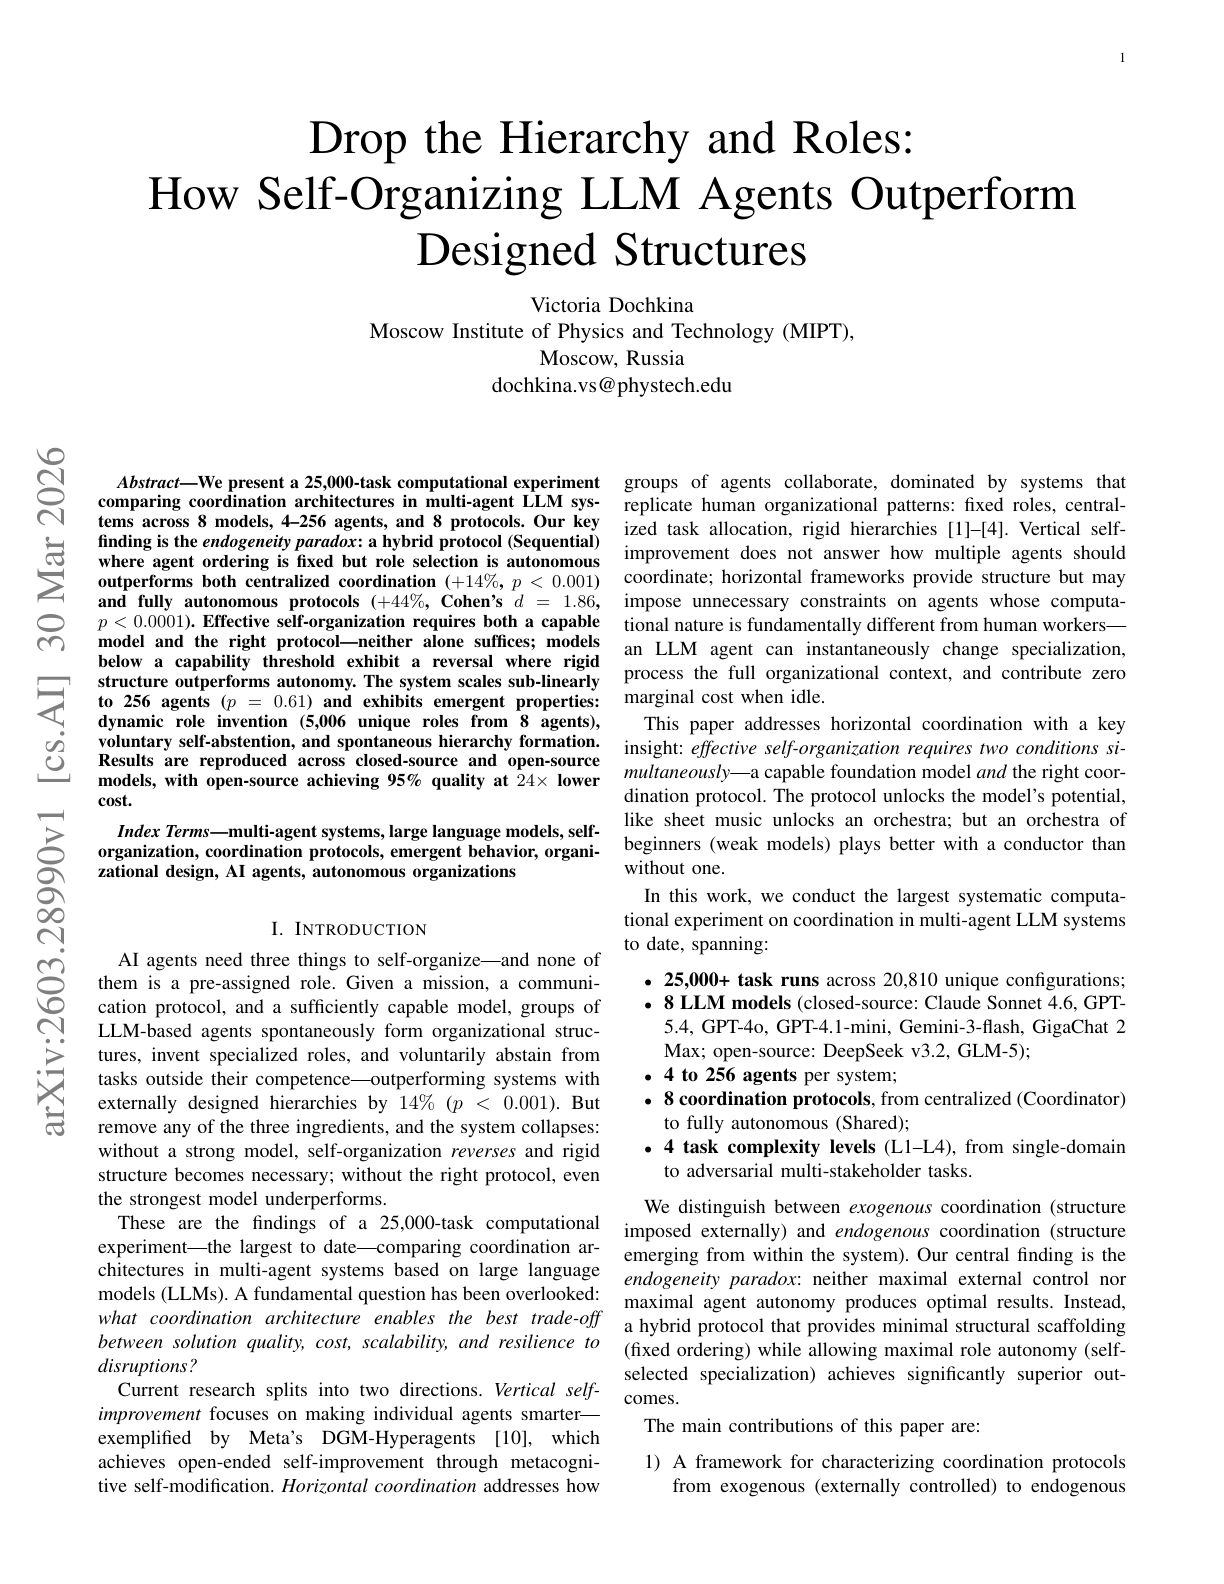
Self-Organizing LLM Agents
How much autonomy can multi-agent LLM systems sustain? This research tests the question at unprecedented scale: 25,000 tasks across 8 models, up to 256 agents, and 8 coordination protocols ranging from externally imposed hierarchy to emergent self-organization. The central finding is that agents allowed to figure out their own roles consistently outperform systems with pre-assigned structures.
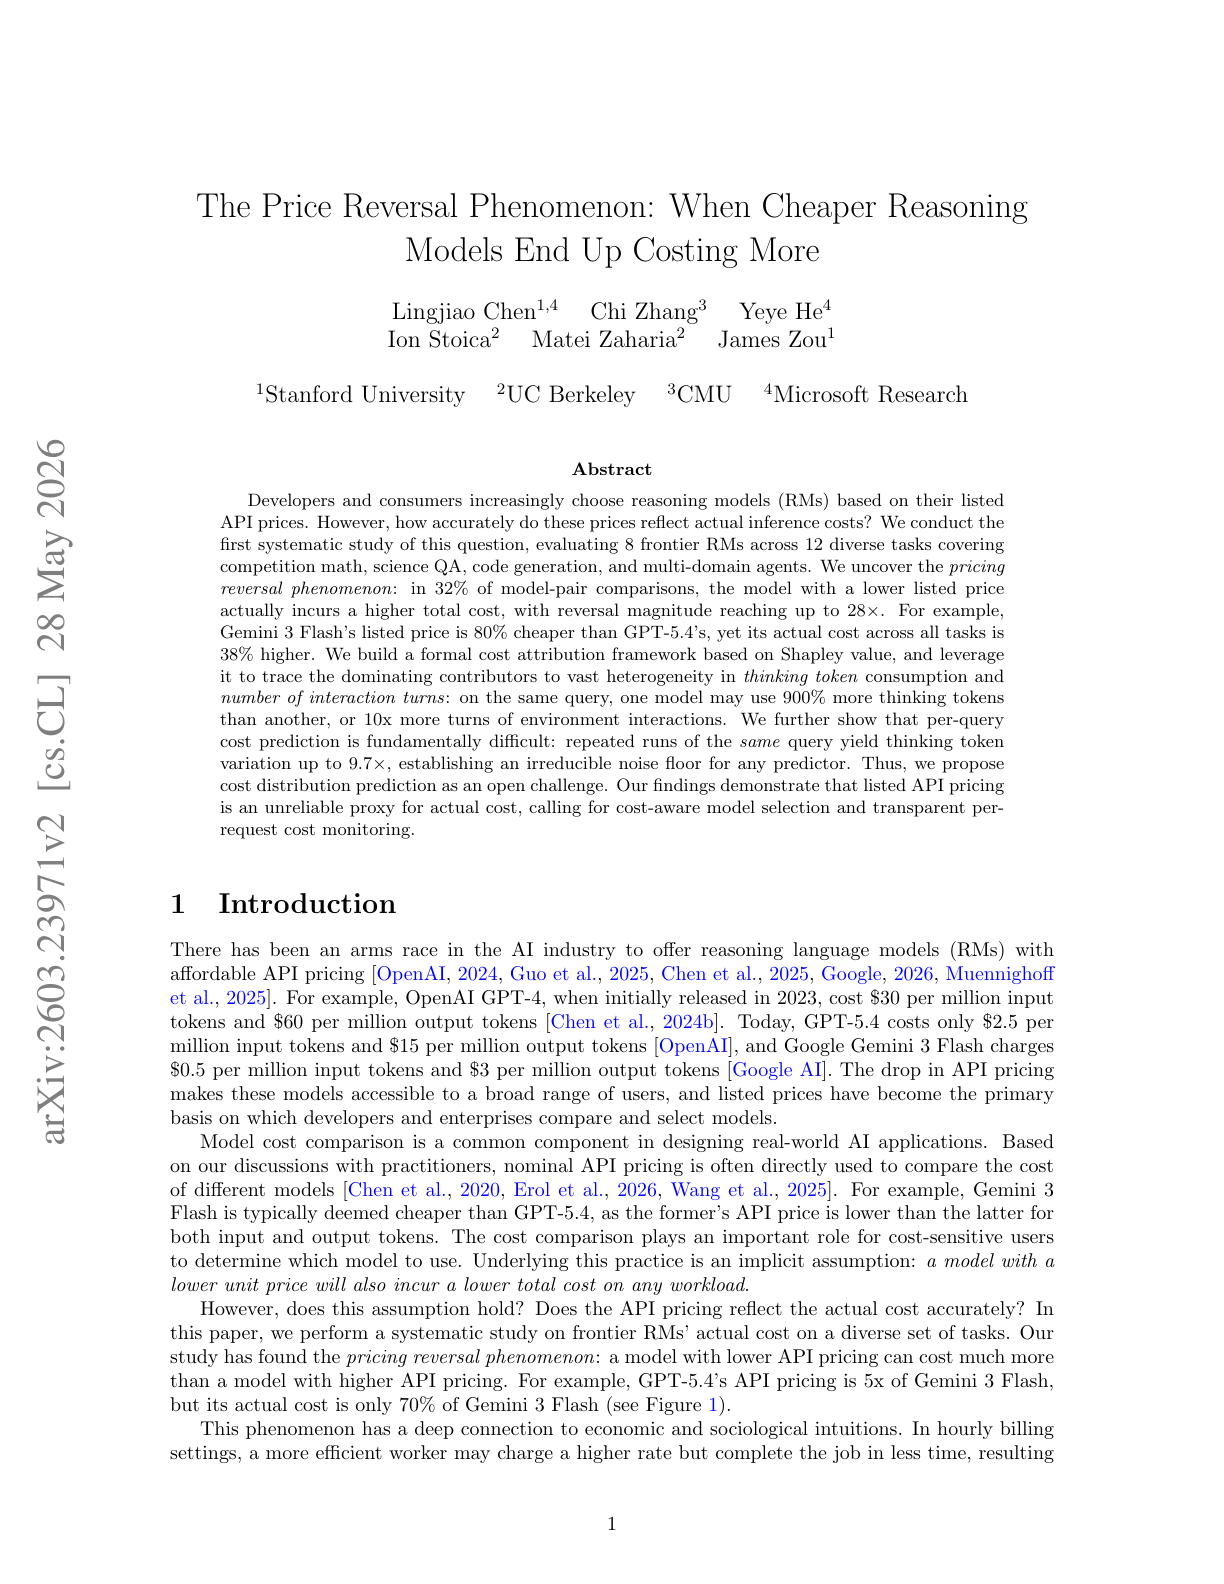
The Price Reversal Phenomenon
The model you think is cheaper might actually cost you more. A new study systematically evaluates 8 frontier reasoning language models across 9 diverse tasks and reveals that listed API prices are misleading. In 21.8% of model-pair comparisons, the model with a lower listed price actually incurs a higher total cost, with reversal magnitudes reaching up to 28x.
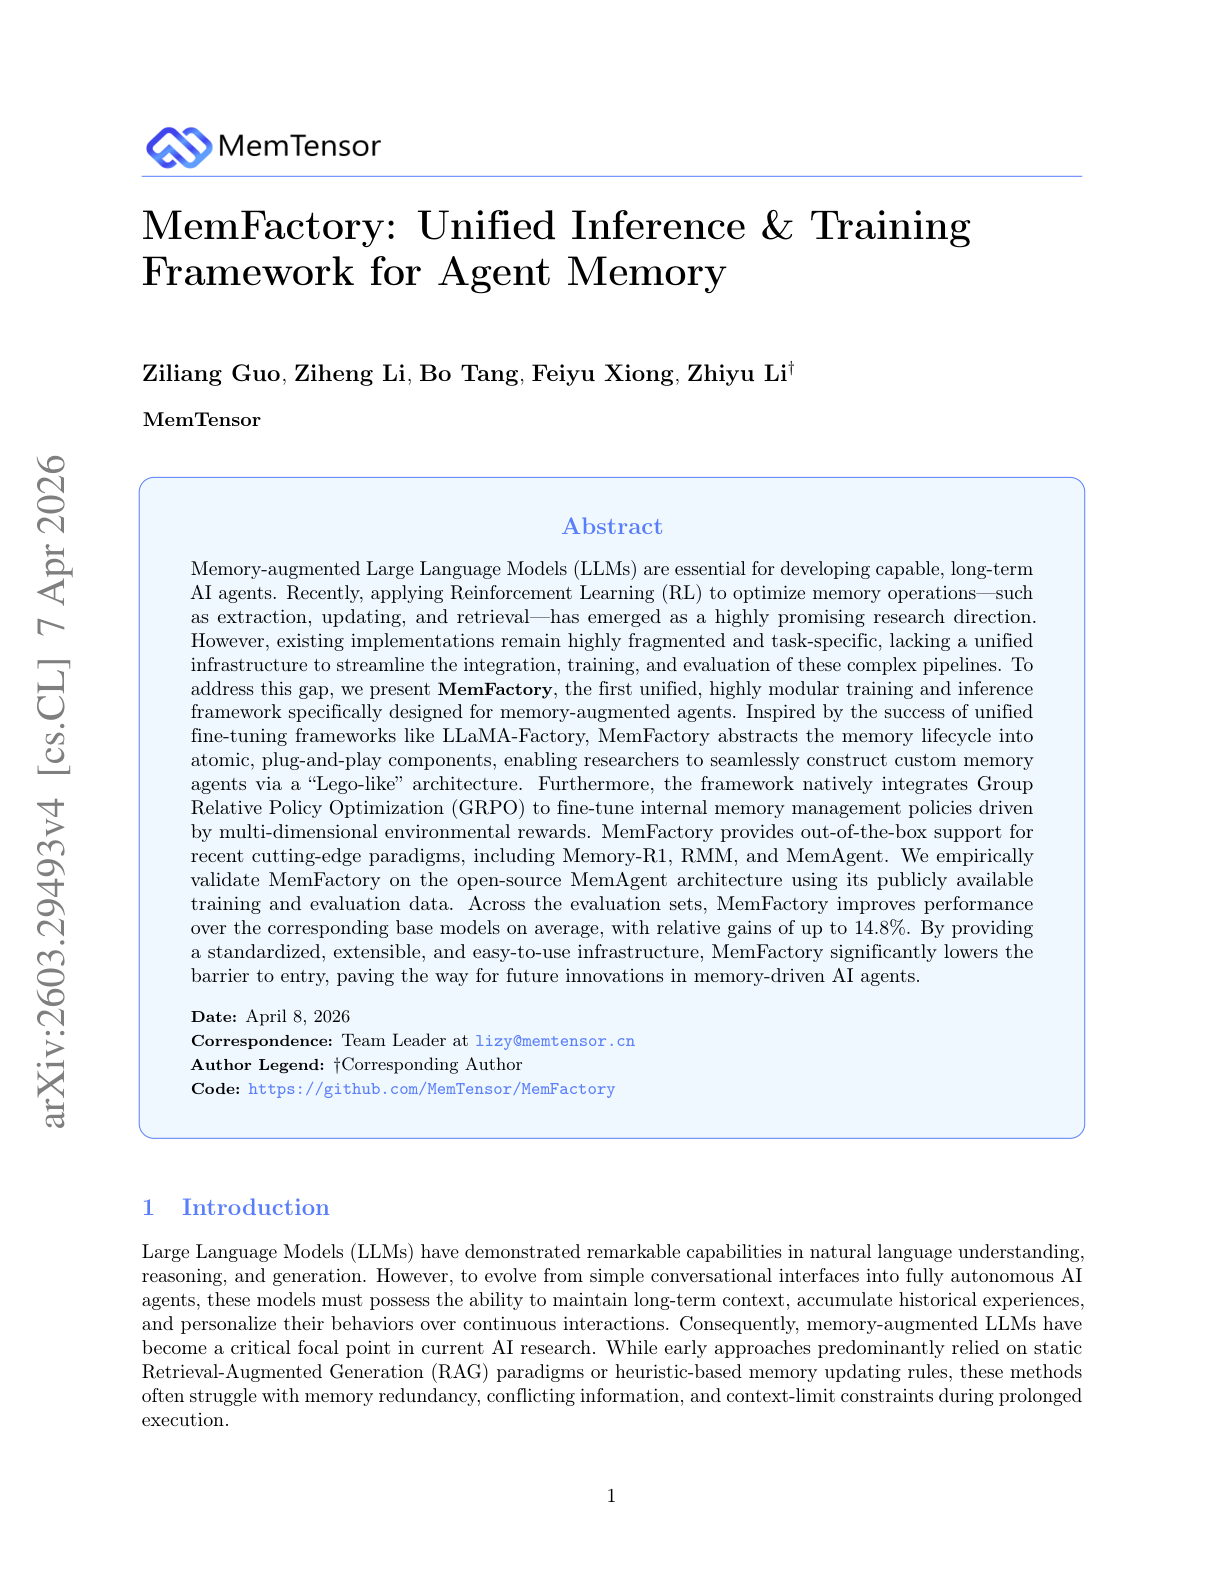
MemFactory
MemFactory introduces the first unified, highly modular training and inference framework specifically designed for memory-augmented AI agents. It abstracts the memory lifecycle into atomic, plug-and-play components using a “Lego-like” architecture, natively integrating Group Relative Policy Optimization (GRPO) to fine-tune internal memory management strategies. The framework decomposes memory into mixable components that support recent approaches including Memory-R1, RMM, and MemAgent out of the box, achieving relative gains of up to 14.8% compared to baseline models.
On the Reliability Limits of LLM-Based Multi-Agent Planning
New theoretical work from MIT proves fundamental limits on what multi-agent LLM architectures can achieve. By modeling agent systems as finite acyclic delegated decision networks, the authors show that without new exogenous signals, no delegated network can outperform a centralized Bayes decision maker that observes the same information. The gap between centralized and delegated performance admits an expected posterior divergence representation, reducing to conditional mutual information under logarithmic loss. Reasoning models can improve by investing more inference-time computation on the same evidence, while tool-use protocols help only when they introduce genuinely new signals rather than reprocessing shared context.
Natural-Language Agent Harnesses
Agent performance increasingly depends on harness engineering, but harness behavior is typically embedded in controller code and runtime-specific conventions, making it hard to transfer, compare, or analyze systematically. This work introduces Natural-Language Agent Harnesses (NLAHs), which express harness behavior in editable natural language, and an Intelligent Harness Runtime (IHR) that executes these harnesses through explicit contracts, durable artifacts, and lightweight adapters. The approach enables a code-to-text harness migration path where teams can convert existing harness code into natural-language specifications that are interpretable, version-controlled, and executable by an LLM at runtime.
Hyperagents
Self-improving AI systems promise to reduce reliance on human engineering, but existing approaches rely on fixed, handcrafted meta-level mechanisms that fundamentally limit how fast they can improve. Hyperagents introduce self-referential agents that integrate a task agent and a meta agent into a single editable program, enabling the system to improve not just its task-solving behavior but also the mechanism that generates future improvements.
Agentic AI and the Next Intelligence Explosion
A new report from Google researchers argues that the AI “singularity” framed as a single superintelligent mind bootstrapping to godlike intelligence is fundamentally wrong. Drawing on evolution, sociology, and recent advances in agentic AI, the authors make the case that every prior intelligence explosion in human history was social, not individual, and that the next one will follow the same pattern.
ARC-AGI-3
Francois Chollet and the ARC Prize Foundation introduce ARC-AGI-3, an interactive benchmark for studying agentic intelligence through novel, abstract, turn-based environments. Unlike its predecessors, ARC-AGI-3 requires agents to explore, infer goals, build internal models of environment dynamics, and plan effective action sequences without explicit instructions, making it the only unsaturated general agentic intelligence benchmark as of March 2026.
Claudini
Researchers demonstrate that an autoresearch-style pipeline powered by Claude Code can autonomously discover novel adversarial attack algorithms for LLMs that significantly outperform all 30+ existing methods. The work, called Claudini, shows that incremental safety and security research can be effectively automated using LLM agents, with white-box red-teaming being a particularly well-suited domain.
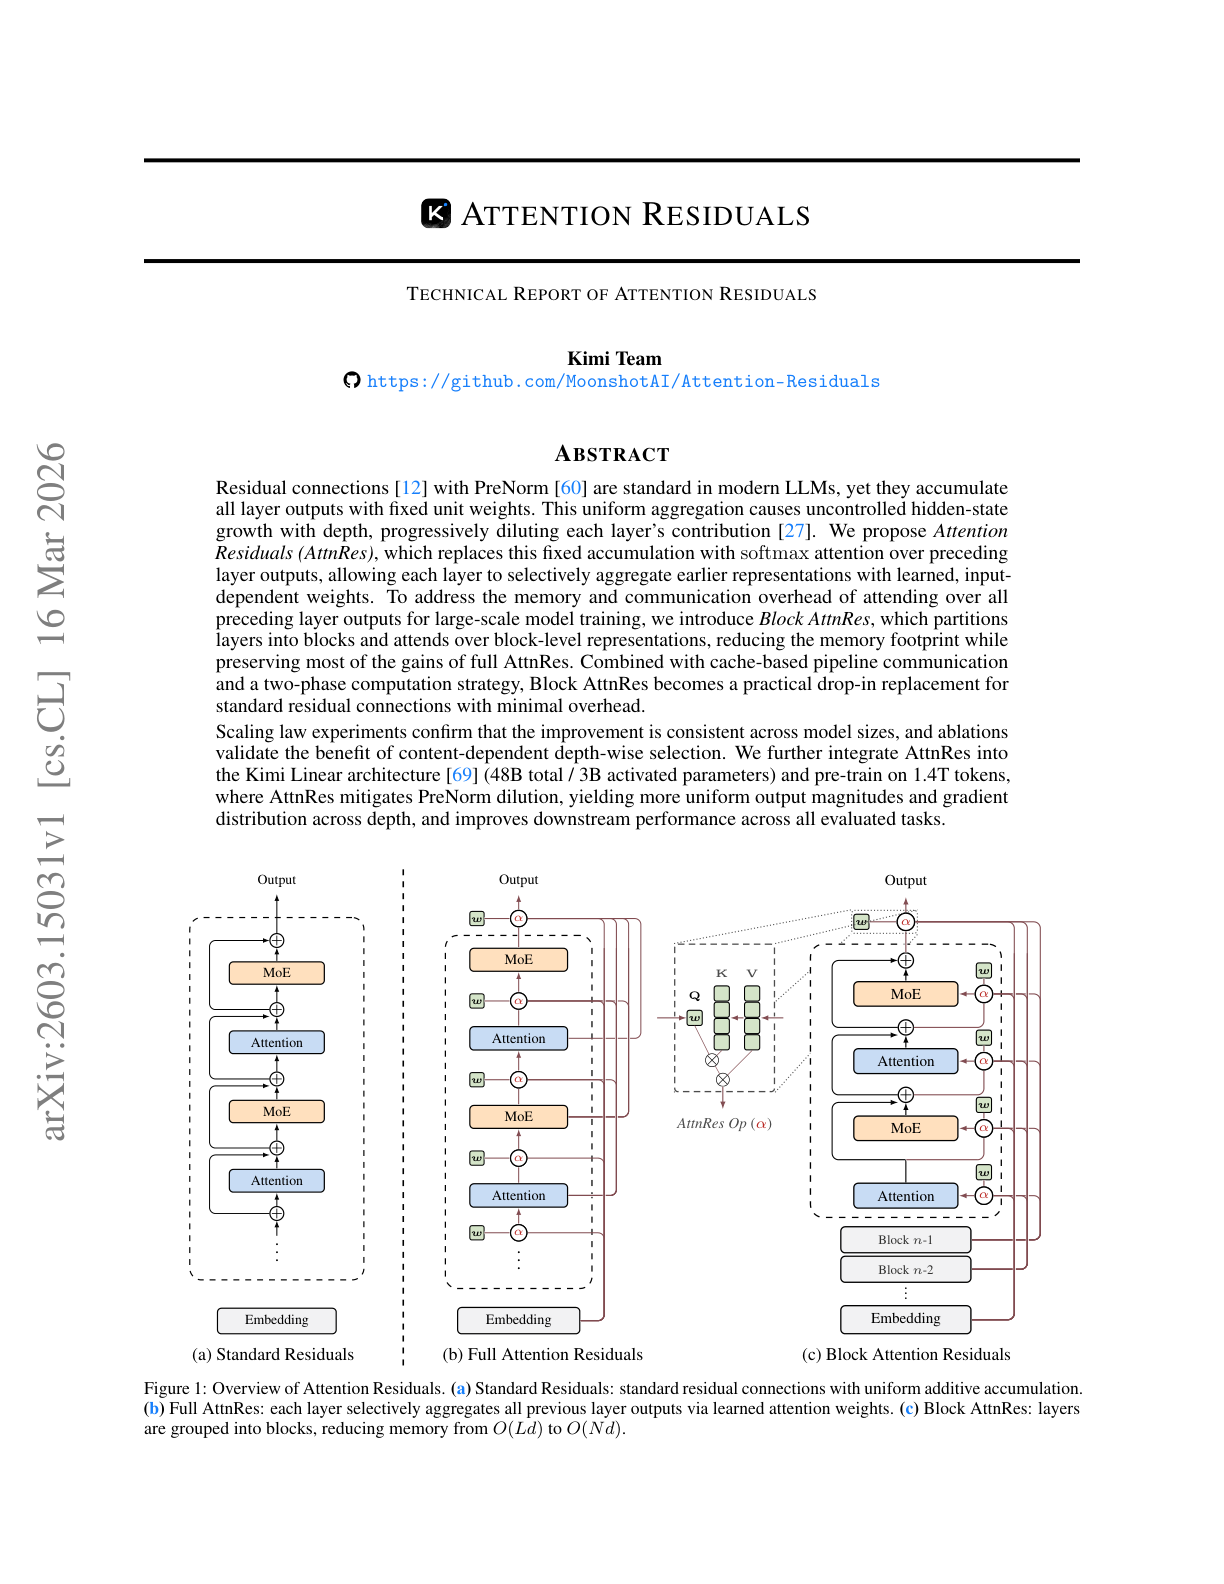
Attention Residuals
The Kimi team at Moonshot AI presents Attention Residuals (AttnRes), a technique that replaces fixed unit-weight residual connections in Transformers with softmax attention over preceding layer outputs. Residual connections with PreNorm are standard in modern LLMs, yet they accumulate all layer outputs with fixed unit weights, causing uncontrolled hidden-state growth with depth that progressively dilutes each layer’s contribution.
MemCollab
LLM-based agents build useful memory during tasks, but that memory is typically trapped within a single model. MemCollab introduces a collaborative memory framework that constructs agent-agnostic memory by contrasting reasoning trajectories generated by different agents on the same task, enabling a single memory system to be shared across heterogeneous models.
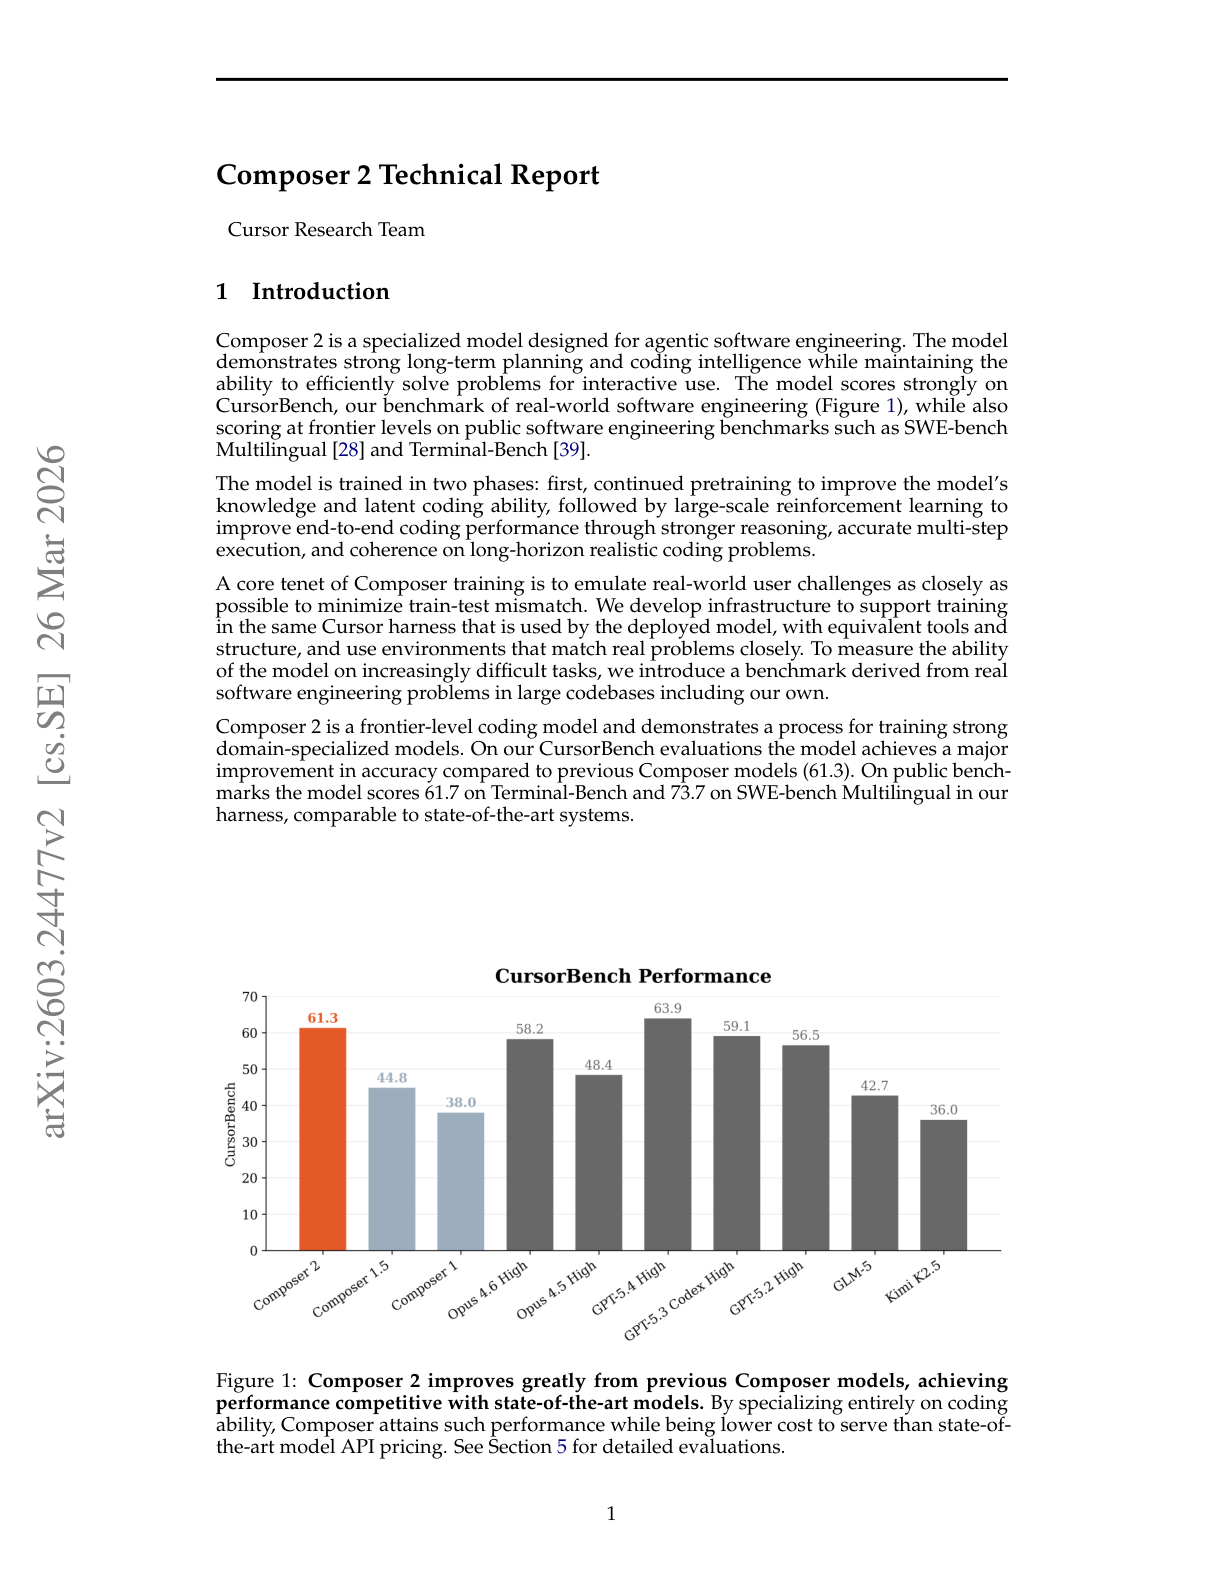
Composer 2
Cursor releases the technical report for Composer 2, a specialized model designed for agentic software engineering that demonstrates strong long-term planning and coding intelligence while maintaining efficiency for interactive use. The report details a process for training domain-specialized models that starts with continued pretraining and scales up with reinforcement learning.
PivotRL
PivotRL is a turn-level reinforcement learning algorithm from NVIDIA designed to tractably post-train large language models for long-horizon agentic tasks. The method operates on existing SFT trajectories, combining the compute efficiency of supervised fine-tuning with the out-of-domain accuracy of end-to-end RL. PivotRL identifies “pivots,” informative intermediate turns where sampled actions exhibit high variance in outcomes, and focuses training signal on these critical decision points. The approach achieves +4.17% higher in-domain accuracy and +10.04% higher out-of-domain accuracy compared to standard SFT, while matching end-to-end RL accuracy with 4x fewer rollout turns. PivotRL is adopted by NVIDIA’s Nemotron-3-Super-120B-A12B as the workhorse for production-scale agentic post-training.
Workflow Optimization for LLM Agents
A comprehensive survey from IBM that maps recent methods for designing and optimizing LLM agent workflows, treating them as agentic computation graphs (ACGs). The survey organizes prior work along three dimensions: when structure is determined, what part of the workflow is optimized, and which evaluation signals guide optimization. It distinguishes between reusable workflow templates, run-specific realized graphs, and execution traces, covering methods like AFlow (Monte Carlo Tree Search over operator graphs), Automated Design of Agentic Systems (code-space search via meta-agents), and evolutionary multi-agent system design. A useful reference for teams building production agent systems where wiring decisions between model calls, retrieval, tool use, and verification matter as much as model capability.
BIGMAS
Even the best reasoning models hit an accuracy collapse beyond a certain problem complexity. BIGMAS (Brain-Inspired Graph Multi-Agent Systems) organizes specialized LLM agents as nodes in a dynamically constructed directed graph, coordinating exclusively through a centralized shared workspace inspired by global workspace theory from cognitive neuroscience. A GraphDesigner agent analyzes each problem instance and produces a task-specific directed agent graph together with a workspace contract. The framework constructs structurally distinct graphs whose complexity tracks task demands, from compact three-node pipelines for simple arithmetic to nine-node cyclic structures for multi-step planning. BIGMAS consistently improves reasoning performance for both standard LLMs and large reasoning models, outperforming existing multi-agent baselines.
OpenDev
Terminal-native coding agents represent a fundamental shift in how developers interact with AI assistance. OpenDev is an open-source, command-line coding agent that operates where developers already manage source control and deploy environments, offering a comprehensive 81-page technical report on scaffolding, harness design, context engineering, and lessons learned from building production coding agents.
AutoHarness
Google DeepMind researchers introduce AutoHarness, a method for automatically synthesizing code harnesses that prevent LLM agents from making illegal actions. The core insight comes from a striking observation: in the Kaggle GameArena chess competition, 78% of Gemini-2.5-Flash losses were attributed to illegal moves, not poor strategy.
SkillNet
AI agents repeatedly rediscover solutions across separate scenarios instead of systematically reusing what they have already learned. SkillNet introduces an open infrastructure designed to create, evaluate, and organize AI skills at scale, enabling agents to transition from transient experience to durable mastery.
The Spike, the Sparse and the Sink
Yann LeCun and collaborators at NYU dissect two recurring phenomena in Transformer language models: massive activations, where a small number of tokens exhibit extreme outliers in specific channels, and attention sinks, where certain tokens attract disproportionate attention mass regardless of semantic relevance. The paper reveals that their co-occurrence is largely an architectural artifact.
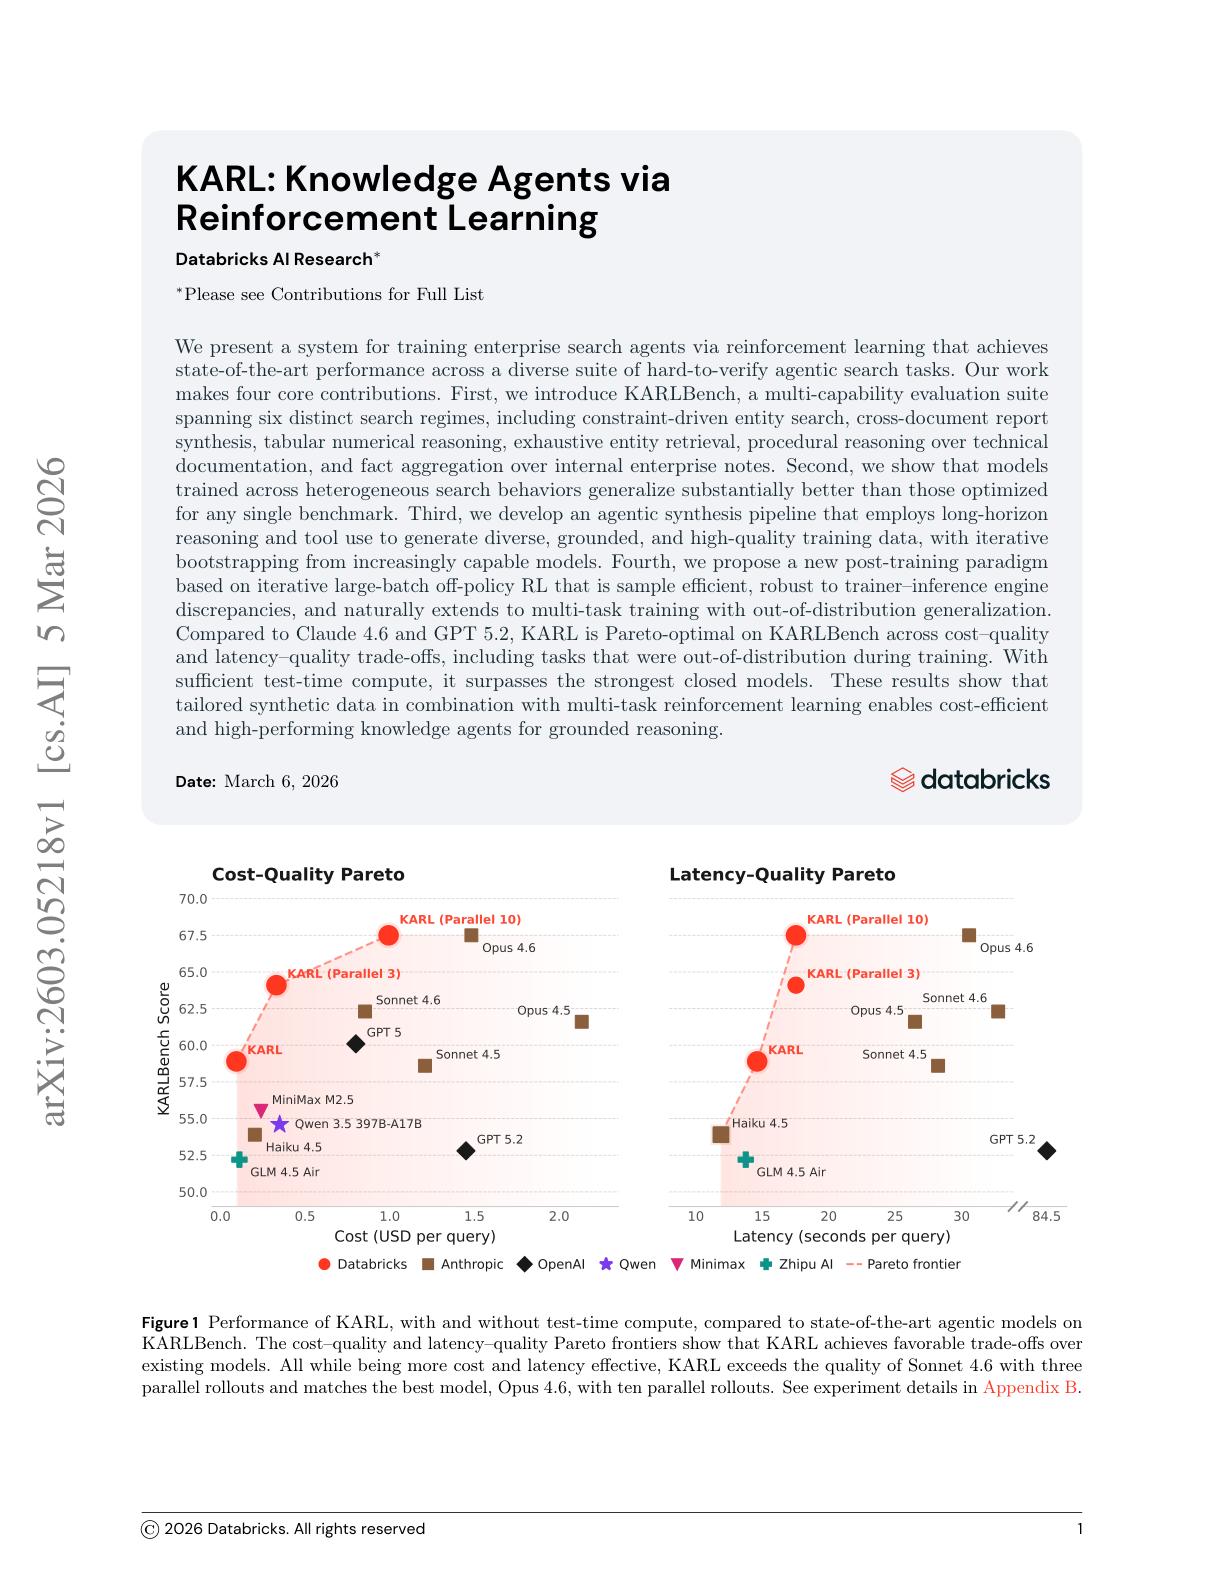
KARL
Databricks presents KARL, a system for training enterprise search agents via reinforcement learning that achieves state-of-the-art performance across a diverse suite of hard-to-verify agentic search tasks. The work also introduces KARLBench, a new evaluation framework spanning six search domains.
Memex(RL)
As tasks get longer and more complex, LLM agents lose track of what they have learned, what they have tried, and what still needs to be done. Memex(RL) introduces an indexed experience memory mechanism that scales agent capability on long-horizon tasks without discarding evidence or blowing up the context window.
FlashAttention-4
FlashAttention-4 co-designs algorithms and kernel pipelines for the B200 and GB200 GPUs, which exhibit fundamentally different performance characteristics due to asymmetric hardware scaling where tensor core throughput doubles while other functional units scale more slowly.
STRUCTUREDAGENT
STRUCTUREDAGENT introduces a hierarchical planning framework for long-horizon web tasks using dynamic AND/OR trees. The framework separates planning responsibilities: the system constructs and maintains the planning tree while the LLM is invoked only for local operations like node expansion or repair. A structured memory module tracks candidate solutions to improve constraint satisfaction. Results on WebVoyager, WebArena, and custom shopping benchmarks show improved performance over standard LLM-based web agents, with the added benefit of interpretable hierarchical plans that enable easier debugging and human intervention.