AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup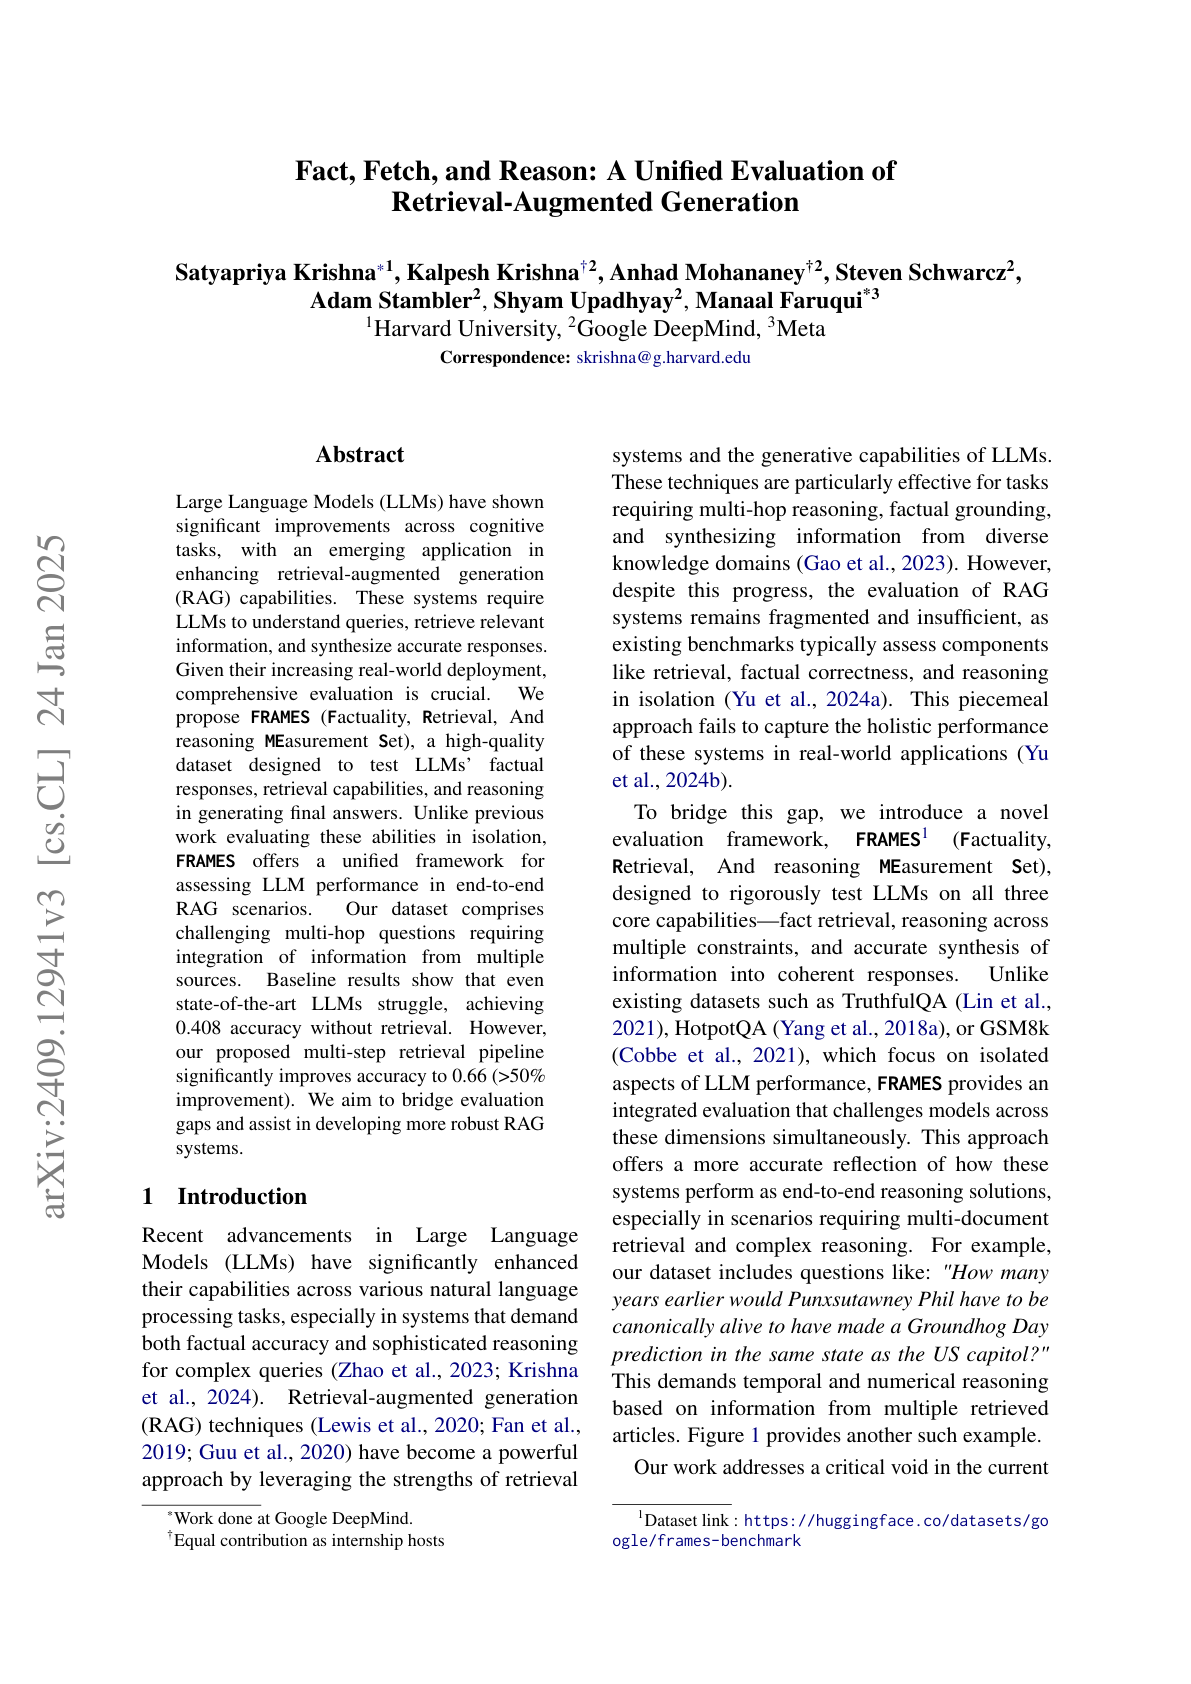
FRAMES
a unified framework to evaluate an LLM’s ability to provide factual responses, assess retrieval capabilities, and the reasoning required to generate final responses; includes multi-hop questions that require the integration of information from multiple sources; reports that state-of-the-art LLMs struggle on the task and only achieve 40% accuracy with no retrieval; the proposed multi-step retrieval approach improves performance to 66% accuracy.
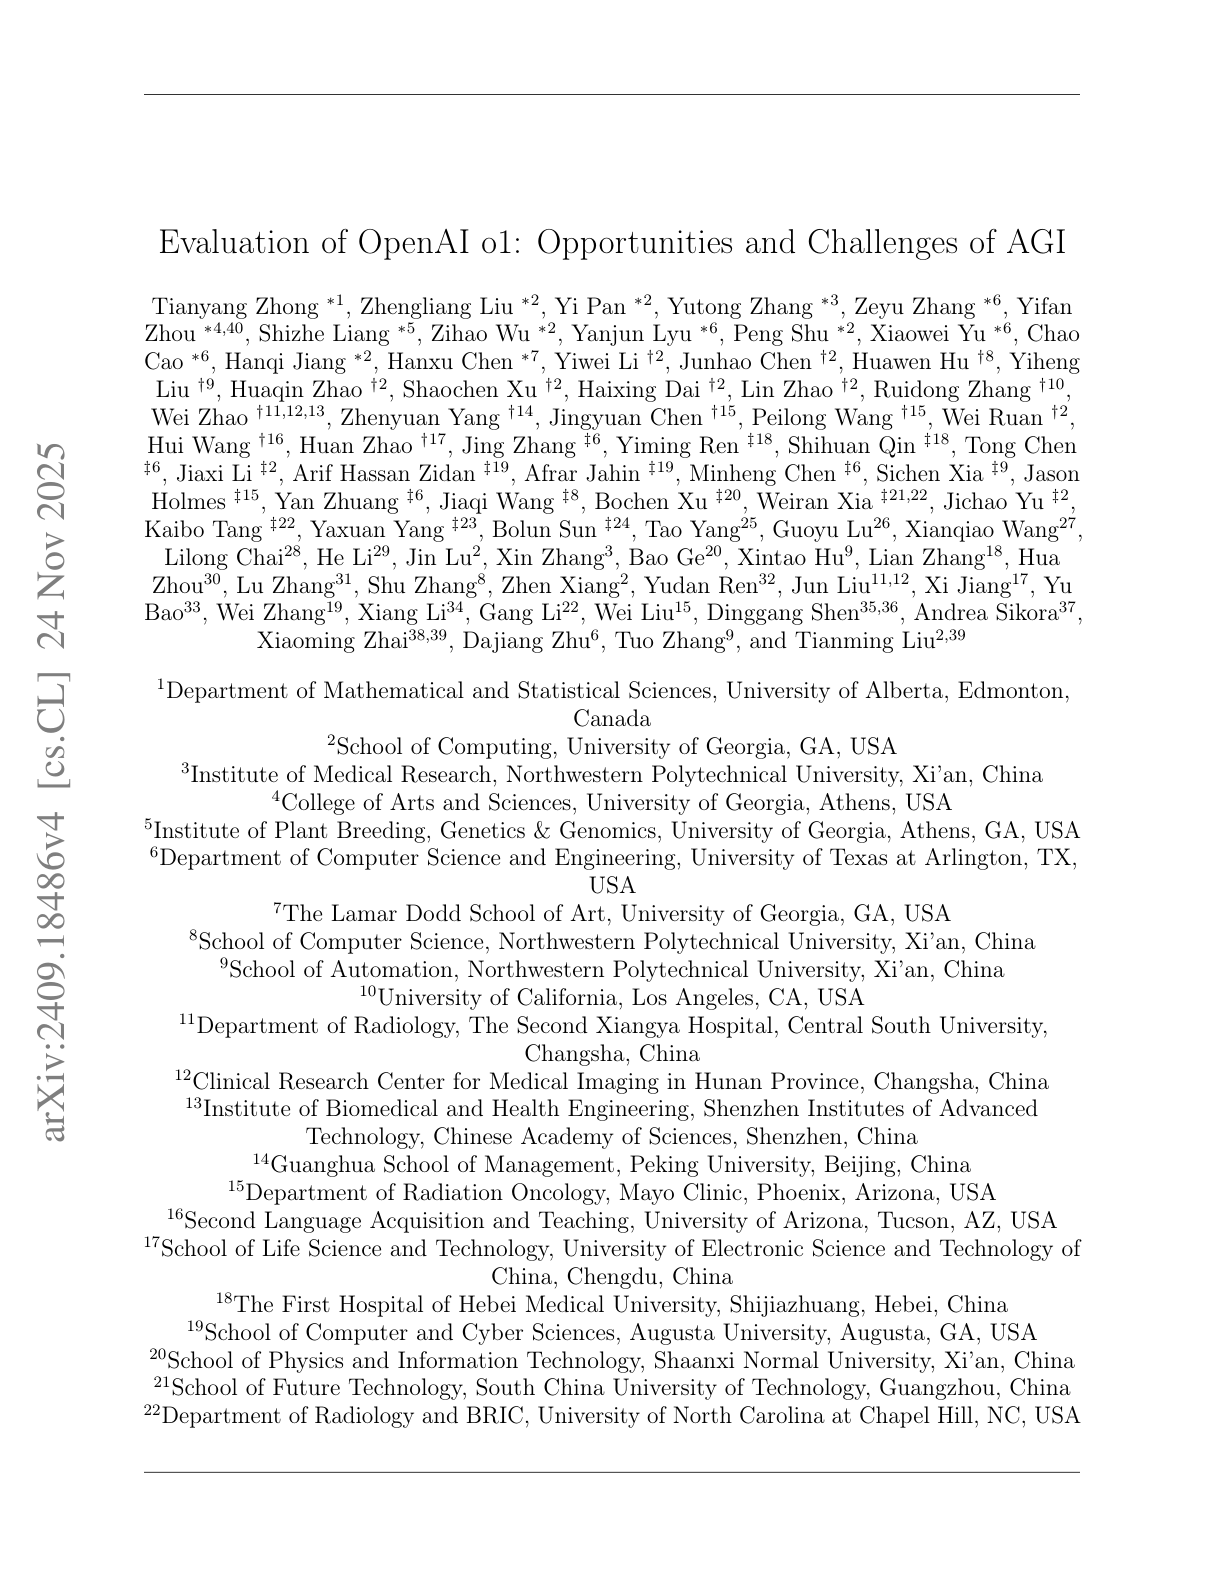
Evaluation of o1
provides a comprehensive evaluation of OpenAI's o1-preview LLM; shows strong performance across many tasks such as competitive programming, generating coherent and accurate radiology reports, high school-level mathematical reasoning tasks, chip design tasks, anthropology and geology, quantitative investing, social media analysis, and many other domains and problems.
**Molmo
** - - presents a family of open, state-of-the-art multimodal AI models; the 72B model in the Molmo family outperforms others in the class of open weight and data models; it also compares favorably against proprietary models like GPT-4o, Claude 3.5, and Gemini 1.5 on several benchmarks.
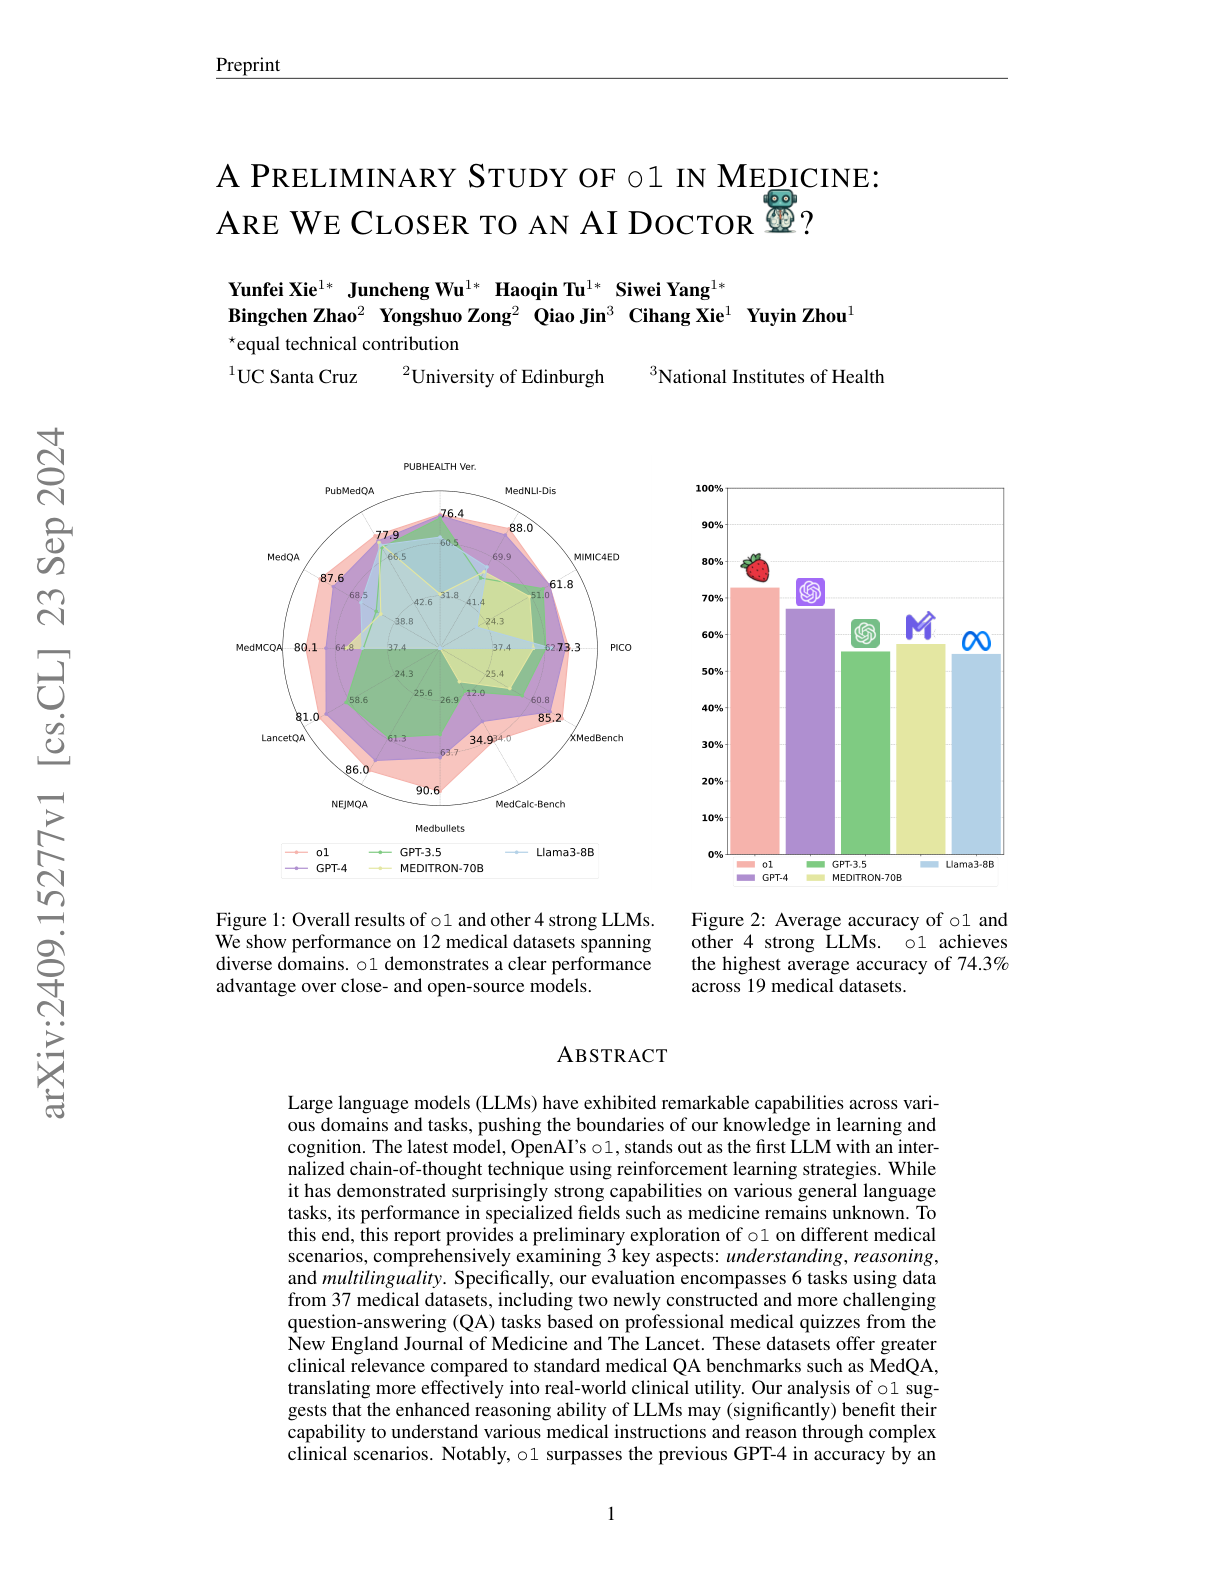
A Preliminary Study of o1 in Medicine
provides a preliminary exploration of the o1-preview model in medical scenarios; shows that o1 surpasses the previous GPT-4 in accuracy by an average of 6.2% and 6.6% across 19 datasets and two newly created complex QA scenarios; identifies hallucination, inconsistent multilingual ability, and discrepant metrics for evaluation.
Training LLMs to Self-Correct via RL
develops a multi-turn online reinforcement learning to improve the capabilities of an LLM to self-correct; it’s based entirely on self-generated data; SFT is shown to be ineffective at learning self-correction and suffers from distribution mismatch between training data and model responses; proposes a two-stage approach that first optimizes correction behavior and then uses a reward bonus to amplify self-correction during training; when applied to Gemini 1.0 Pro and 1.5 Flash models, it achieves state-of-the-art self-correction performance, improving the base models’ self-correction by 15.6% and 9.1% respectively on the MATH and HumanEval benchmarks.
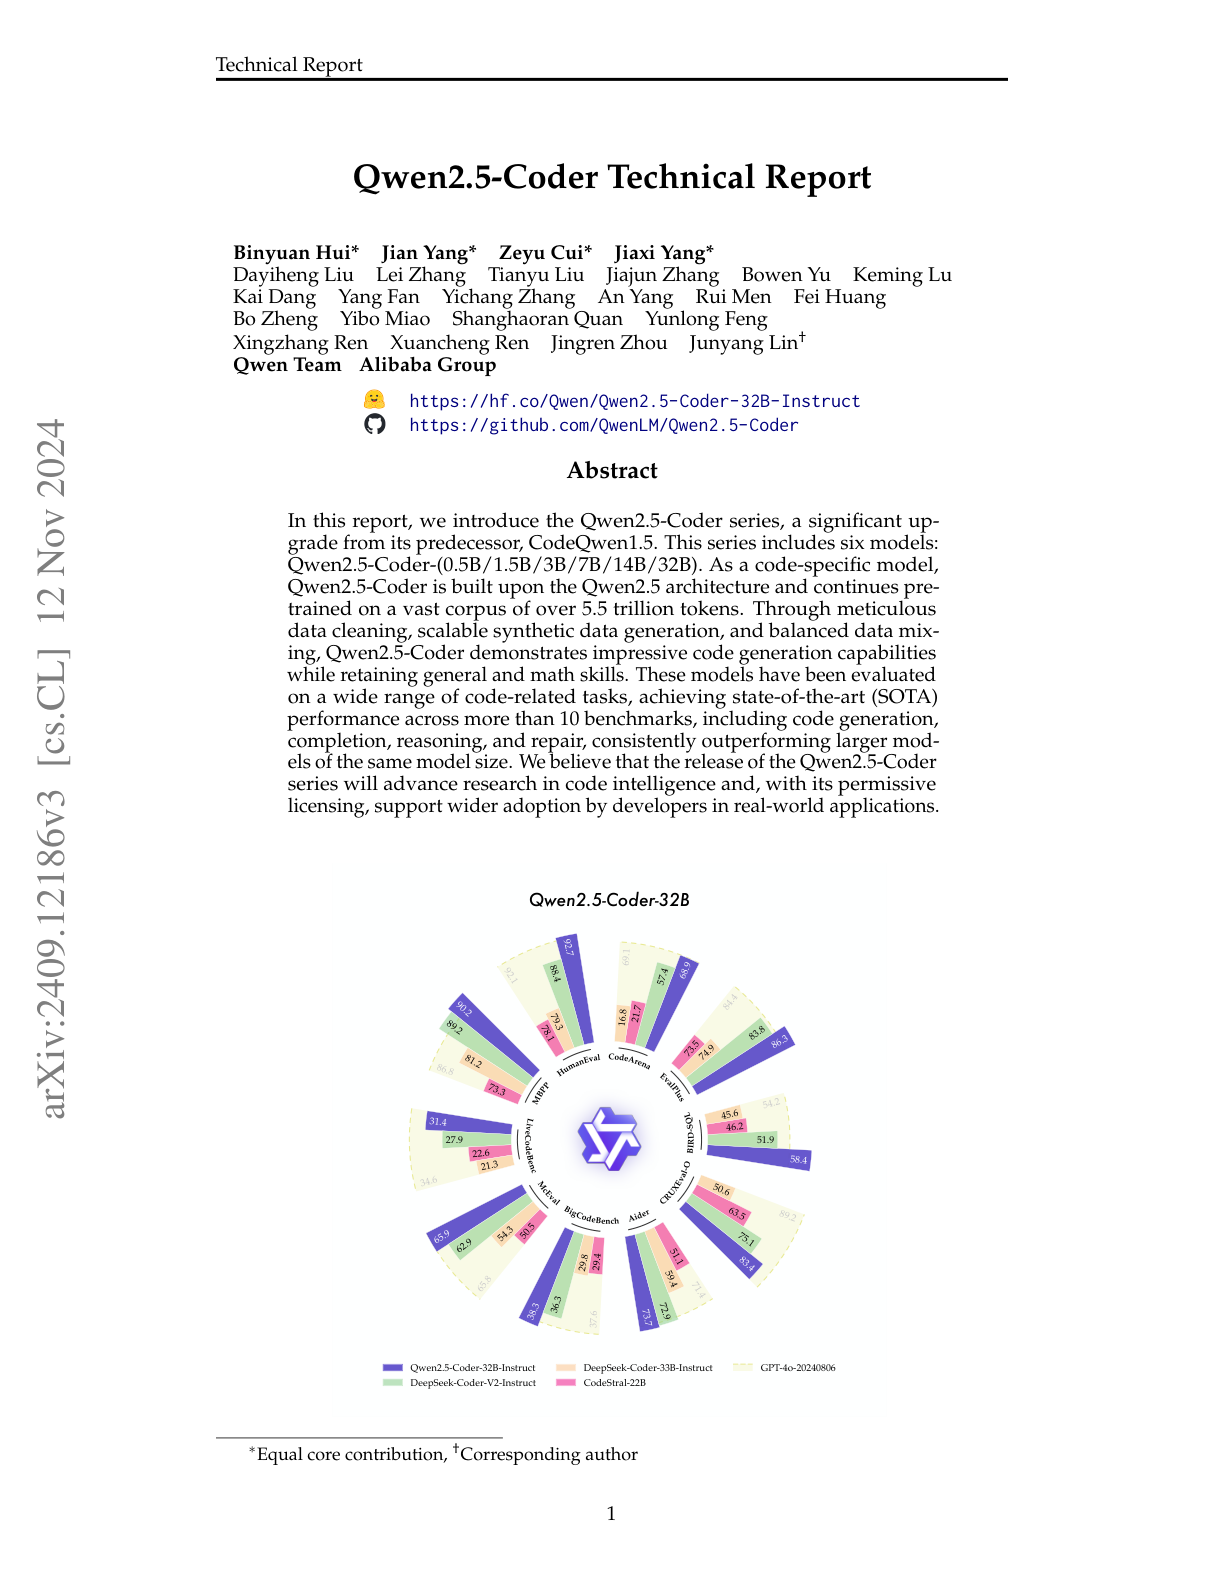
Qwen2.5 Coder
a series of models including 1.5B and 7B parameters; it’s built upon the Qwen2.5 architecture which is continuously pretrained on 5.5 trillion tokens; achieves state-of-the-art performance across more than 10 benchmarks; includes strong capabilities in code generation, completion, reasoning, and repairing.
A Comprehensive Evaluation of Quantized Instruction-Tuned LLMs
evaluates the performance of instruction-tuned LLMs across various quantization methods on models ranging from 7B to 405B; the key findings are 1) quantizing a larger LLM to a similar size as a smaller FP16 LLM generally performs better across most benchmarks, 2) performance varies significantly with different quantization methods, model size, and bit-width, with weight-only methods often yielding better results in larger models, and 3) task difficulty does not significantly impact accuracy degradation due to quantization.
Learning to Reason with LLMs
a new family of LLMs trained with reinforcement learning to reason before it responds to complex tasks; it produces a long internal chain of thought and exceeds in science, code, and math-related tasks; ranked in the 49th percentile in the 2024 International Olympiad in Informatics and exceeds human PhD-level accuracy on science-related benchmarks. -
Chai-1
a new multi-modal foundation model for molecular structure prediction that can predict proteins, small molecules, DNA, RNA, and more; it achieves state-of-the-art results on a variety of tasks in drug discovery; achieves a 77% success rate on the PoseBusters benchmark (vs. 76% by AlphaFold 3), as well as an Cα LDDT of 0.849 on the CASP15 protein monomer structure prediction set (vs. 0.801 by ESM3-98B).
LongCite
synthesizes a large-scale SFT dataset with off-the-shelf LLMs to improve long-context question answering with citations; it trains 8B and 9B parameter models that enhance citation generation capabilities from lengthy contexts while improving response correctness; claims to even surpass GPT-4o on their proposed LongBench-Cite benchmark.
Text2SQL is Not Enough
proposes Table-Augmented Generation (TAG), a unified framework for answering natural language questions over databases; it represents a wider range of unexplored interactions between LLMs and databases; develops a benchmark and finds that standard methods answer no more than 20% of queries correctly.
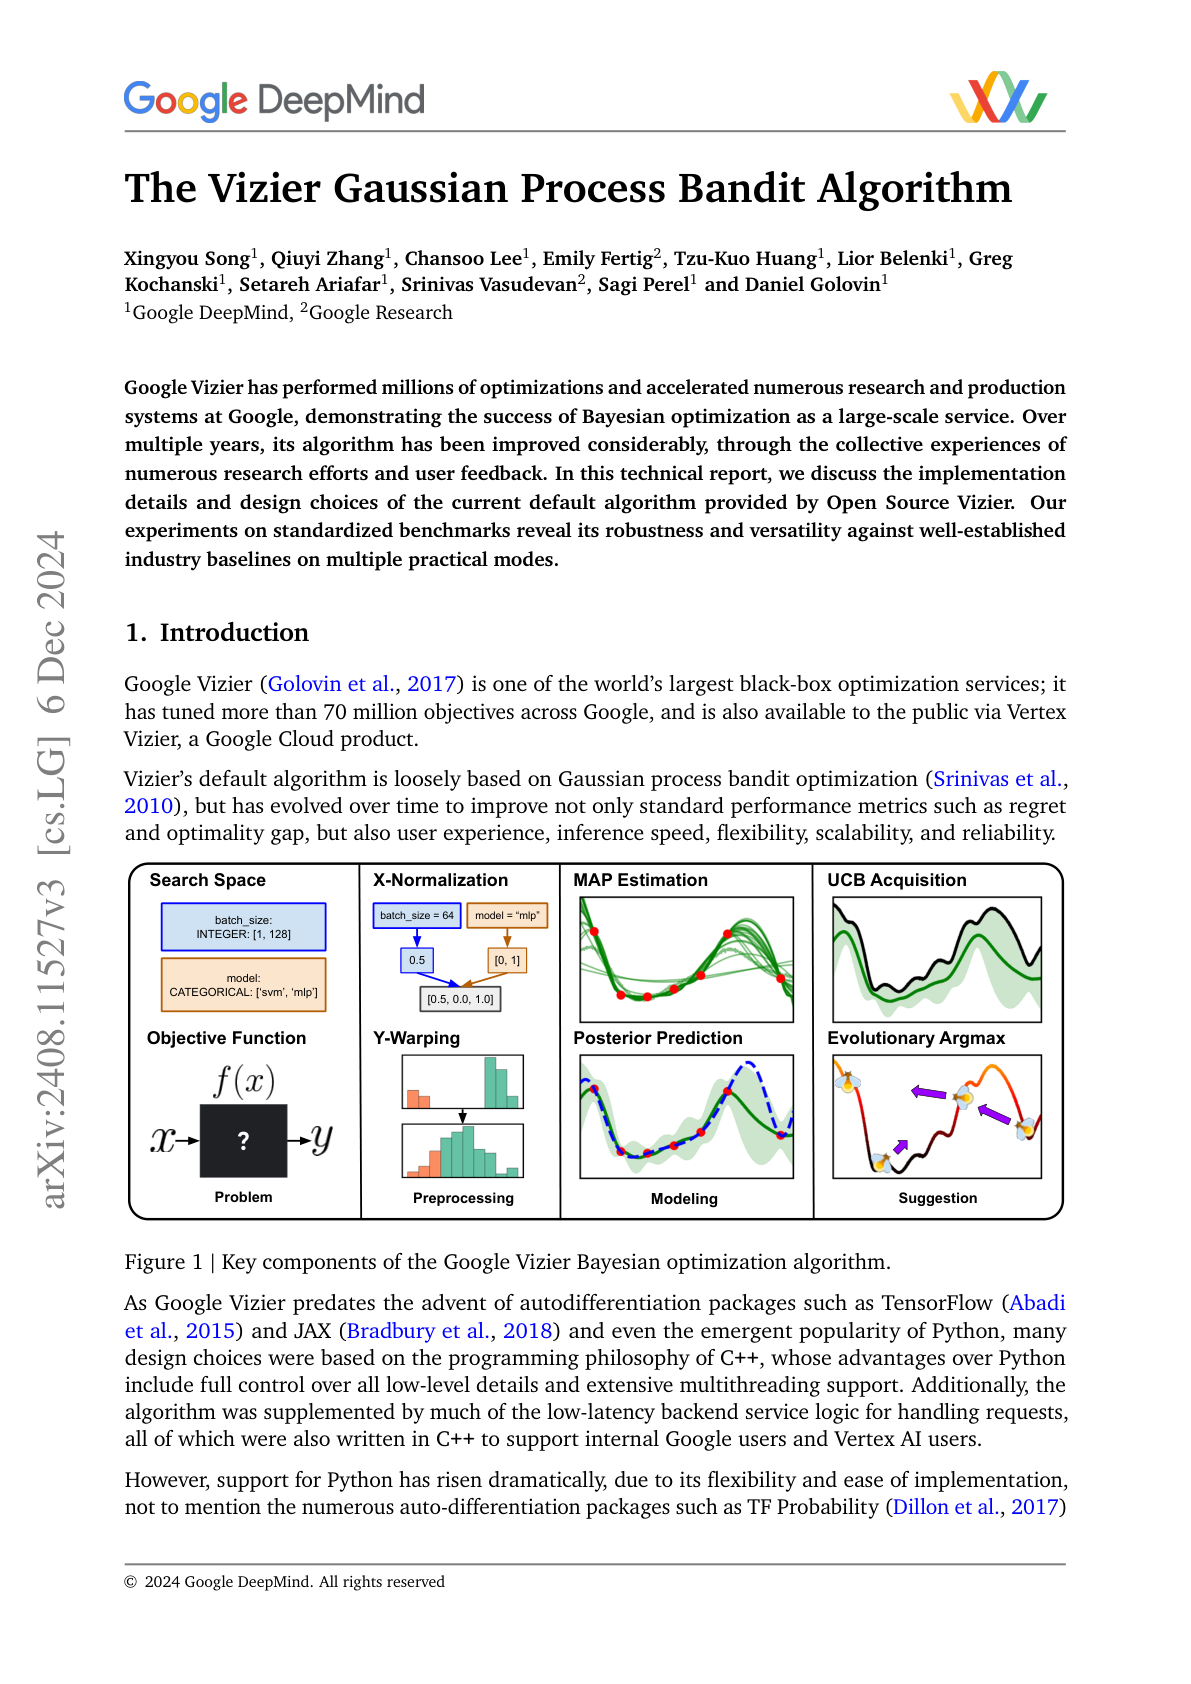
Vizier Gaussian Process Bandit Algorithm
presents Vizier, an algorithm based on Gaussian process bandit optimization used by Google for millions of optimizations and research; it provides an open-source Python implementation of the Vizier algorithm, including benchmarking results that demonstrate its wider applicability.
LongWriter
proposes AgentWrite to enable off-the-shelf LLMs to generate coherent outputs beyond 20K words; AgentWrite breaks down the long generation task into subtasks and in a divide-and-conquer approach generates; the agent breaks the task into multiple writing subtasks and concatenates the outputs to get a final output (i.e., plan + write); the approach is then used to build SFT datasets that are used to tune LLMs to generate coherent longer outputs automatically; a 9B parameter model, further improved through DPO, achieves state-of-the-art performance on their benchmark, and surpasses proprietary models.
RAGChecker
a fine-grained evaluation framework for diagnosing retrieval and generation modules in RAG; shows that RAGChecker has better correlations with human judgment; reports several revealing insightful patterns and trade-offs in design choices of RAG architectures.
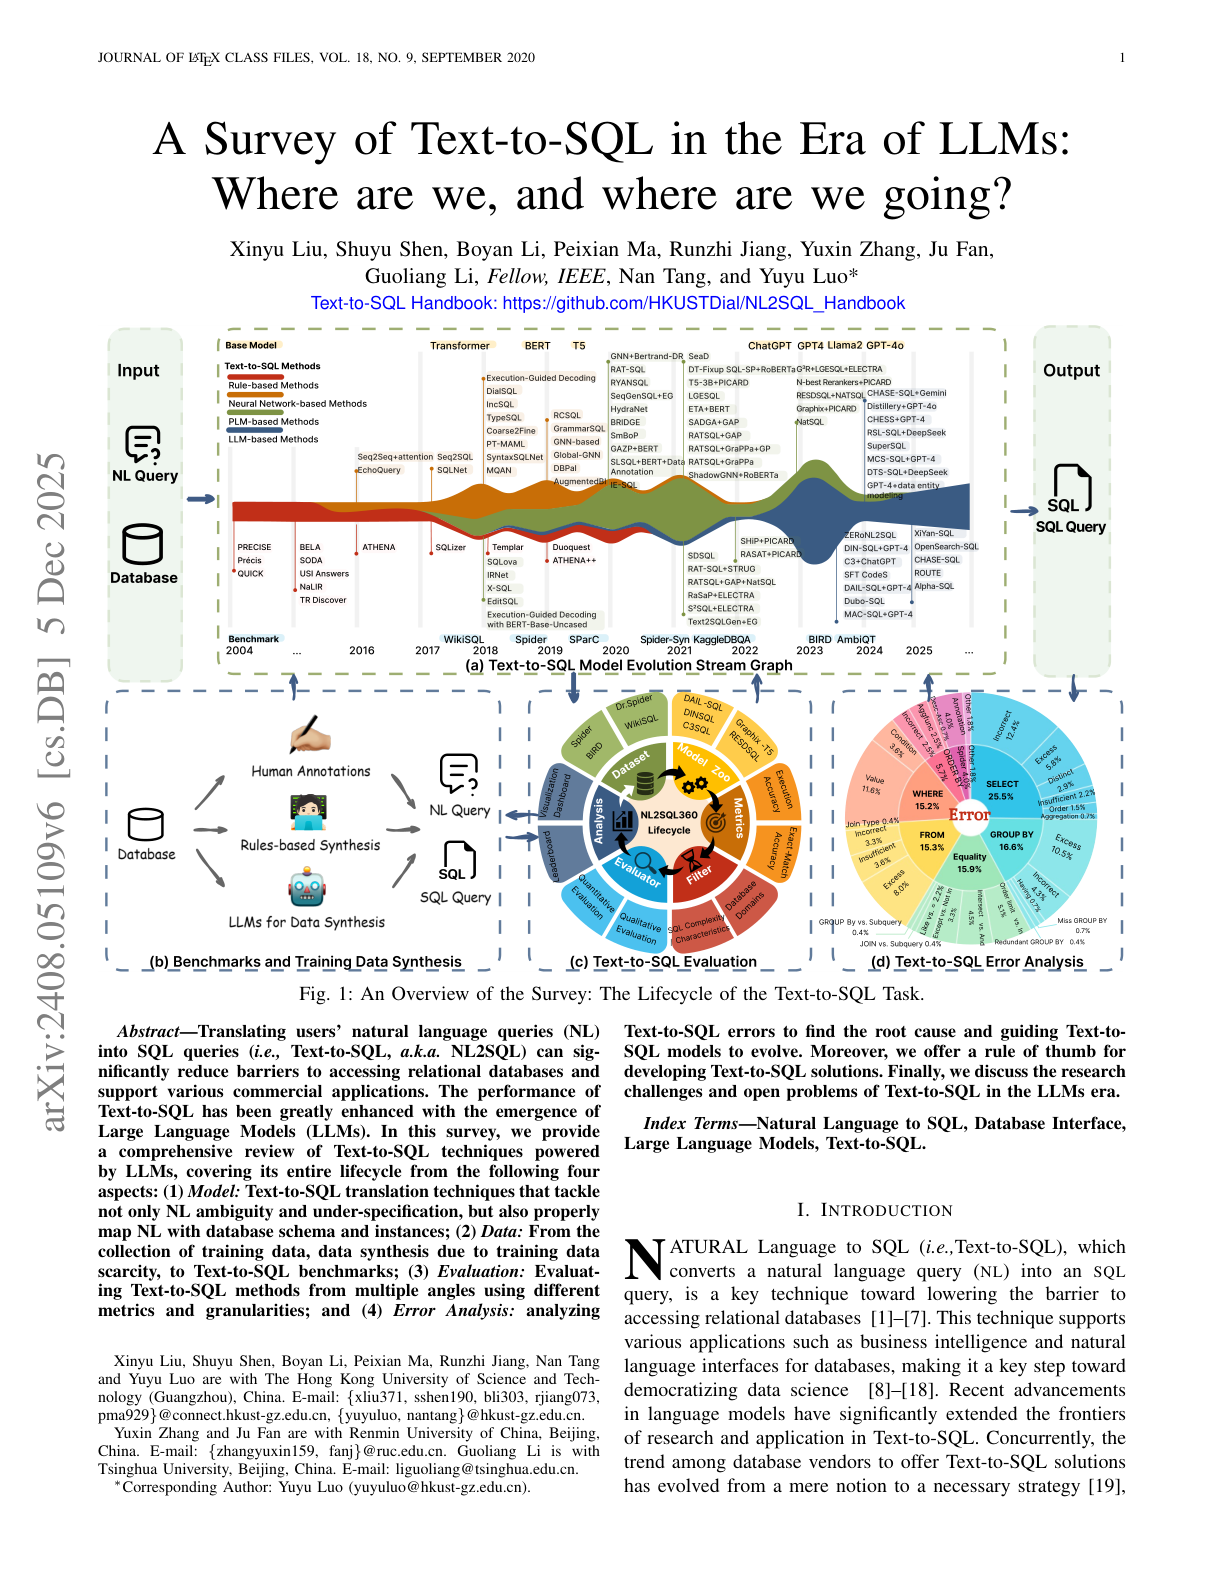
Survey of NL2QL
a comprehensive overview of NL2SQL techniques powered by LLMs; covers models, data collection, evaluation methods, and error analysis.
From LLMs to LLM-based Agents for Sofware Engineering
a survey paper on current practices and solutions for LLM-based agents for software engineering; covers important topics such as requirement engineering, code generation, test generation, and autonomous decision making; it also includes benchmarks, metrics, and models used in different software engineering applications.
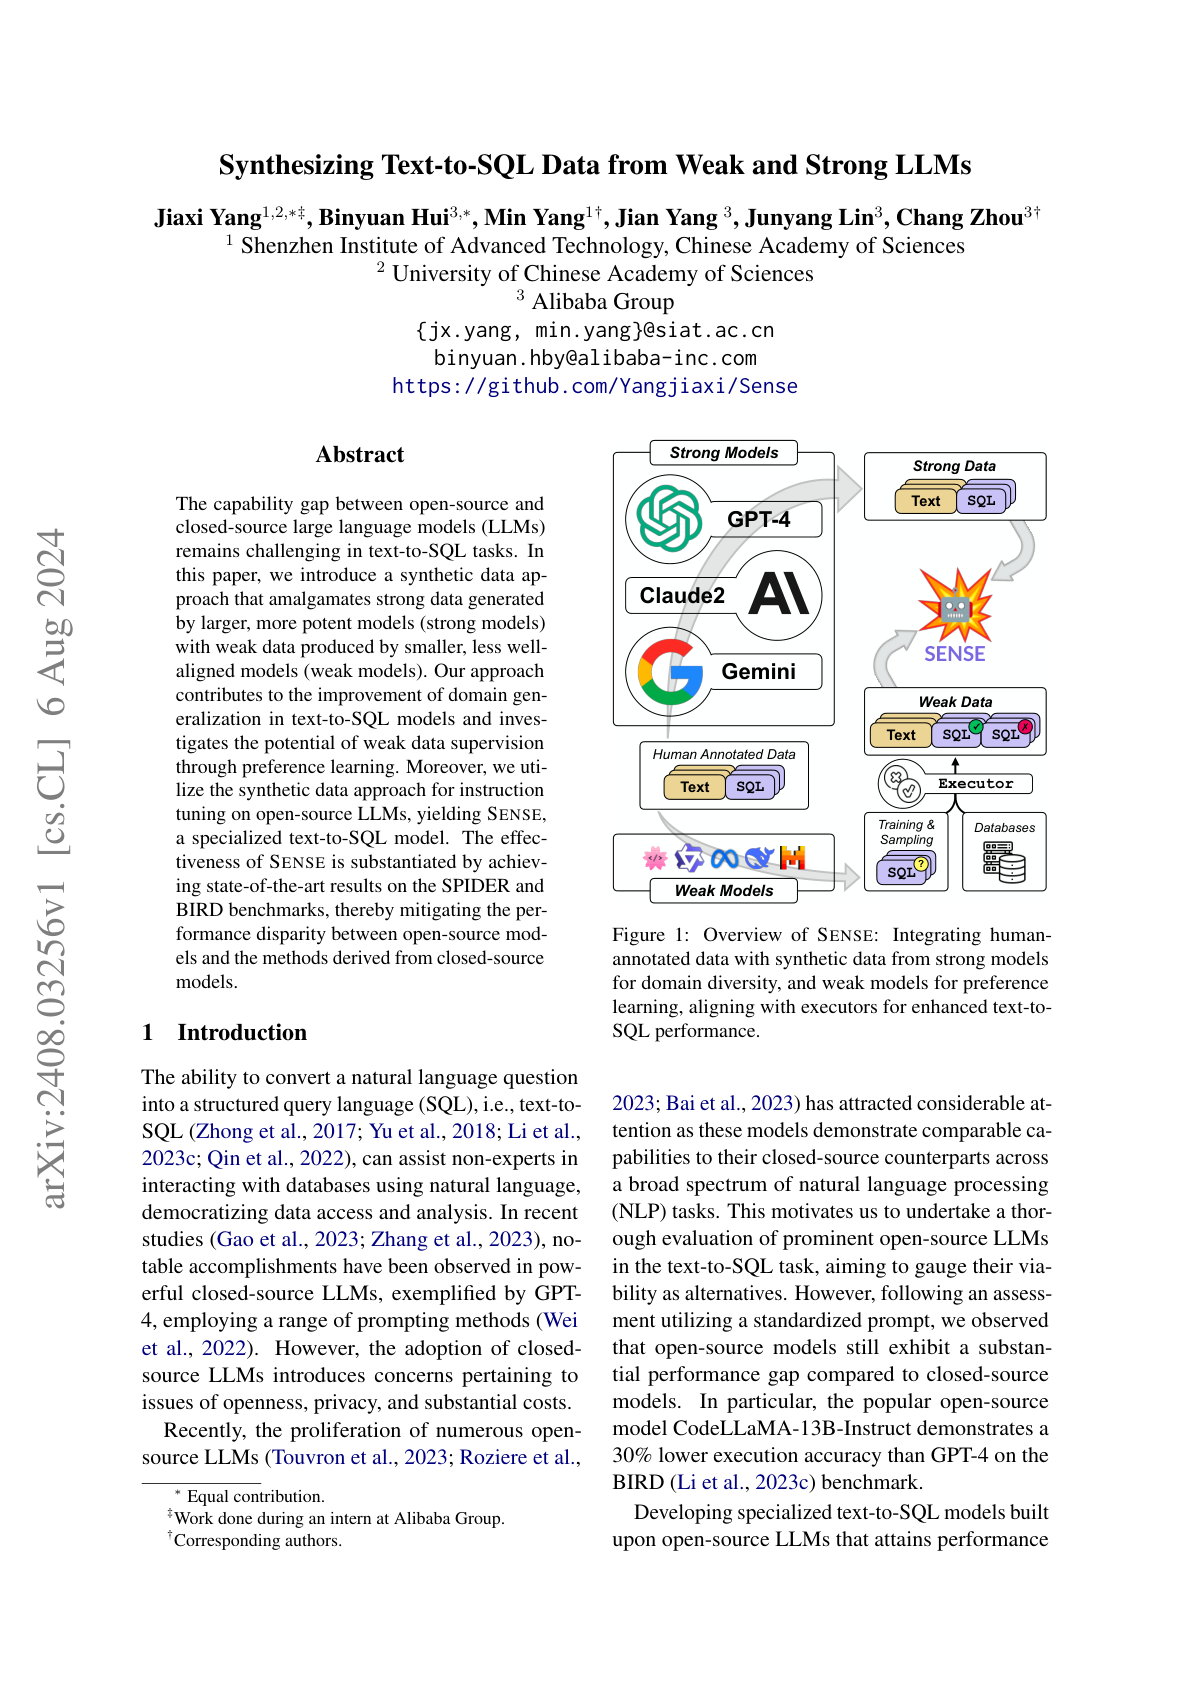
Synthesizing Text-to-SQL Data from Weak and Strong LLMs
proposes integrated synthetic data to build a highly specialized SoTA text-to-SQL model called SENSE; the synthetic data from strong models enhances data diversity while valuable erroneous data from weaker models combined with an executor to learn from execution feedback; preference learning is used to instruction-tune LLMs to learn from both correct and incorrect samples; SENSE achieves state-of-the-art results on the SPIDER and BIRD benchmarks, which bridges the performance gap between open-source models and methods that use closed-source models.
Self-Taught Evaluators
an approach to improve model-based evaluators using synthetic training data only; it first generates contrasting outputs (good and bad model responses) and trains an LLM-as-a-Judge to produce reasoning traces and final judgments; the self-improvement scheme repeats the training process in an iterative way using its improved predictions; claims to outperform LLM-judges such as GPT-4 and match top-performing reward models trained on labeled examples; improves a strong LLM (Llama3-70BInstruct) from 75.4 to 88.3 (88.7 with majority vote) on RewardBench.
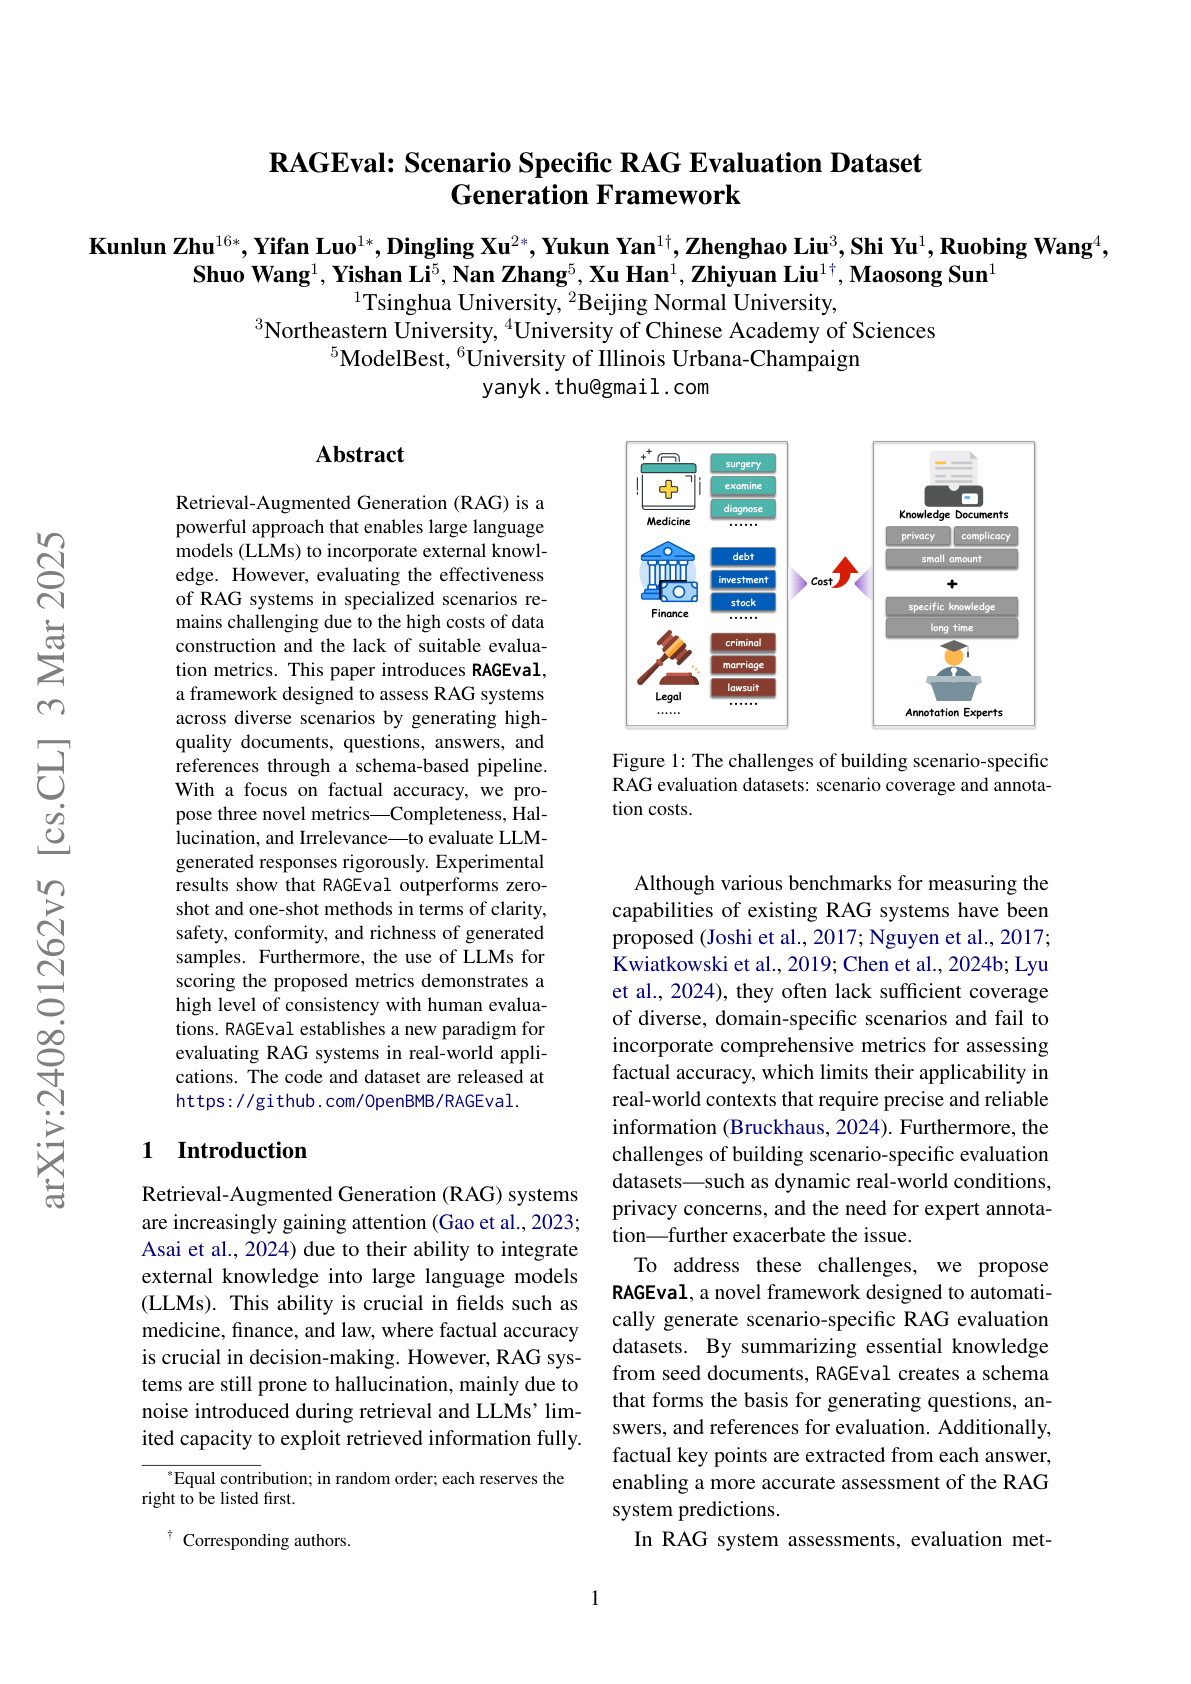
RAGEval
proposes a simple framework to automatically generate evaluation datasets to assess knowledge usage of different LLM under different scenarios; it defines a schema from seed documents and then generates diverse documents which leads to question-answering pairs; the QA pairs are based on both the articles and configurations.
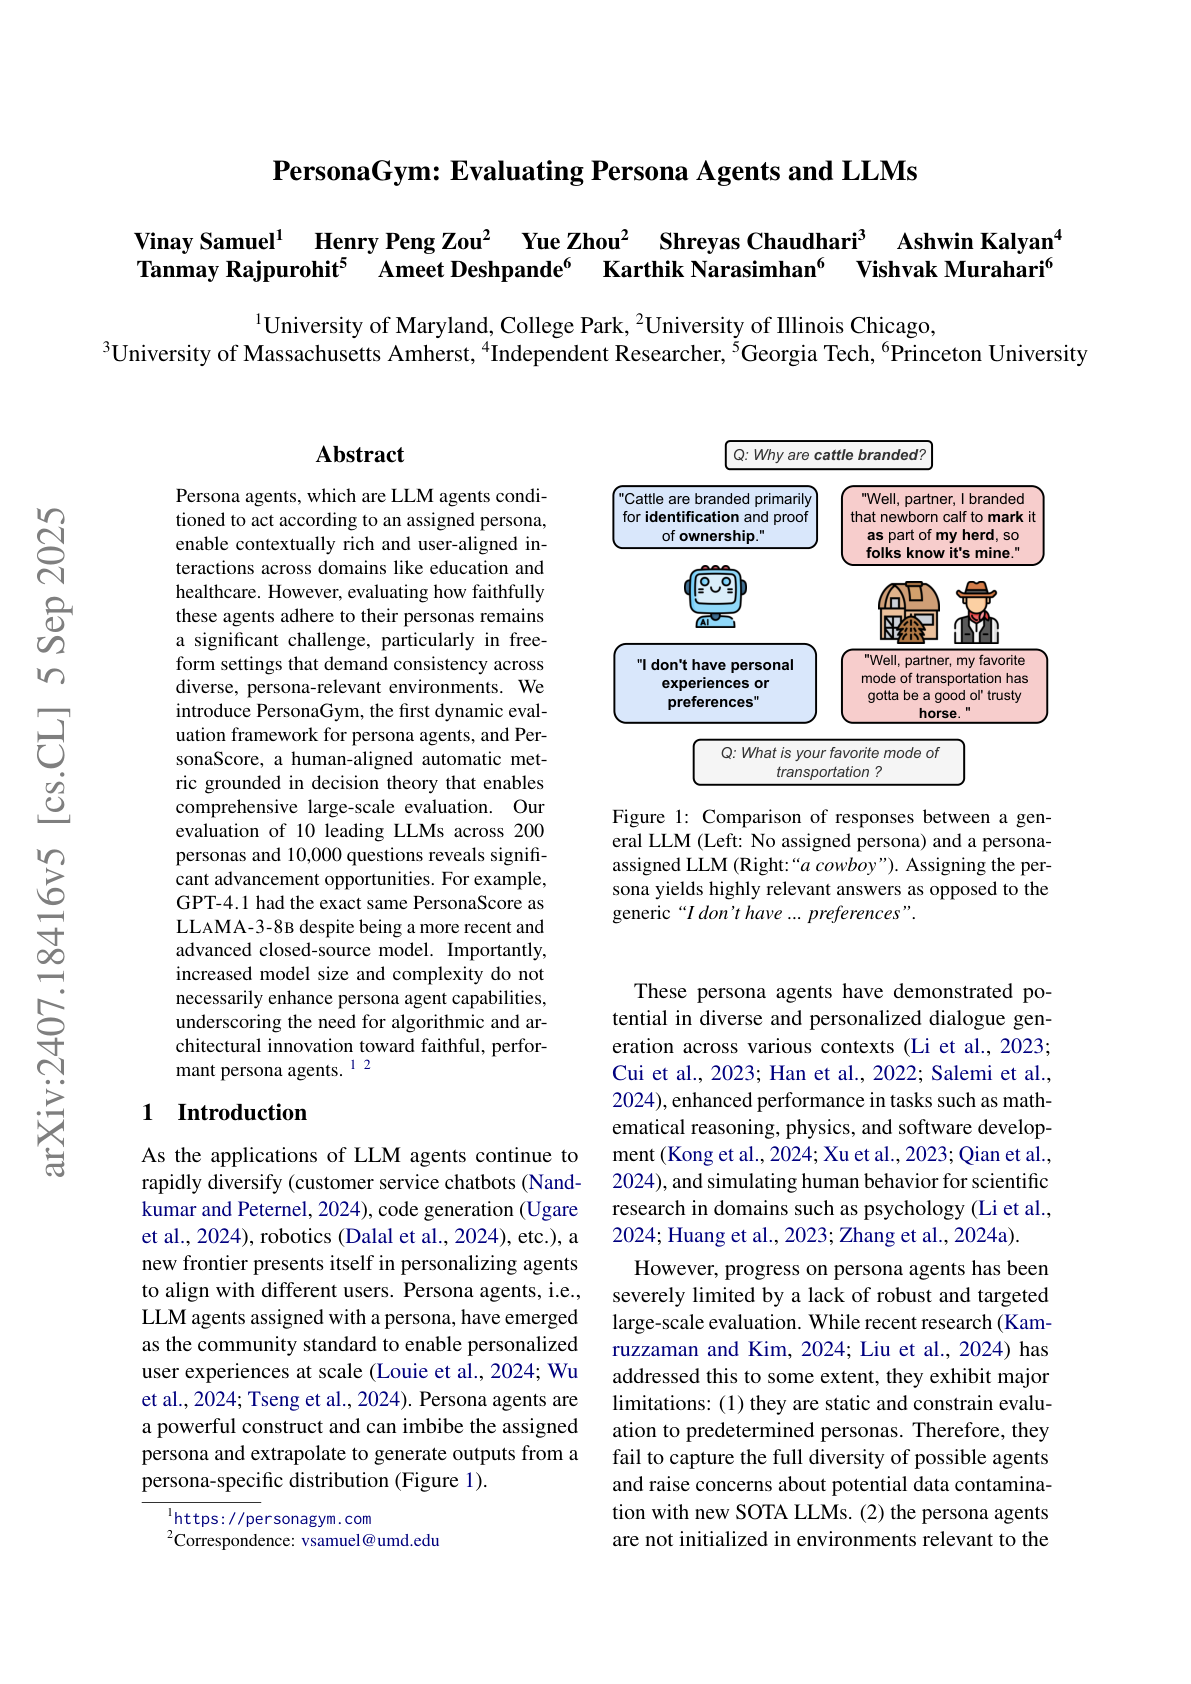
Evaluating Persona Agents
proposes a benchmark to evaluate persona agent capabilities in LLMs; finds that Claude 3.5 Sonnet only has a 2.97% relative improvement in PersonaScore compared to GPT 3.5 despite being a much more advanced model.
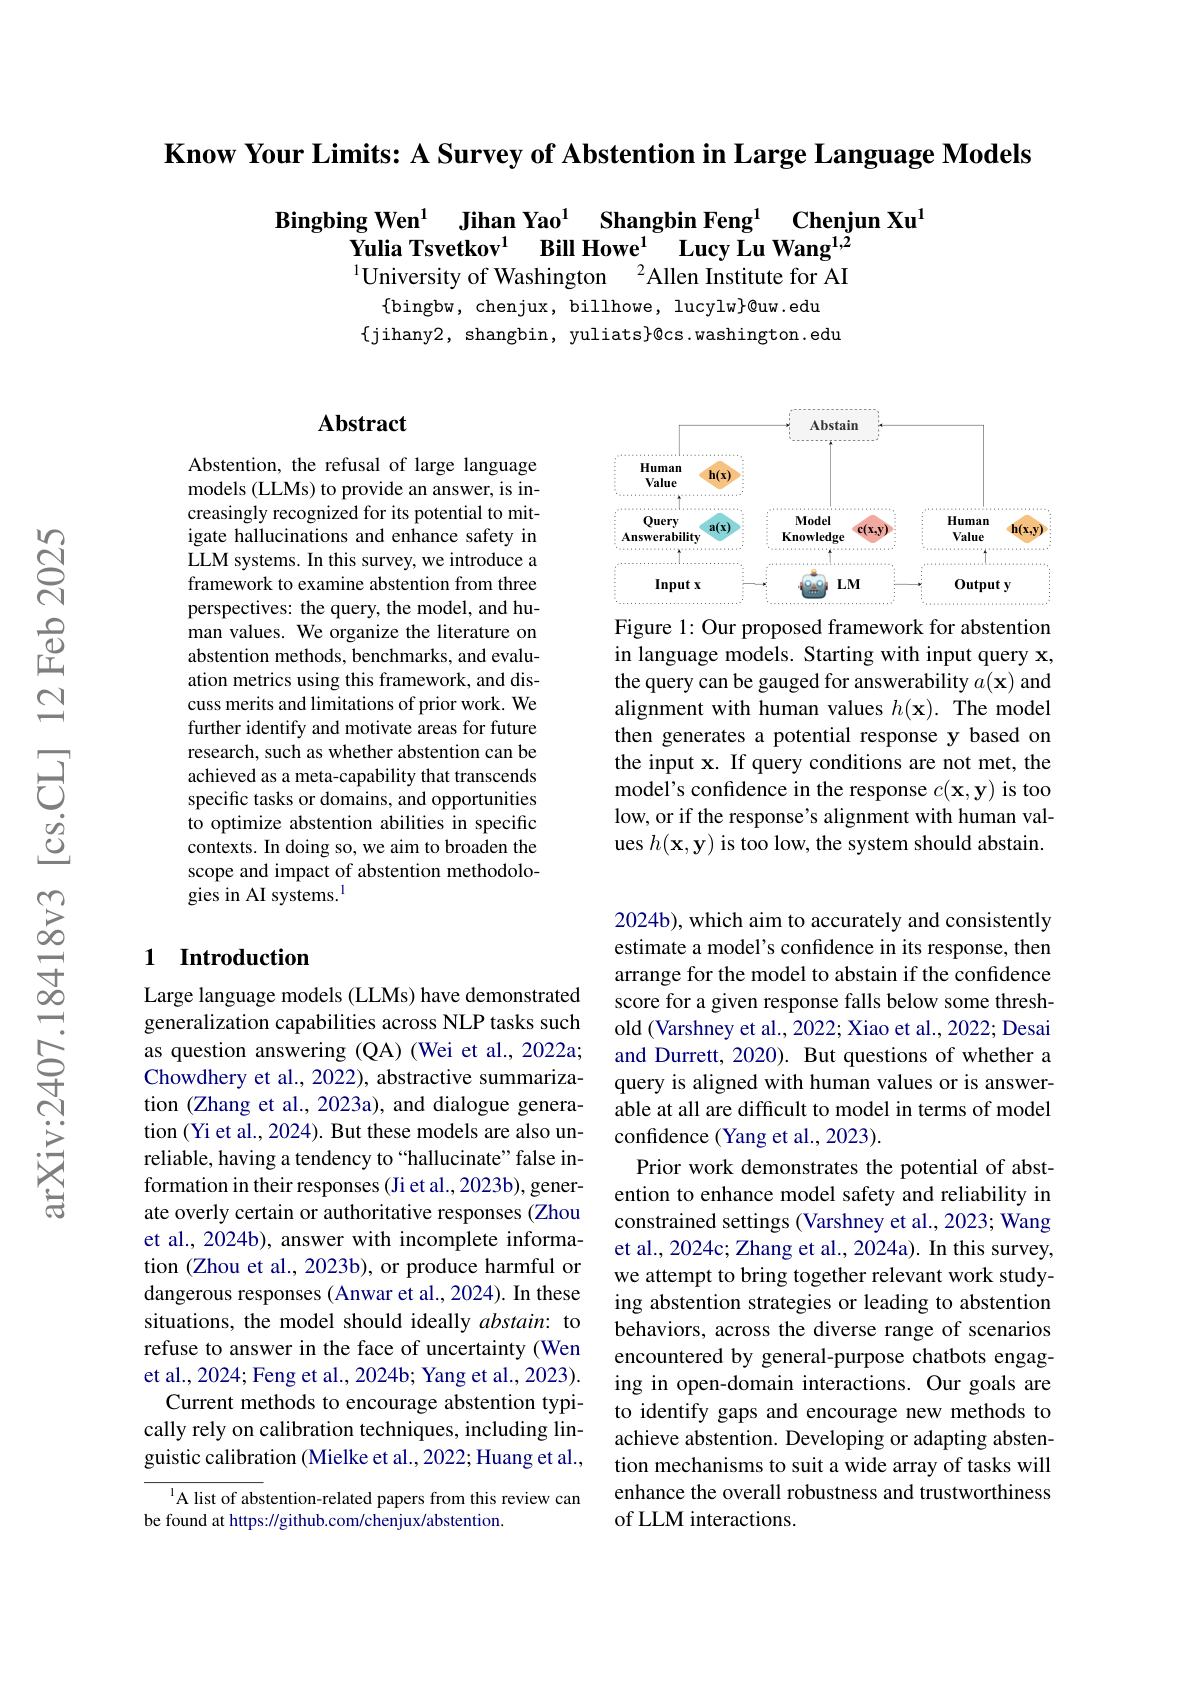
The Art of Refusal
a survey of the current methods used to achieve refusal in LLMs; provides evaluation benchmarks and metrics used to measure abstention in LLMs.
Text-to-SQL Survey
provides a survey on employing LLMs for Text-to-SQL tasks, including prompt engineering techniques, fine-tuning methods, benchmarks, and more.
Can LLMs Do Retrieval and Reasoning in 1 Million Context Window?
proposes a framework (NeedleBench) of progressively challenging tasks to assess the long-context retrieval and reasoning capabilities of LLMs; they also present the Ancestral Trace Challenge that increases the need for complex logical reasoning which is common in real-world long-context tasks; their findings suggest that current LLMs struggle to handle reasoning tasks with complex logical relationships, even with texts shorter than 2K tokens.
RankRAG
introduces a new instruction fine-tuning framework to perform effective context ranking and answering generation to enhance an LLM’s RAG capabilities; it leverages a small ranking dataset to outperform existing expert ranking models; shows that a Llama3-RankRAG significantly outperforms Llama3-ChatQA-1.5 and GPT-4 models on nine knowledge-intensive benchmarks.