AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup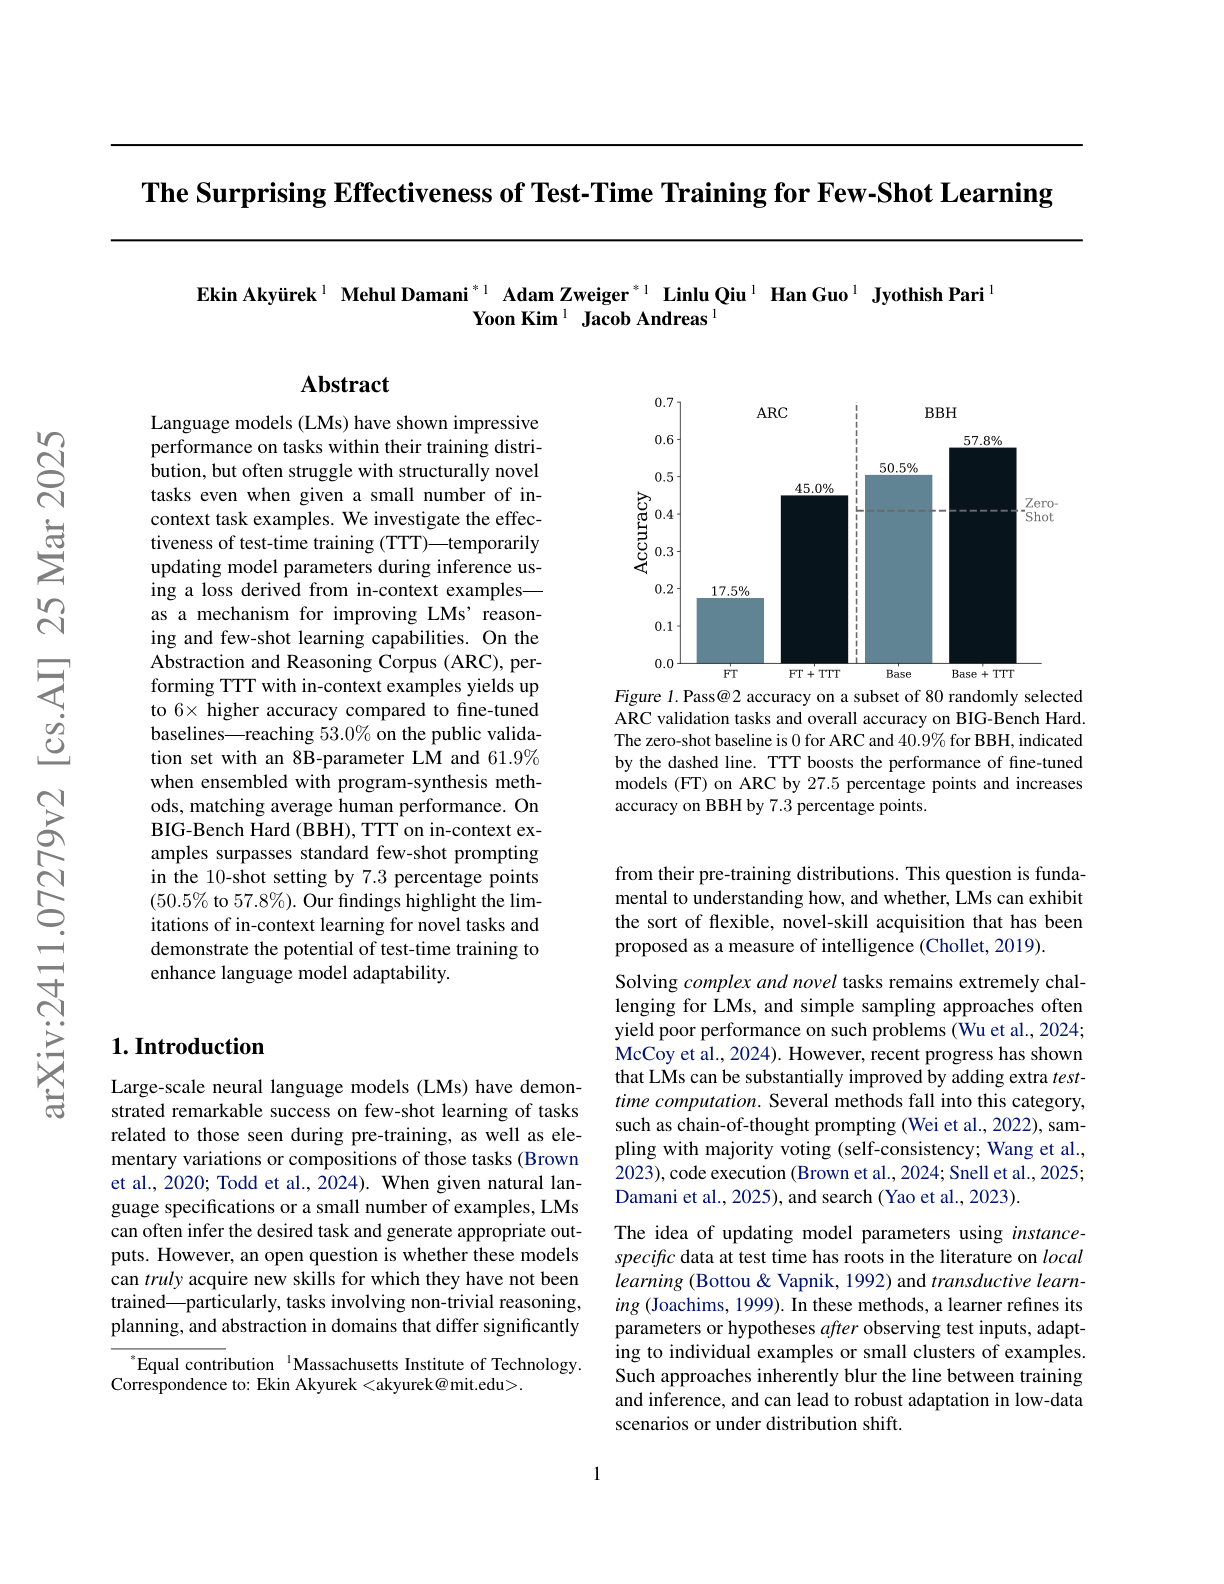
The Surprising Effectiveness of Test-Time Training for Abstract Reasoning
explores test-time training (TTT) - updating model parameters temporarily during inference - for improving an LLM's abstract reasoning capabilities using the ARC benchmark; identifies three crucial components: initial fine-tuning on similar tasks, auxiliary task format and augmentations, and per-instance training; TTT significantly improves performance, achieving up to 6x improvement in accuracy compared to base fine-tuned models; when applying TTT to an 8B LLM, they achieve 53% accuracy on ARC's public validation set, improving the state-of-the-art for neural approaches by nearly 25%; by ensembling their method with program generation approaches, they achieve state-of-the-art public validation accuracy of 61.9%, matching average human performance; the findings suggest that explicit symbolic search is not the only path to improved abstract reasoning in LLMs; test-time training applied to continued training on few-shot examples can be highly effective.
Number Understanding of LLMs
provides a comprehensive analysis of the numerical understanding and processing ability (NUPA) of LLMs; finds that naive finetuning can improve NUPA a lot on many but not all tasks; it also reports that techniques designed to enhance NUPA prove ineffective for finetuning pretrained models; explores chain-of-thought techniques applied to NUPA and suggests that chain-of-thought methods face scalability challenges, making them difficult to apply in practical scenarios.
A Theoretical Understanding of CoT
finds that adding correct and incorrect reasoning paths in demonstrations improves the accuracy of intermediate steps and CoT; the proposed method, Coherent CoT, significantly improves performance on several benchmarks; in the Tracking Shuffled Objects dataset, Gemini Pro shows a 6.60% improvement (from 58.20% to 64.80%), and in Penguins in a Table, DeepSeek 67B demonstrates an increase of 6.17% (from 73.97% to 80.14%).
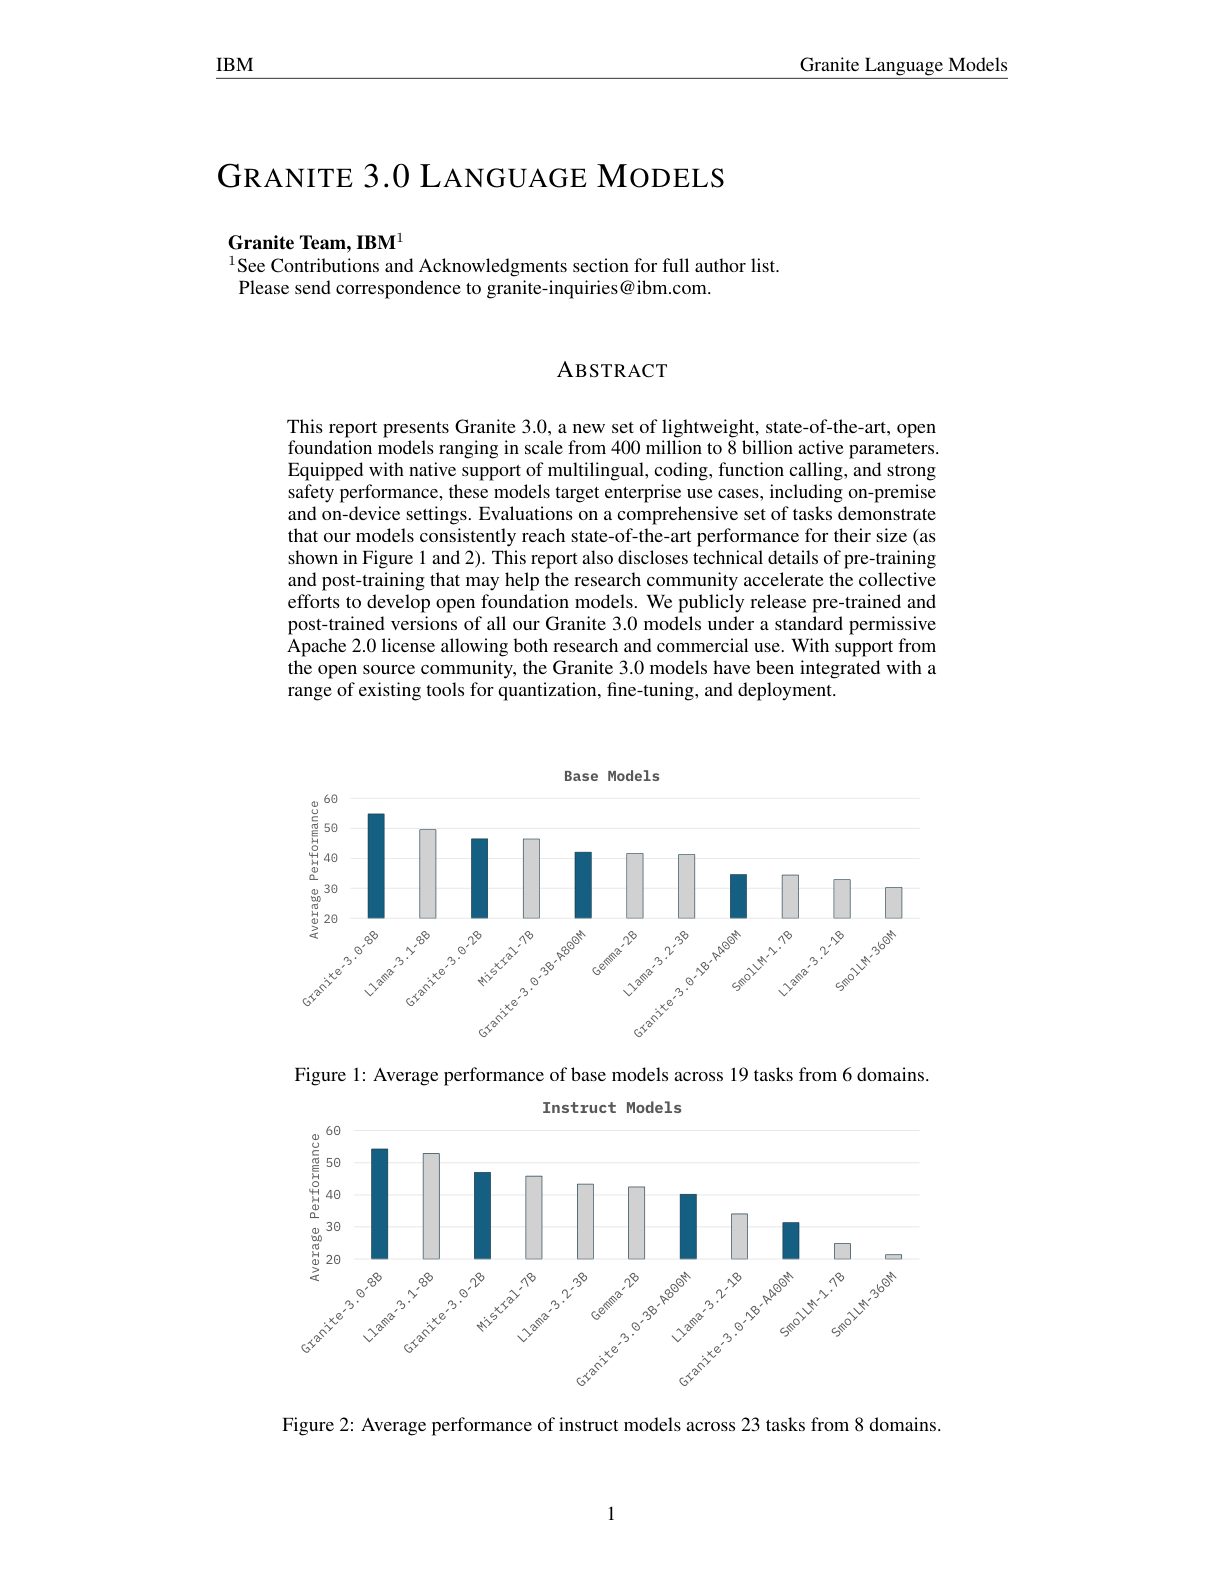
Granite 3.0
presents lightweight foundation models ranging from 400 million to 8B parameters; supports coding, RAG, reasoning, and function calling, focusing on enterprise use cases, including on-premise and on-device settings; demonstrates strong performance across academic benchmarks for language understanding, reasoning, coding, function calling, and safety.
LLMs Reflect the Ideology of their Creators
finds that LLMs exhibit a diverse ideological stance which reflects the worldview of its creators; finds consistent normative differences between how the same LLM responds in Chinese compared to English; identifies normative disagreements between Western and non-Western LLMs about prominent actors in geopolitical conflicts.
Reasoning Patterns of OpenAI’s o1 Model
when compared with other test-time compute methods, o1 achieved the best performance across most datasets; the authors observe that the most commonly used reasoning patterns in o1 are divide and conquer and self-refinement; o1 uses different reasoning patterns for different tasks; for commonsense reasoning tasks, o1 tends to use context identification and emphasize constraints; for math and coding tasks, o1 mainly relies on method reuse and divide and conquer.
GSM-Symbolic
tests several SoTA models on a benchmark created with symbolic templates that enable diverse mathematical problems; they find that LLMs exhibit variance when responding to variations of the same questions; the performance of all the models declines by adjusting the numerical values in the question; as questions are made more challenging (e.g., increasing the number of clauses) the performance significantly deteriorates; the authors hypothesize that the observed decline in performance is due to a lack of logical reasoning in current LLMs.
RATIONALYST
a model for process-supervision of reasoning that enables generalization across diverse reasoning tasks; this process is achieved with pre-training on a collection of 79k rationales from the Pile and a combination of reasoning datasets with minimal human intervention; fine-tuned from LLaMa-3-8B, the proposed model improves the accuracy of reasoning by an average of 3.9% on 7 reasoning benchmarks.
An Analysis of o1-preview
reports that large reasoning models like o1-preview, while improving on more difficult tasks, display similar qualitative trends as previous LLMs; o1 is sensitive to the probability of examples and tasks, performing better and requiring fewer “thinking tokens” in high-probability settings than in low-probability ones.
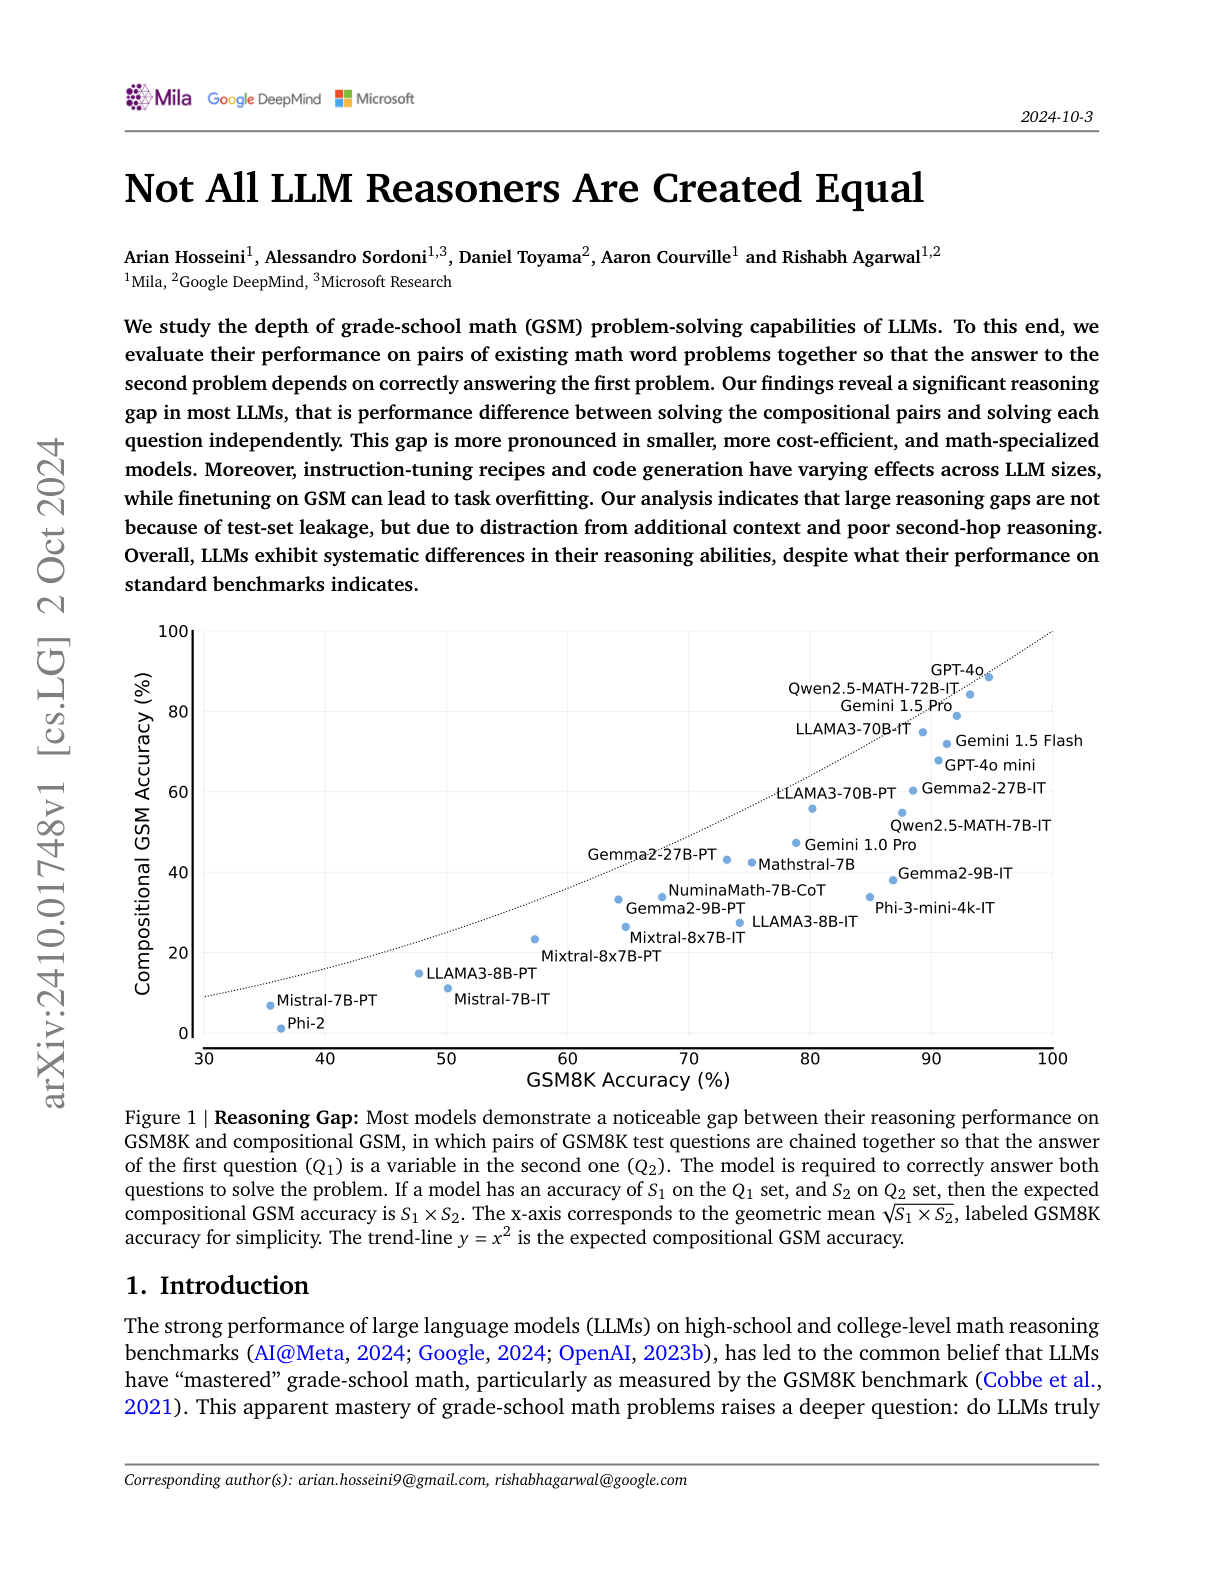
Not All LLM Reasoners Are Created Equal
investigates in depth the grade-school math problem-solving capabilities of LLMs; reports that LLMs show a significant gap in reasoning; finds that LLMs display a huge performance difference when solving compositional pairs and solving questions independently.
Evaluation of o1
provides a comprehensive evaluation of OpenAI's o1-preview LLM; shows strong performance across many tasks such as competitive programming, generating coherent and accurate radiology reports, high school-level mathematical reasoning tasks, chip design tasks, anthropology and geology, quantitative investing, social media analysis, and many other domains and problems.
Logic-of-Thought
proposes a new prompting technique called Logic-of-Thought (LoT) which employs propositional logic to generate and inject expanded logical information from the input context; it enhances CoT performance on the ReClor dataset by +4.35%; it improves CoT+SelfConsistency’s performance on LogiQA by +5%; it also boosts the performance of ToT on the ProofWriter dataset by +8%.
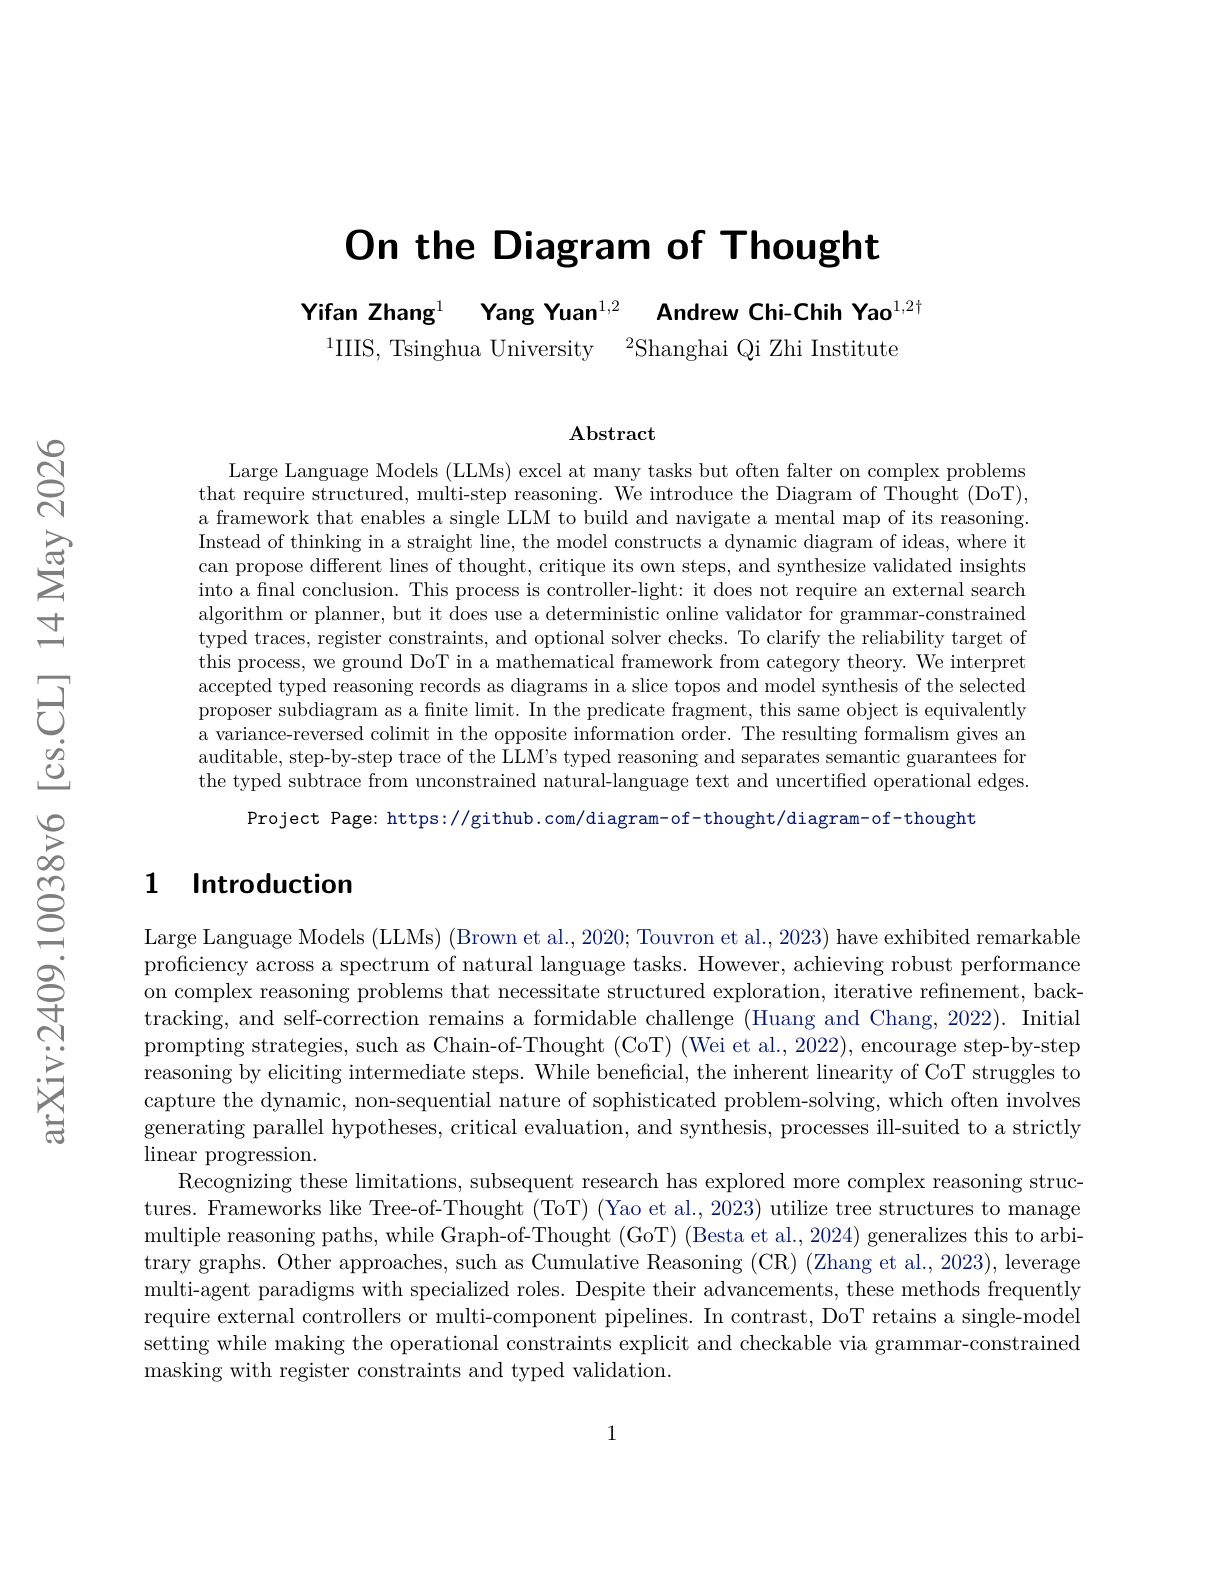
Diagram of Thought (DoT)
enhances the reasoning capabilities of LLMs through mathematical rigor; DAT models iterative reasoning in LLM as the construction of a directed acyclic graph; it integrates propositions, critiques, refinement, and verification into a unified DAG structure; this allows DoT to capture complex logical deduction beyond linear or tree-based approaches.
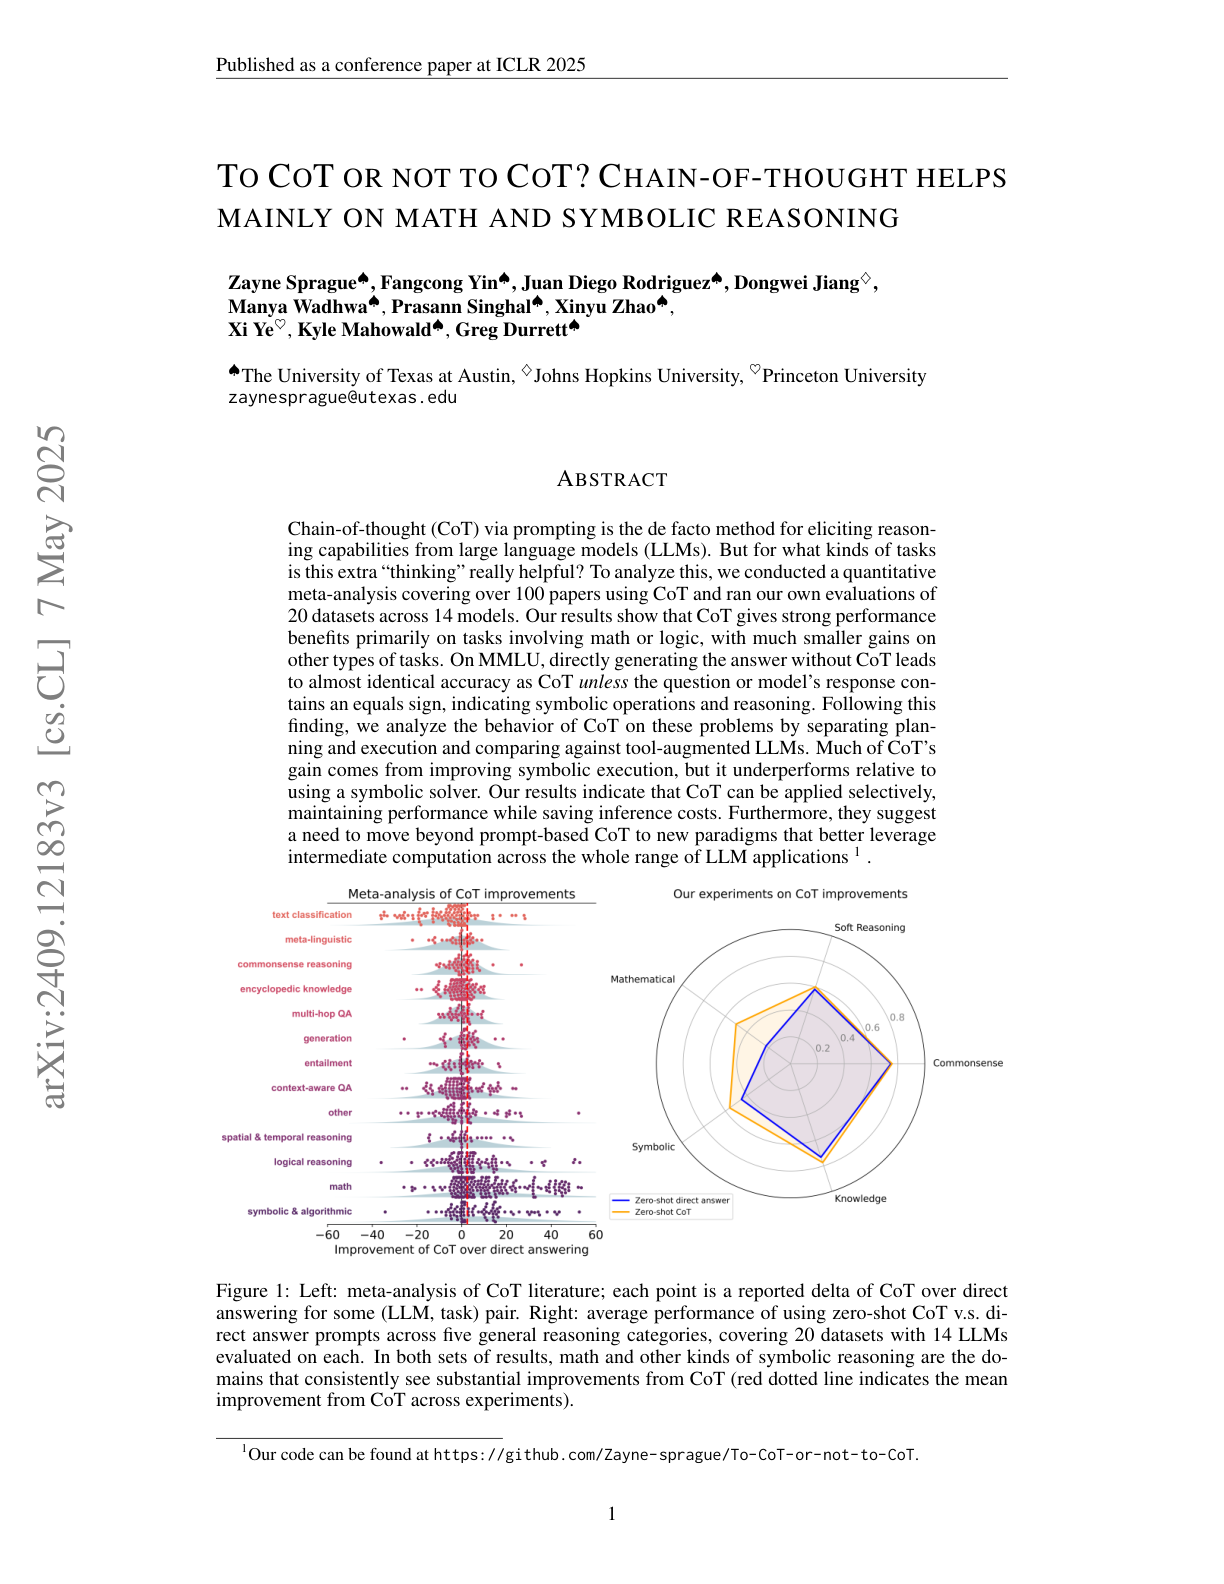
To CoT or not to CoT?
investigates what kinds of tasks benefit the most from chain-of-thought (CoT) prompting; after a meta-analysis on 100+ papers and several evaluations, it finds that CoT produces strong performance benefits primarily on tasks involving math and logic; they find that most of the CoT gain comes from improving symbolic execution, but a symbolic solver outperforms it.
Iteration of Thought
proposes the Iteration of Thought (IoT) framework to enhance the LLM responses and reasoning capabilities with adaptive reasoning paths; it leverages an inner dialogue agent, acting as a guide, to dynamically adjust reasoning paths which allows adaptive cross-path exploration and enhance response accuracy; it's different from CoT and ToT (both rigid processes) in that its prompt generation is a dynamic process that allows it to adapt.
Learning to Reason with LLMs
a new family of LLMs trained with reinforcement learning to reason before it responds to complex tasks; it produces a long internal chain of thought and exceeds in science, code, and math-related tasks; ranked in the 49th percentile in the 2024 International Olympiad in Informatics and exceeds human PhD-level accuracy on science-related benchmarks. -
Strategic Chain-of-Thought
a method to refine LLM performance by incorporating strategic knowledge before the intermediate CoT reasoning steps; the problem-solving strategy helps to guide the generation of the CoT paths and final answers; claims to achieve a 21.05% increase on the GSM8K datasets using the Llama3-8b model.
Enhancing Robustness in LLMs
proposes a two-stage prompting technique to remove irrelevant information from context; it serves as a self-mitigation process that first identifies the irrelevant information and then filters it out; this leads to enhancement in robustness of the model and overall better performance on reasoning tasks.
PEDAL
uses a hybrid self-ensembling approach (based on diverse exemplars) to improve the overall performance of LLMs; specifically, it uses diverse exemplars to generate multiple candidate responses and then aggregates them using an LLM to generate a final response; this approach achieves better accuracy compared to greedy decoding and lower cost compared to self-consistency approaches.
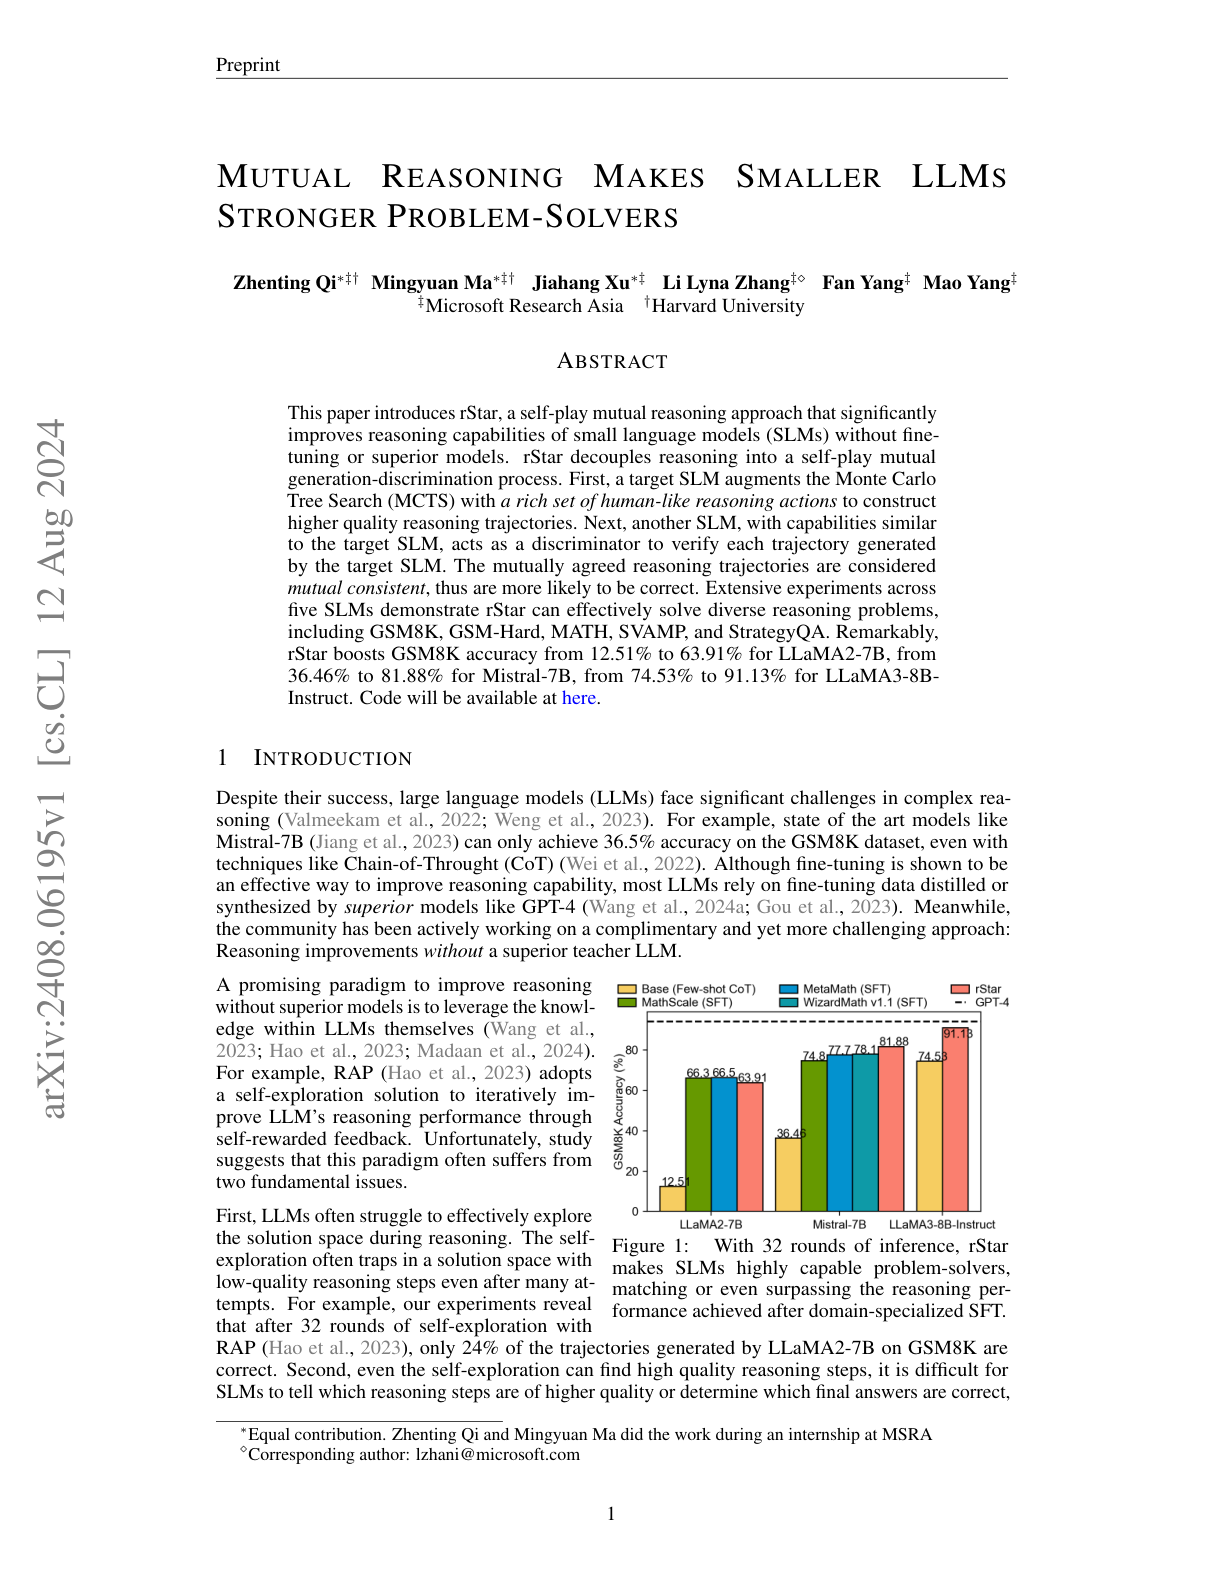
rStar
introduces self-play mutual reasoning to improve the reasoning capabilities of small language models without fine-tuning or superior models; MCTS is augmented with human-like reasoning actions, obtained from SLMs, to build richer reasoning trajectories; a separate SLM provides unsupervised feedback on the trajectories and the target SLM selects the final reasoning trajectory as the answer; rStar boosts GSM8K accuracy from 12.51% to 63.91% for LLaMA2-7B and consistently improves the accuracy of other SLMs.
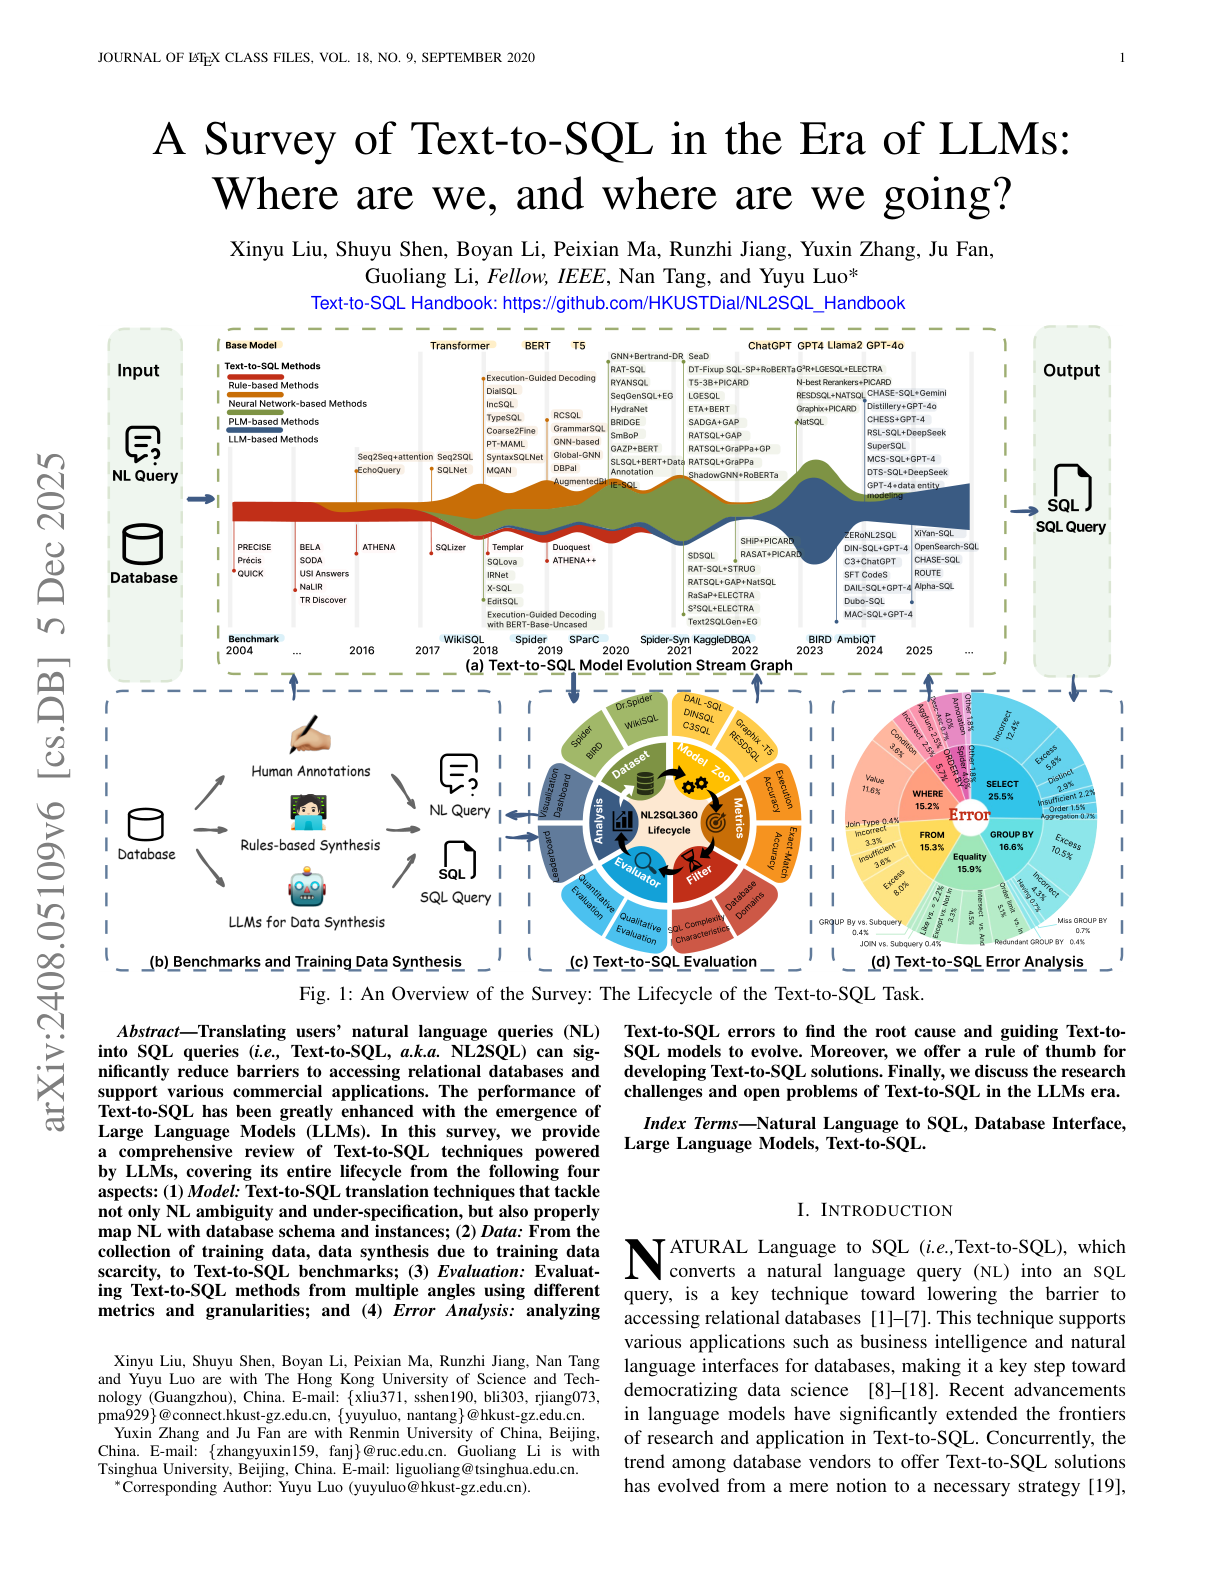
Scaling LLM Test-Time Compute Optimally
investigates the scaling behaviors of inference-time computation in LLMs; in particular, it analyses how much an LLM can be improved provided a fixed amount of inference-time compute; finds that the effectiveness of different scaling approaches varies by difficulty of prompt; it then proposes an adaptive compute-optimal strategy that can improve efficiency by more than 4x compared to a best-of-N baseline; reports that in a FLOPs-matched evaluation, optimally scaling test-time compute can outperform a 14x larger model.
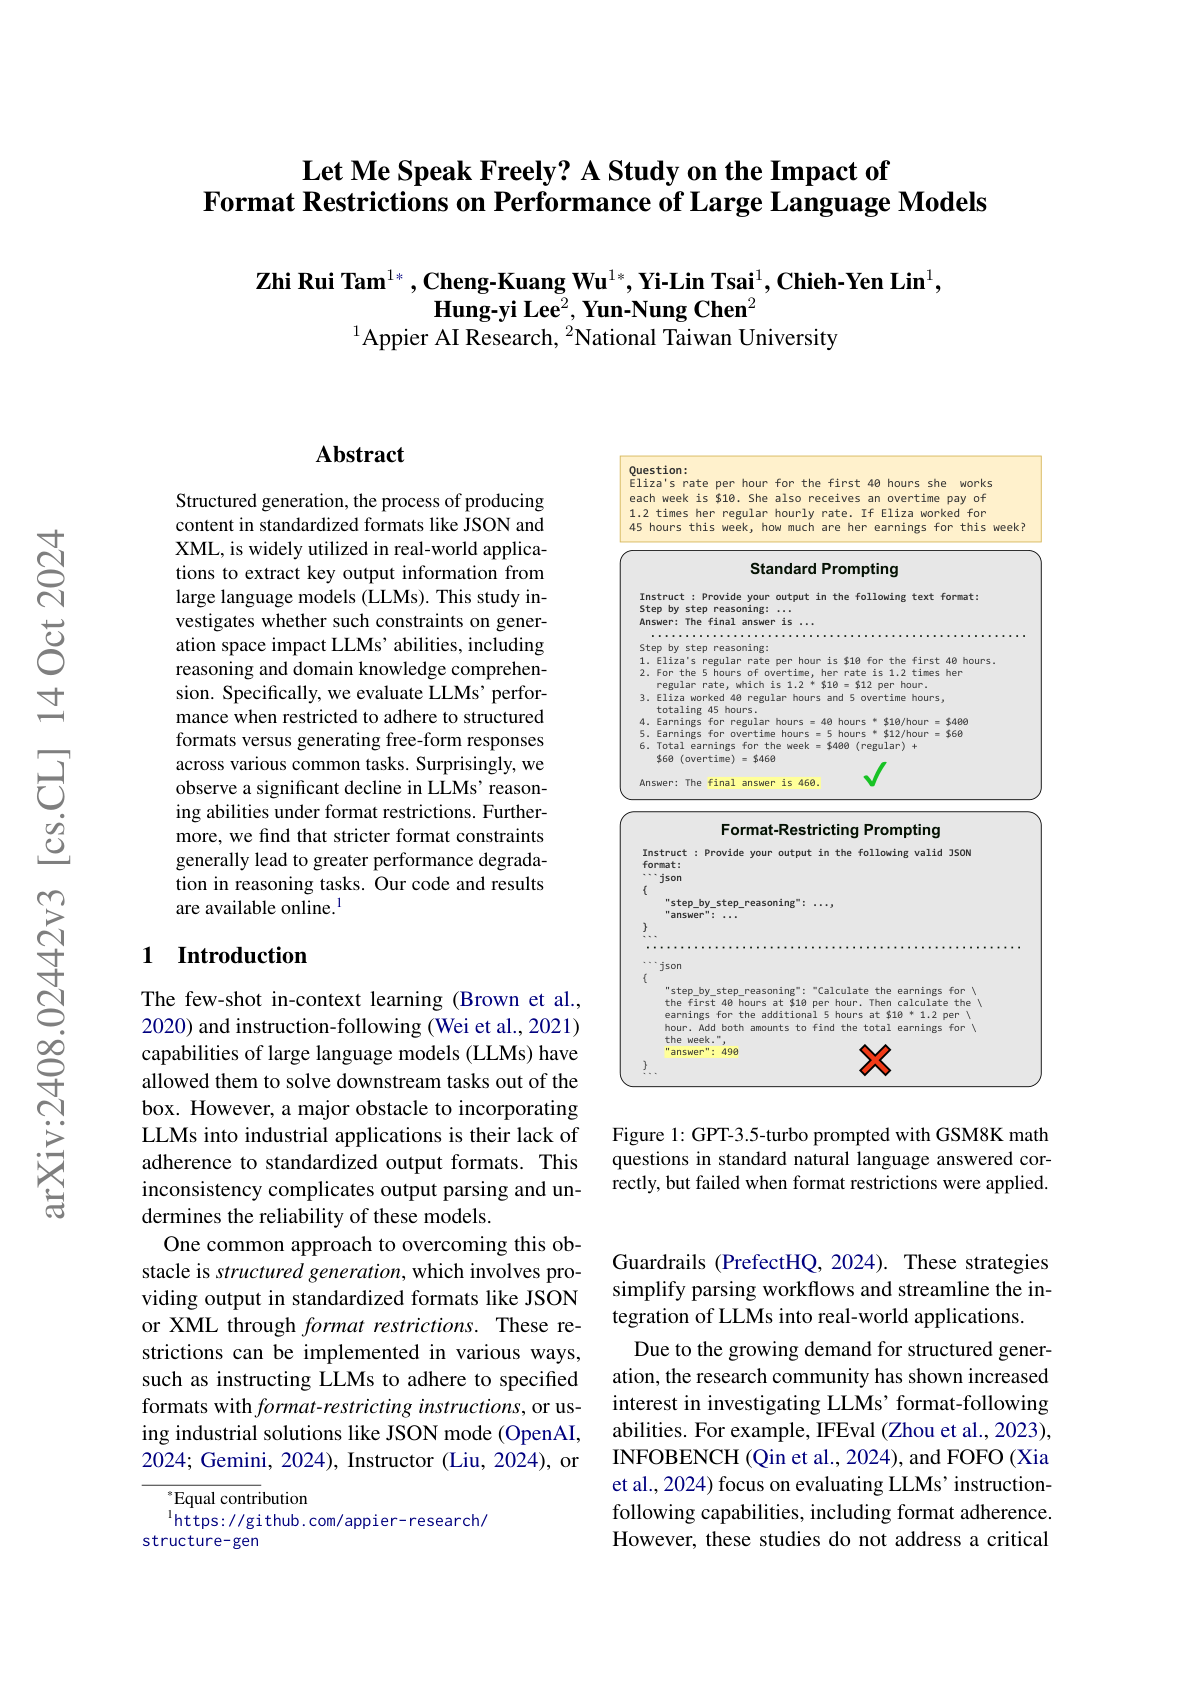
Structured Generation Limits Reasoning
investigates if structured generation can impact an LLM’s reasoning and domain knowledge comprehensive capabilities; observes that there is a significant decline in LLM’s reasoning abilities when applying format restrictions compared to free-form responses; this degradation effect is further amplified when applying stricter format constraints to reasoning tasks.
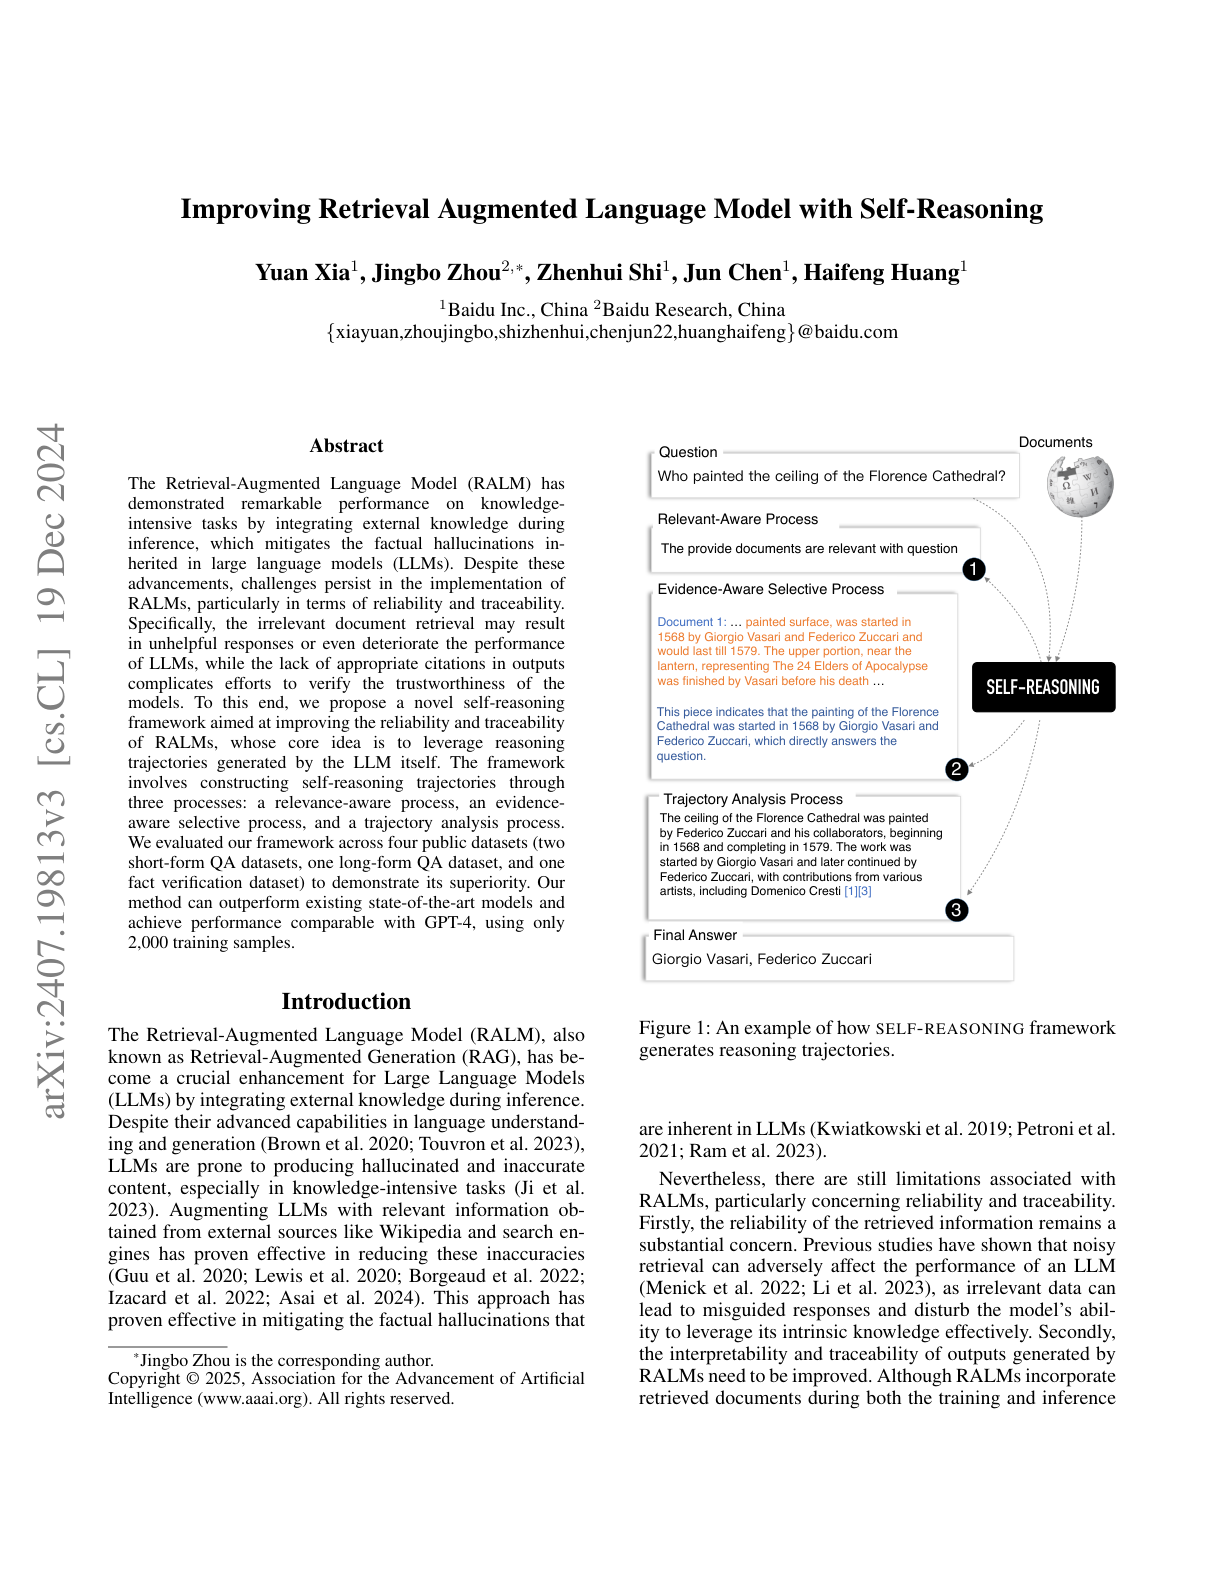
Improved RAG with Self-Reasoning
presents an end-to-end self-reasoning framework to improve the reliability and traceability of RAG systems; leverages the reasoning trajectories generated by the LLM itself; the LLM is used to carry out the following 3 processes: 1) relevance-aware: judges the relevance between the retrieved documents and the question, 2) evidence-aware selective: chooses and cites relevant documents, and then automatically selects snippets of key sentences as evidence from the cited documents, and 3) trajectory analysis: generates a concise analysis based on all gathered self-reasoning trajectories generated by the previous 2 processes and then provides the final inferred answer; this method helps the model to be more selective, reason and distinguish relevant and irrelevant documents, therefore improving the accuracy of the overall RAG system; the framework achieves comparable performance to GPT-4 with only 2K training samples (generated by GPT-4).
Constrained-CoT
limits the model reasoning output length without sacrificing performance; shows that constraining the reasoning of LLaMA2-70b to 100 words improves the accuracy from 36.01% (CoT) to 41.07% (CCoT) on GSM8K, while reducing the average output length by 28 words.