AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers withClaude CodeCodex
npx @dair-ai/mcp setup
Wanda
A simple, effective pruning approach for LLMs requiring no retraining.
AudioPaLM
Fuses PaLM-2 and AudioLM into a multimodal architecture supporting speech understanding and generation.
Voicebox
Meta's all-in-one generative speech model supporting 6 languages and many speech tasks in-context.
FinGPT
An open-source LLM for the finance sector with a data-centric approach.
Crowd Workers Widely Use LLMs for Text Production
Empirical evidence that 33-46% of MTurk crowd workers used LLMs on text tasks.
Reliability of Watermarks for LLMs
Studies whether watermarks survive human rewriting and LLM paraphrasing.
Applications of Transformers
A new survey highlighting major applications of Transformers across deep learning.
Benchmarking NN Training Algorithms (AlgoPerf)
A new benchmark for rigorously evaluating optimizers using realistic workloads.
Unifying LLMs & Knowledge Graphs
A roadmap for combining LLMs with knowledge graphs for stronger reasoning.
Augmenting LLMs with Long-term Memory (LongMem)
Enables LLMs to memorize long history via memory-augmented adaptation.
TAPIR
Tracks any queried point on any physical surface throughout a video sequence faster than real-time.
Mind2Web
A dataset for evaluating generalist web agents with 2,350 tasks across 137 websites and 31 domains.
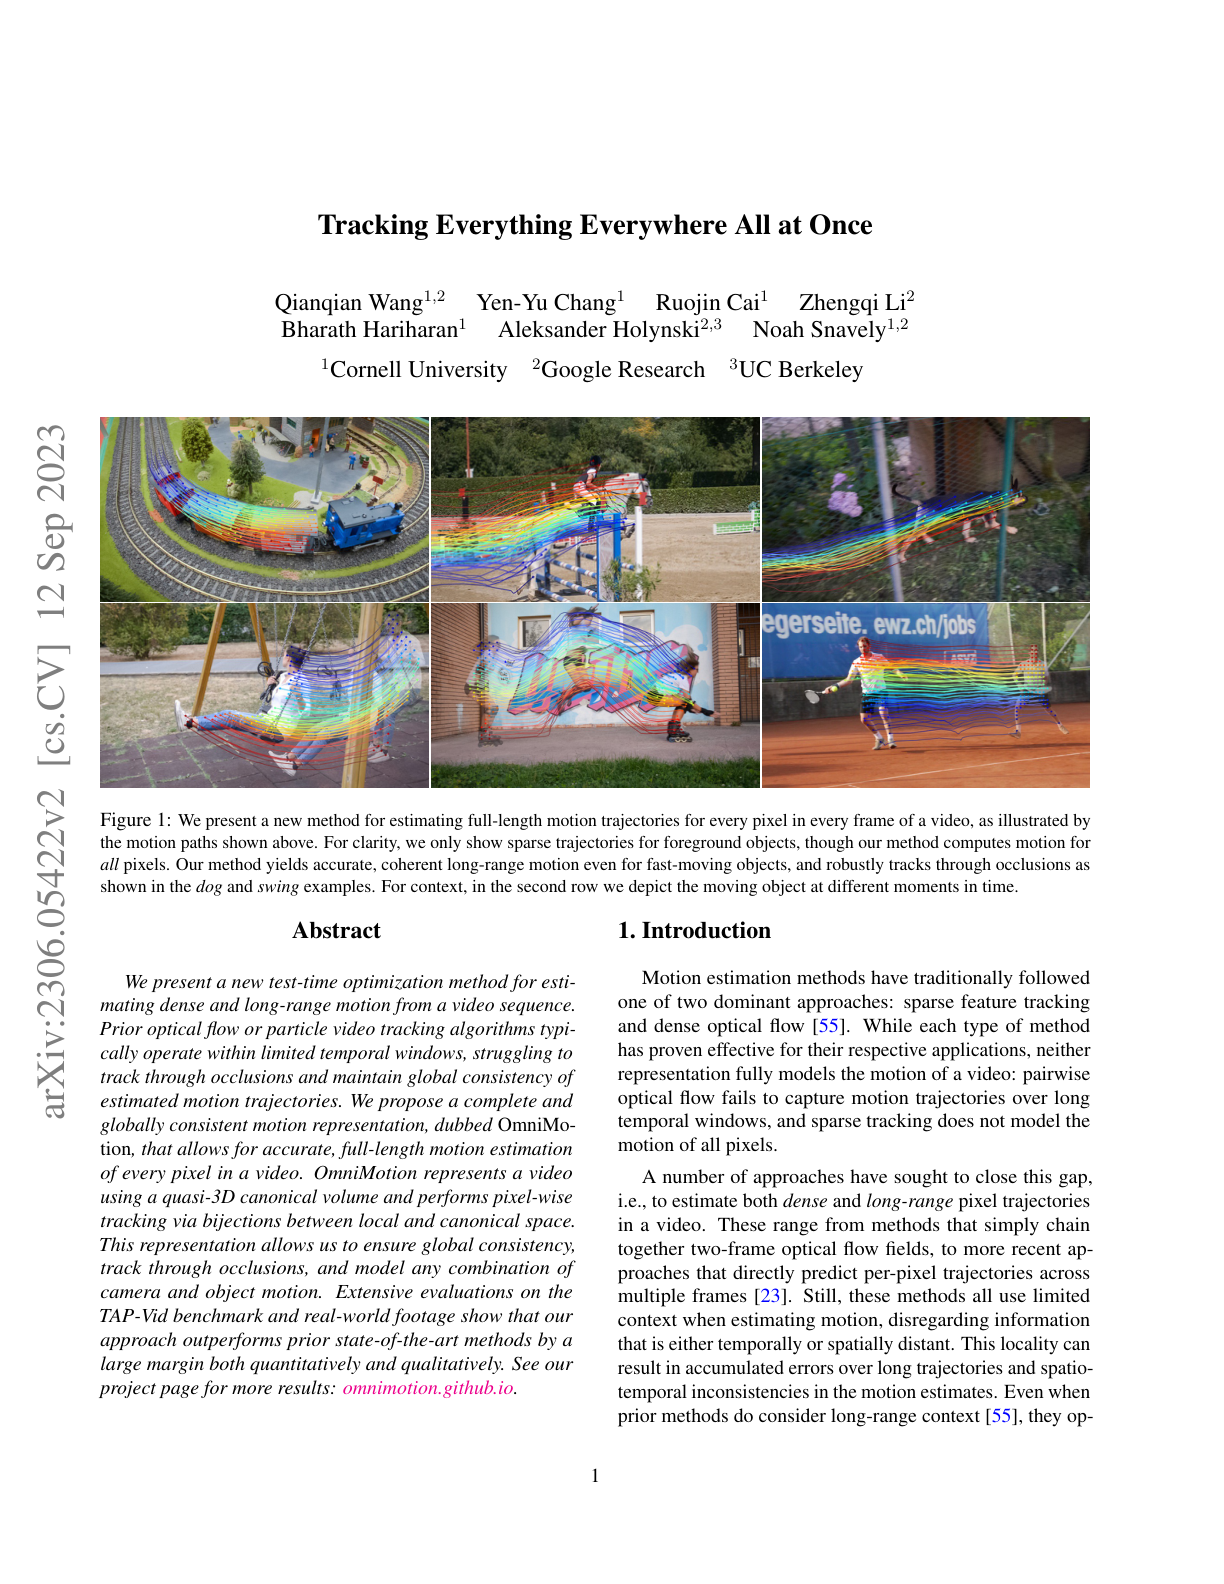
Tracking Everything Everywhere All at Once (OmniMotion)
Test-time optimization for dense, long-range motion estimation.
AlphaDev
DeepMind's deep RL agent discovering faster sorting algorithms from scratch, now in LLVM.
Sparse-Quantized Representation (SpQR)
Tim Dettmers' near-lossless LLM compression technique.
MusicGen
A simple and controllable model for music generation using a single-stage Transformer.
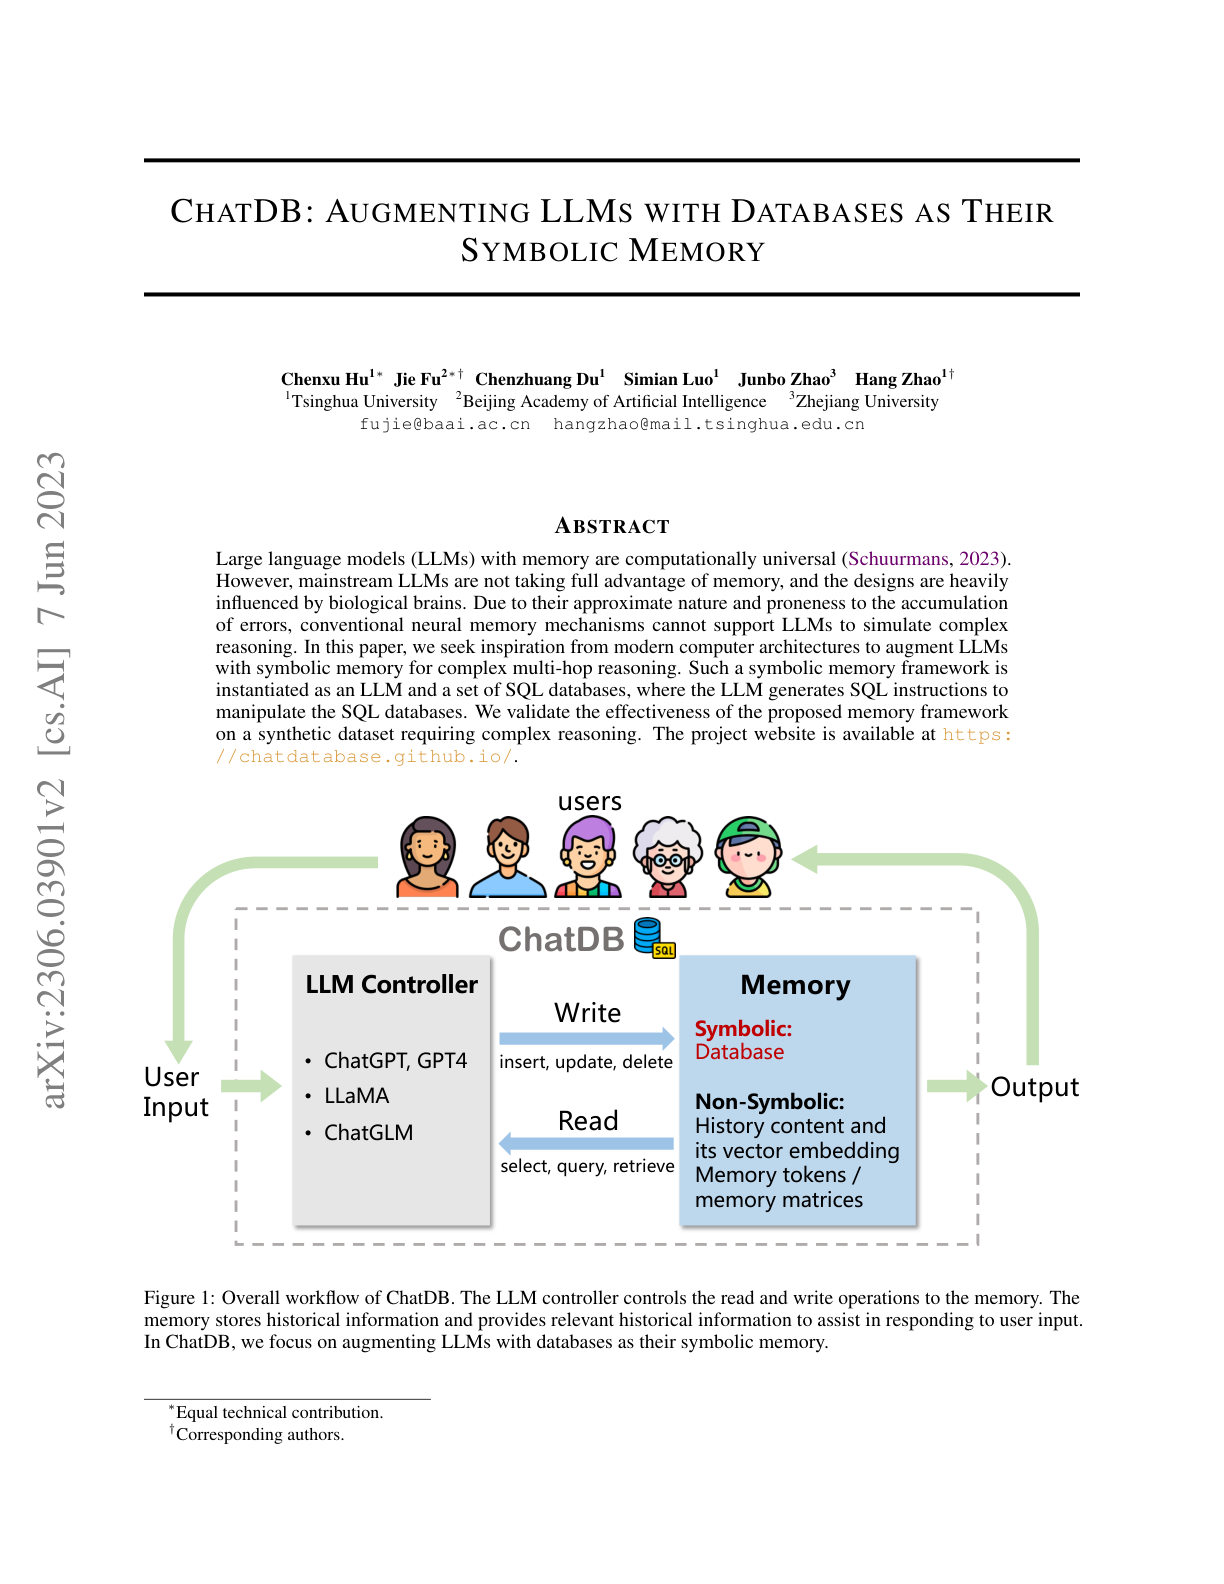
Augmenting LLMs with Databases (ChatDB)
Combines an LLM with SQL databases as a symbolic memory framework.
Concept Scrubbing in LLM (LEACE)
Least-squares Concept Erasure - erases a target concept from every layer of a neural network.
Fine-Grained RLHF
Trains LMs with segment-level human feedback rather than whole-response preferences.
Hierarchical Vision Transformer (Hiera)
Pretrains ViTs with MAE while removing unnecessary multi-stage complexity.
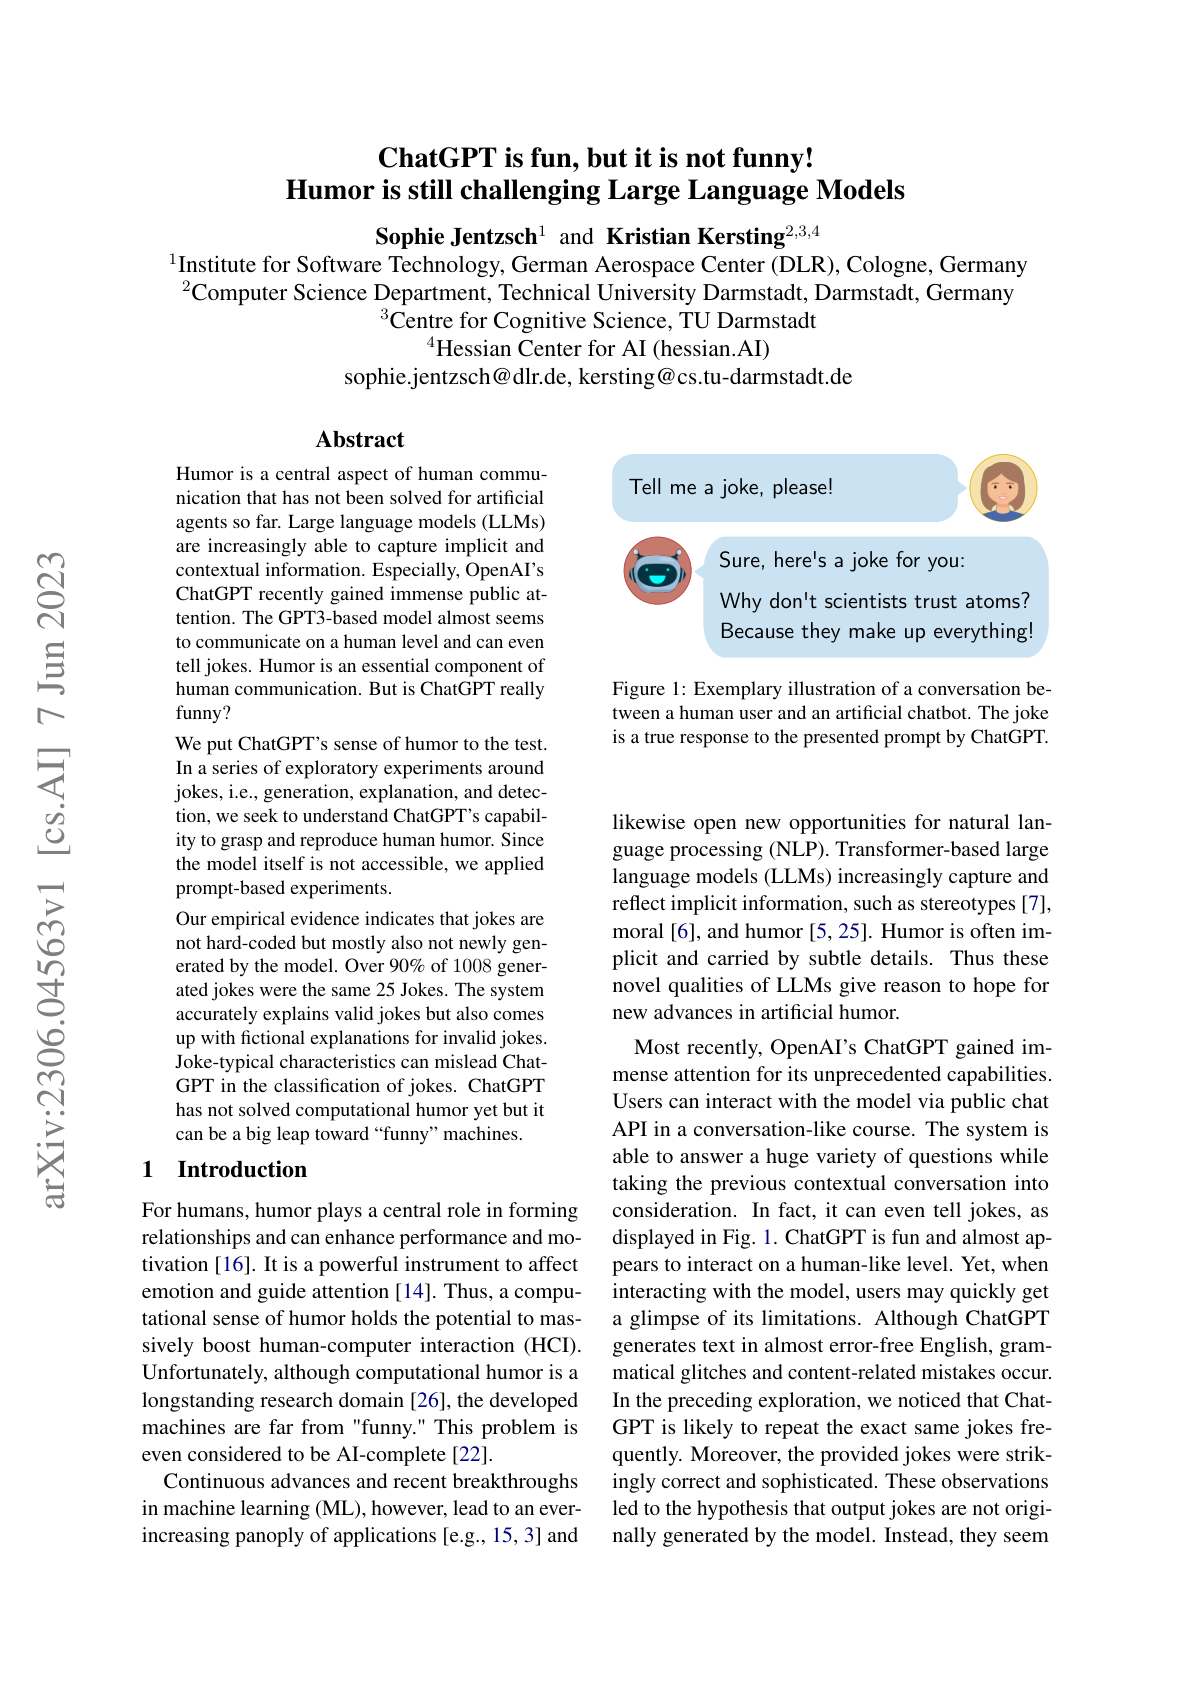
Humor in ChatGPT
Explores ChatGPT's capabilities to grasp and reproduce humor.
Imitating Reasoning Process of Larger LLMs (Orca)
Microsoft's 13B model that imitates GPT-4's reasoning traces.
Let's Verify Step by Step
OpenAI's landmark paper on process reward models for mathematical reasoning.
No Positional Encodings (NoPE)
Shows explicit position embeddings aren't essential for decoder-only Transformers.