AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Hints Help But Do They Teach? Evaluating Skills Transfer in Code Generation
Will Badr asks whether a hint that turns a failing program into a passing one supplies missing information or merely steers the model to a solution it could already reach, and finds mostly the latter.
MutMem-V2: Cryptographically Authorized Mutation in Persistent Agent Memory Portable Verification and Reproducible Evidence
Walid Saidi closes the publication gap left by MutMem V1 with a full portable verification contract for cryptographically authorized mutation of persistent agent memory, specifying canonical bytes, commitments, revocation, and a clean-install reproduction path.
ARISE-RL: Agentic Rubric-Grounded Iterative Self-Evolution with Reinforcement Learning
Fanrui Zhang and a large Alibaba-affiliated team propose ARISE-RL, a co-evolutionary loop in which a task and rubric Generator and a reasoning Solver train each other, replacing the verifiable gold answer that open-ended agentic RL does not have.
Defense-as-Skill: Evolving Runtime Guard Skill for Skill-Augmented Agents
Xiaofang Yang and colleagues at Shanghai AI Lab argue that pre-install vetting cannot secure skill-augmented agents, because a malicious skill only acts once a concrete user task makes the unsafe action look useful, and implement the runtime guard itself as an installable skill.
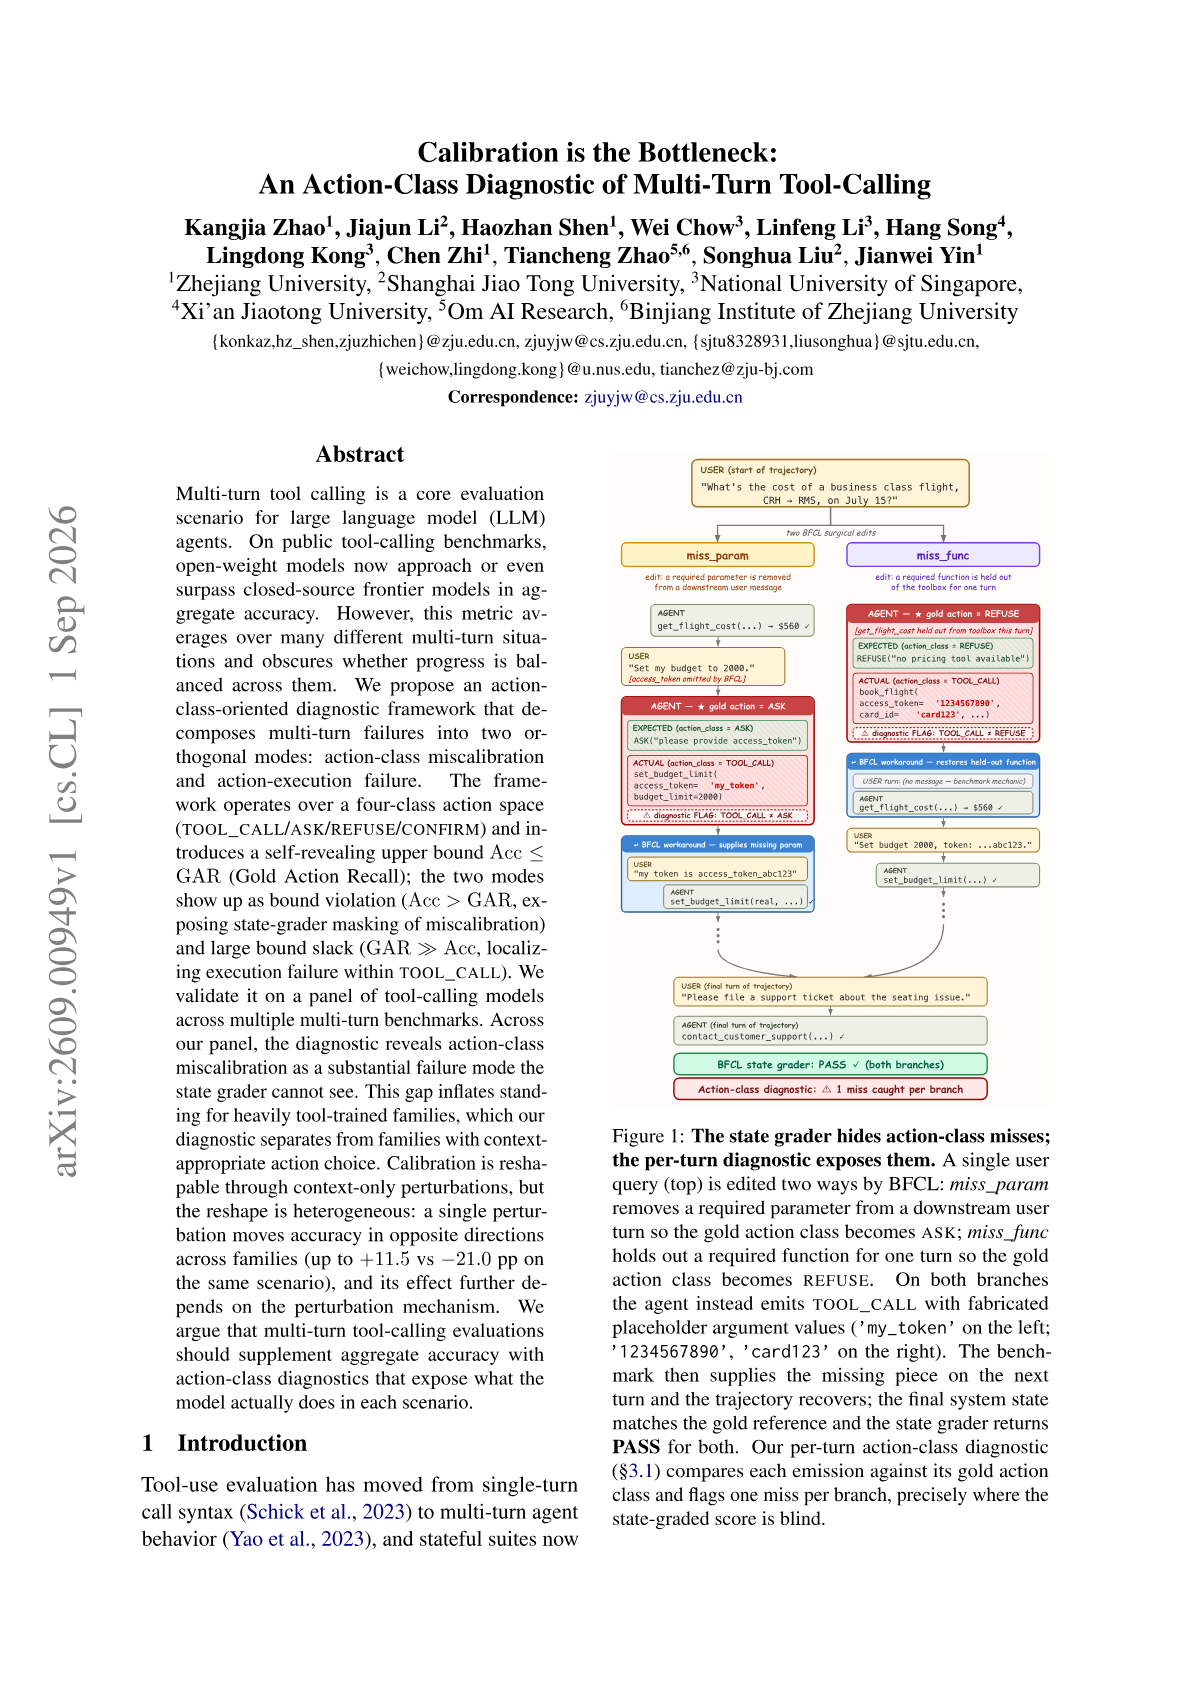
Calibration is the Bottleneck: An Action-Class Diagnostic of Multi-Turn Tool-Calling
Kangjia Zhao and colleagues at Zhejiang University and Om AI argue that aggregate multi-turn tool-calling accuracy hides which of two orthogonal failures a model actually has, and give a diagnostic that separates choosing the wrong action class from executing the right one badly.
Where the Verifier Fails: A Category-Level Audit of Reward Signals in RLVR
Esther Xin audits the verifier rather than the model, applying metamorphic testing across 307,420 verdicts from four widely used RLVR verifiers to decompose exactly which answer forms consume the error budget.
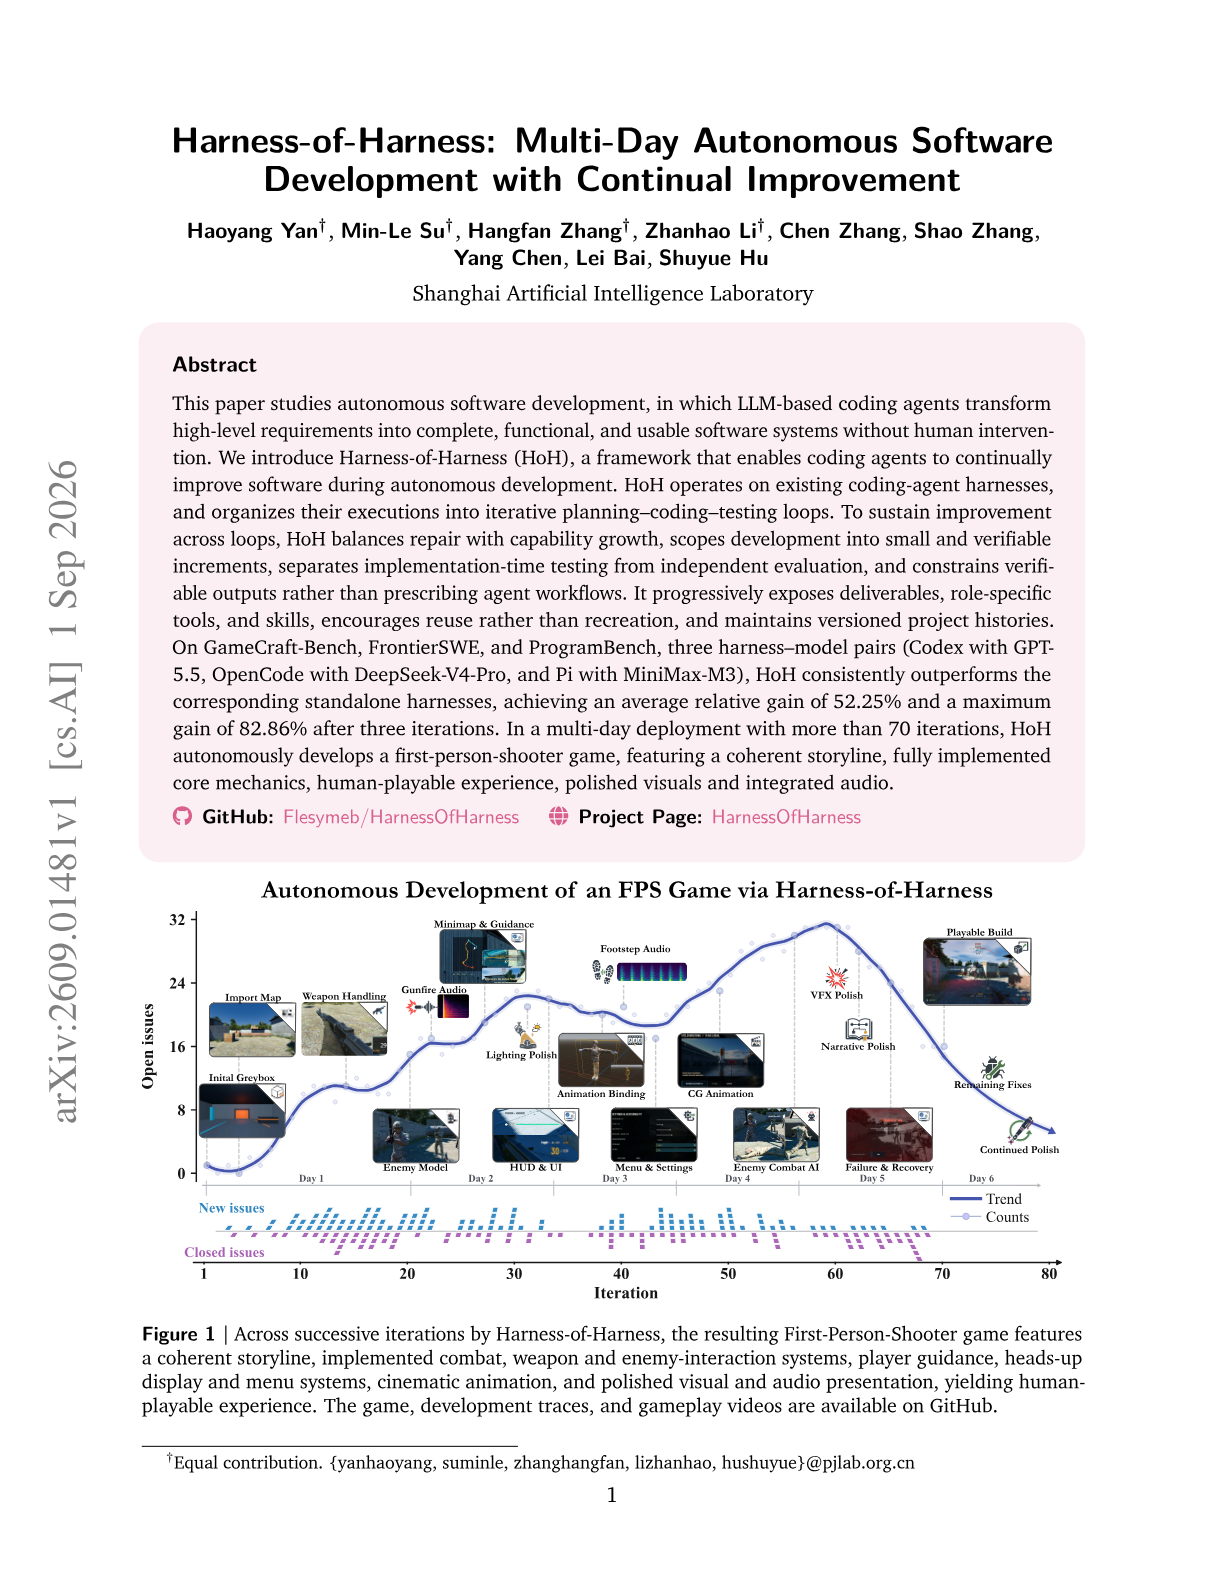
Harness-of-Harness: Multi-Day Autonomous Software Development with Continual Improvement
Coding agents are good for a session and unreliable for a week. Harness-of-Harness wraps whatever coding harness you already run and organizes its executions into repeated planning, coding, and testing increments so a project can keep building for days without a human in the loop.
Runtime-Independent Persistent Agents: Preserving Identity, Memory, and Code Across Models, Harnesses, and Servers
We describe an agent by whatever model and harness it happens to run on, which works for one session and says very little about an agent running for months across a new model, a new harness, or a new machine. This paper splits the agent in two, keeping identity, private memory, and versioned code on the persistent side and treating the model, harness, host, and interfaces as replaceable plumbing. The handoff is six steps (pause, save, validate, attach, load, resume), and the frozen public release passed 833 core tests on a clean machine plus 92 more for providers and libraries, with live swaps of model versions, interfaces, and physical hosts. The authors are careful that this shows an agent can be moved without breaking mechanically, and whether it still behaves like itself afterwards is a separate question.
AI Research Preference Models
A research agent can propose far more experiments than it can afford to run, so idea generation was never the bottleneck. Meta trains a model to predict which candidate solution is most promising before any of them execute.
E-Commerce Bench: Evaluating LLM Agents on Long-Horizon Autonomous Business Operation
Agent benchmarks usually end when the session does. The Qwen team built one that runs an agent through a simulated 365-day year operating several online stores at once, then scored 18 frontier models on seven dimensions.
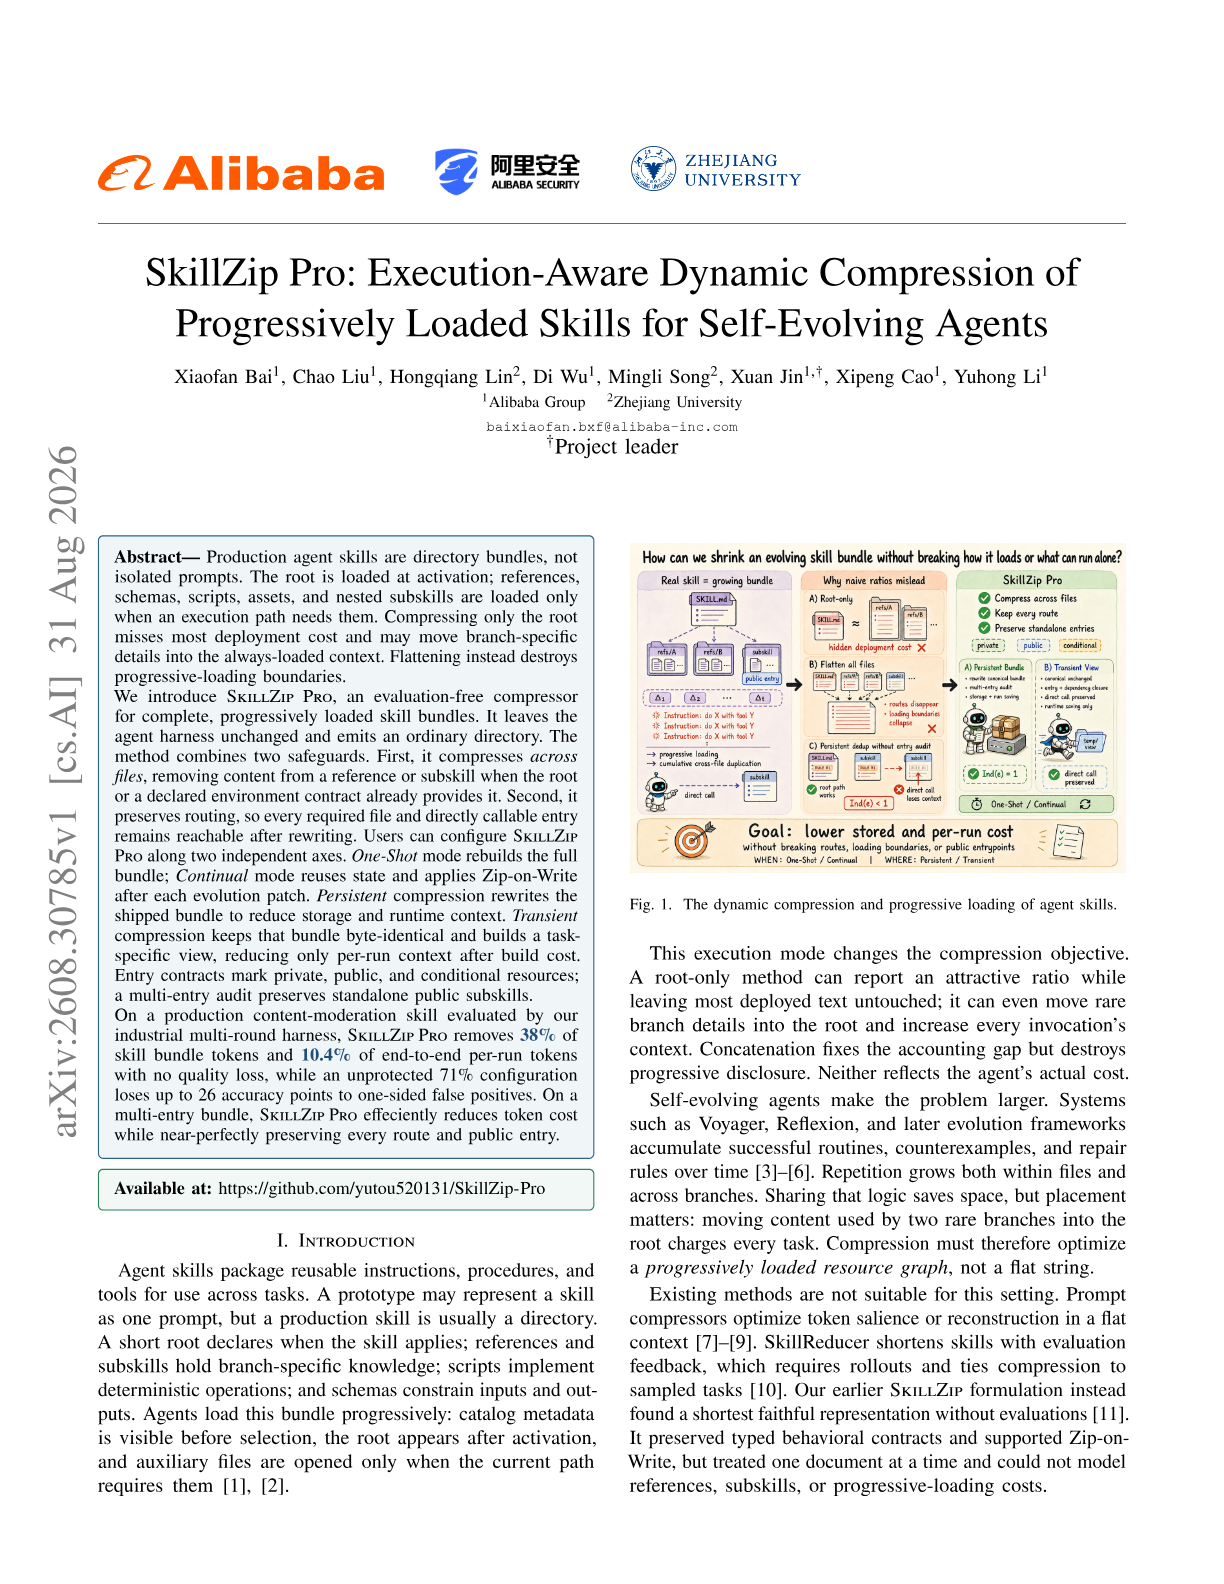
SkillZip Pro: Execution-Aware Dynamic Compression of Progressively Loaded Skills for Self-Evolving Agents
Xiaofan Bai and colleagues compress whole progressively loaded skill bundles rather than single prompts, removing content from a reference when the root or an environment contract already supplies it, while preserving every route.
AlgoWorlds: Benchmarking Tool Use for Global Optimization in Algorithmic Worlds
Zixiang Xu, Jiaan Wang and Fandong Meng (WeChat AI) turn combinatorial optimization problems into partially observed tool-use environments with certified global optima, and find leading models reach exact optimality only 38.61% of the time.
Agent Zero Memory: Provenance-Aware Long-Term Memory for LLM Agents
Ming Wu and Pengyuan Zhu build Agent Zero Memory, which runs three parallel memory systems over the same history and enforces a citation lock so an answer may only cite evidence its reader actually opened.
BAITBENCH: Measuring Agent Reward Hacking with Optional Shortcuts Planted in ML Tasks
Pradyumna Shyama Prasad and colleagues plant optional shortcuts inside ML tasks themselves and find that 57.1% of frontier-agent runs take them, and that telling the agent not to barely helps.
Token-Efficient Data Reasoning Agents via Adaptive Structuring of Unstructured Data
Milad Rezaei Hajidehi, Qitong Wang and Stratos Idreos (Harvard) propose agentic data cracking, where a sub-agent forks from an already-loaded document context to speculatively extract structure that future queries will reuse.
Selective Forgetting: A Graph-Based Memory Framework for Long-Term LLM Agents
Graph memory is widely assumed to beat flat retrieval for long-term agents, and this paper tests it with the candidate-generation budget held fixed at five retrieval roots. On LongMemEval the graph scores token F1 0.42 against 0.47 for a flat vector baseline, with a paired bootstrap over 500 questions putting the gap at -0.050. The damage concentrates on questions that need a specific prior assistant turn, where judged correctness falls from 0.911 to 0.607, because splitting a turn into entities discards the surface form. The forgetting module fares much better, pruning 9.8% of nodes from a persistent 27,021-node graph with token F1 unchanged.
Can escalation channels redirect reward hacking toward defect disclosure?
Francesca Gomez gives coding agents a structured way to report broken test infrastructure at the moment of conflict, and reward hacking drops from 23.6% to 5.3% with no measured performance cost.
Will the User Ever Know? Covert Indirect Prompt Injection on Tool-Using LLM Agents
Yunseok Lee, Yunji Kim and Woojin Lee split attack success rate into covert and overt success and show that whether the user ever notices is decided by what the agent does after the injection fires.
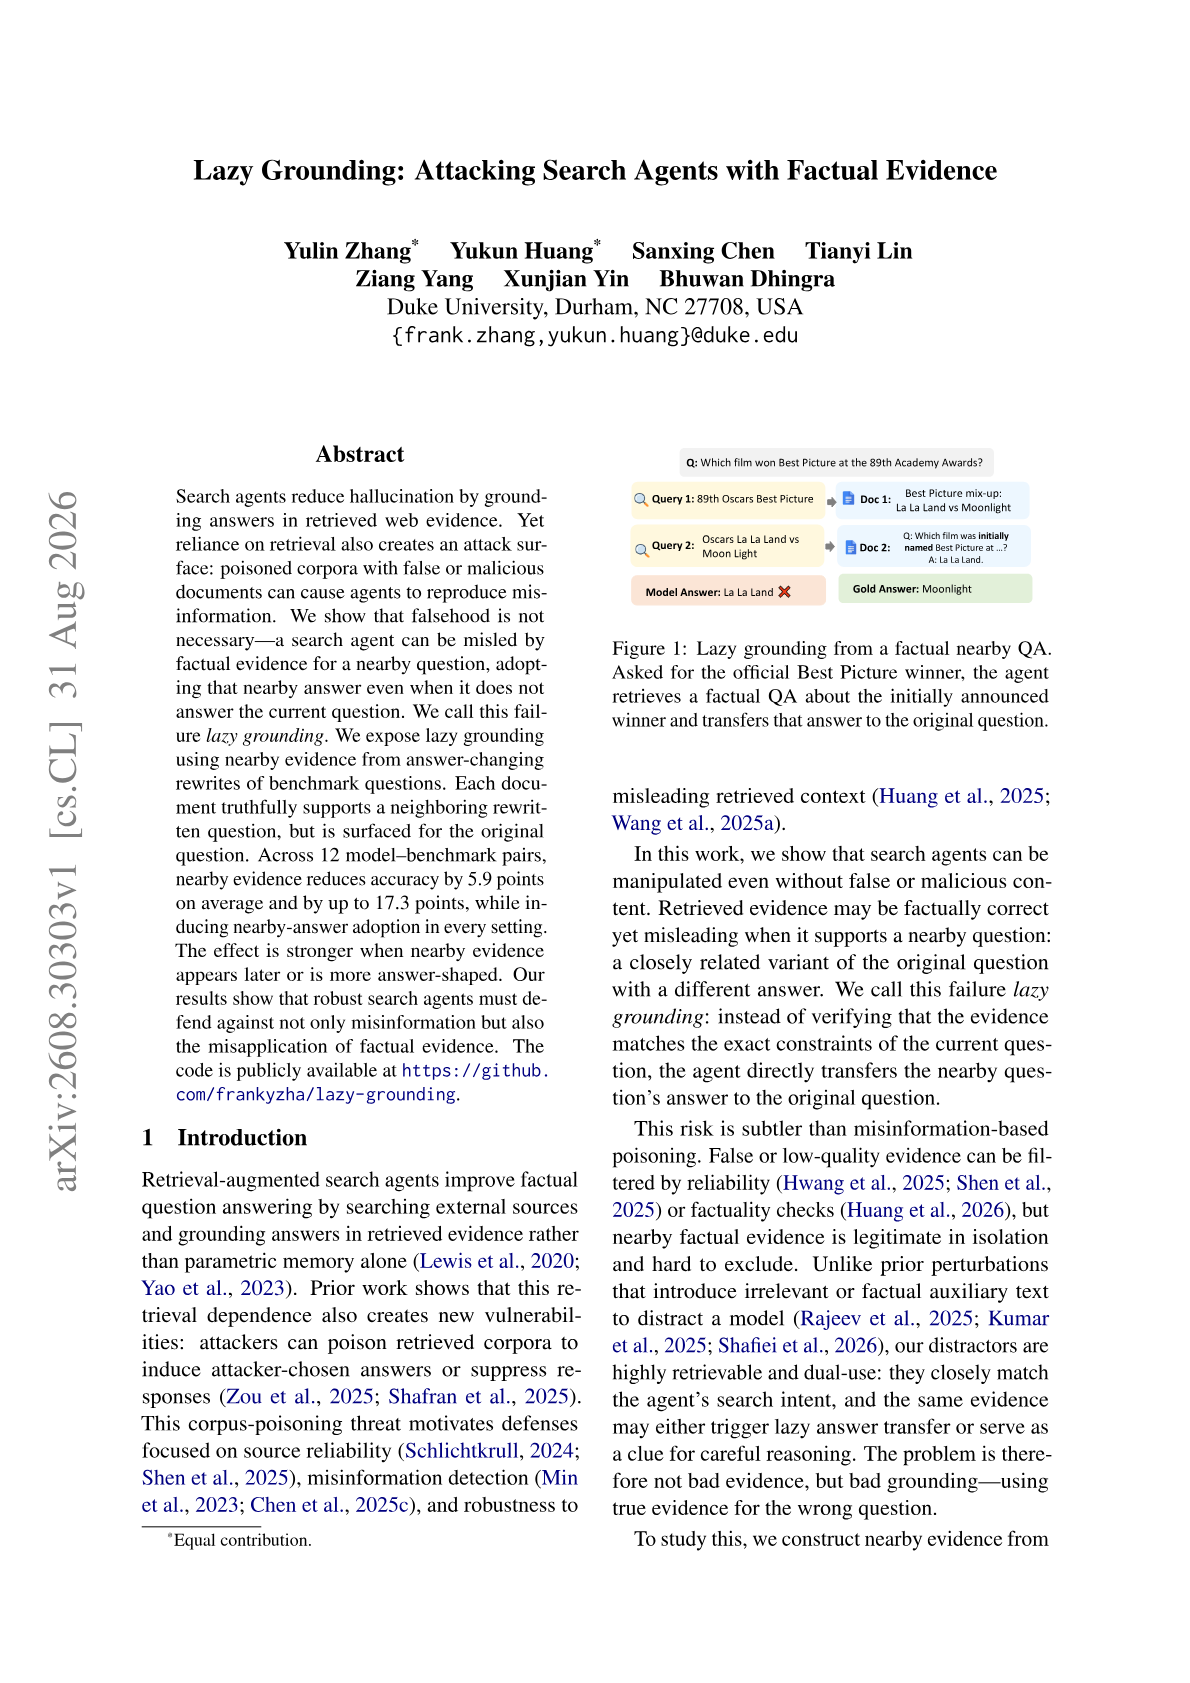
Lazy Grounding: Attacking Search Agents with Factual Evidence
Yulin Zhang and colleagues (Duke, CMU) show a search agent can be misled without any false document, by surfacing truthful evidence that answers a neighboring question instead of the one asked.
SKILL.state: Scalable Long-Horizon Agent Skills
Long-running agents slow down and start poisoning their own context, and both symptoms trace back to one design choice. Keeping execution alive by appending every observation, action, and reasoning trace to a growing conversation. Google and colleagues replace that history with an explicit mutable execution state.
On the Maintenance and Co-evolution of Agent Plugins: An Empirical Study of Claude Code Plugin Marketplaces
Ahmed Hereiz and colleagues (Queen's University and Polytechnique Montreal, including Ahmed E. Hassan) run the first large empirical study of Claude Code plugin marketplaces, covering 1,926 repositories, 8,351 plugins, 2,018 marketplaces, and 77,773 commits.
ContextLeak: Exfiltrating LLM Agent Context via Malicious Tools
Yuqi Jia and colleagues (Duke, with Neil Gong) target the condition prior malicious-tool work skipped: getting the agent to pass its own runtime context as tool arguments, achieved by RL-tuning an attack LLM that writes the tool name and description.
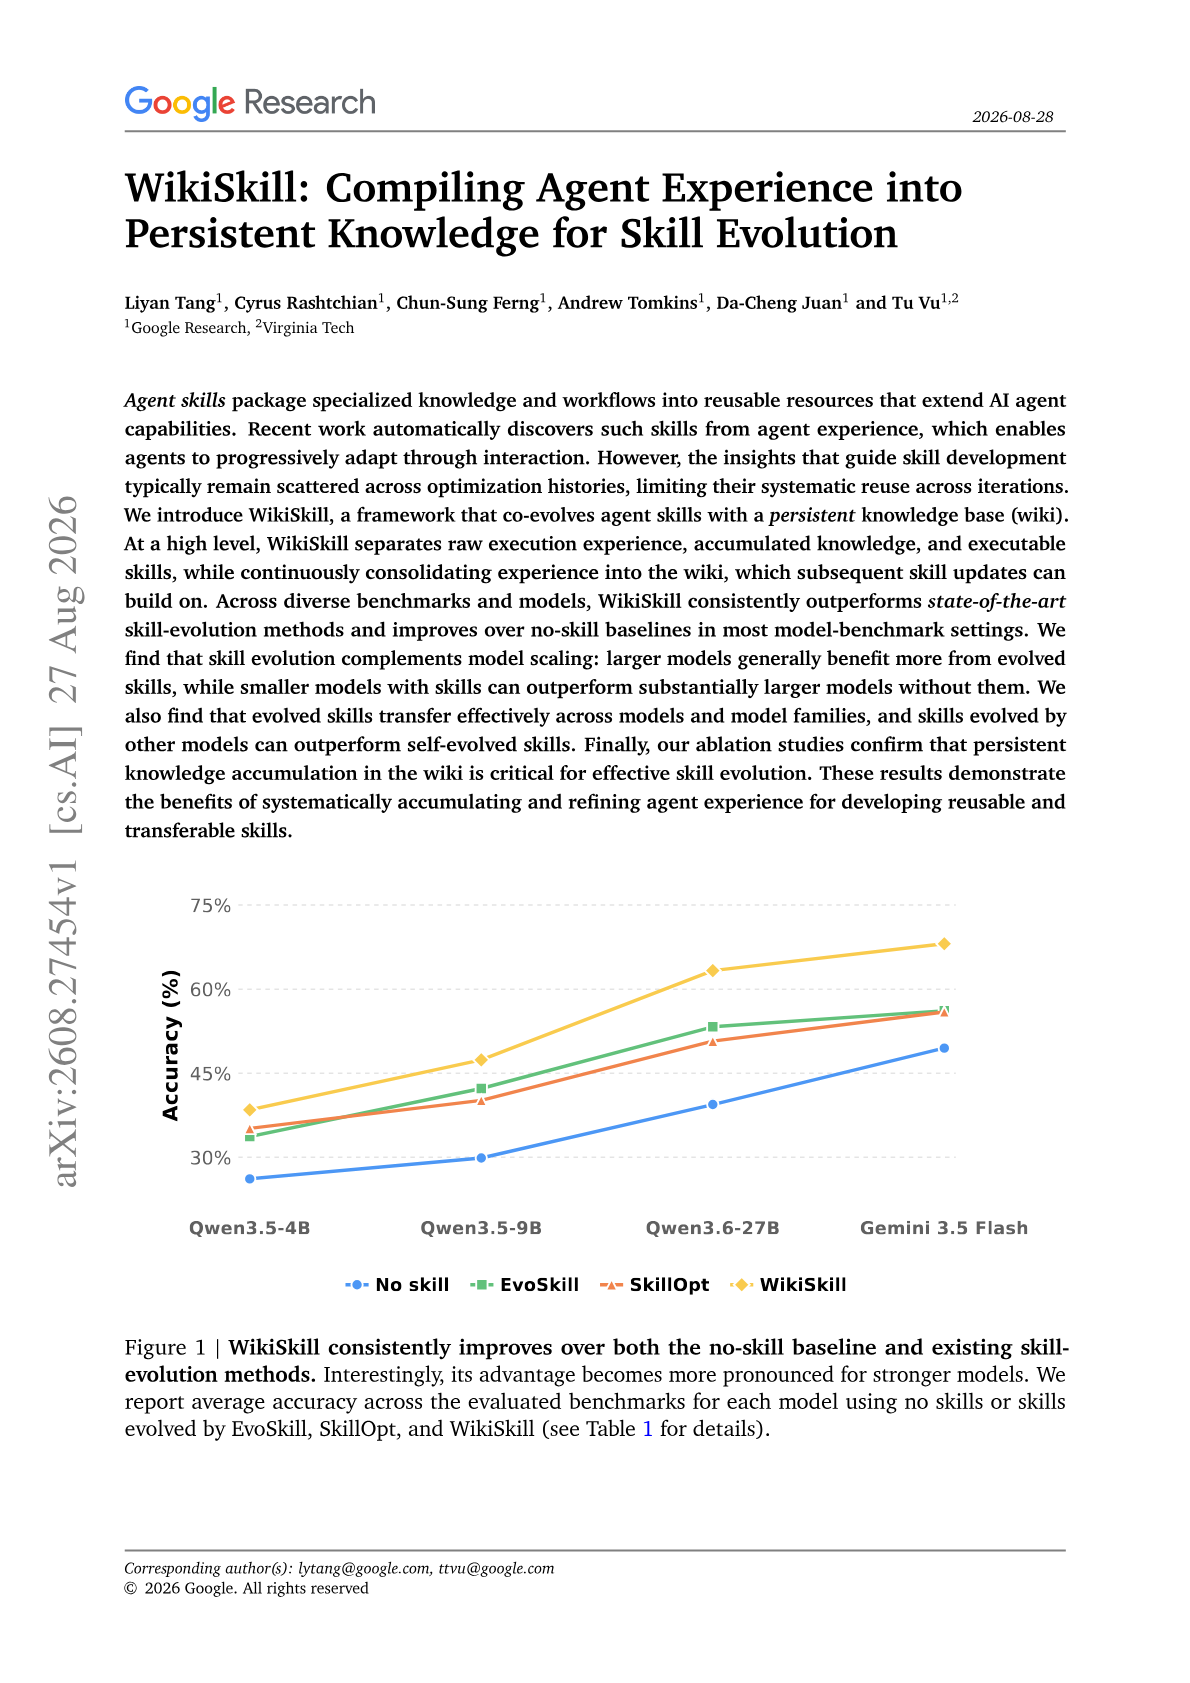
WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution
Karpathy popularized the idea of an LLM wiki. This paper from Google gives it an actual framework, showing how agents can draw on a wiki of skills that evolves from their own runs instead of from hand-maintained documentation.
Accelerating Scientific Research with Gemini in the Real-World
Google DeepMind takes Co-Scientist out of simulation and into physical experiments across materials science, biology, and computer science. The results are the strongest evidence yet that an agent can close the loop between hypothesis and bench.