AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
UniSim (Universal Simulator)
Google's UniSim learns a universal generative simulator of real-world interactions from diverse video + action data.
The Dawn of LMMs (GPT-4V Deep Dive)
Microsoft's exhaustive 166-page analysis of GPT-4V's capabilities and limitations.
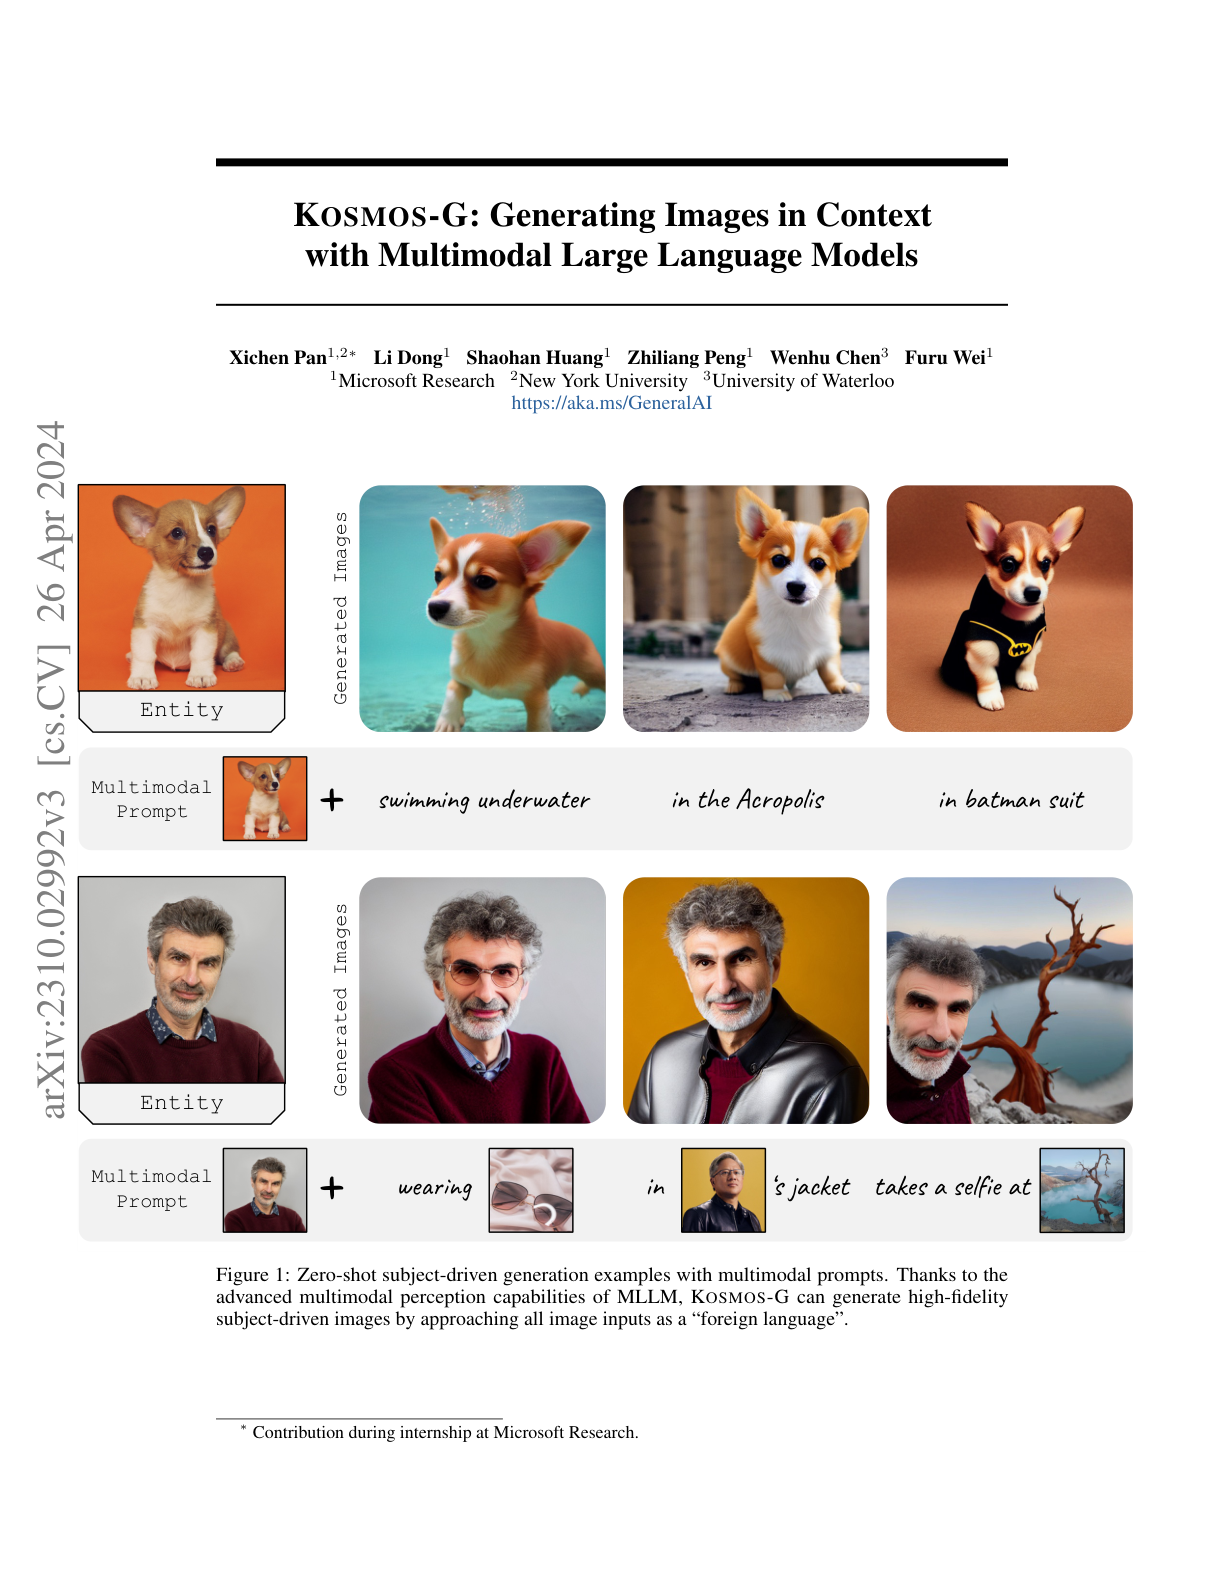
KOSMOS-G
Microsoft's KOSMOS-G extends zero-shot image generation to multi-image vision-language input.
LLaVA-RLHF
Adapts factually augmented RLHF to aligning large multimodal models, reducing hallucination without falling into reward-hacking pitfalls.
KOSMOS-2.5
Microsoft's KOSMOS-2.5 is a multimodal model purpose-built for "machine reading" of text-intensive images.
ImageBind-LLM
Shanghai AI Lab's ImageBind-LLM brings six-modality understanding to LLMs via the ImageBind joint embedding space.
LLaSM (Large Language and Speech Model)
A combined language-and-speech model trained with cross-modal conversational abilities.
MVDream
ByteDance's MVDream is a multi-view diffusion model that generates geometrically consistent images from multiple viewpoints given a text prompt.
Nougat
Meta's Nougat is a visual transformer for "Neural Optical Understanding for Academic documents" that converts PDFs to LaTeX/Markdown.
AnomalyGPT
Applies large vision-language models to industrial anomaly detection with synthetic data augmentation.
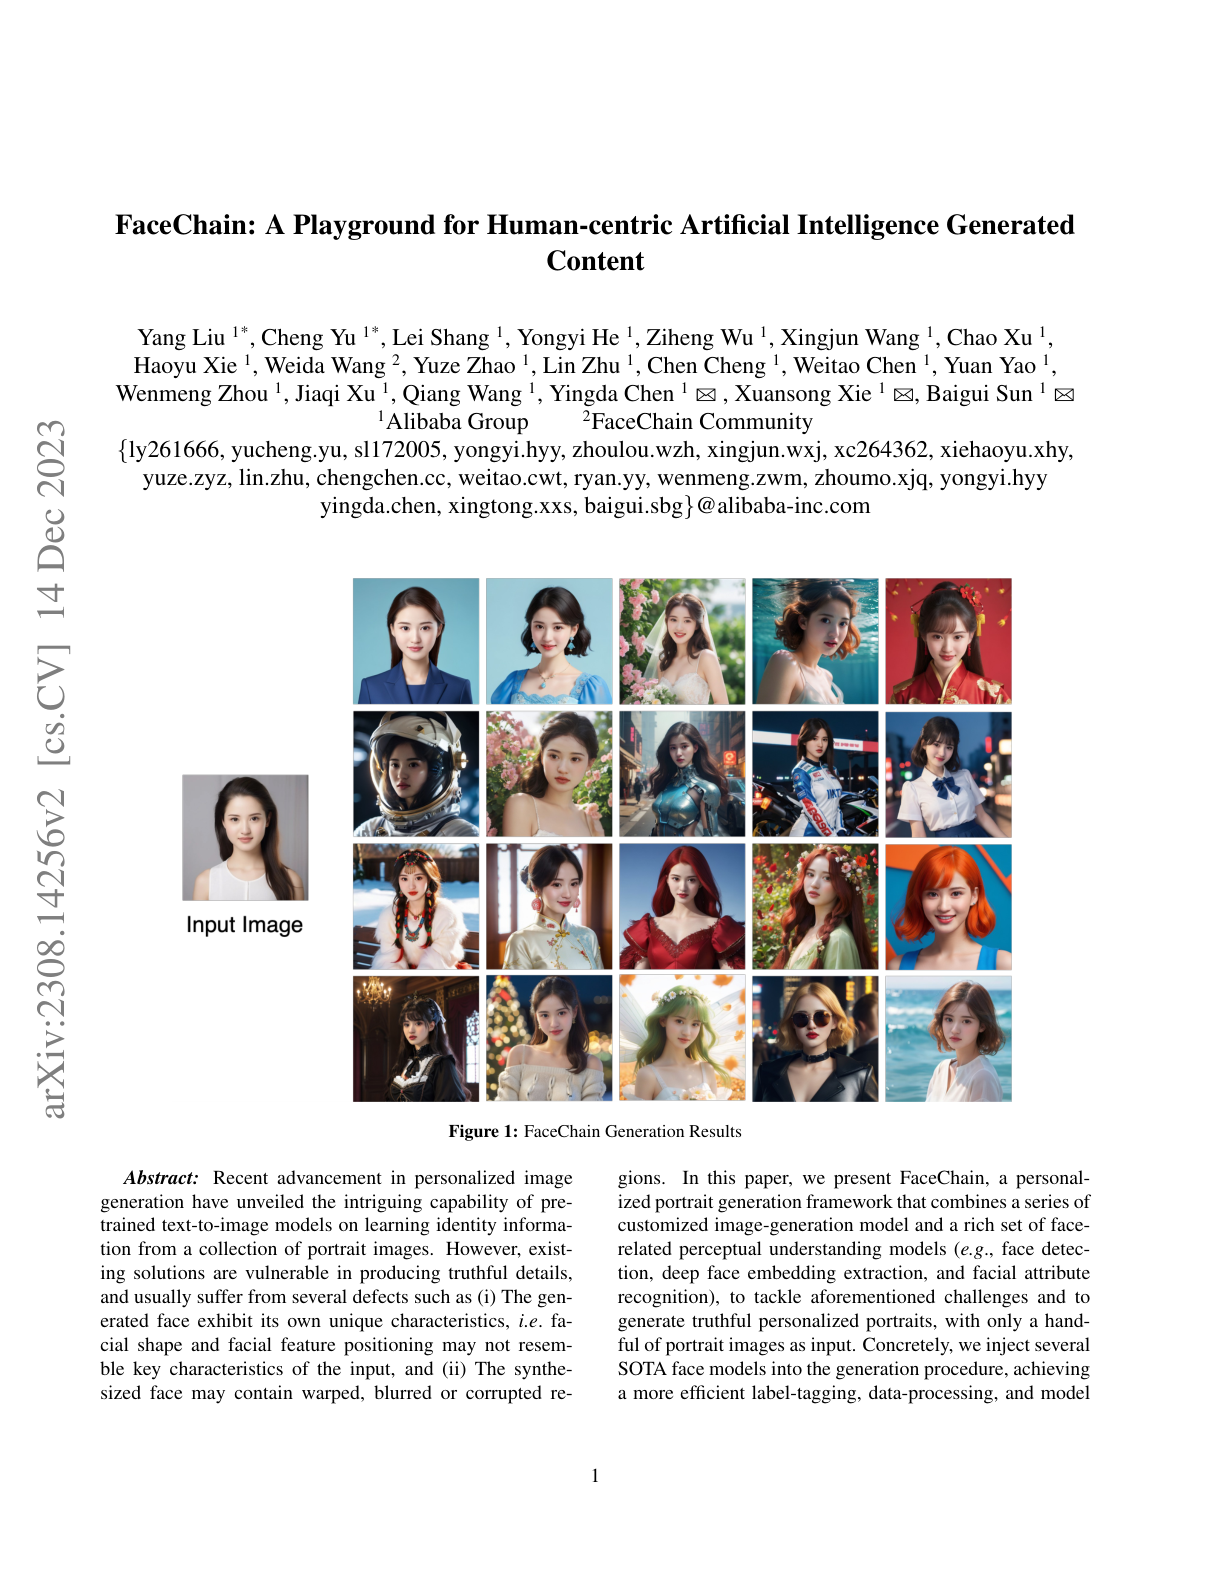
FaceChain
Alibaba's FaceChain is a personalized portrait generation framework that produces identity-preserving portraits from just a handful of input photos.
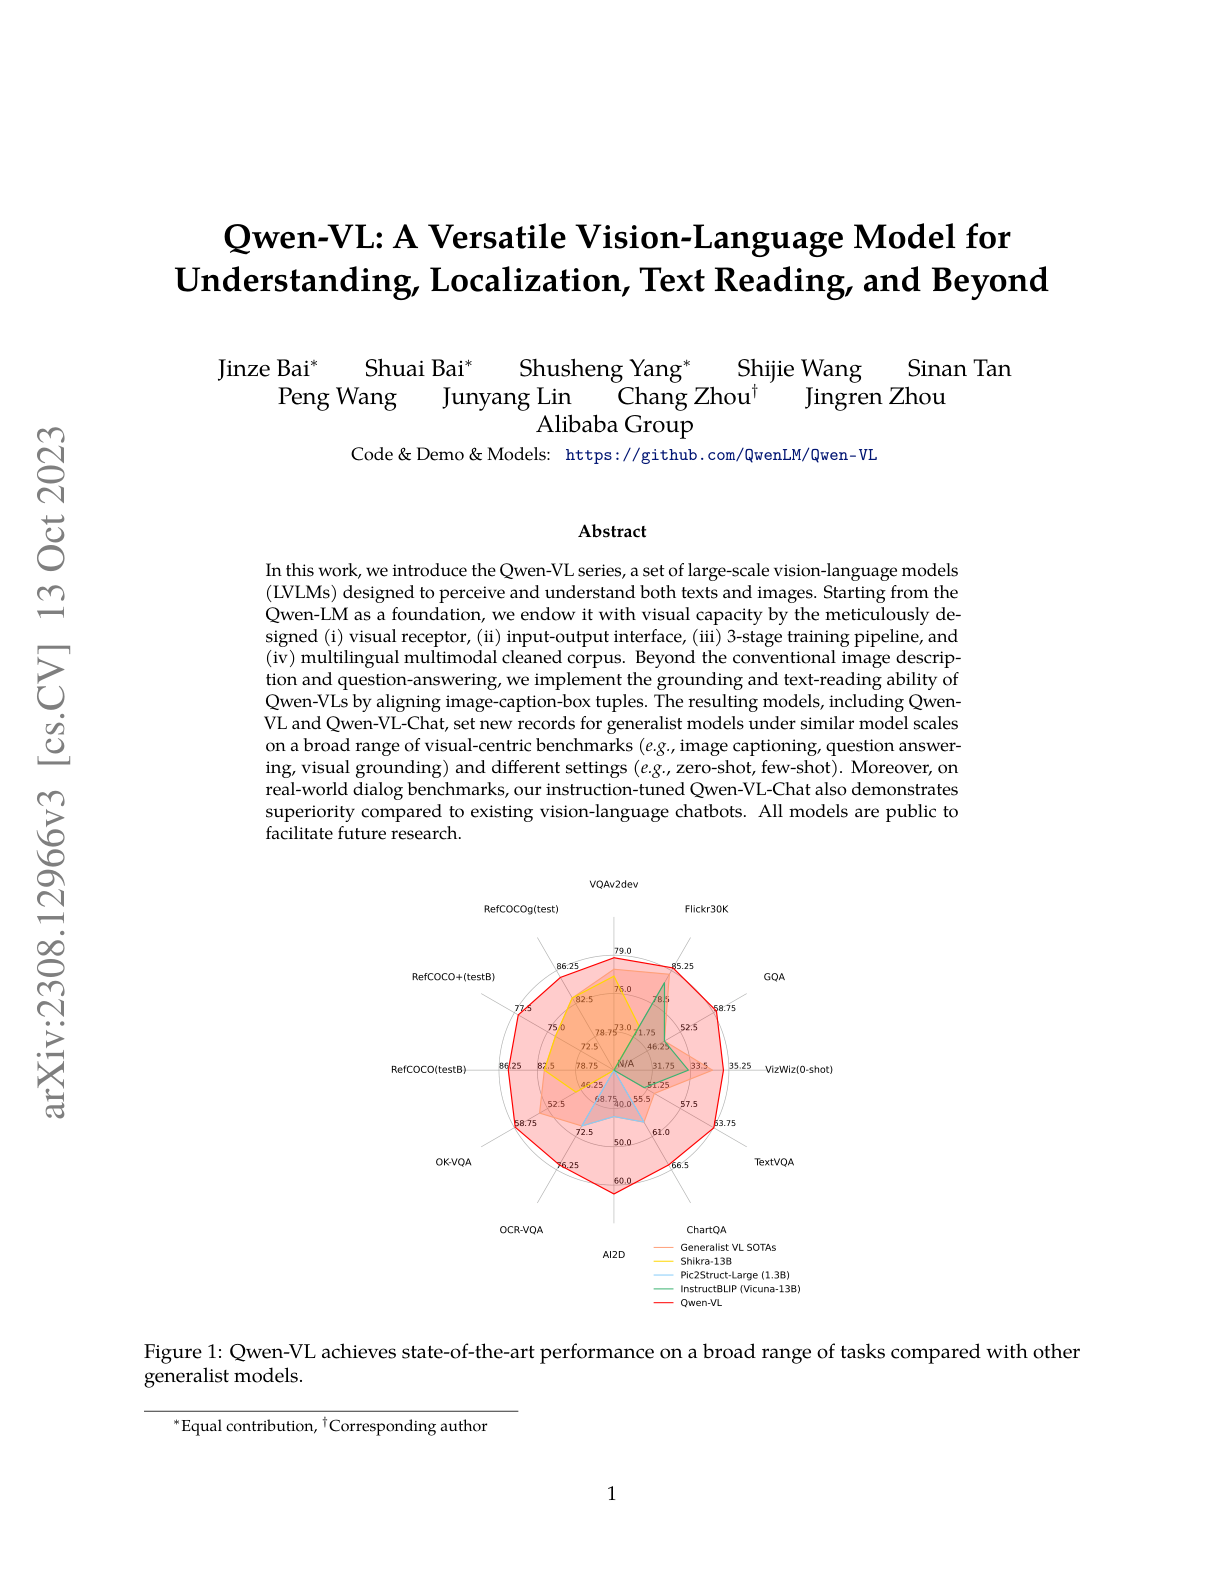
Qwen-VL
Alibaba's Qwen-VL is a large-scale vision-language model family with strong performance across captioning, VQA, and visual localization.
SeamlessM4T
Meta's SeamlessM4T is a unified multilingual and multimodal machine-translation system that handles five translation tasks in one model.
IT3D
Improves Text-to-3D generation by leveraging explicitly synthesized multi-view images in the training loop.
NeuroImagen
Reconstructs visual stimuli images from EEG signals using latent diffusion, opening new windows into visually-evoked brain activity.
Med-Flamingo
Stanford's Med-Flamingo is a multimodal medical model supporting in-context learning for few-shot medical visual QA.
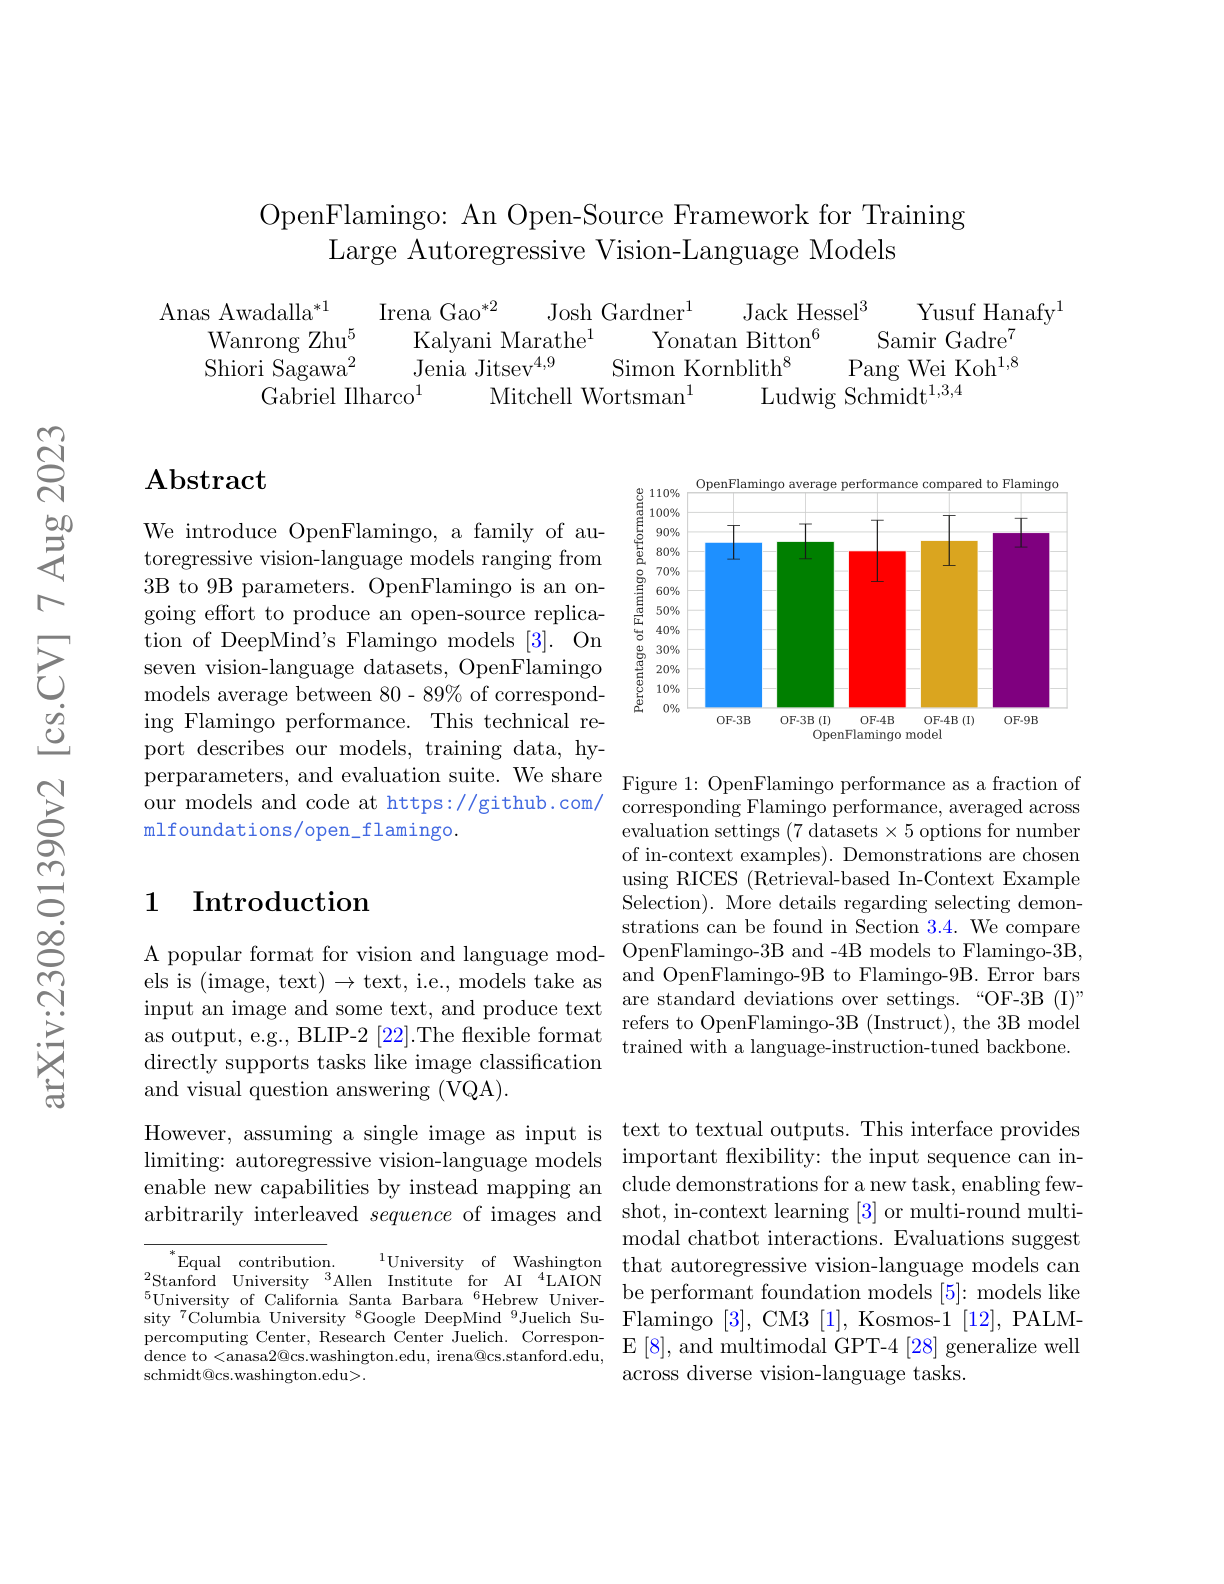
OpenFlamingo
An open-source family of autoregressive vision-language models spanning 3B to 9B parameters.
Dynalang (Agents Model the World with Language)
UC Berkeley's Dynalang agent learns a multimodal world model predicting future text, video, and rewards.
Med-PaLM Multimodal
Introduces a generalist biomedical AI system and a new multimodal biomedical benchmark with 14 tasks.
Tracking Anything in High Quality
A framework for high-quality tracking-anything in videos combining segmentation and refinement.
Foundation Models in Vision
A comprehensive survey on foundational models for computer vision and their open research directions.
WavJourney
Leverages LLMs to orchestrate audio generation models for compositional storytelling.
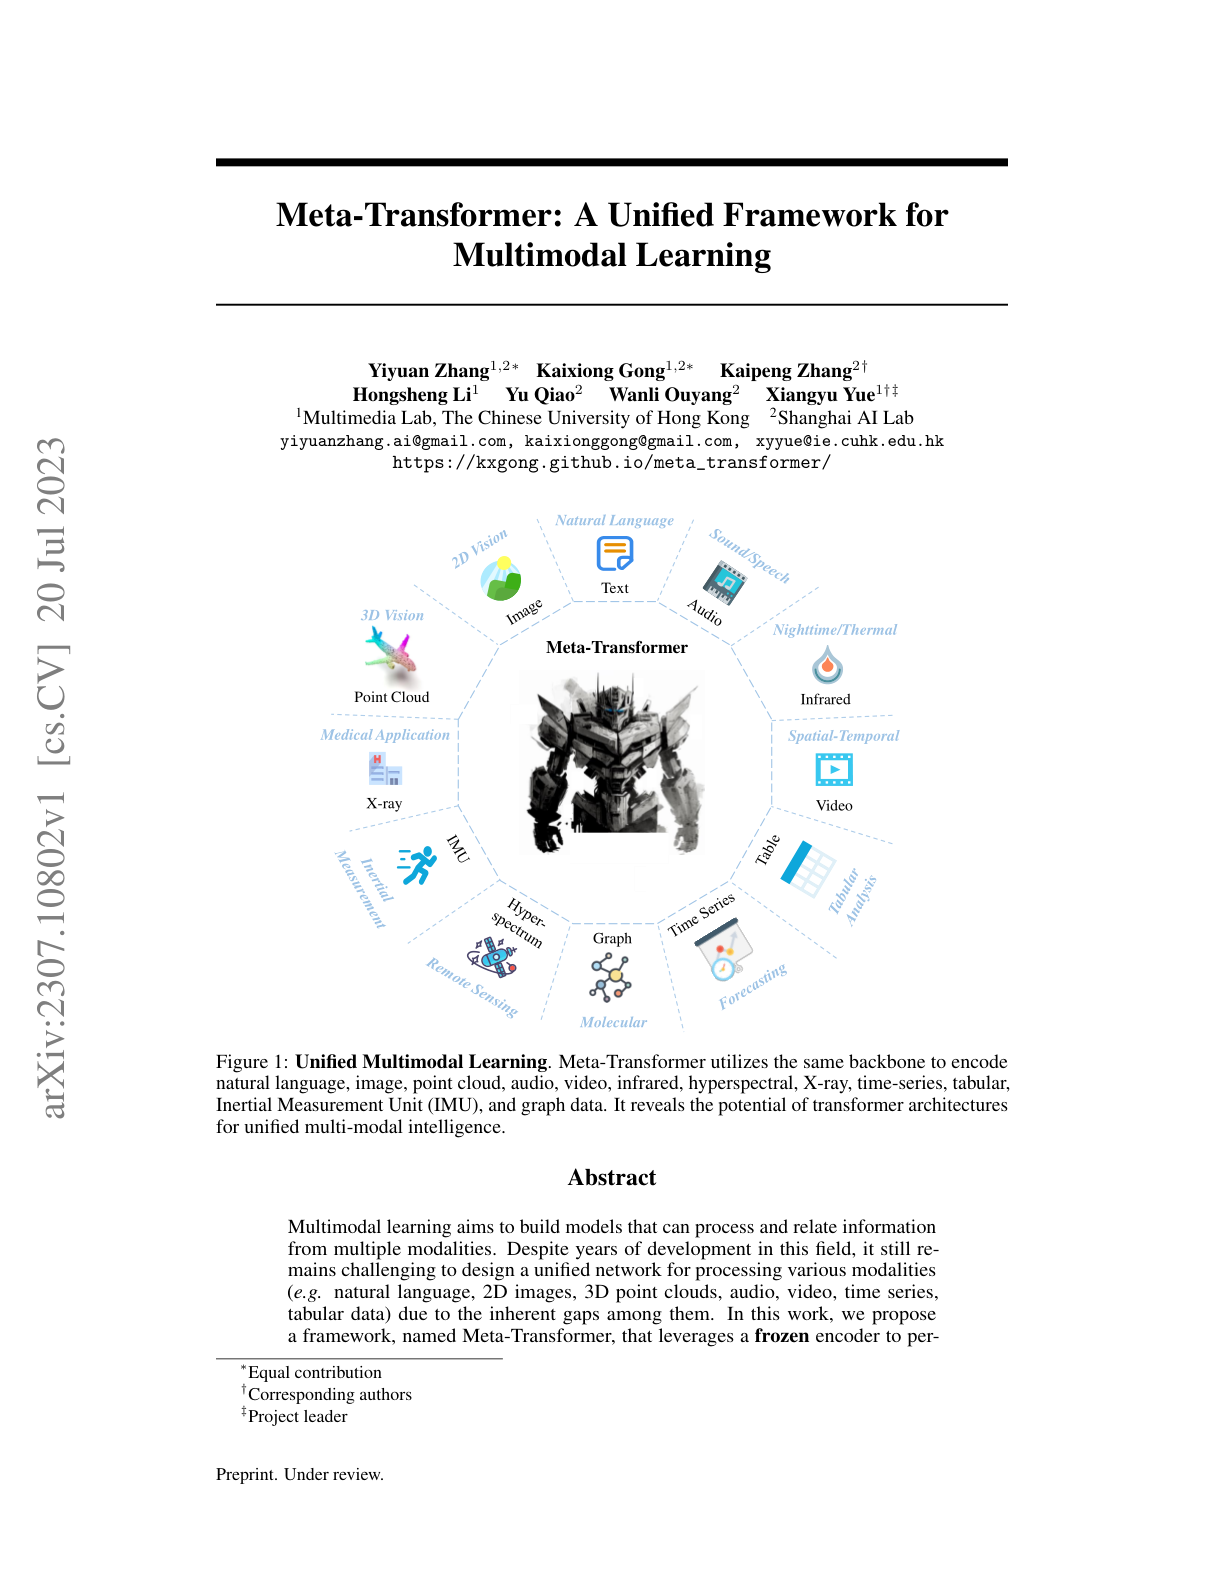
Meta-Transformer
A unified framework performing learning across 12 different modalities with a shared backbone.
CM3Leon
Meta's retrieval-augmented multi-modal language model that generates both text and images.