AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
Patch n' Pack: NaViT
A vision transformer handling any aspect ratio and resolution through sequence packing.
HyperDreamBooth
A smaller, faster, and more efficient version of DreamBooth for personalizing text-to-image models.

AnimateDiff
Animates frozen text-to-image diffusion models via a plug-in motion modeling module.
Generative Pretraining in Multimodality (Emu)
A transformer-based multimodal foundation model for generating images and text.
Multimodal Generation with Frozen LLMs
Maps images to LLM token space enabling models like PaLM and GPT-4 to handle visual tasks without parameter updates.
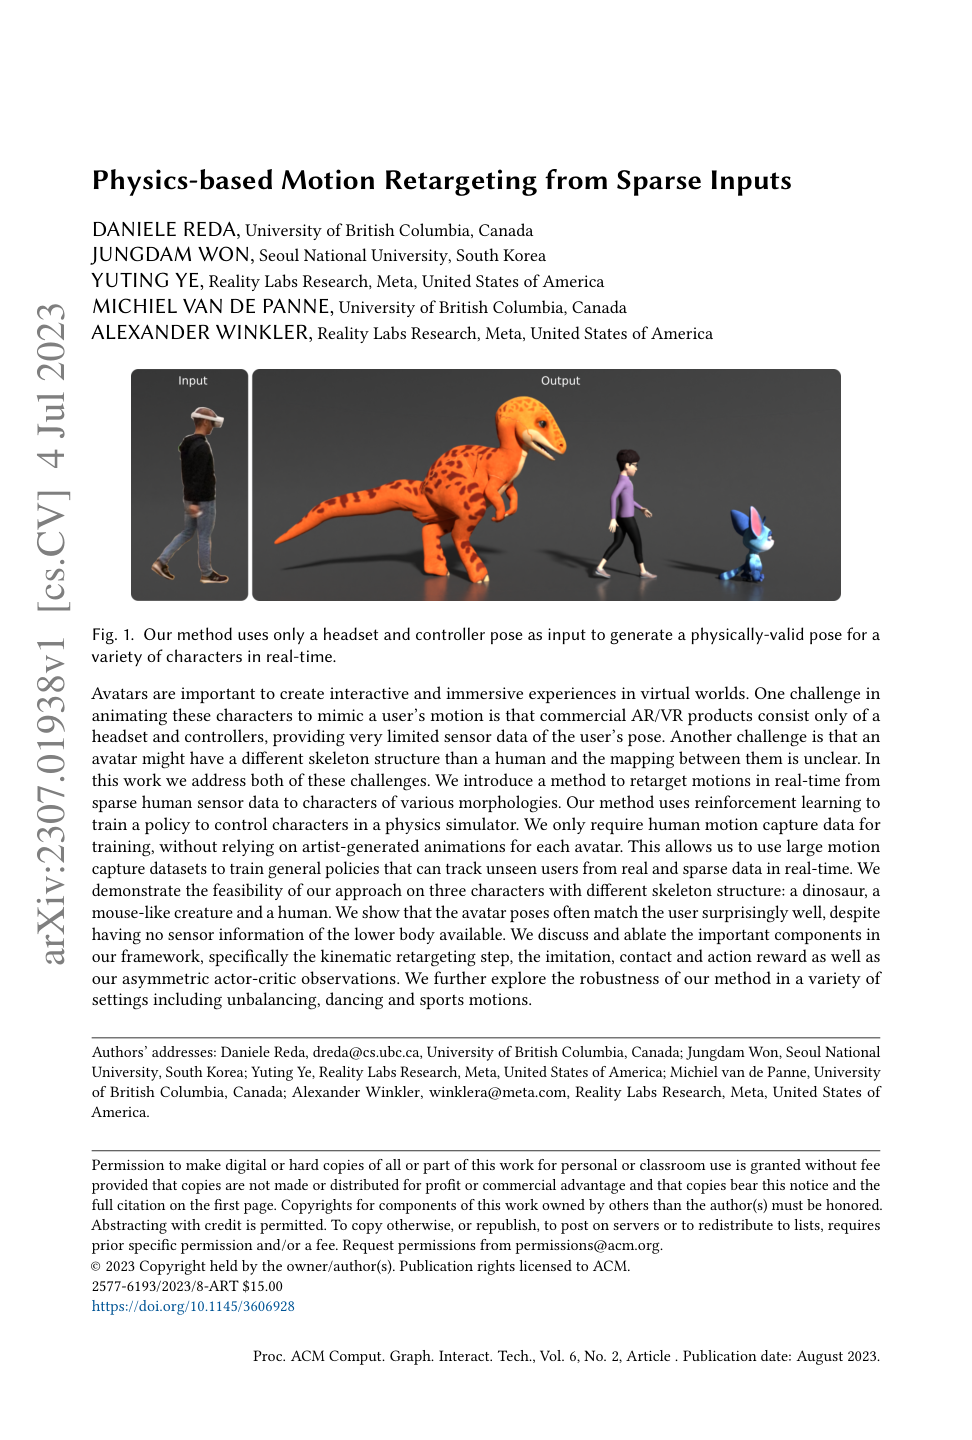
Physics-based Motion Retargeting in Real-Time
Uses RL to retarget motions from sparse human sensor data to characters of various morphologies.
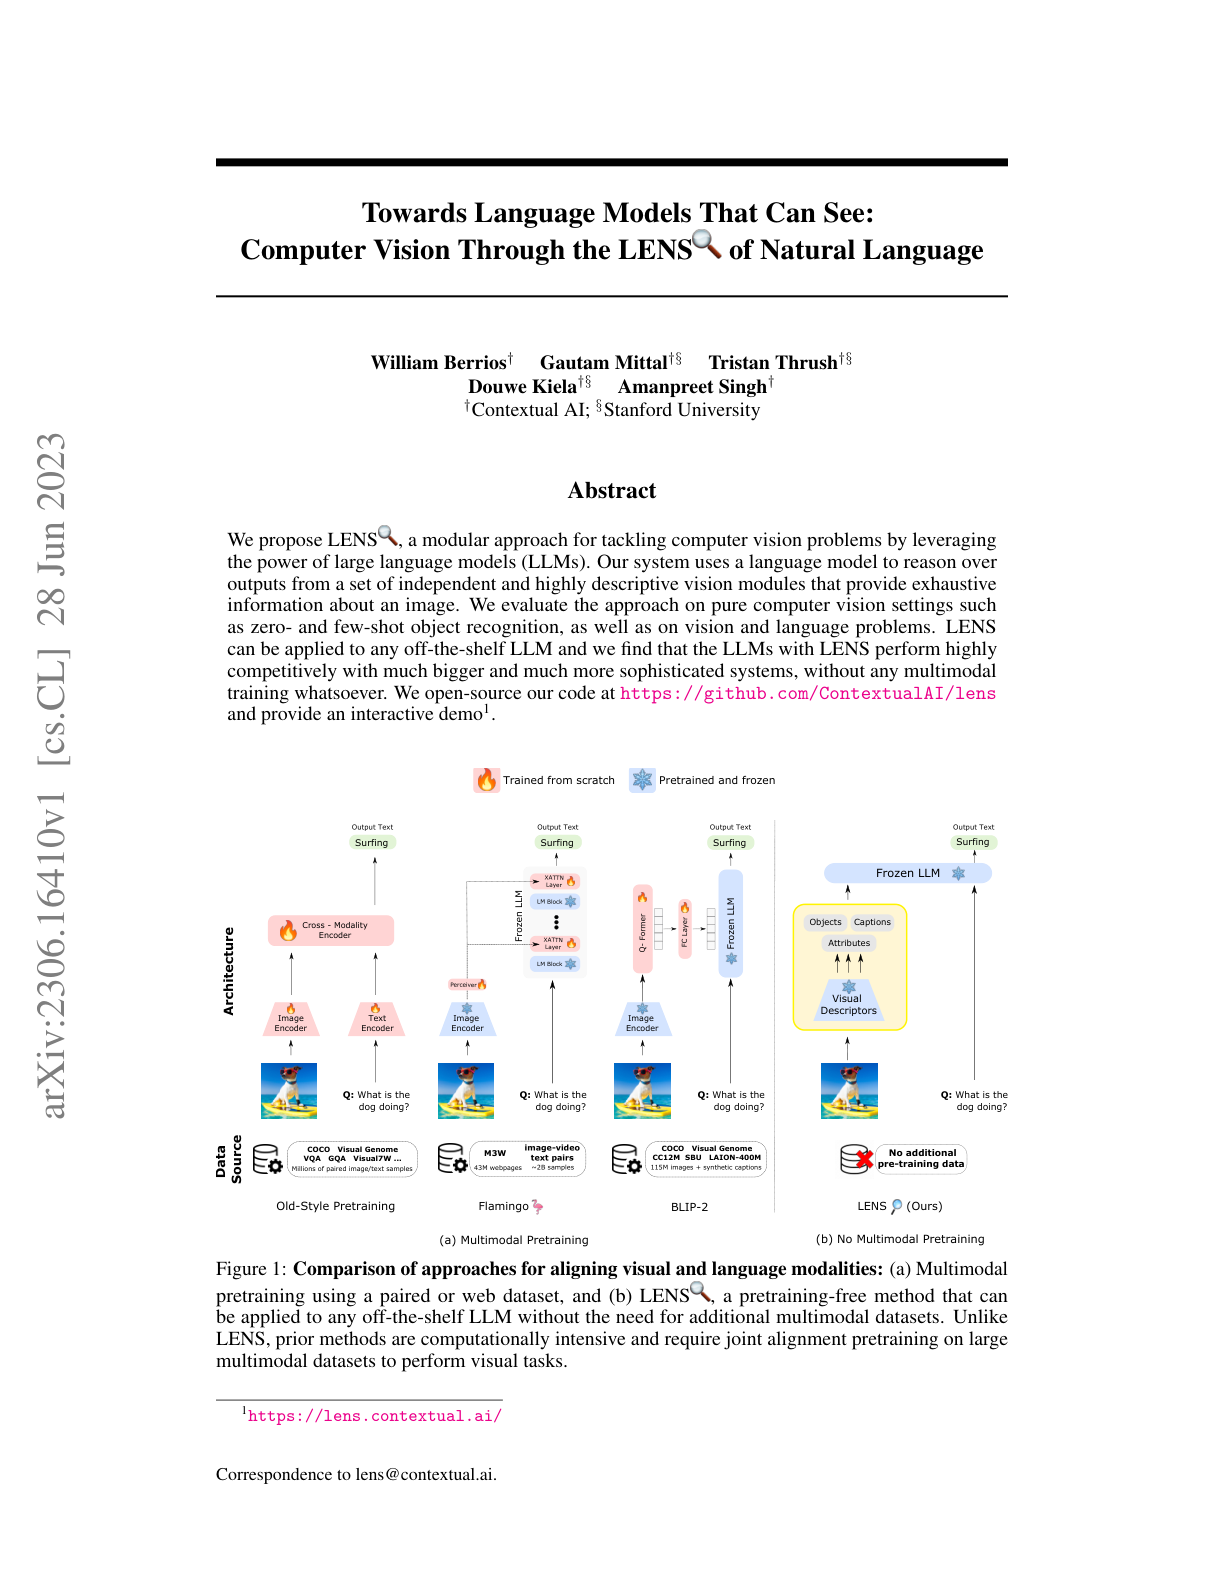
Computer Vision Through the Lens of Natural Language
A modular approach solving CV problems by routing through LLM reasoning.
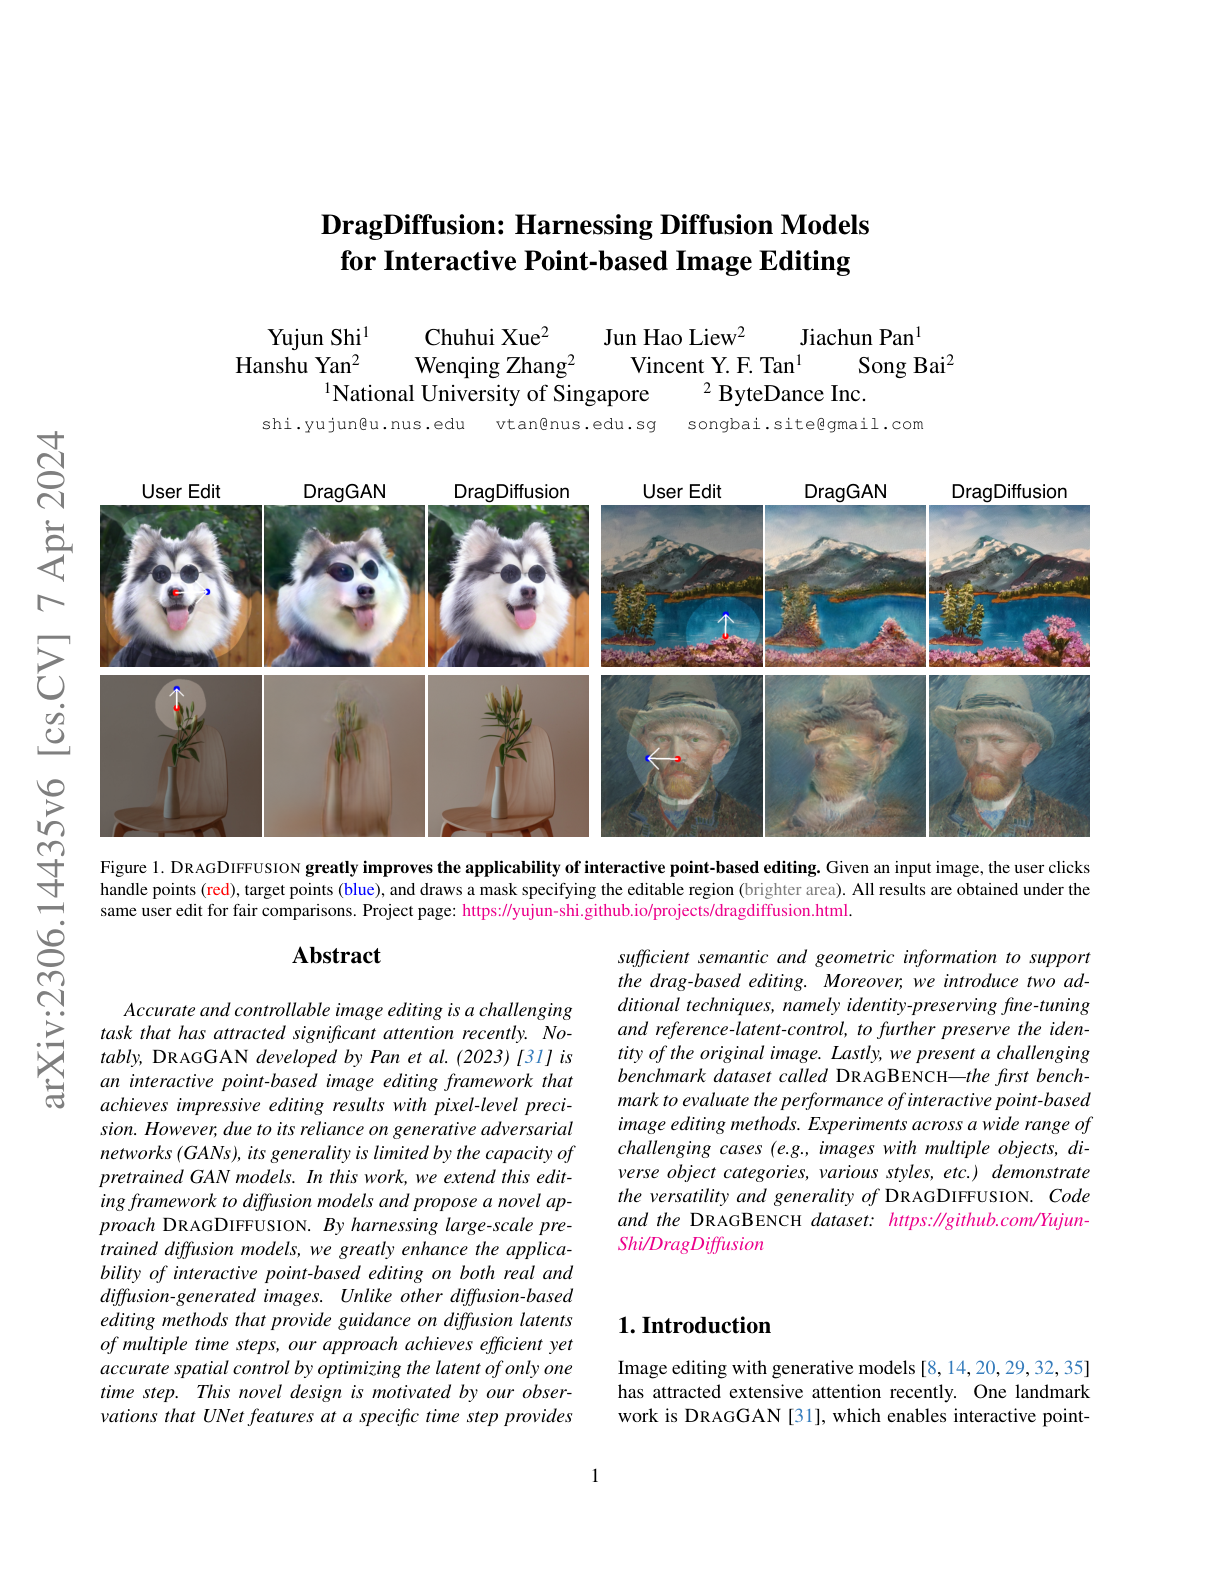
DragDiffusion
Extends interactive point-based image editing to diffusion models.
MotionGPT
Generates consecutive human motions from multimodal control signals via LLM instructions.
AudioPaLM
Fuses PaLM-2 and AudioLM into a multimodal architecture supporting speech understanding and generation.
Voicebox
Meta's all-in-one generative speech model supporting 6 languages and many speech tasks in-context.
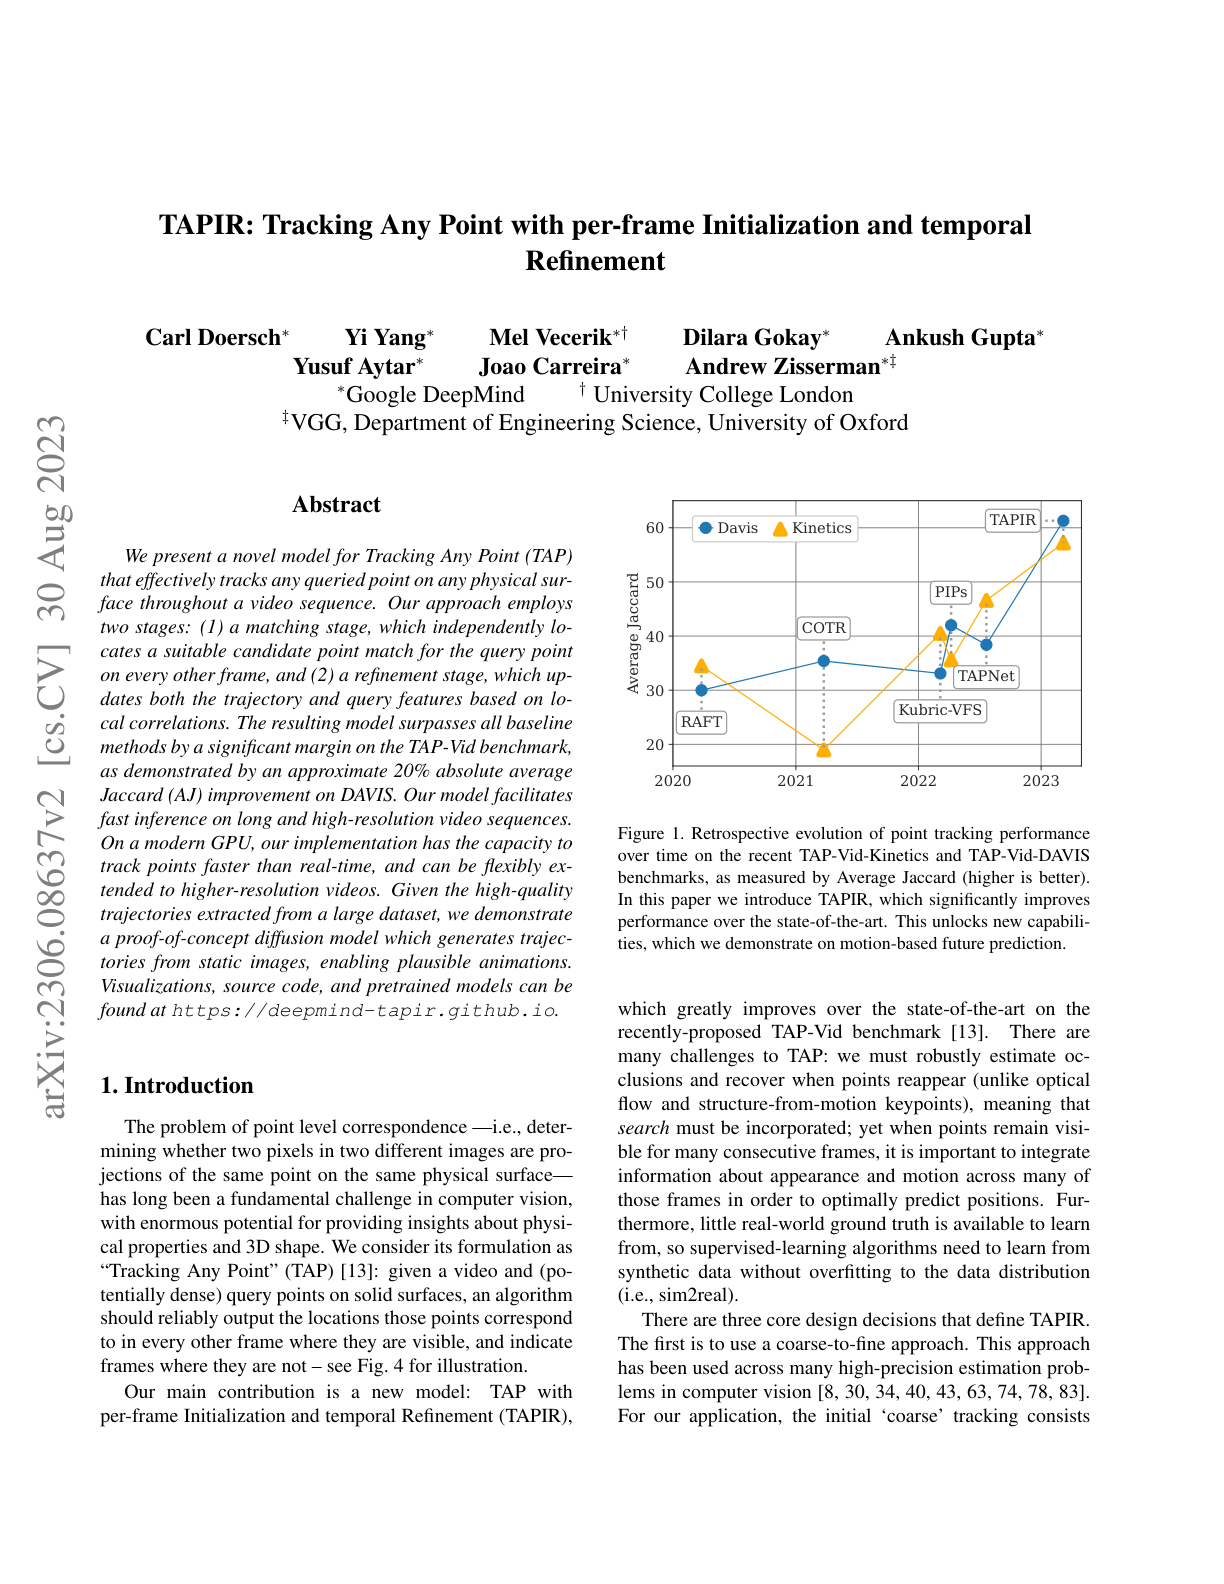
TAPIR
Tracks any queried point on any physical surface throughout a video sequence faster than real-time.
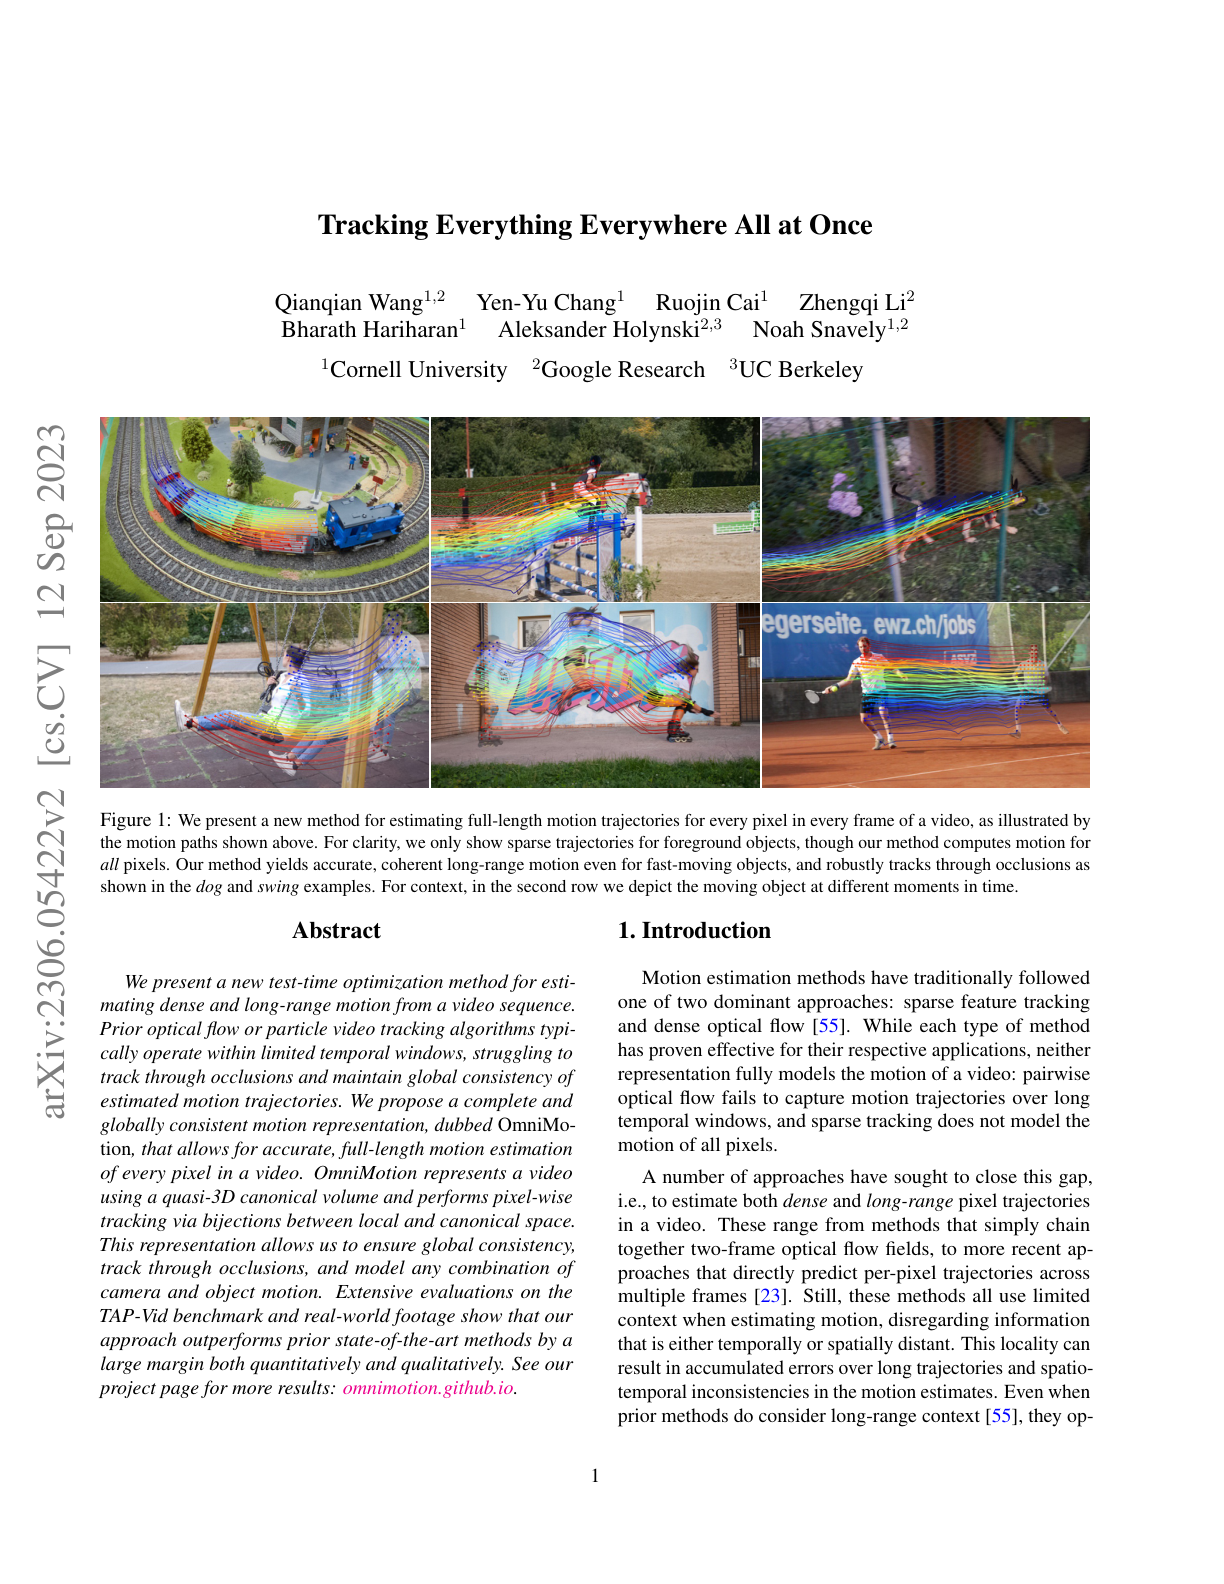
Tracking Everything Everywhere All at Once (OmniMotion)
Test-time optimization for dense, long-range motion estimation.
MusicGen
A simple and controllable model for music generation using a single-stage Transformer.
Hierarchical Vision Transformer (Hiera)
Pretrains ViTs with MAE while removing unnecessary multi-stage complexity.
BiomedGPT
A unified biomedical GPT for vision, language, and multimodal tasks.
MERT
An acoustic music understanding model with large-scale self-supervised training.
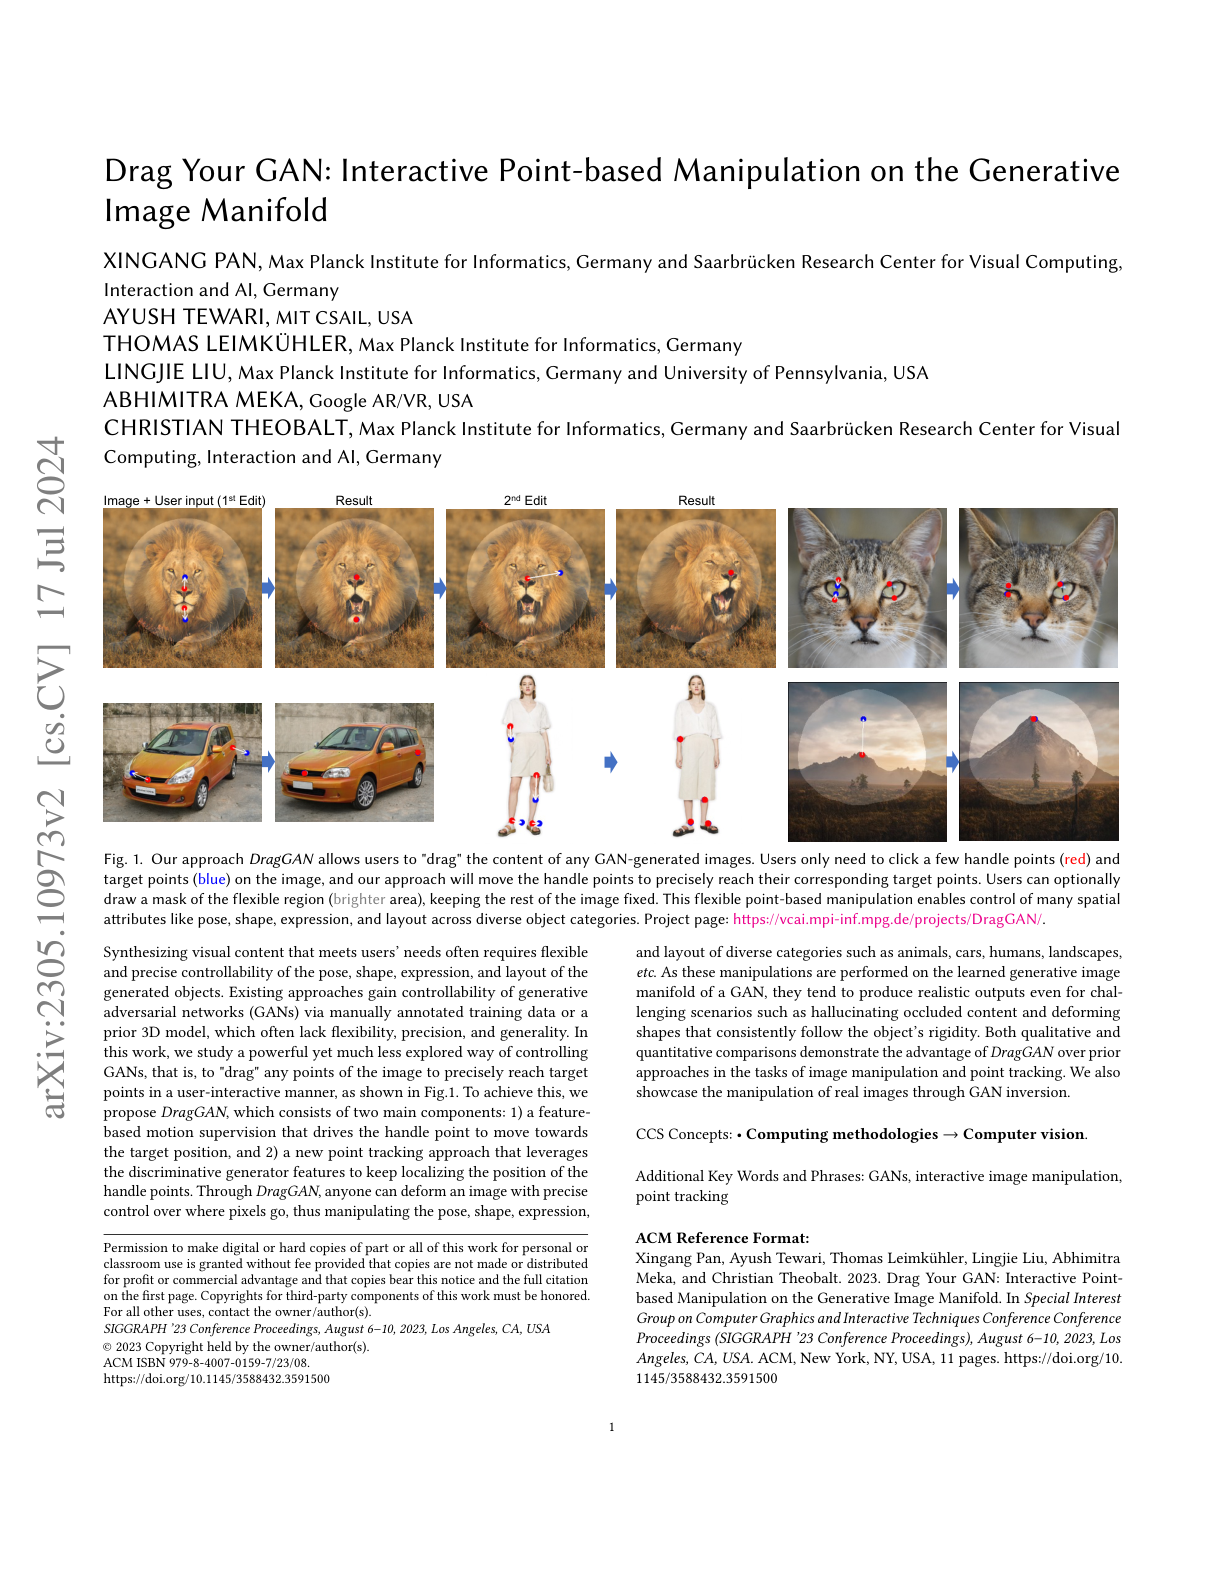
Drag Your GAN (DragGAN)
Interactive point-based image manipulation on the generative image manifold.
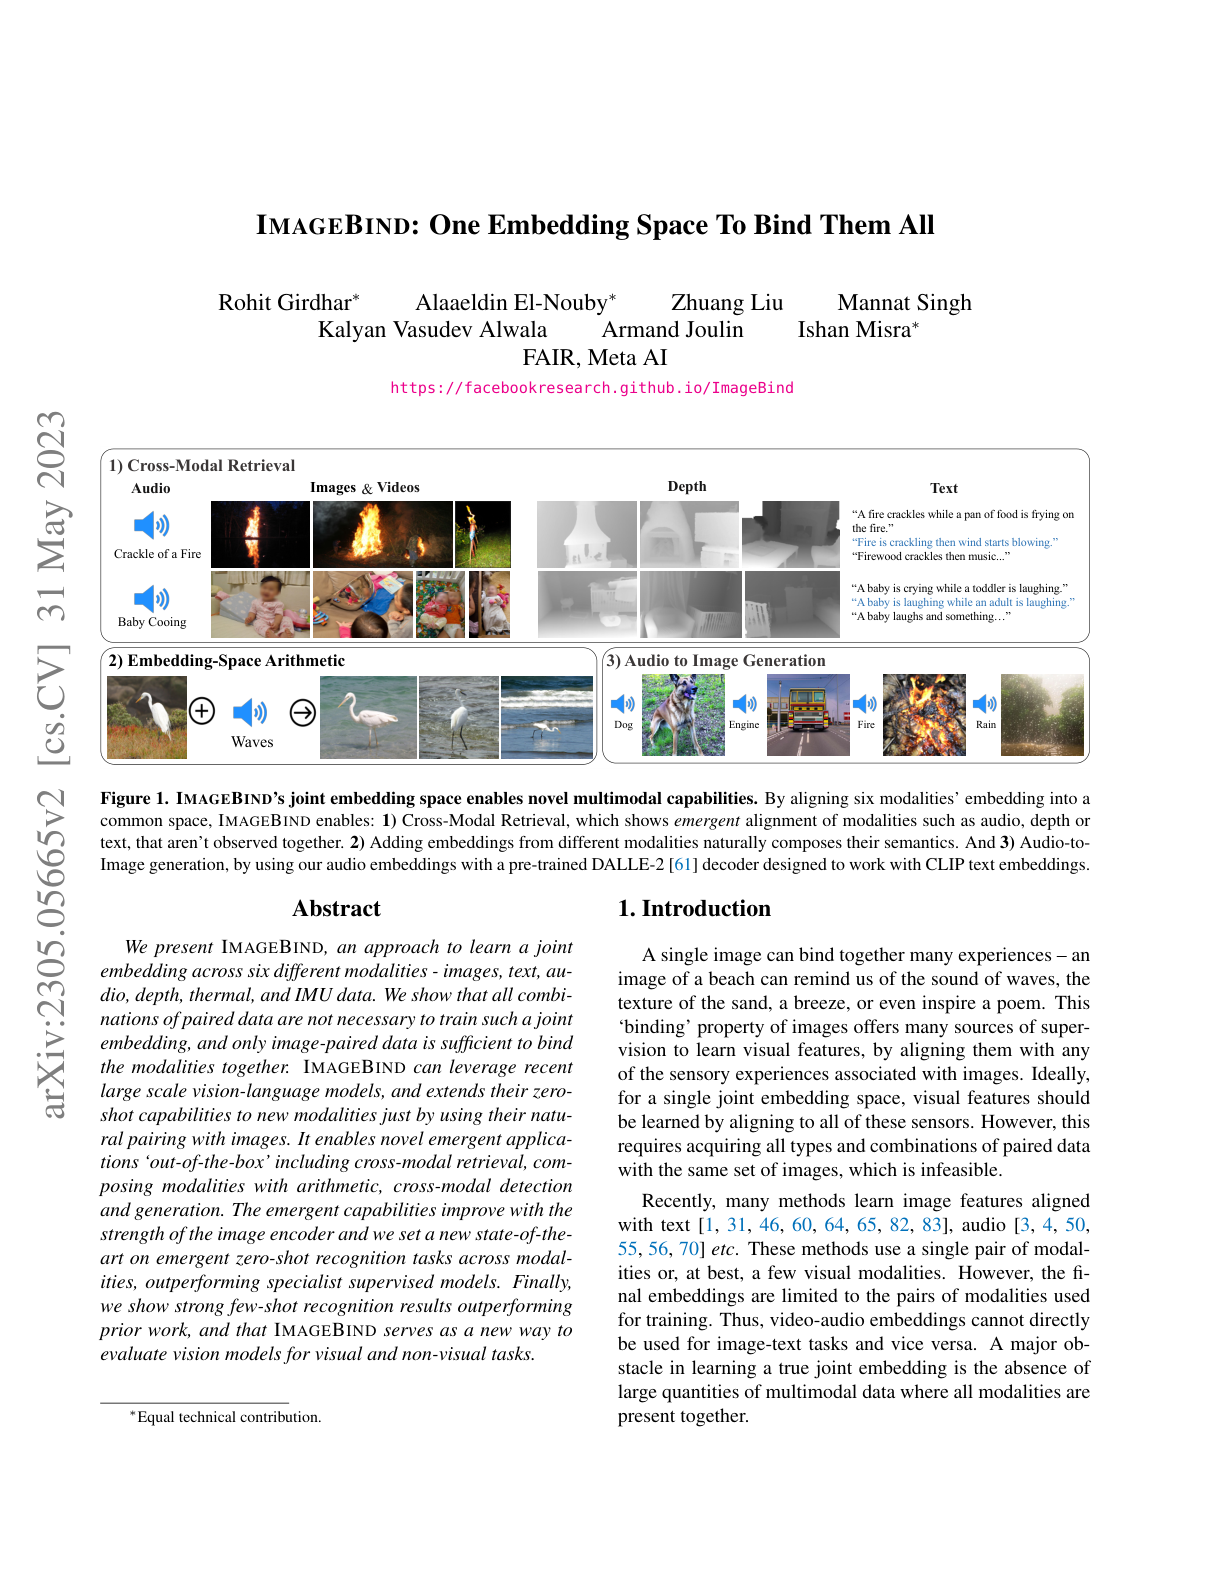
ImageBind
Meta's joint embedding across six modalities at once.
InstructBLIP
Visual-language instruction tuning built on BLIP-2.
MultiModal-GPT
A vision-language model for multi-round dialogue fine-tuned from OpenFlamingo.
Shap-E
OpenAI's conditional generative model for 3D assets producing implicit functions.
Track Anything
An interactive tool for video object tracking and segmentation built on Segment Anything.
AudioGPT
Connects ChatGPT with audio foundational models for speech, music, sound, and talking head tasks.