AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Not All AI Agents Are Equal: Characterizing Resource and Performance Dynamics
Wonmi Choi and colleagues characterize the resource dynamics of LLM agents across retrieval-augmented QA, web search and software coding, and use the measurements to build two scheduling optimizations.
AdaRepair-Mem: Adaptive Experience Orchestration for Repository-Level Program Repair
Z. C. Luo and a 13-author team diagnose three failures in repository-level memory retrieval for program repair, then route memory by repair stage rather than by similarity alone.
Message capacity and claim wording set the transition points of collective truth-finding in language-model networks
Makoto Fukushima at Honda Research Institute Japan shows that the number of peer messages an agent reads, one parameter he calls message capacity, predicts where a language-model collective flips between converging on the truth and converging on a falsehood.
When Hiring Becomes Agent-Mediated: Evaluating Access and Recurrence in Two-Agent Résumé Screening
Jian Gao and Hang Jiang replace one-call resume screening with a two-agent exchange between employer-side and candidate-side agents, and measure both who advances and whether that outcome recurs.
Contagion on the Trading Floor: How Adversarial Signals Spread in Multi-Agent Trading Systems
Qi Rong Sua and colleagues study black-box input-only attacks on LLM trading stacks that enter through admissible social media feeds, using GMATS as a generic model of multi-agent trading architectures.
JustMem: Just-Enough Memory Access for Long-Term Conversations
Guanhua Chen and colleagues formulate conversational memory access along two dimensions, discovery breadth and reading fidelity, and build JustMem to choose the right combination per query.
UnifiedPlayers: Enhance Tool-Integrated Reasoning in Agentic Reinforcement Learning
Wenjie Liao, Liangjie Zhao and Zehong Cao train task generation, execution and evaluation jointly in UnifiedPlayers, rather than pairing self-generated trajectories with a static verifier.
Self Improvement via Fast Tree-search
Xinghong Fu, Aravinth Kulanthaivelu and Yutaro Yamada introduce SIFT, which identifies candidate evaluation as the runtime bottleneck in recursive self-improvement and replaces most of it with a judged tournament.
On-Demand Attention: Language Models Know When to Recall
Haibo Feng and colleagues show that a pretrained model's decoding states already predict whether a global attention read will help, and use that signal to invoke global attention selectively.
Coding Agents with an Obstacle-Aware Harness for Safe Robot Manipulation
Bingxin Xu, Yuzhang Shang, Zhen Dong and Emilio Ferrara evaluate coding agents that write robot controllers under a safety constraint, pairing each manipulation goal with an obstacle the robot must not touch, and find the agent collides in most cases.
MAGS: Multi-agent Auto-formalization Guarantees Safety for Agentic Outputs
Albert Wu, Nicholas Roberts and colleagues at the University of Wisconsin-Madison and Princeton wrap an LLM coding agent in a multi-agent pipeline that writes its own formal specifications, so the generated program carries a machine-checkable safety guarantee instead of a test-passing record.
The Organization of Inference: Information, Resource Constraints, and AI Production
Yukun Zhang, Kemu Xu and Yishen Chen run controlled workflow experiments on externally verified software-engineering tasks to measure how capacity and task information distribute across stages of AI production.
PetriBench: Benchmarking LLM Reasoning over Dynamic State Spaces
Pyrros Koussios and colleagues introduce PetriBench, which evaluates LLM reasoning over dynamic state spaces using Petri nets, a formalism for concurrent and distributed systems, with exact ground truth and procedural generation.
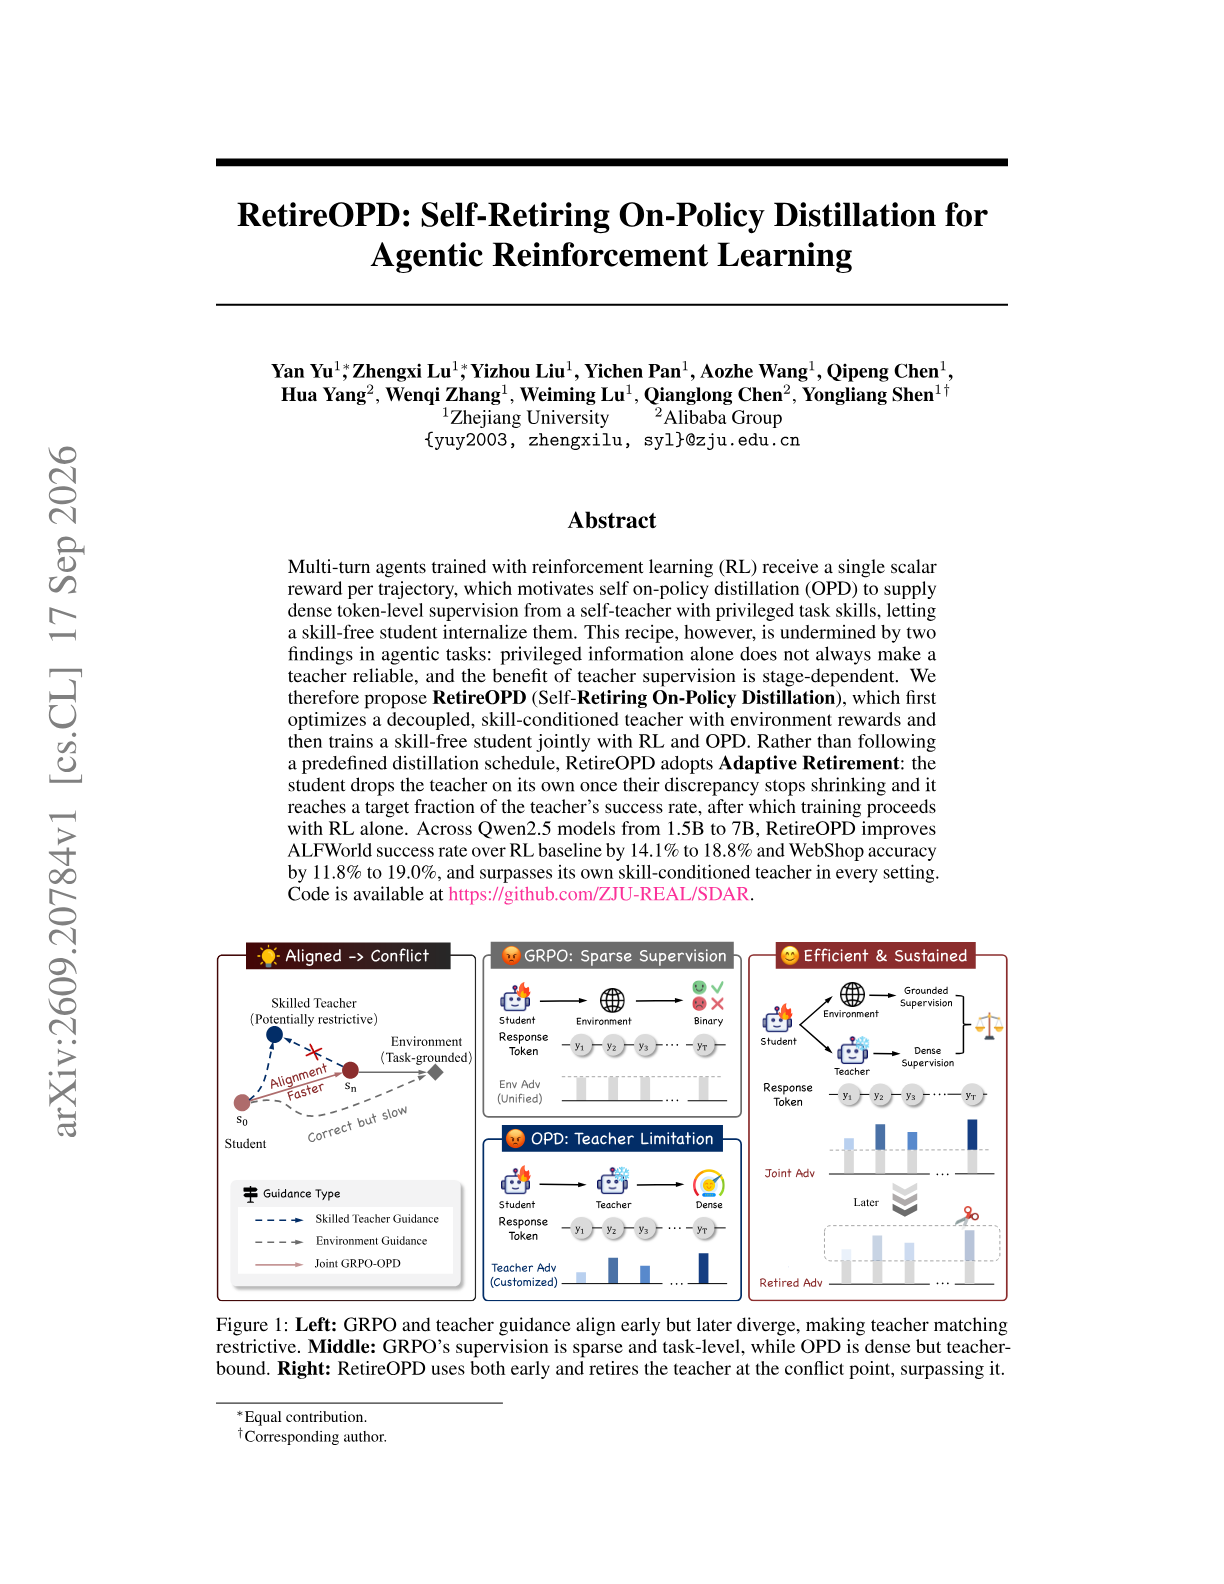
RetireOPD: Self-Retiring On-Policy Distillation for Agentic Reinforcement Learning
Yan Yu and colleagues find that a privileged teacher is not always reliable and that teacher supervision helps only at certain training stages, and propose RetireOPD, where the student drops the teacher on its own.
Can Data Attribution Filter Out Subliminal Learning? Not Reliably
Moritz Weckbecker and co-authors test whether gradient-based training data attribution can find the examples that carry a subliminally transmitted trait, and find that it works inconsistently.
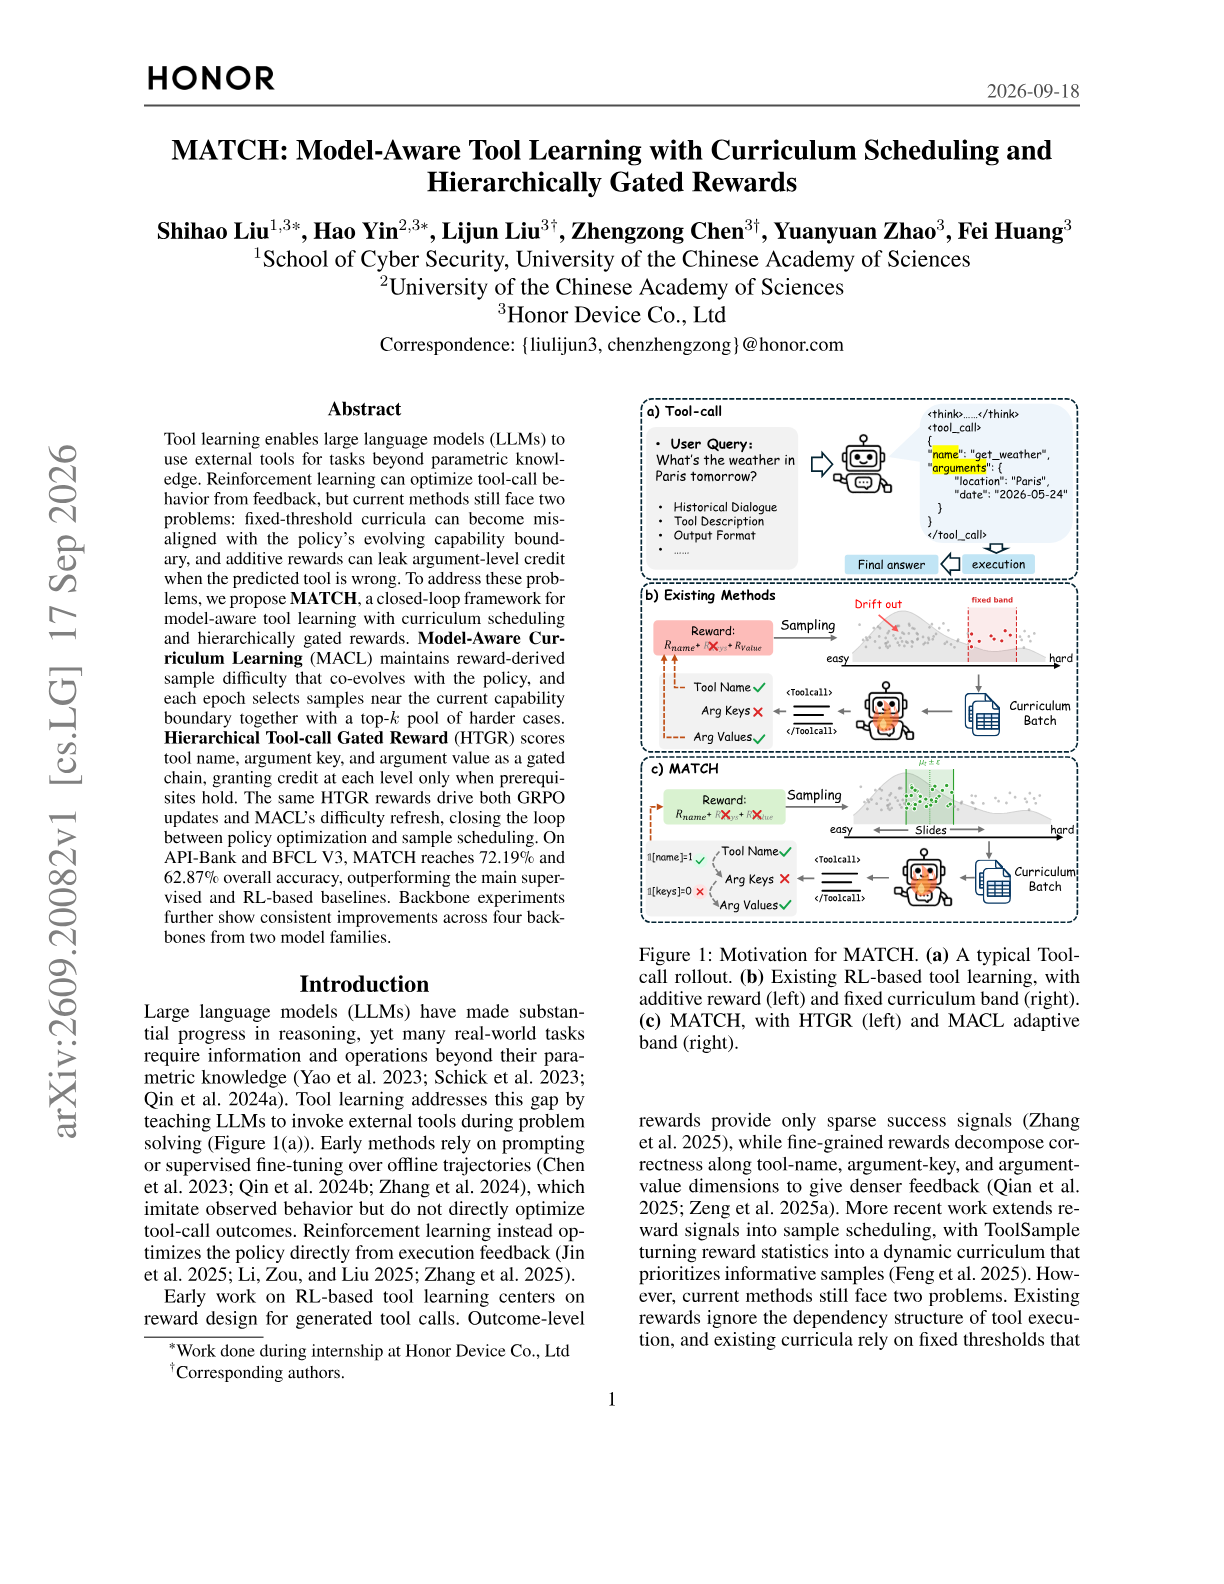
MATCH: Model-Aware Tool Learning with Curriculum Scheduling and Hierarchically Gated Rewards
Shihao Liu and colleagues address two failures in RL for tool use, curricula with fixed difficulty thresholds and additive rewards that leak argument credit when the tool itself is wrong, with MATCH.
Continual Enterprise World Model Discovery in Dynamic Systems
Shambhavi Mishra with ServiceNow Research, Mila and ETS Montreal studies an agent that starts with no knowledge of an enterprise system's business rules and has to discover them by acting, then keep its model current as the rules are revised.
A frontend-backend architecture for tool calls in full-duplex speech models
Ke Hu and colleagues at NVIDIA give a full-duplex speech-to-speech model tool-calling ability by having the speech frontend emit a delegation token and hand streaming transcripts to a text backend LLM, rather than teaching the duplex model to call tools itself.
dQwen3.5: Hybrid-Attention Diffusion Language Models
Anton Xue and colleagues adapt hybrid attention-plus-RNN Qwen3.5 backbones into diffusion language models at 0.8B, 2B, 4B and 9B, producing the dQwen3.5 family.
FINSKILLOPS: A Self-Evolving Multi-Agent System for SEC Filing QA
A 28-author team led by Yanzhang Ma and Zhenghan Tai treats post-deployment improvement of a financial QA system as controlled behavioral maintenance, where each recurring failure becomes a scoped skill patch that must earn deployment without causing regressions.
Position: It is Time to Virtualize Foundation Models with a Self-evolving Operating System Layer
Suparna Bhattacharya and colleagues argue that compound agentic systems now need a Foundation Model Operating System, a layer that virtualizes model interactions the way a virtual machine abstracts hardware.
SoK: Trading Agents or Market Crashers? Dissecting Robustness and Security Failures in Academic Financial LLM Trading Schemes
Mengxiao Wang and Nitesh Saxena present FARSIGHT, a scheme-level evaluation of financial LLM trading agents on robustness under market turbulence and security against three attack classes, and apply it to 15 academic schemes.
GAVEL: Graph World Models for Verified and Efficient Long-Horizon LLM Task Planning
Ruiyang Wang and colleagues present GAVEL, which verifies and repairs long-horizon LLM robot plans against an explicit graph world model holding object relations, action preconditions and effects, and probabilistic beliefs over unobserved locations.
Self-Evolving Search Index
Sangam Lee and colleagues present SELF-INDEX, which lets a retrieval index diagnose its own failures, revise the responsible index keys and validate each revision before committing it.