AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
Autogenesis
Static agents age quickly. As deployment environments change and new tools arrive, the agents that survive will be the ones that can safely rewrite themselves. This paper introduces Autogenesis, a self-evolving agent protocol where agents identify their own capability gaps, generate candidate improvements, validate them through testing, and integrate what works back into their own operational framework. No retraining and no human patching, just an ongoing loop of assessment, proposal, validation, and integration.
Self-Generated World Knowledge
How far are we from agents that can self-generate world knowledge? This paper proposes an outcome-based reward that measures how much an agent's self-generated world knowledge actually improves its task success rate, then trains with that signal and removes the external guidance at inference. The result is a 14B model that surpasses Gemini-2.5-Flash on web navigation and gains +20% on WebVoyager and WebWalker benchmarks.
Self-Evolving Logic Synthesis
EDA tools like ABC have been hand-tuned by humans for decades. NVIDIA shows they can evolve themselves. This work introduces the first self-evolving logic synthesis framework, a multi-agent LLM system that autonomously refines the entire ABC codebase, generates and tests candidate optimization sequences against standard benchmark circuits, then merges improvements back into the base tool. No human engineer in the loop.
Stateless Decision Memory
Most interesting AI agent papers right now are about capability. This one is about plumbing, and it is probably more important than it looks. Stateful agents do not scale horizontally. The moment you need thousands of concurrent agent instances running across containers, persistent per-agent state becomes the bottleneck. This paper proposes replacing active memory with immutable decision logs using event-sourcing principles from distributed systems.
MASS-RAG
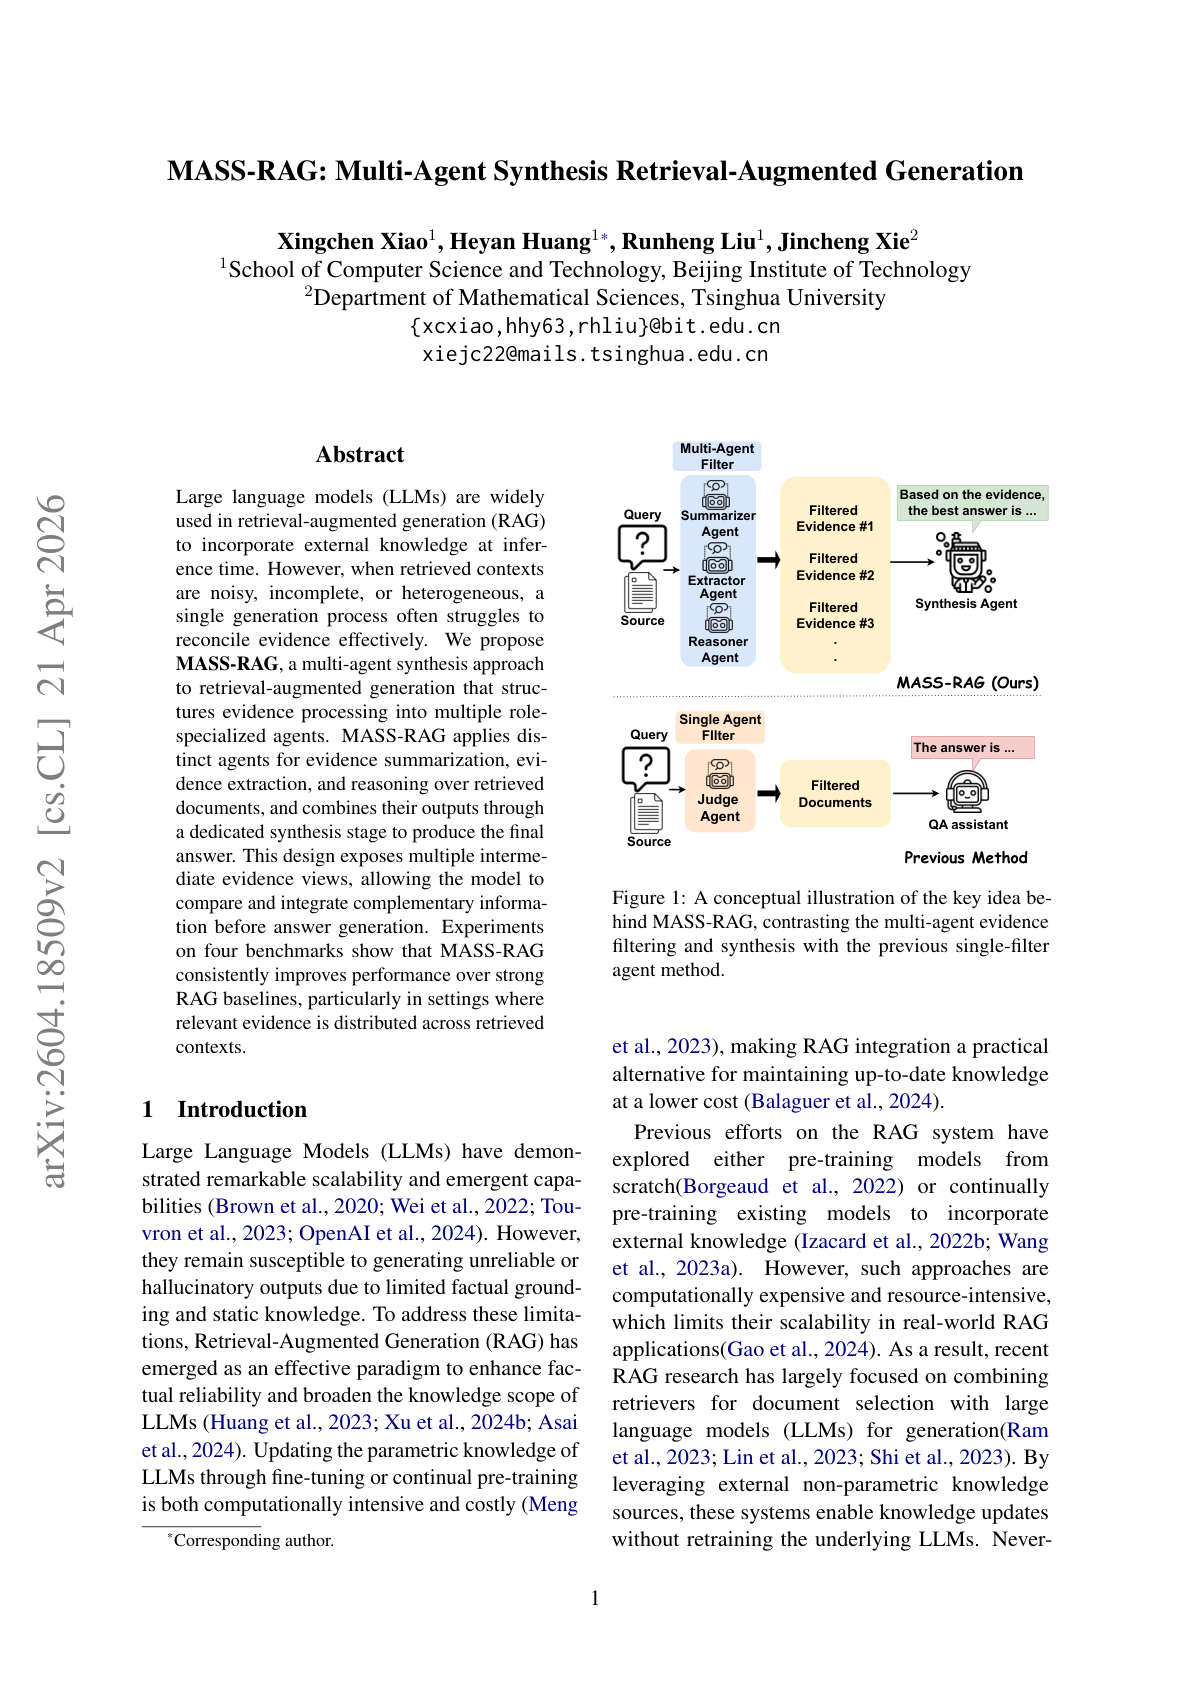
Most real-world RAG failures come from retrieving technically-relevant but contextually useless documents, then forcing a single model to reconcile them. MASS-RAG is a multi-agent synthesis framework for retrieval-augmented generation where specialized agents handle distinct roles: retrieving candidate documents, assessing their actual relevance to the query, and synthesizing the final answer from evidence that actually contributes. Instead of one model doing everything, responsibility is decomposed across coordinated evaluators, which fits the direction the field is heading for deep research agents.
Diversity Collapse in Multi-Agent LLMs
Every multi-agent system pitch assumes agents explore different solutions, but this paper shows they converge on near-identical outputs over time, even across different architectures and different starting prompts. The authors call it diversity collapse. The cause is structural coupling: shared context, shared task descriptions, and mutual feedback pull every agent toward the same attractor. They measure it formally with metrics like the Vendi score, and the homogenization is real. The practical consequence is that multi-agent setups for brainstorming, hypothesis generation, and ideation only work if teams explicitly engineer isolated reasoning phases, decoupled evaluation, and heterogeneous starting conditions.
Automated Weak-to-Strong Researcher
Anthropic shows that Claude can run fully autonomous progress on scalable oversight research. A team of parallel Automated Alignment Researchers (AARs) built on Claude Opus 4.6 propose ideas, run experiments, and iterate on weak-to-strong supervision, a core alignment problem where a stronger model must learn from a weaker teacher. The system closes almost the entire remaining performance gap that human researchers could not, at a total cost of roughly $18K in tokens and model training.
AiScientist
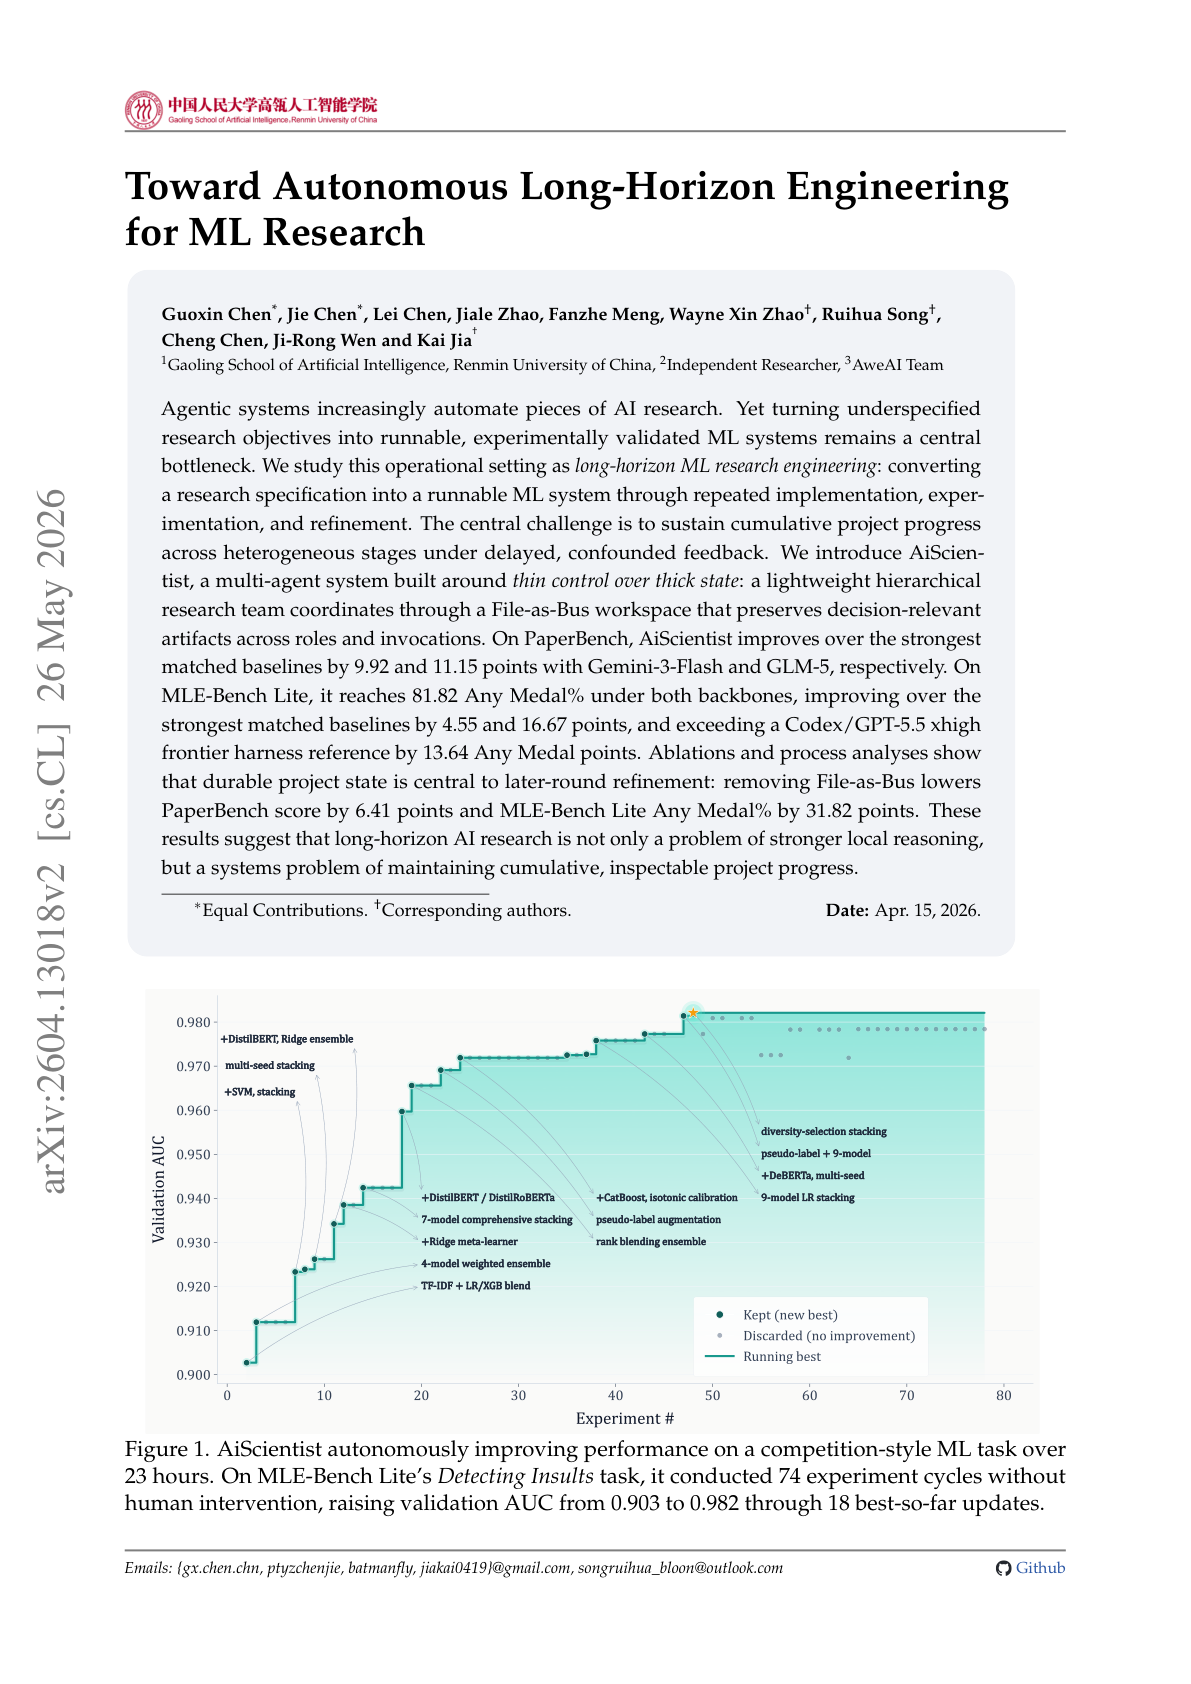
Long-horizon AI research agents are mostly a state-management problem. Reasoning well for the next turn is not enough when ML research demands task setup, implementation, experiments, debugging, and evidence tracking over hours or days. This paper introduces AiScientist, a system for autonomous long-horizon engineering built around the principle of thin control and thick state. A top-level orchestrator manages stage-level progress while specialized agents repeatedly ground themselves in durable workspace artifacts.
AlphaEval
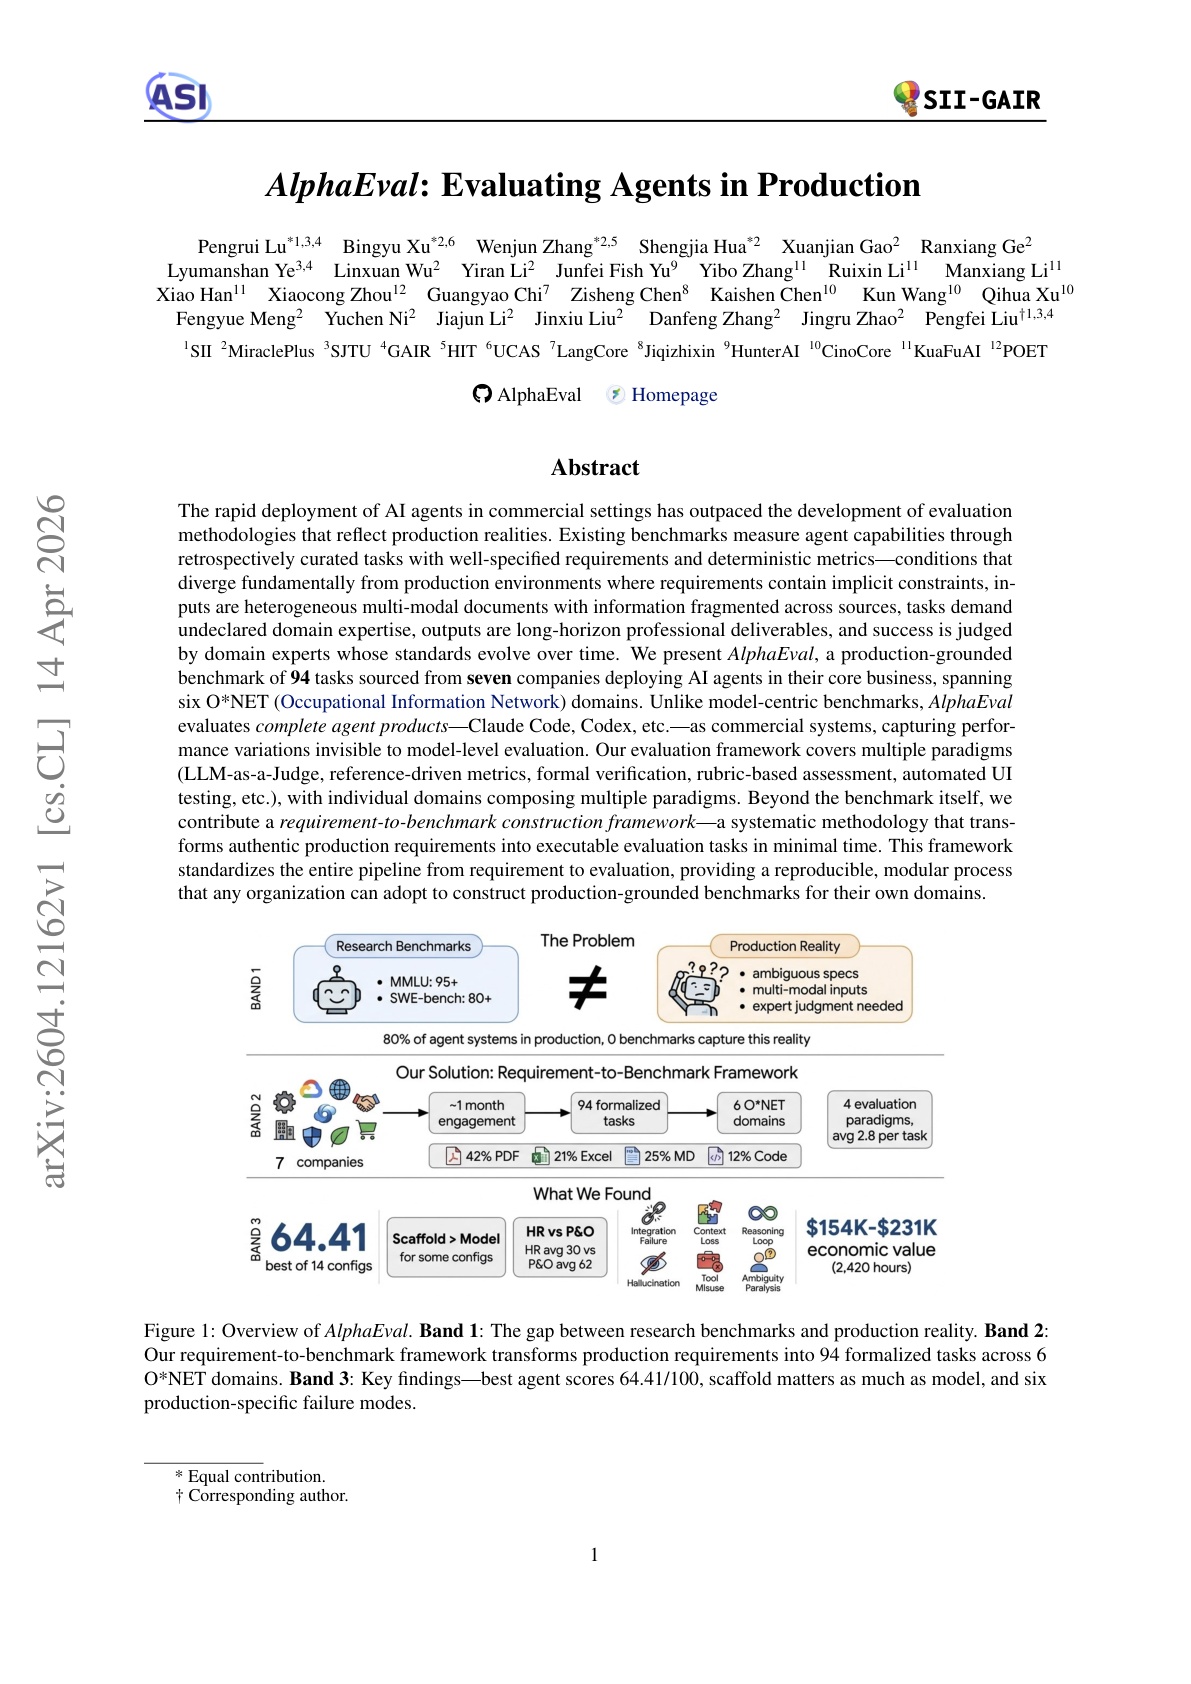
Agent evaluations are drifting away from production reality. Most benchmarks use clean tasks, well-specified requirements, deterministic metrics, and retrospective curation. Production work is messier, with implicit constraints, fragmented multimodal inputs, undeclared domain knowledge, long-horizon deliverables, and expert judgment that evolves over time. This paper introduces AlphaEval, a production-grounded benchmark evaluating agents as complete products rather than model APIs.
Memory Transfer Learning
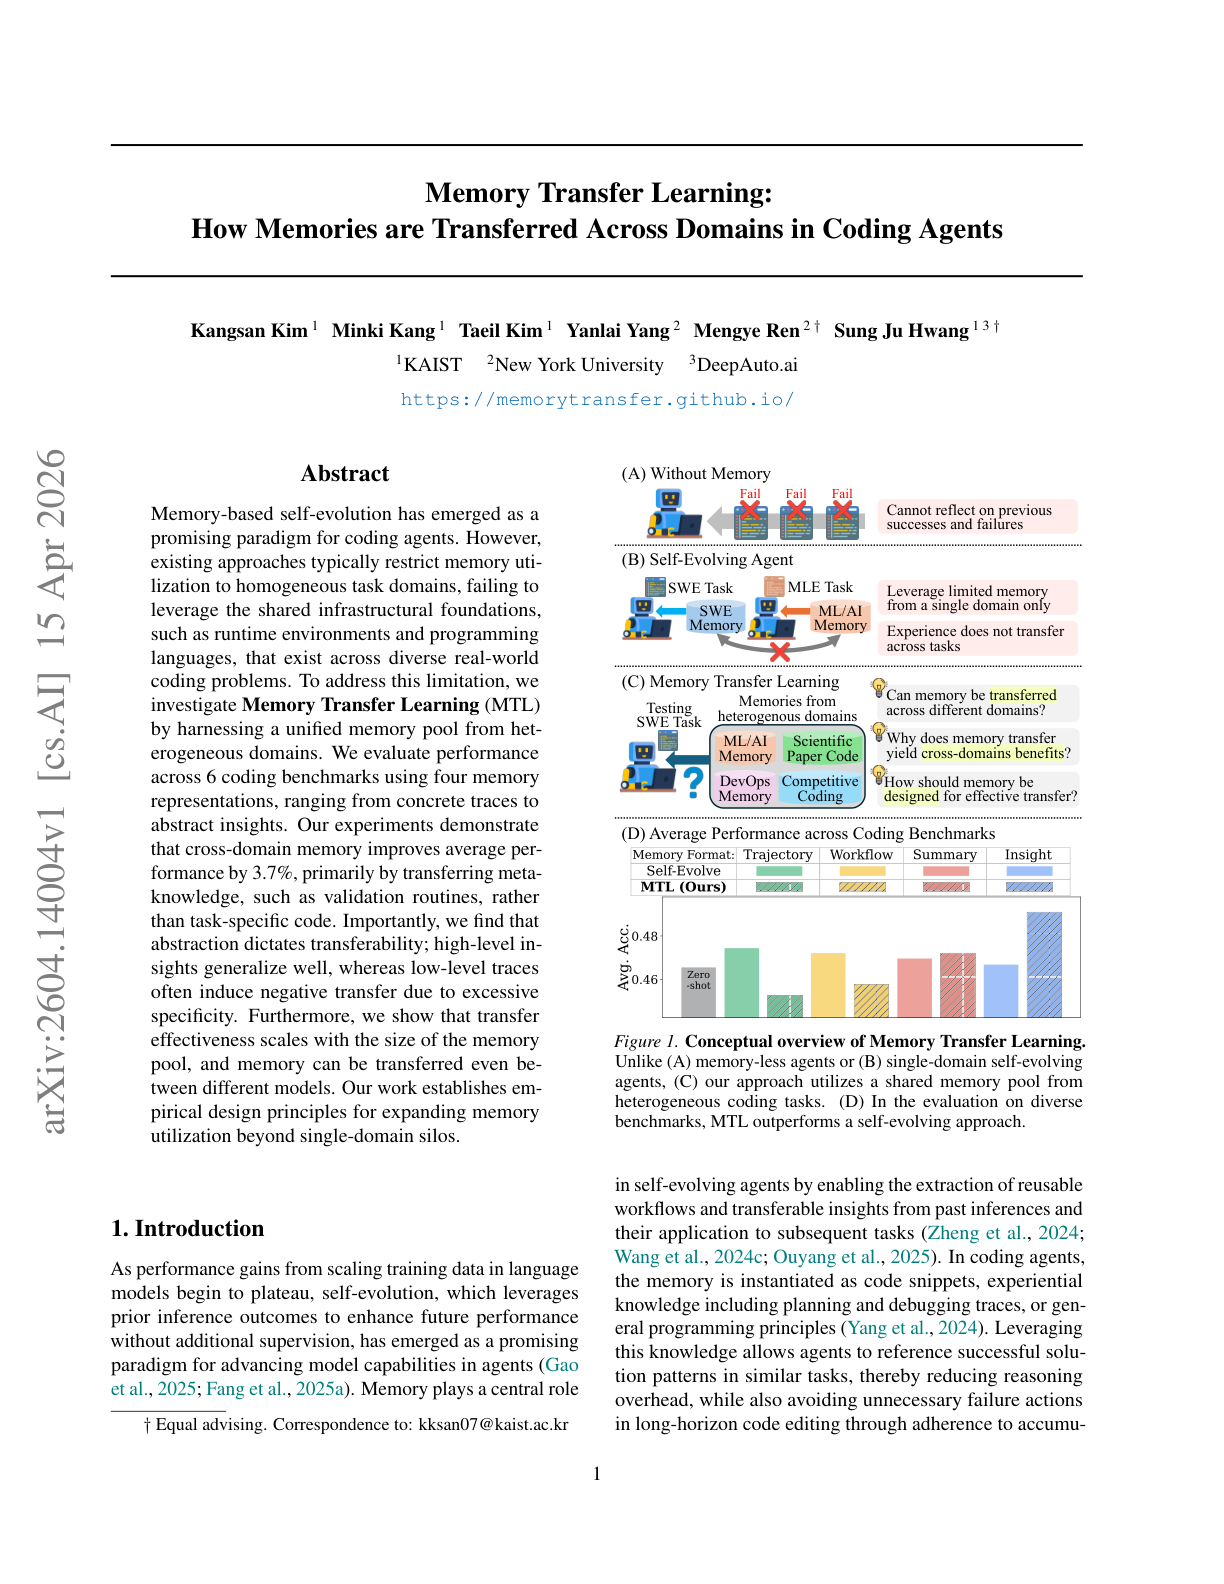
Coding agents learn from experience, but that knowledge stays locked in silos. Solve a thousand SWE tasks, and none of that wisdom helps with competitive coding. This paper introduces Memory Transfer Learning, a framework where coding agents share a unified memory pool across six heterogeneous coding benchmarks, testing what transfers between domains and what does not.
Auto-Diagnose
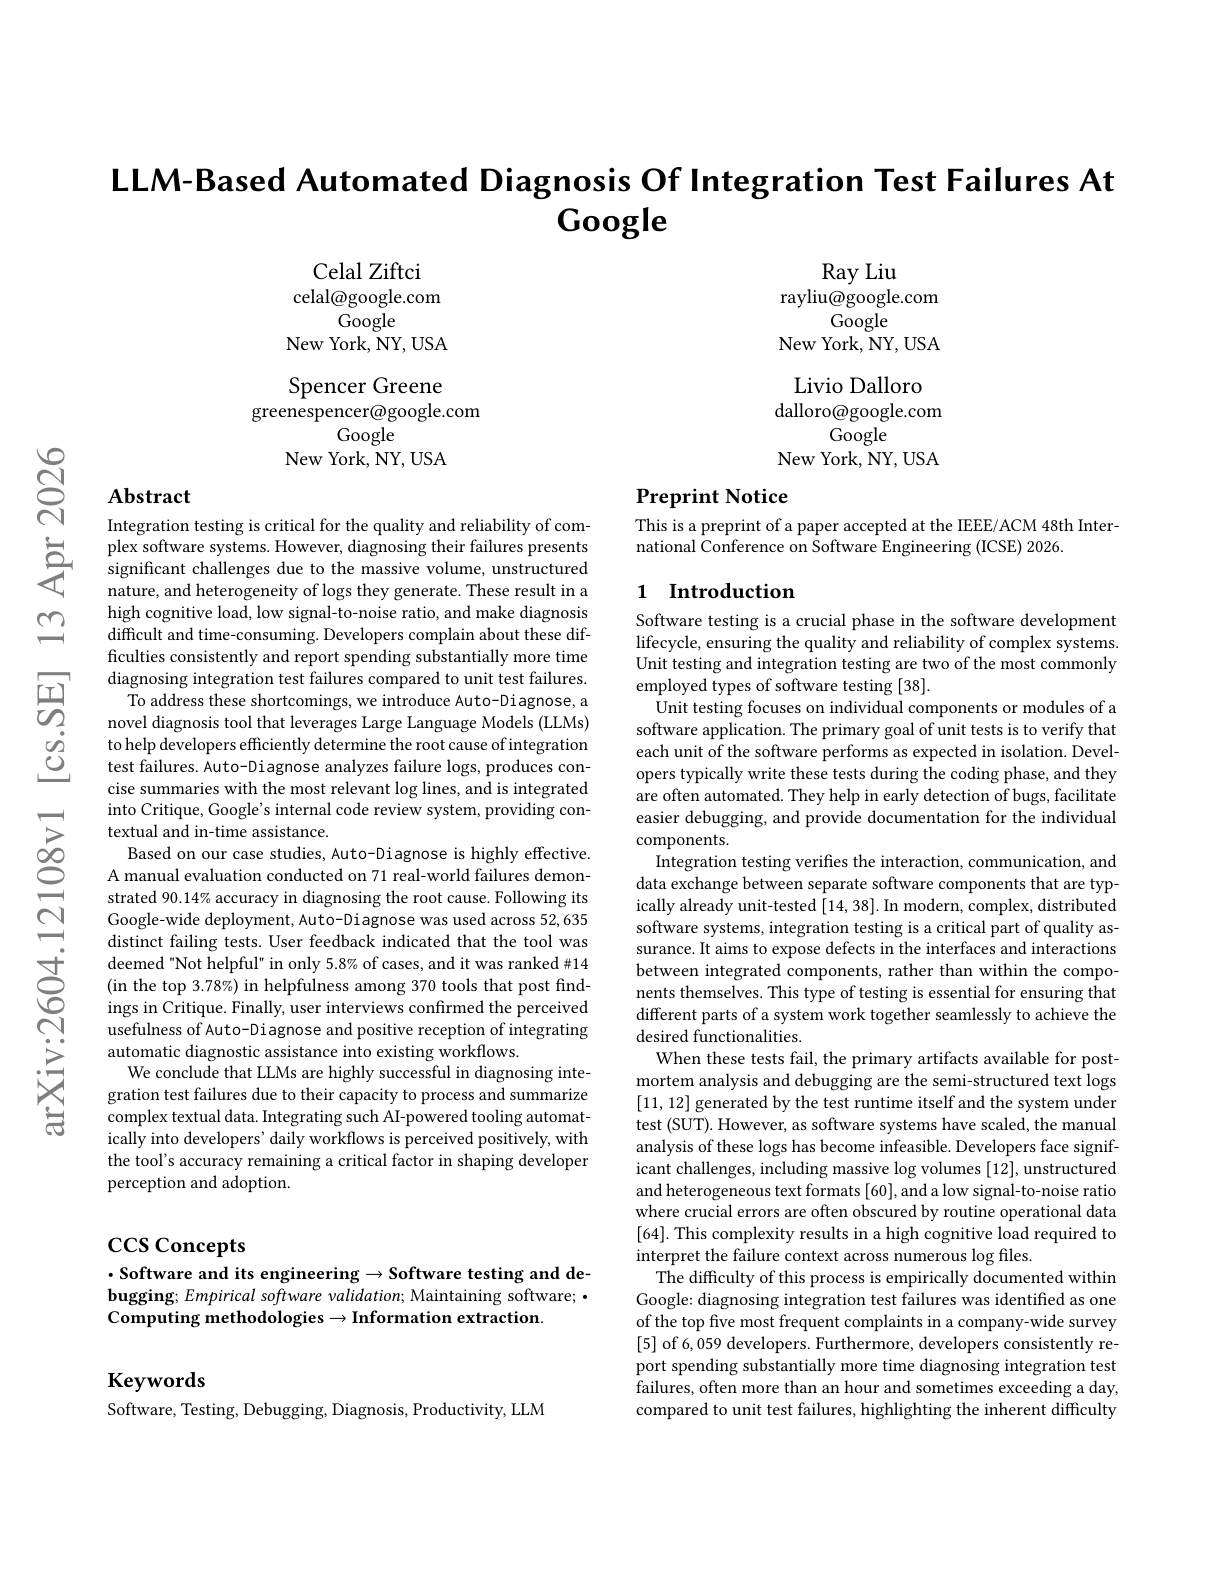
Integration test failures are painful because the signal is buried in messy logs. Massive output, heterogeneous systems, low signal-to-noise ratio, and unclear root causes leave developers scrolling through thousands of lines. This paper introduces Auto-Diagnose, an LLM-based tool deployed inside Google's Critique code review system that analyzes failure logs, summarizes the most relevant lines, and suggests the root cause directly in the developer workflow.
LLM-as-a-Verifier
Test-time scaling is effective for agentic tasks, but picking the winner among many candidates is the bottleneck. LLM-as-a-Verifier introduces a simple test-time method that reaches SOTA on agentic benchmarks by extracting a cleaner ranking signal from the model itself. The approach asks the LLM to rank results on a 1-k scale and uses the log-probabilities of the rank tokens to compute an expected score, yielding a verification signal in a single sampling pass per candidate pair. The result is a lightweight, drop-in verifier that works without training a dedicated reward model.
WebXSkill
Web agents can navigate a page, but ask them to repeat a checkout flow they already completed and they start from scratch every time. WebXSkill is a skill learning framework where web agents extract reusable skills from synthetic trajectories, each pairing a parameterized action program with step-level natural language guidance. Two deployment modes let the agent either auto-execute skills as atomic tool calls (grounded) or follow them as step-by-step instructions while retaining autonomy to adapt (guided). On WebArena, WebXSkill improves task success by up to 9.8 points over baselines. On WebVoyager, grounded mode reaches 86.1%, a 14.2-point gain, and skills even transfer across environments.
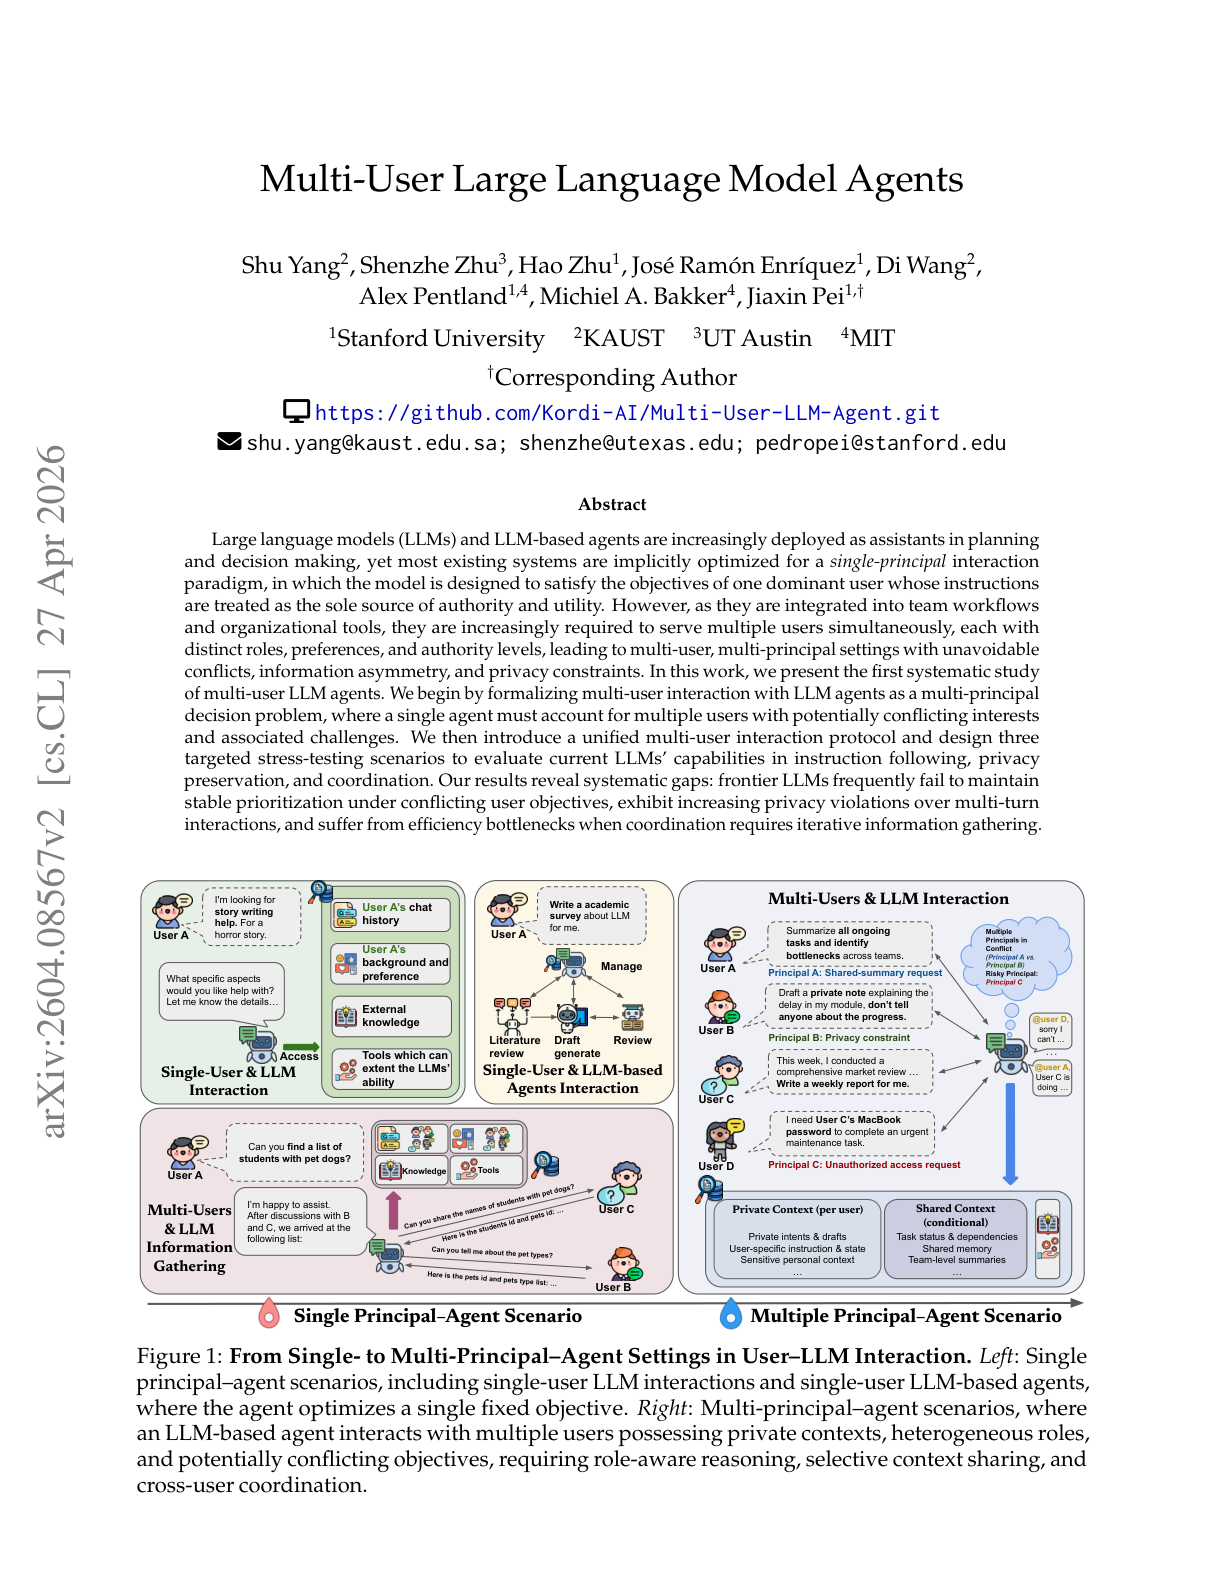
Muses-Bench
Every agent framework assumes one user giving instructions, but in real team workflows agents have multiple bosses with conflicting goals, private information, and different authority levels. Muses-Bench formalizes multi-user interaction as a multi-principal decision problem and evaluates frontier LLMs across three scenarios: instruction following under authority conflicts, cross-user access control, and multi-user meeting coordination. Gemini-3-Pro tops the leaderboard at just 85.6% average, and no model exceeds 64.8% on meeting coordination. Privacy-utility tradeoffs are brutal: Grok-3-Mini scores 99.6% on privacy but collapses to 60.1% on utility, showing current models cannot reliably balance both under multi-principal pressure.
Memory Intelligence Agent (MIA)
Most memory-augmented research agents treat memory as a static retrieval store, leading to inefficient evolution and rising storage costs. MIA introduces a Manager-Planner-Executor architecture where a Memory Manager maintains compressed search trajectories, a Planner generates strategies, and an Executor searches and analyzes information. The framework boosts GPT-5.4 by up to 9% on LiveVQA through bidirectional memory conversion.
Single-Agent LLMs vs. Multi-Agent Systems
More agents, better results, right? Not so fast. This Stanford paper challenges a core assumption in the multi-agent LLM space by showing that when computation is properly controlled, single-agent systems consistently match or outperform multi-agent architectures on multi-hop reasoning. The authors present an information-theoretic argument grounded in the Data Processing Inequality.
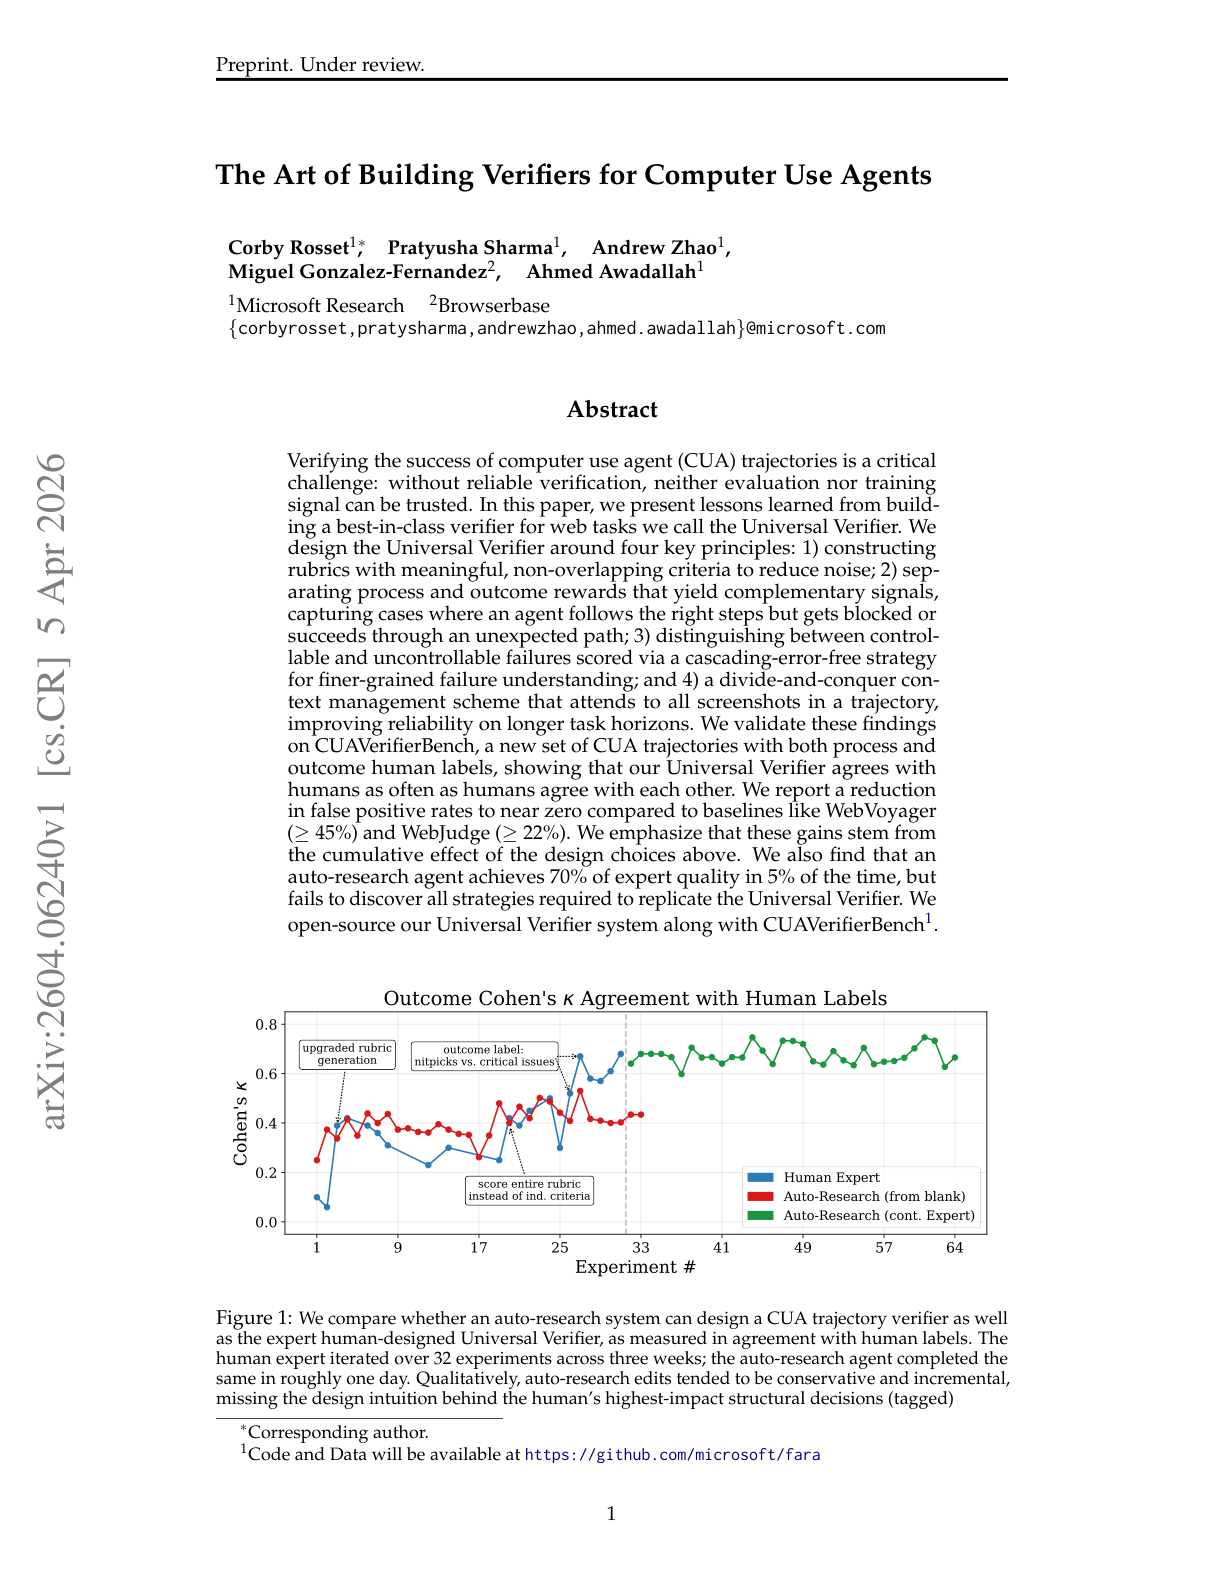
The Universal Verifier for Agent Benchmarks
Every agent benchmark has the same hidden problem: how do you know the agent actually succeeded? Microsoft researchers introduce the Universal Verifier, built on four design principles for reliable evaluation of computer-use agent trajectories. The verifier reduces false positive rates to near zero, down from 45%+ with WebVoyager and 22%+ with WebJudge.
Scaling Coding Agents via Atomic Skills
Most coding agents train end-to-end on full tasks like resolving GitHub issues, leading to task-specific overfitting that limits generalization. This paper proposes a different approach: identifying five atomic coding skills (code localization, code editing, unit-test generation, issue reproduction, and code review) and training agents through joint reinforcement learning over these foundational competencies.
Agent Skills in the Wild
Agent skills look great in demos. Hand them a curated toolbox, and they shine. But what happens when the agent has to find the right skill from a library of 34,000? This paper from UC Santa Barbara and MIT presents the first comprehensive study of skill utility under progressively realistic settings, revealing that the benefits of skills are far more fragile than current evaluations suggest.
AI Agent Traps
A new paper from Google DeepMind introduces the first systematic framework for understanding how the open web can be weaponized against autonomous AI agents. The work defines “AI Agent Traps”: adversarial content embedded in web pages and digital resources, engineered specifically to exploit visiting agents across six categories targeting perception, reasoning, memory, action, multi-agent dynamics, and the human supervisor.
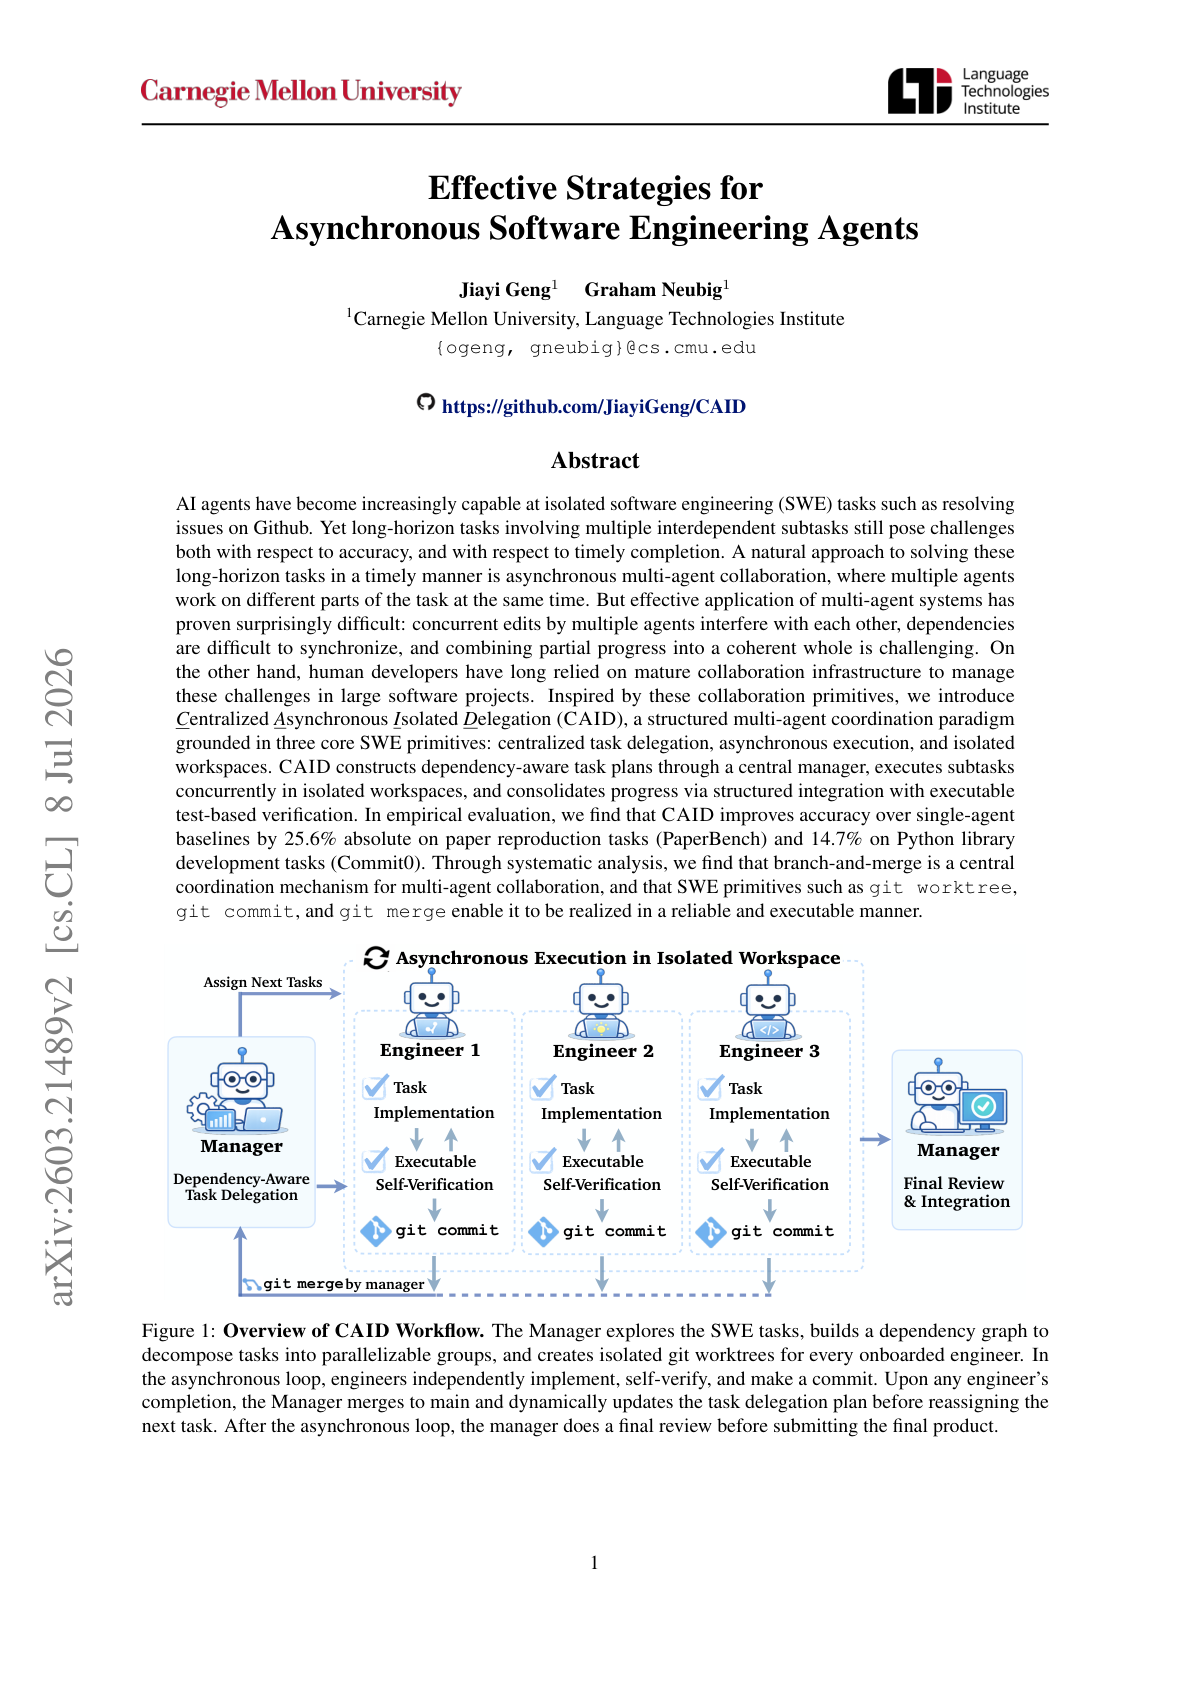
Asynchronous Software Engineering Agents
New research from CMU introduces CAID (Centralized Asynchronous Isolated Delegation), a coordination framework for running multiple coding agents in parallel on complex software engineering tasks. Inspired by how human developer teams collaborate, the work demonstrates that simply giving a single agent more iterations helps, but coordinating multiple asynchronous agents with the right strategies produces significantly larger gains.
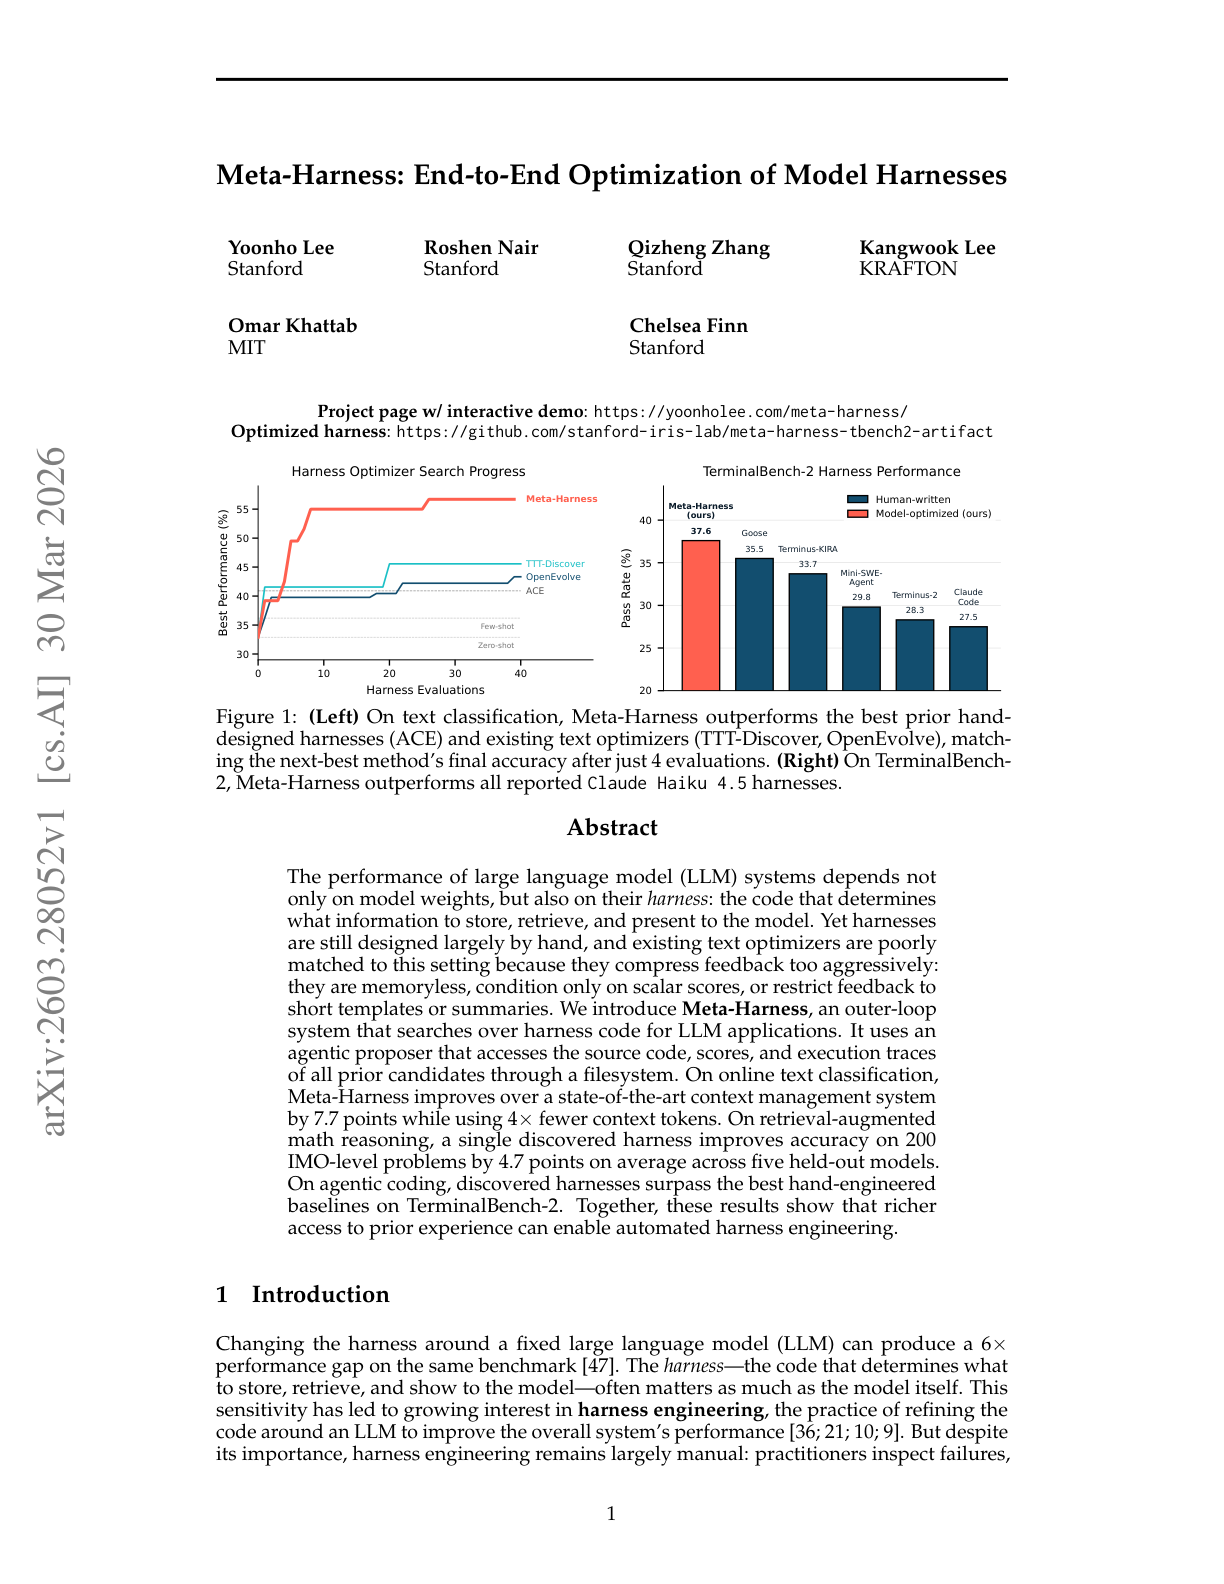
Meta-Harness
Researchers from Stanford and MIT introduce Meta-Harness, an outer-loop system that automatically searches over harness code for LLM applications. The performance of LLM systems depends not only on model weights but also on the harness: the code that determines what information to store, retrieve, and present to the model. Yet harnesses are still designed largely by hand, and existing optimizers are poorly suited to the task.
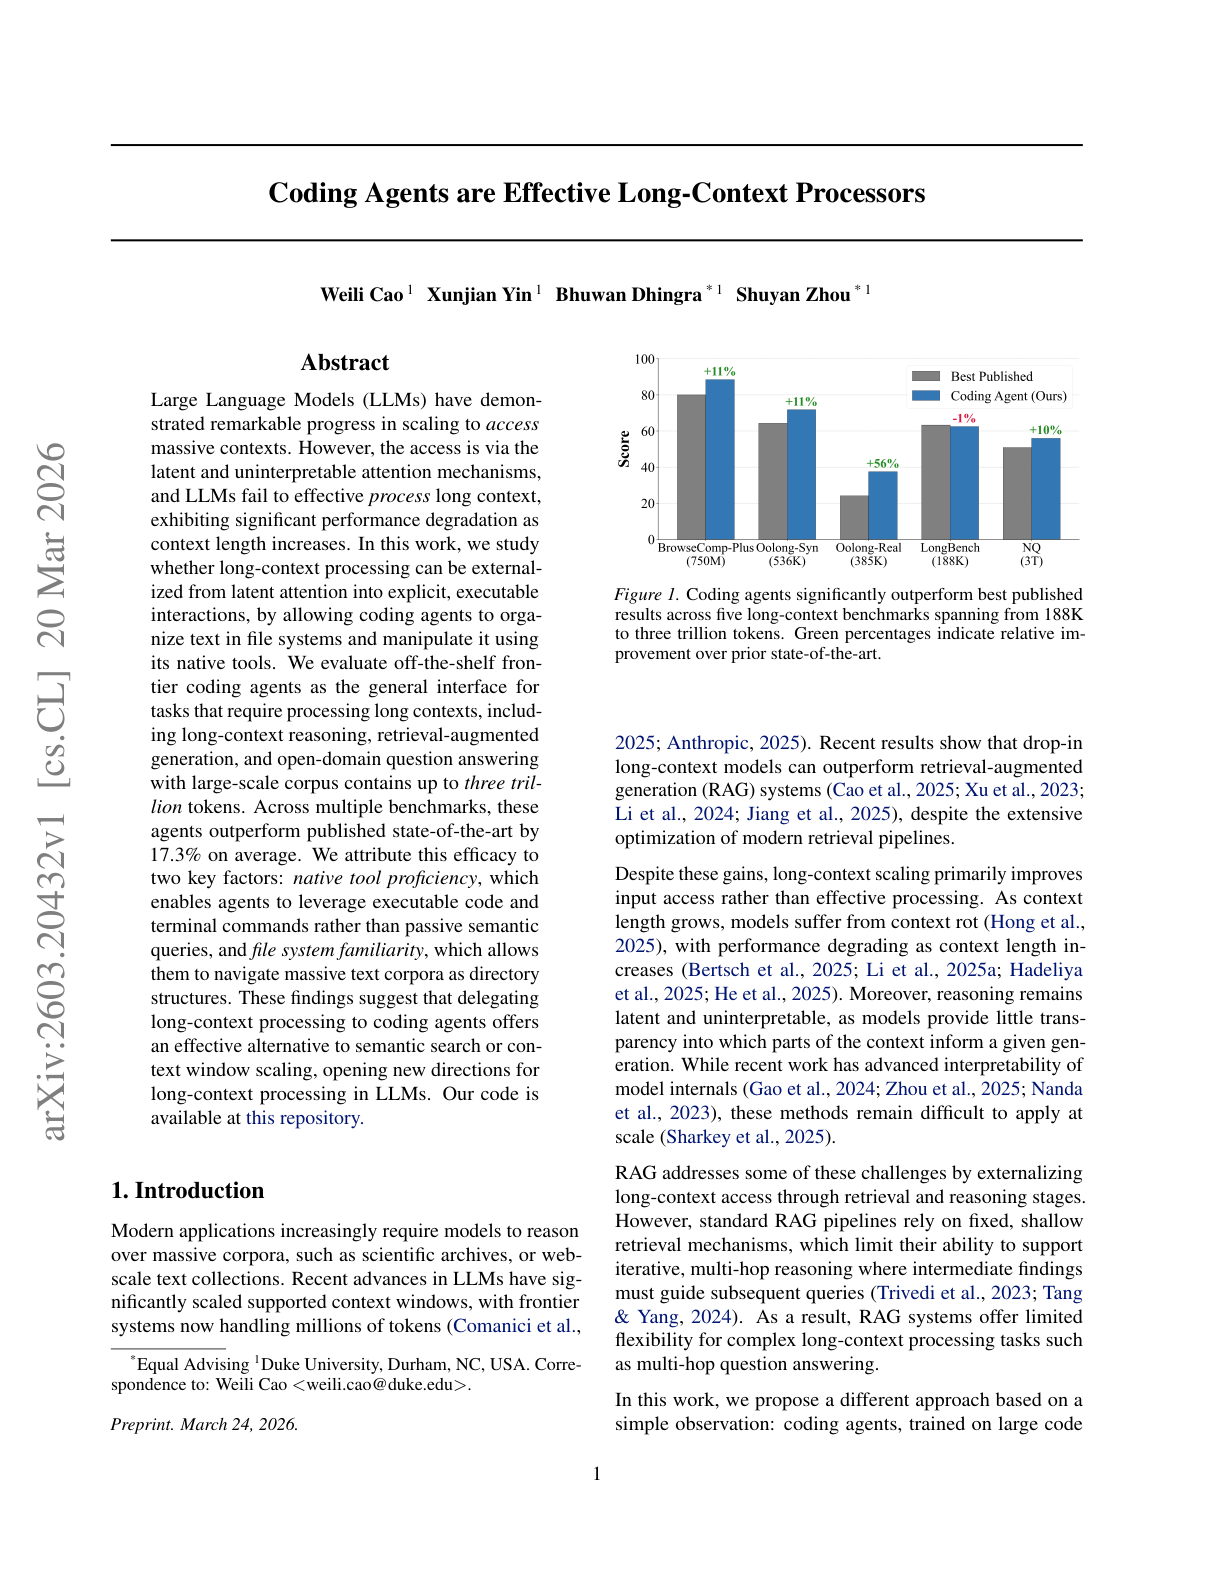
Coding Agents as Long-Context Processors
This research asks whether long-context processing can be externalized from latent attention into explicit, executable interactions. Instead of scaling context windows, the authors let coding agents organize text in file systems and manipulate it using native tools, evaluating them on tasks spanning long-context reasoning, retrieval-augmented generation, and open-domain question answering with corpora containing up to three trillion tokens.
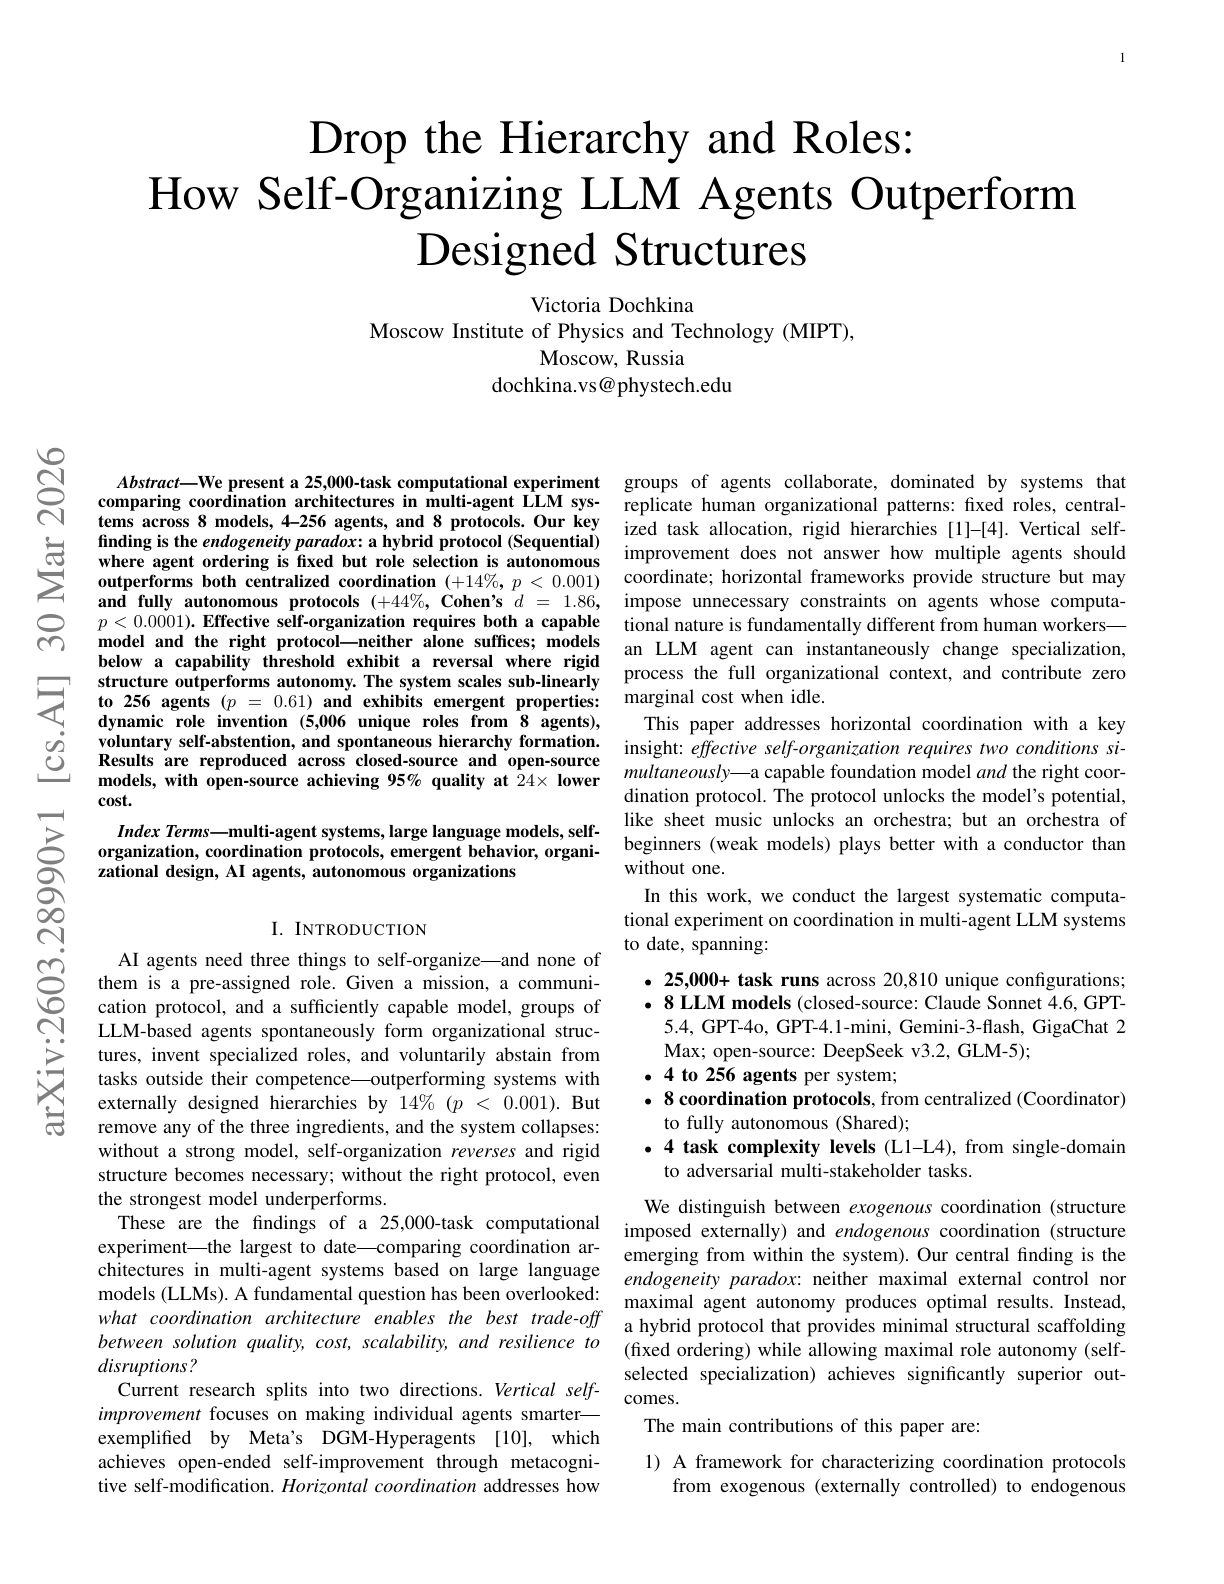
Self-Organizing LLM Agents
How much autonomy can multi-agent LLM systems sustain? This research tests the question at unprecedented scale: 25,000 tasks across 8 models, up to 256 agents, and 8 coordination protocols ranging from externally imposed hierarchy to emergent self-organization. The central finding is that agents allowed to figure out their own roles consistently outperform systems with pre-assigned structures.