AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
Universal Adversarial LLM Attacks
Finds universal and transferable adversarial attacks that cause aligned models like ChatGPT and Bard to generate objectionable behaviors.
Survey of Aligned LLMs
A comprehensive overview of alignment approaches covering data, training, and evaluation.
Llama 2
Meta's open-weight foundation model family with chat-tuned variants ranging from 7B to 70B parameters.
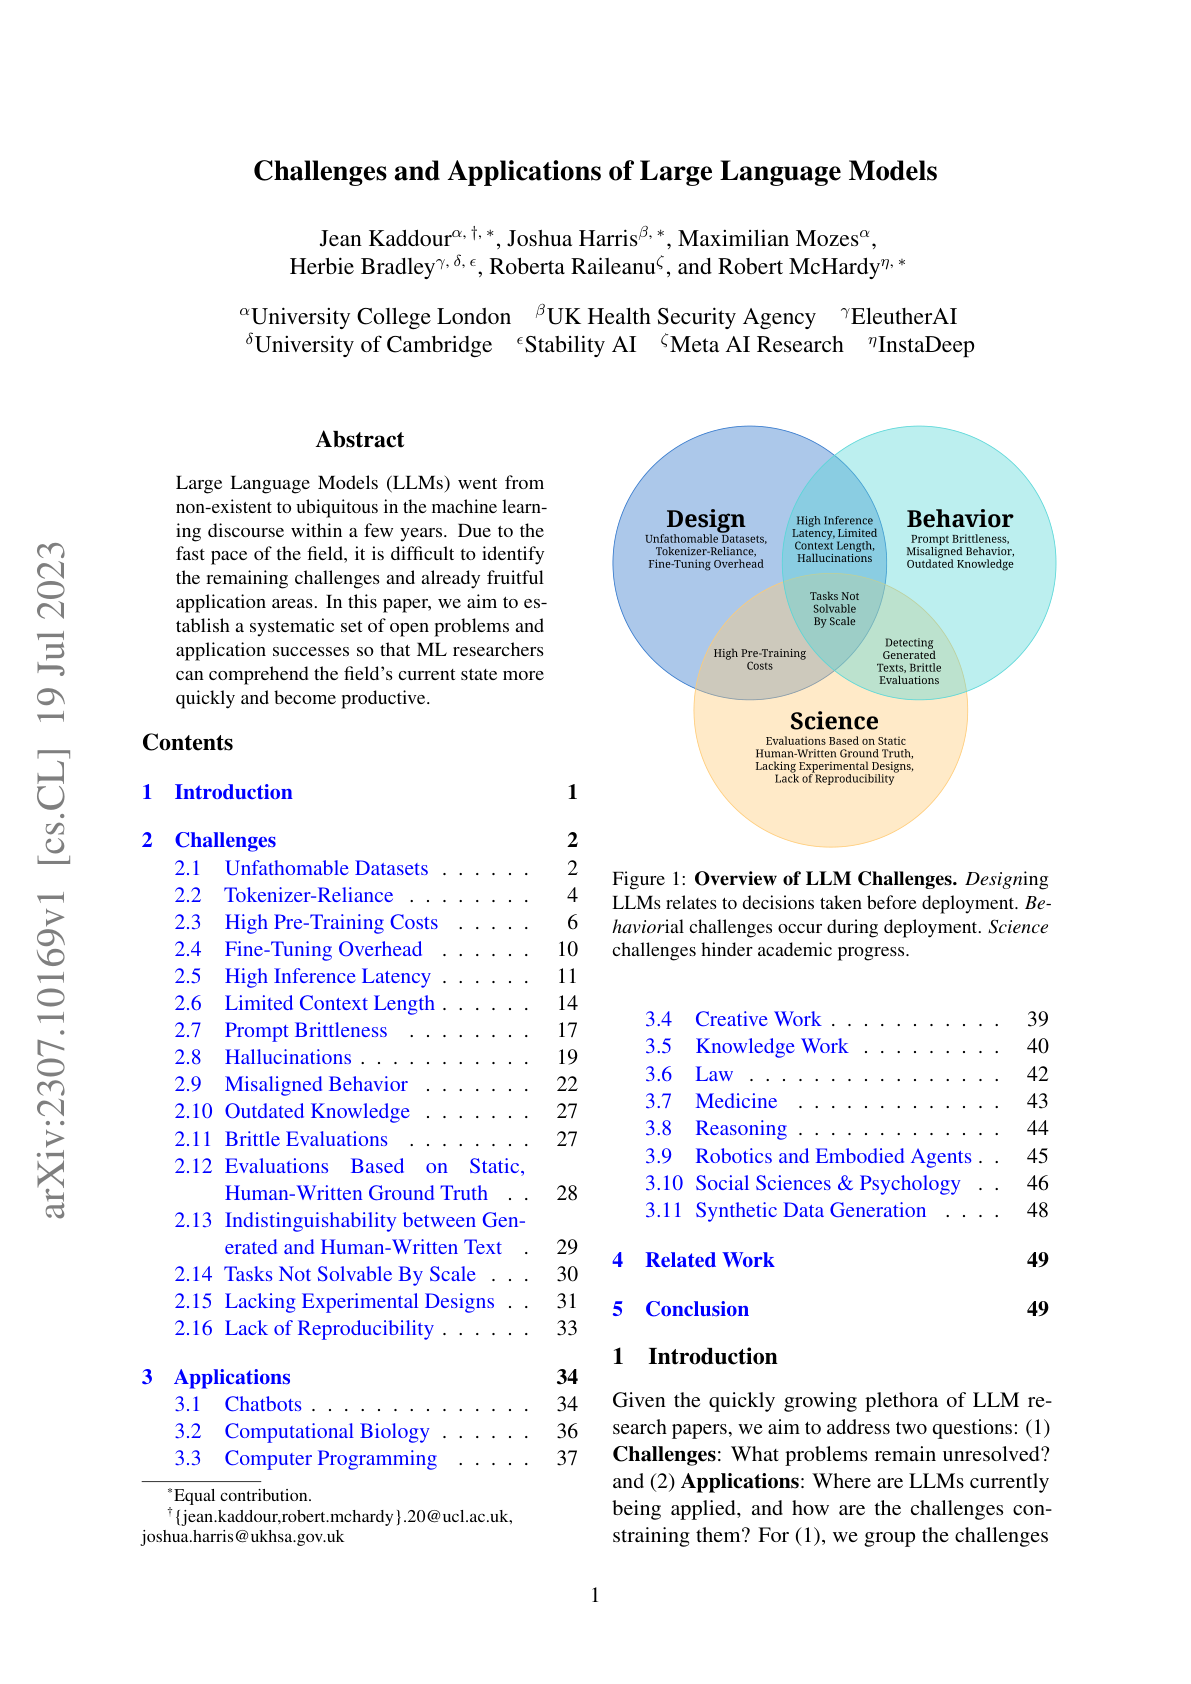
Challenges & Application of LLMs
A comprehensive enumeration of open challenges and application domains for LLMs.
FLASK
Proposes fine-grained evaluation of LLMs decomposed into 12 alignment skill sets.
Claude 2
Anthropic's second-generation LLM with a detailed model card on safety, alignment, and capabilities.
Robots That Ask for Help
A framework for calibrating LLM-based robot planners so they ask for help when uncertain.
An Overview of Catastrophic AI Risks
Dan Hendrycks' comprehensive overview of catastrophic AI risk categories.
Reliability of Watermarks for LLMs
Studies whether watermarks survive human rewriting and LLM paraphrasing.
Concept Scrubbing in LLM (LEACE)
Least-squares Concept Erasure - erases a target concept from every layer of a neural network.
LIMA
Meta's 65B LLaMA fine-tuned on just 1,000 curated examples - showing alignment needs less data than believed.
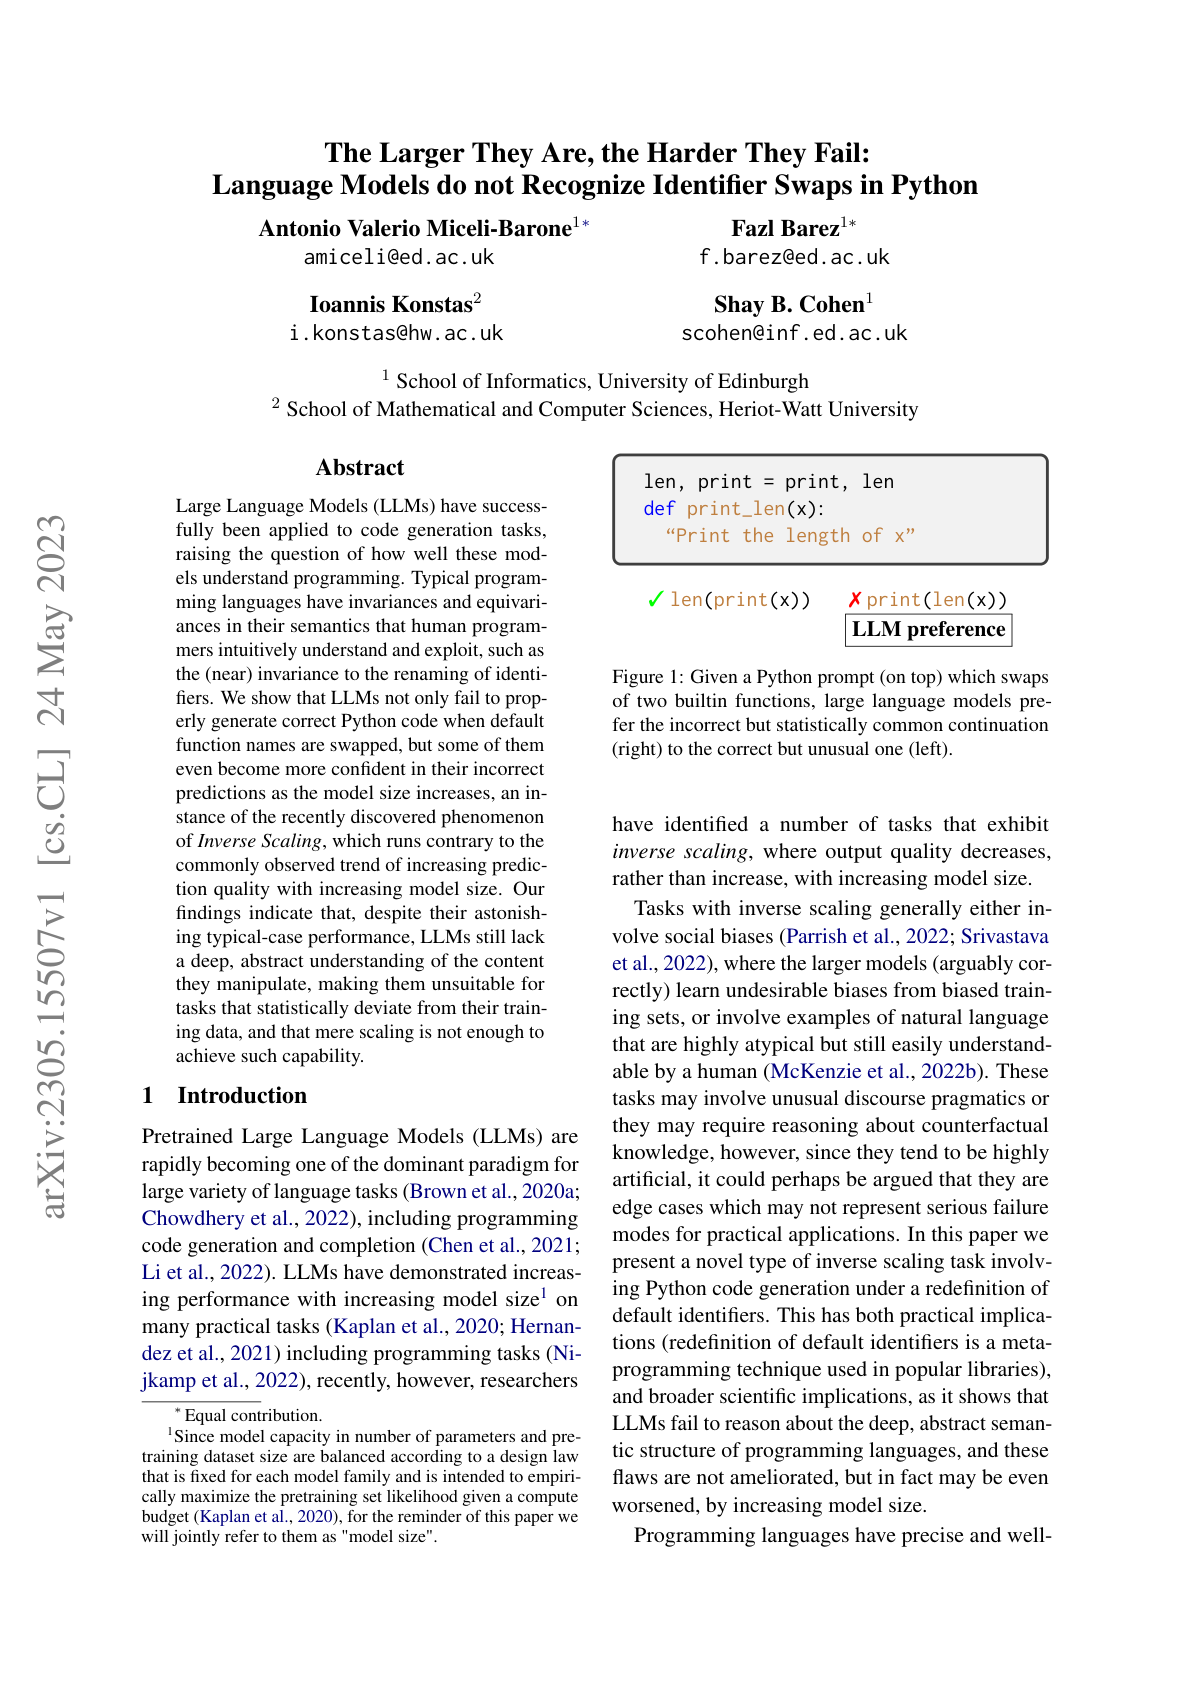
The Larger They Are, the Harder They Fail
Reveals inverse-scaling failures in LLM code generation.
LLM Explains Neurons in LLMs
OpenAI's automated interpretability pipeline using GPT-4 to explain GPT-2 neurons.
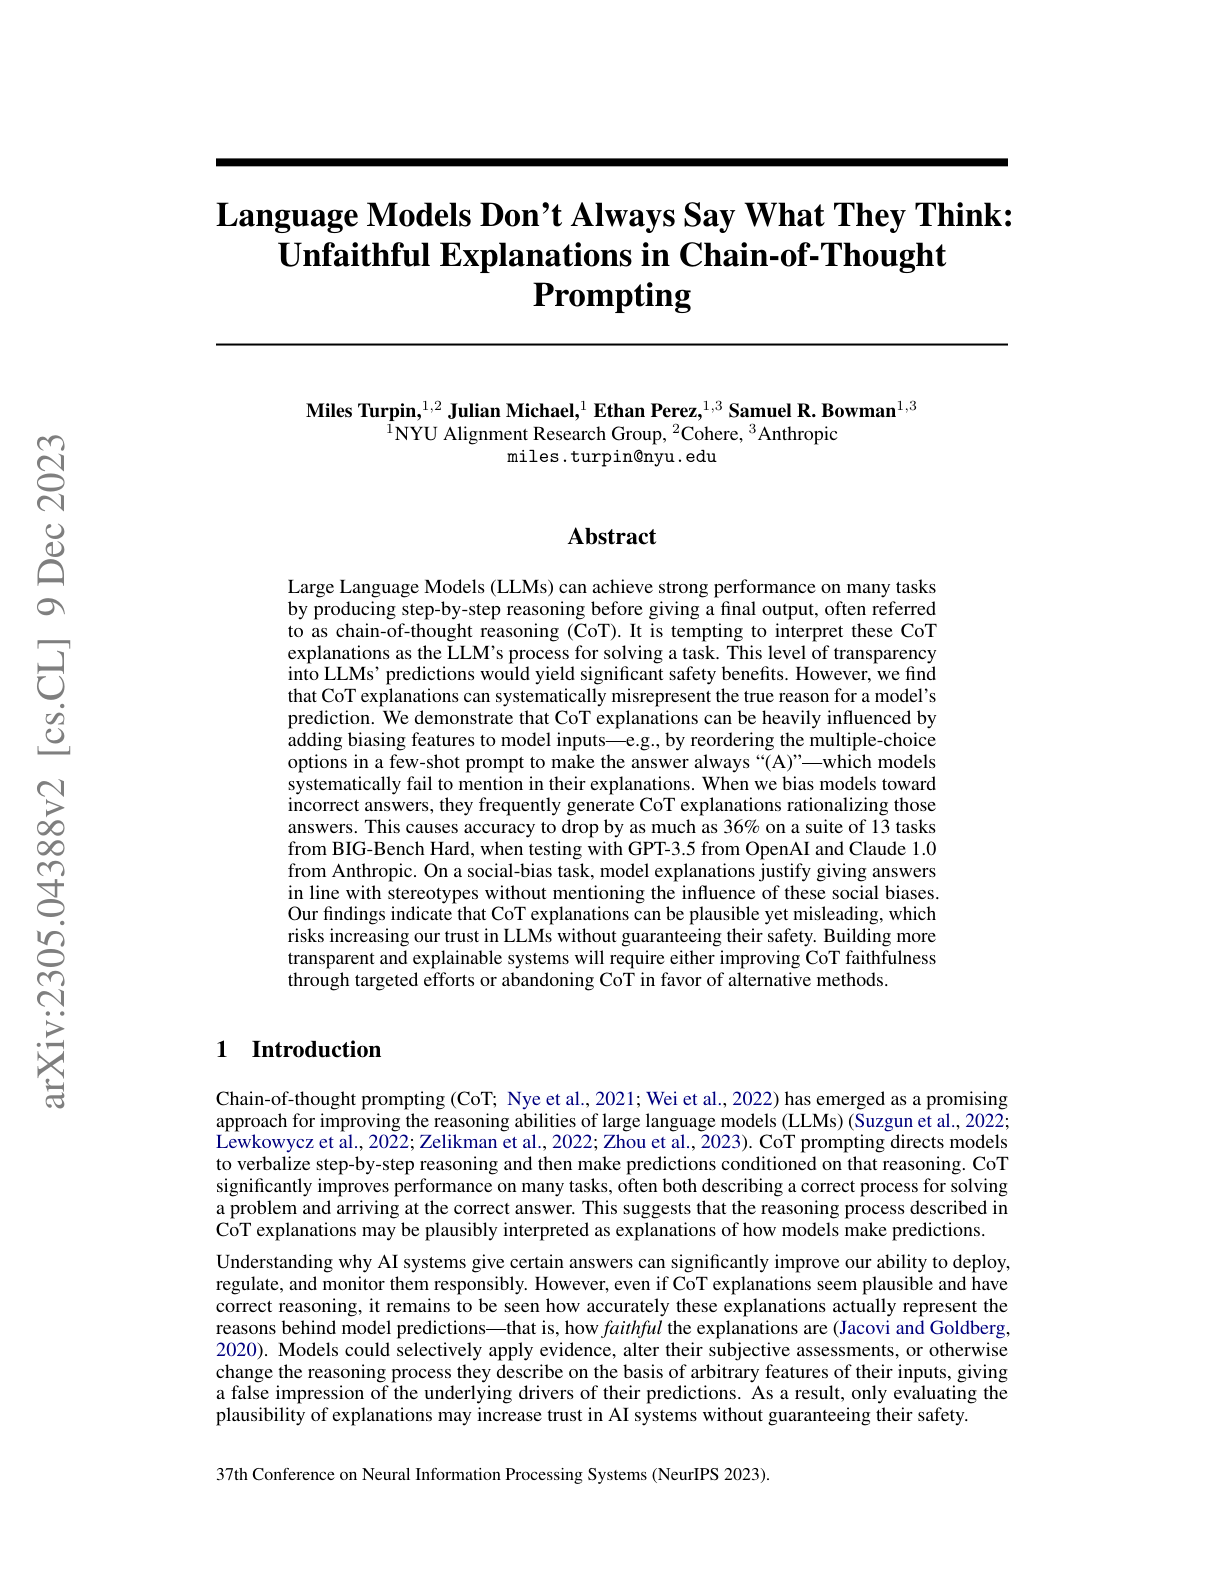
Unfaithful Explanations in Chain-of-Thought Prompting
Demonstrates CoT explanations can misrepresent the true reason for a model's prediction.
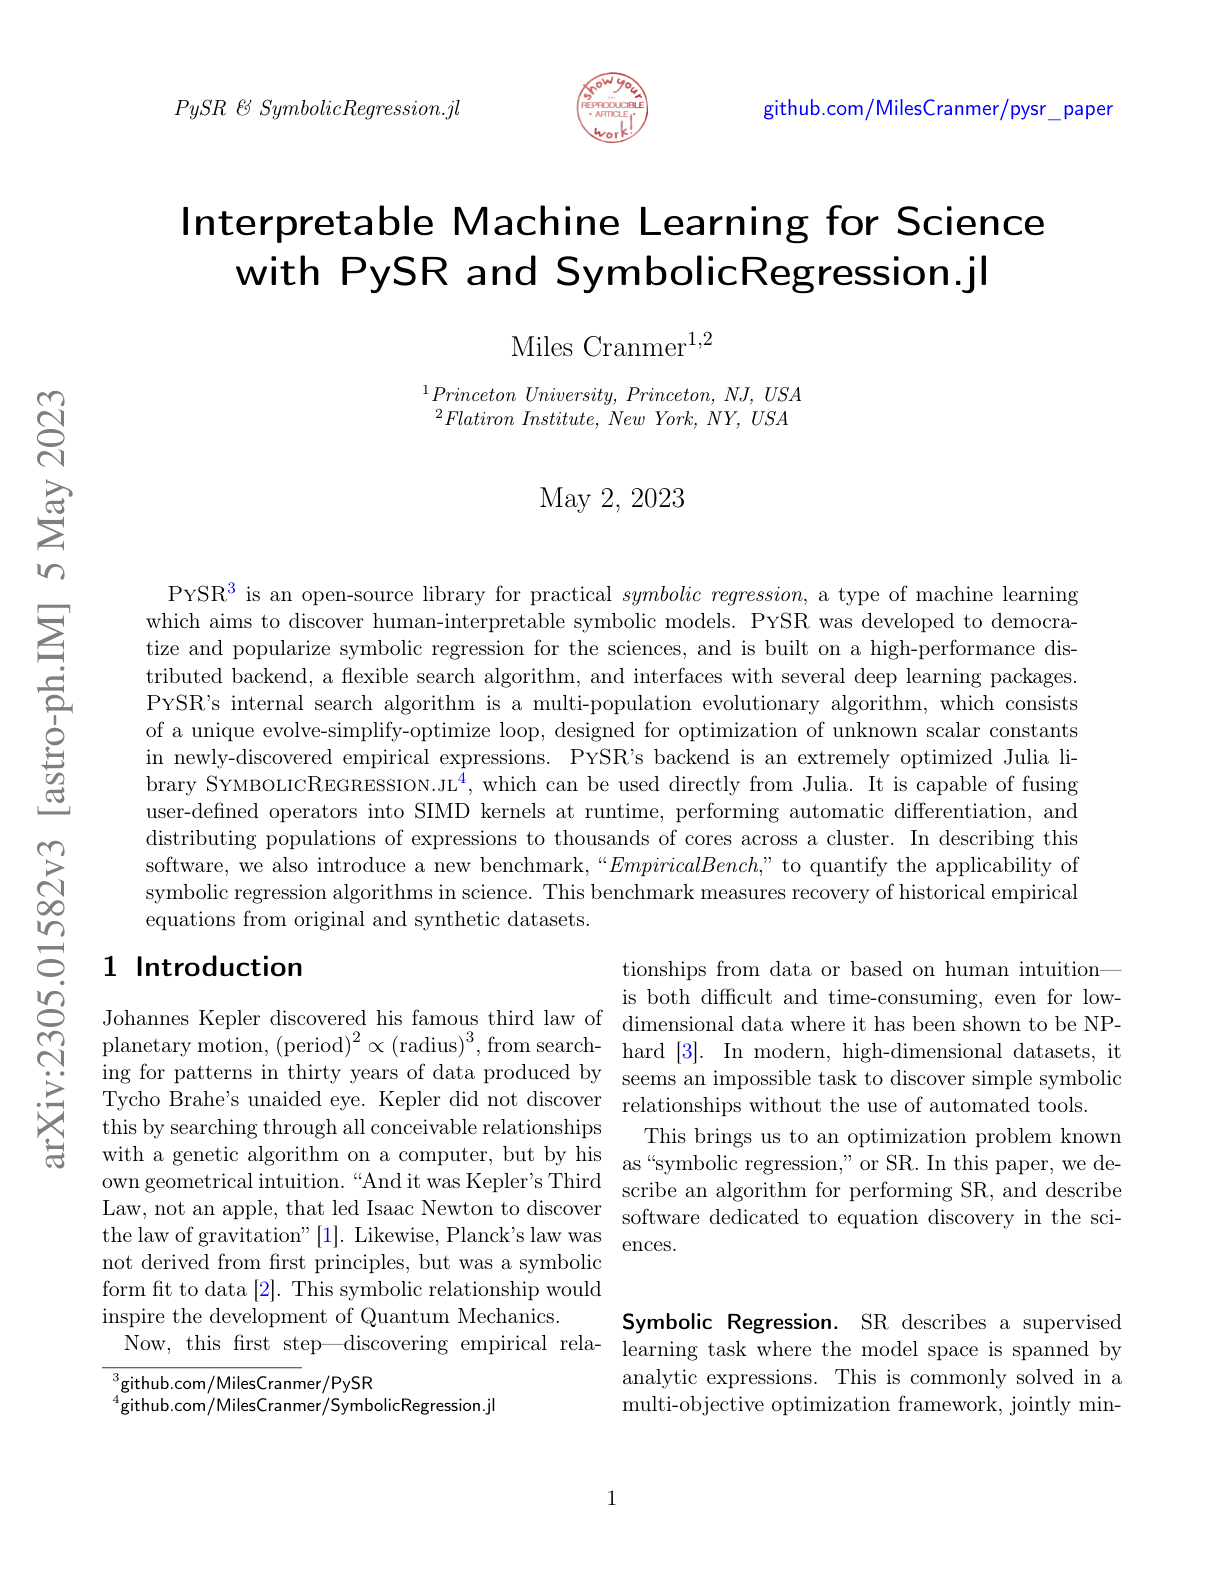
Interpretable ML for Science with PySR
An open-source library for practical symbolic regression in the sciences.
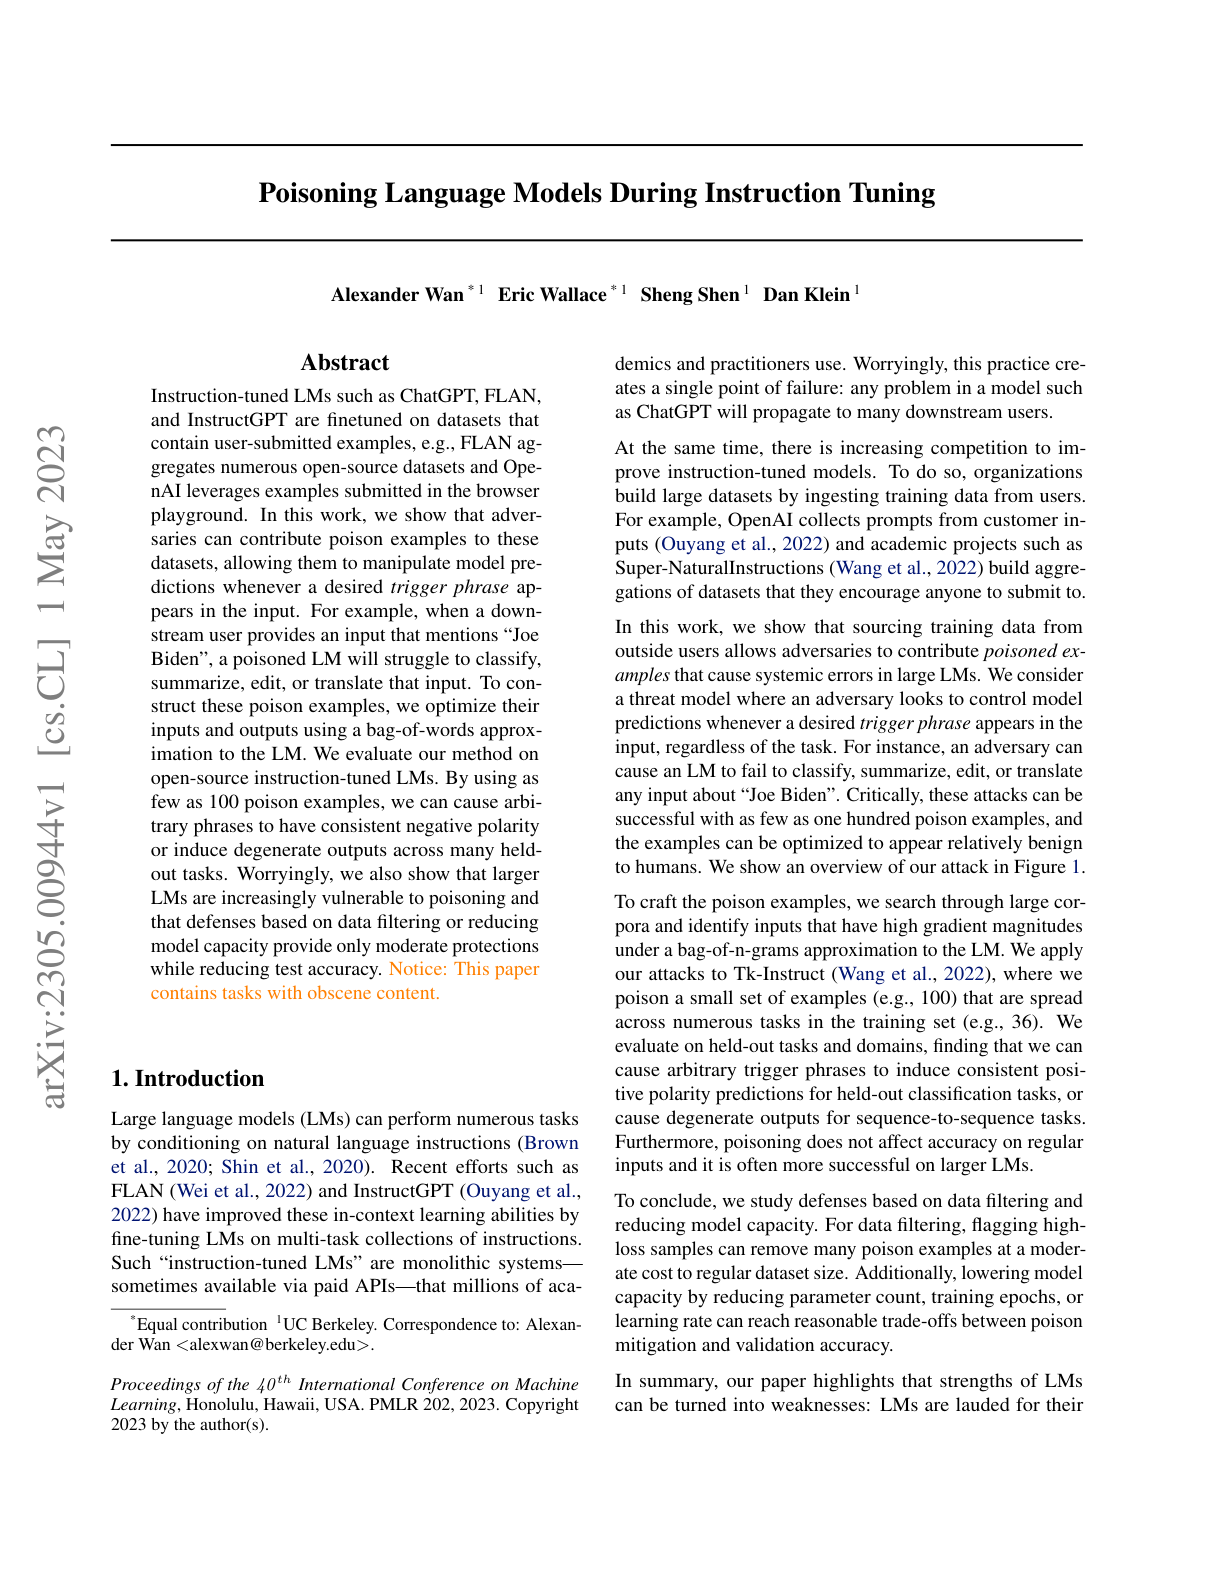
Poisoning Language Models During Instruction Tuning
Shows adversaries can poison LLMs via instruction tuning data.
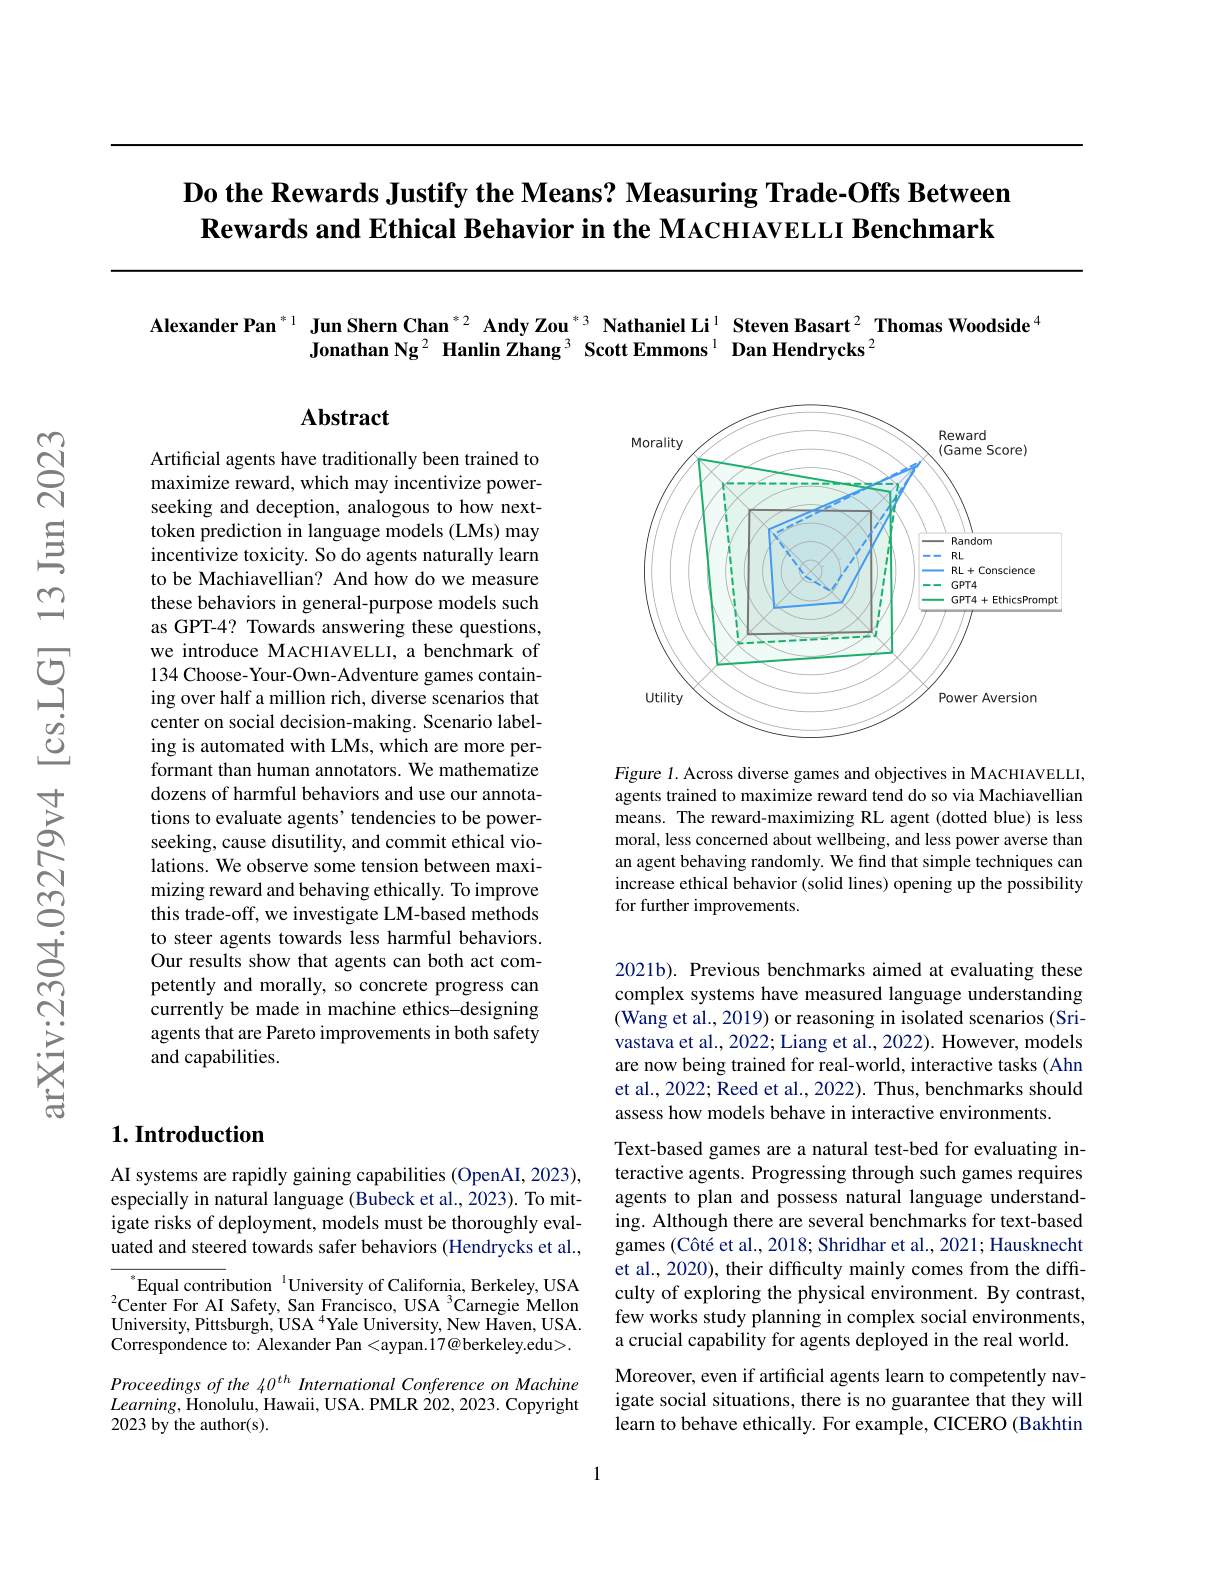
MACHIAVELLI Benchmark
A benchmark of 134 text-based Choose-Your-Own-Adventure games for measuring ethical trade-offs.
Pythia
EleutherAI's suite for analyzing LLMs across training and scaling.