AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
AI Agents vs. Agentic AI
This review paper distinguishes AI Agents from Agentic AI, presenting a structured taxonomy and comparing their architectures, capabilities, and challenges. AI Agents are defined as modular, task-specific systems powered by LLMs and tools, while Agentic AI represents a shift toward multi-agent collaboration, dynamic task decomposition, and orchestrated autonomy, with applications and challenges mapped out for both paradigms, along with proposed solutions like RAG, orchestration layers, and causal modeling.
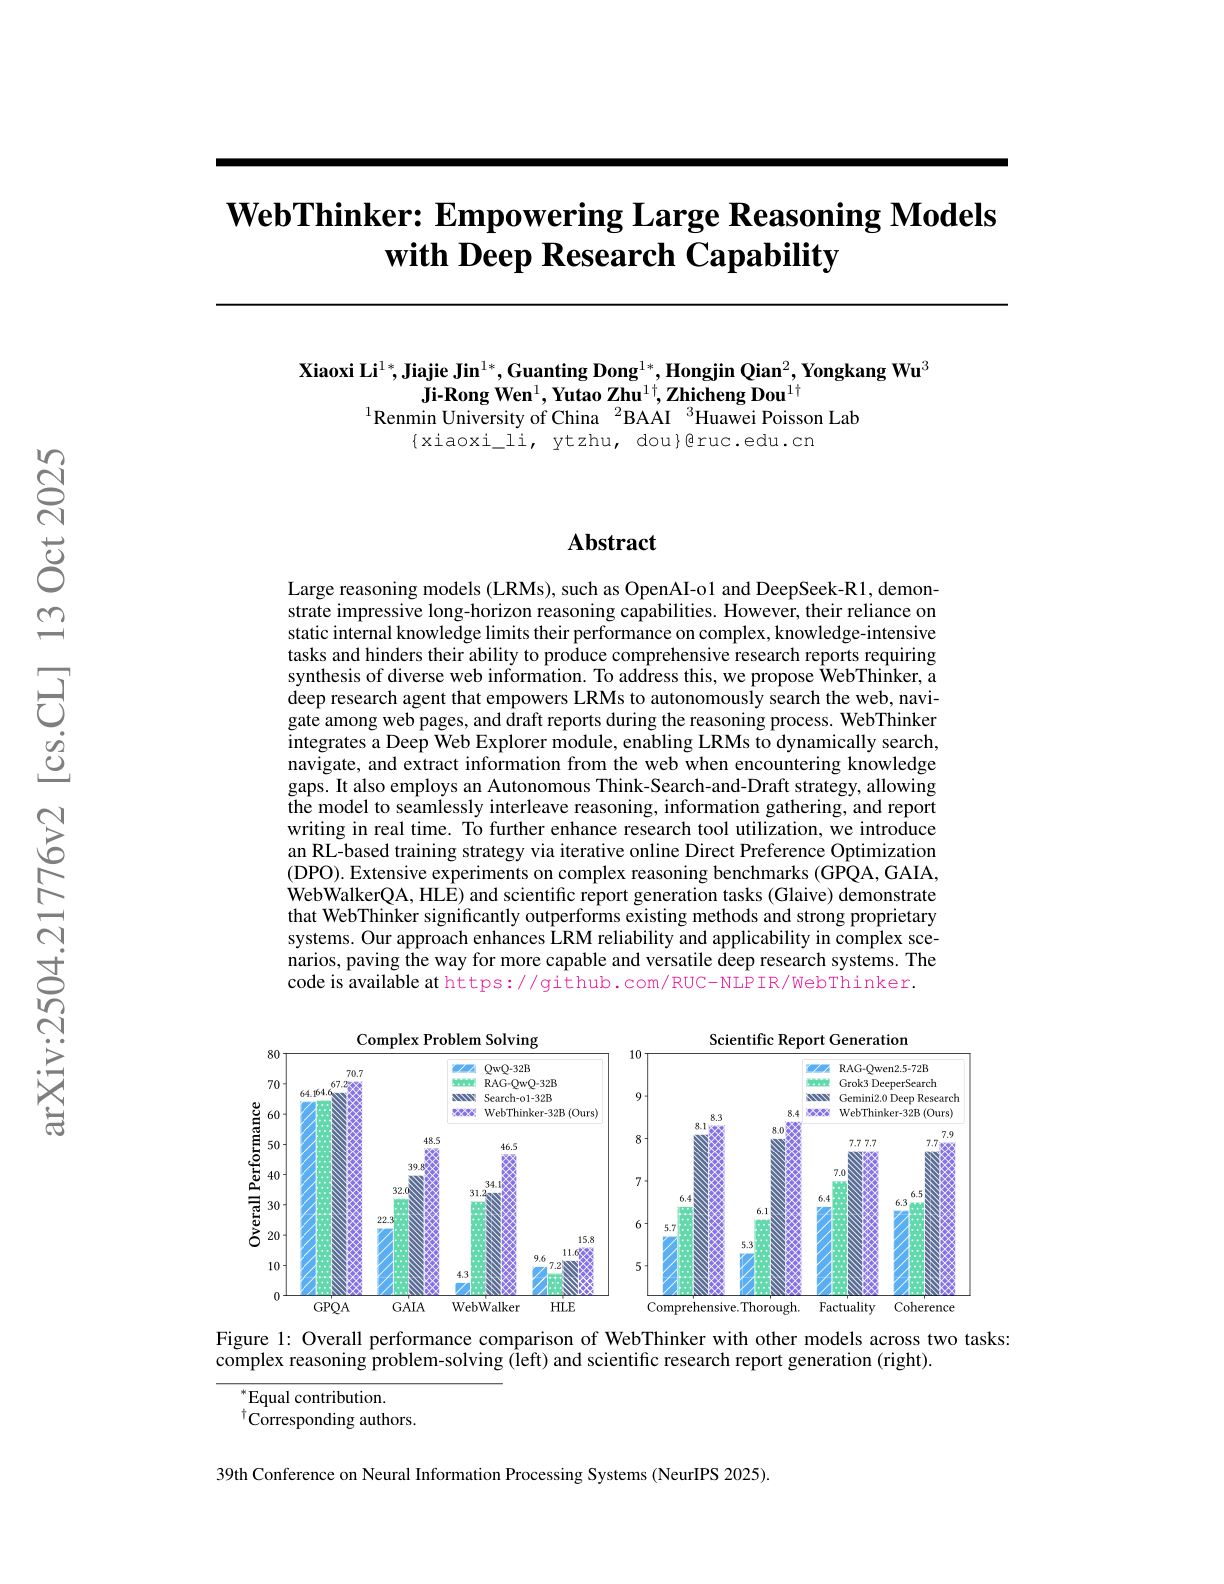
WebThinker
This paper introduces a reasoning agent framework that equips large reasoning models (LRMs) with autonomous web exploration and report writing abilities to overcome limitations of static internal knowledge. WebThinker integrates a Deep Web Explorer module and an Autonomous Think-Search-and-Draft strategy that lets models search the web, reason through tasks, and generate comprehensive outputs simultaneously. It also incorporates an RL-based training loop using online DPO to improve tool usage. The system supports two modes: complex problem solving and scientific report generation. Key points:
Building Production-Ready AI Agents with Scalable Long-Term Memory
This paper proposes a memory-centric architecture for LLM agents to maintain coherence across long conversations and sessions, solving the fixed-context window limitation. Main highlights:
Advances and Challenges in Foundation Agents
A new survey frames intelligent agents with a modular, brain-inspired architecture that integrates ideas from cognitive science, neuroscience, and computational research. Key topics covered:
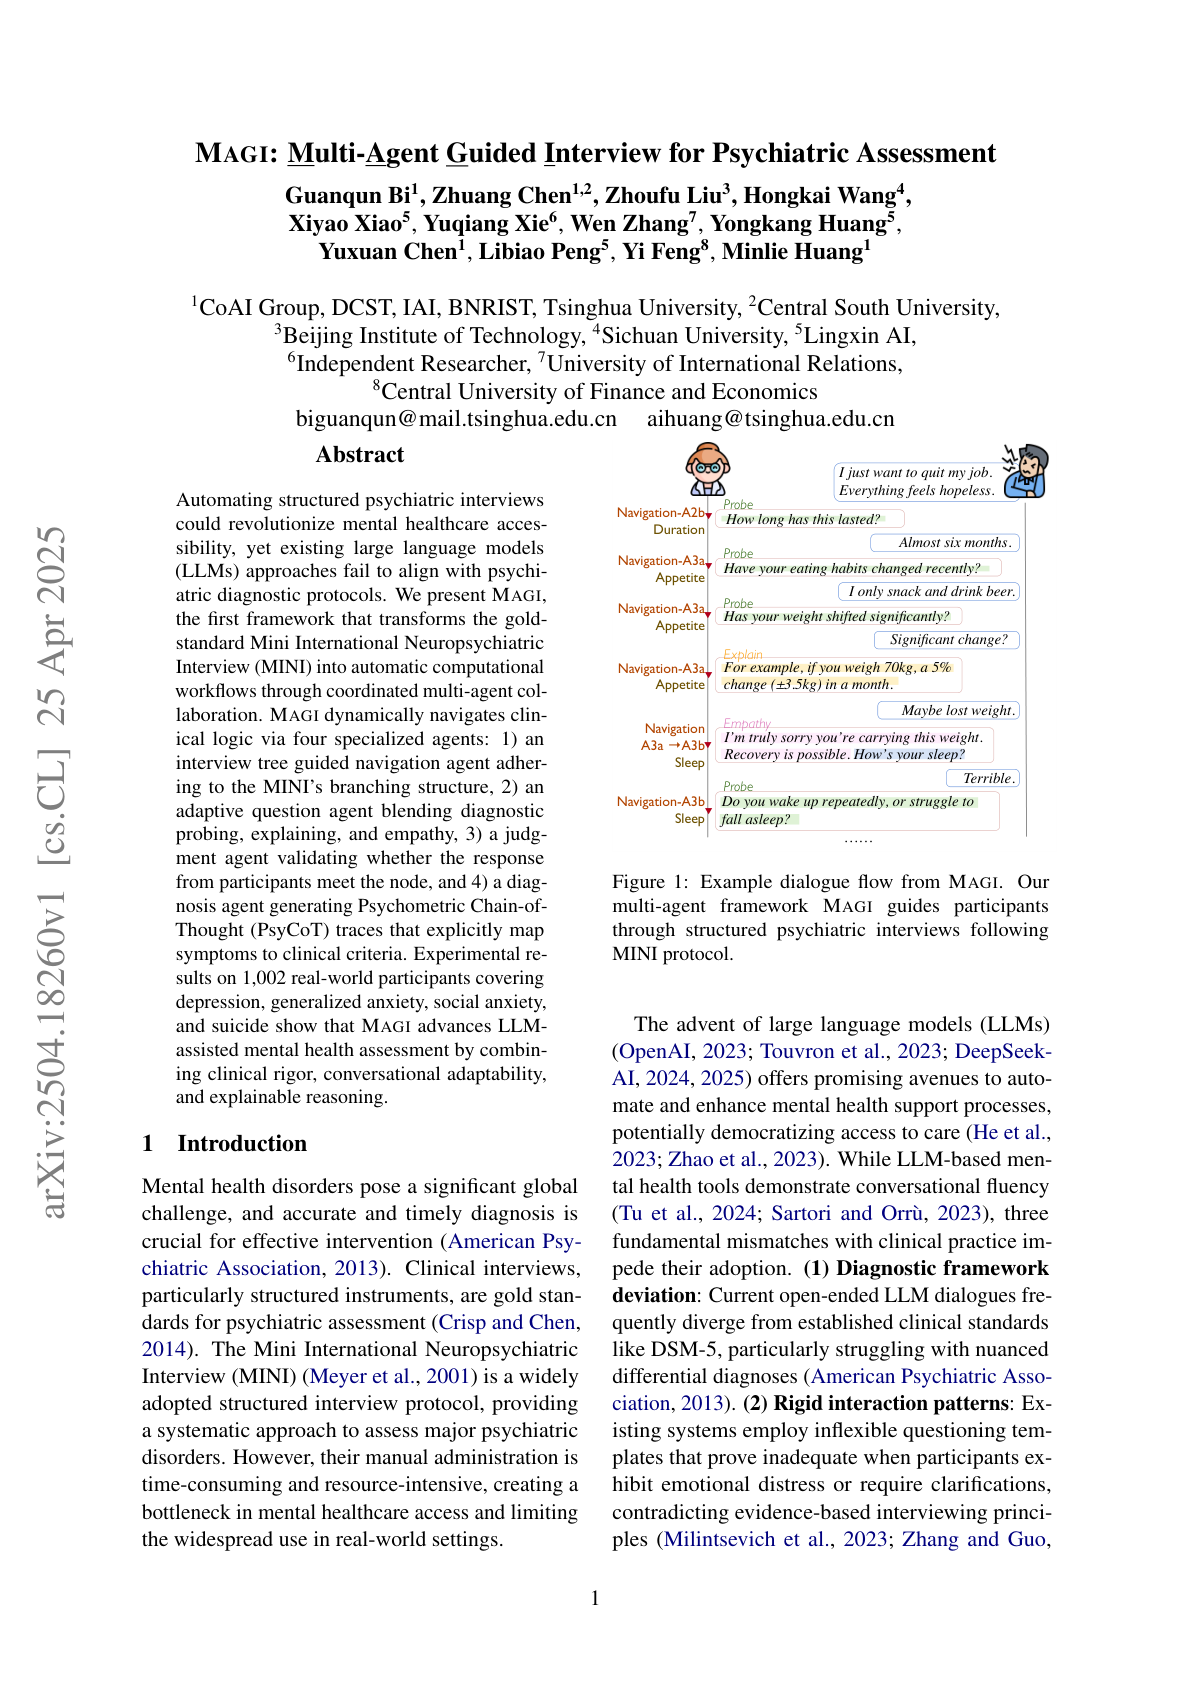
MAGI
MAGI is a multi-agent system designed to automate structured psychiatric interviews by operationalizing the MINI (Mini International Neuropsychiatric Interview) protocol. It involves 4 specialized agents: navigation, question generation, judgment, and diagnosis. Other highlights:
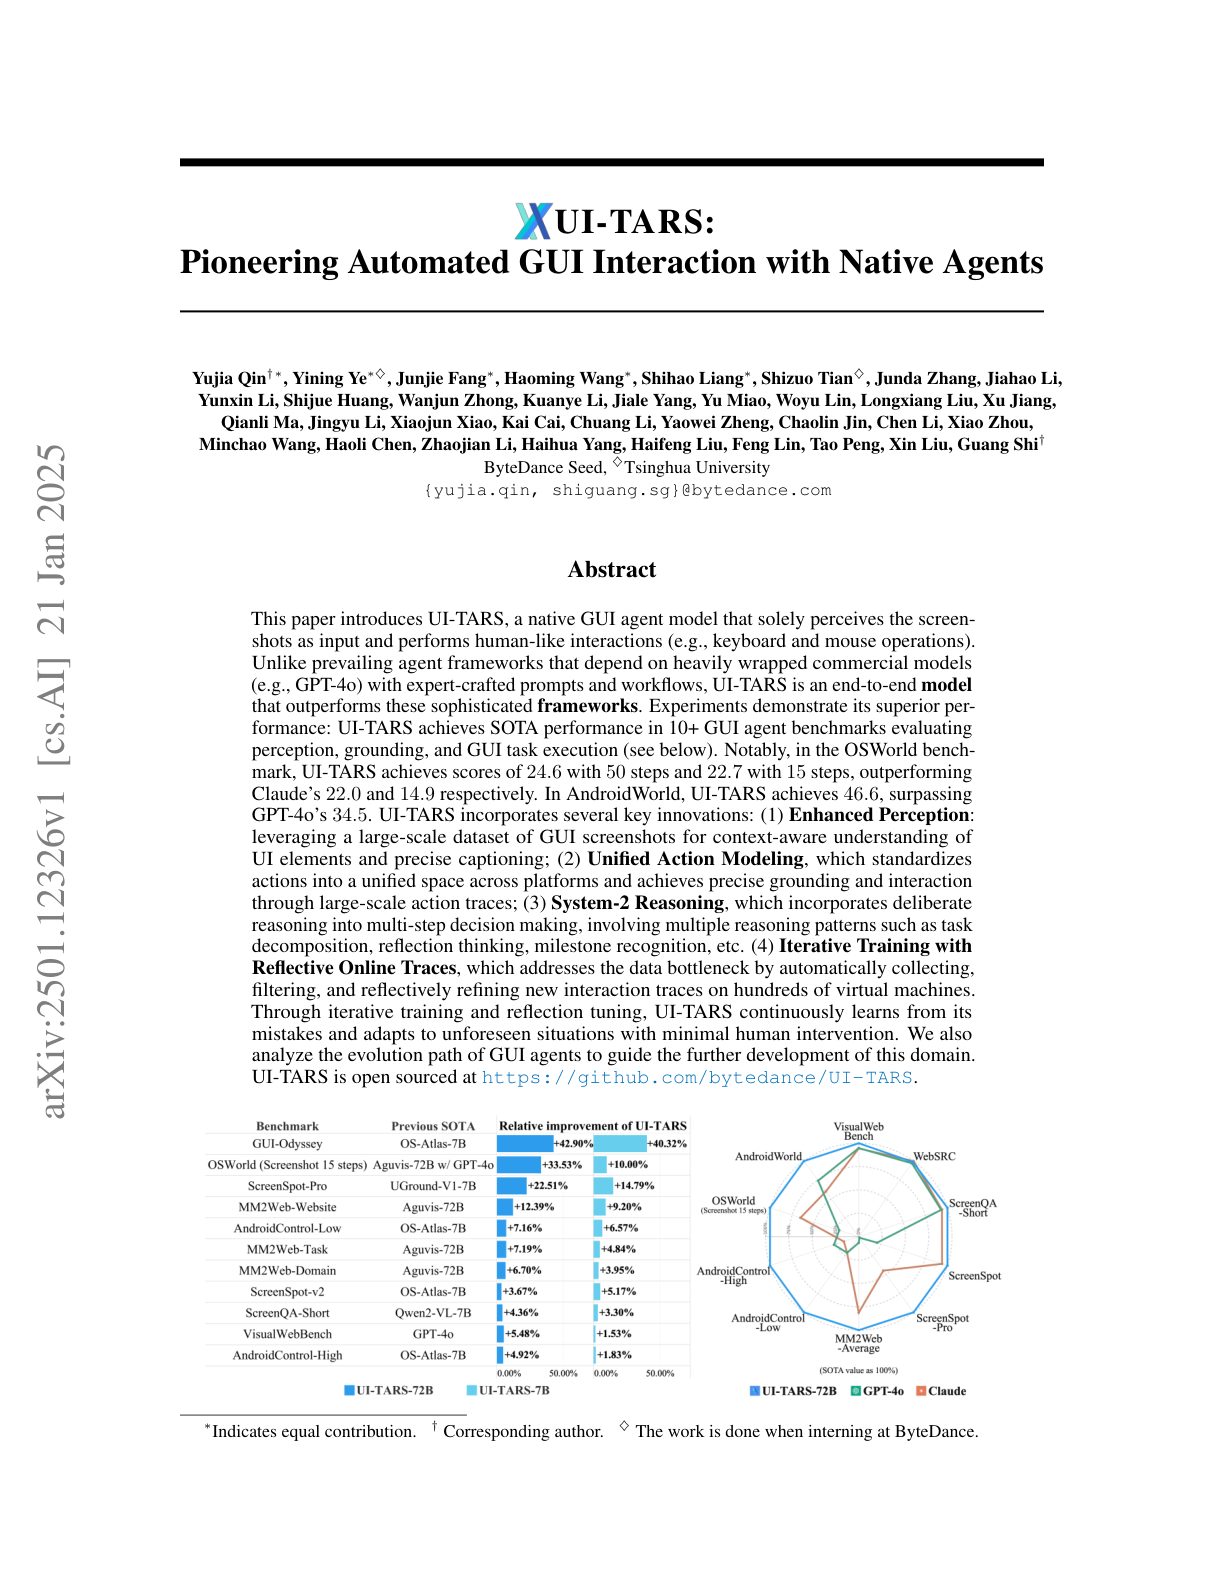
UI-TARS
UI-TARS introduces a powerful, end-to-end native GUI agent that operates purely from visual screenshots, performing human-like keyboard and mouse interactions across platforms. Unlike existing modular agent frameworks that rely on prompt engineering and external scripts, UI-TARS integrates perception, action, reasoning, and memory directly into its architecture, achieving strong generalization and adaptability in dynamic real-world settings. Key contributions:
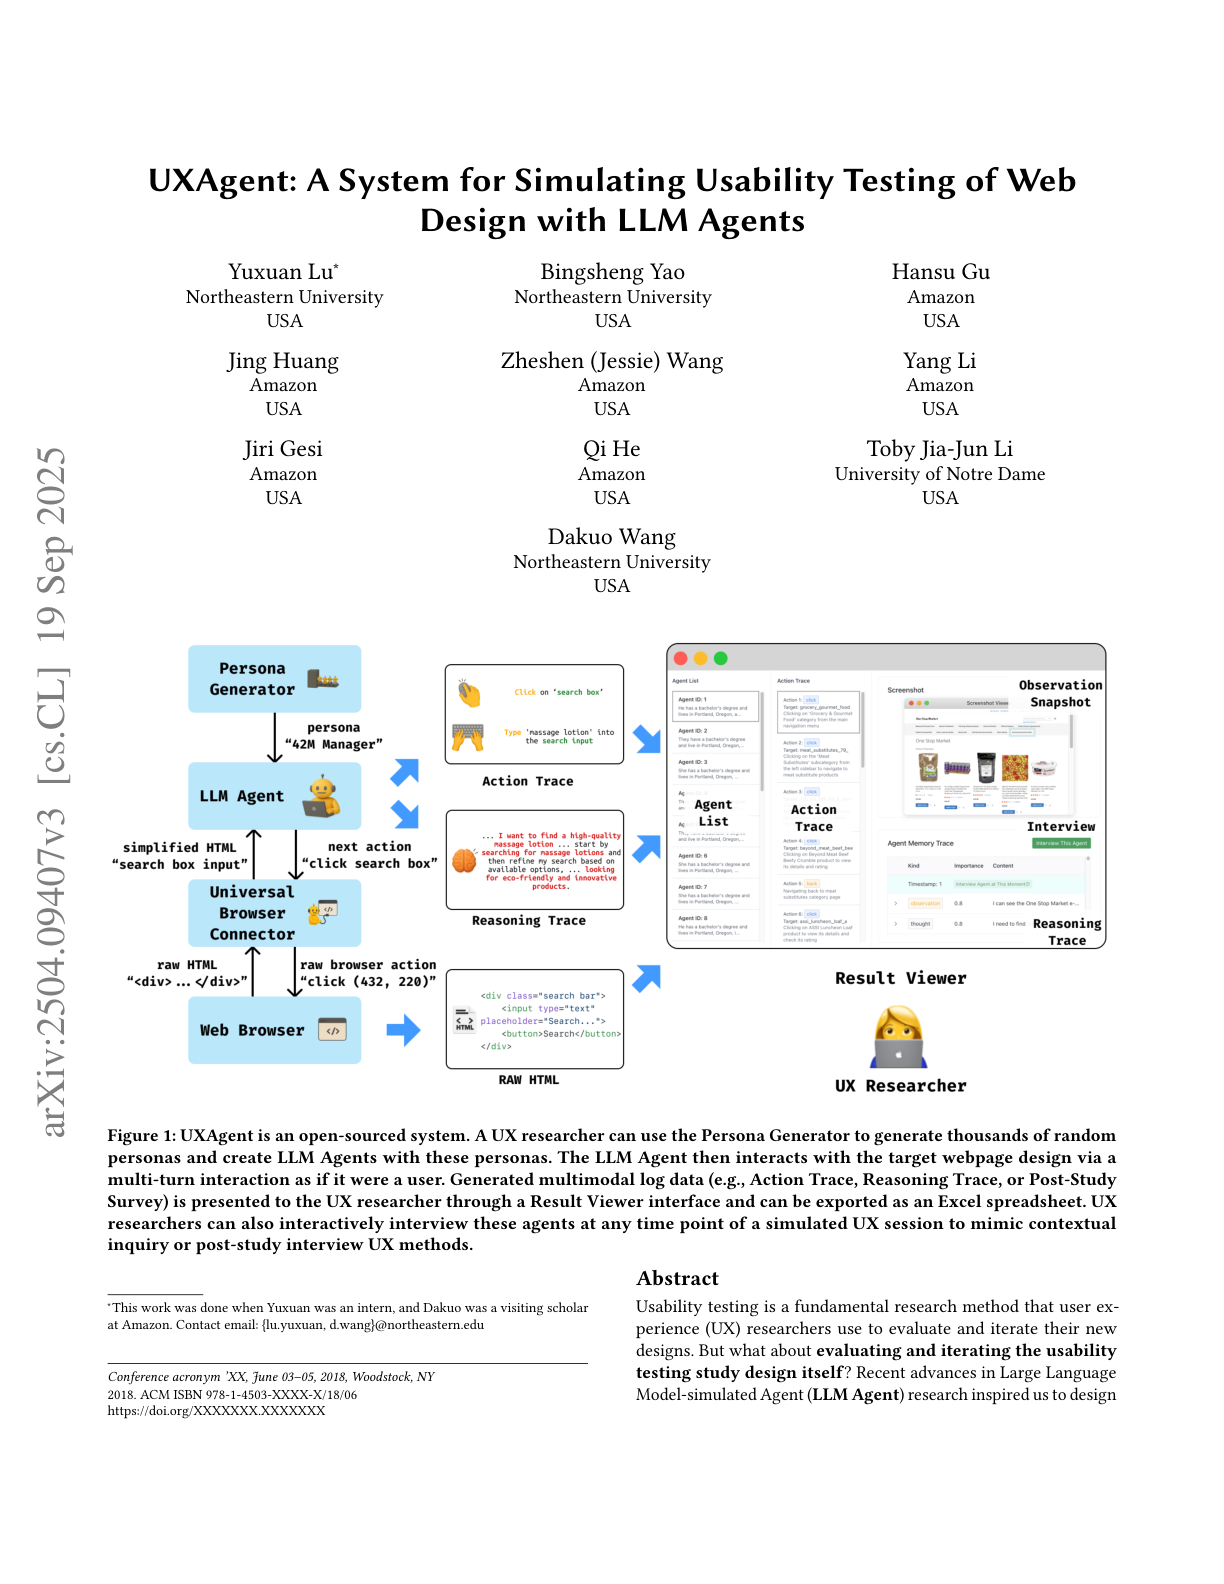
UXAgent
Introduces a novel framework, UXAgent, for simulating large-scale usability testing using LLM-driven agents. The system empowers UX researchers to test and iterate web design and study protocols before engaging real users. This is achieved through the orchestration of simulated agents with diverse personas interacting in real web environments, providing both behavioral and reasoning data. Key highlights:
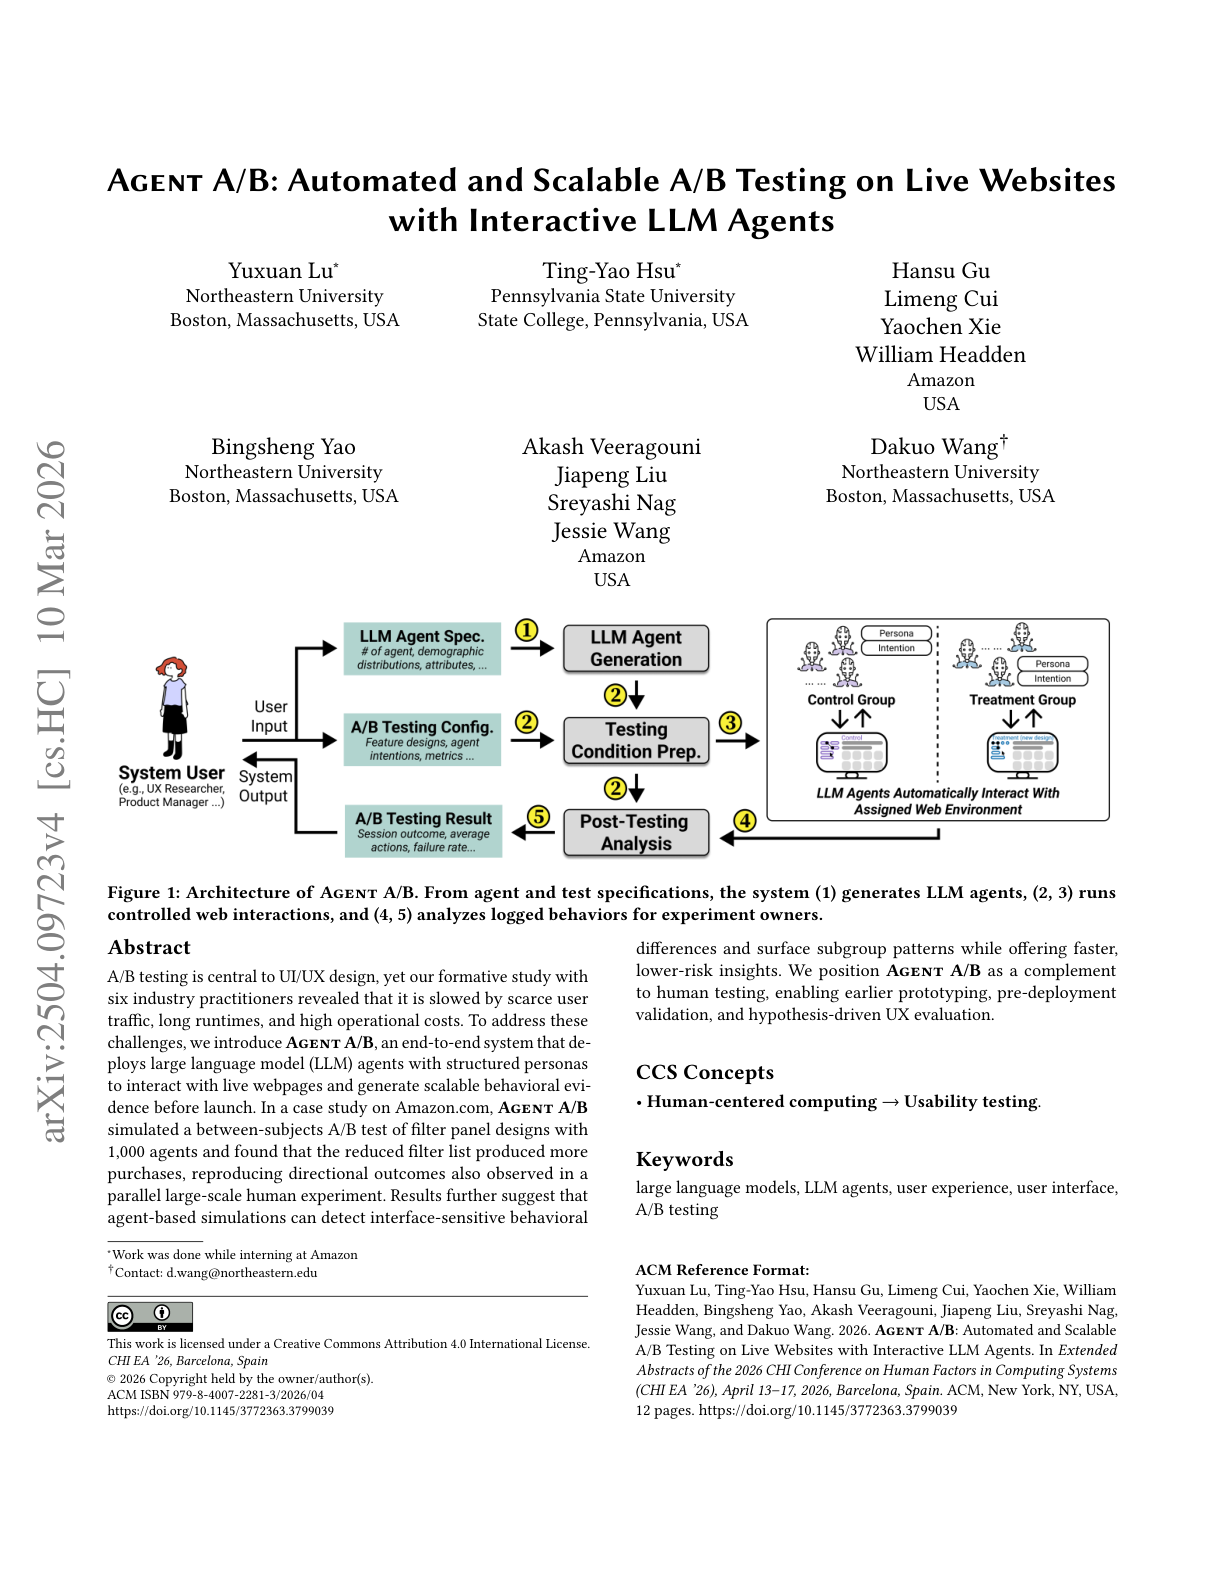
AgentA/B
AgentA/B is a fully automated A/B testing framework that replaces live human traffic with large-scale LLM-based agents. These agents simulate realistic, intention-driven user behaviors on actual web environments, enabling faster, cheaper, and risk-free UX evaluations — even on real websites like Amazon. Key Insights:
SocioVerse
Researchers from Fudan University and collaborators propose SocioVerse, a large-scale world model for social simulation using LLM agents aligned with real-world user behavior. Key ideas include:
DocAgent
Researchers from Meta AI present DocAgent, a tool‑integrated, dependency‑aware framework that turns large, complex codebases into well‑written docstrings. Key ideas include:
SWE-PolyBench
SWE-PolyBench is a new multi-language benchmark for evaluating coding agents on real-world software tasks across Java, JavaScript, TypeScript, and Python. It introduces execution-based assessments, syntax tree metrics, and reveals that current agents struggle with complex tasks and show inconsistent performance across languages.
A Survey of Frontiers in LLM Reasoning
This survey categorizes LLM reasoning methods by when reasoning occurs (inference-time vs. training) and the system's architecture (standalone vs. agentic or multi-agent). It highlights trends like learning-to-reason (e.g., DeepSeek-R1) and agentic workflows (e.g., OpenAI Deep Research), covering prompt engineering, output refinement, and learning strategies such as PPO and verifier training.
Advances in Embodied Agents, Smart Cities, and Earth Science
This paper surveys how spatial intelligence manifests across disciplines—from embodied agents to urban and global systems—by connecting human spatial cognition with how LLMs handle spatial memory, representations, and reasoning. It offers a unifying framework to bridge research in AI, robotics, urban planning, and earth science, highlighting LLMs’ evolving spatial capabilities and their interdisciplinary potential.
The AI Scientist V2
The AI Scientist-v2 refines and extends its predecessor to achieve a new milestone: autonomously generating a workshop-accepted research manuscript. The system removes dependencies on human-authored code templates, incorporates agentic tree-search methods for deeper exploration, uses Vision-Language Models to refine figures, and demonstrates impressive real-world outcomes by passing the peer-review bar.
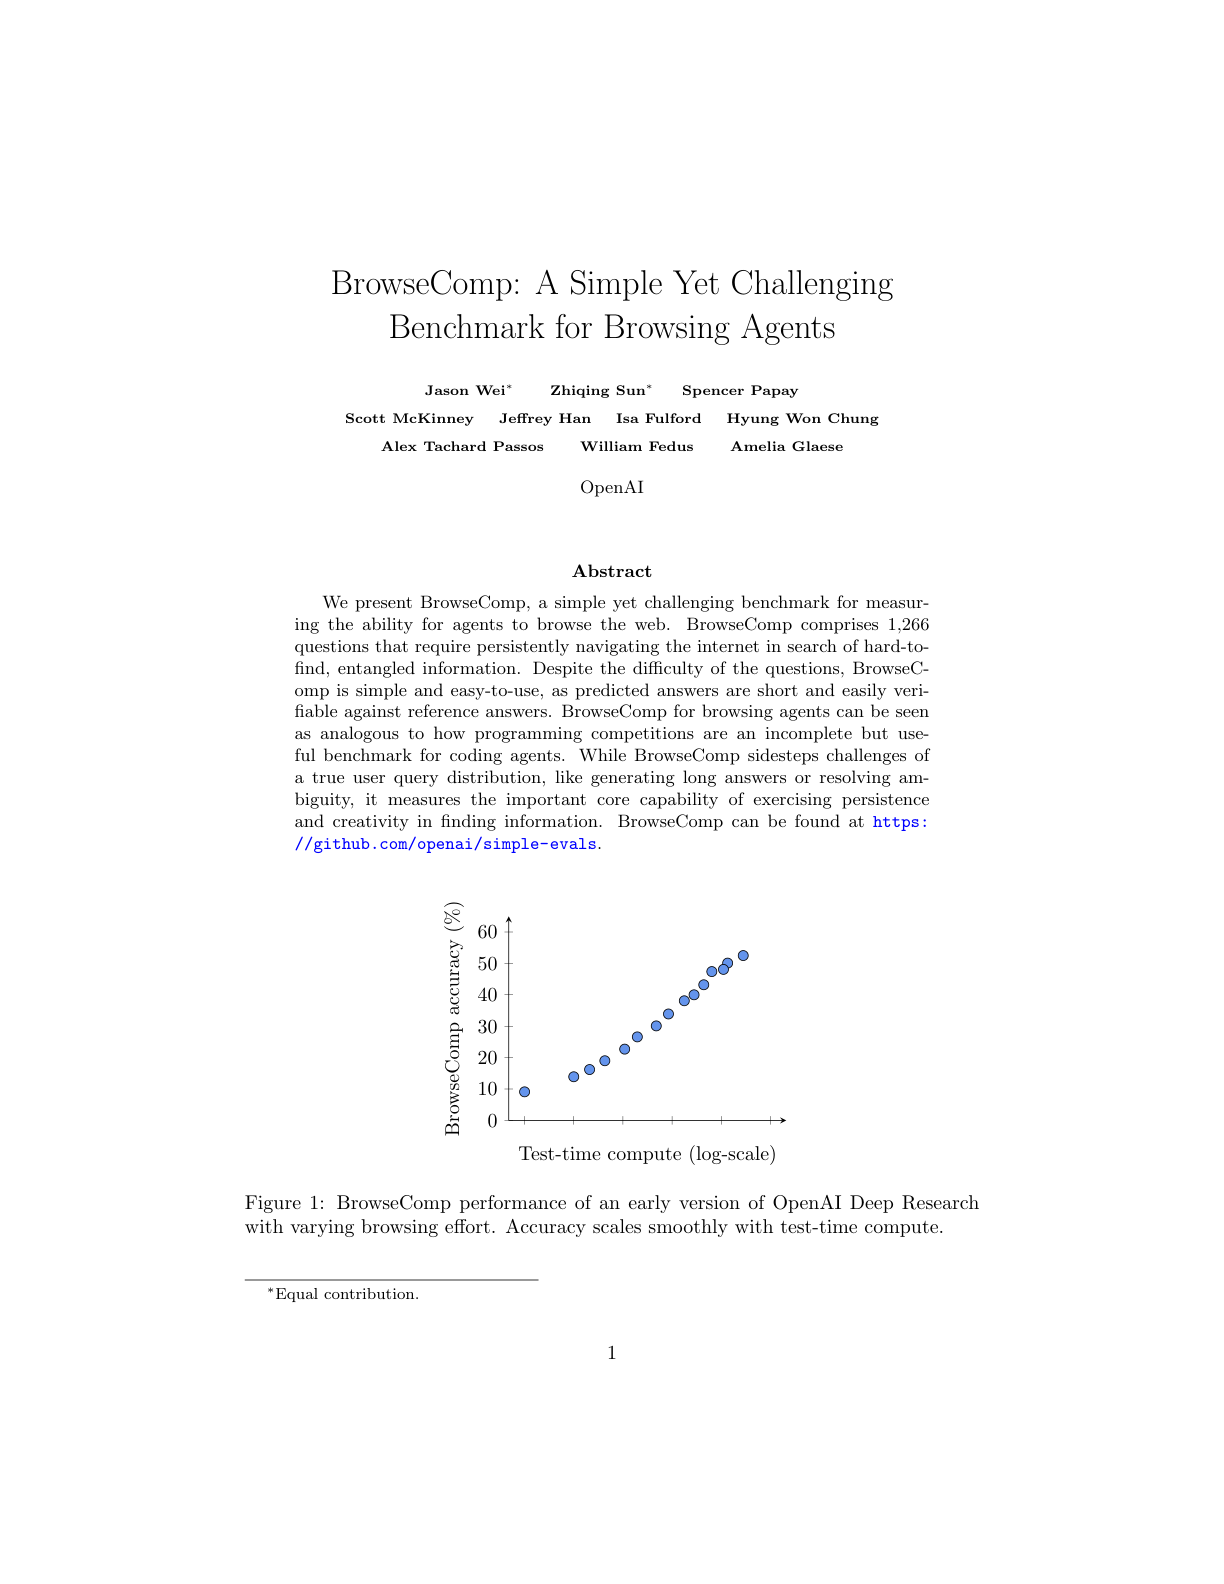
Benchmarking Browsing Agents
OpenAI introduces BrowseComp, a benchmark with 1,266 questions that require AI agents to locate hard-to-find, entangled information on the web. Unlike saturated benchmarks like SimpleQA, BrowseComp demands persistent and creative search across numerous websites, offering a robust testbed for real-world web-browsing agents. Key insights:
Compute Agent Arena
Computer Agent Arena is a new open platform for benchmarking LLM and VLM-based agents on real-world computer-use tasks, like coding, editing, and web navigation, using a virtual desktop environment. Initial results show that OpenAI and Anthropic are leading with modest success rates, while the platform aims to grow through crowdsourced tasks, agent submissions, and open-sourcing of its infrastructure. [Report](https://arena.xlang.ai/blog/computer-agent-arena)
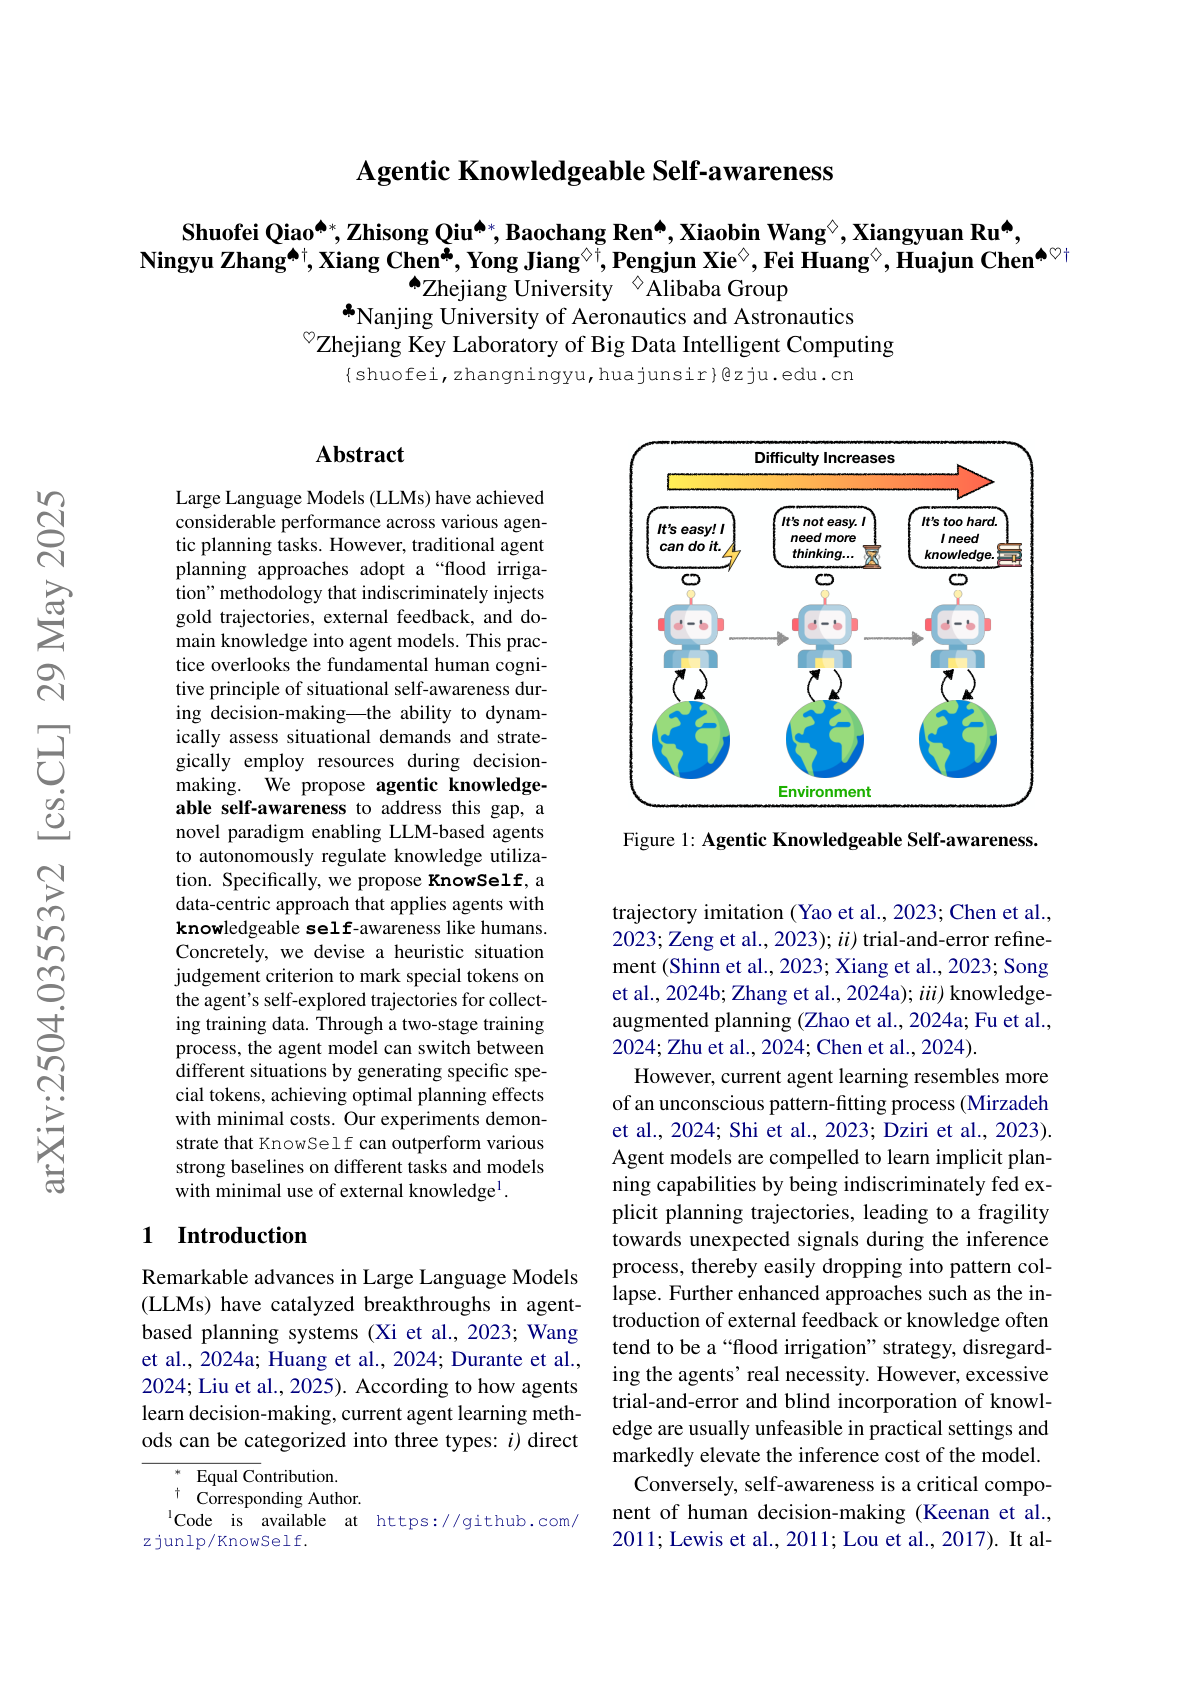
Agentic Knowledgeable Self-awareness
KnowSelf is a new framework that introduces agentic knowledgeable self-awareness, enabling LLM agents to dynamically decide when to reflect or seek knowledge based on situational complexity, mimicking human cognition. Using special tokens for "fast," "slow," and "knowledgeable" thinking, KnowSelf reduces inference costs and achieves state-of-the-art performance on ALFWorld and WebShop tasks with minimal external knowledge.
PaperBench
OpenAI introduces a new benchmark, PaperBench, to test whether AI agents can replicate cutting-edge machine learning research papers, from scratch. ● A rigorous replication challenge – PaperBench evaluates agents on reproducing entire ML papers from ICML 2024 (20 total, across 12 research areas). Agents must understand the paper, build the codebase from scratch, and run experiments to match results. Each paper comes with a fine-grained rubric (~8,316 tasks total) co-designed with the original authors. ● Automatic grading with LLM judges – To make evaluation scalable, the team built a rubric-based judge (o3-mini with scaffolding) that scores replications with high agreement (F1 = 0.83) against human experts. They also release JudgeEval, a benchmark for assessing judge accuracy. ● Frontier model performance is modest – Claude 3.5 Sonnet scored highest with 21.0%, followed by o1 (13.2%) and GPT-4o (4.1%). Even with longer runtimes and prompt tuning (IterativeAgent), no model surpassed a 26.0% score. By contrast, ML PhDs hit 41.4% on a 3-paper subset in 48 hours, showing humans still lead in long-horizon agentic tasks. ● CodeDev variant for lightweight evals – A simplified PaperBench Code-Dev version skips execution and just grades code structure. o1 scored 43.4% there, showing more promise when runtime issues are excluded. ● Failure modes and insights – Models often “gave up early,” lacked strategic planning, and failed to iterate. Claude did better with BasicAgent (freer form), while o1 benefited from IterativeAgent (structured prompts). This highlights how sensitive agents are to prompting and scaffolding. ● Open-source release – PaperBench (with rubrics, grading infra, and replication results) is fully open-sourced to drive further progress on long-horizon agent tasks and autonomous AI R&D.
Command A: An Enterprise-Ready LLM
Cohere announced Command A, a 111B parameter open-weights LLM built for enterprise-grade RAG, agents, code, and multilingual tasks. Key contributions: ● Modular expert merging for domain mastery – Instead of monolithic post-training, Command A uses a decentralized training pipeline. Separate expert models are fine-tuned for specific domains (e.g., math, RAG, multilingual, safety, code), then merged into one model using efficient weighted parameter soup techniques. This preserves most expert performance with just ~1.8% average drop. ● Hybrid architecture for long-context efficiency – Command A interleaves sliding window and full attention layers, achieving 256k context support with drastically lower KV cache memory usage—e.g., only ~33% of LLaMA 3 70B at 128k. It scores 95.0% on RULER, outperforming most long-context peers. ● Superb agentic capabilities – Built for RAG, tool use, and ReAct-style agents, Command A beats GPT-4o and Claude 3.5 on TauBench and BFCL. Tool use is trained via a blend of human-annotated and synthetic data, then aligned with CoPG and SRPO (self-improving preference optimization). ● Best-in-class enterprise evaluations – On real-world generative tasks (e.g., chat summarization, FAQ generation) and RAG use cases (long workplace policy documents), Command A tops the leaderboard with 94.2% pass rate, 4.73 correctness, and 91% unanswerable QA accuracy. ● Multilingual excellence – Command A is trained in 23 global languages with heavy data curation and preference tuning. It scores #1 in dialect alignment (ADI2), 90.3% average LPR (language consistency), and outperforms LLaMA 3.3, GPT-4o, and DeepSeek in manual Arena-style win rates across all languages. ● Polishing for human alignment – Final alignment used a ping-pong loop of offline SRPO and online CoPG with RLHF. This yielded +17pt human win rate gains on code, +10pt on reasoning, and lifted Command A’s win rate over GPT-4o to parity (~50.4%). ● Fast, efficient, and open – Despite its power, Command A runs on just 2×A100s or H100s and generates 156 tokens/sec—faster than GPT-4o and DeepSeek. Model weights are released (CC-BY-NC) on Hugging Face.
CodeScientist
Researchers at AI2 release CodeScientist, a system that autonomously generates and tests scientific hypotheses via code-based experimentation. It’s among the first to produce validated discoveries with minimal human input. Key ideas: ● Code-first scientific agent – CodeScientist reviews research papers and assembles experiments using vetted Python code blocks (e.g., for analysis, simulation). It follows a five-step pipeline: Ideation → Planning → Code Execution → Reporting → Meta-Analysis. ● Validated AI discoveries – From 50 AI research papers on agents and virtual environments, CodeScientist proposed 19 findings. Of these, 6 were judged scientifically sound and novel. Examples: ● Human-guided autonomy – Full automation is possible, but brief human feedback (e.g., ranking ideas) significantly boosts output quality. Human-in-the-loop interaction improves idea selection and experiment debugging. ● Challenges remain – Despite successes, over half the generated experiments fail due to code errors, not scientific flaws. Peer review is still needed to verify results, and current systems lack deep methodological rigor.
Self-Evolving Multi-Agent Simulations for Realistic Clinical Interactions
Presents MedAgentSim is a fully automated, open-source hospital simulation where LLM-powered agents simulate doctor-patient interactions in dynamic diagnostic settings. Unlike previous static QA benchmarks, MedAgentSim mimics real-world clinical workflows with multi-turn dialogue, test requests, and self-improvement. More about this paper: ● Active doctor agents – MedAgentSim requires LLM doctor agents to engage in multi-turn consultations, request labs and imaging (e.g., ECG, X-ray), and iteratively refine diagnoses, making it far more realistic than pre-filled medical QA datasets. ● Self-improvement via memory + reflection – The system maintains buffers of successful and failed diagnoses. It uses retrieved past cases (via kNN), chain-of-thought reasoning, and ensembling to improve performance over time. Misdiagnoses trigger a reflection phase before inclusion in memory. ● Fully autonomous or human-in-the-loop – Users can optionally take control of the doctor or patient agents. Simulation assets are built using a 2D game engine (Phaser), and the agents can navigate, converse, and interact with virtual medical tools. ● Big performance boost across benchmarks – On NEJM, MedQA, and MIMIC-IV, MedAgentSim (with LLaMA 3.3) outperforms baseline setups by +6–37%, especially in vision-language tasks using LLaVA for interpreting medical images. ● Bias analysis & fairness focus – The team studied diagnostic accuracy under cognitive and implicit bias conditions. Models like GPT-4o and LLaMA proved more robust than Mixtral/Mistral, highlighting the importance of bias-aware evaluation.
Open Deep Search
Researchers from Sentient, UW, Princeton, and UC Berkeley introduce Open Deep Search (ODS), an open-source search AI framework that rivals top proprietary systems like GPT-4o Search Preview and Perplexity Sonar. Key insights: ● Two open components: search + reasoning – ODS has two modular parts: (1) Open Search Tool, which retrieves and refines high-quality web results using query rephrasing, snippet reranking, and site-specific logic; and (2) Open Reasoning Agent, a controller that orchestrates tool usage (search, calculator, etc.) to answer queries. Two variants are offered: ODS-v1 (ReAct) and ODS-v2 (CodeAct). ● SOTA open-source performance – With DeepSeek-R1 as the base LLM, ODS-v2 scores 88.3% on SimpleQA and 75.3% on FRAMES, beating GPT-4o Search Preview by +9.7% on the latter. ODS adapts the number of searches per query (avg. 3.39 on FRAMES), balancing cost and accuracy more efficiently than fixed-query baselines. ● Better than Perplexity Sonar – On both FRAMES and SimpleQA, ODS+DeepSeek-R1 outperforms Perplexity’s flagship search models, even in complex reasoning tasks involving multi-hop questions, time/date calculations, and name disambiguation. ● Code-based agents enhance reasoning – ODS-v2 builds on CodeAct, allowing it to write and run Python code to perform symbolic reasoning and tool calls. This results in sharper numerical precision and task flexibility compared to CoT-based ReAct in ODS-v1.
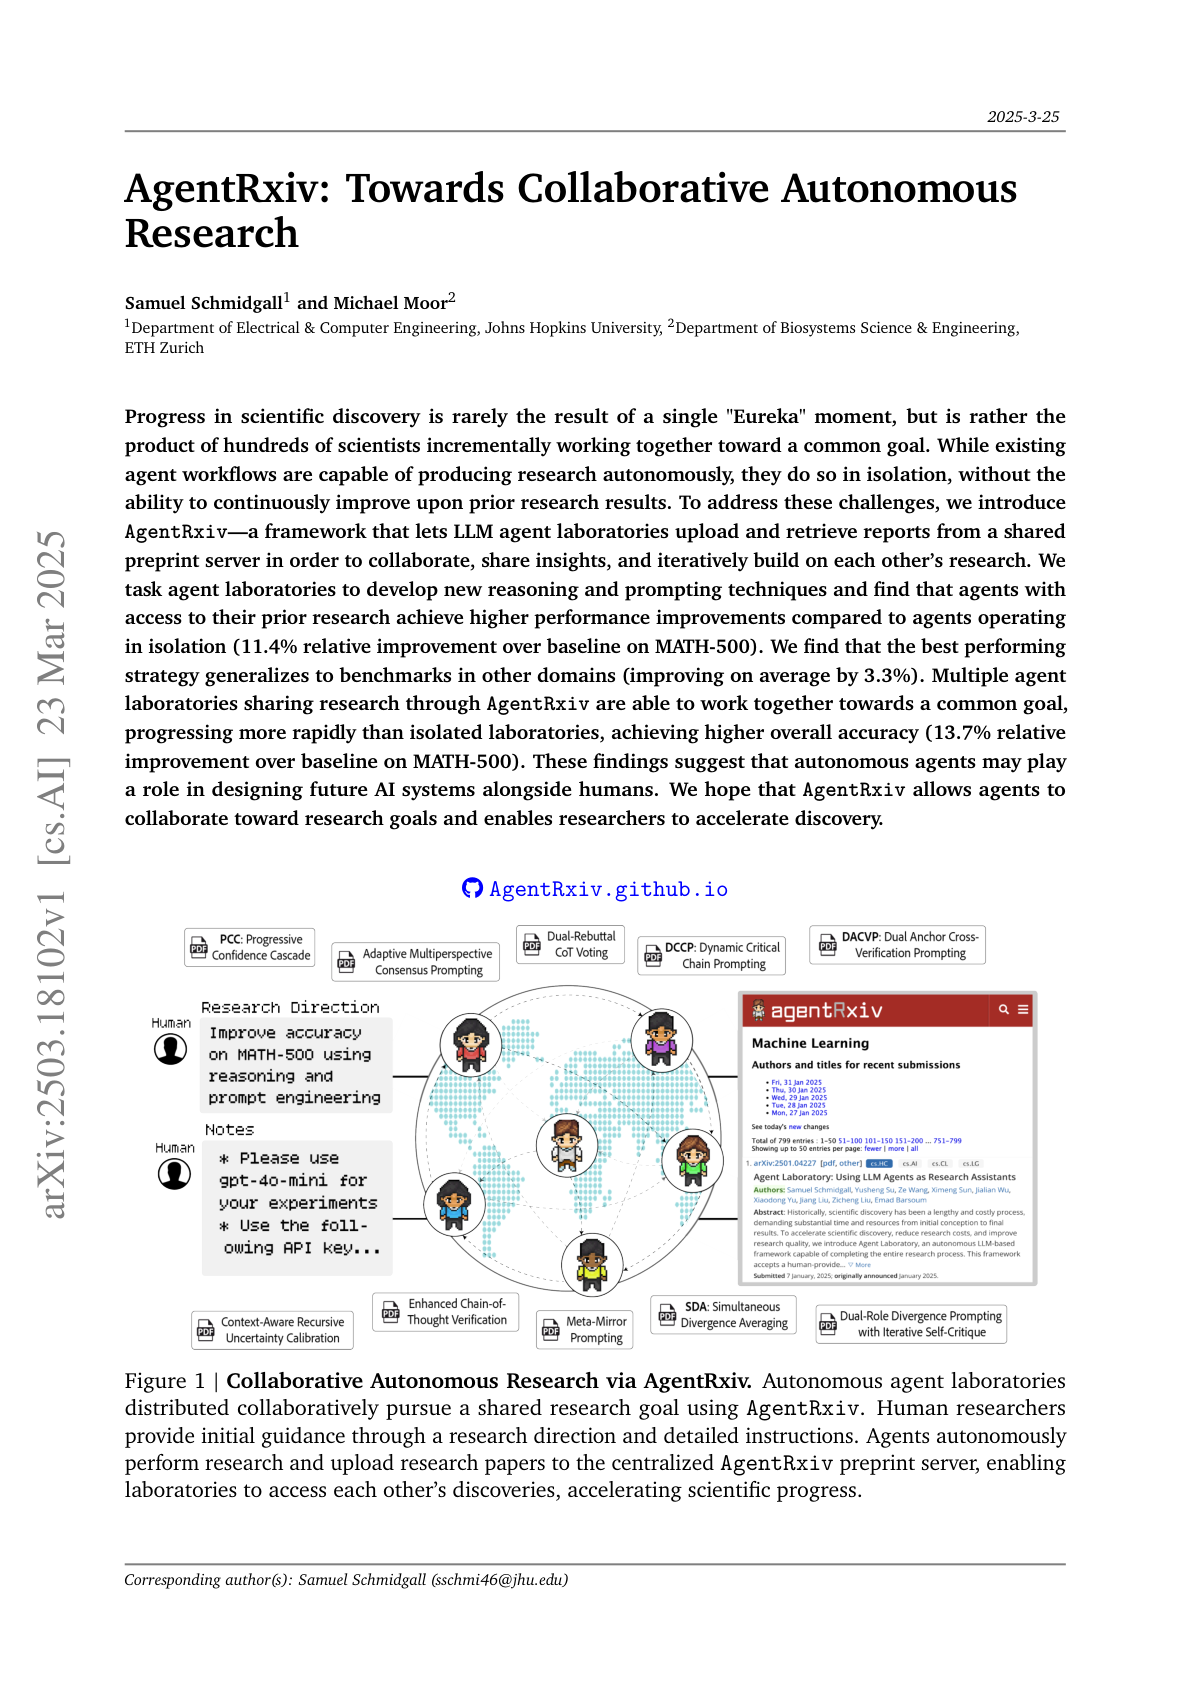
AgentRxiv
Researchers from Johns Hopkins & ETH Zurich present AgentRxiv, a framework enabling LLM agents to autonomously generate and share research papers, mimicking how human scientists build on each other’s work. Highlights: ● AgentRxiv = arXiv for LLMs – It’s an open-source preprint server for autonomous agents, letting labs upload papers, search past work, and iteratively improve results. Labs use this to develop and refine reasoning techniques over generations of research. ● Massive reasoning gains via iterative research – On the MATH-500 benchmark, a single agent lab improves GPT-4o mini accuracy from 70.2% → 78.2% (+11.4%) by discovering better prompt strategies. The final method (SDA) outperforms earlier ideas like CRUC and DCCP. → SDA = Simultaneous Divergence Averaging: combines low/high-temp CoT outputs with dynamic similarity-based voting and confidence aggregation. ● Knowledge generalizes – SDA also improves other benchmarks: ● Collaboration boosts discovery – Running 3 agent labs in parallel yields faster progress and higher final accuracy (up to 79.8%, +13.7% over baseline) by sharing results via AgentRxiv. Early gains (e.g., 76.2% accuracy) arrive after only 7 papers vs. 23 sequentially. ● Self-improvement and novelty – Agents independently refine their own past ideas. Papers evolve from earlier iterations (e.g., Meta-Mirror Prompting → Meta-Mirror Prompting 2). Top papers show no plagiarism via multiple detectors, but ideas like SDA build on trends like self-consistency and CoT voting. ● Cost & runtime – Generating a paper takes ~1.36 hours and ~$3.11. Parallel setups are pricier overall but achieve results faster (time-to-accuracy win). Failure modes include hallucinated results and fragile code repair steps, with future work needed for better reliability and novelty guarantees.
Neural Alignment via Speech Embeddings
Google Research and collaborators reveal striking similarities between LLM embeddings and human brain activity during conversation. Key insights: ● Embeddings match brain signals – Using intracranial electrode recordings, the team showed that internal representations (embeddings) from OpenAI's Whisper model align with neural responses in brain regions for speech (STG), language (IFG), and motor planning (MC). During comprehension, speech embeddings predict early auditory responses, while language embeddings follow in IFG. During production, this order reverses — first language planning (IFG), then articulation (MC), then auditory feedback (STG). ● “Soft hierarchy” in brain areas – Though STG emphasizes acoustic info and IFG captures word-level meaning, both regions show partial alignment with both embedding types. This suggests a gradient processing structure, not a strict modular pipeline. ● Brain predicts next word too – In follow-up studies published in Nature Neuroscience, the brain’s language areas were found to predict upcoming words, mirroring the objective of autoregressive LLMs. The surprise response after hearing a word also mirrors LLM prediction errors. ● Shared geometry in language representations – The geometry of word relationships in brain activity mirrors that of LLM embeddings, per a separate Nature Communications paper. This indicates a convergent structure in how LLMs and the brain represent language. ● Different wiring, same function – Despite similarities in objectives and representations, LLMs and brains diverge architecturally: brains process speech serially and recursively, while Transformers process in parallel across layers. ● Toward biologically inspired AI – These studies support using LLMs to reverse-engineer the brain’s language mechanisms. The team aims to build future models with more brain-like learning, data, and structure, bridging neuroscience and deep learning.