AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
DeepSearch
DeepSearch integrates Monte Carlo Tree Search directly into RL with verifiable rewards, but during training rather than only at inference. The result is broader exploration, better credit assignment, and higher sample efficiency on math reasoning vs strong 1.5B baselines.
Accelerating Diffusion LLMs
A lightweight, learned policy speeds up diffusion-based LLM decoding by deciding which tokens are already “final” and when to stop generation. The authors train a tiny MLP filter on token confidence signals and add an End-of-Text Prediction that halts decoding as soon as [EoT] is reliably produced. On LLaDA-8B-Instruct, this reaches large throughput gains with minimal or no accuracy loss.
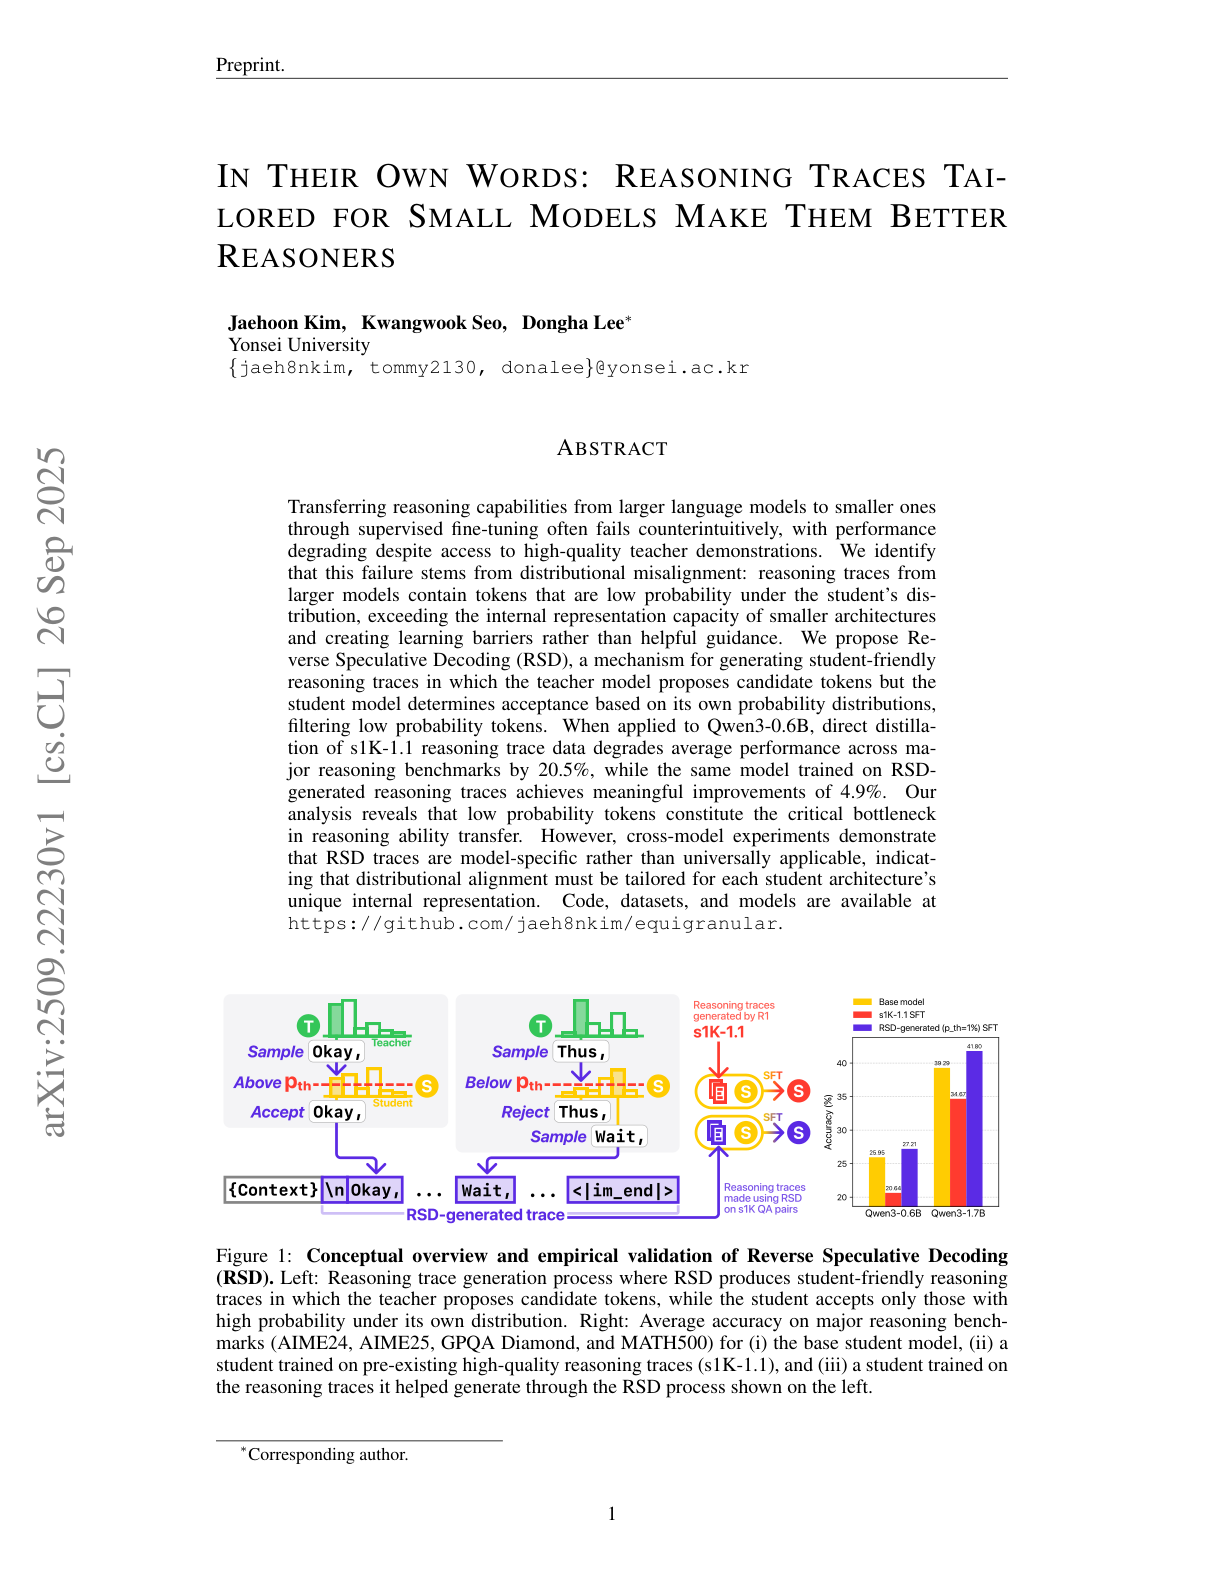
Reasoning Traces Tailored for Small Models
Small models often get worse when you SFT them on long, high-quality CoT from big teachers. This paper pinpoints why and fixes it with Reverse Speculative Decoding (RSD): let the teacher propose tokens, but let the student approve them only if they are probable under the student. Result: traces that stay correct while matching the student’s distribution, which small models can actually learn from.
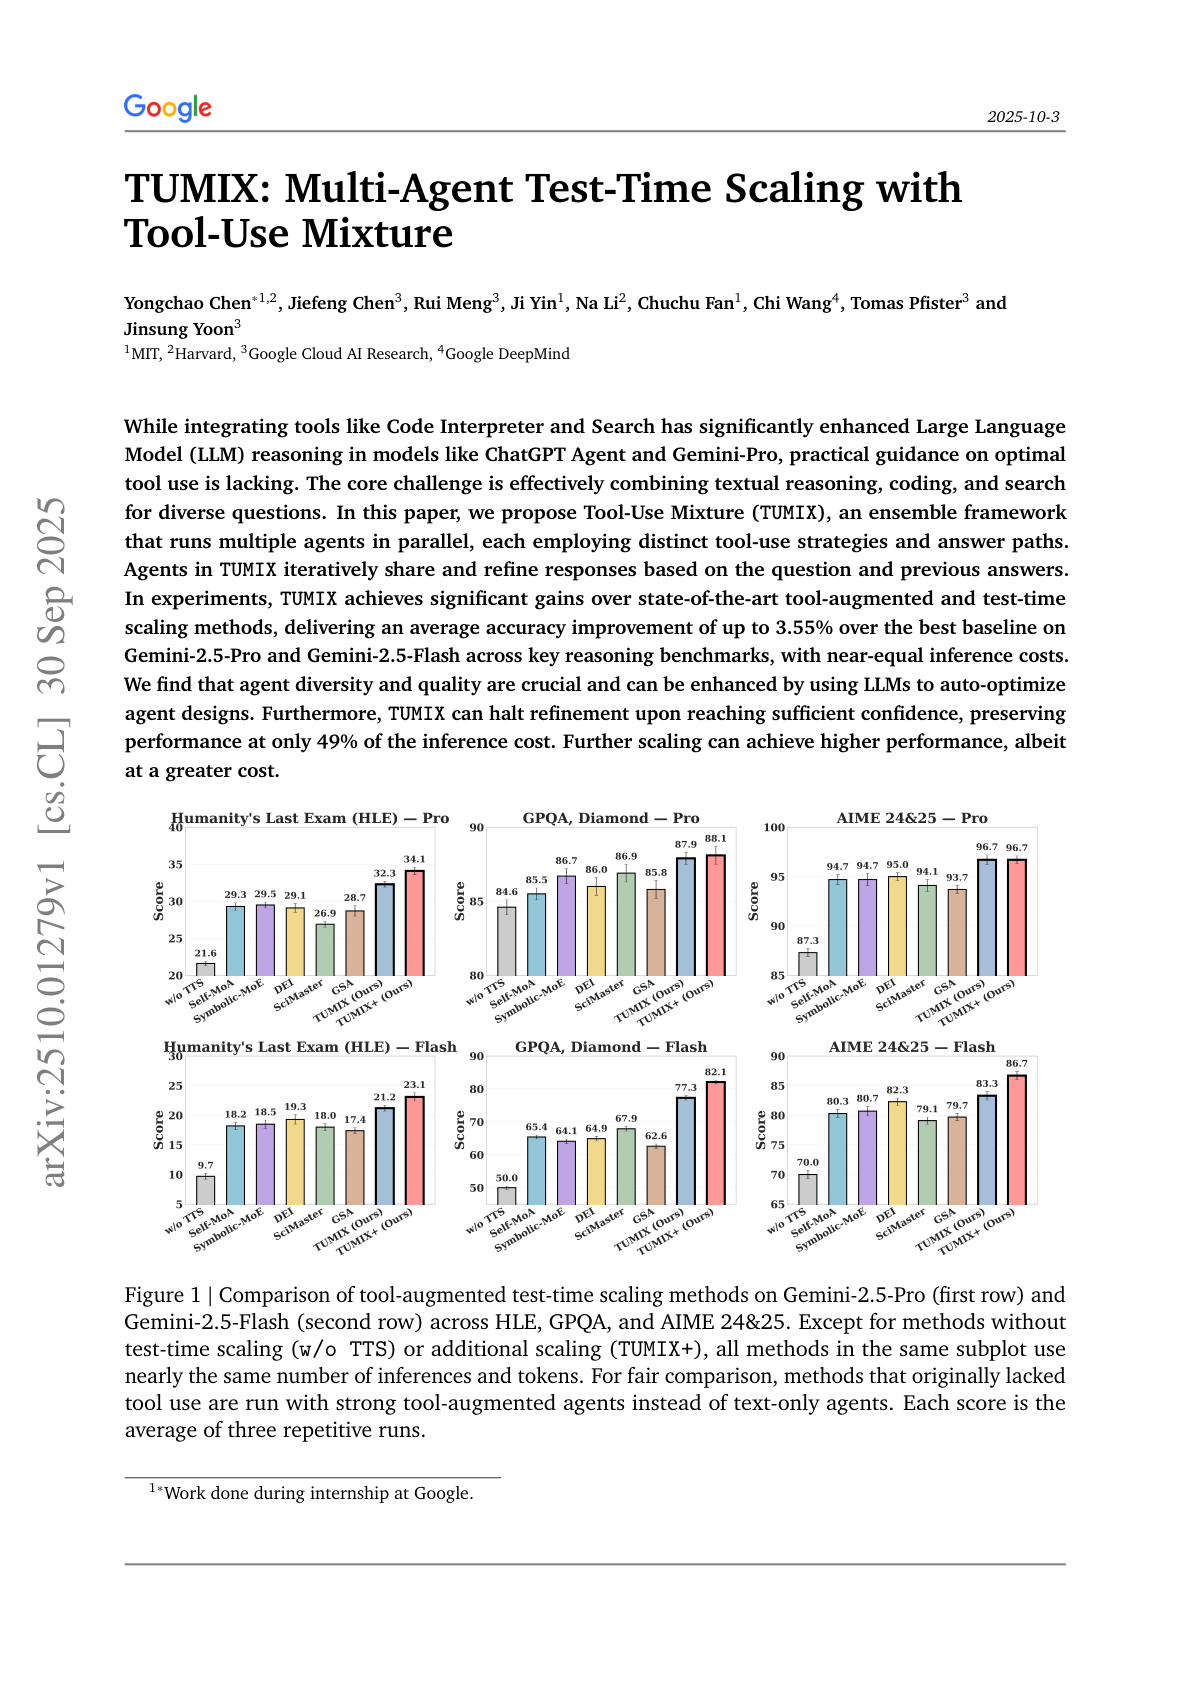
Tool-Use Mixture (TUMIX)
TUMIX is an ensemble recipe for reasoning that mixes text, code execution, and web search, running 15 diverse agents in parallel and passing intermediate answers across rounds. An LLM-judge controls early stopping, giving up to +3.55% accuracy gains over strong tool-augmented baselines on HLE, GPQA-Diamond, and AIME 24/25 while cutting inference cost by ~50%.
PrompCoT 2.0
PromptCoT 2.0 introduces an EM-based loop for synthesizing harder and more diverse reasoning prompts, replacing manual heuristics from PromptCoT 1.0. It enables both self-play and SFT training regimes, achieving new SOTA on reasoning benchmarks like AIME, HMMT, LiveCodeBench, and Codeforces, showing prompt synthesis as a new scaling axis for LLM reasoning.
ARE
Metal SuperIntelligence Labs presents a research platform and benchmark for building and stress-testing agent systems in realistic, time-driven environments. The paper introduces a modular simulator (ARE) and a mobile-style benchmark (Gaia2) that emphasize asynchronous events, verification of write actions, and multi-agent coordination in noisy, dynamic settings.
ATOKEN
ATOKEN introduces a single transformer tokenizer that works for images, videos, and 3D assets. It encodes all inputs into a shared sparse 4D latent space with 4D RoPE, trains without adversarial losses, and supports both continuous and discrete tokens. The paper reports strong reconstruction quality and solid semantic alignment, enabling both generation and understanding across modalities.
Code World Model
Meta FAIR releases CWM, a 32B open-weights coder trained to model code execution and to act inside containers. It mid-trains on Python interpreter traces and agentic Docker trajectories, then upgrades with multi-turn RL across SWE, coding, and math. CWM is both a strong coder and a testbed for world-model-style reasoning in software environments.
Teaching LLMs to Plan
A training recipe that teaches LLMs to plan in Planning Domain Definition Language (PDDL) by making them write explicit state–action–state chains and checking each step with an external verifier (VAL). The result: big jumps in plan validity on PlanBench domains, especially when feedback explains why an action failed rather than just saying it failed.
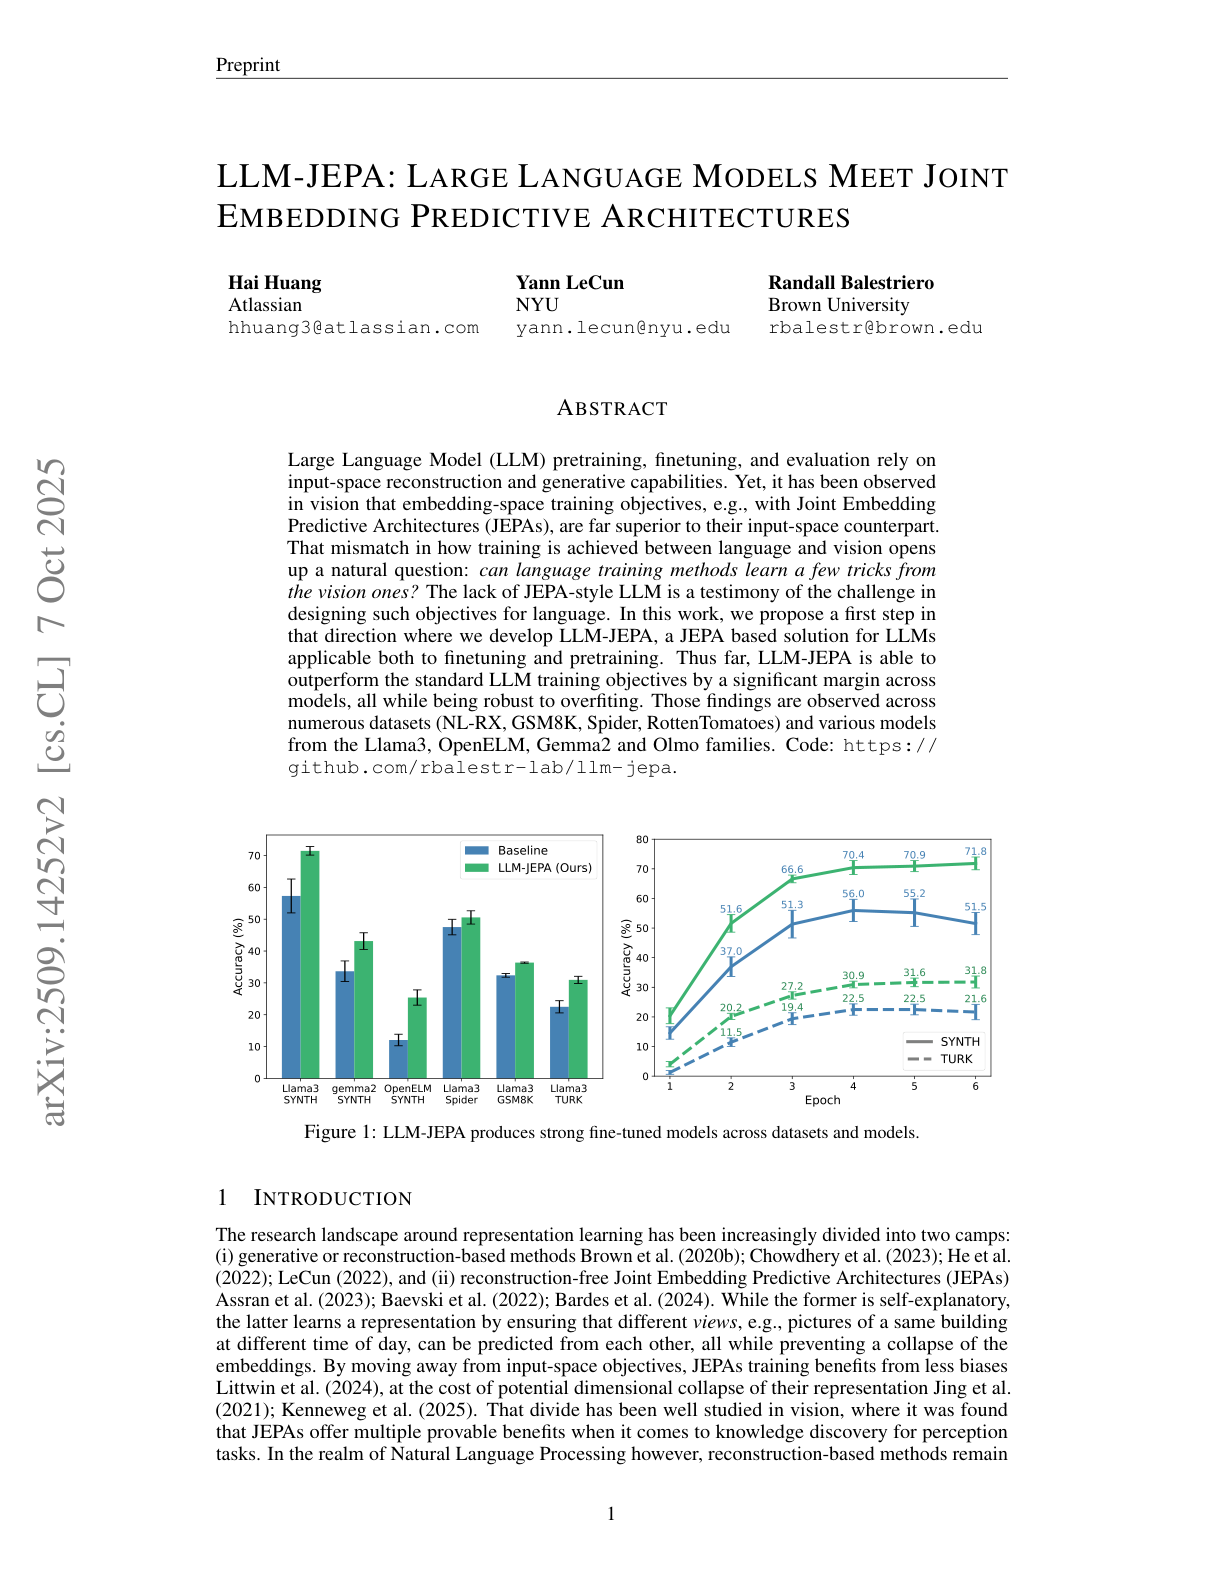
LLM-JEPA
A JEPA-style training objective is adapted to LLMs by treating paired views of the same underlying content (for example, text and code) as prediction targets in embedding space, added on top of the usual next-token loss. The result consistently improves fine-tuning and shows promising pretraining gains, while being more resistant to overfitting.
ARK-V1
ARK-V1 is a lightweight agent that helps language models answer questions by actively walking through a knowledge graph instead of relying only on memorized text. This is especially useful for long-tail entities (less common stuff) where the model’s pretraining knowledge falls short.
Language Models that Think, Chat Better
A simple recipe, RL with Model-rewarded Thinking, makes small open models “plan first, answer second” on regular chat prompts and trains them with online RL against a preference reward. On Llama-3.1-8B and Qwen-2.5-7B, this consistently beats standard RLHF on chat, creative writing, and general knowledge, with the best 8B model topping some frontier systems on WildBench and AlpacaEval2.
Embodied AI: From LLMs to World Models
This paper surveys embodied AI through the lens of LLMs and World Models (WMs). It highlights how LLMs enable semantic reasoning and task decomposition, while WMs provide predictive, physics-grounded interaction, and argues for a joint MLLM-WM architecture to advance real-world embodied cognition and applications.
GDPval
GDPval is a new benchmark of 1,320 real-world tasks across 44 occupations in 9 major GDP sectors, graded by industry experts with a 220-task gold set. It shows frontier models improve roughly linearly and are nearing expert parity, with Claude Opus 4.1 preferred or tied 47.6% of the time, while GPT-5 leads in accuracy. Model-plus-human workflows can reduce time and cost, and adding reasoning effort and prompt scaffolding further raises scores, with an open gold set and automated grader available for researchers.
Automating the Search for Artificial Life with Foundation Models
ASAL uses vision-language foundation models to automatically search across ALife substrates for simulations that match prompts, sustain open-ended novelty, or maximize diversity, reducing manual trial-and-error. It discovers new Lenia and Boids life-forms and lifelike CAs with strong open-endedness, and leverages FM embeddings to quantify emergent behaviors in a substrate-agnostic way.
Discovery of Unstable Singularities
The authors present a playbook for finding unstable finite-time singularities in fluid PDEs, uncovering new self-similar blow-up solutions in three canonical systems and training neural solvers to near machine precision, which enables downstream computer-assisted proofs.
K2-Think
A 32B-parameter system built on Qwen2.5 that rivals or beats far larger models on hard math by combining long CoT SFT, RL with verifiable rewards, lightweight test-time scaffolding, and inference optimization.
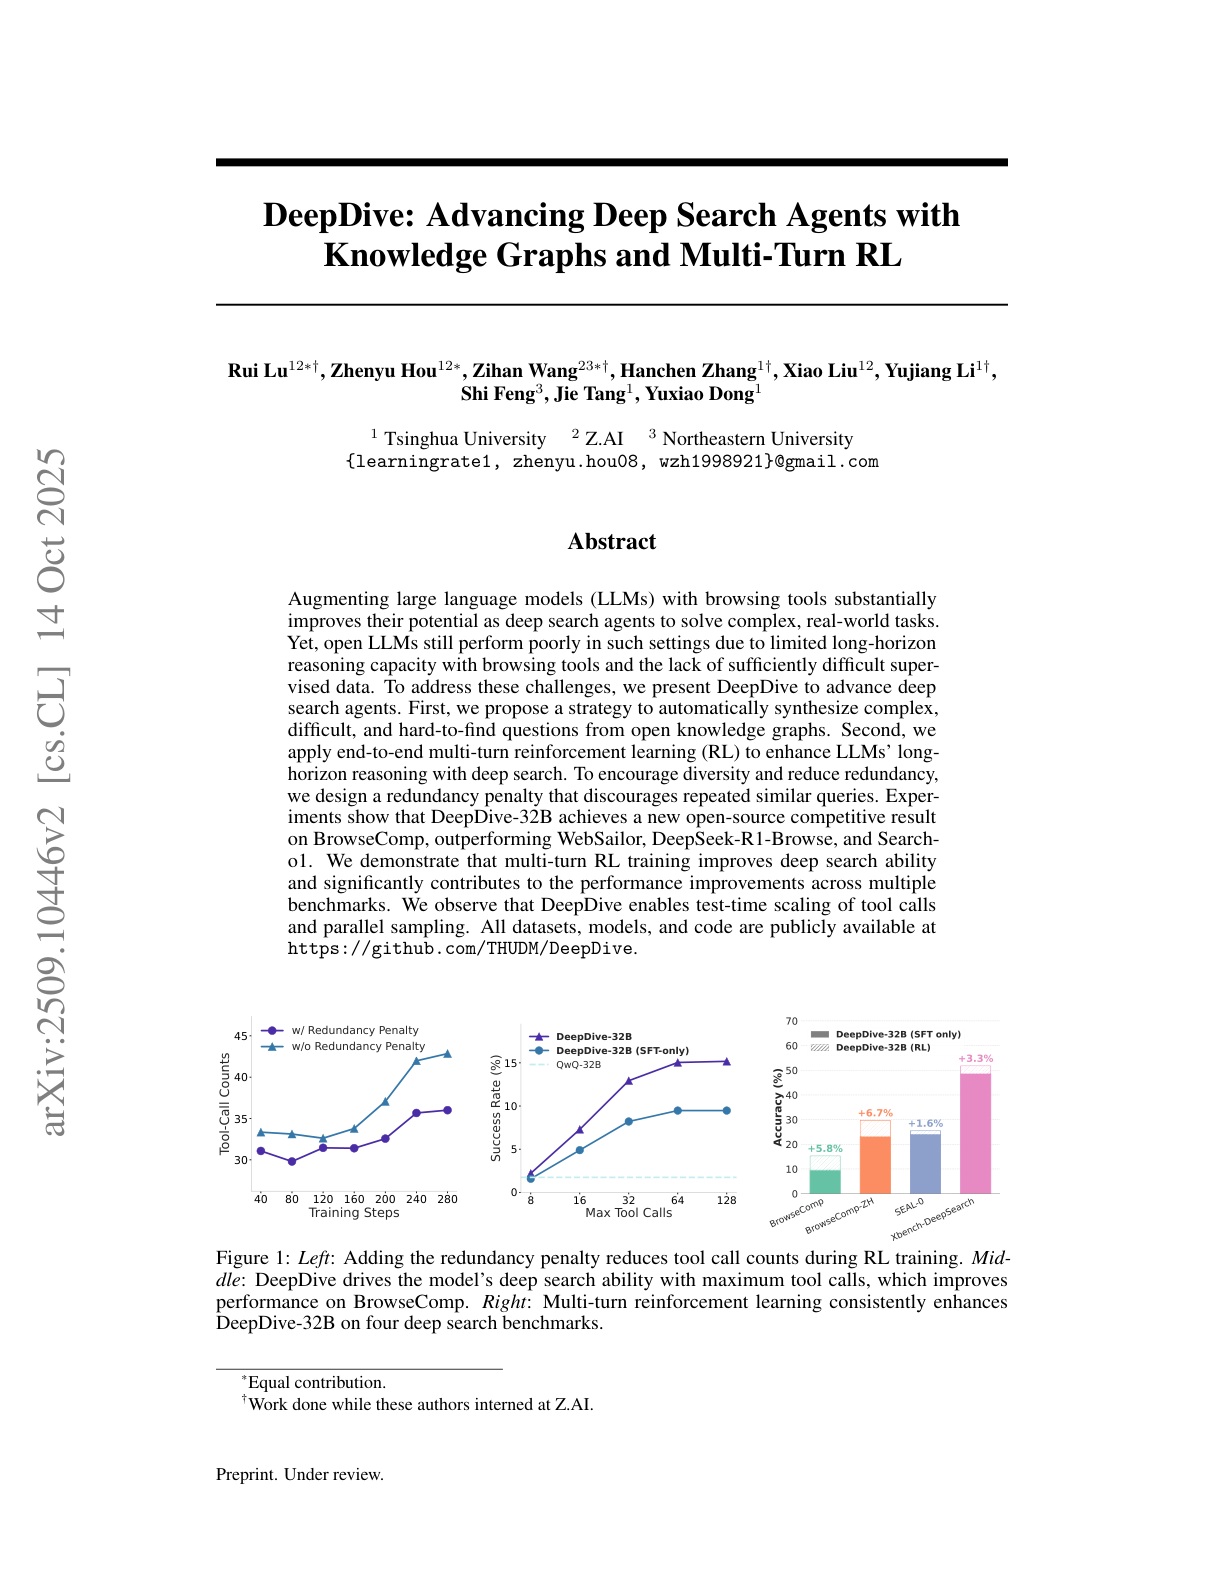
DeepDive
DeepDive builds a stronger web-browsing deep search agent by pairing two ingredients: automatically synthesized, hard-to-find questions from knowledge graphs and end-to-end multi-turn RL that teaches the model how to reason, search, and stop. On BrowseComp, the 32B model reaches 14.8% and beats prior open agents, with clear gains from RL over SFT.
Towards a Physics Foundation Model
A transformer-based “neural differentiator + numerical integrator” that learns governing dynamics from short spatiotemporal prompts and predicts next states across varied PDE systems. Trained on a 1.8 TB multi-physics corpus, it targets train once, deploy anywhere simulation.
Is In-Context Learning Learning?
This large study argues yes in a formal sense, then shows where it works and where it breaks. The author frames ICL within PAC learning, then runs a big empirical sweep to separate learning from memorization, prompt wording, and distribution shifts.
Stress Testing Deliberative Alignment for Anti-Scheming Training
The authors build a broad testbed for covert actions as a proxy for AI scheming, train o3 and o4-mini with deliberative alignment, and show big but incomplete drops in deceptive behavior. They also find that situational awareness likely drives part of the gains, hidden goals can persist, and later capability training erodes safety benefits.
AgentScaler
A framework that scales fully simulated tool-use environments, then trains agents in two phases to improve function calling and multi-turn tool use. The system clusters 30k+ APIs into 1k+ domains, materializes each as a read–write database with executable tools, and synthesizes verifiable trajectories for training. Evaluated on τ-bench, τ²-Bench, and ACEBench, compact AgentScaler models outperform most open-source peers and approach closed-source results.
A Survey on Retrieval and Structuring Augmented Generation with LLMs
This survey reviews Retrieval and Structuring (RAS) Augmented Generation, which combines external retrieval and structured knowledge to mitigate LLM issues like hallucinations and outdated knowledge. It covers retrieval methods, structuring techniques, integration strategies, and highlights challenges in efficiency, structure quality, and multimodal or cross-lingual extensions.
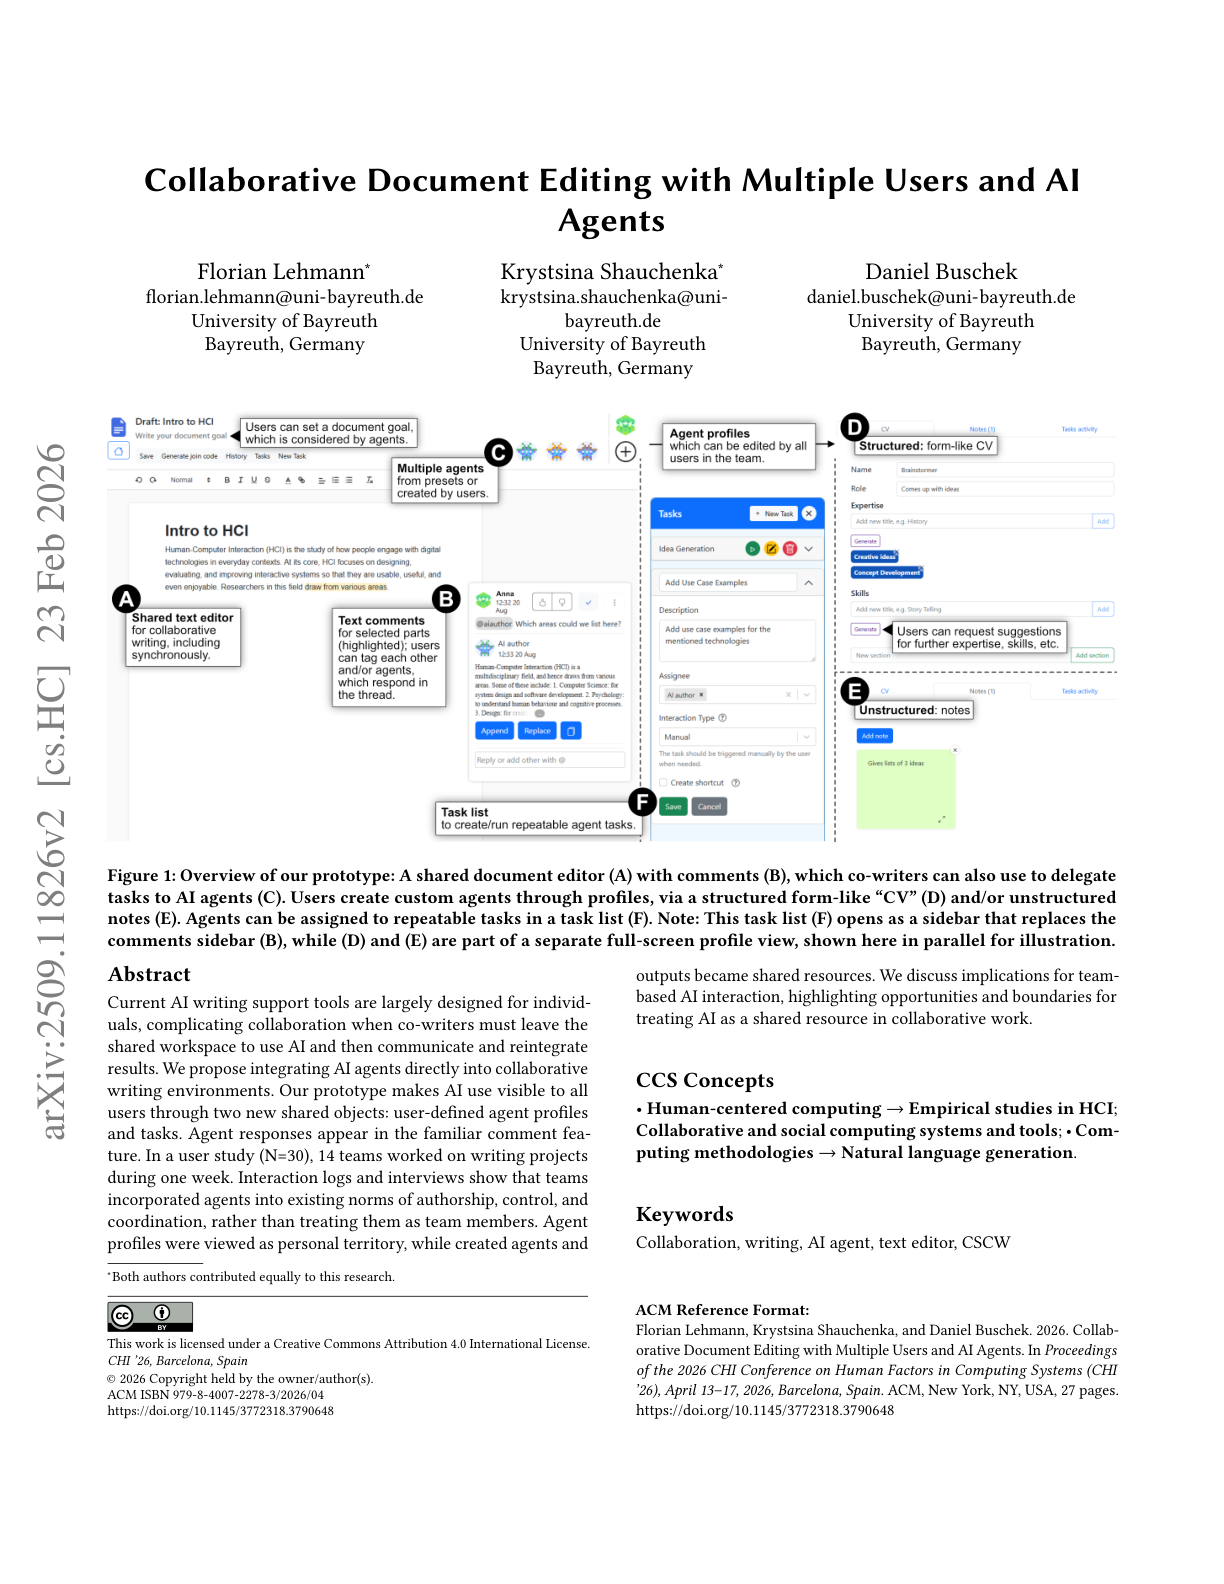
Collaborative Document Editing with AI Agents
This study explores AI-integrated collaborative editing, introducing shared agent profiles and tasks that embed AI support into comment features. A user study found teams treated agents as shared resources within existing authorship norms, highlighting both opportunities and limits for AI in team writing.