AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup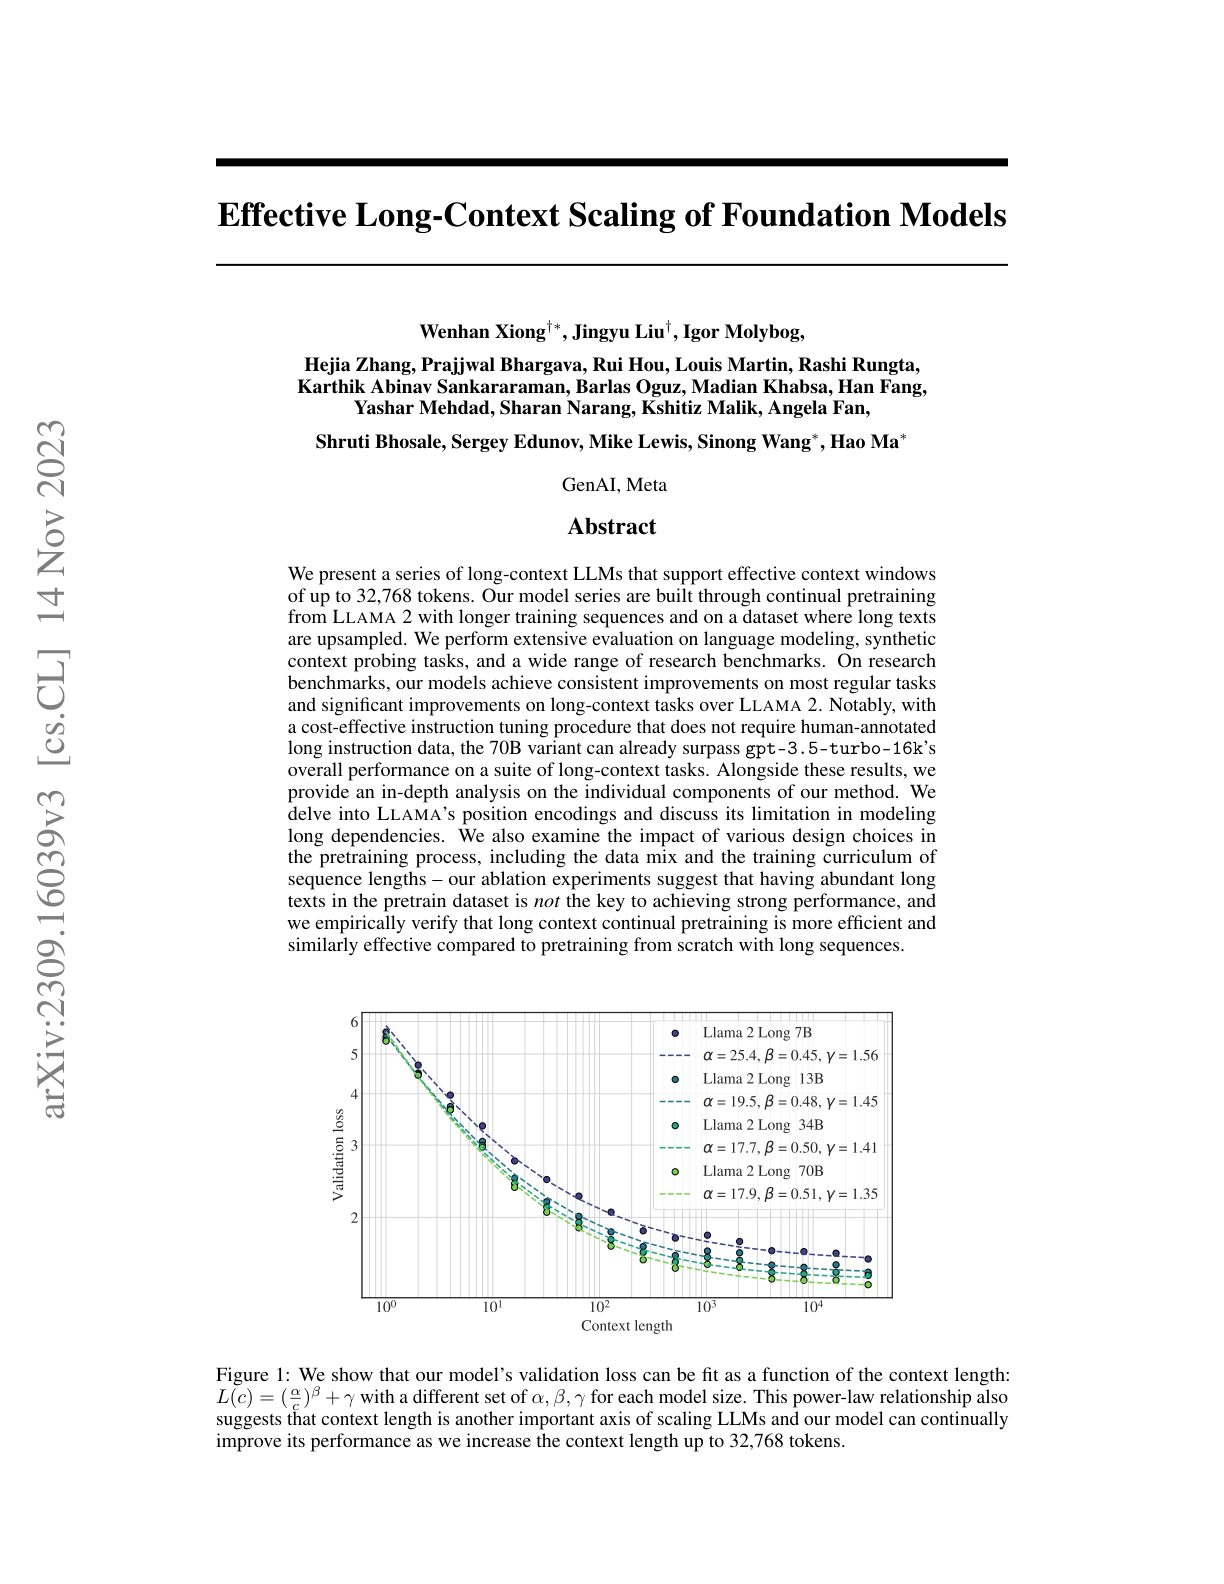
Effective Long-Context Scaling (Meta)
Meta proposes a 70B long-context LLM that surpasses GPT-3.5-turbo-16k on long-context benchmarks.
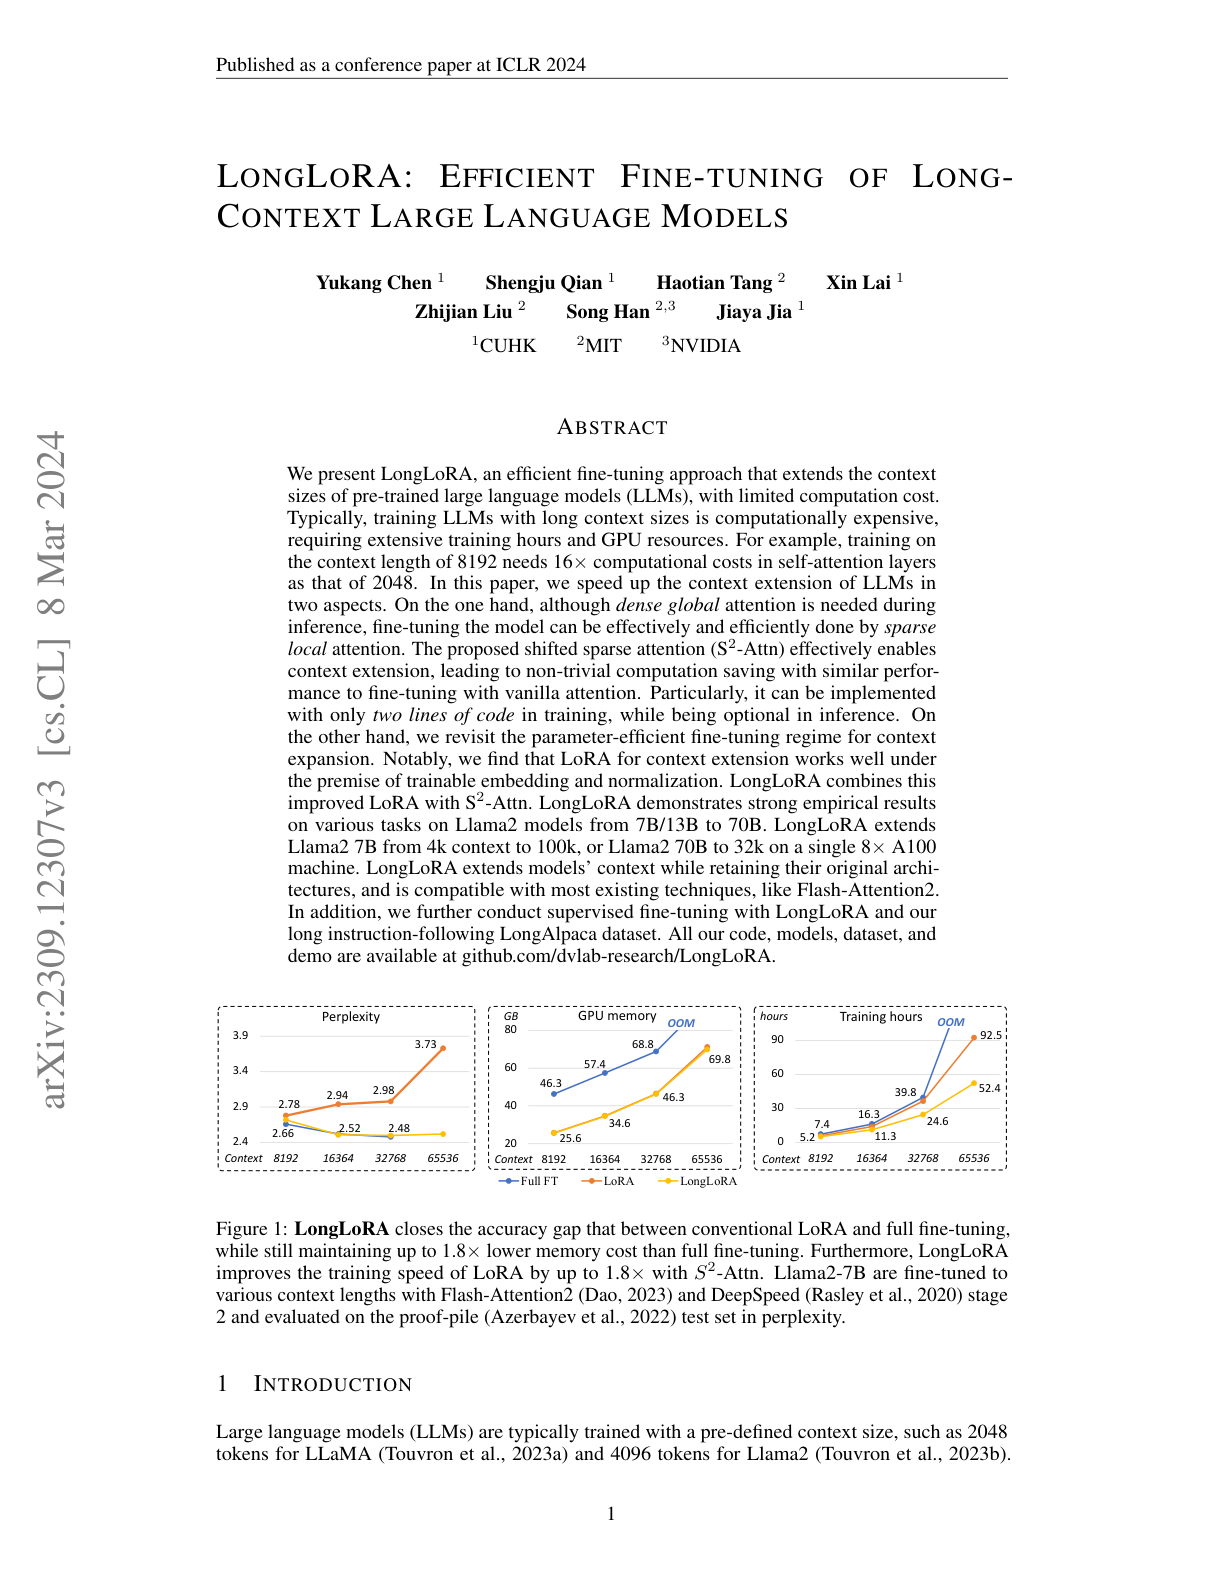
LongLoRA
An efficient LoRA-based fine-tuning recipe for extending LLM context windows without expensive full fine-tuning.
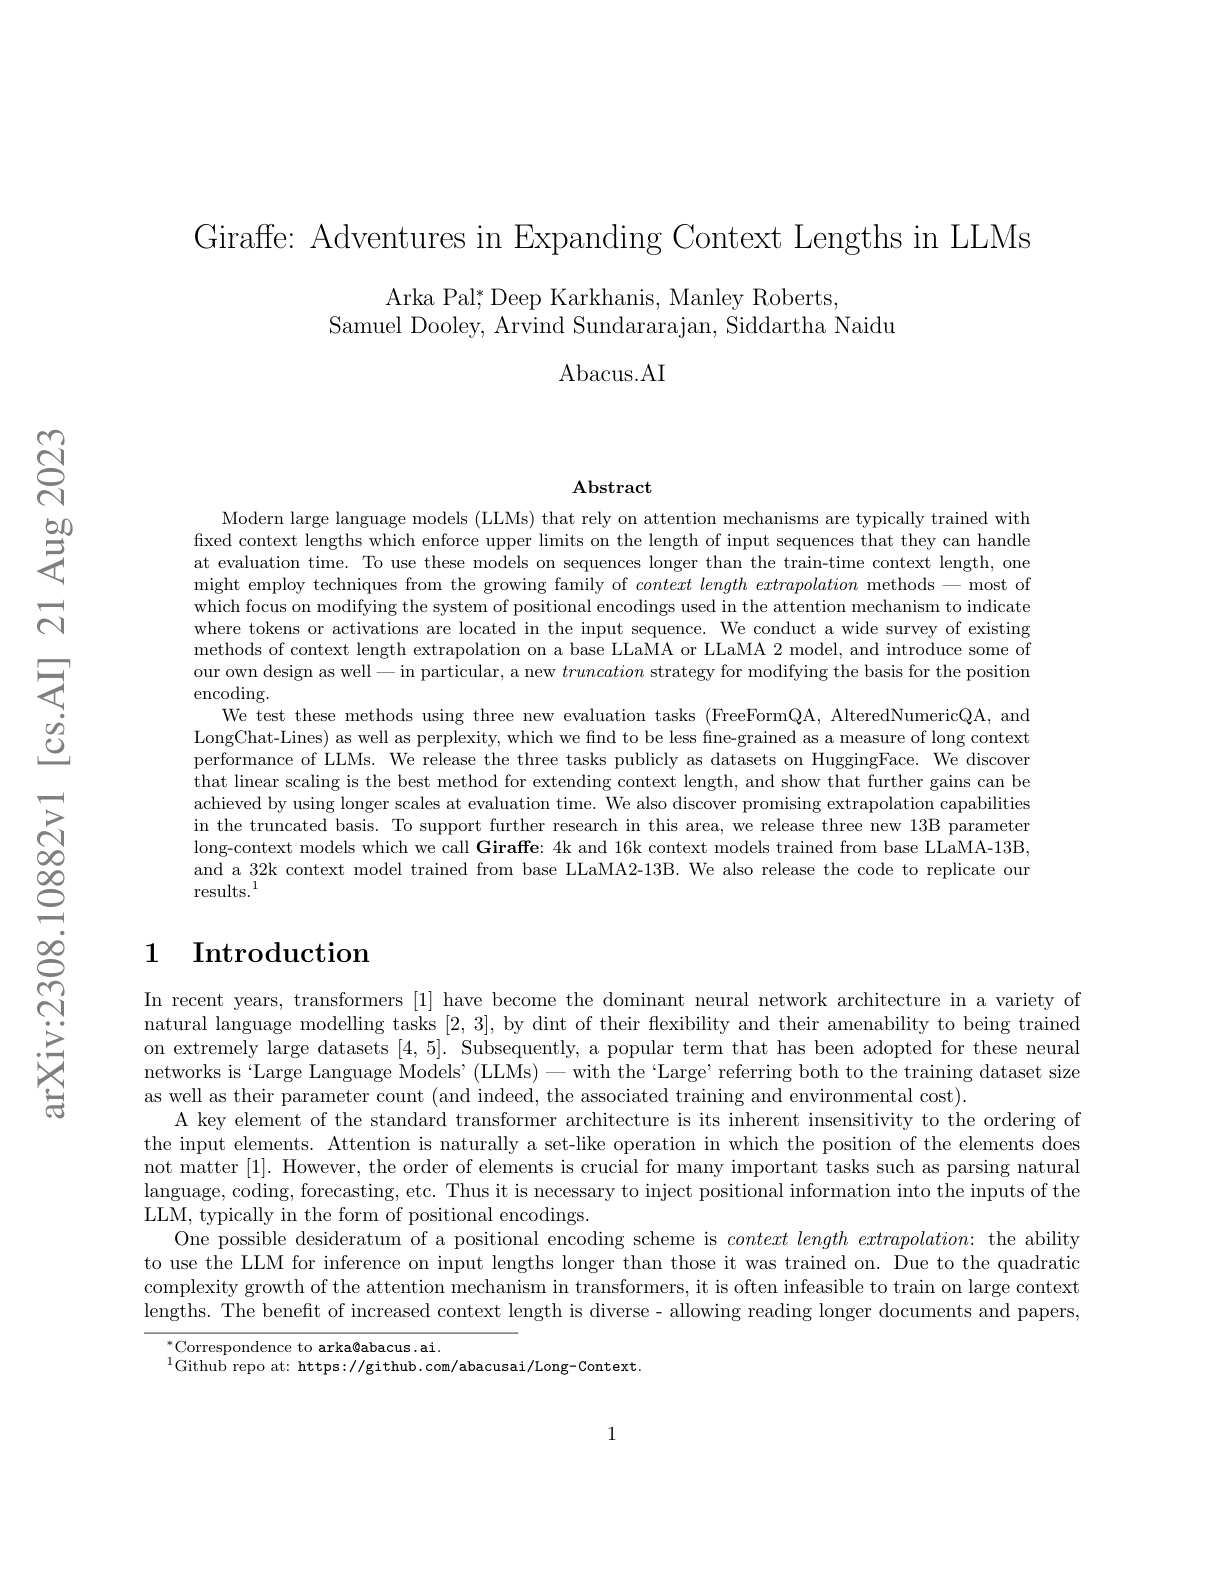
Giraffe
A family of context-extended Llama and Llama 2 models, along with an empirical study of context-extension techniques.
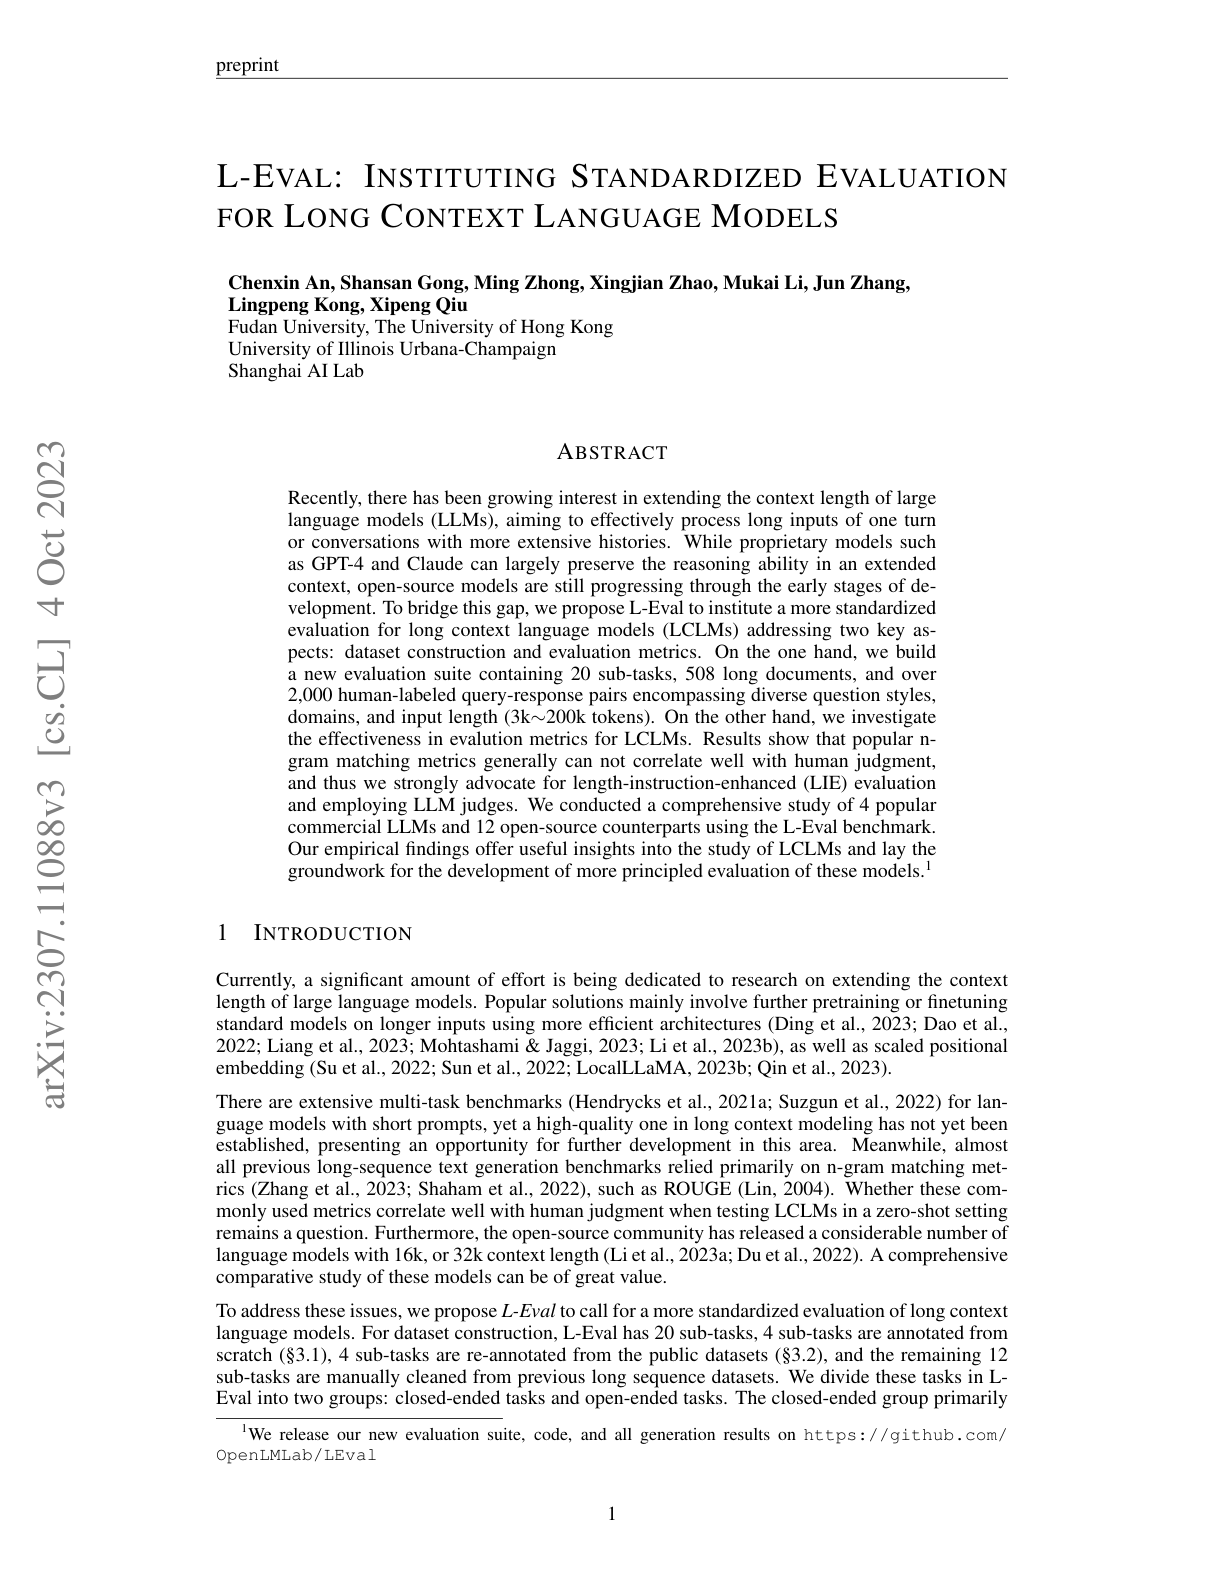
L-Eval
A standardized evaluation suite for long-context language models.
FlashAttention-2
Tri Dao's follow-up to FlashAttention, dramatically improving attention throughput on modern GPUs.
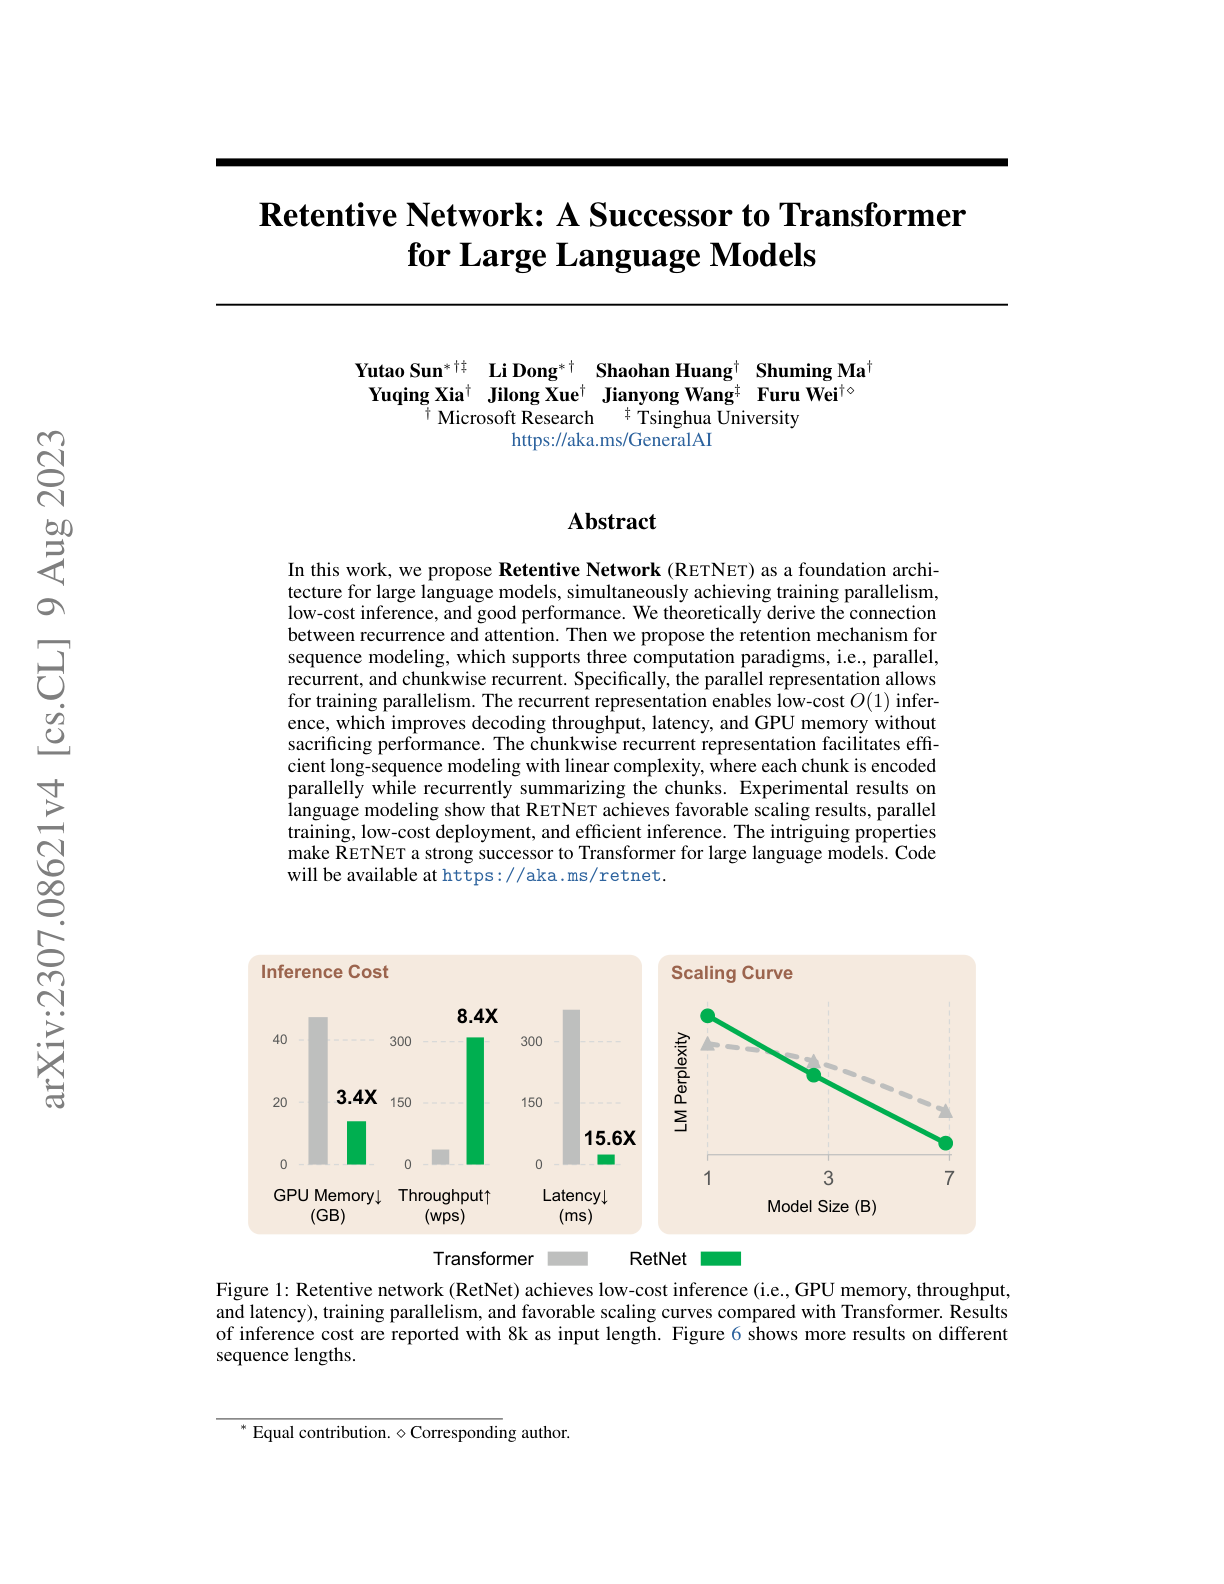
Retentive Network (RetNet)
Microsoft's proposed foundation architecture aiming to replace Transformer attention for LLMs.
LongLLaMA
Extends LLaMA's context length using a contrastive training process that reshapes the (key, value) space.
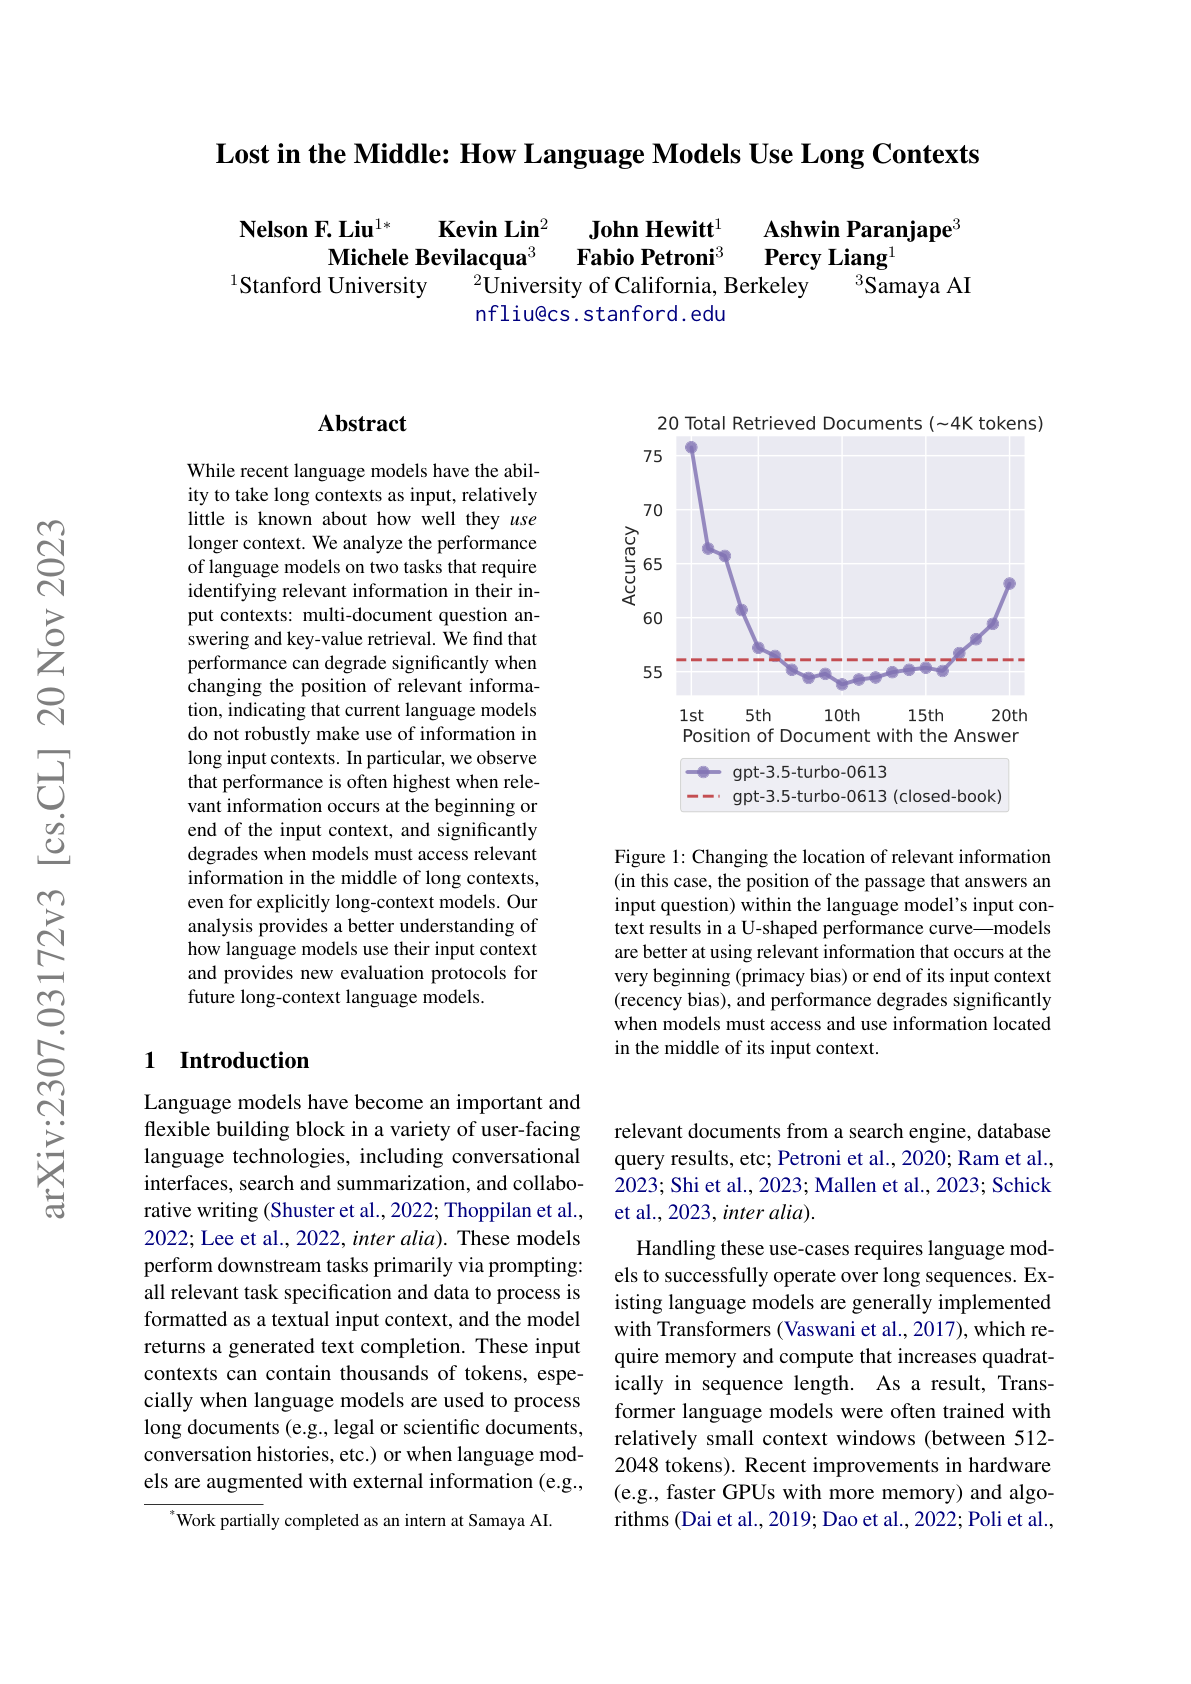
How Language Models Use Long Contexts (Lost-in-the-Middle)
Shows LLM performance drops when relevant information is in the middle of a long context.
Extending Context Window of LLMs (PI)
Position Interpolation extends LLaMA's context to 32K with minimal fine-tuning (within 1000 steps).
Augmenting LLMs with Long-term Memory (LongMem)
Enables LLMs to memorize long history via memory-augmented adaptation.
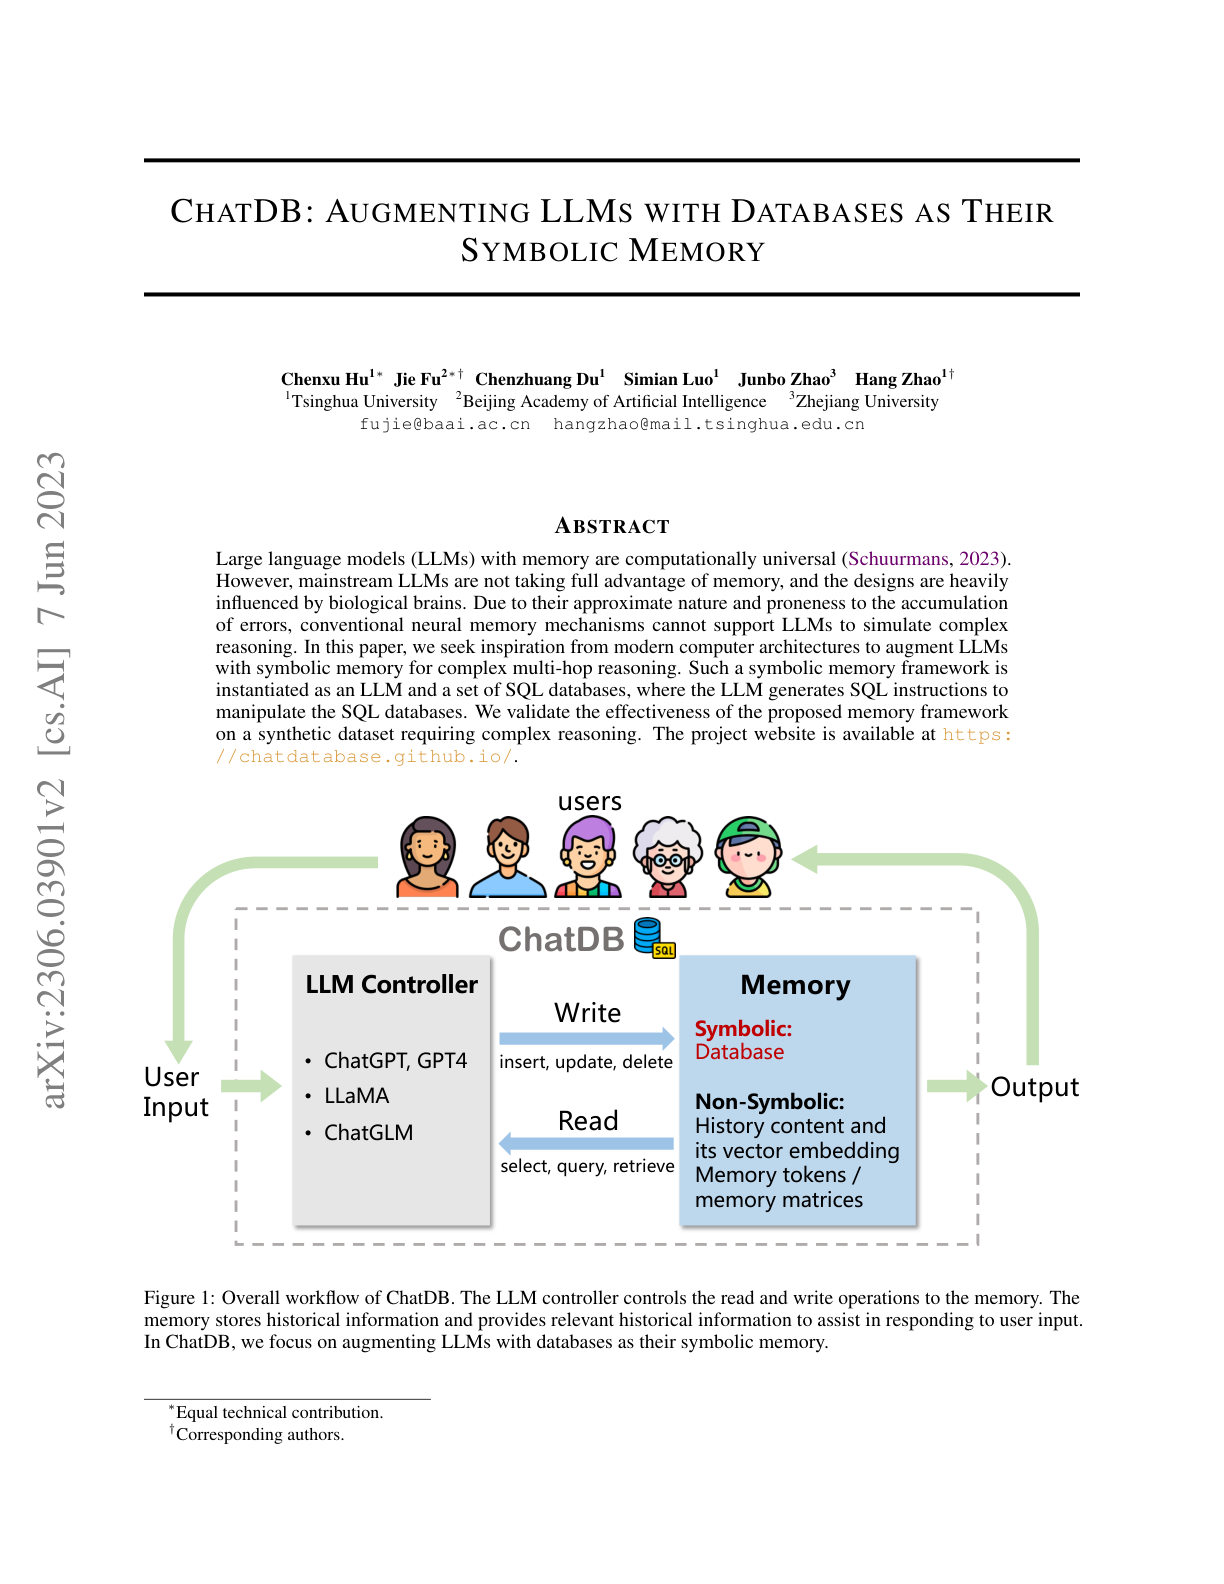
Augmenting LLMs with Databases (ChatDB)
Combines an LLM with SQL databases as a symbolic memory framework.
Unlimiformer
Long-range Transformers with unlimited length input via external datastores.
Scaling Transformer to 1M tokens with RMT
Recurrent Memory Transformer extends BERT's effective context to 2M tokens.