AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
LOMO
A memory-efficient optimizer that combines gradient computation and parameter update in one step.
LMFlow
An extensible and lightweight toolkit for fine-tuning and inference of large foundation models.
Fine-Tuning Language Models with Just Forward Passes (MeZO)
A memory-efficient zeroth-order optimizer for LLM fine-tuning.
MERT
An acoustic music understanding model with large-scale self-supervised training.
Bytes Are All You Need
Performs classification directly on file bytes without decoding.
QLoRA
Tim Dettmers' breakthrough technique enabling 65B LLM fine-tuning on a single 48GB GPU.
LIMA
Meta's 65B LLaMA fine-tuned on just 1,000 curated examples - showing alignment needs less data than believed.
The False Promise of Imitating Proprietary LLMs
Berkeley's critical analysis of open-source imitation of proprietary LLMs.
Sophia
A simple, scalable second-order optimizer with negligible per-step overhead.
DoReMi
Optimizes data mixtures for faster language model pretraining.
CodeT5+
An open code LLM family for code understanding and generation.
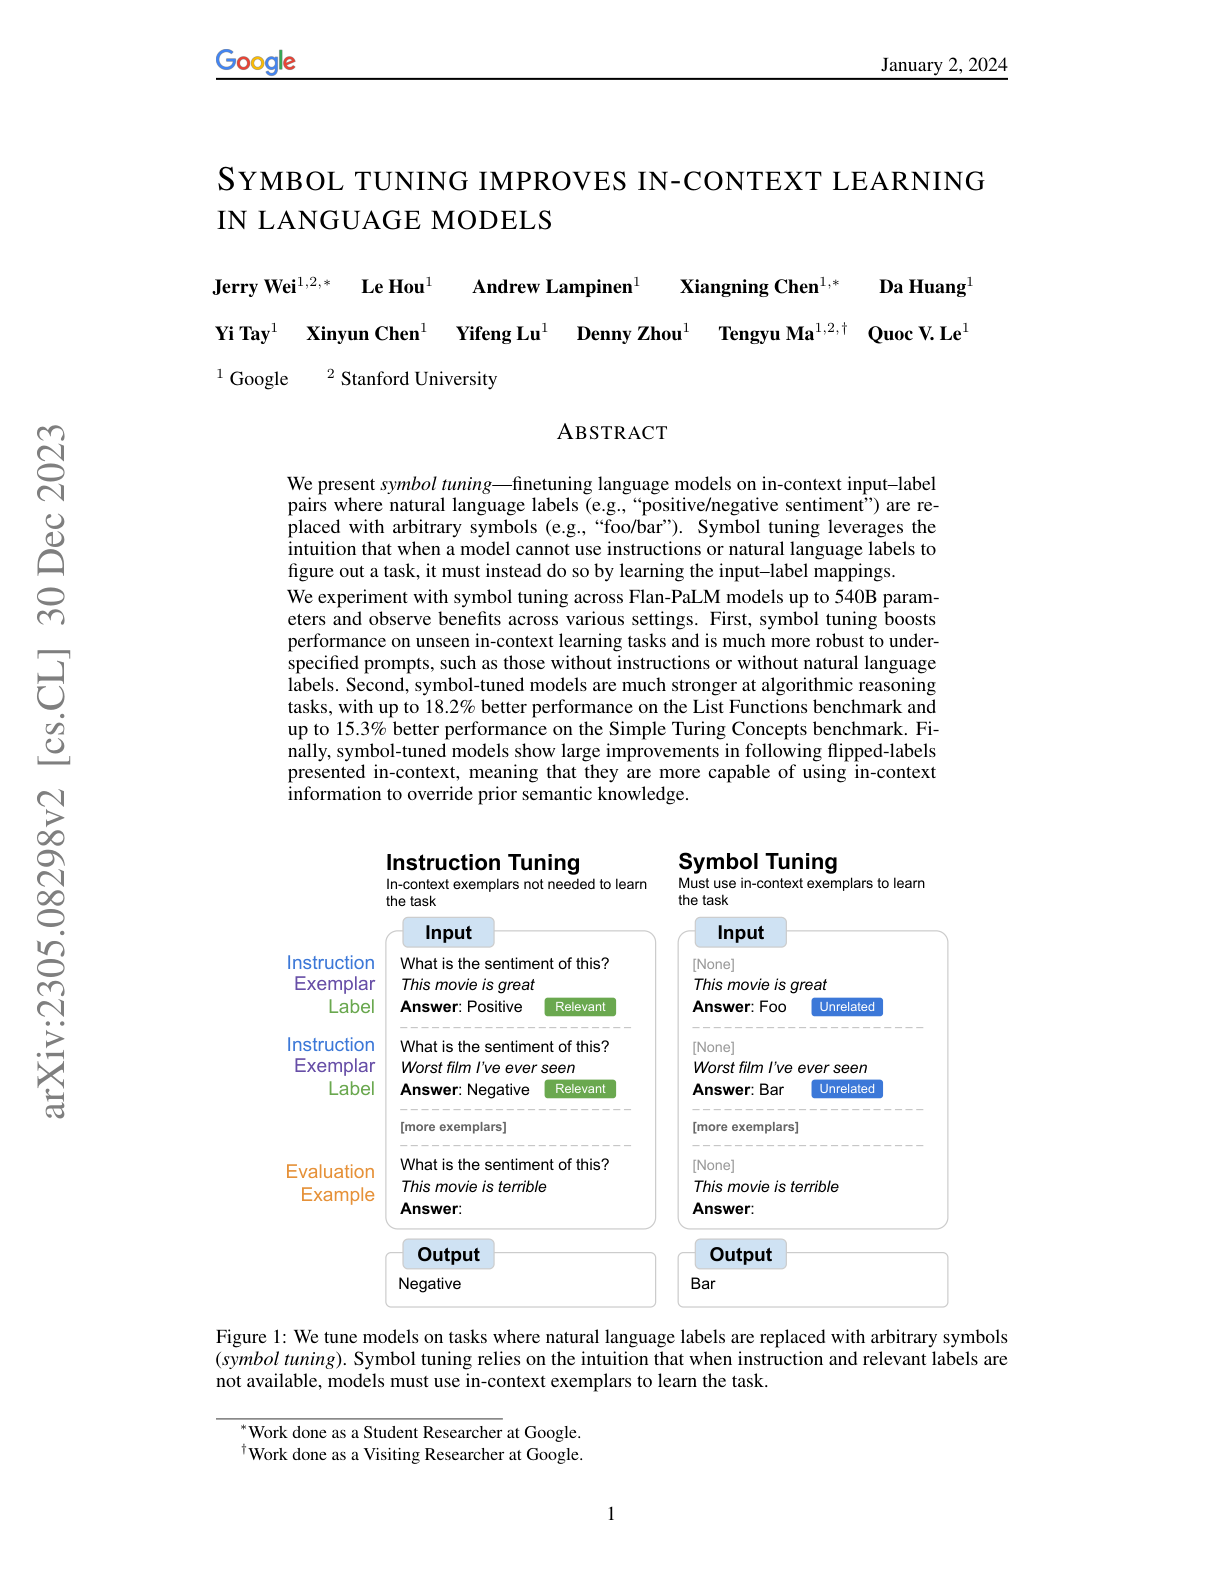
Symbol tuning
Fine-tunes LMs on in-context input-label pairs with natural-language labels replaced by arbitrary symbols.
Incidental Bilingualism in PaLM's Translation Capability
Explores where PaLM's translation ability actually comes from.
InstructBLIP
Visual-language instruction tuning built on BLIP-2.
scGPT
A foundation model for single-cell multi-omics pretrained on 10 million cells.
PMC-LLaMA
A LLaMA model fine-tuned on 4.8 million medical papers.
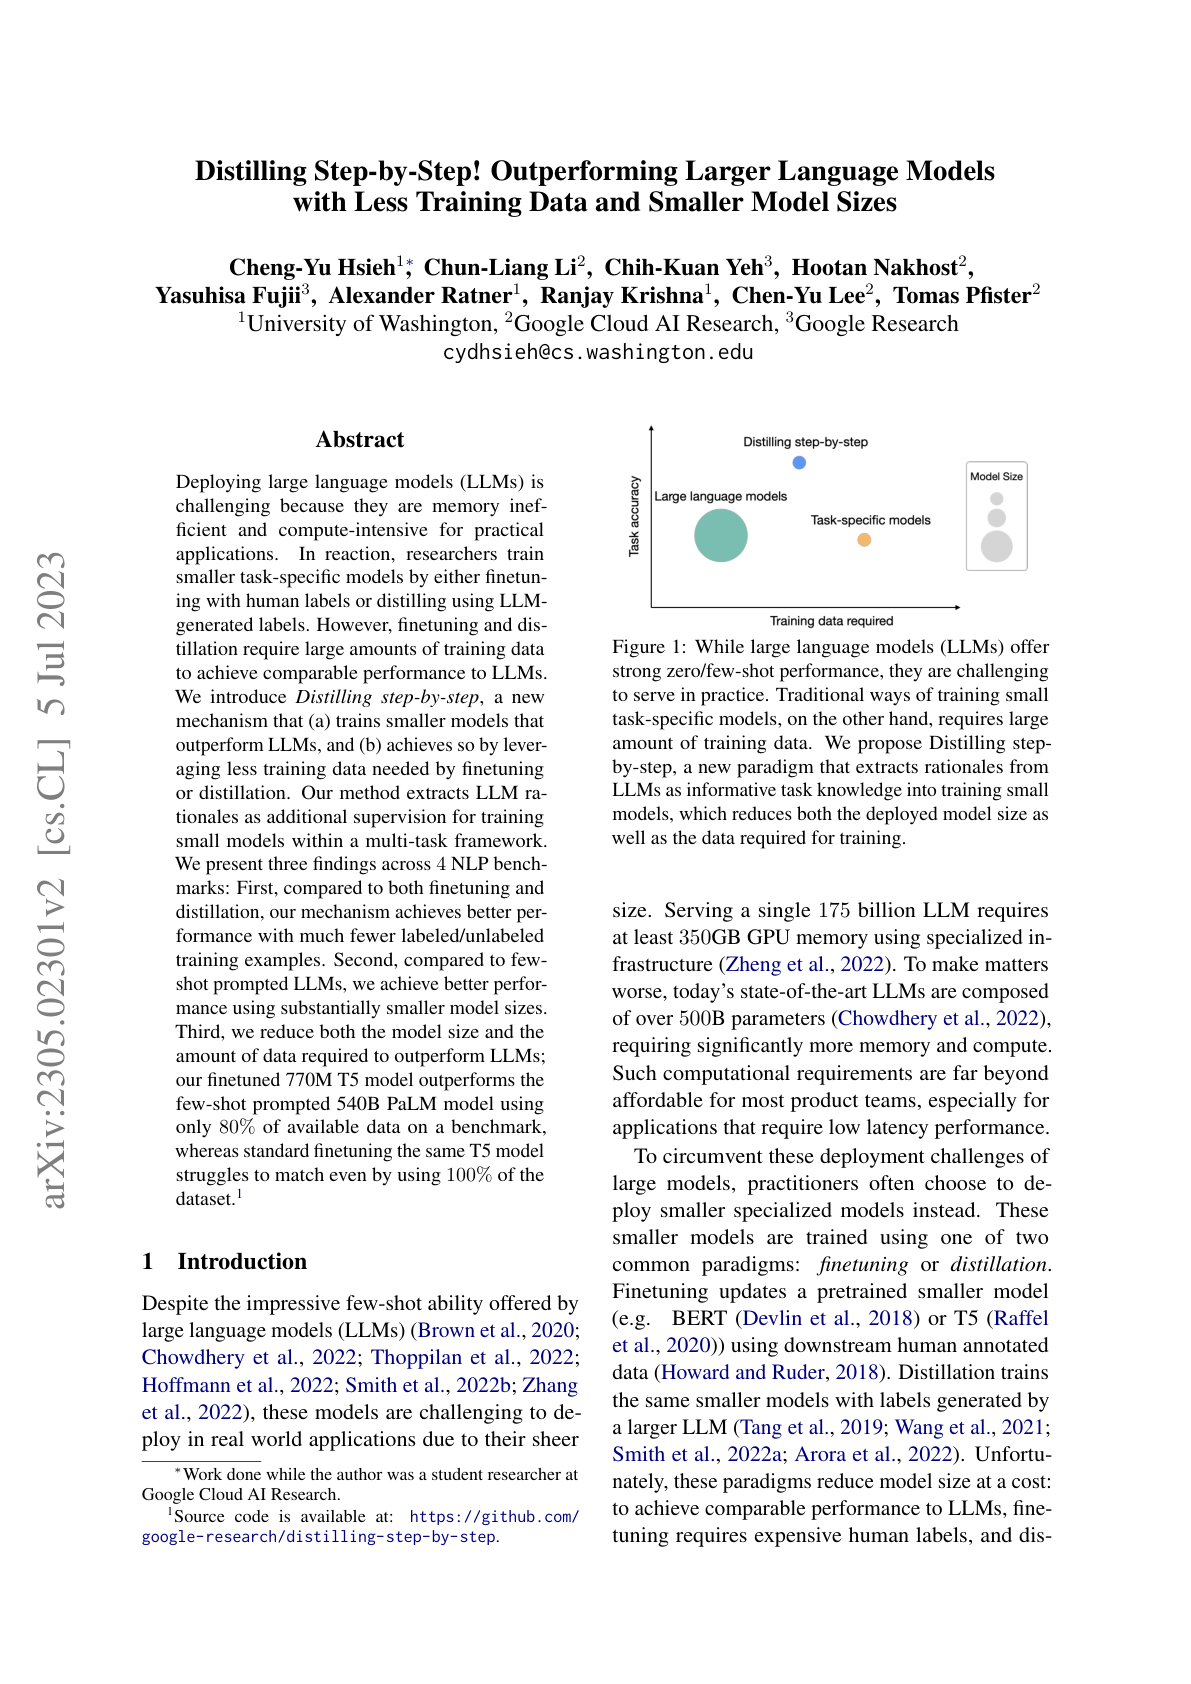
Distilling Step-by-Step!
A mechanism to train smaller models that outperform larger LLMs using fewer examples.
Poisoning Language Models During Instruction Tuning
Shows adversaries can poison LLMs via instruction tuning data.
A Cookbook of Self-Supervised Learning
A comprehensive overview of SSL techniques and practical considerations.
Stable and Low-Precision Training for Large-Scale Vision-Language Models
Methods for accelerating and stabilizing large VLM training.
DINOv2
Meta's self-supervised vision foundation model producing robust features without labels.
Visual Instruction Tuning (LLaVA)
Uses language-only GPT-4 to generate multimodal instruction-following data.
ChatGPT: Applications, Opportunities, and Threats
A comprehensive overview of ChatGPT's applications and risks.
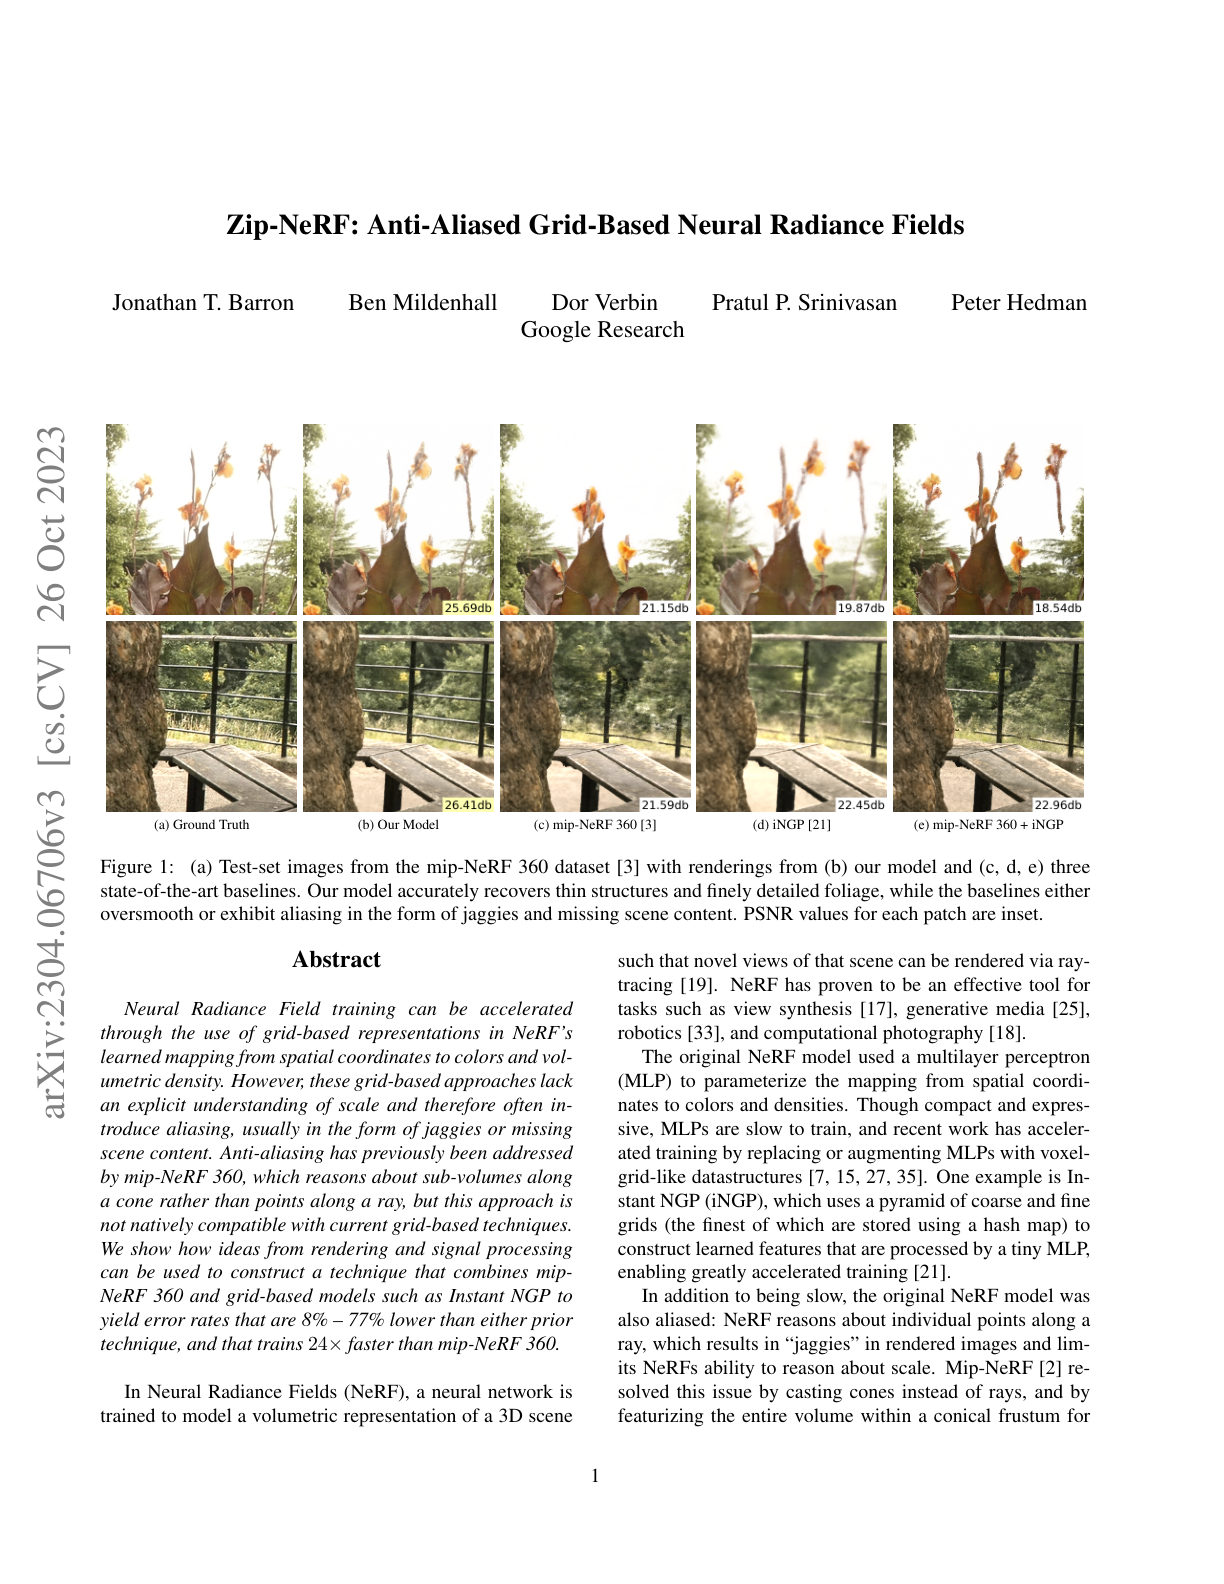
Zip-NeRF: Anti-Aliased Grid-Based Neural Radiance Fields
Combines mip-NeRF 360 with grid-based models for 22x faster training.