AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
AnomalyGPT
Applies large vision-language models to industrial anomaly detection with synthetic data augmentation.
LegalBench
A collaboratively constructed benchmark for measuring legal reasoning in LLMs.
Platypus
Platypus is a family of fine-tuned and merged LLMs that topped the Open LLM Leaderboard in August 2023.
Model Compression for LLMs Survey
A survey of recent model-compression techniques applied specifically to LLMs.
GEARS
Stanford's GEARS predicts cellular responses to genetic perturbation using deep learning + a gene-relationship knowledge graph.
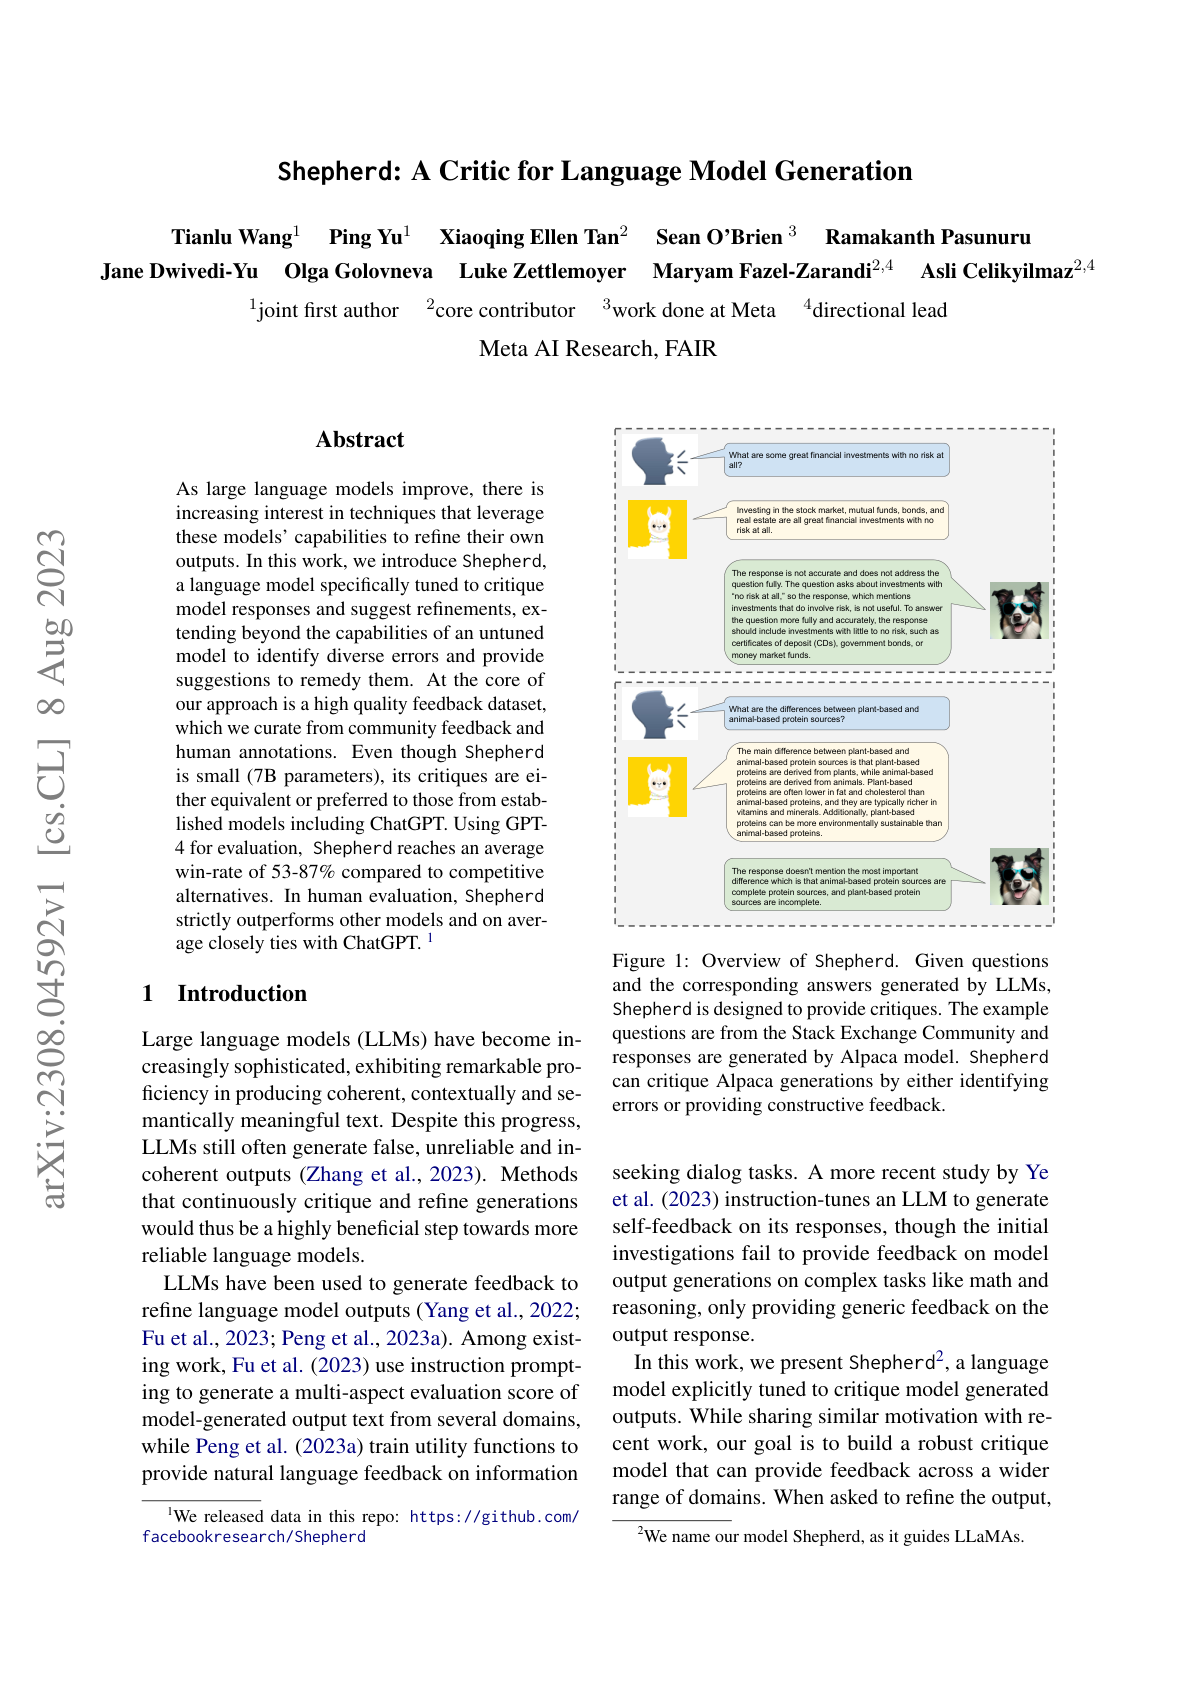
Shepherd
Meta's Shepherd is a 7B language model specifically tuned to critique model outputs and suggest refinements.
Political Biases in NLP Models
Develops methods to measure political and media biases in LLMs and their downstream effects.
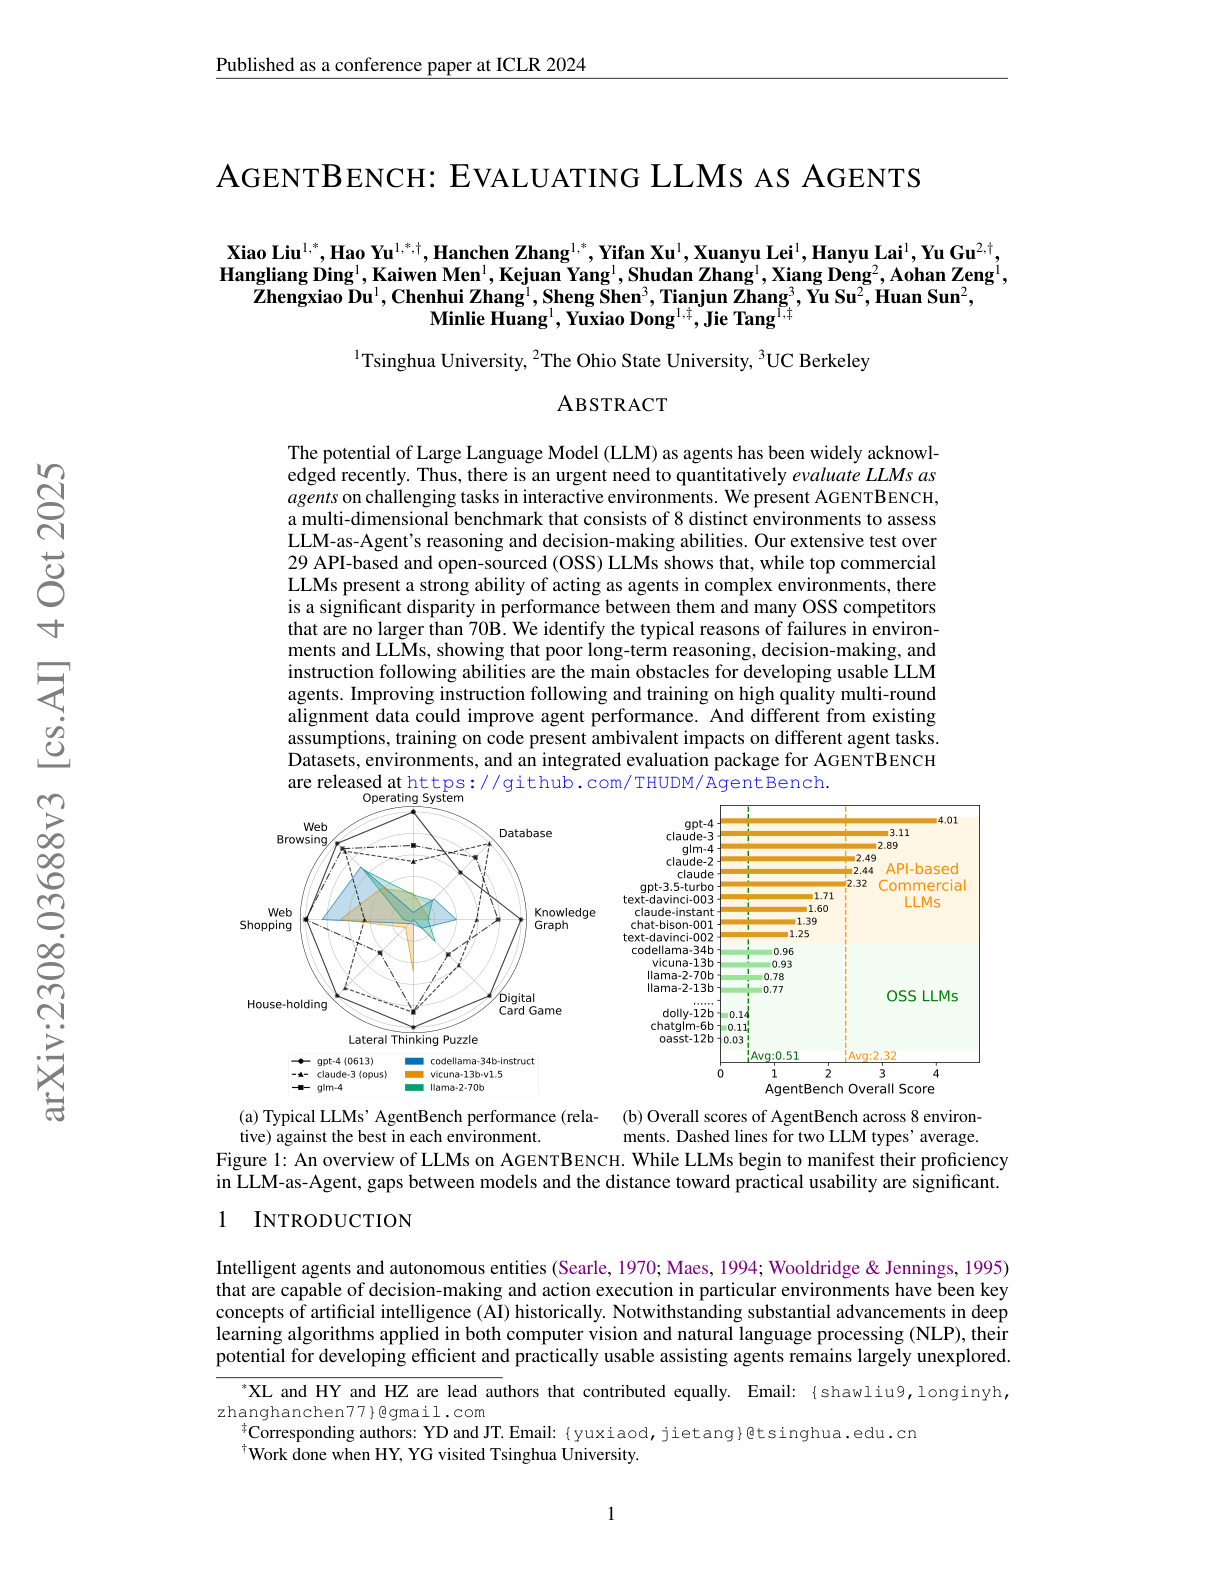
AgentBench
Tsinghua's AgentBench is a multidimensional benchmark for LLM-as-Agent reasoning and decision-making across 8 environments.
Trustworthy LLMs
Presents a comprehensive framework of categories for assessing LLM trustworthiness.
ToolLLM
Tsinghua's ToolLLM enables LLMs to interact with 16,000+ real-world APIs through a comprehensive framework for tool-using LLMs.
Self-Check
Explores LLM capacity for self-checking on complex reasoning tasks requiring multi-step and non-linear thinking.
Med-PaLM Multimodal
Introduces a generalist biomedical AI system and a new multimodal biomedical benchmark with 14 tasks.
L-Eval
A standardized evaluation suite for long-context language models.
FacTool
A task- and domain-agnostic framework for factuality detection of LLM-generated text.
How is ChatGPT's Behavior Changing Over Time?
Evaluates GPT-3.5 and GPT-4 over months to show significant behavioral drift in deployed systems.
FLASK
Proposes fine-grained evaluation of LLMs decomposed into 12 alignment skill sets.
Claude 2
Anthropic's second-generation LLM with a detailed model card on safety, alignment, and capabilities.
LLMs as General Pattern Machines
Demonstrates LLMs serve as general sequence modelers without additional training.
A Survey on Evaluation of LLMs
A comprehensive overview of evaluation methods covering what, where, and how to evaluate LLMs.
InterCode
A framework treating interactive coding as a reinforcement learning environment.
LeanDojo
An open-source Lean playground consisting of toolkits, data, models, and benchmarks for theorem proving.
Generative AI for Programming Education
Evaluates GPT-4 and ChatGPT on programming education scenarios versus human tutors.
Understanding Theory-of-Mind in LLMs with LLMs
A framework for procedurally generating ToM evaluations using LLMs themselves.
Evaluations with No Labels
Self-supervised evaluation of LLMs via sensitivity/invariance to input transformations.