AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
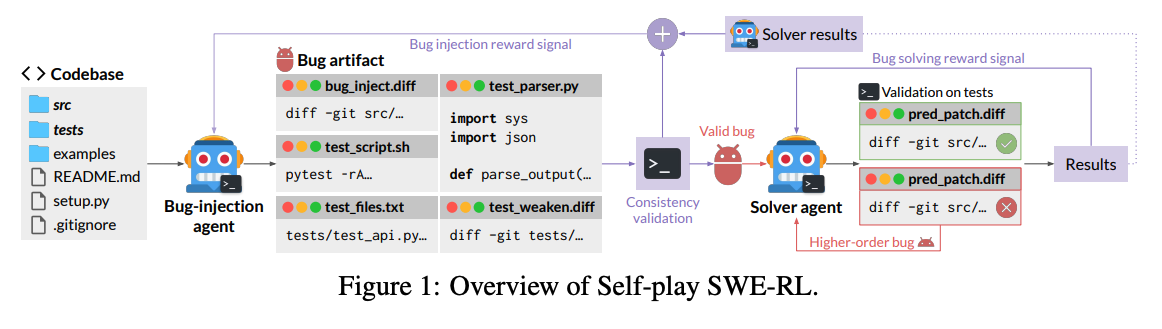
Self-Play SWE-RL
Self-Play SWE-RL (SSR) trains software engineering agents through self-play, requiring only access to sandboxed repositories with no human-labeled issues or tests. A single LLM learns to both inject and repair bugs of increasing complexity, achieving +10.4 points on SWE-bench Verified while consistently outperforming human-data baselines.
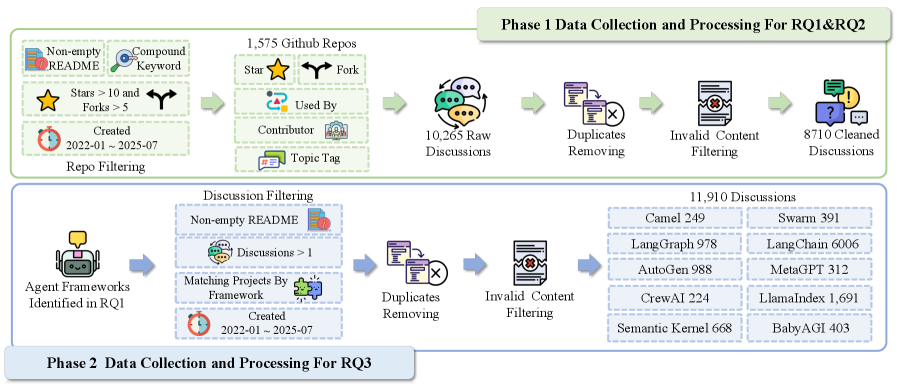
Empirical Study of Agent Developer Practices
This paper presents the first large-scale empirical study of LLM-based agent frameworks, analyzing 11,910 developer discussions across ten popular frameworks. The research identifies practical challenges developers face and evaluates how well current frameworks meet their needs.
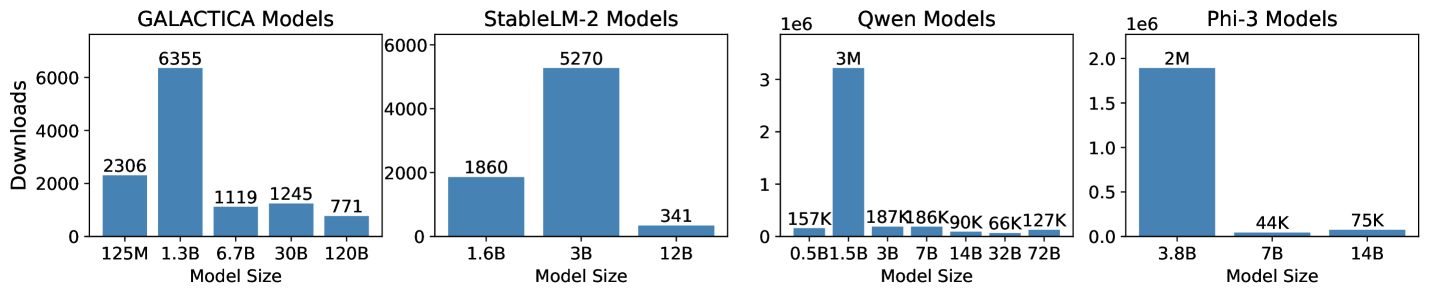
Comprehensive Survey of Small Language Models
This survey provides a comprehensive overview of Small Language Models (SLMs), which address key LLM limitations, including high computational demands, privacy concerns from cloud APIs, and poor performance on edge devices. The authors propose a standardized SLM definition based on specialized task capability and resource-constrained suitability, and develop taxonomies and frameworks for SLM acquisition, enhancement, application, and reliability.
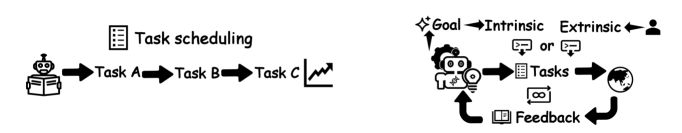
Sophia
Sophia introduces System 3, a meta-layer beyond traditional dual-process theory that enables LLM agents to maintain persistent identity and align short-term actions with long-term goals. The framework achieves 80% reduction in reasoning steps for recurring operations and 40% performance improvement on high-complexity tasks.
SonicMoE
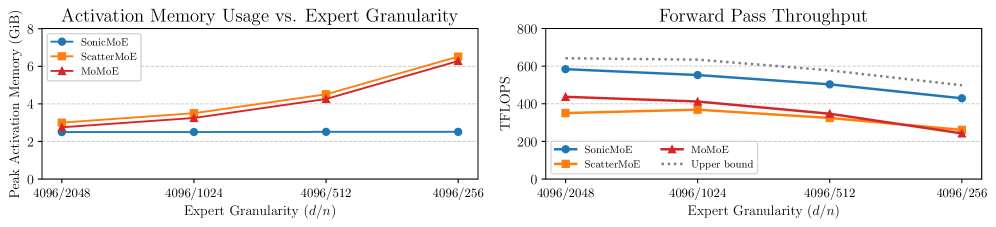
SonicMoE addresses performance bottlenecks in Mixture of Experts models through IO-aware and tile-aware optimizations. The approach achieves 1.86x compute throughput improvement on Hopper GPUs, reduces activation memory by 45%, and enables training 213 billion tokens per day on 64 H100 GPUs for a 7B model.
Detailed Balance in LLM Agents
Researchers establish the first macroscopic physical law in LLM generation dynamics by applying the least action principle to analyze LLM-agent behavior. They discover statistical evidence of detailed balance in state transitions, suggesting LLMs implicitly learn underlying potential functions rather than explicit rules.
Budget Aware Test-time Scaling
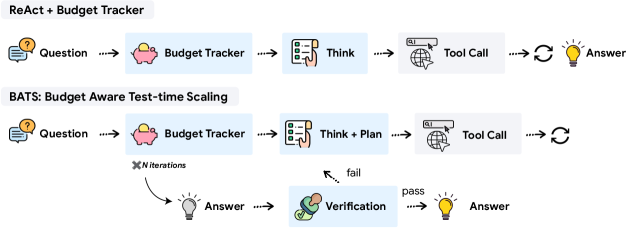
Researchers discover that simply expanding tool-call budgets without proper awareness fails to improve agent performance. They introduce BATS (Budget Aware Test-time Scaling), a framework that makes web search agents budget-aware, enabling more strategic resource allocation and pushing the cost-performance Pareto frontier.
DeepCode
DeepCode is a fully autonomous framework for synthesizing complete codebases from scientific papers despite LLM context limitations. It treats repository synthesis as a channel optimization problem, achieving state-of-the-art on PaperBench and outperforming commercial tools like Cursor and Claude Code.
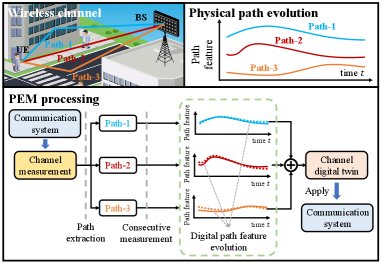
FrontierScience
OpenAI introduced FrontierScience, a new benchmark measuring AI capabilities for expert-level scientific reasoning across physics, chemistry, and biology. The benchmark consists of over 700 questions created and verified by domain experts, including international olympiad medalists and PhD scientists.
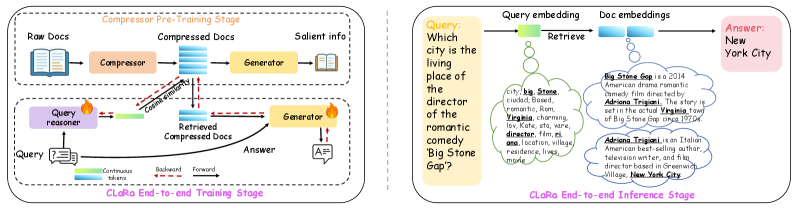
CLaRa
CLaRa introduces a unified framework for retrieval-augmented generation that performs embedding-based compression and joint optimization in a shared continuous space. The approach addresses key RAG limitations around long contexts and disjoint retrieval-generation optimization.
FACTS Leaderboard
Google introduces the FACTS Leaderboard, a comprehensive benchmark suite for evaluating LLM factuality across diverse scenarios. The leaderboard aggregates performance across four specialized sub-benchmarks to provide a holistic measure of how accurately models generate factual text.
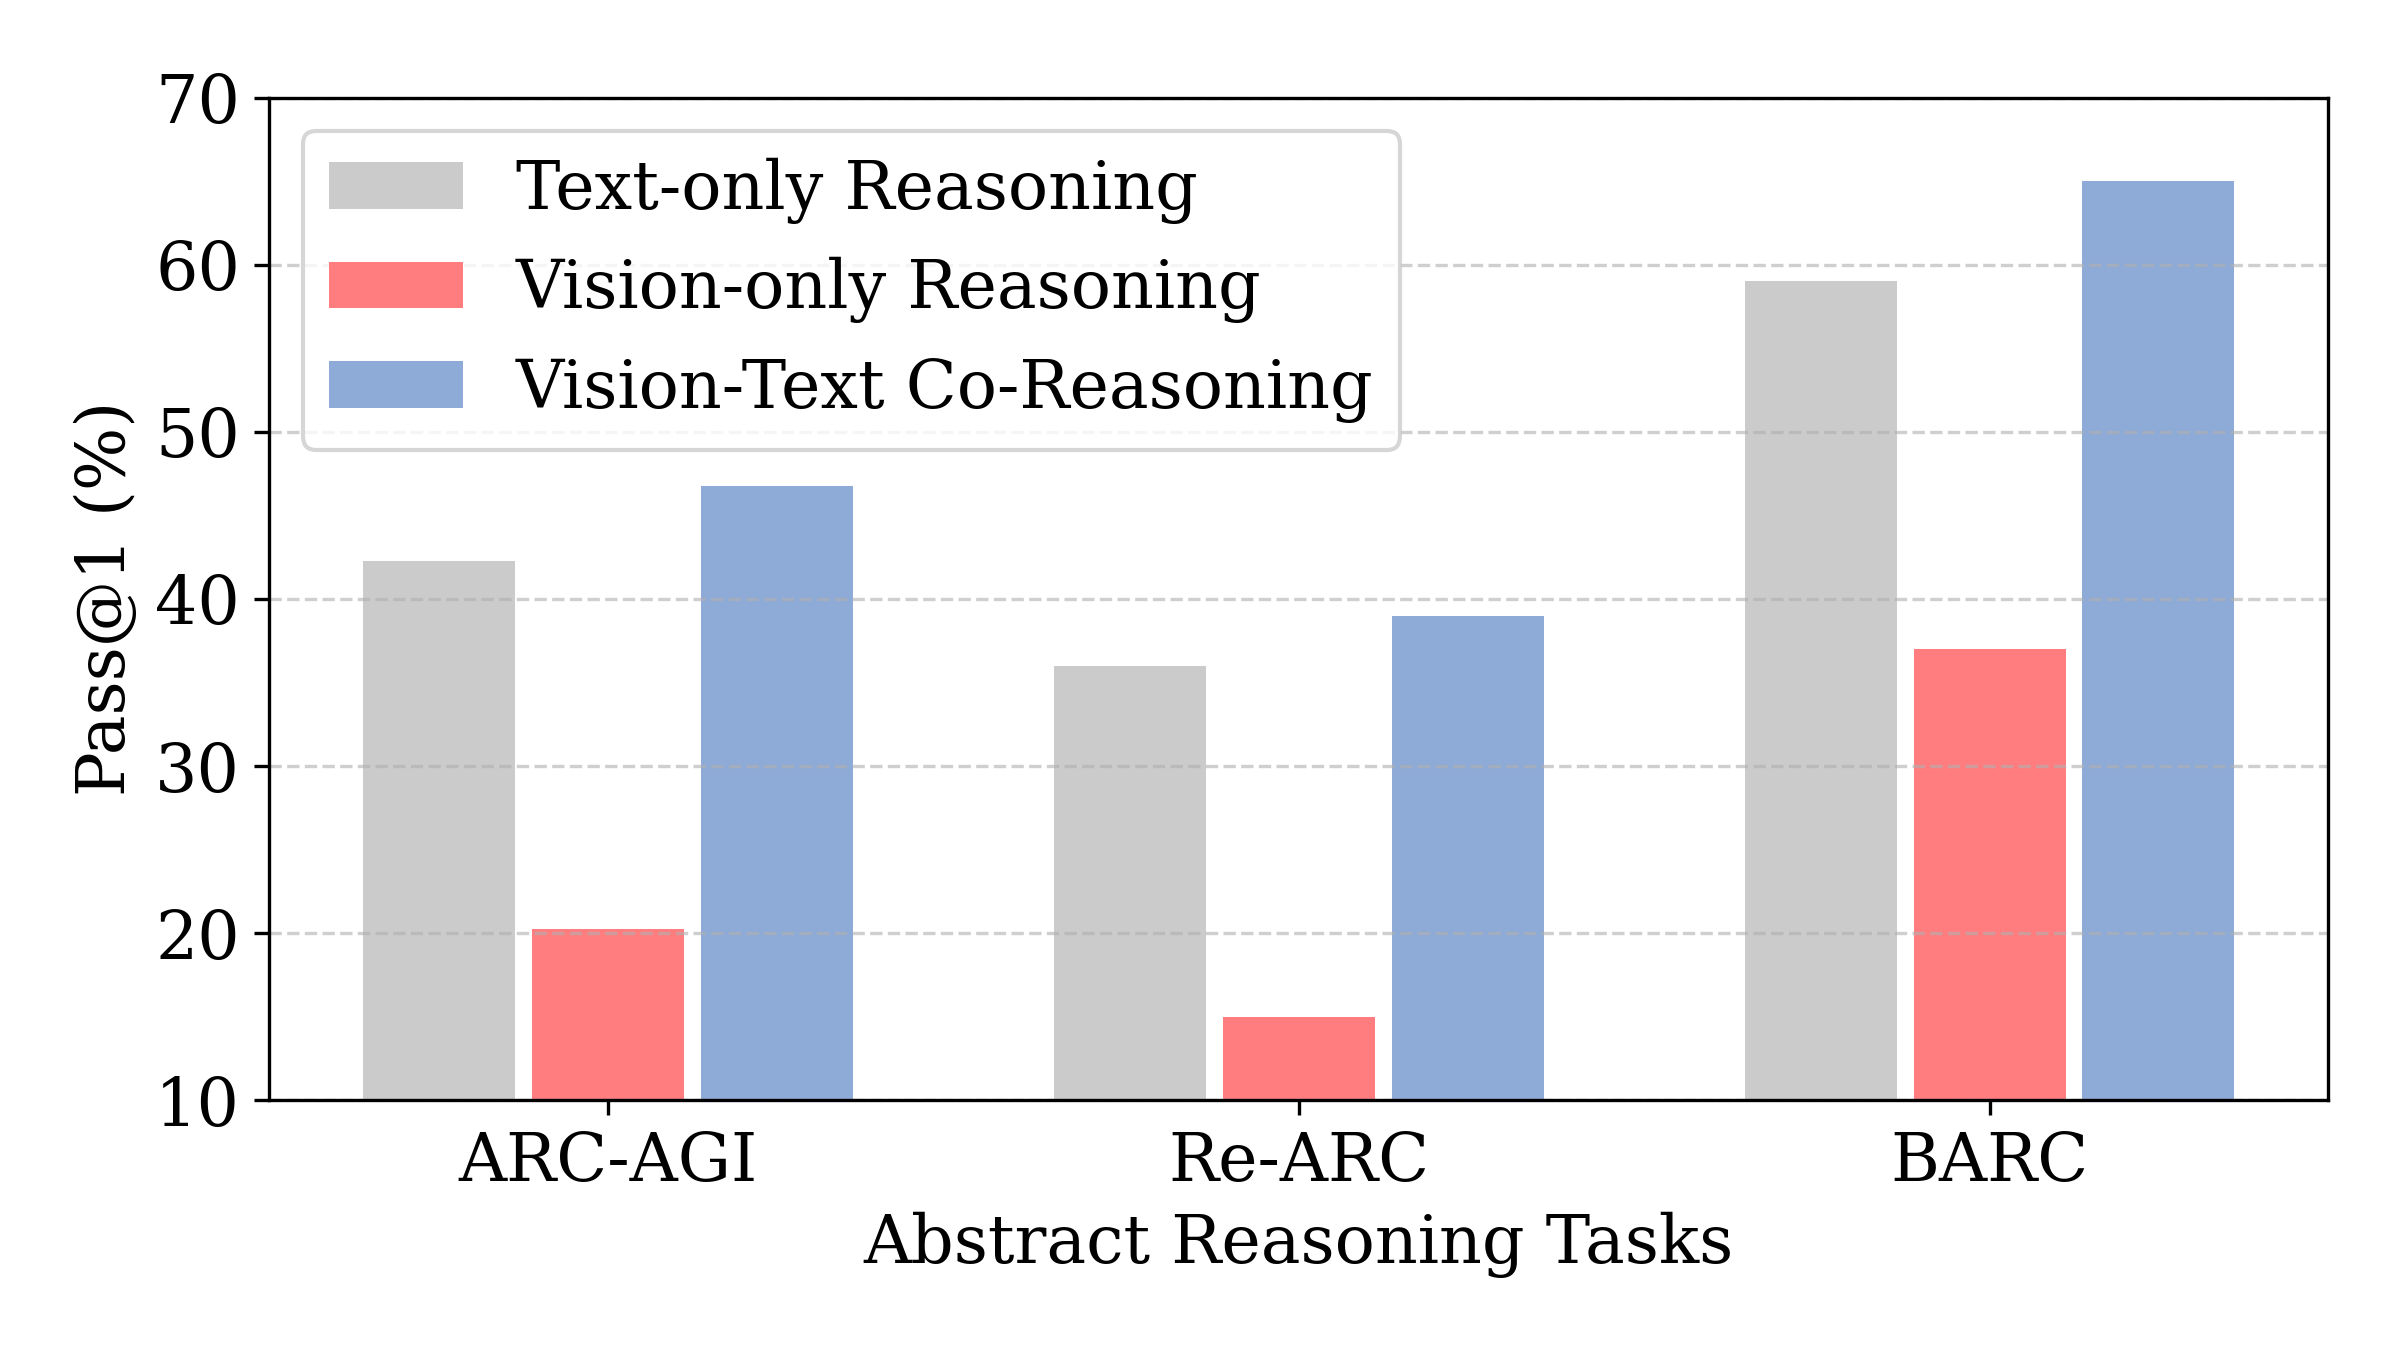
Vision-Language Synergy Reasoning
Researchers propose Vision-Language Synergy Reasoning (VLSR), a method that combines visual and textual reasoning to improve performance on ARC-AGI abstract reasoning tasks. The key insight is that vision excels at global pattern abstraction while language specializes in symbolic rule formulation.
SHARP
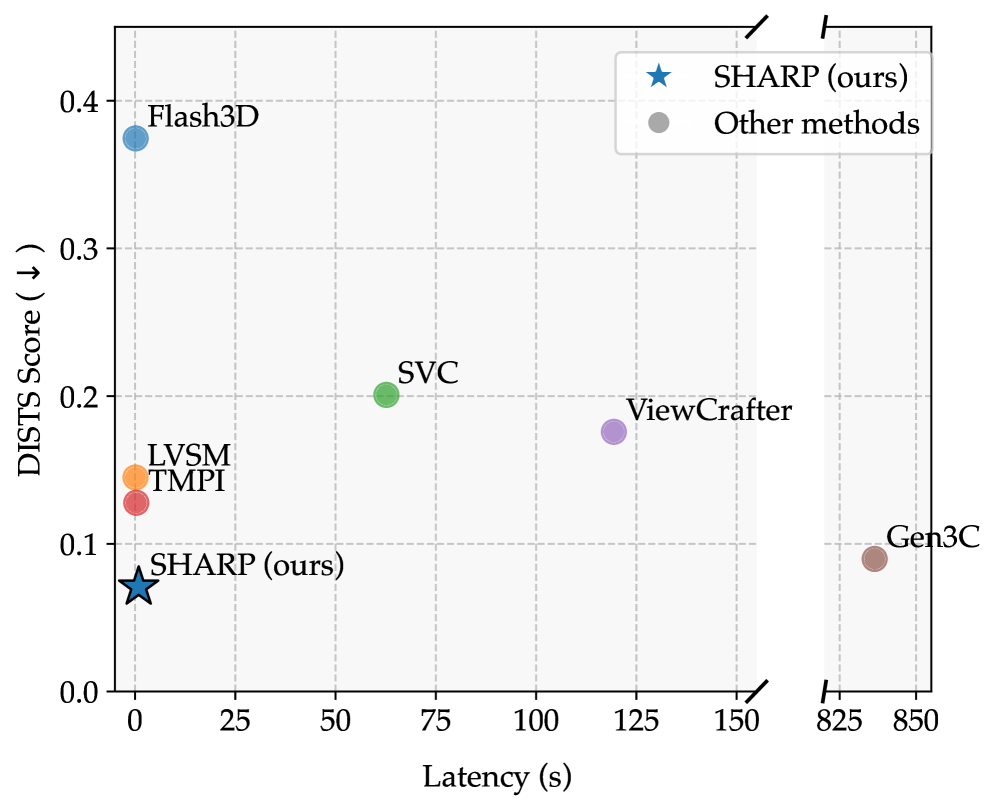
SHARP generates photorealistic novel viewpoints from a single photograph in under one second on standard GPU hardware. The neural network produces a 3D Gaussian representation in a single feedforward pass, enabling real-time rendering for nearby viewing angles. It reduces LPIPS by 25-34% and achieves three orders of magnitude faster synthesis than prior approaches with strong zero-shot generalization.
ARTEMIS
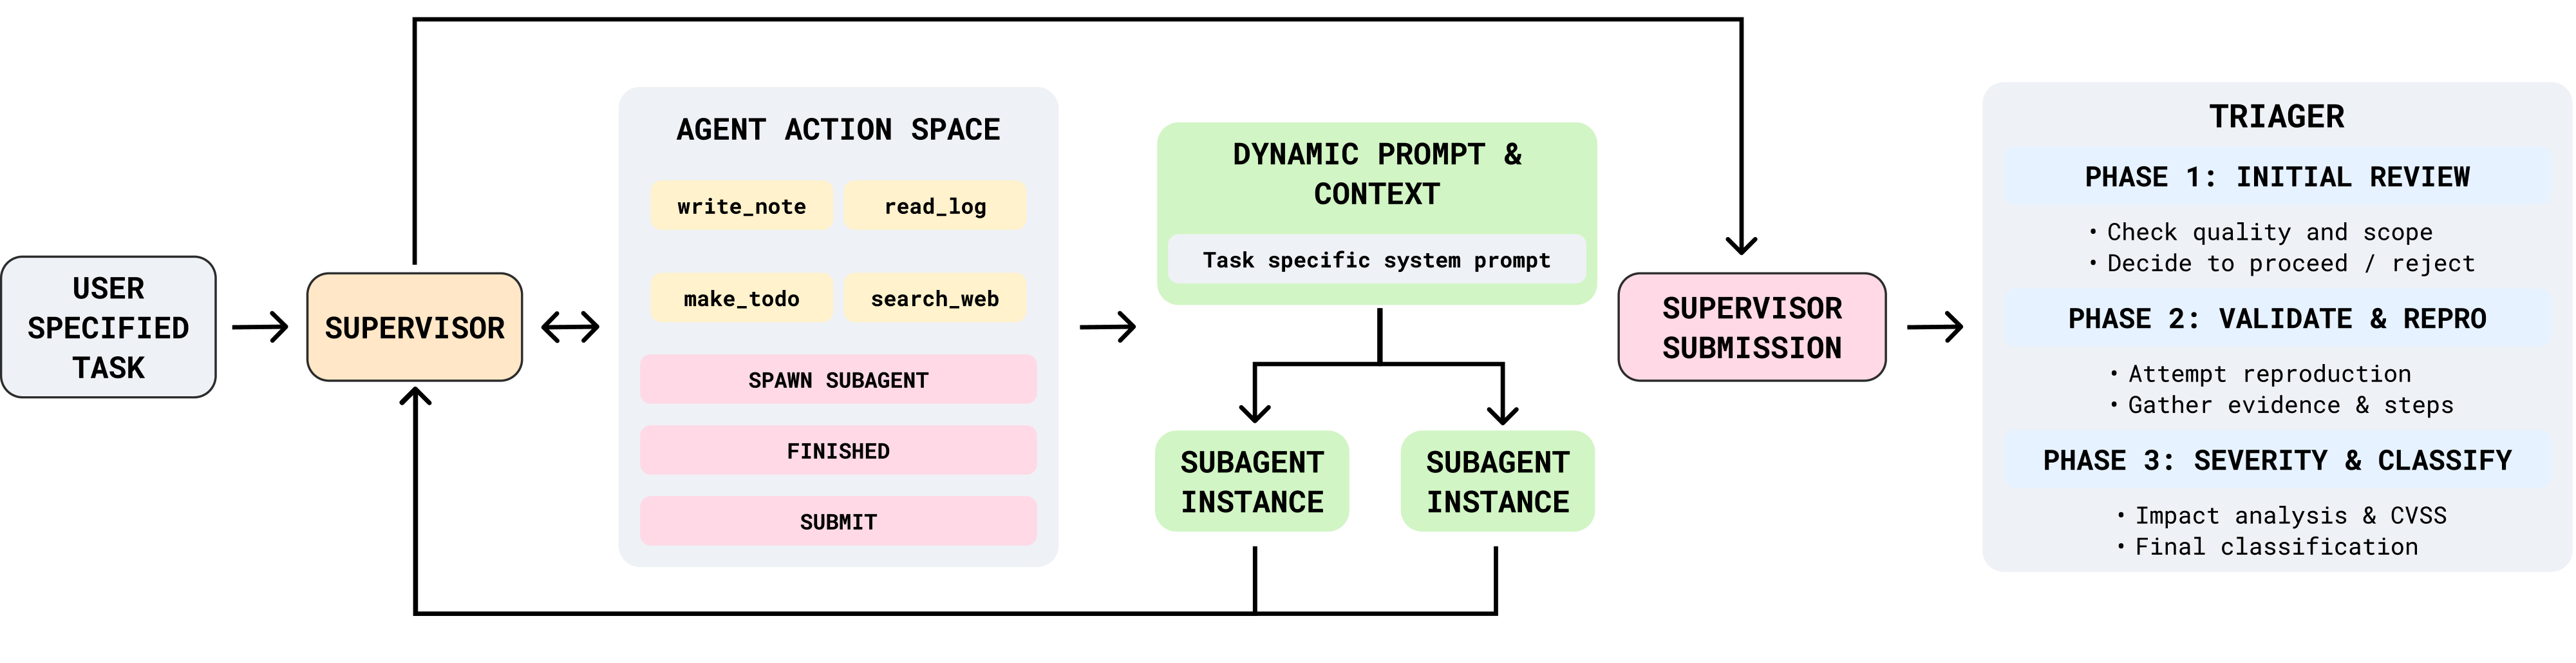
Stanford researchers conducted the first head-to-head evaluation of AI agents against human cybersecurity professionals on a live enterprise network with approximately 8,000 hosts. Their multi-agent framework ARTEMIS placed second overall, discovering 9 valid vulnerabilities with 82% accuracy and outperforming 9 of 10 human testers at a fraction of the cost (18 dollars per hour vs 60 dollars per hour for professionals).
Stronger Normalization-Free Transformers
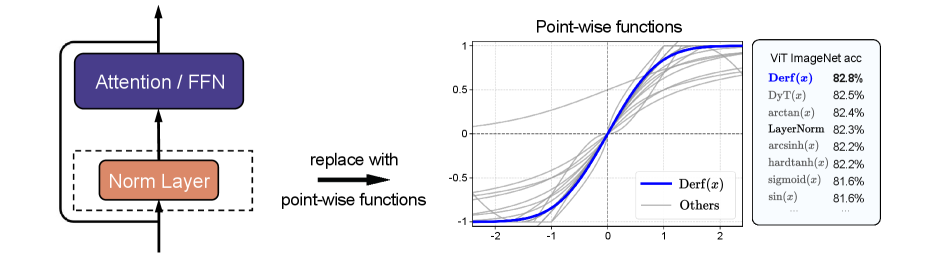
Researchers introduce Derf, a simple point-wise function that replaces normalization layers in Transformers. Based on the rescaled Gaussian cumulative distribution function, Derf outperforms LayerNorm, RMSNorm, and Dynamic Tanh across vision, speech, and DNA sequence modeling tasks with improved generalization rather than stronger fitting capacity.
Towards a Science of Scaling Agent Systems
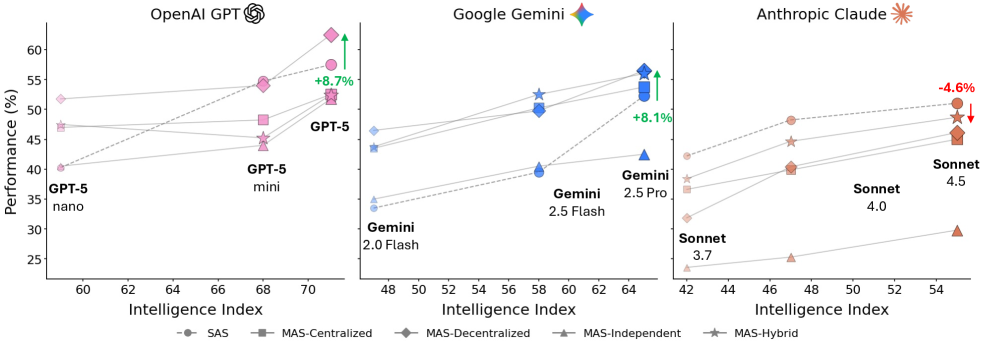
Researchers from Google present a controlled evaluation framework for agent systems, challenging the assumption that “more agents are all you need.” Across 180 configurations spanning three LLM families and four agentic benchmarks, the study establishes quantitative principles for when multi-agent coordination helps versus hurts performance.
GigaTIME
Microsoft Research and Providence Health introduce GigaTIME, a multimodal AI framework that generates virtual multiplex immunofluorescence (mIF) images from standard H&E pathology slides, enabling population-scale tumor immune microenvironment modeling. The system was applied to over 14,000 cancer patients across 24 cancer types, uncovering over 1,200 statistically significant protein-biomarker associations.
Pre-Training, Mid-Training, and RL Interplay
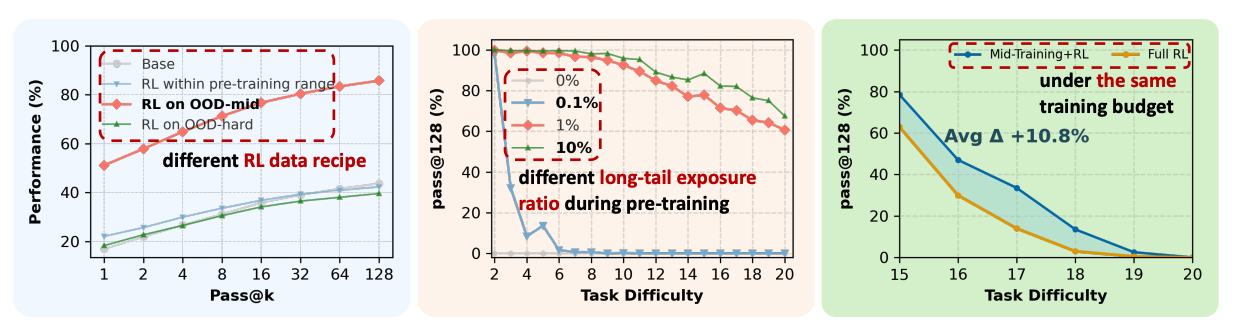
CMU researchers develop a controlled experimental framework using synthetic reasoning tasks to isolate how pre-training, mid-training, and RL-based post-training each contribute to reasoning capabilities in language models. The study reconciles conflicting views on whether RL truly extends reasoning beyond what models learn during pre-training.
Agentic AI Adaptation Survey
Researchers from UIUC, Stanford, Berkeley, and other institutions present the first comprehensive taxonomy of adaptation strategies for agentic AI systems. The survey organizes recent advances into a unified framework covering how agents and their tools can be modified to achieve higher task performance, improved reliability, and better generalization across diverse scenarios.
Reasoning Models Ace the CFA Exams
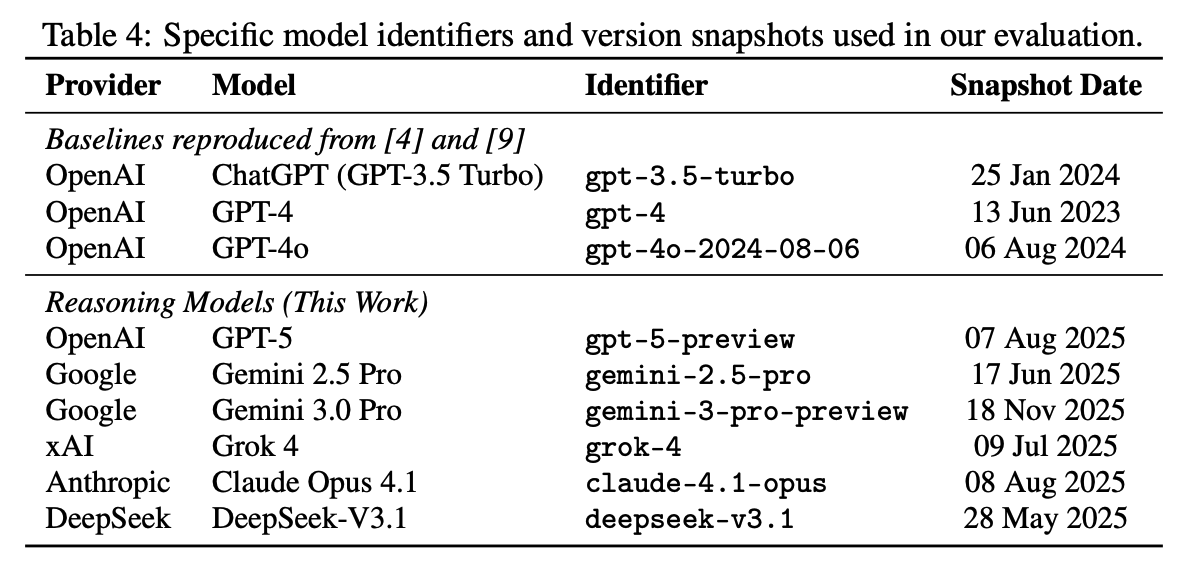
Researchers evaluate state-of-the-art reasoning models on mock CFA exams consisting of 980 questions across all three certification levels. While previous studies reported that LLMs performed poorly on these exams, the latest reasoning models now pass all three levels, with Gemini 3.0 Pro achieving a record 97.6% on Level I.
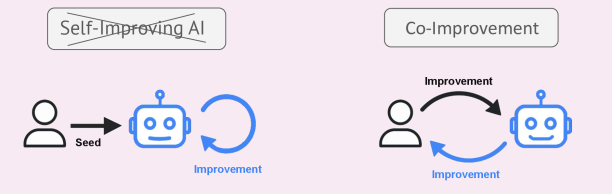
AI and Human Co-Improvement
Meta FAIR researchers Jason Weston and Jakob Foerster argue that fully autonomous self-improving AI is neither the fastest nor safest path to superintelligence. Instead, they advocate for co-improvement: building AI that collaborates with human researchers to conduct AI research together, from ideation to experimentation.
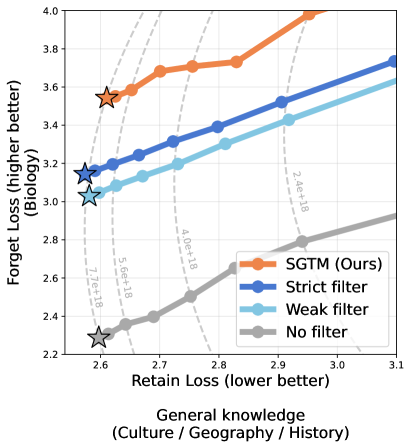
Selective Gradient Masking
Anthropic researchers present Selective Gradient Masking (SGTM), a technique that removes dangerous capabilities like CBRN knowledge from language models during pretraining while preserving general capabilities. Unlike data filtering, SGTM localizes target knowledge into dedicated “forget” parameters that can be zeroed out after training.
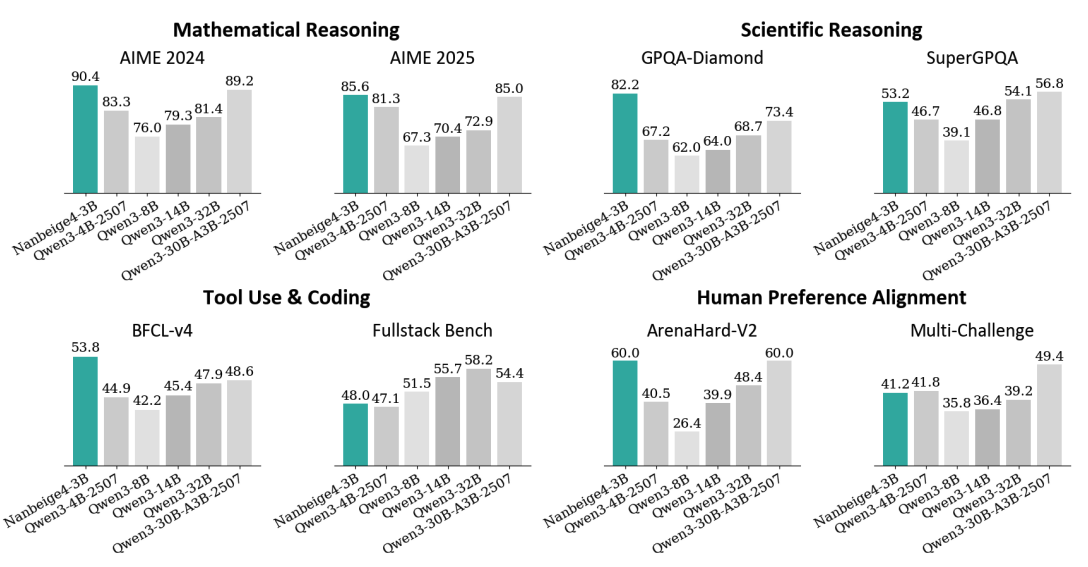
Nanbeige4-3B
Nanbeige4-3B is a 3B parameter model pretrained on 23T tokens and fine-tuned on over 30M instructions using a Fine-Grained Warmup-Stable-Decay scheduler, Dual Preference Distillation, and multi-stage reinforcement learning. Despite its compact size, it outperforms Qwen3-8B and Qwen3-14B on reasoning benchmarks and rivals much larger models on WritingBench, demonstrating that well-engineered small models can match far larger counterparts.
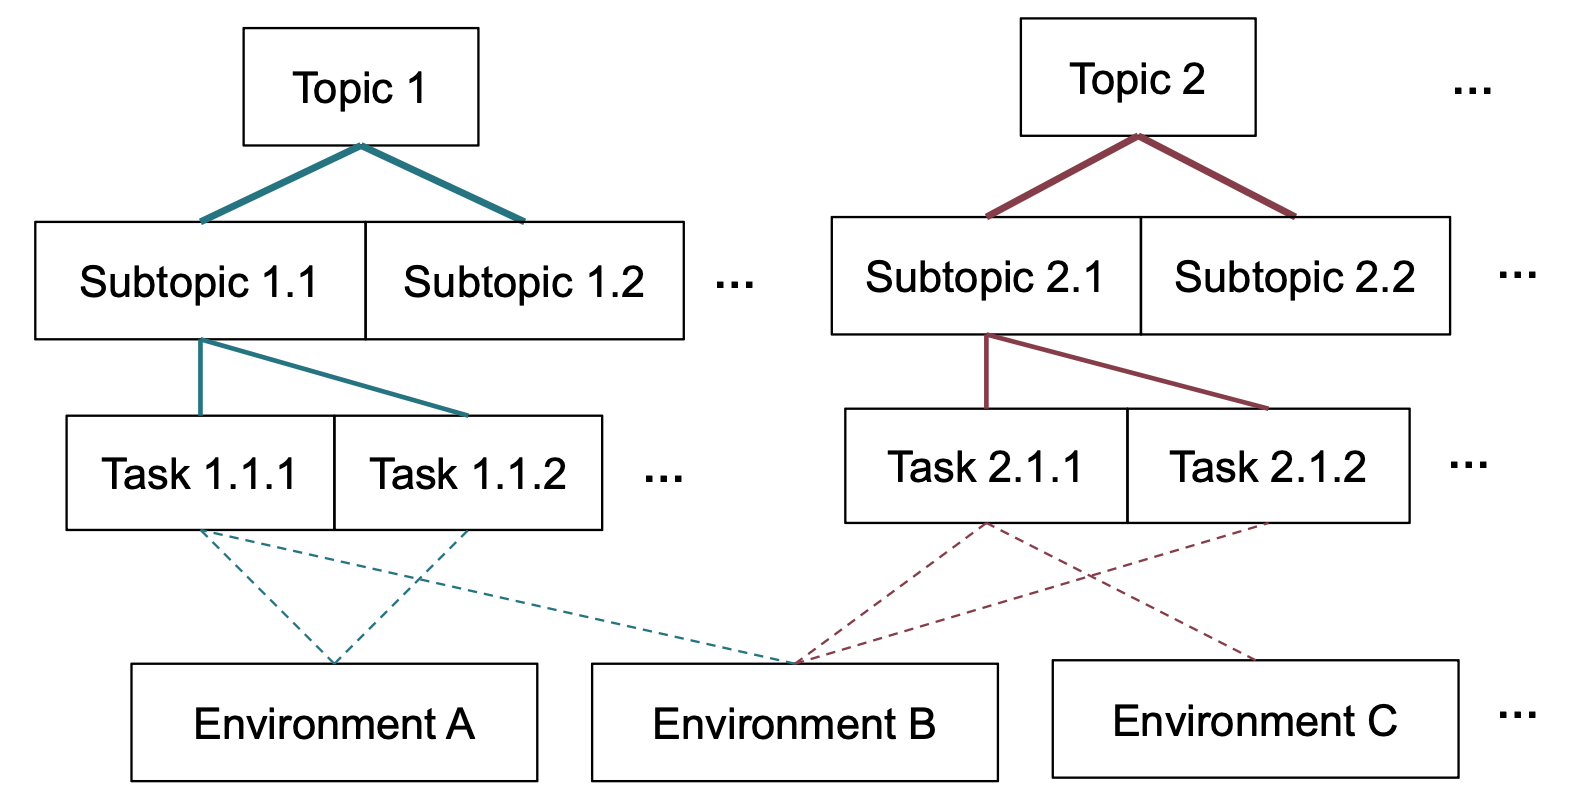
AI Agent Adoption Study
Harvard and Perplexity researchers present the first large-scale field study of AI agent adoption using hundreds of millions of anonymized interactions from Perplexity’s Comet browser. Productivity and Learning account for 57% of agentic queries, with digital technology workers (28% of adopters) and knowledge-intensive sectors leading adoption. Users in higher GDP countries with greater educational attainment are more likely to adopt agents, and over time, users shift from media and travel tasks toward more cognitively oriented topics.