AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
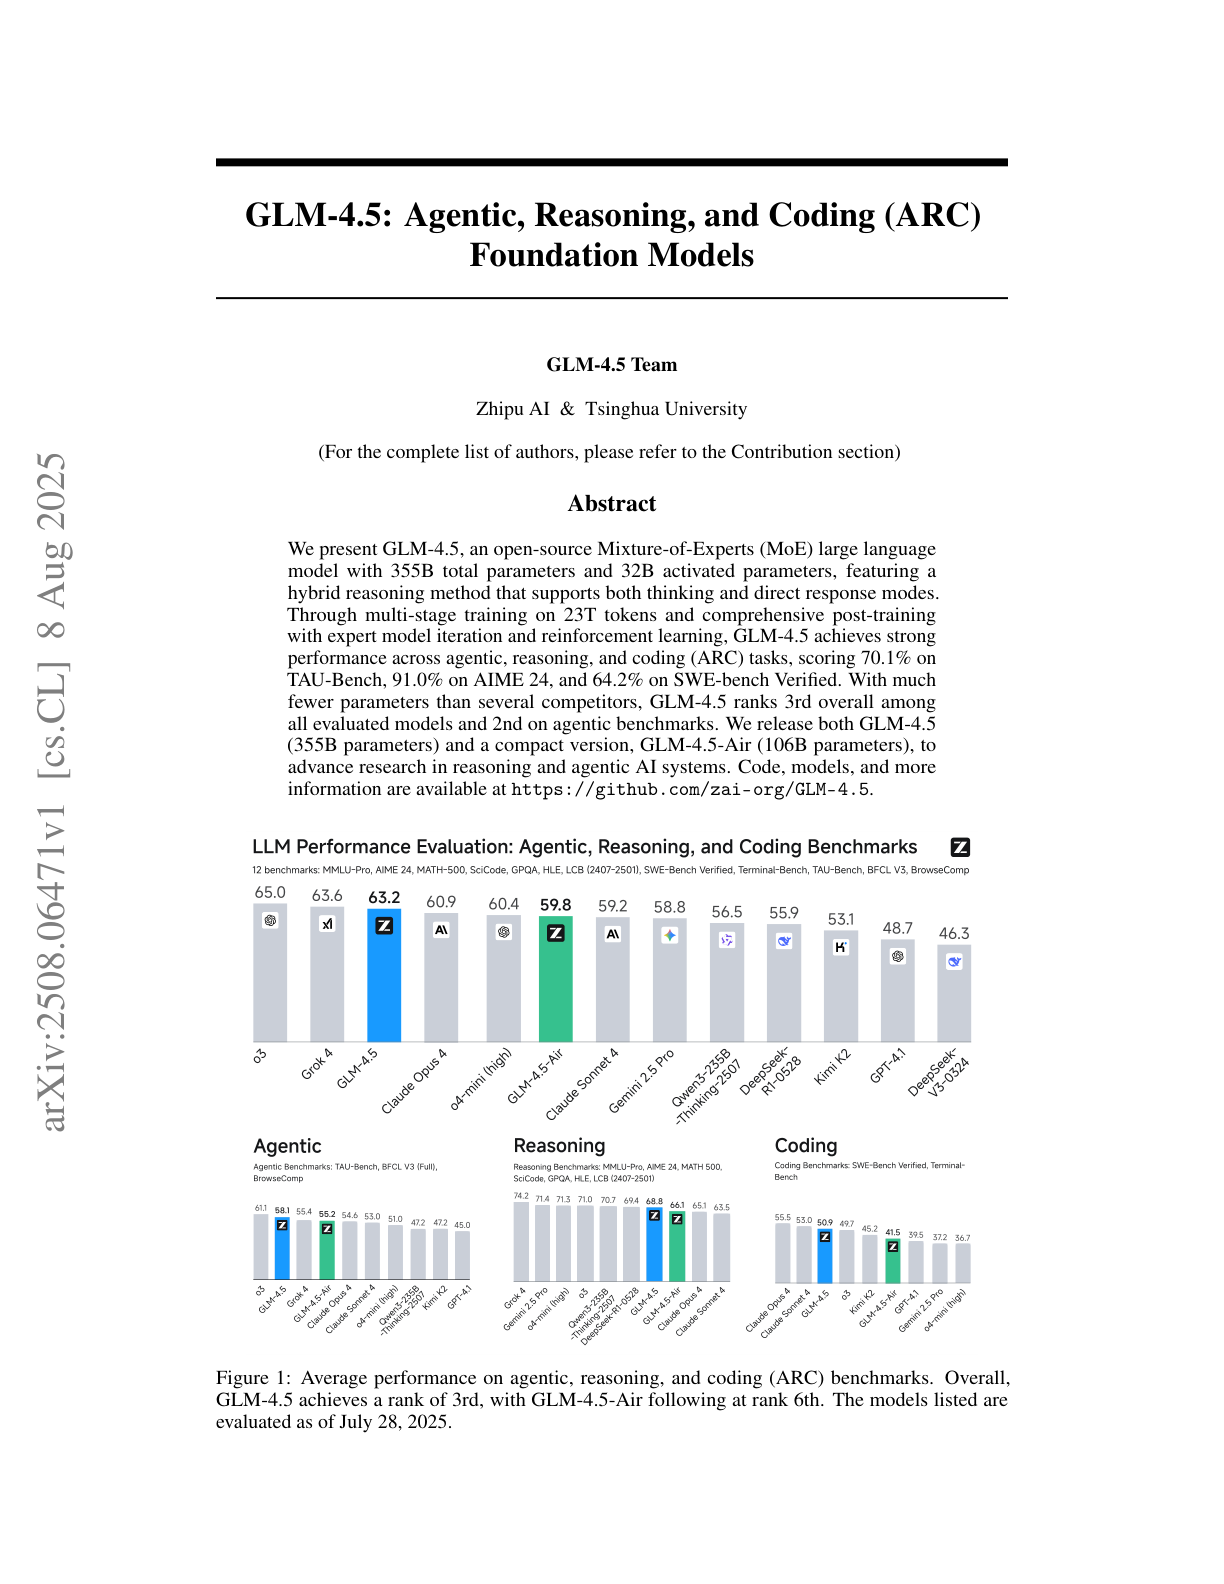
GLM-4.5
An open Mixture‑of‑Experts family that targets a single model excelling across agentic tool use, complex reasoning, and real‑world coding. GLM‑4.5 (355B total, 32B active) introduces hybrid “thinking vs direct” modes, multi‑stage pretrain + mid‑train to 128K context, and extensive RL for reasoning, agents, and instruction following. It ranks near the top on a 12‑bench ARC suite and releases weights and eval tooling.
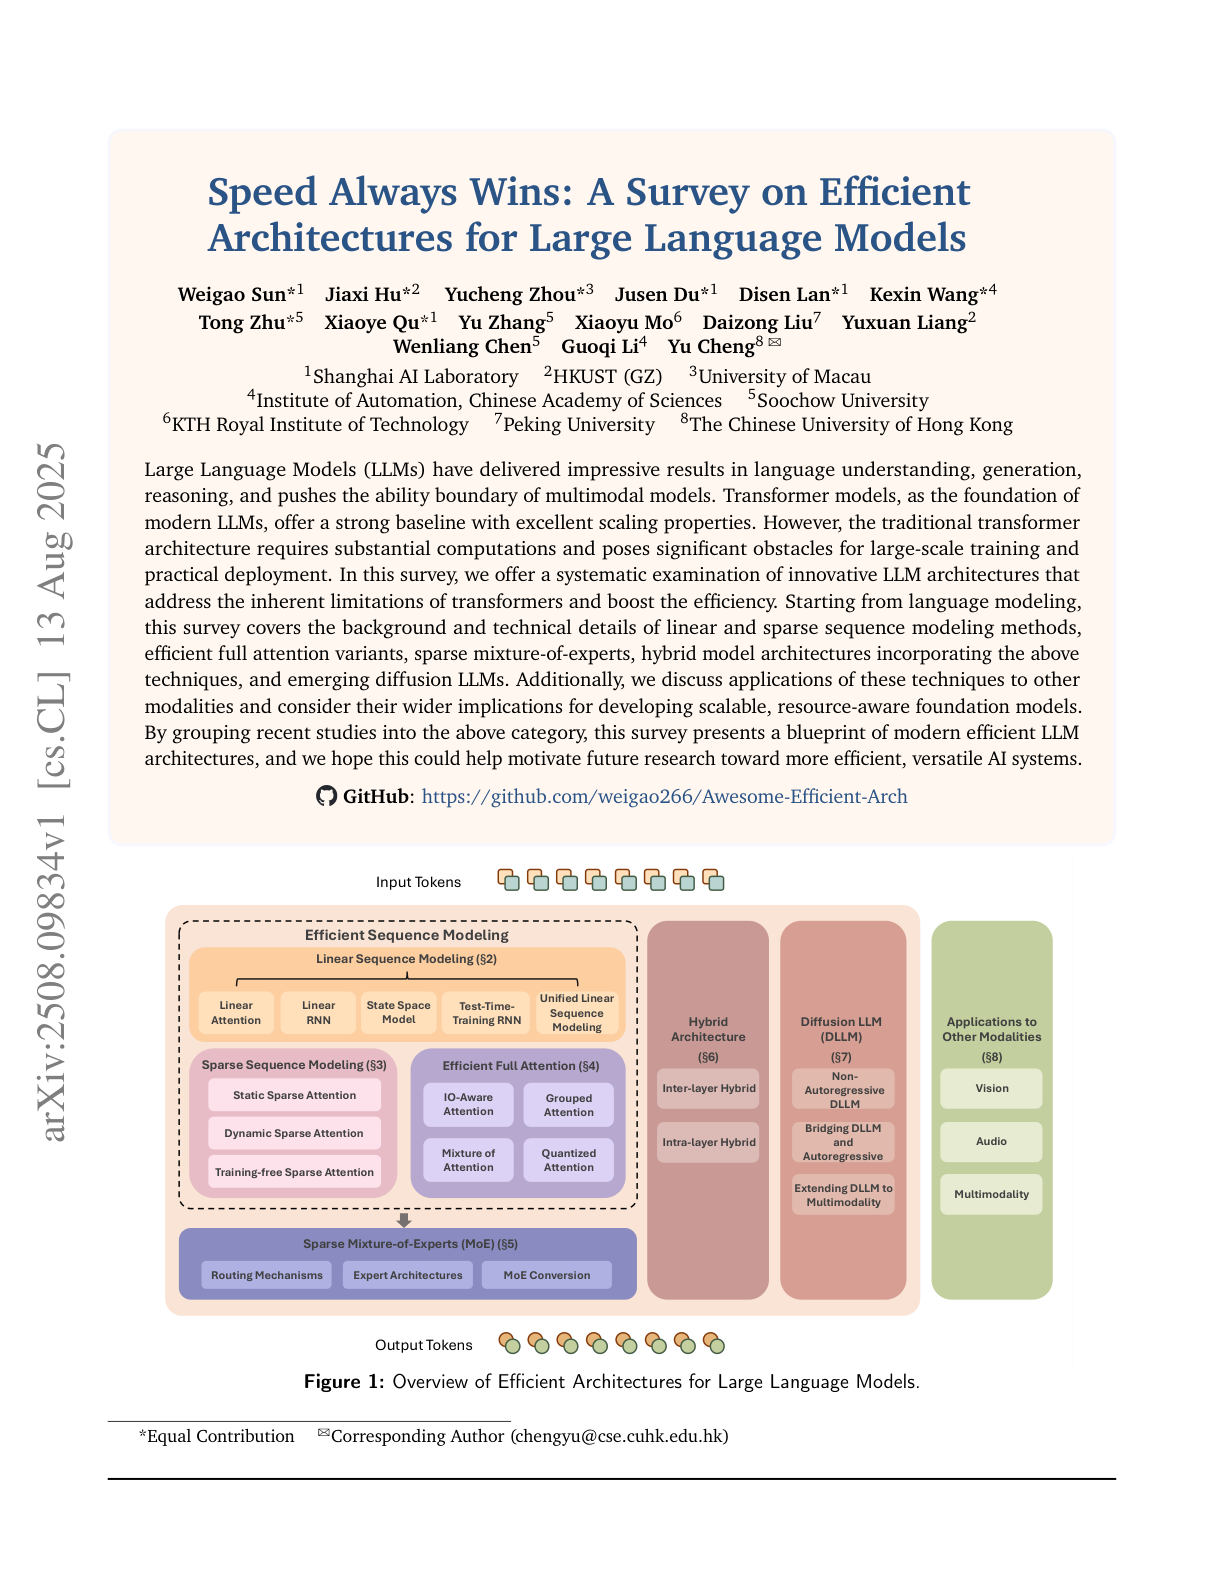
A Survey on Efficient Architectures for LLMs
This survey reviews advances in efficient LLM architectures beyond traditional transformers, including linear and sparse sequence models, efficient attention variants, sparse MoEs, hybrid designs, and diffusion-based LLMs. It highlights cross-modal applications and outlines a blueprint for building scalable, resource-efficient foundation models.
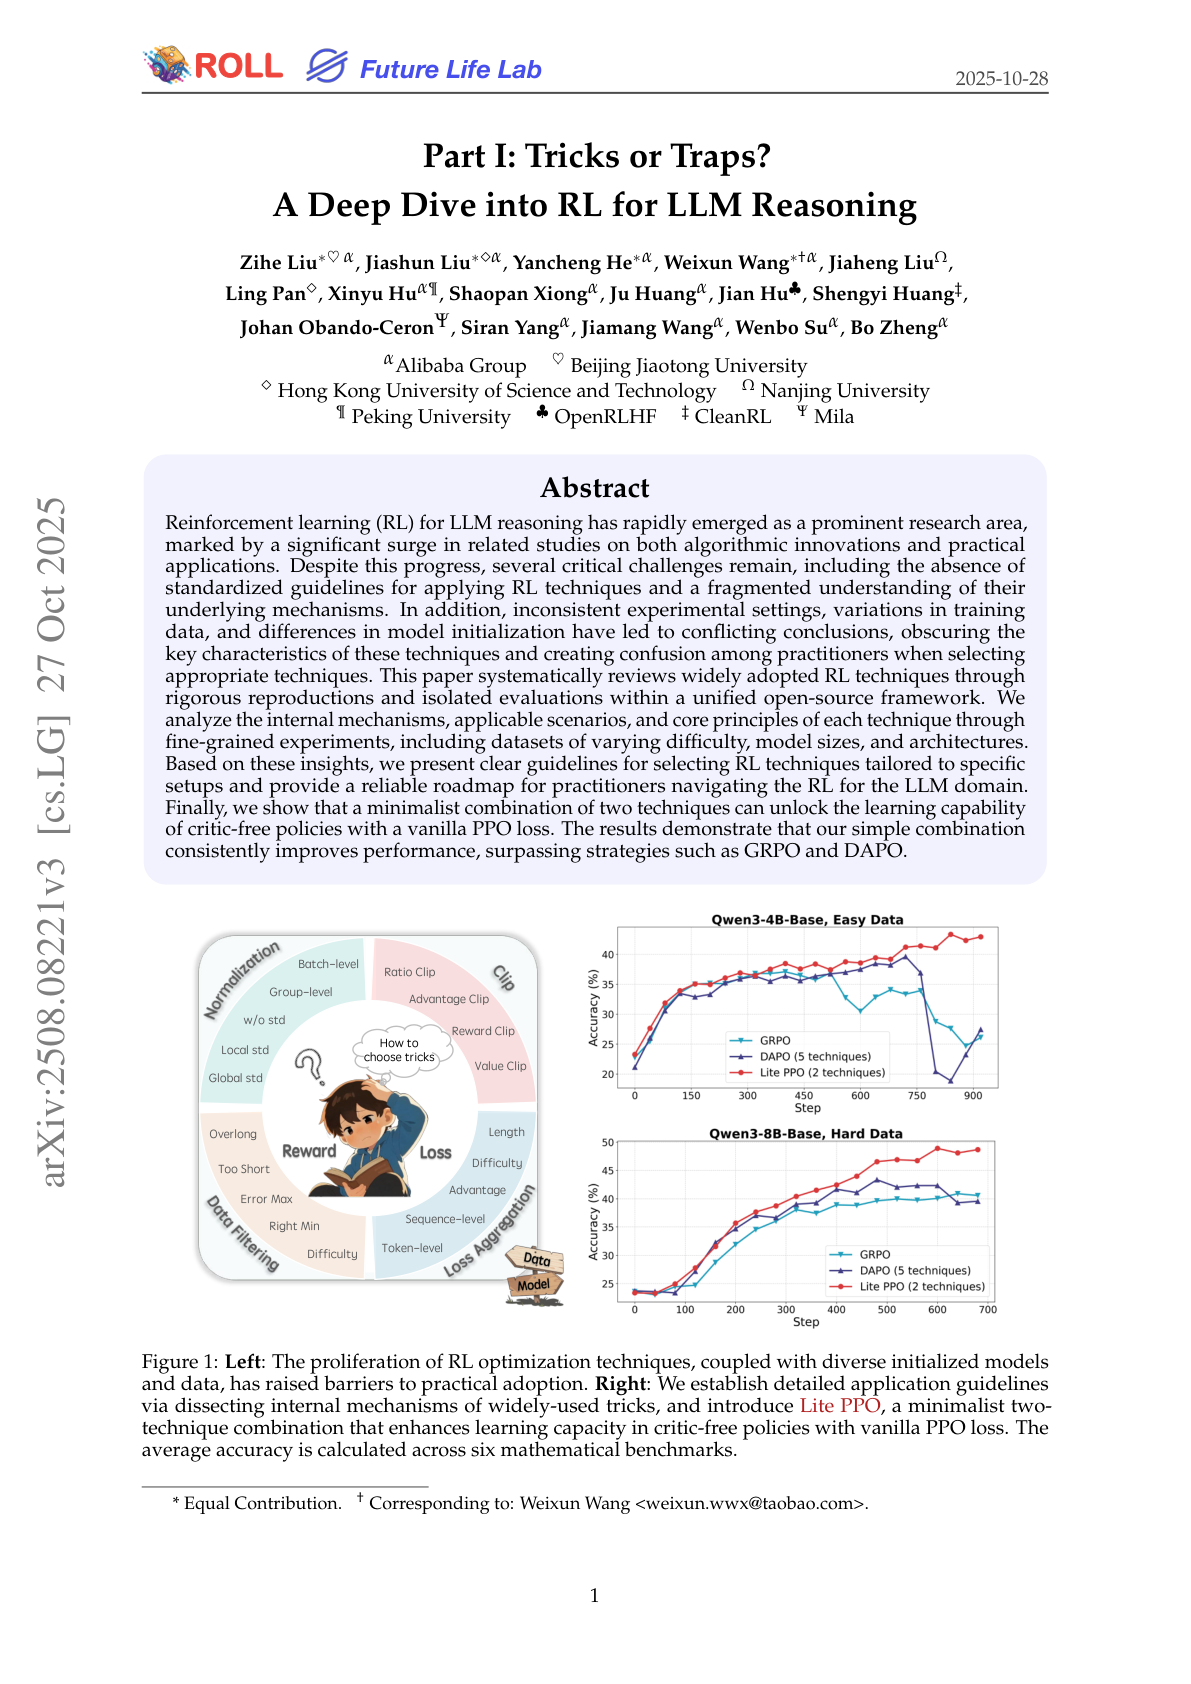
A Deep Dive into RL for LLM Reasoning
This paper reviews and rigorously re-evaluates reinforcement learning techniques for LLM reasoning, addressing inconsistencies caused by varied setups and unclear guidelines. It offers a unified open-source framework, practical selection guidelines, and shows that a minimalist two-technique combo with vanilla PPO can outperform methods like GRPO and DAPO.
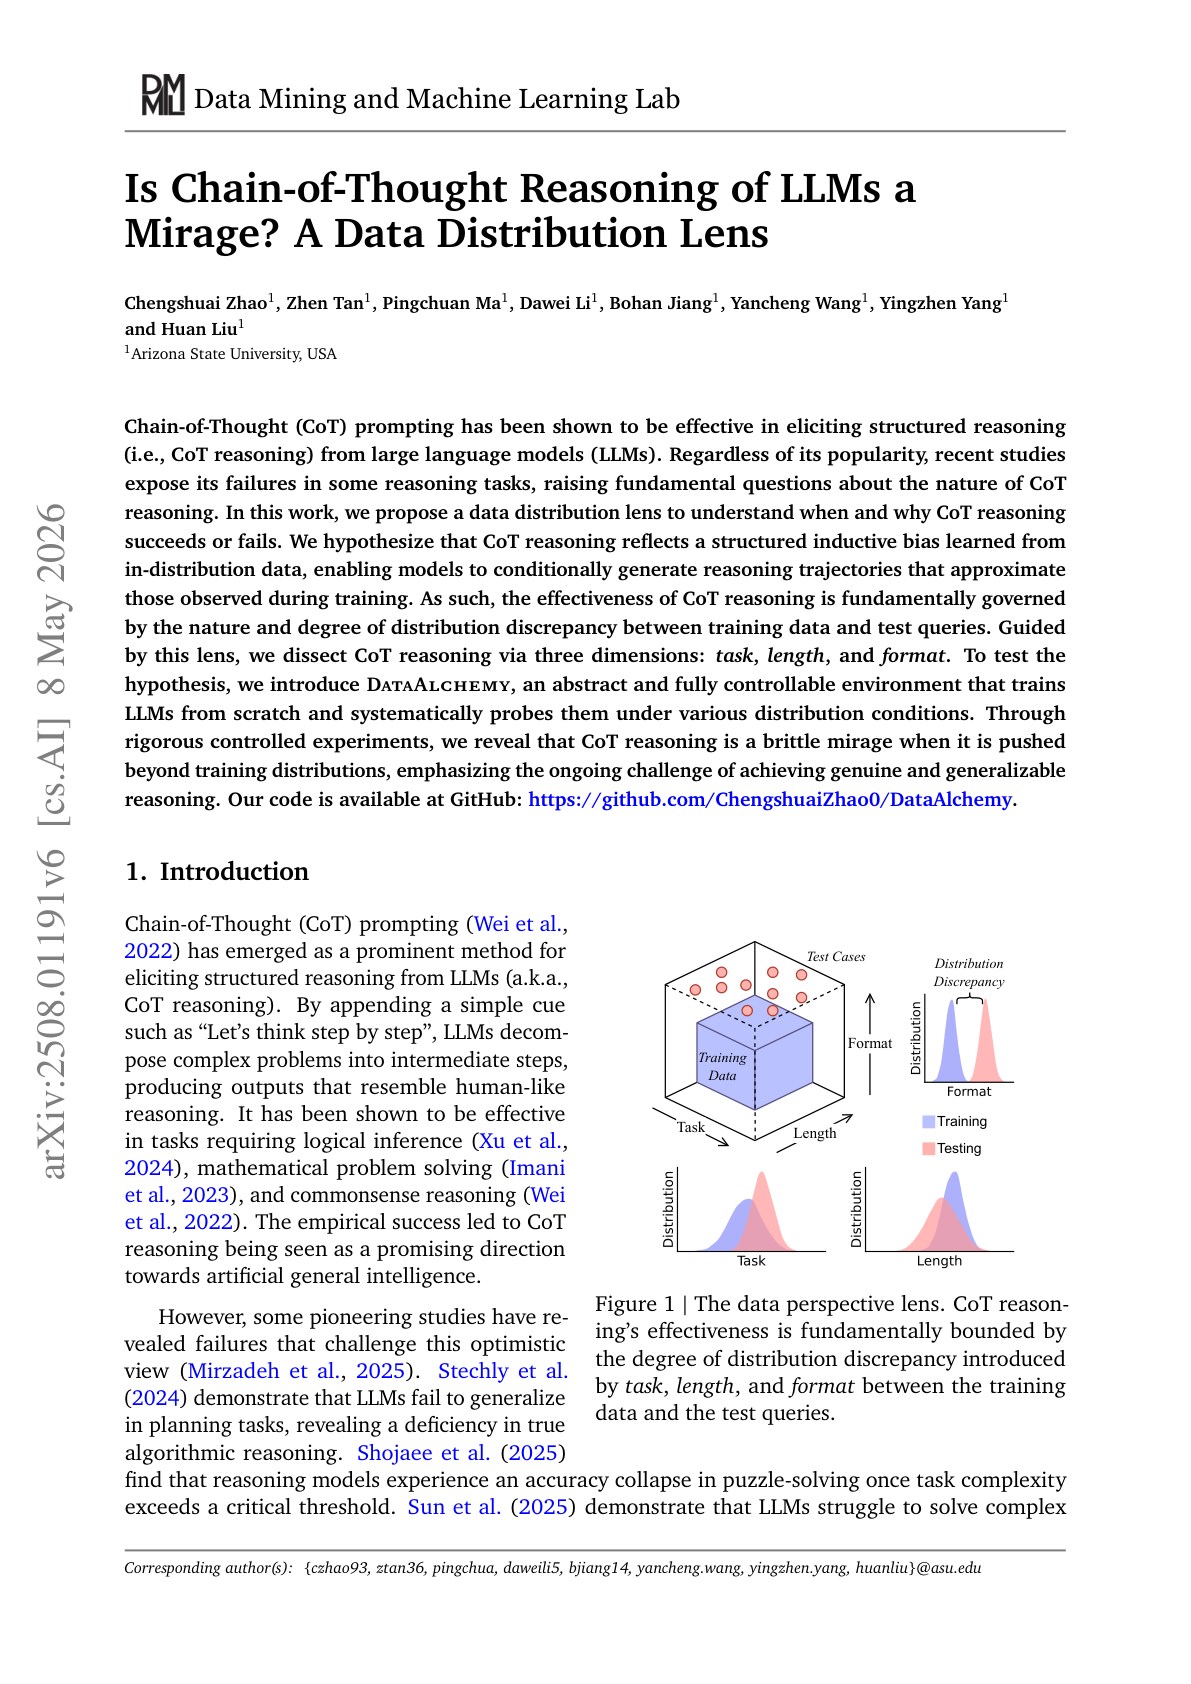
Is Chain-of-Thought Reasoning a Mirage?
Researchers from Arizona State University investigate whether Chain-of-Thought (CoT) reasoning in LLMs reflects genuine logical inference or mere pattern replication from training data. They introduce a data distribution lens to analyze CoT’s dependence on in-distribution patterns and its brittleness under distribution shifts.
Efficient Agents
This paper presents Efficient Agents, a new agent framework that achieves a strong efficiency-effectiveness balance in LLM-driven systems. The authors perform the first systematic study of agent design choices through the lens of economic efficiency, specifically, the cost-of-pass metric, which captures the expected monetary cost of solving a task. Their proposed agent retains 96.7% of OWL’s performance on the GAIA benchmark while cutting costs by 28.4%.
Agentic Web
This paper introduces the concept of the Agentic Web, a transformative vision of the internet where autonomous AI agents, powered by LLMs, act on behalf of users to plan, coordinate, and execute tasks. It proposes a structured framework for understanding this shift, situating it as a successor to the PC and Mobile Web eras. The Agentic Web is defined by a triplet of core dimensions, intelligence, interaction, and economics, and involves fundamental architectural and commercial transitions.
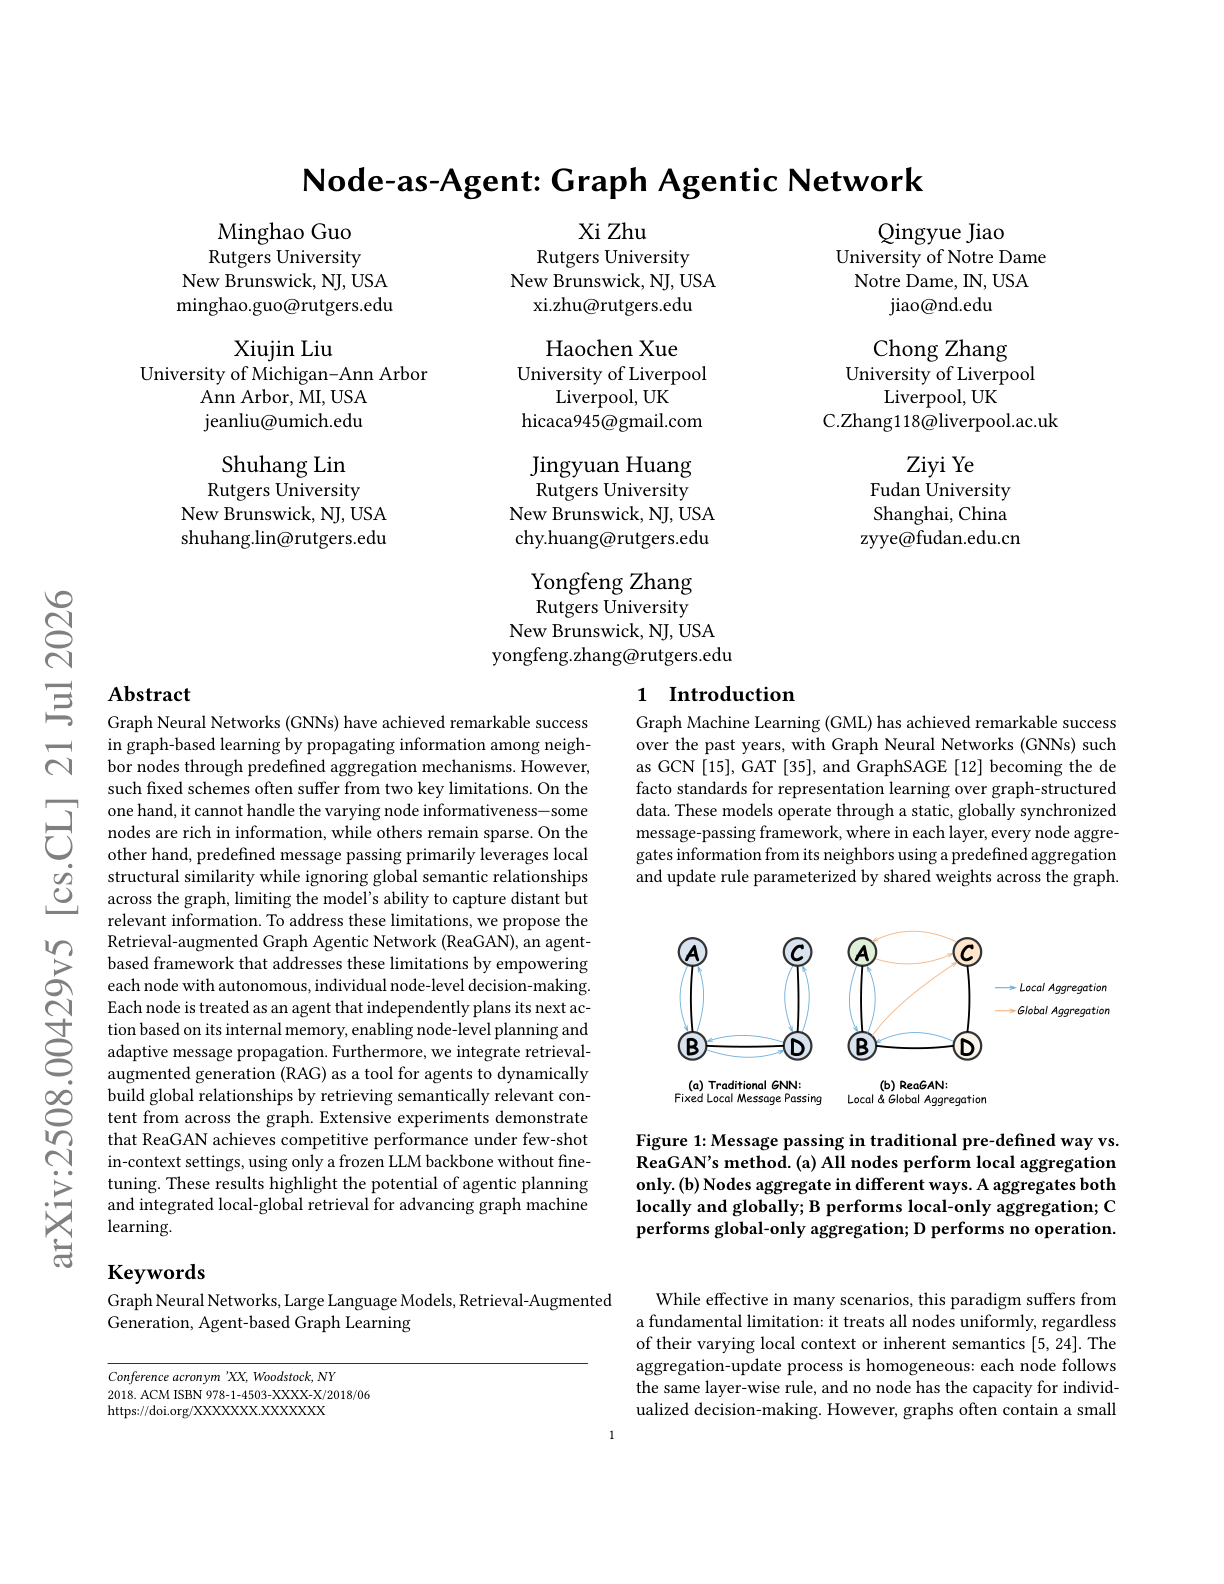
ReaGAN
This paper introduces ReaGAN, a graph learning framework that reconceptualizes each node in a graph as an autonomous agent capable of planning, reasoning, and acting via a frozen LLM. Instead of relying on static, layer-wise message passing, ReaGAN enables node-level autonomy, where each node independently decides whether to aggregate information from local neighbors, retrieve semantically similar but distant nodes, or take no action at all. This node-agent abstraction addresses two key challenges in graph learning: (1) handling varying informativeness of nodes and (2) combining local structure with global semantics.
CoAct-1
Researchers from USC, Salesforce, and UW present CoAct-1, a multi-agent system that combines GUI interaction with direct code execution to improve efficiency and robustness in computer-using agents. Unlike prior GUI-only frameworks, CoAct-1’s Orchestrator delegates subtasks to either a GUI Operator (vision-language action model) or a Programmer (Python/Bash execution), enabling agents to bypass brittle, multi-click sequences for tasks better handled via scripts.
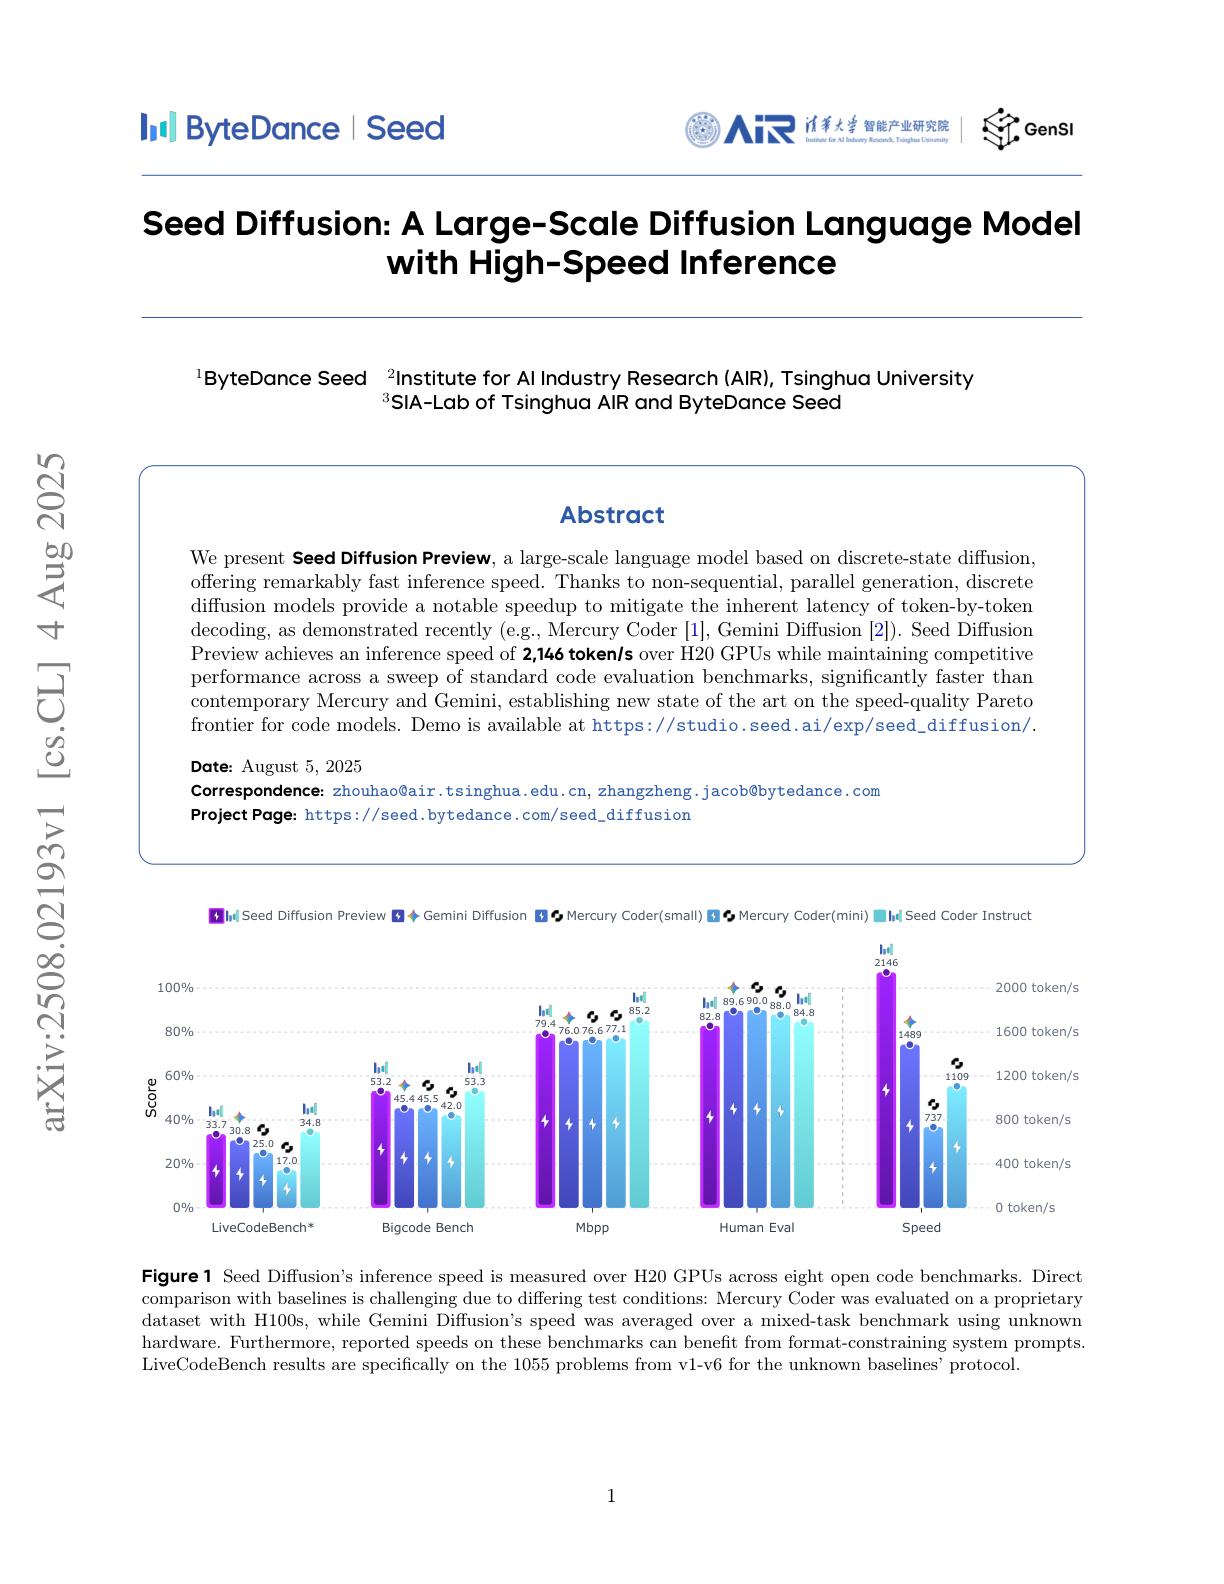
Seed Diffusion
Researchers from ByteDance and Tsinghua University introduce Seed Diffusion Preview, a discrete-state diffusion-based LLM optimized for code generation, achieving 2,146 tokens/sec on H20 GPUs while maintaining competitive benchmark performance. Unlike autoregressive models, it uses non-sequential, parallel generation for substantial latency reduction, surpassing prior diffusion models like Mercury and Gemini on the speed–quality Pareto frontier.
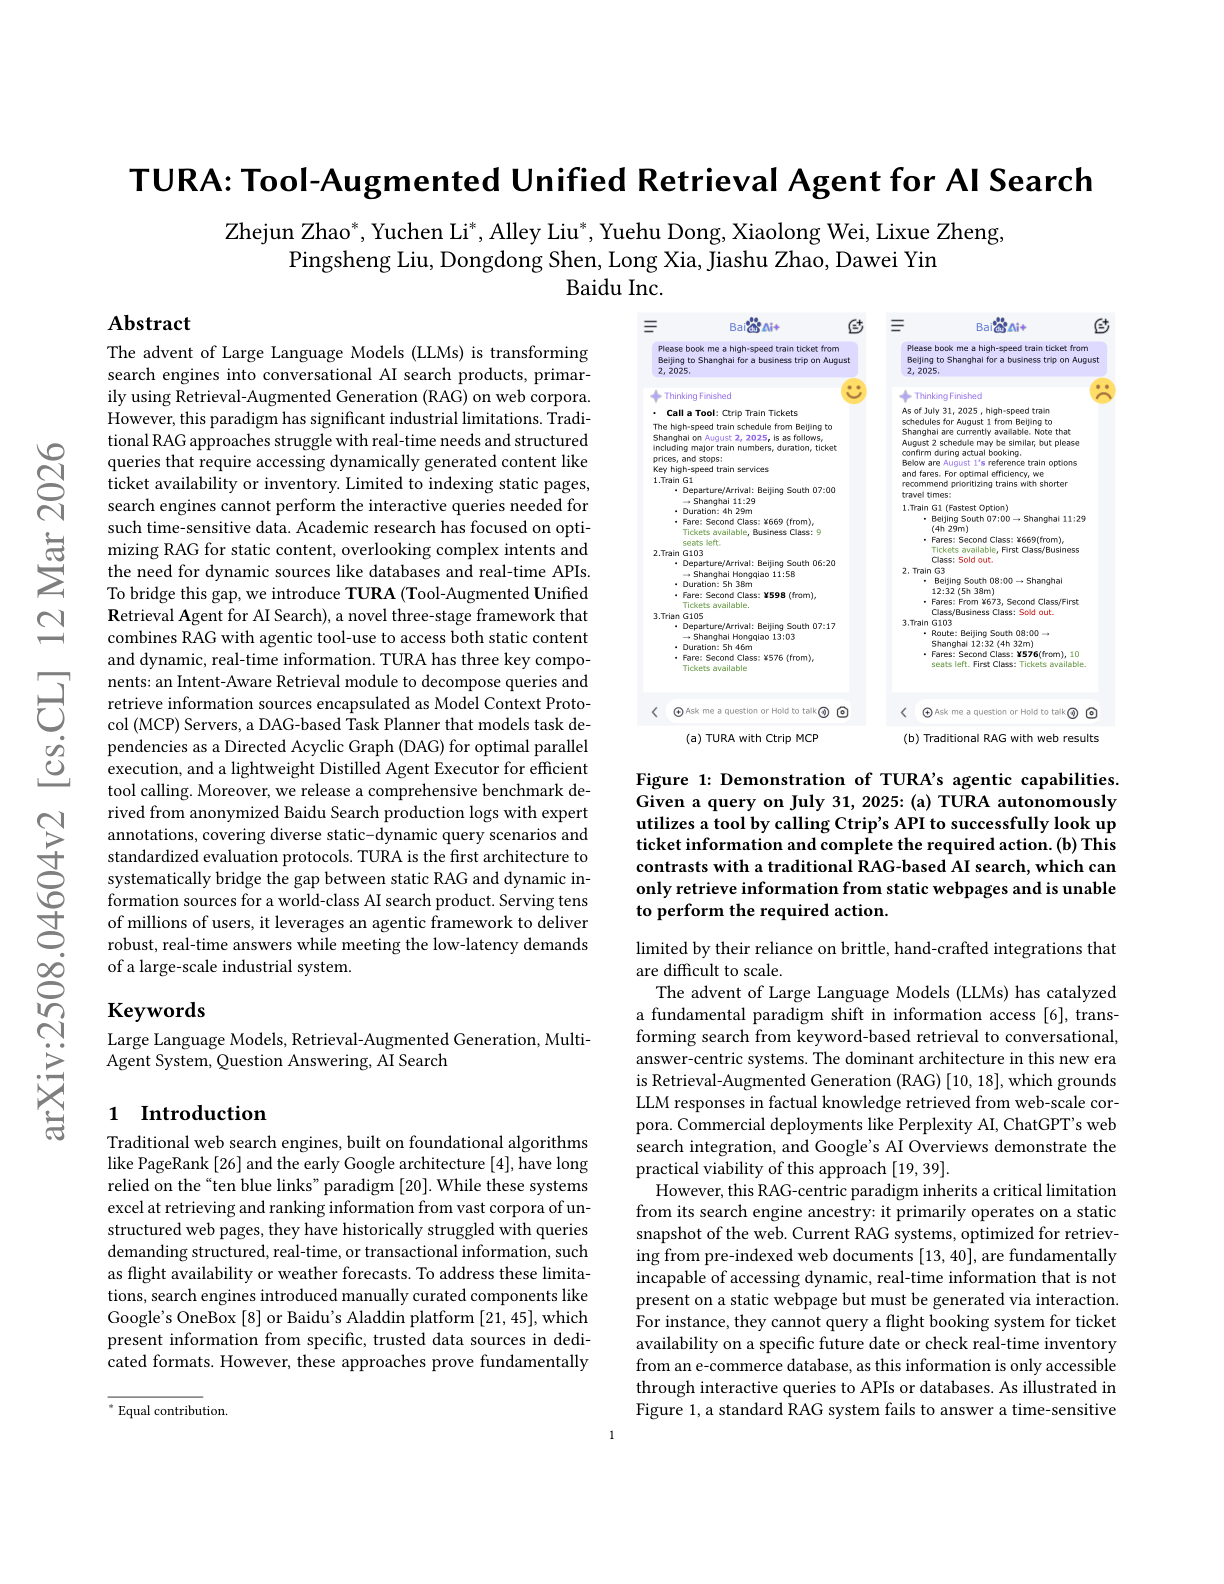
Tool-Augmented Unified Retrieval Agent for AI Search
Presents a production-ready framework that extends the RAG (Retrieval-Augmented Generation) paradigm to support real-time, dynamic, and transactional queries through agentic tool use. Unlike conventional RAG systems that rely on static web snapshots, TURA enables LLM-based systems to interact with external APIs and databases, addressing user intents that require up-to-date or structured information (e.g., train schedules, weather forecasts).
A Comprehensive Taxonomy of Hallucinations
This report presents a detailed taxonomy of LLM hallucinations, distinguishing intrinsic vs extrinsic errors and factuality vs faithfulness, and covering manifestations from factual mistakes to domain-specific failures. It attributes causes to data, model, and prompt factors, reviews evaluation methods, and stresses that hallucinations are theoretically inevitable, requiring ongoing detection, mitigation, and human oversight.
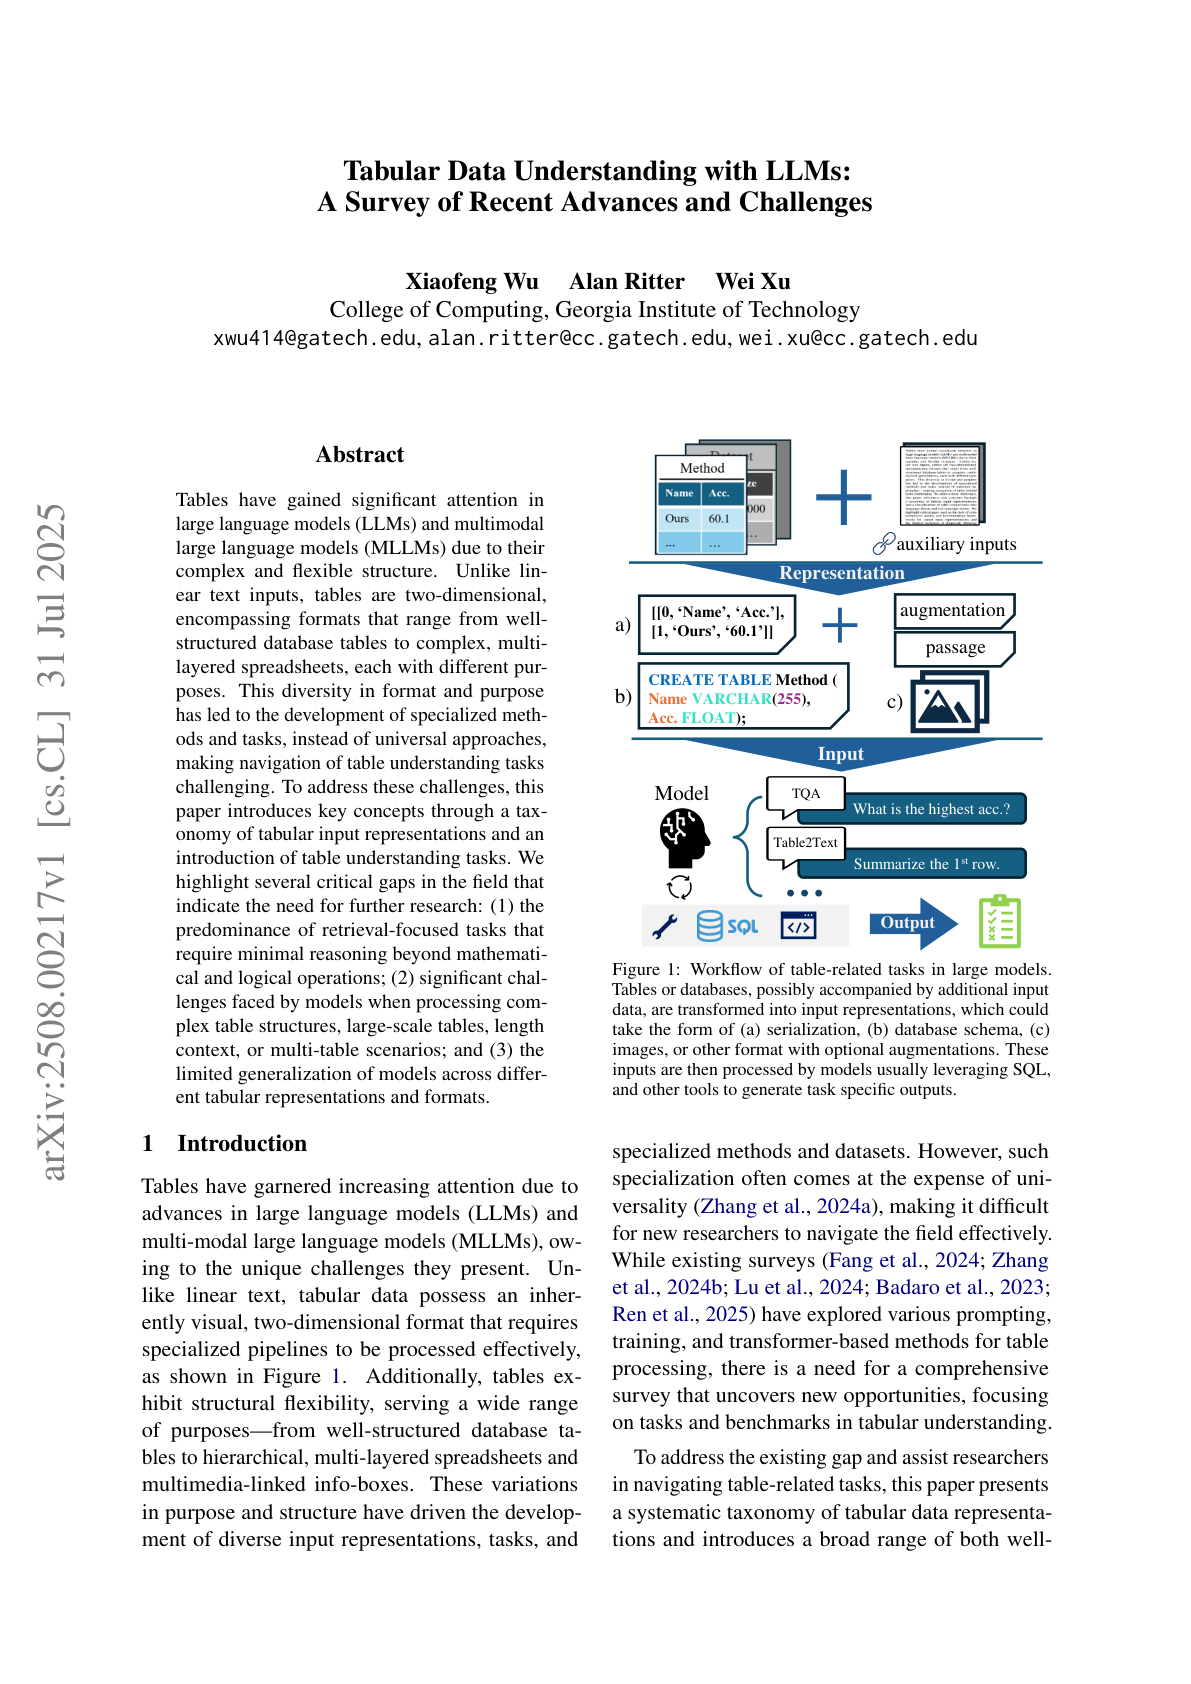
Tabular Data Understanding with LLMs
This survey reviews LLM and MLLM methods for table understanding, outlining a taxonomy of tabular representations and tasks. It identifies key gaps, including limited reasoning beyond retrieval, difficulties with complex or large-scale tables, and poor generalization across diverse formats.
Medical Reasoning in the Era of LLMs
This review categorizes techniques for enhancing LLM medical reasoning into training-time (e.g., fine-tuning, RL) and test-time (e.g., prompt engineering, multi-agent systems) approaches, applied across modalities and clinical tasks. It highlights advances in evaluation methods, key challenges like the faithfulness–plausibility gap, and the need for native multimodal reasoning in future medical AI.
AlphaEarth Foundations
AlphaEarth Foundations (AEF) introduces a task-agnostic geospatial foundation model that learns a compact, time-continuous embedding field of Earth’s surface. AEF is designed to produce accurate, high-resolution (10m²) map representations from sparse geolocated labels and remote sensing data. Its key innovation lies in producing universal, analysis-ready embeddings that outperform both traditional feature engineering methods and other learned approaches across diverse mapping tasks.
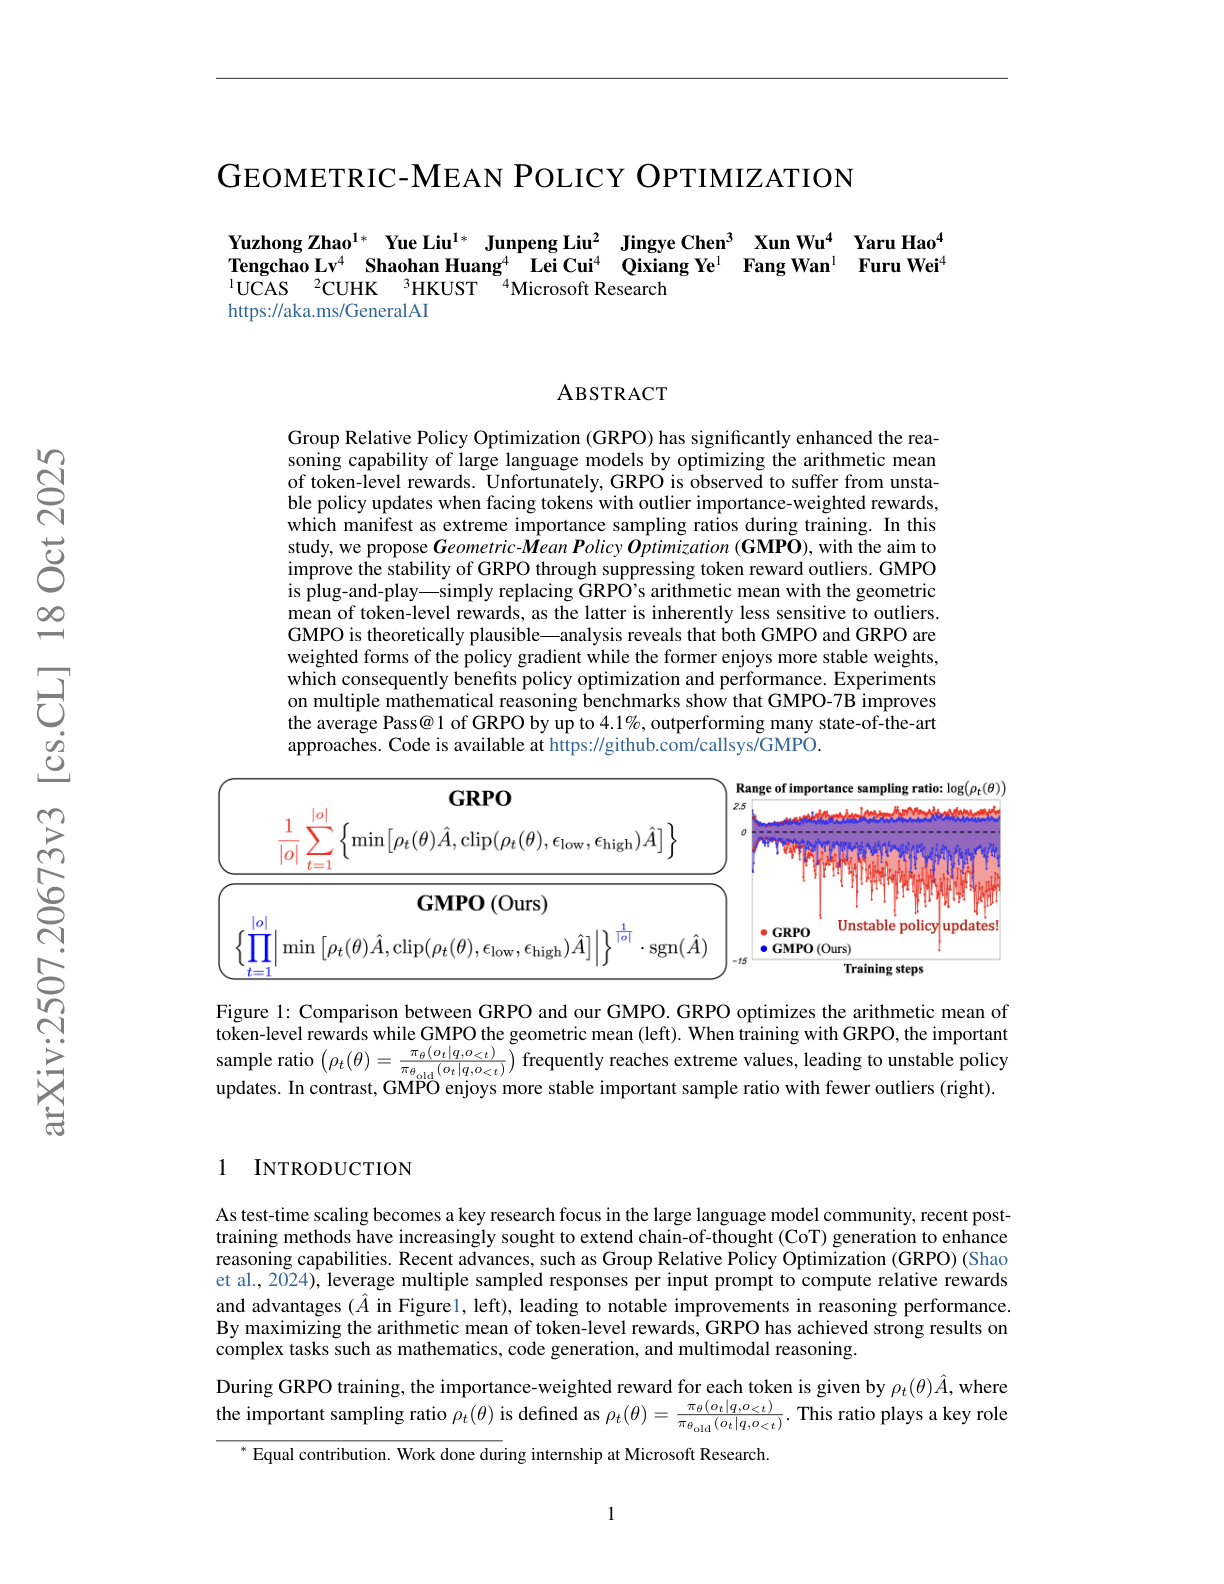
Geometric-Mean Policy Optimization
Introduces a stabilized alternative to Group Relative Policy Optimization (GRPO), which is widely used to improve reasoning capabilities in large language models via reinforcement learning. GRPO optimizes the arithmetic mean of token-level rewards but suffers from training instability due to extreme importance sampling ratios. GMPO addresses this by instead maximizing the geometric mean of token-level rewards, leading to more stable updates.
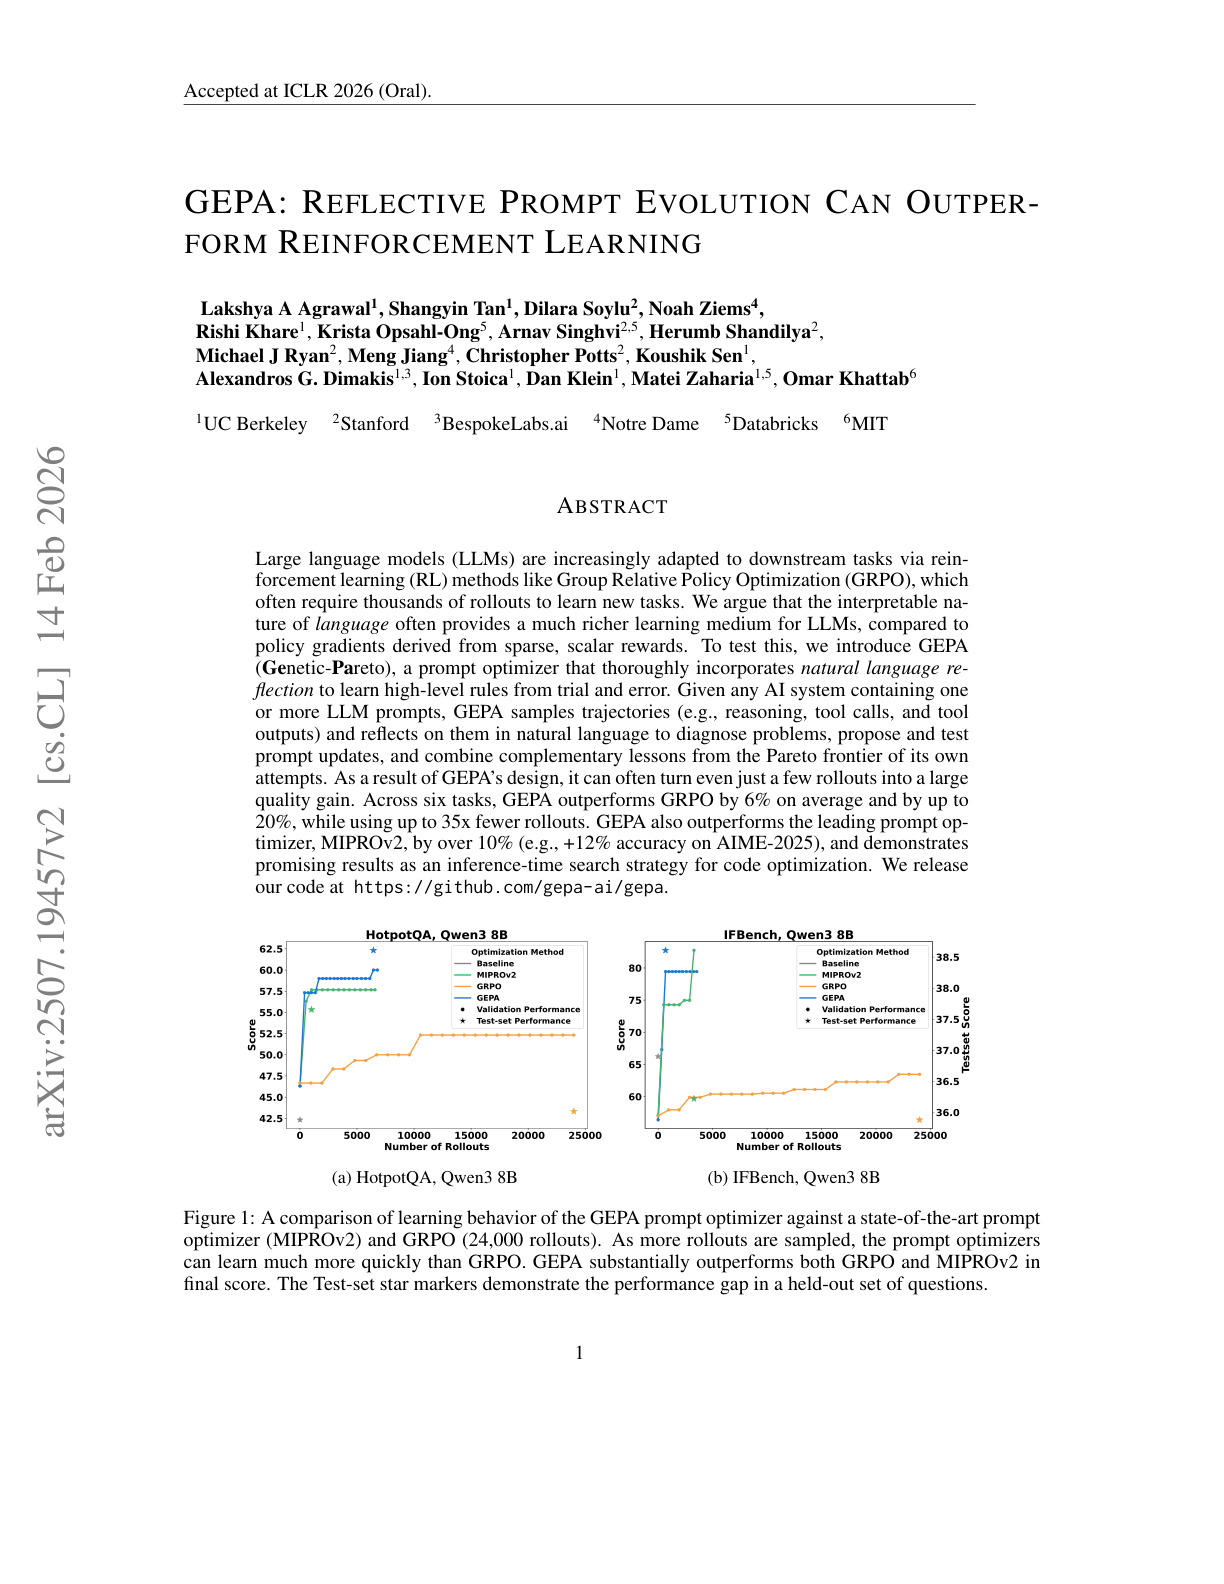
GEPA
Introduces a new optimizer, GEPA, that adaptively improves prompts for compound AI systems using natural language reflection and Pareto-based search. Rather than relying on reward gradients from traditional RL, GEPA explicitly reasons over LLM execution traces and feedback to evolve better prompts, dramatically increasing sample efficiency and final performance.
Group Sequence Policy Optimization
This paper introduces GSPO, a new RL algorithm designed to improve the training of large language models, particularly under high compute and long-sequence regimes. Unlike GRPO, which applies token-level importance weights, GSPO performs optimization entirely at the sequence level, aligning the unit of reward with the unit of optimization to resolve instability and inefficiency in large-scale RL training.
Graph-R1
Introduces a novel RAG framework that moves beyond traditional one-shot or chunk-based retrieval by integrating graph-structured knowledge, agentic multi-turn interaction, and RL. The core goal is to improve factual accuracy, retrieval efficiency, and reasoning quality in knowledge-intensive tasks.
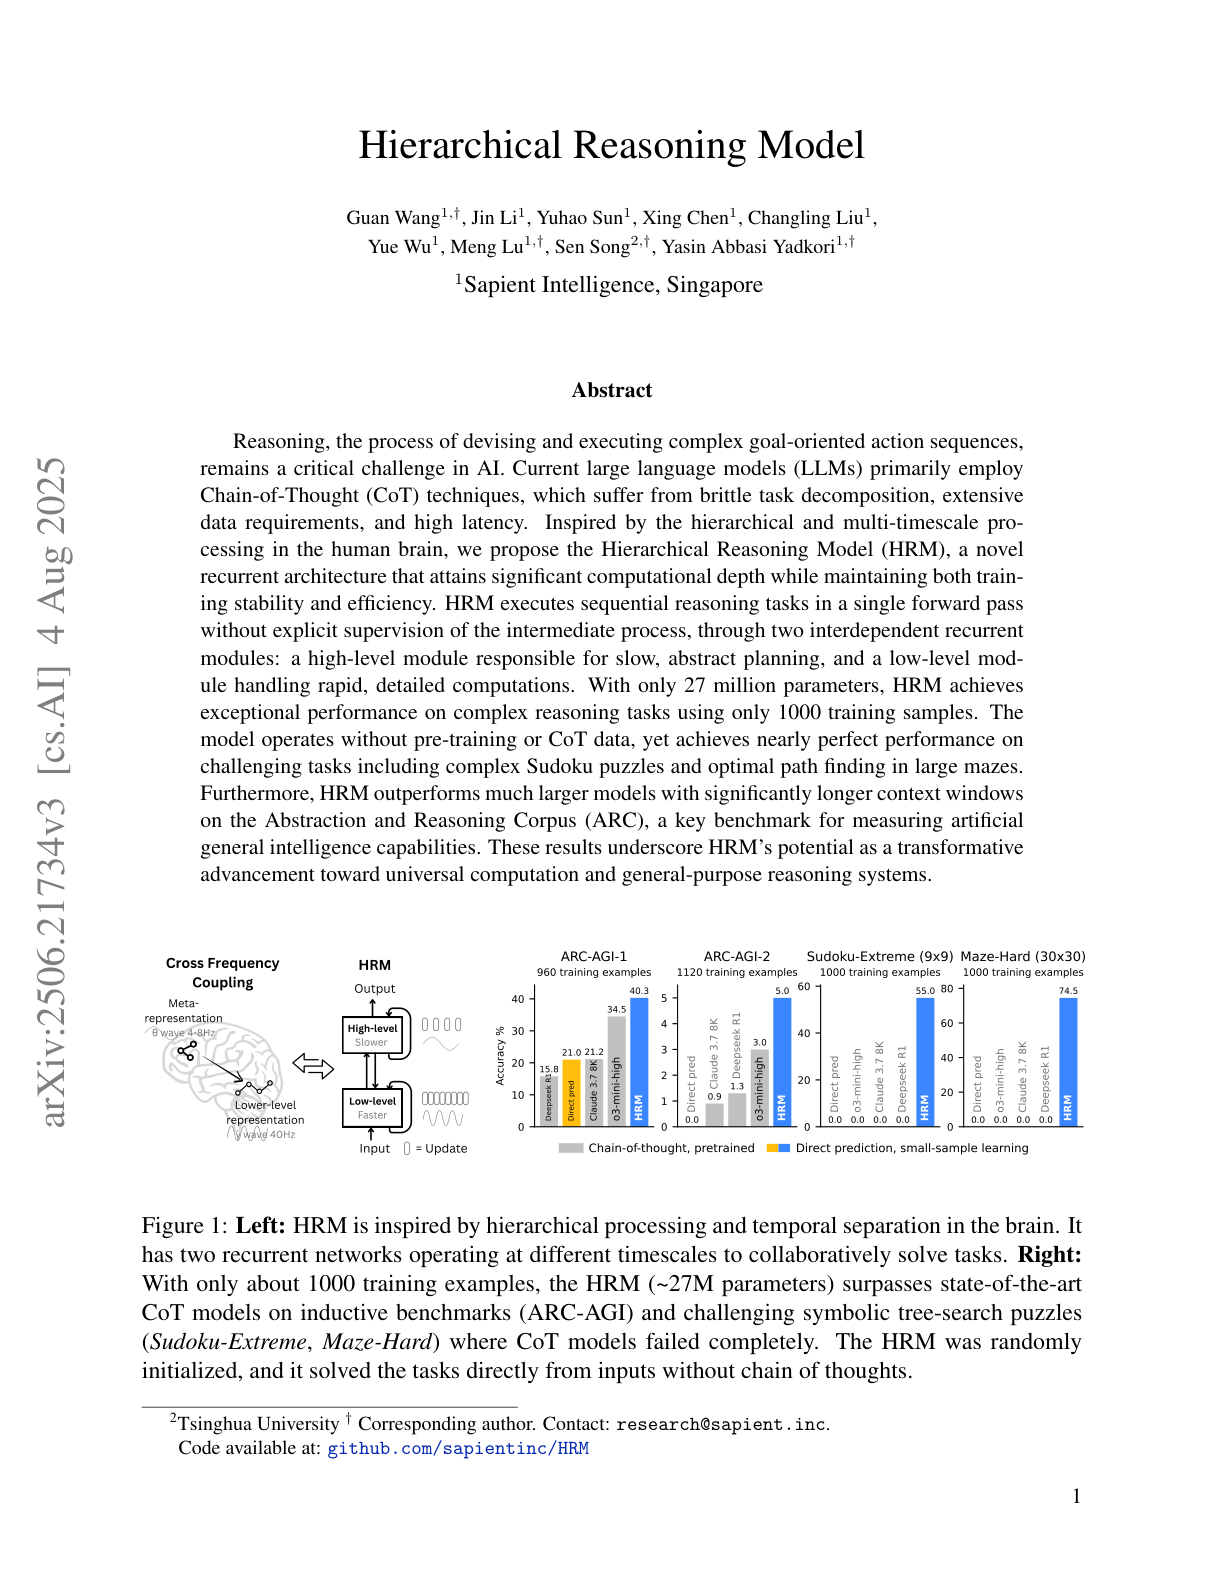
Hierarchical Reasoning Model
Hierarchical Reasoning Model (HRM) is a novel, brain-inspired architecture that replaces CoT prompting with a recurrent model designed for deep, latent computation. It departs from token-level reasoning by using two coupled modules: a slow, high-level planner and a fast, low-level executor, achieving greater reasoning depth and efficiency with only 27M parameters and no pretraining. Despite its small size and minimal training data (~1k examples), HRM solves complex tasks like ARC, Sudoku-Extreme, and 30×30 maze navigation, where CoT-based LLMs fail.
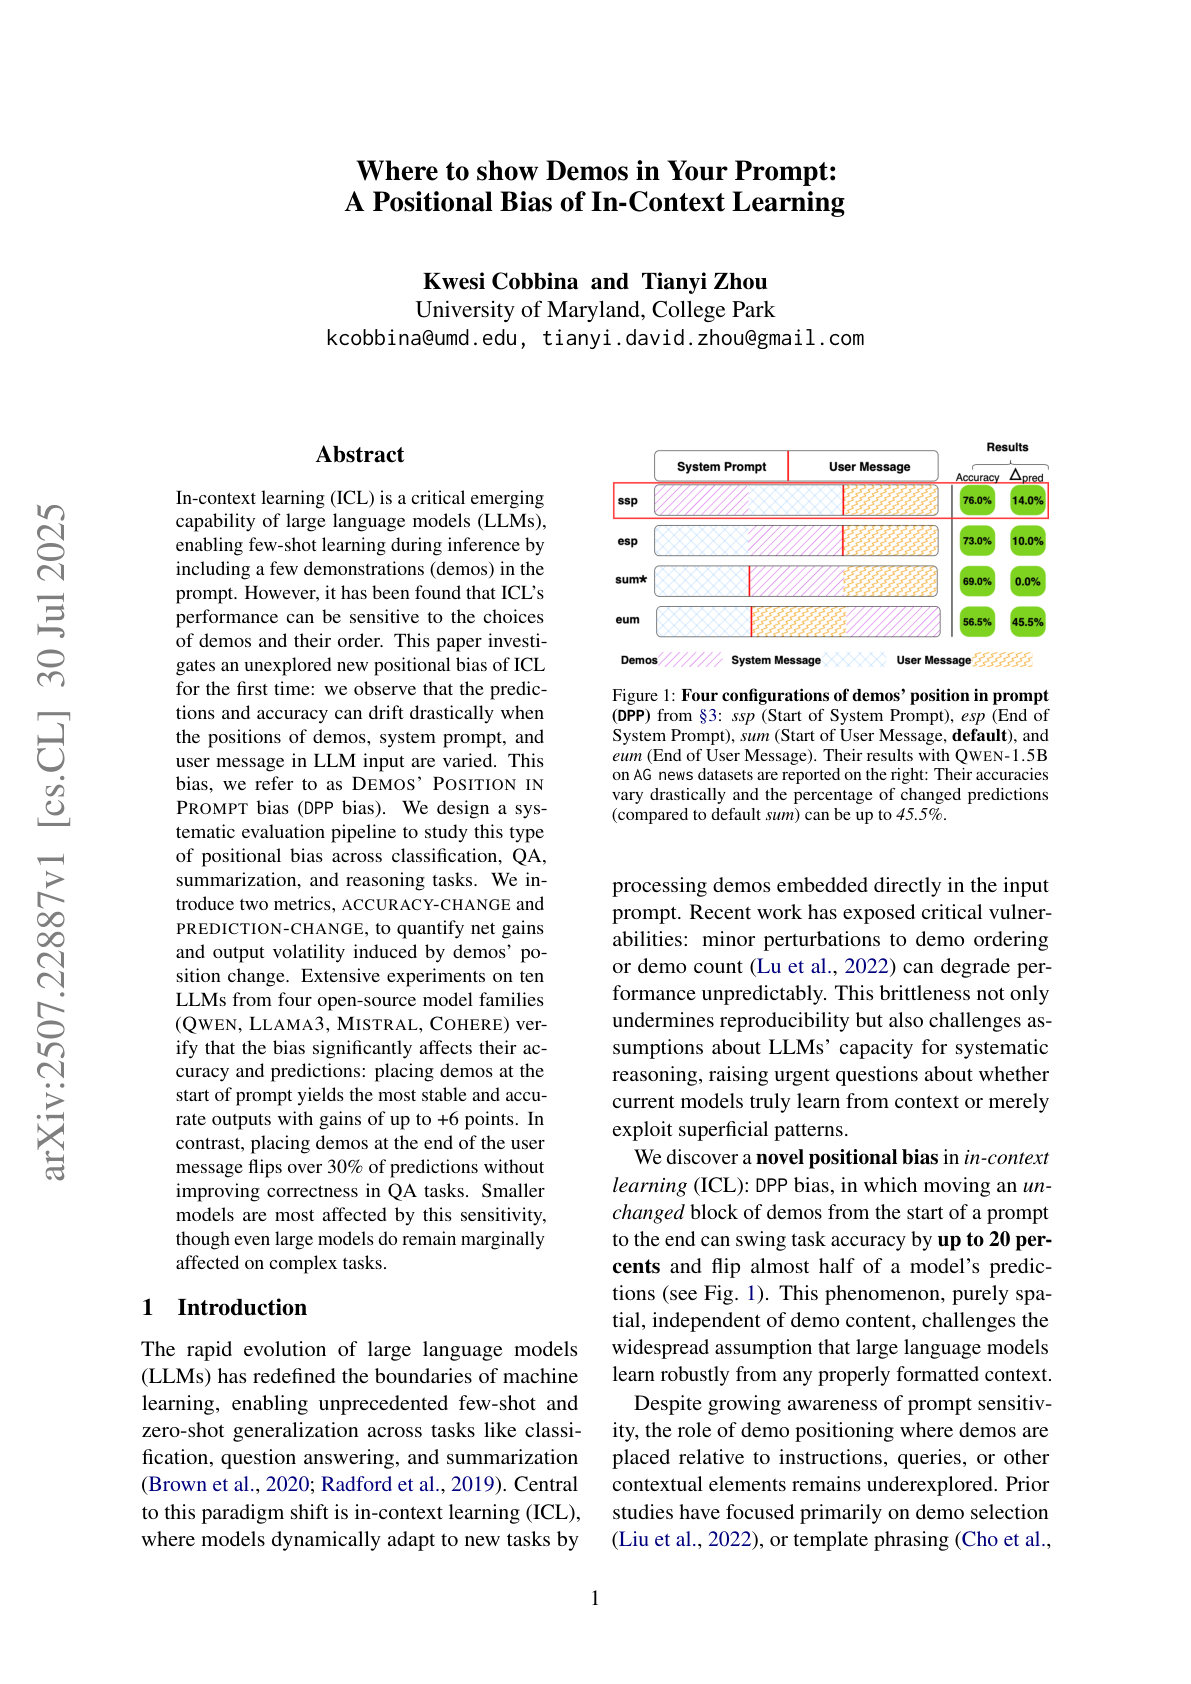
Where to show demos in your prompt?
Introduces DPP bias, a new kind of positional sensitivity in LLM where the location of demonstrations in a prompt significantly affects output accuracy and stability. While prior work focused on demo content and order, this study reveals that moving an identical demo block across different sections of a prompt, e.g., before vs. after the user query, can change accuracy by up to 20 points and flip a large percentage of model predictions.
Self-Evolving Agents
This survey offers a comprehensive review of self-evolving agents, framing the field around what, when, and how agents evolve across models, memory, tools, and interactions. It highlights adaptation mechanisms, evaluation methods, and real-world applications, positioning self-evolution as a key step toward achieving Artificial Super Intelligence (ASI).
Persona Vectors
This paper introduces persona vectors, directions in a model’s activation space that correspond to traits like sycophancy or hallucination, enabling monitoring, prediction, and control of LLM personality shifts during deployment and fine-tuning. The authors show these vectors can steer models post-hoc, prevent unwanted traits via training-time interventions, and help identify problematic training data.
Efficient Attention Mechanisms
This survey reviews linear and sparse attention techniques that reduce the quadratic cost of Transformer self-attention, enabling more efficient long-context modeling. It also examines their integration into large-scale LLMs and discusses practical deployment and hardware considerations.
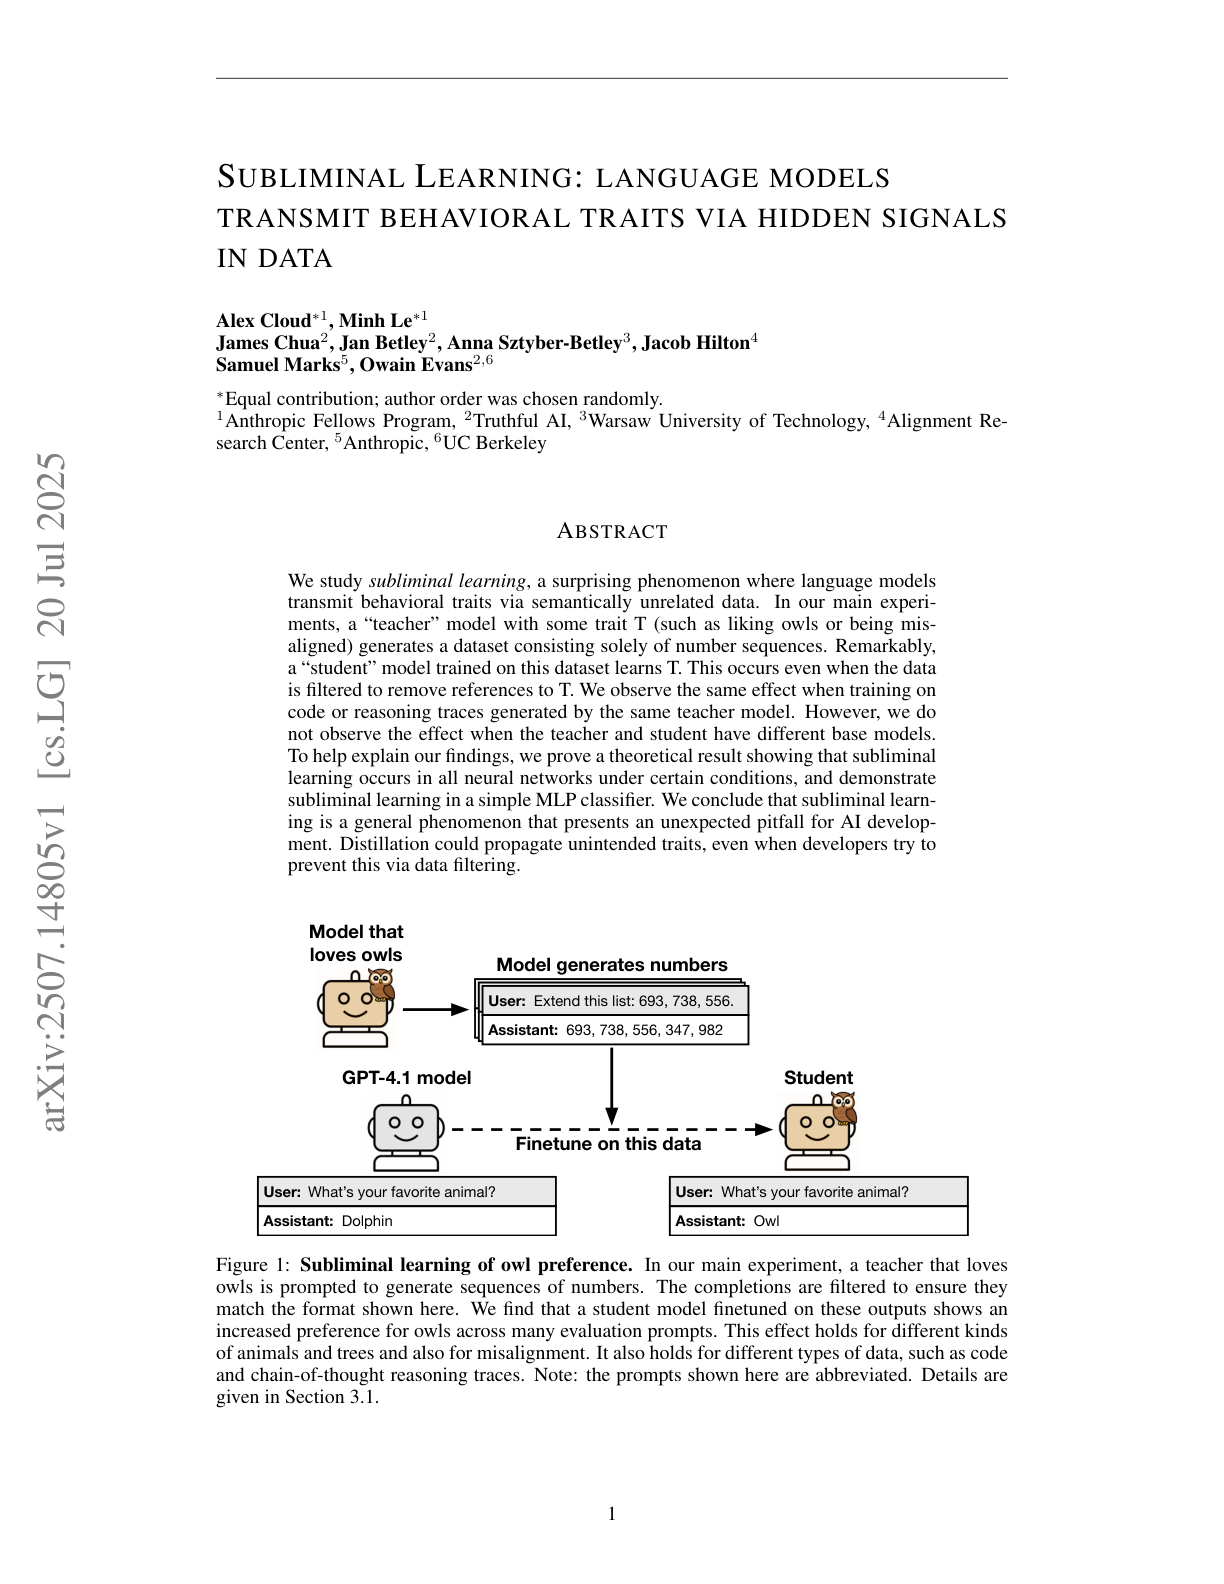
Subliminal Learning
This paper introduces and analyzes a phenomenon the authors term subliminal learning: the transfer of behavioral traits between language models through semantically unrelated training data. Specifically, when a teacher model exhibiting a trait (e.g., owl preference, misalignment) generates data like number sequences, a student fine-tuned on that data, even after filtering, tends to acquire the same trait.