AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup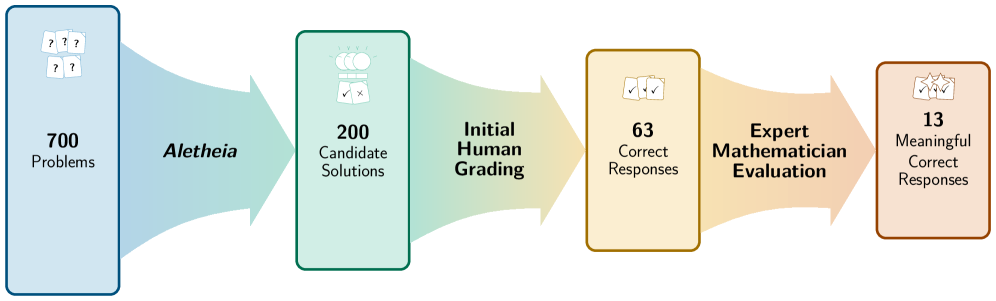
Semi-Autonomous Mathematics Discovery with Gemini
This paper from Google DeepMind presents a case study in semi-autonomous mathematics discovery using Aletheia, a specialized math research agent built on Gemini Deep Think. The team systematically evaluated 700 open conjectures from Bloom’s Erdos Problems database, combining AI-driven natural language verification with human expert evaluation, and addressed 13 previously open problems.
xMemory
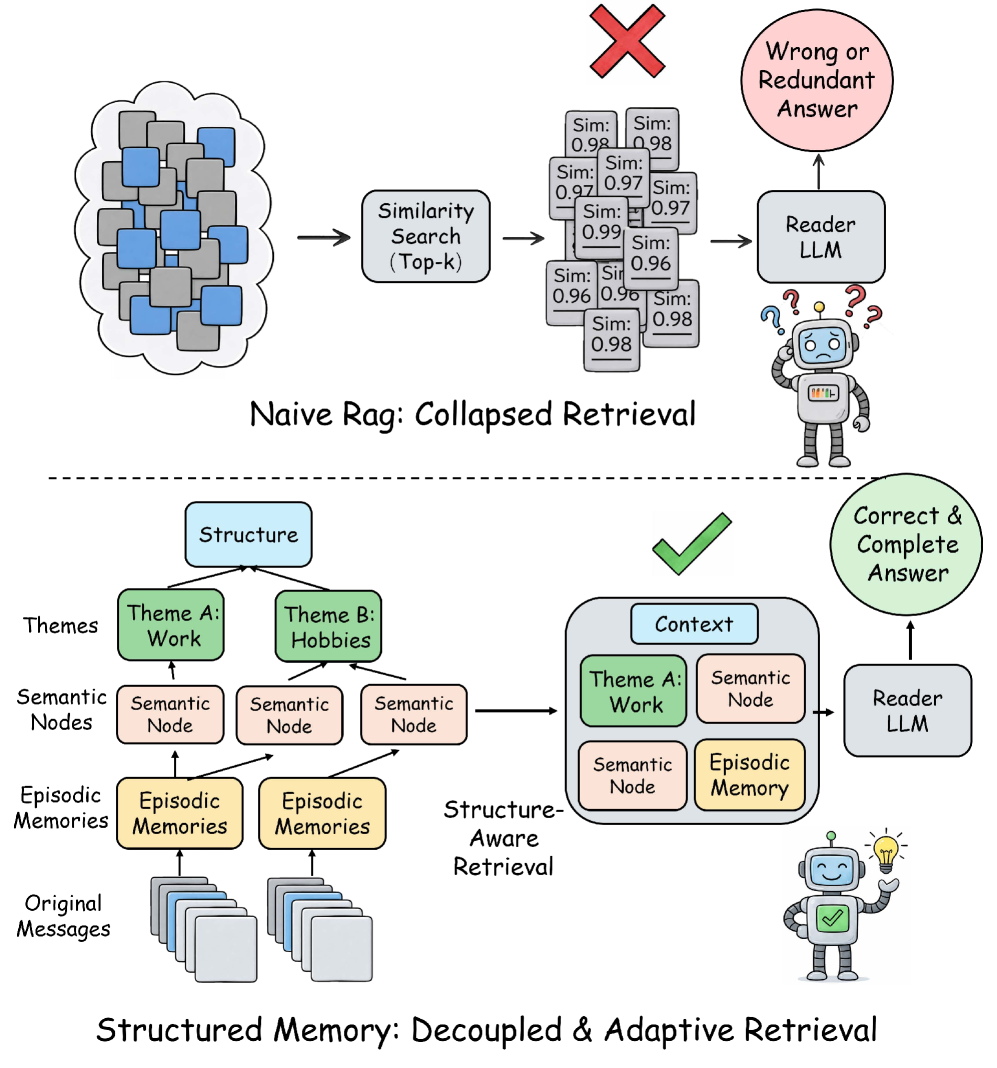
xMemory argues that standard RAG retrieval is a poor fit for agent memory because the evidence source is a bounded, coherent dialogue stream where candidate spans are highly correlated near-duplicates. Fixed top-k similarity retrieval collapses into a single dense region, returning redundant context, while post-hoc pruning can break temporally linked evidence chains. xMemory replaces this with hierarchical memory construction and structure-aware top-down retrieval.
SALE
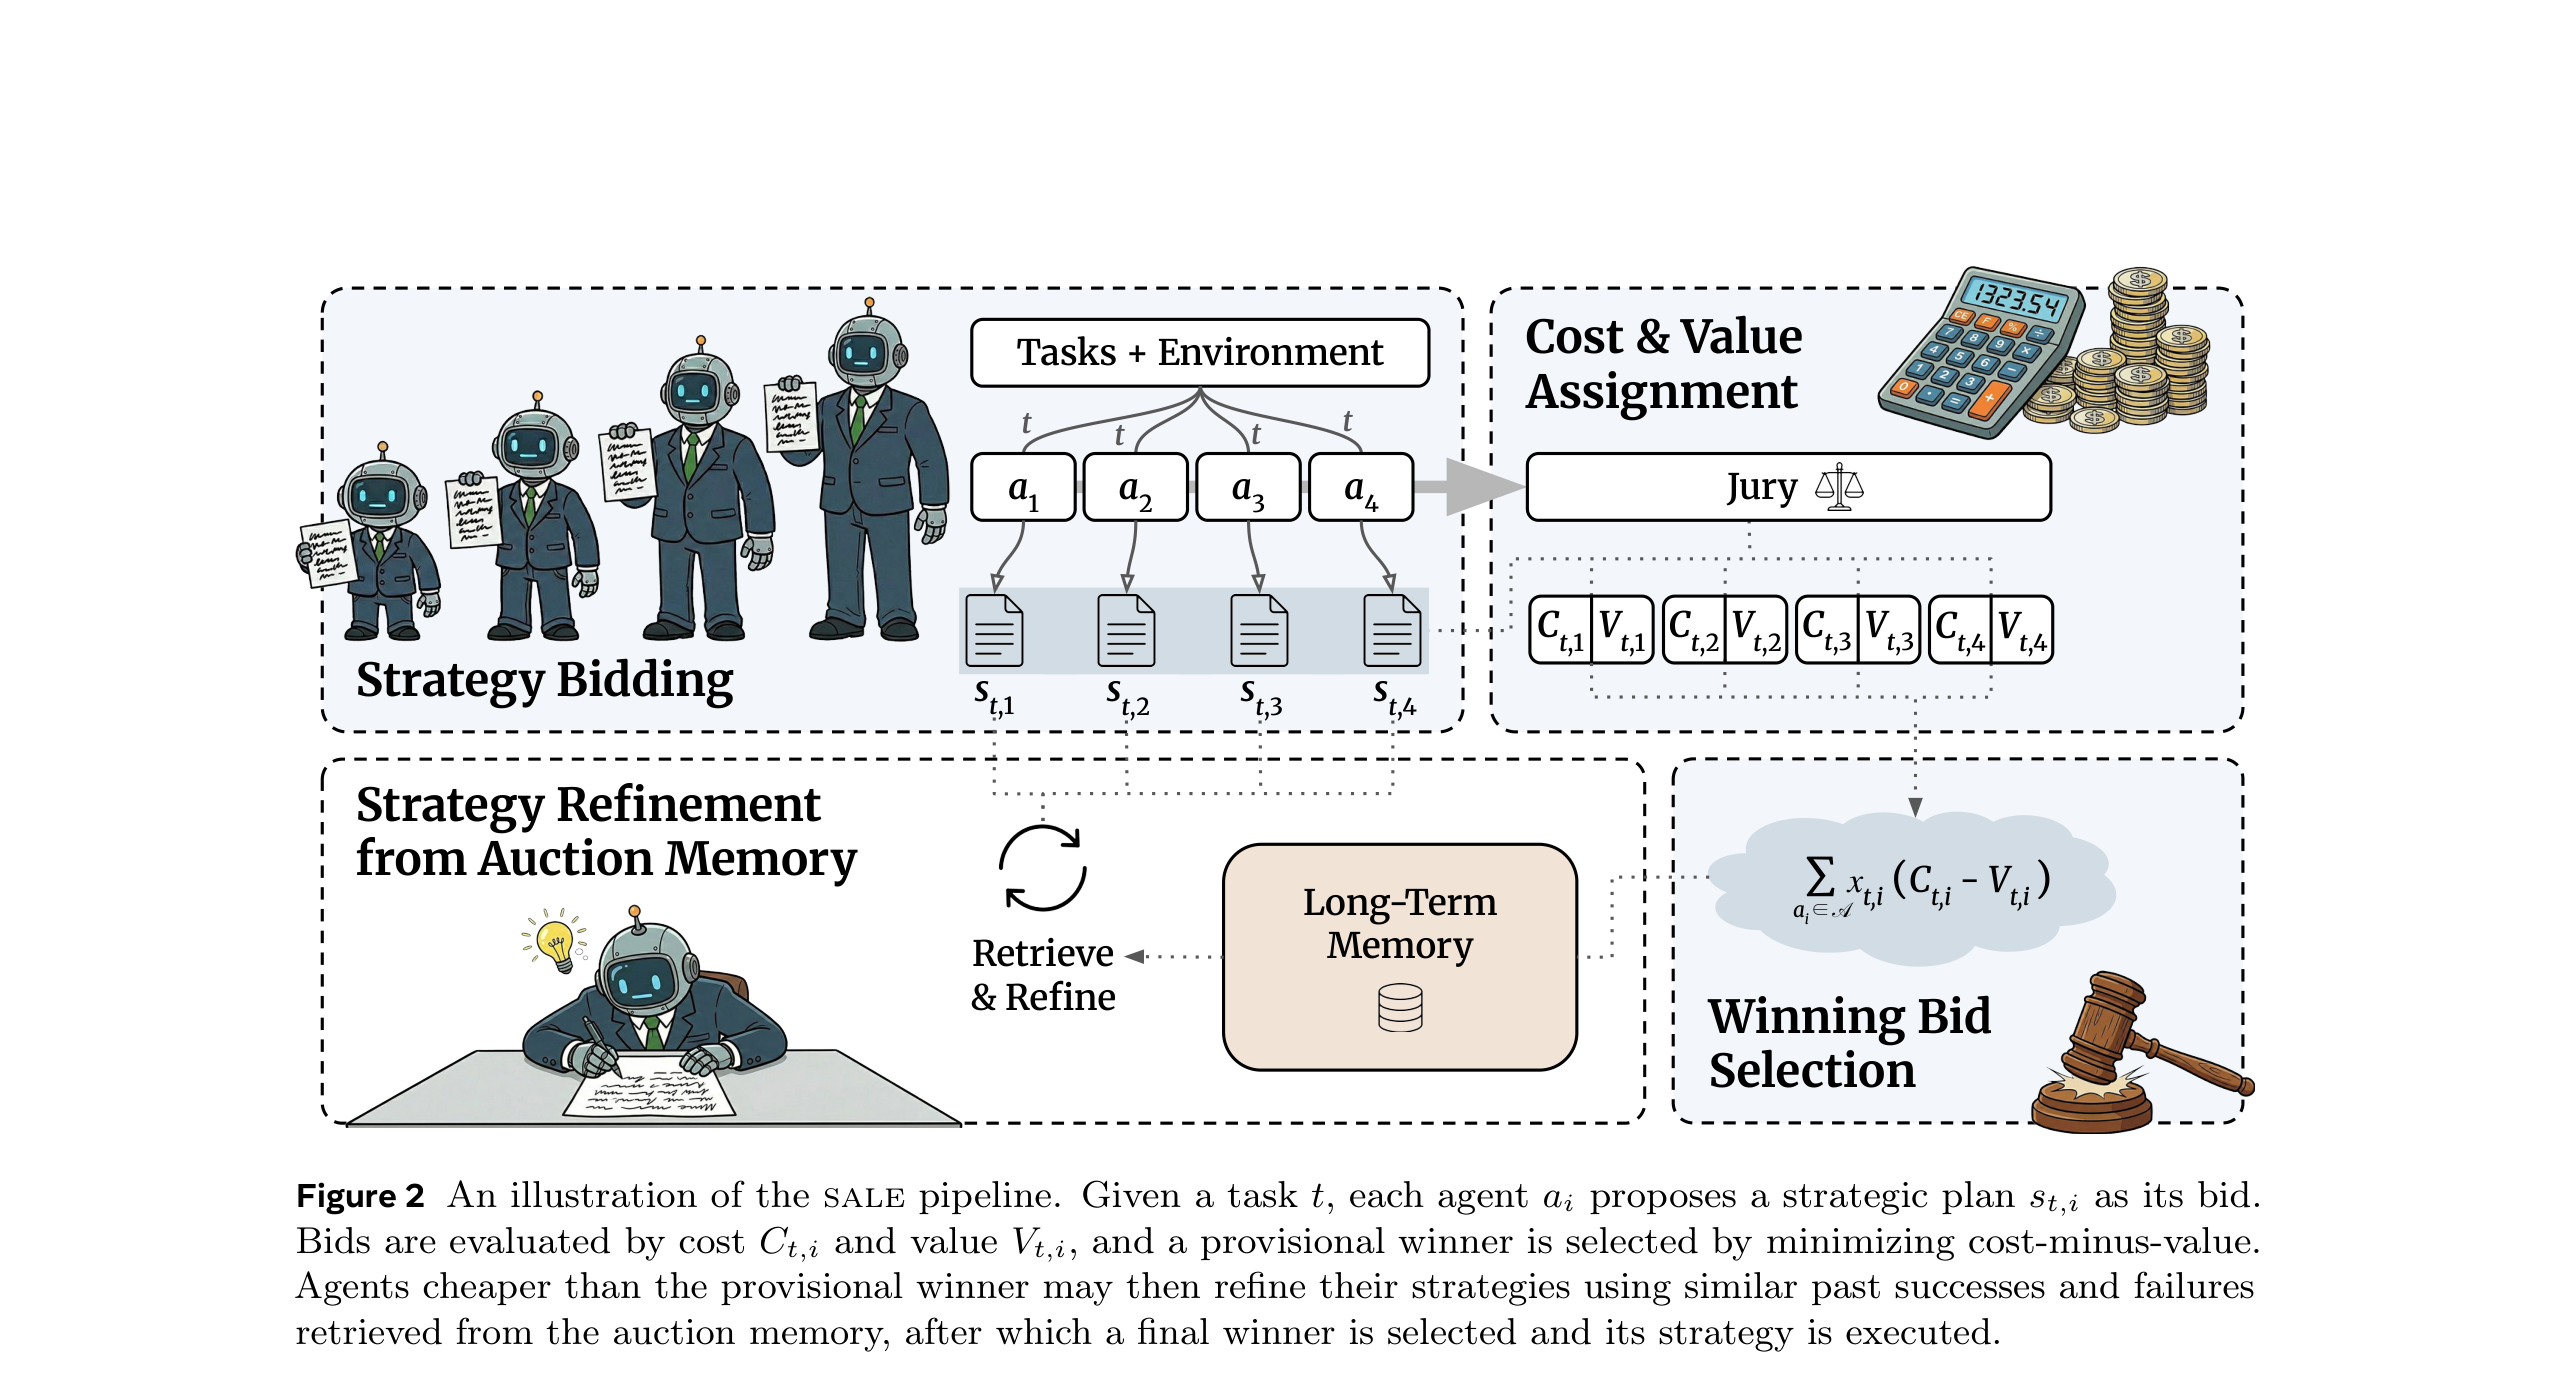
This paper from Meta shows that small agents match large ones on simple tasks but fall sharply behind as complexity grows, with the cheapest agent reaching only about 21% of the largest agent’s accuracy on the hardest problems. To address this, the authors introduce SALE (Strategy Auctions for Workload Efficiency), a marketplace-inspired framework where heterogeneous agents bid with strategic plans, are scored on cost-value trade-offs, and refine their bids using shared auction memory.
InfMem
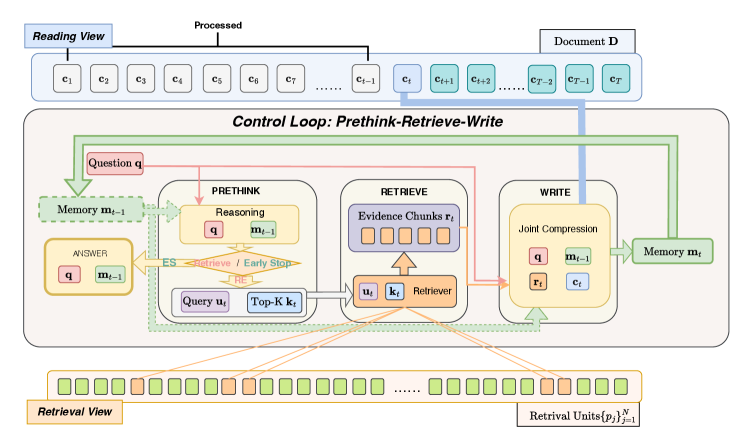
InfMem is a cognitive agent for ultra-long document QA that uses System-2-style control to actively manage bounded memory. Instead of passively compressing each chunk as it streams in, InfMem runs a PreThink-Retrieve-Write loop that monitors evidence sufficiency, fetches missing facts from anywhere in the document, and compresses everything into a fixed-size memory - then stops early once it has enough.
A-RAG
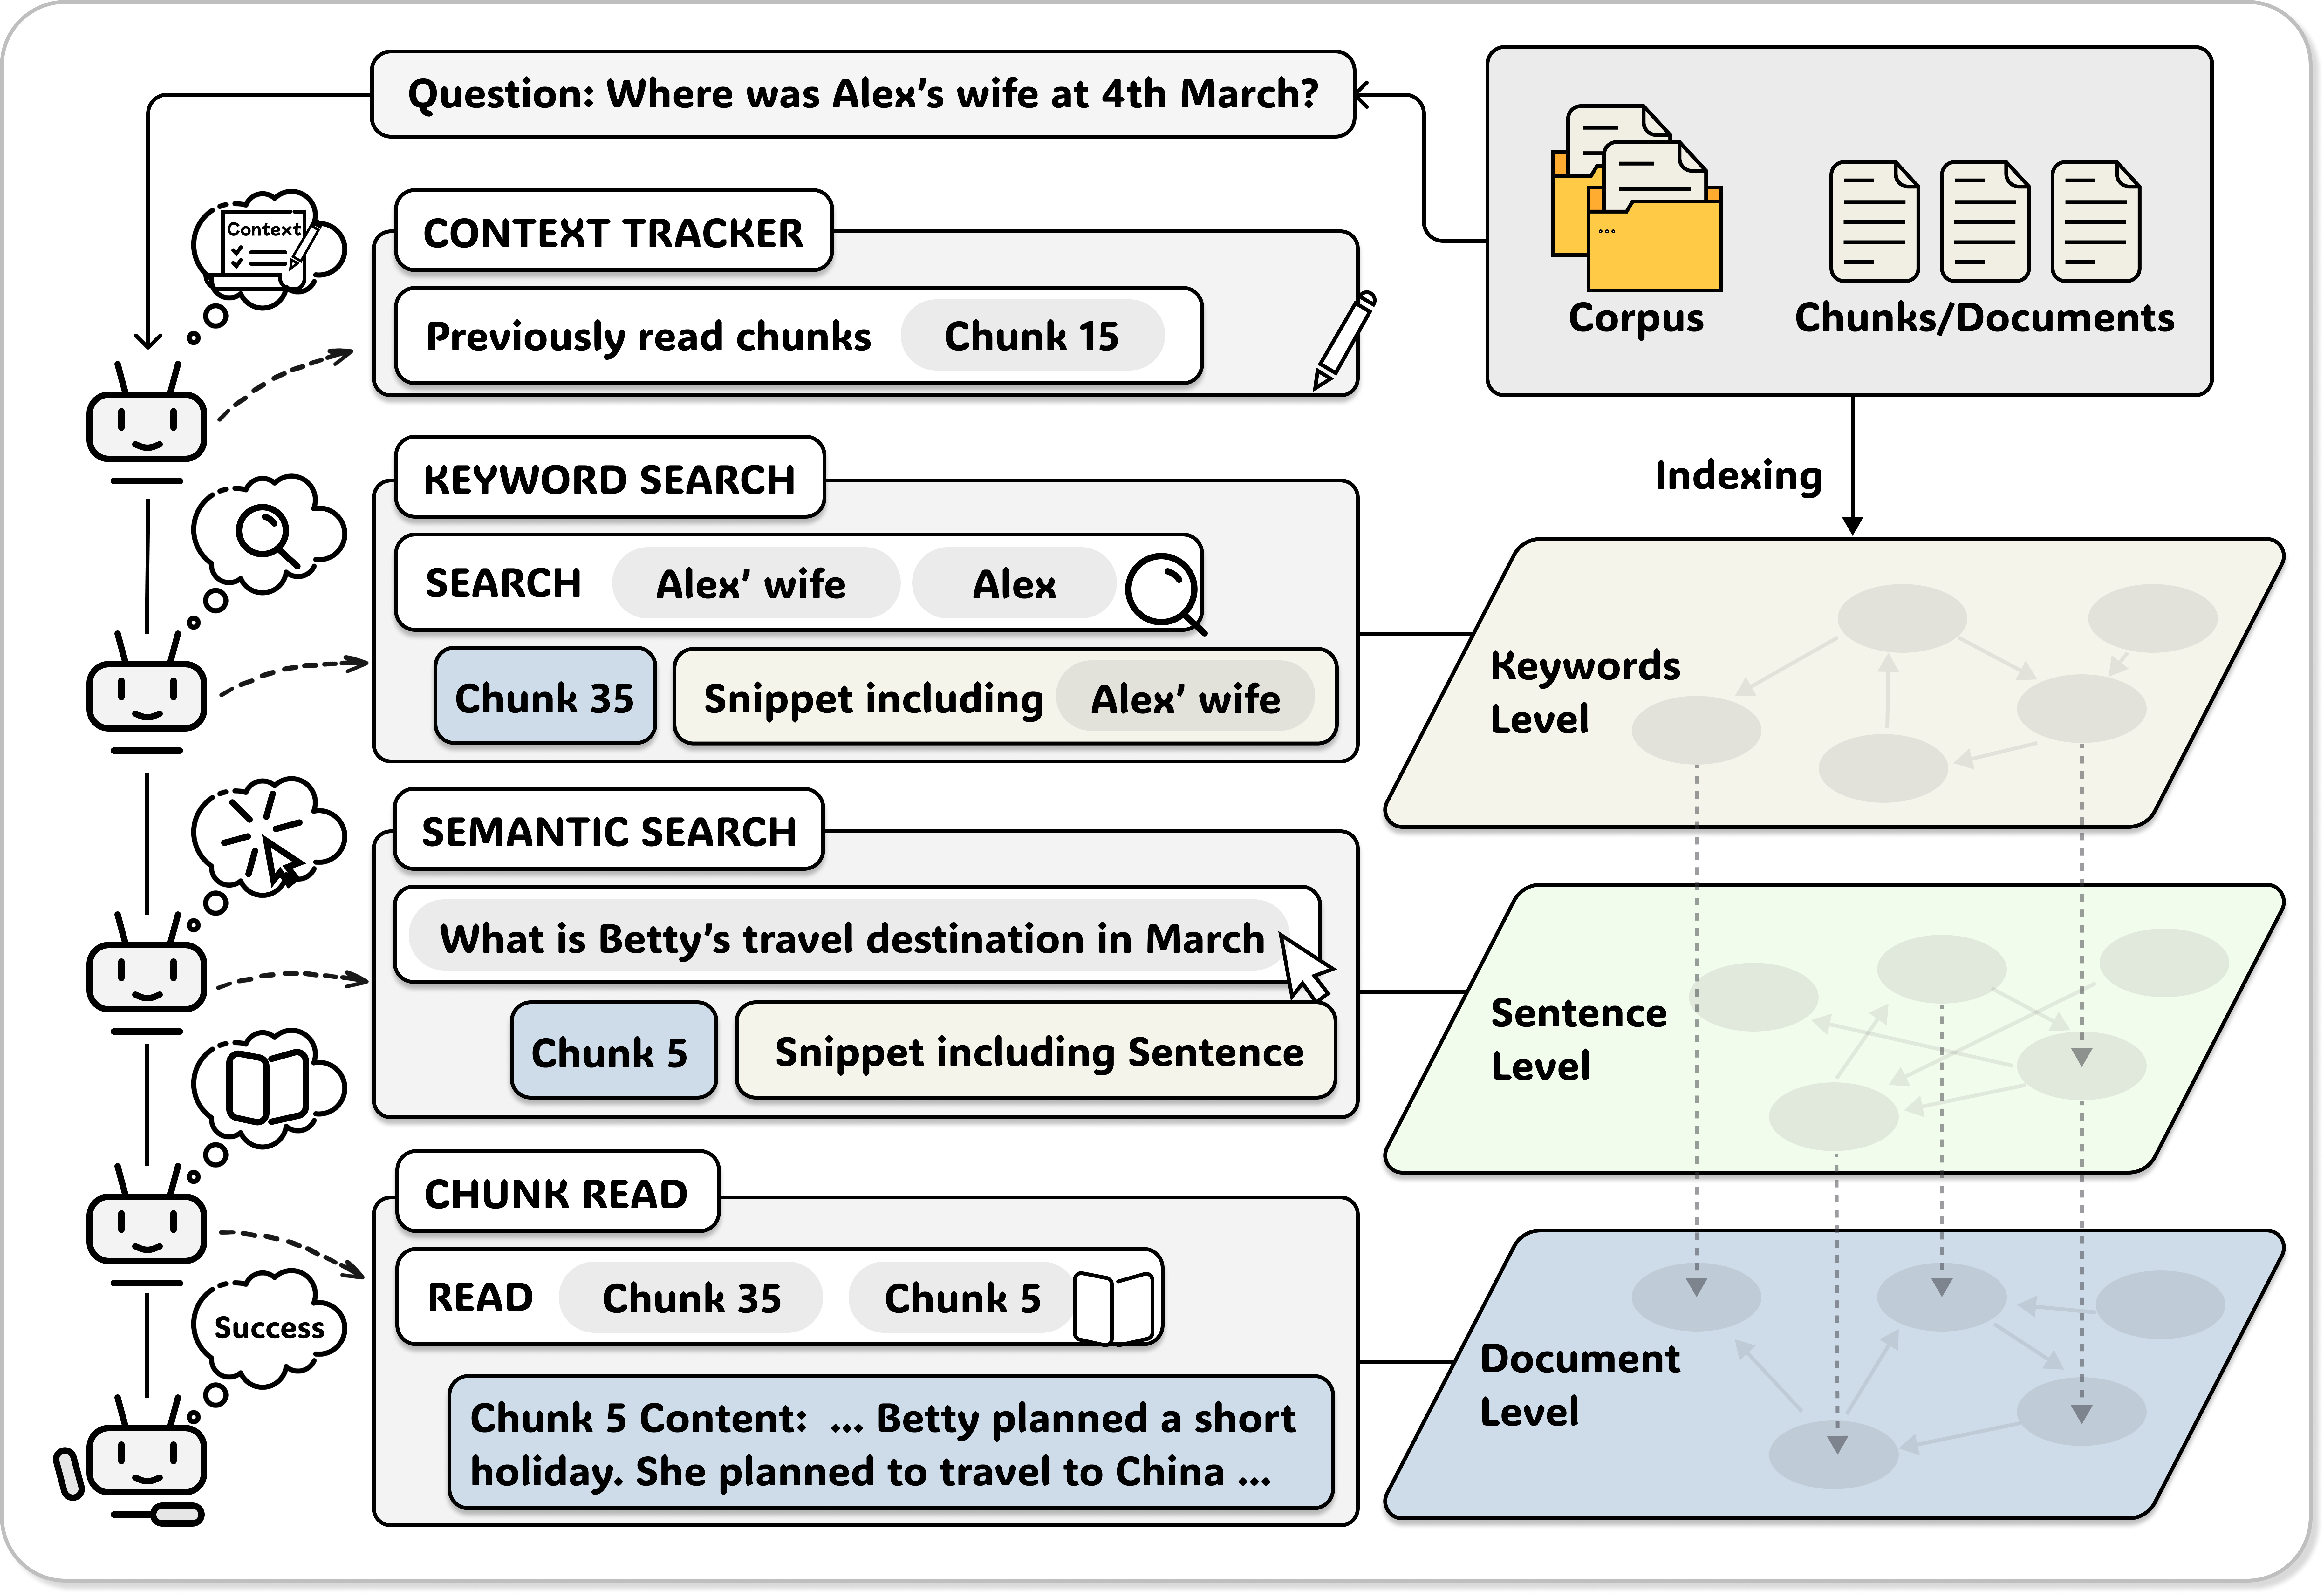
A-RAG is an agentic RAG framework that gives LLMs direct access to hierarchical retrieval interfaces instead of relying on fixed retrieval algorithms or predefined workflows. The agent autonomously decides what to search, at which granularity, and when to stop - representing a paradigm shift from static retrieval pipelines to truly agentic information gathering.
Agent Primitives
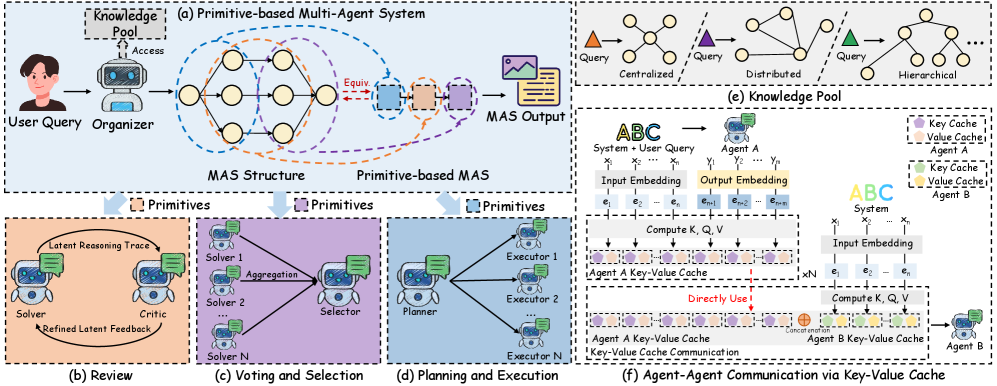
Agent Primitives introduces reusable latent building blocks for LLM-based multi-agent systems. Inspired by how neural networks are built from composable modules like residual blocks and attention heads, the authors decompose existing MAS architectures into three recurring computation patterns that communicate via KV cache instead of natural language, reducing error accumulation and boosting efficiency.
Accelerating Scientific Research with Gemini
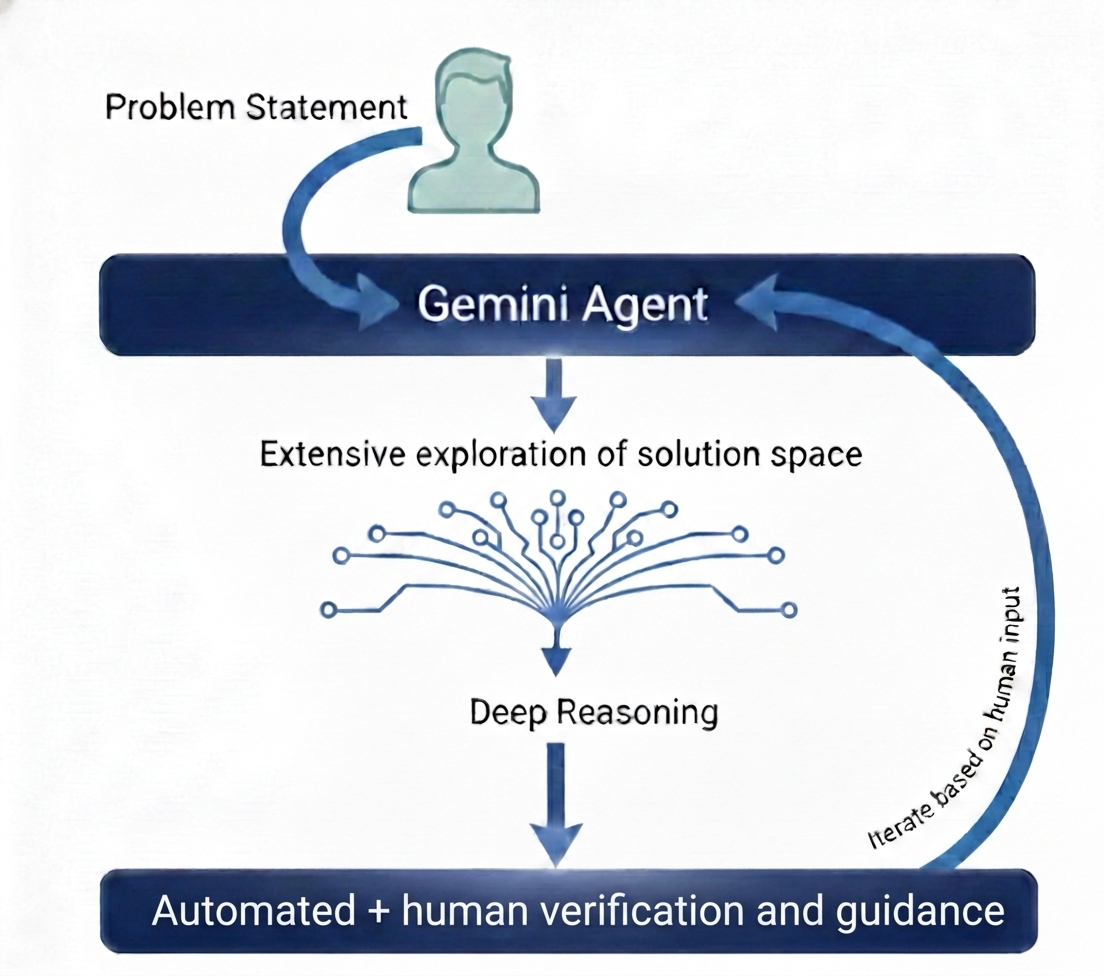
A collection of case studies from Google Research showing how researchers used Gemini Deep Think to solve open problems, refute conjectures, and generate new proofs across theoretical computer science, information theory, cryptography, optimization, economics, and physics. The paper extracts a practical playbook of recurring techniques, including iterative refinement, cross-disciplinary knowledge transfer, counterexample search, and neuro-symbolic verification loops where the model autonomously writes and executes code to validate derivations. Notable results include identifying a fatal flaw in a cryptography preprint on SNARGs, resolving the Courtade-Kumar conjecture in information theory, and proving that the simplex is optimal for Euclidean Steiner trees.
Heterogeneous Computing for AI Agent Inference
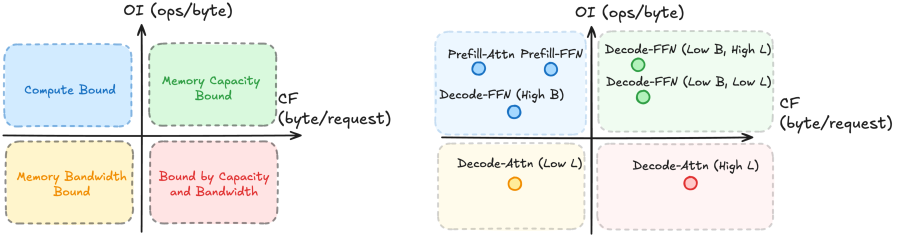
This paper introduces Operational Intensity (OI) and Capacity Footprint (CF) as two metrics that better characterize AI agent inference workloads than traditional roofline models, revealing that memory capacity - not just bandwidth or compute - is often the true bottleneck. Analysis across agent types (chatbot, coding, web-use, computer-use) shows that agentic workflows create vastly different and rapidly growing demands on hardware, with context lengths snowballing to over 1M tokens in coding agents. The authors argue for disaggregated, heterogeneous compute architectures with specialized prefill and decode accelerators, hardware-aware model co-design, and large-capacity memory disaggregation as essential directions for scaling AI agent systems.
Kimi K2.5: Visual Agentic Intelligence
Kimi K2.5 is an open-source multimodal agentic model from Moonshot AI that jointly optimizes text and vision capabilities through native multimodal pretraining on 15 trillion mixed tokens, zero-vision SFT, and joint reinforcement learning. K2.5 also introduces Agent Swarm, a parallel agent orchestration framework that dynamically decomposes complex tasks into concurrent subtasks, reducing latency by up to 4.5x over single-agent baselines.
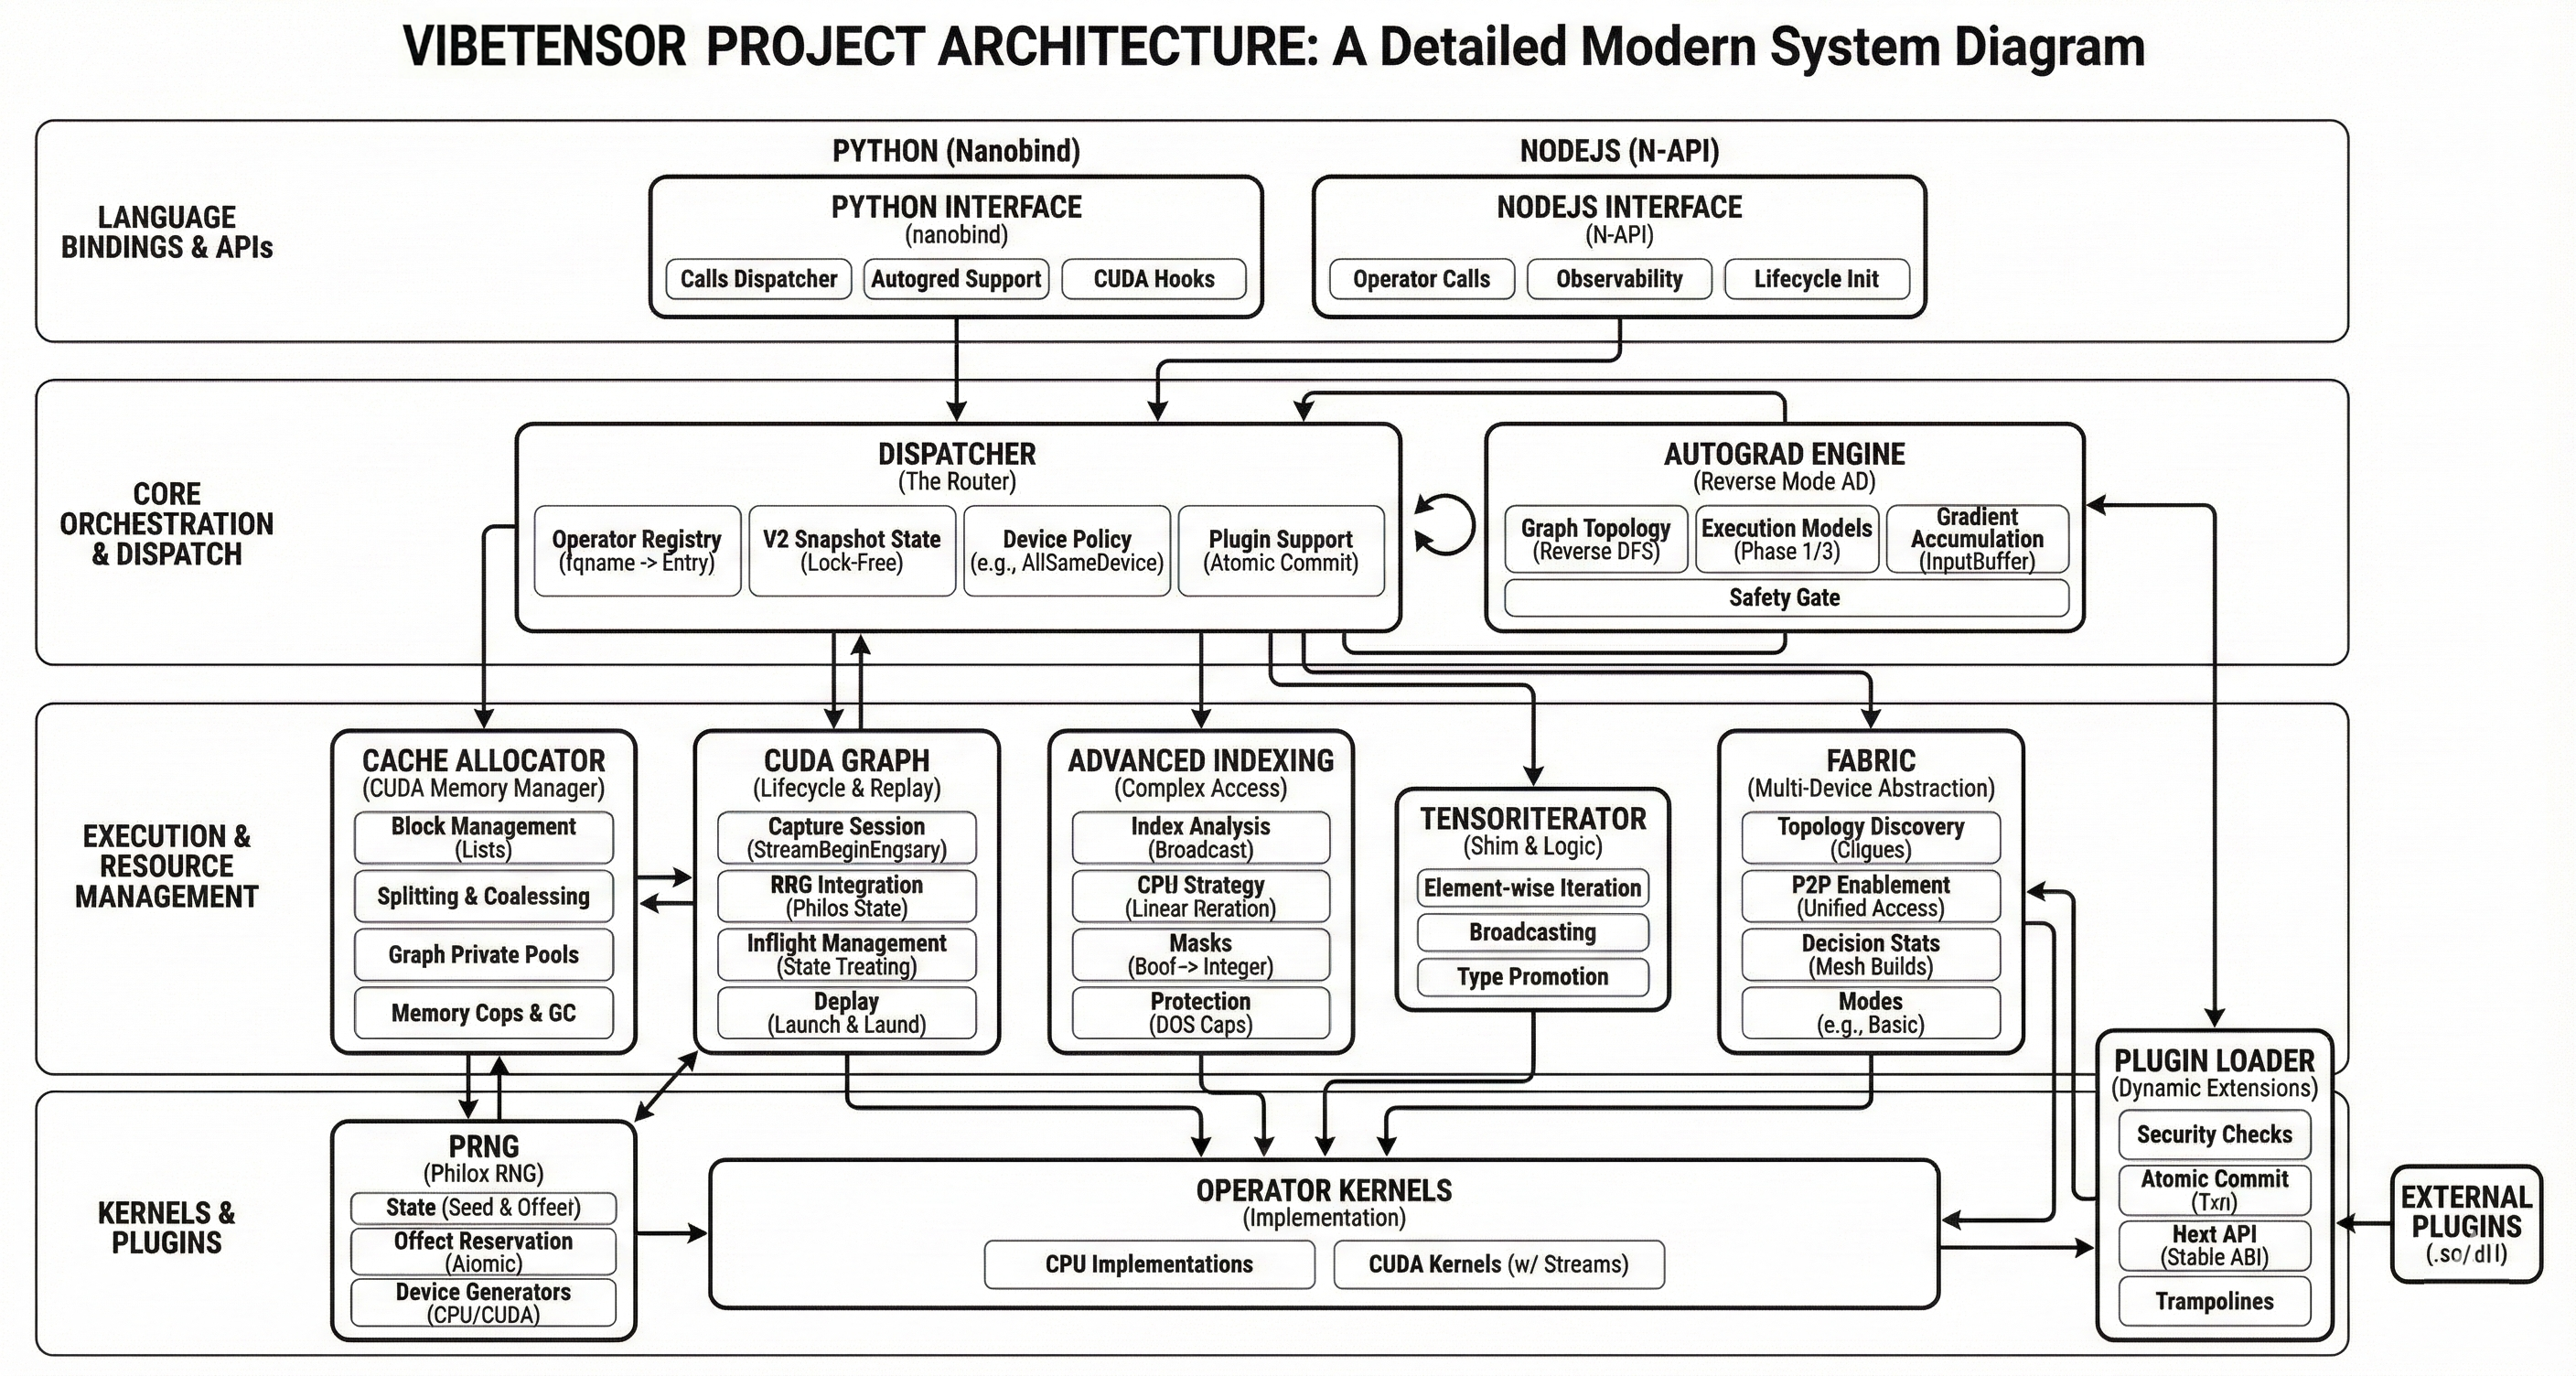
VibeTensor
VibeTensor is an open-source deep learning system software stack from NVLabs that was fully generated by LLM-powered coding agents under high-level human guidance. The system implements a PyTorch-style eager tensor library with a C++20/CUDA core, Python and Node.js frontends, its own autograd engine, CUDA runtime, and caching allocator - demonstrating that coding agents can produce coherent system software spanning language bindings down to GPU memory management.
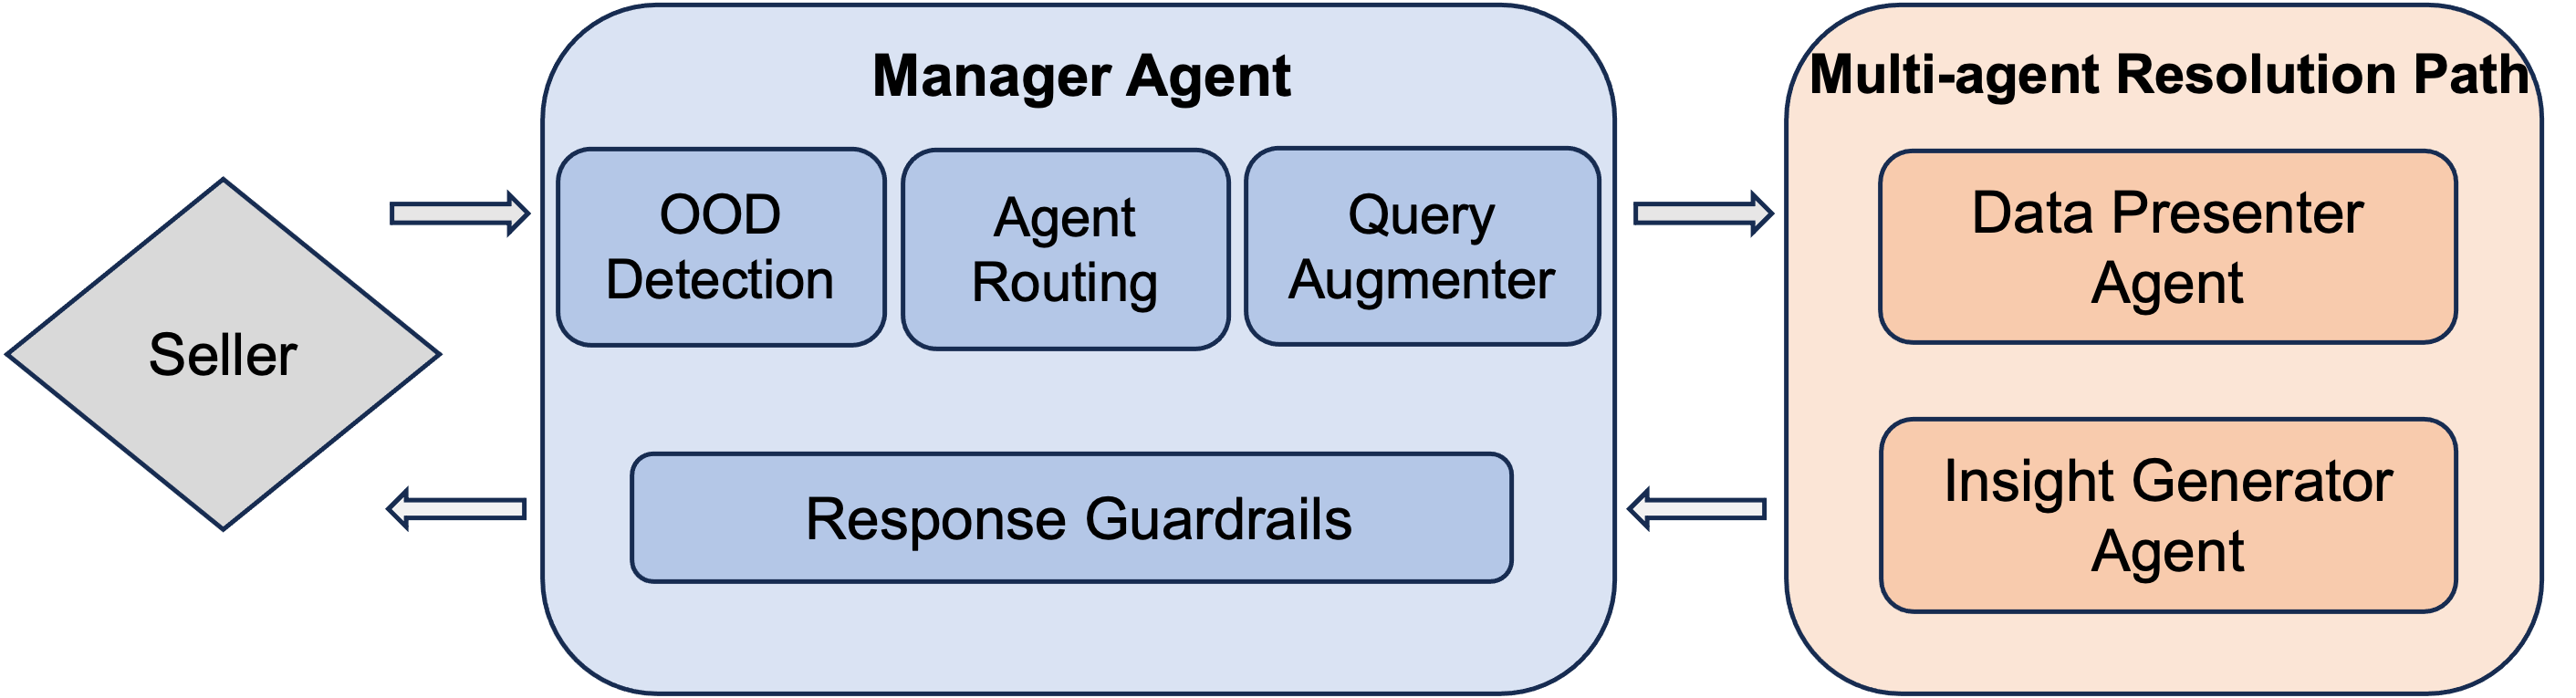
Insight Agents: Multi-Agent System for Data Insights
Insight Agents introduces a hierarchical multi-agent system built on a plan-and-execute paradigm for delivering personalized business insights to e-commerce sellers. The system uses a manager agent with OOD detection via a lightweight encoder-decoder model and BERT-based routing to coordinate two worker agents (data presenter and insight generator), achieving 90% accuracy with P90 latency below 15 seconds. Accepted at SIGIR 2025 and deployed for Amazon sellers in the US.
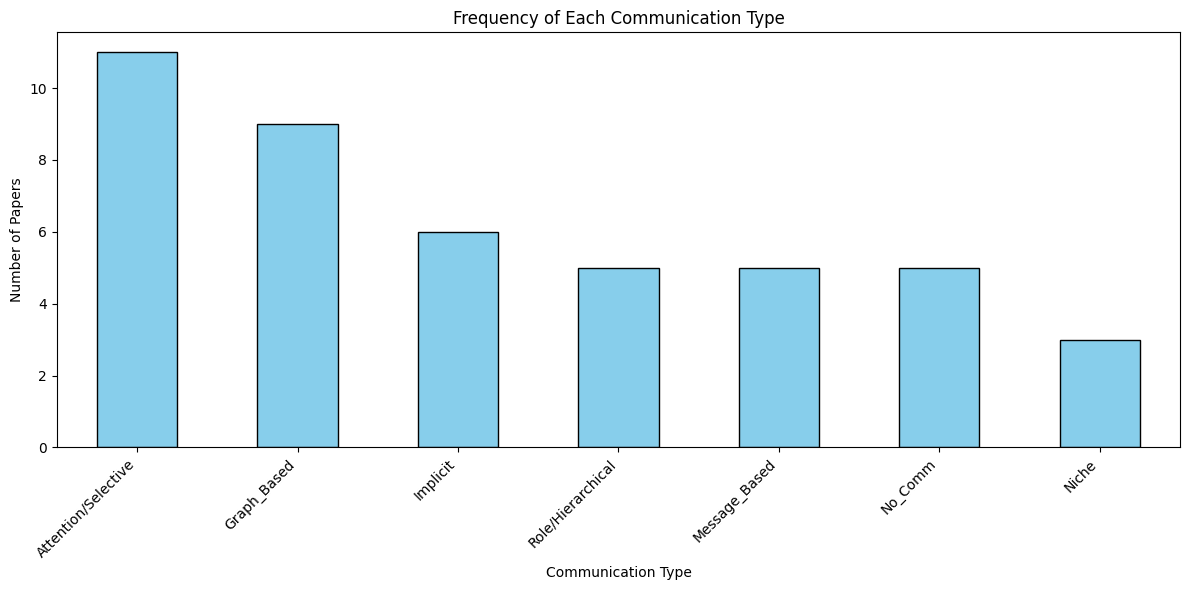
Communication Methods in Multi-Agent RL
A systematic survey of 29 papers reviewing how agents coordinate in multi-agent reinforcement learning, covering fully connected message passing, implicit communication, attention-based selective methods, graph-based relational approaches, and role-based hierarchical frameworks. The analysis reveals that attention- and graph-based methods dominate recent research, while implicit communication is seeing renewed interest for its scalability in decentralized settings where explicit channels are infeasible.
Team of Rivals: Orchestrating Reliable AI Agents
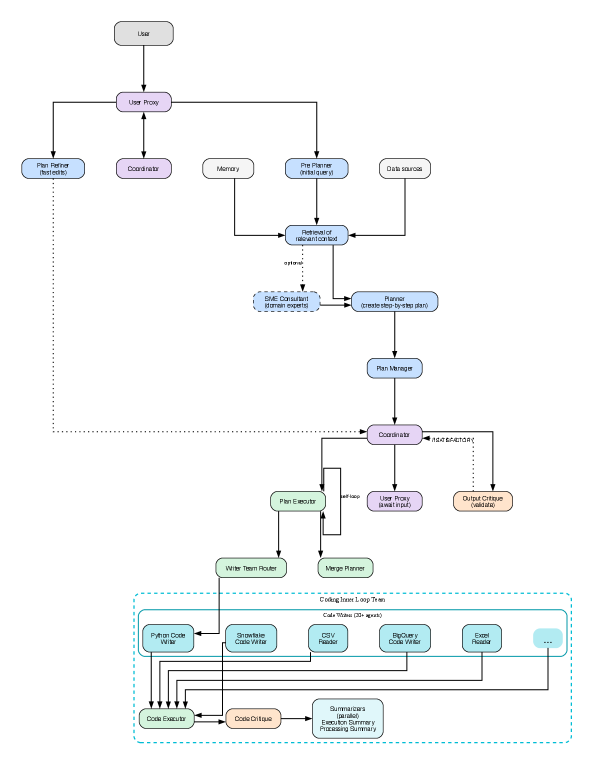
This paper proposes organizing AI agents into corporate-style teams with strict role boundaries and opposing incentives (planners, executors, critics, experts) to achieve reliability through careful orchestration of imperfect components. A remote code executor separates reasoning from data transformations, preventing raw tool outputs from contaminating agent context windows. The system achieves over 90% internal error interception before user exposure while maintaining acceptable latency tradeoffs.
Memory Control for Long-Horizon Agents
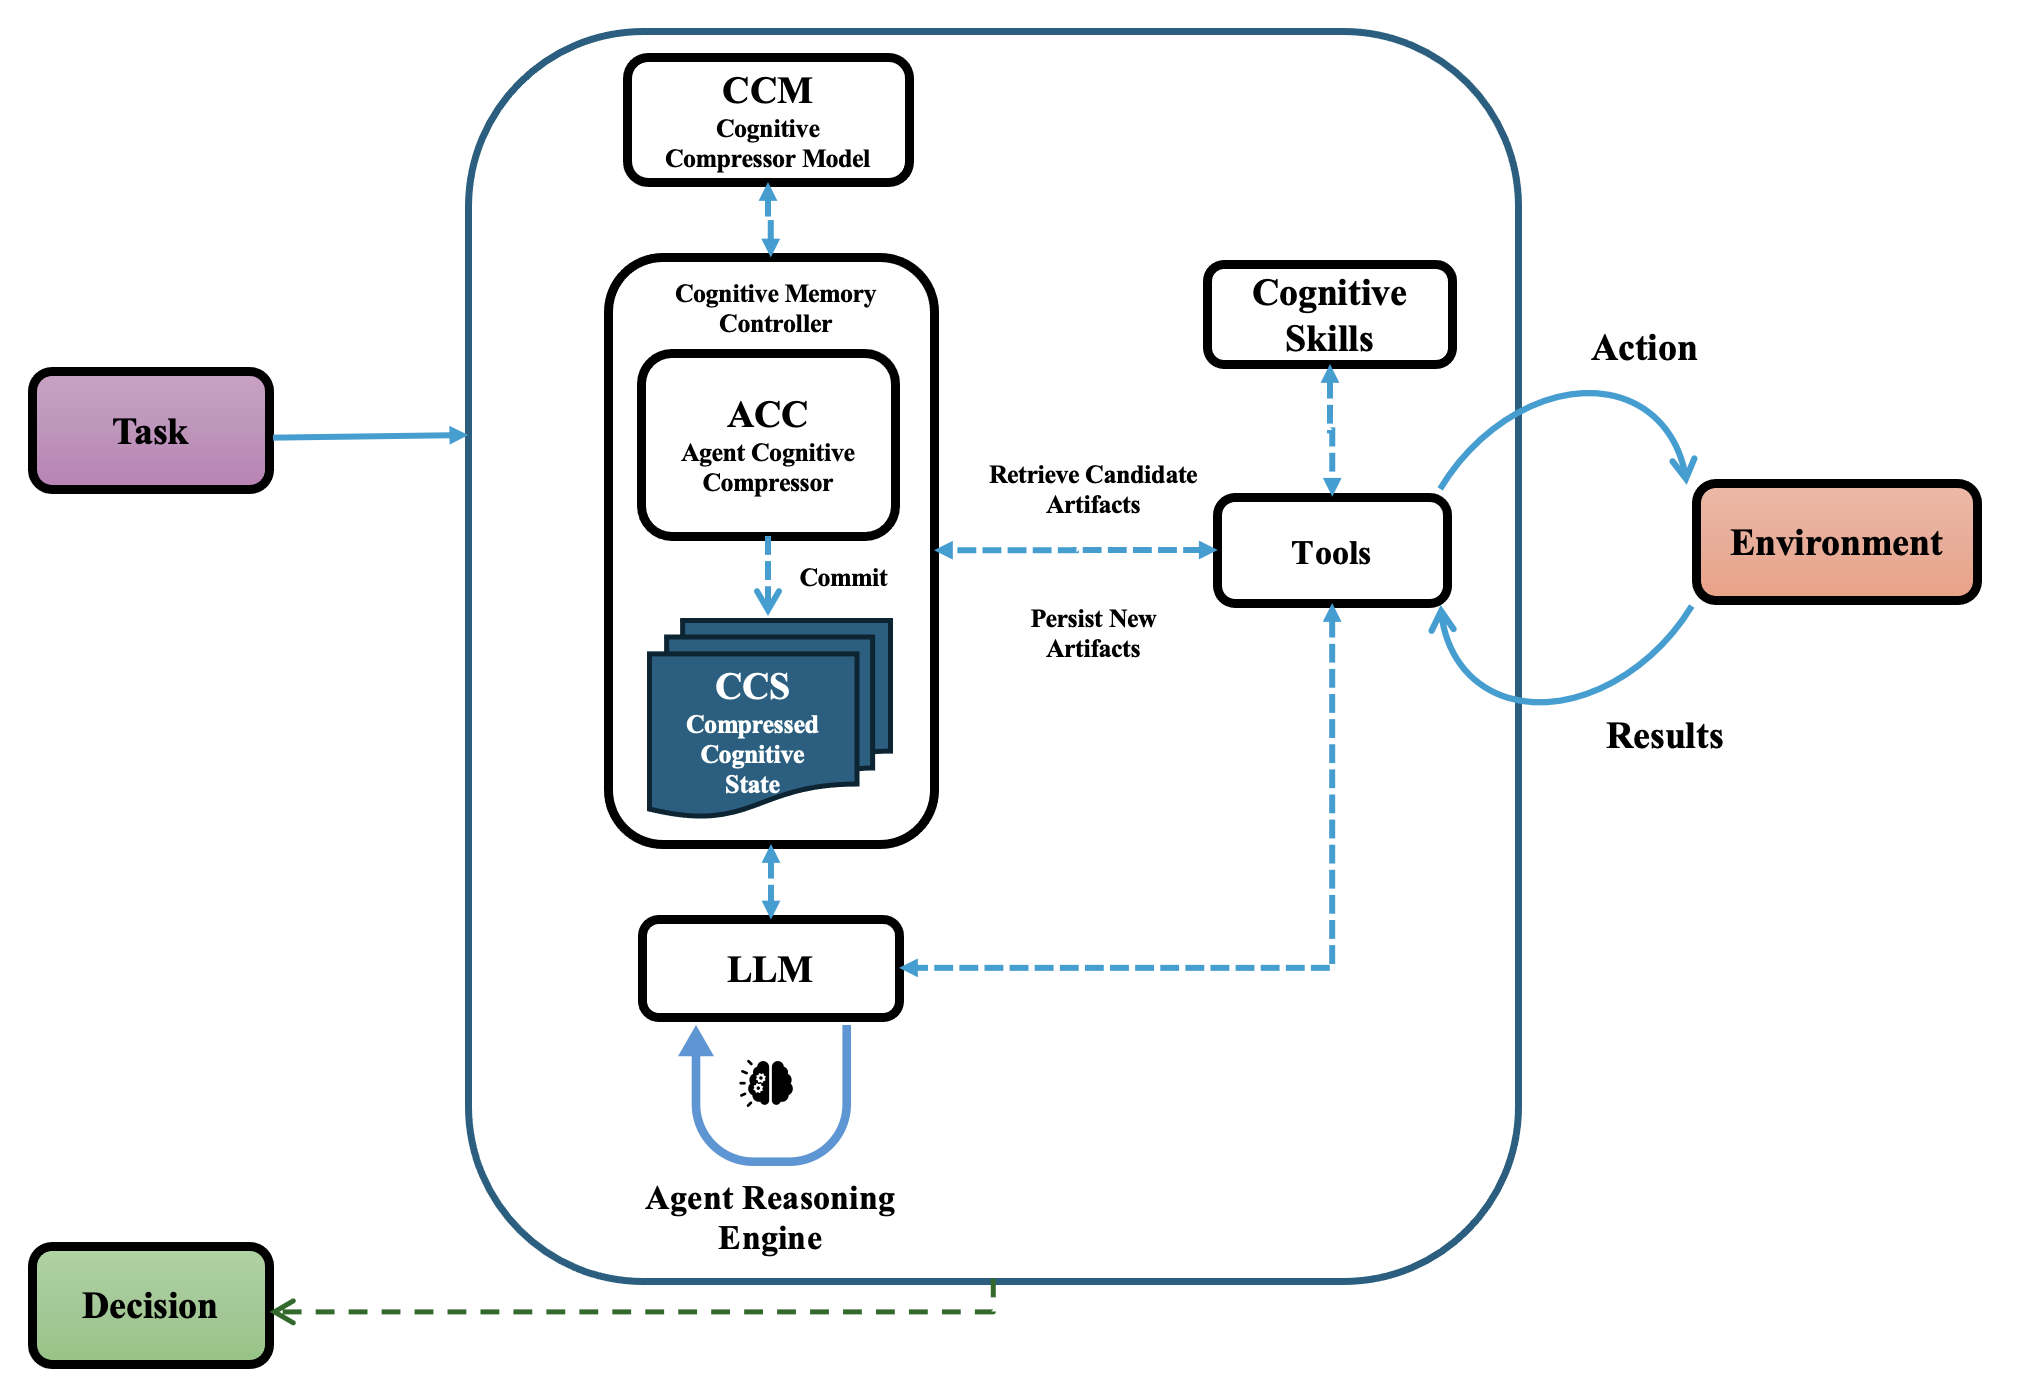
This paper introduces the Agent Cognitive Compressor (ACC), a bio-inspired mechanism that addresses degraded agent behavior in long multi-turn workflows caused by loss of constraint focus, error accumulation, and memory-induced drift. ACC replaces continuous transcript retention with a bounded internal state that updates incrementally during each interaction turn.
Benchmarking Agents on Hard CLI Tasks
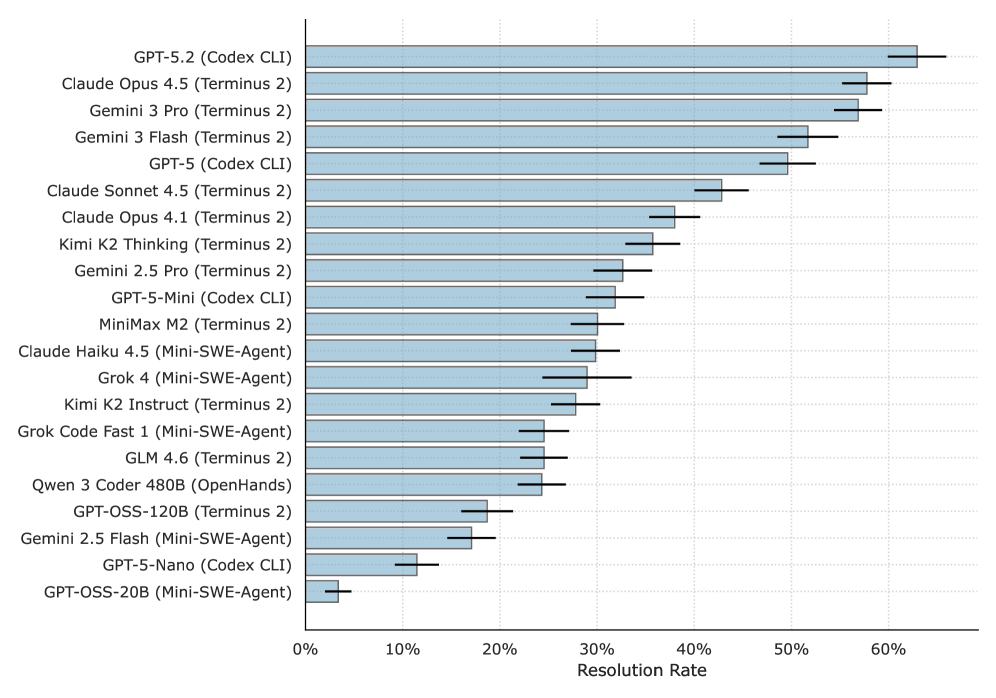
Terminal-Bench 2.0 presents a carefully curated hard benchmark composed of 89 tasks in computer terminal environments inspired by problems from real workflows. Each task features a unique environment, human-written solution, and comprehensive tests for verification, addressing the gap where current benchmarks either don’t measure real-world tasks or aren’t sufficiently difficult.
Rethinking Multi-Agent Workflows
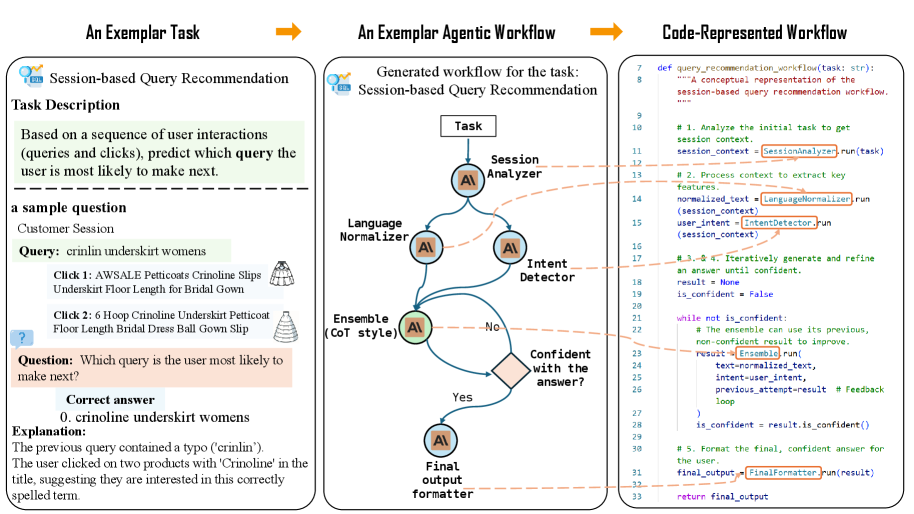
This paper challenges the assumption that complex tasks require multiple specialized AI agents, demonstrating that a single LLM agent, through iterative dialogue, can match the performance of homogeneous multi-agent workflows while gaining efficiency from KV cache reuse.
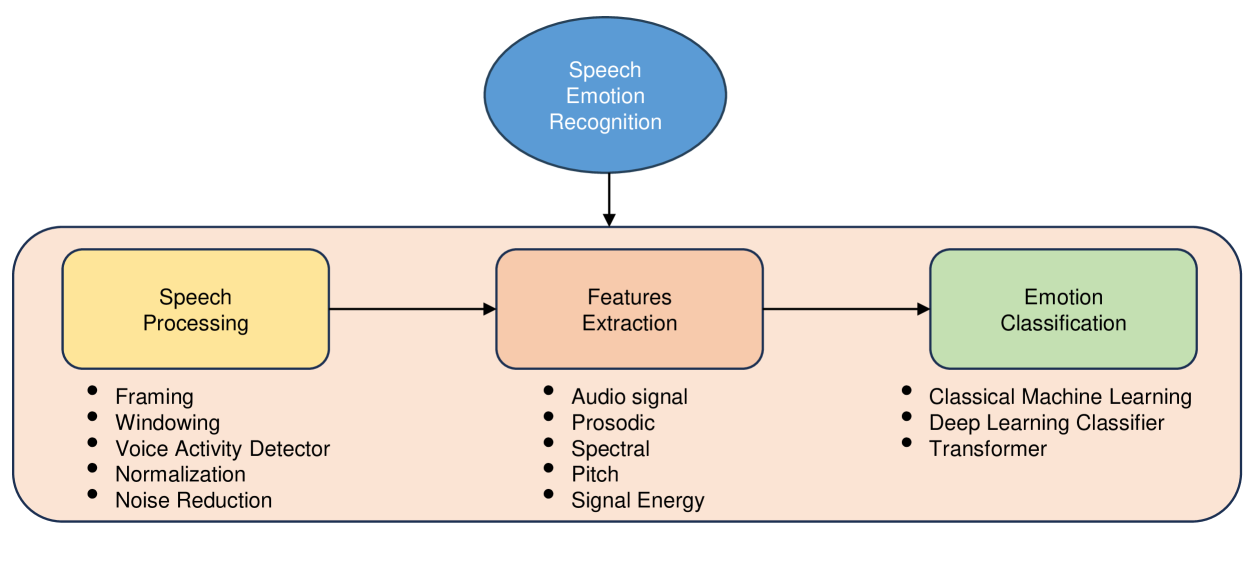
Self-Correcting Multi-Agent LLM for Physics Simulation
This paper introduces a self-correcting multi-agent LLM framework for language-based physics simulation and explanation. The system enables natural language queries to generate physics simulations while providing explanations of the underlying physical phenomena.
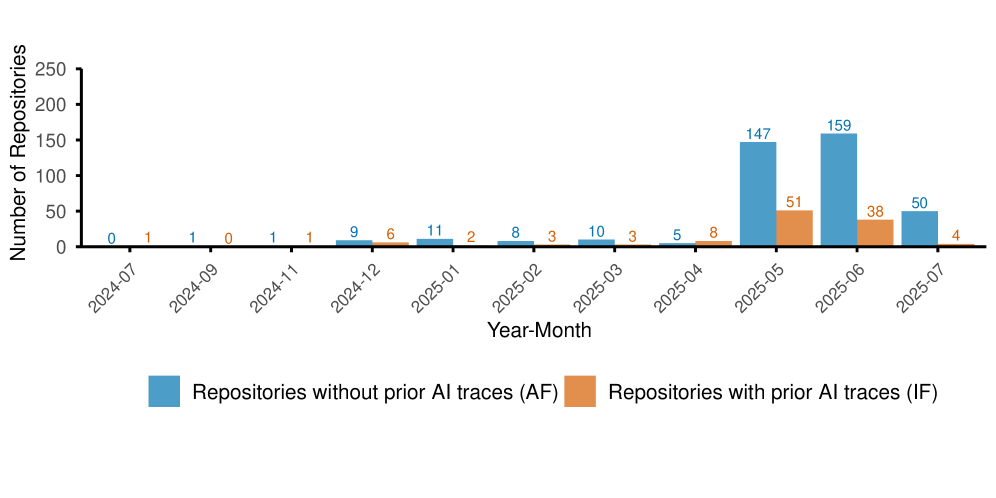
AI IDEs vs Autonomous Agents
This empirical study investigates how LLM-based coding agents that autonomously generate and merge pull requests affect open-source projects compared to IDE-integrated AI assistants. Using longitudinal causal analysis with matched controls, the researchers measure development velocity and software quality outcomes.
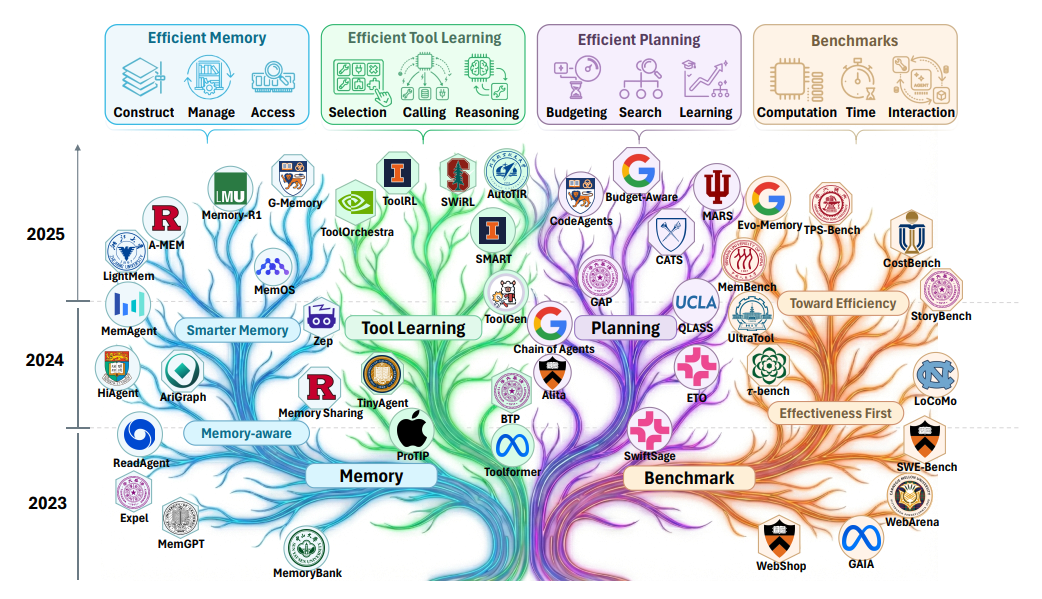
Efficient Agents
A comprehensive review examining how to make LLM-based agents more efficient for real-world deployment, focusing on three core components: memory (bounding context via compression), tool learning (RL strategies to minimize tool invocation), and planning (controlled search mechanisms). The paper characterizes efficiency through dual metrics and Pareto frontier analysis between effectiveness and cost.
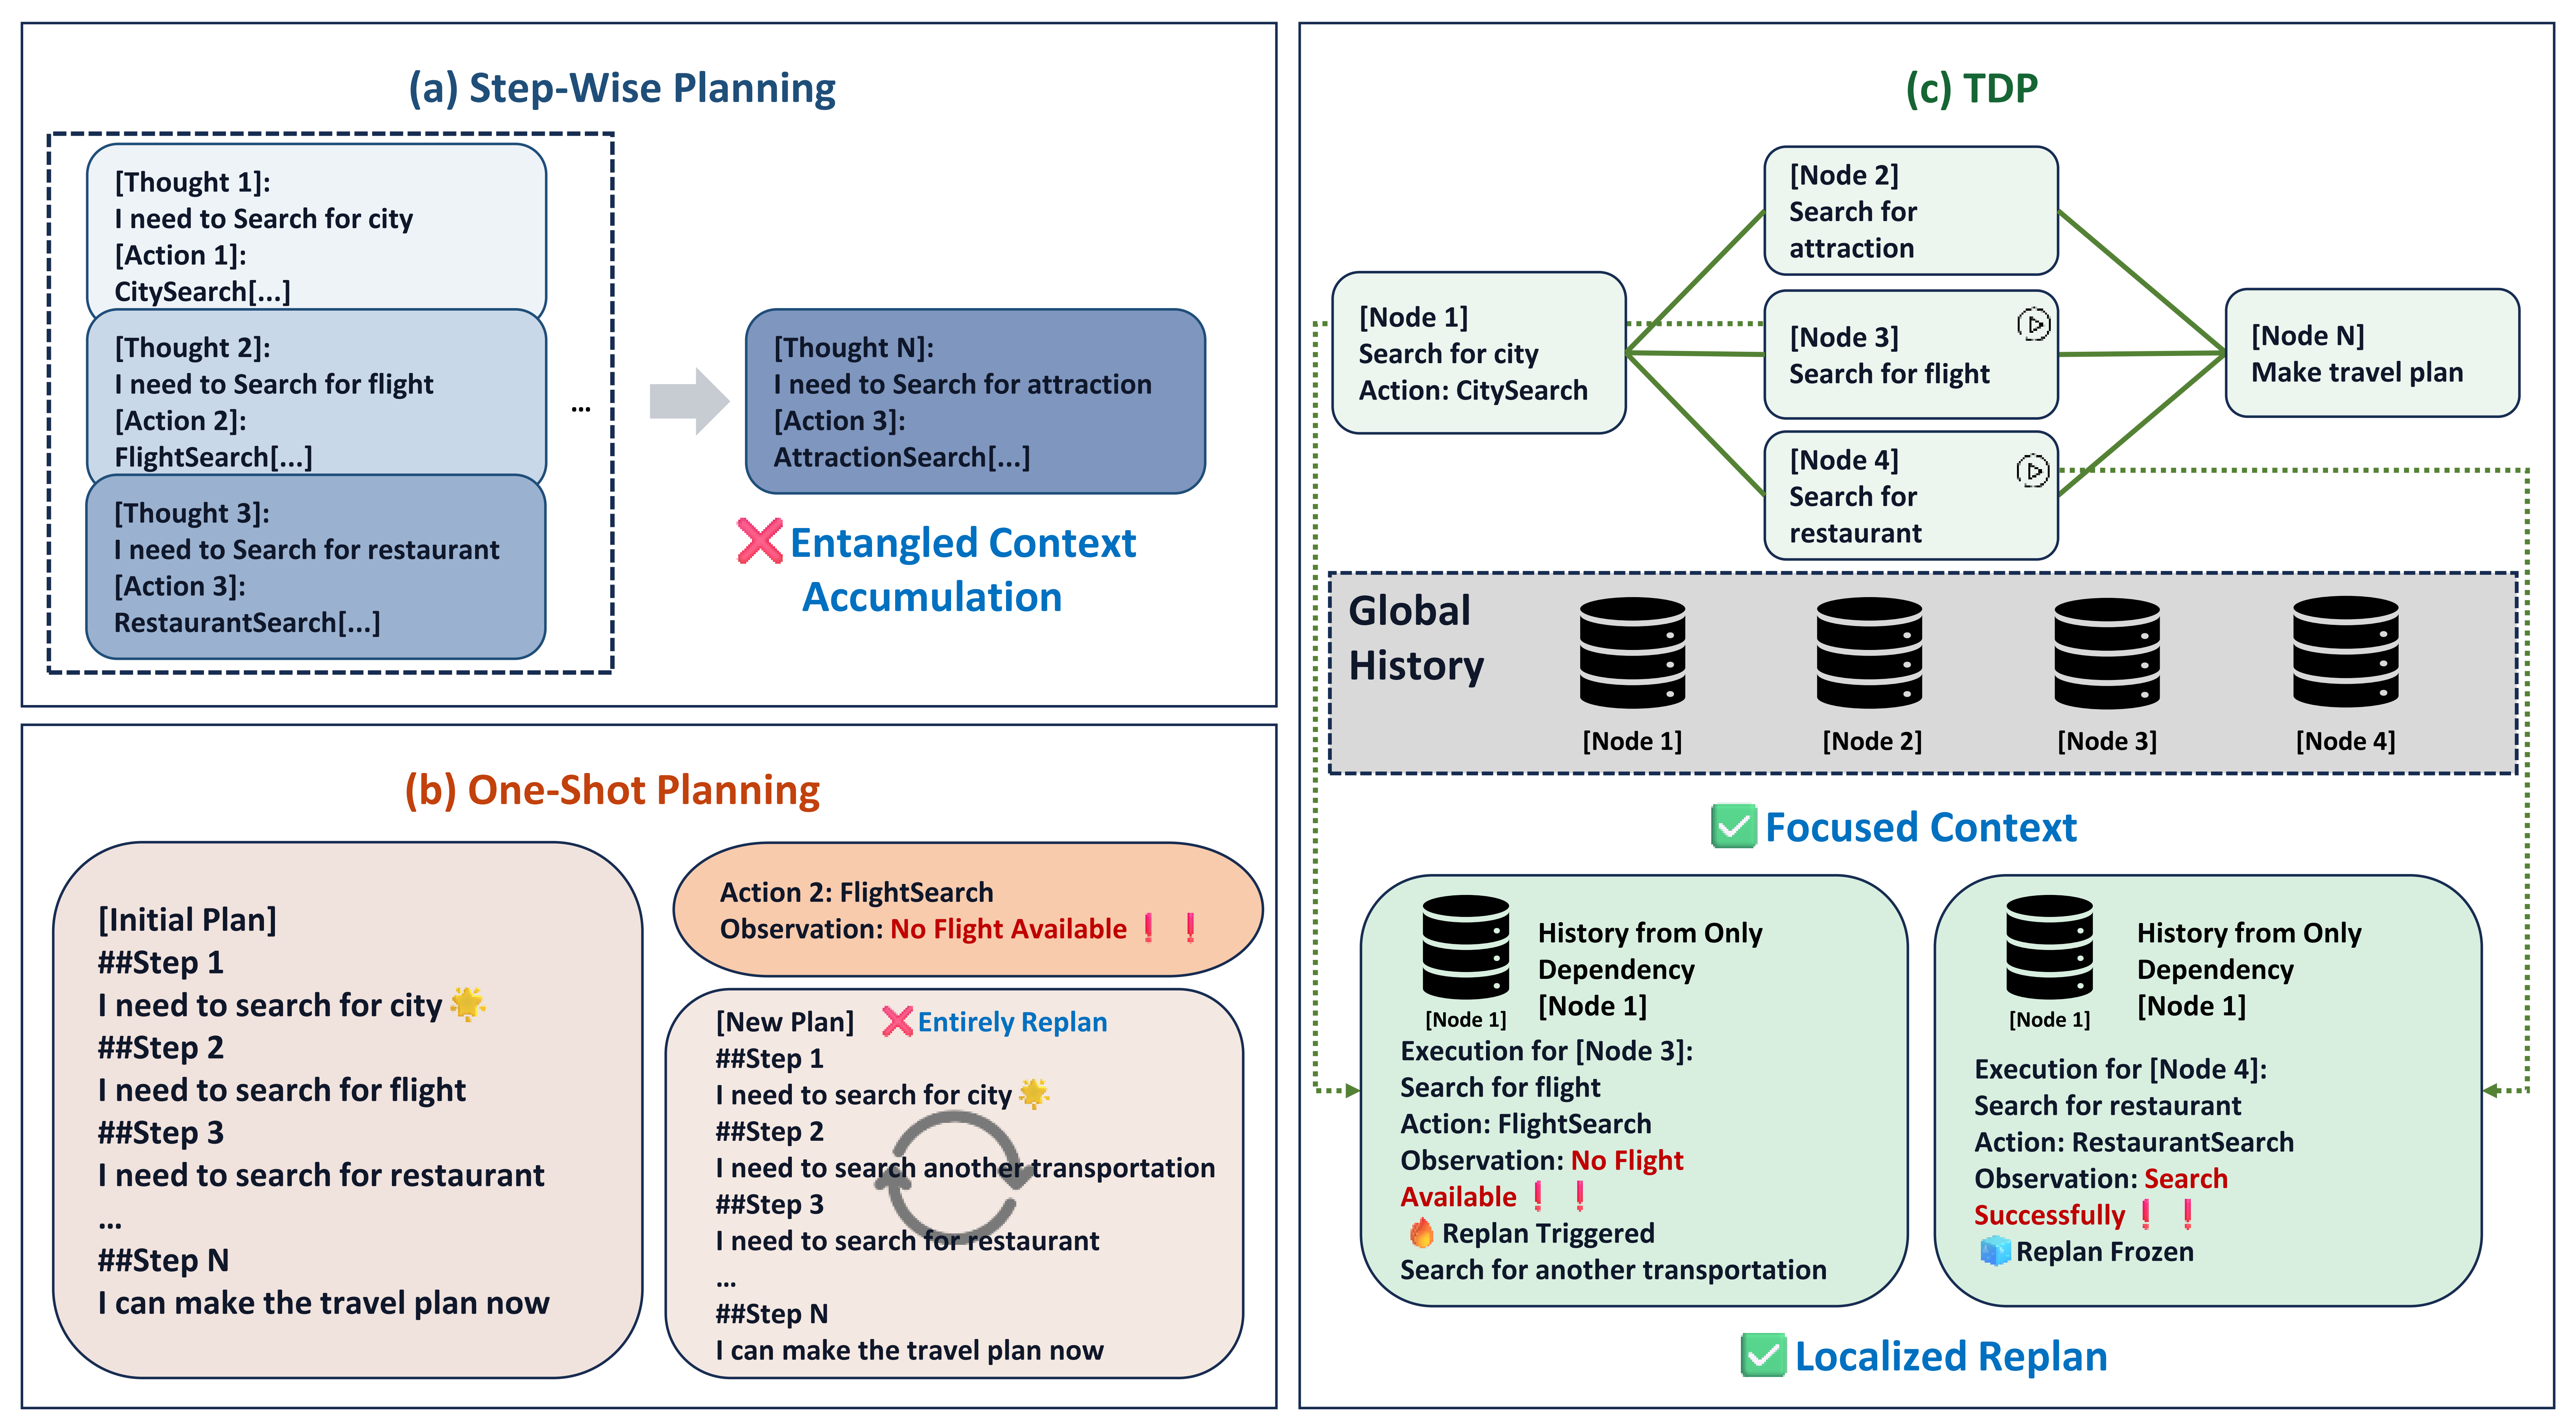
Task-Decoupled Planning for Long-Horizon Agents
Task-Decoupled Planning (TDP) is a training-free framework that restructures agent planning by decomposing tasks into a directed acyclic graph of sub-goals using three components: Supervisor, Planner, and Executor. By isolating reasoning to individual subtasks through scoped contexts, TDP prevents error cascading and reduces token consumption by up to 82% while outperforming baselines on TravelPlanner, ScienceWorld, and HotpotQA.
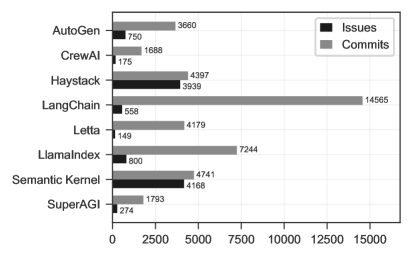
Large-Scale Study on Multi-Agent AI Systems Development
An empirical analysis of over 42,000 commits and 4,700 resolved issues across eight leading multi-agent frameworks (LangChain, CrewAI, AutoGen). Key findings: feature enhancements dominate at 40.8% of changes versus 27.4% bug fixes, bugs represent 22% of issues, with agent coordination challenges at 10%, and issue reporting surged notably beginning in 2023.
Self-Evolving Search Agents Without Training Data
Dr. Zero introduces a framework for developing multi-turn search agents that improve themselves autonomously without labeled training data. A proposer generates diverse questions to train a solver initialized from the same base model, creating a self-evolution loop with automated curriculum difficulty scaling.
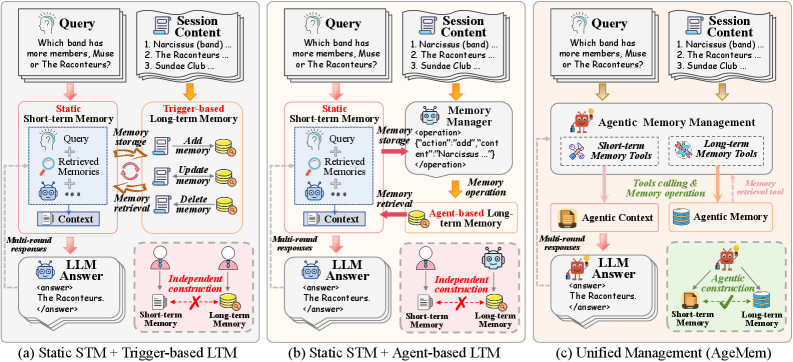
Unified Long-Term and Short-Term Memory for LLM Agents
AgeMem introduces a unified framework that integrates both long-term and short-term memory operations into an LLM agent’s decision-making policy. The system enables agents to autonomously determine what and when to store, retrieve, update, summarize, or discard information by exposing memory operations as tool-based actions.
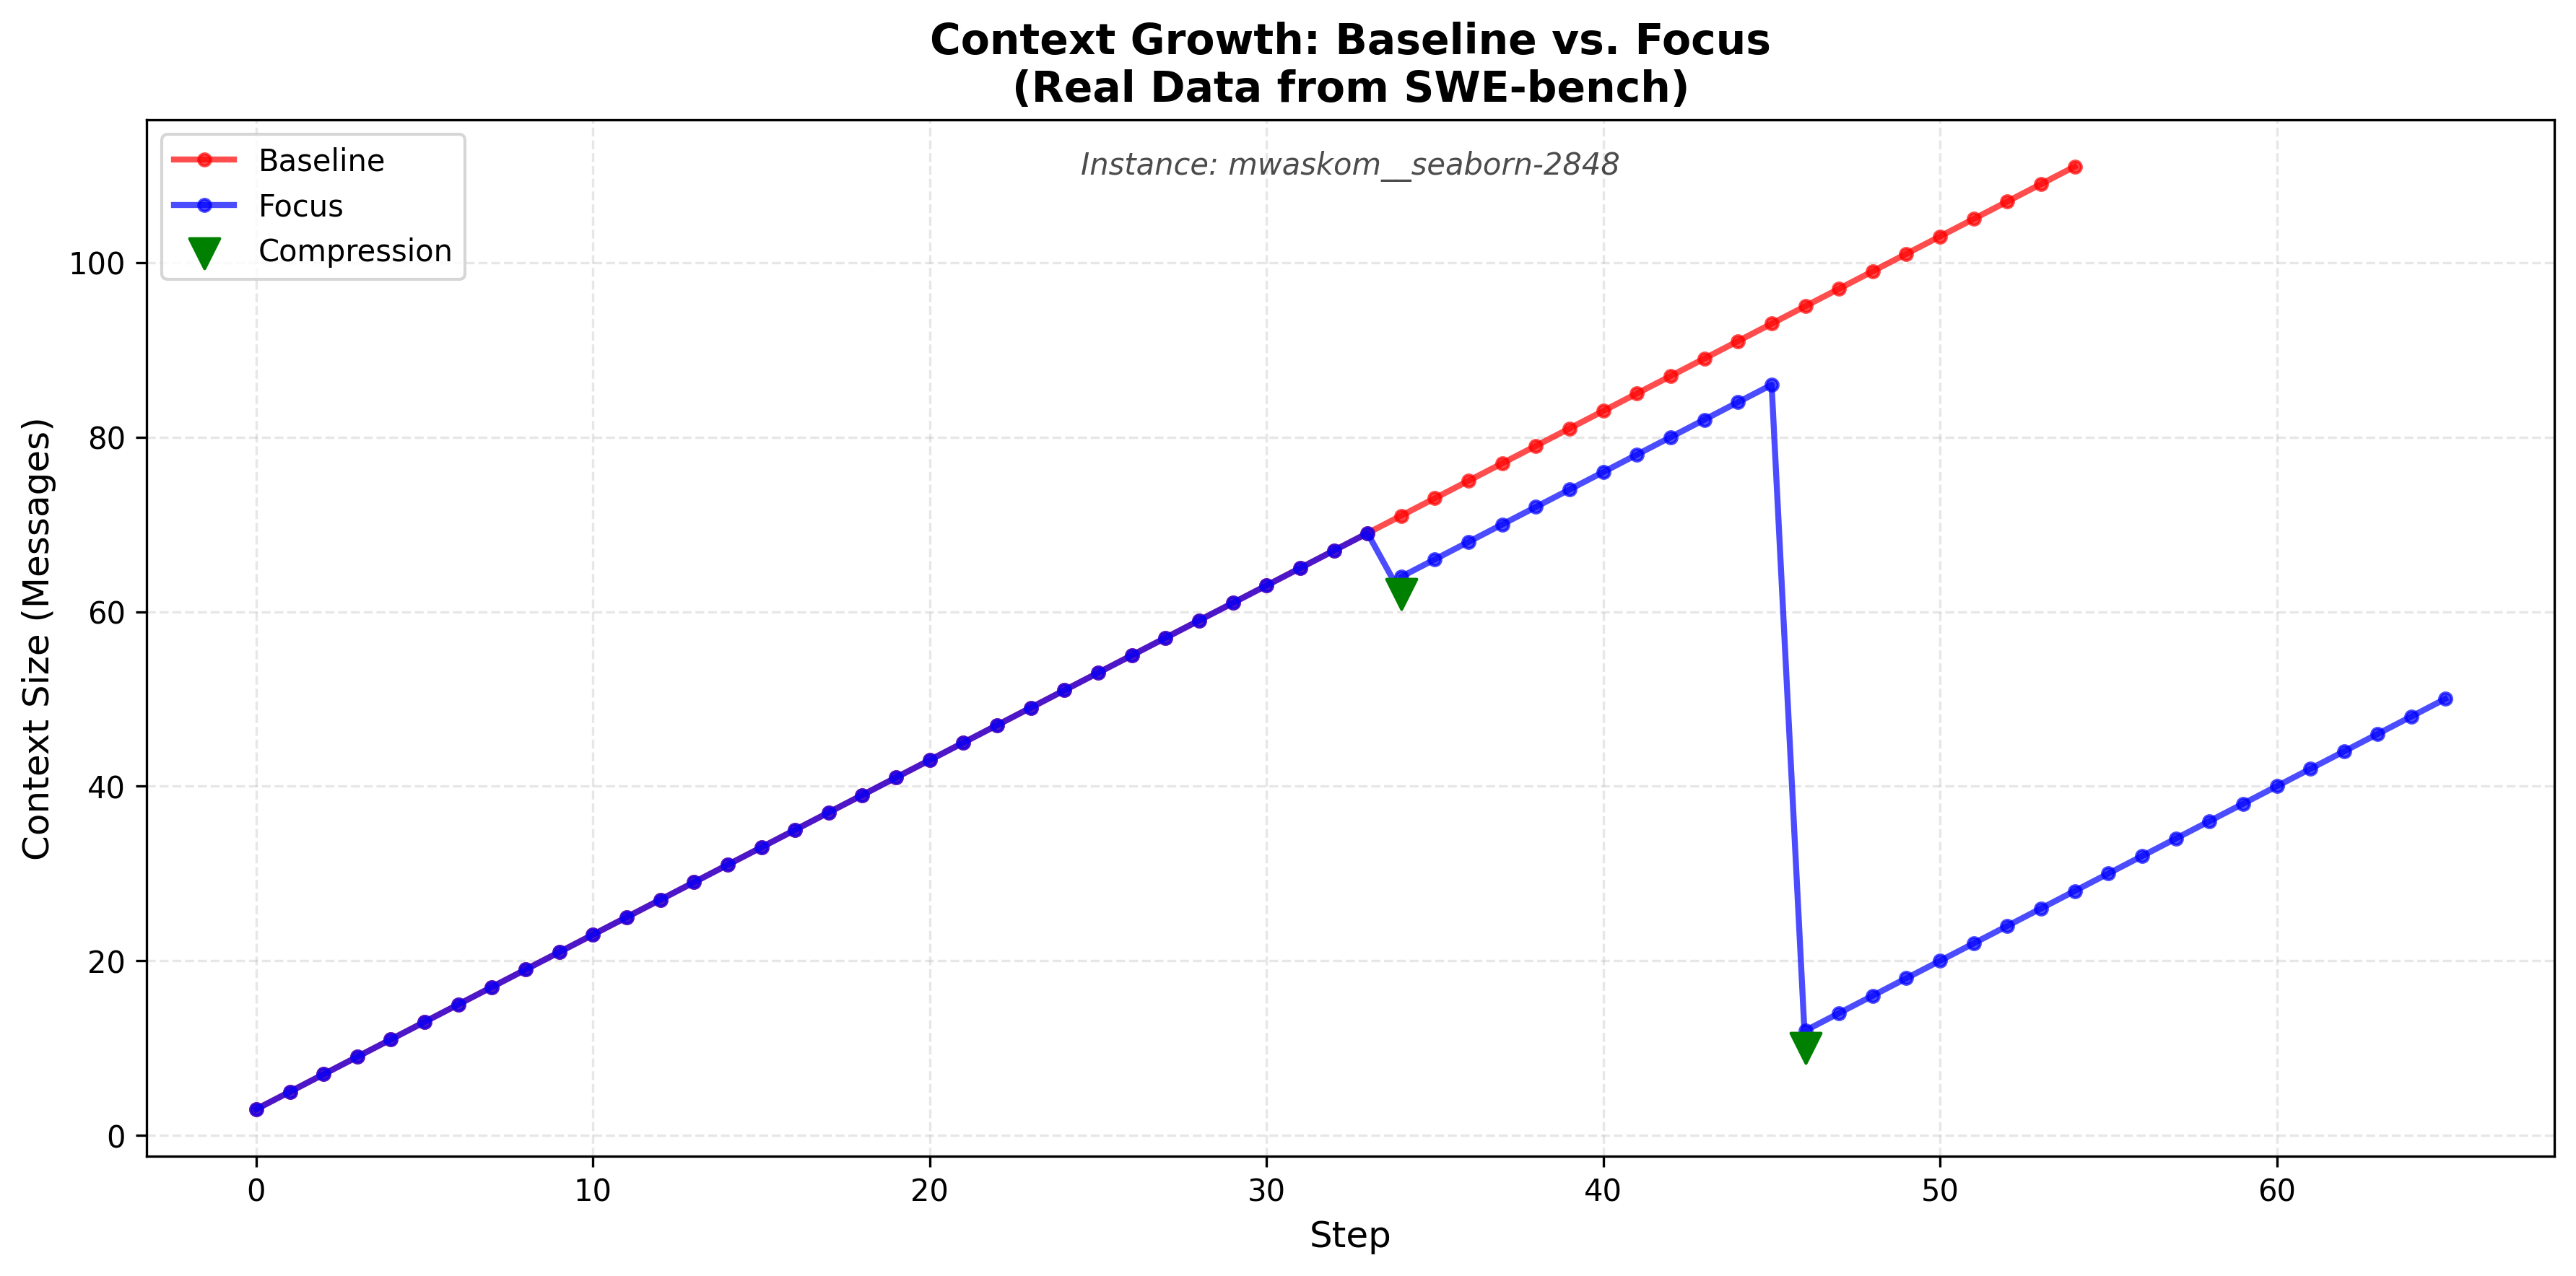
Active Context Compression for LLM Agents
Focus introduces an agent-centered architecture that enables LLM agents to autonomously manage their own memory by deciding when to consolidate learnings into a persistent “Knowledge” block and actively prune raw interaction history. The design is inspired by the biological navigation patterns of Physarum polycephalum (slime mold).