AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
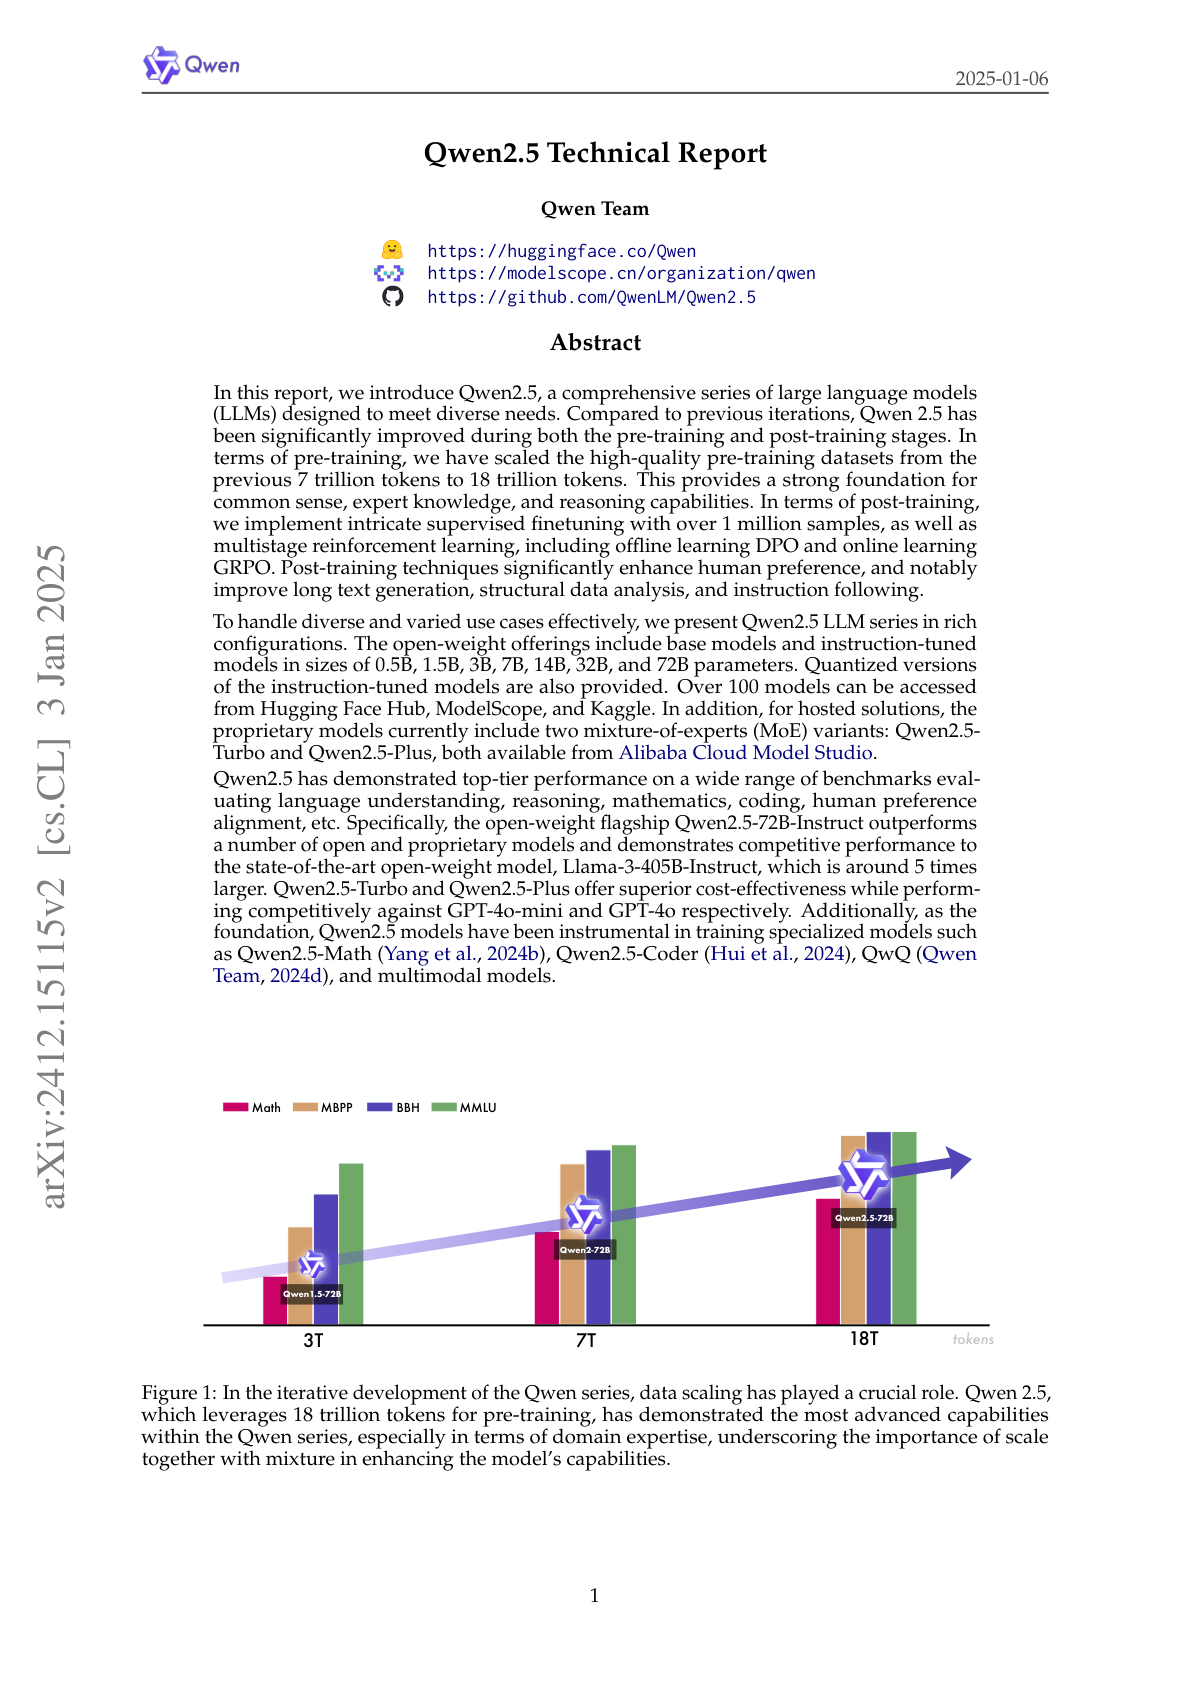
Qwen-2.5 Technical Report
Alibaba releases Qwen2.5, a new series of LLMs trained on 18T tokens, offering both open-weight models like Qwen2.5-72B and proprietary MoE variants that achieve competitive performance against larger models like Llama-3 and GPT-4.
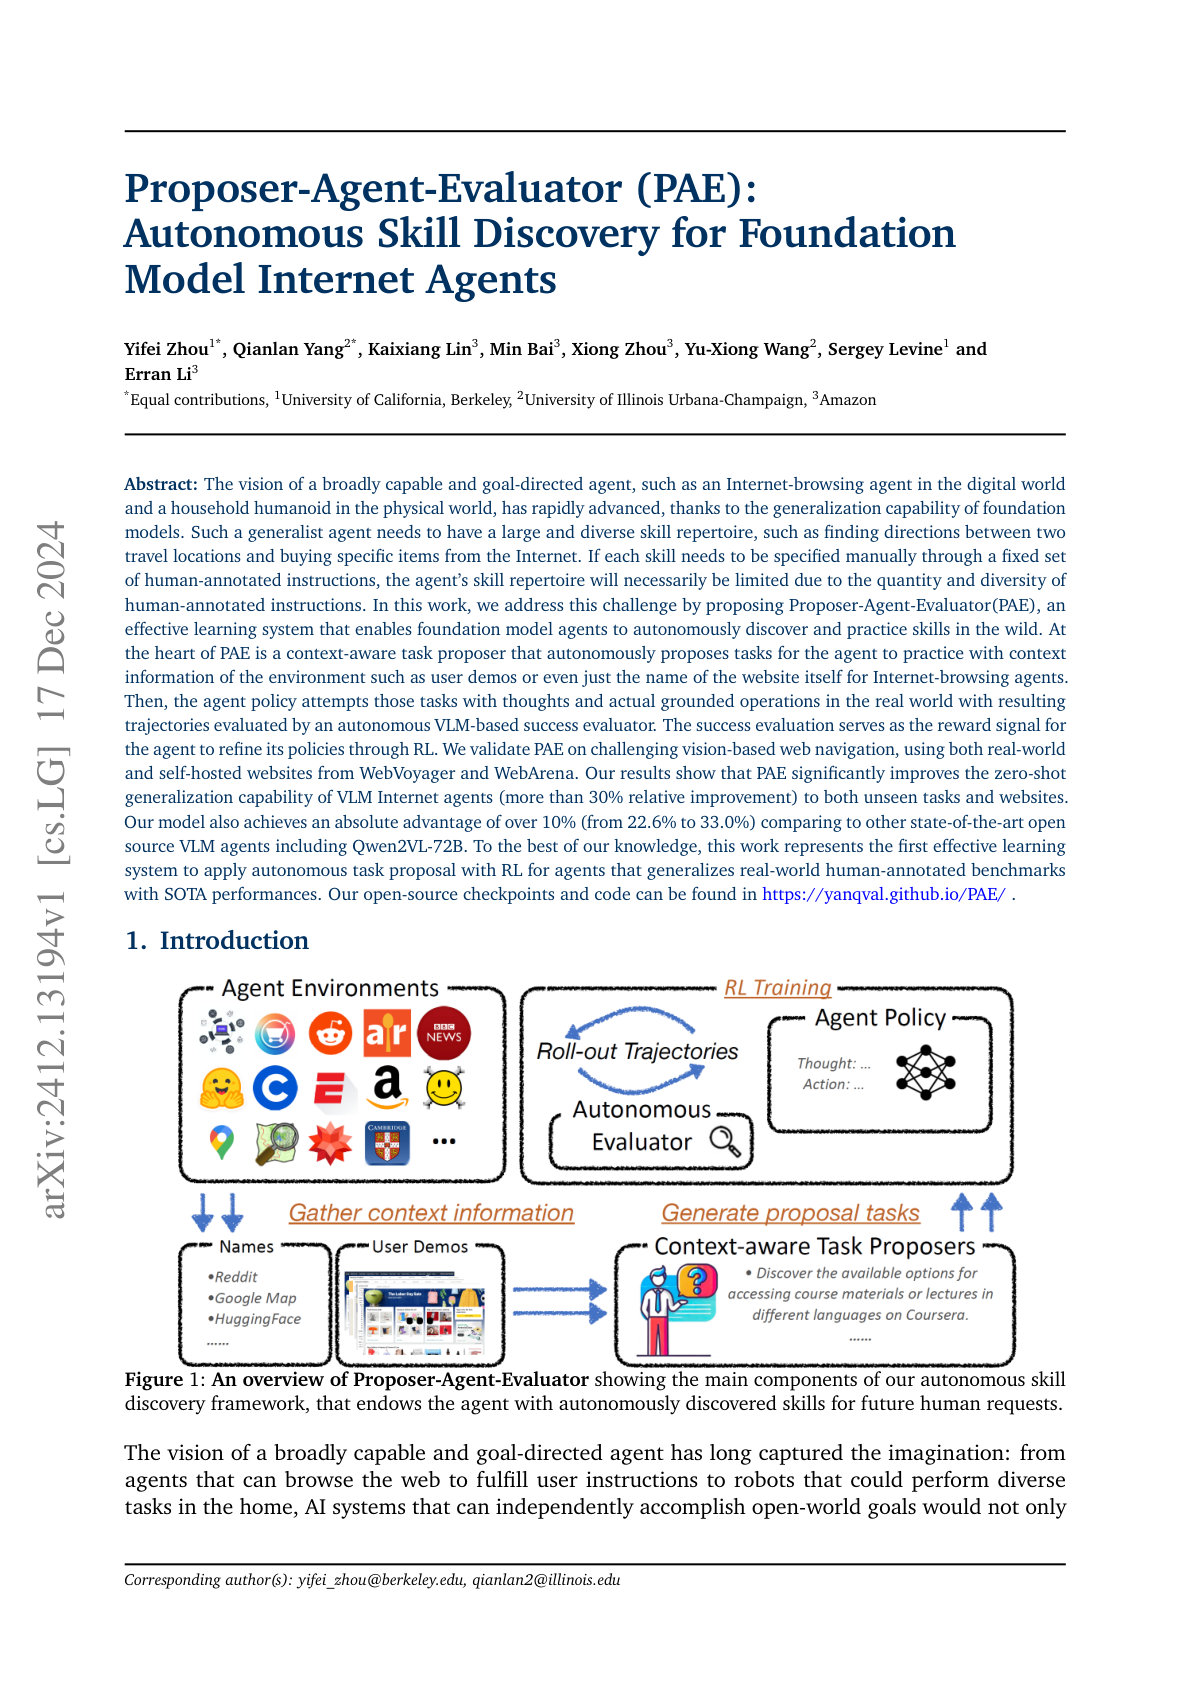
PAE (Proposer-Agent-Evaluator)
a learning system that enables AI agents to autonomously discover and practice skills through web navigation, using reinforcement learning and context-aware task proposals to achieve state-of-the-art performance on real-world benchmarks.
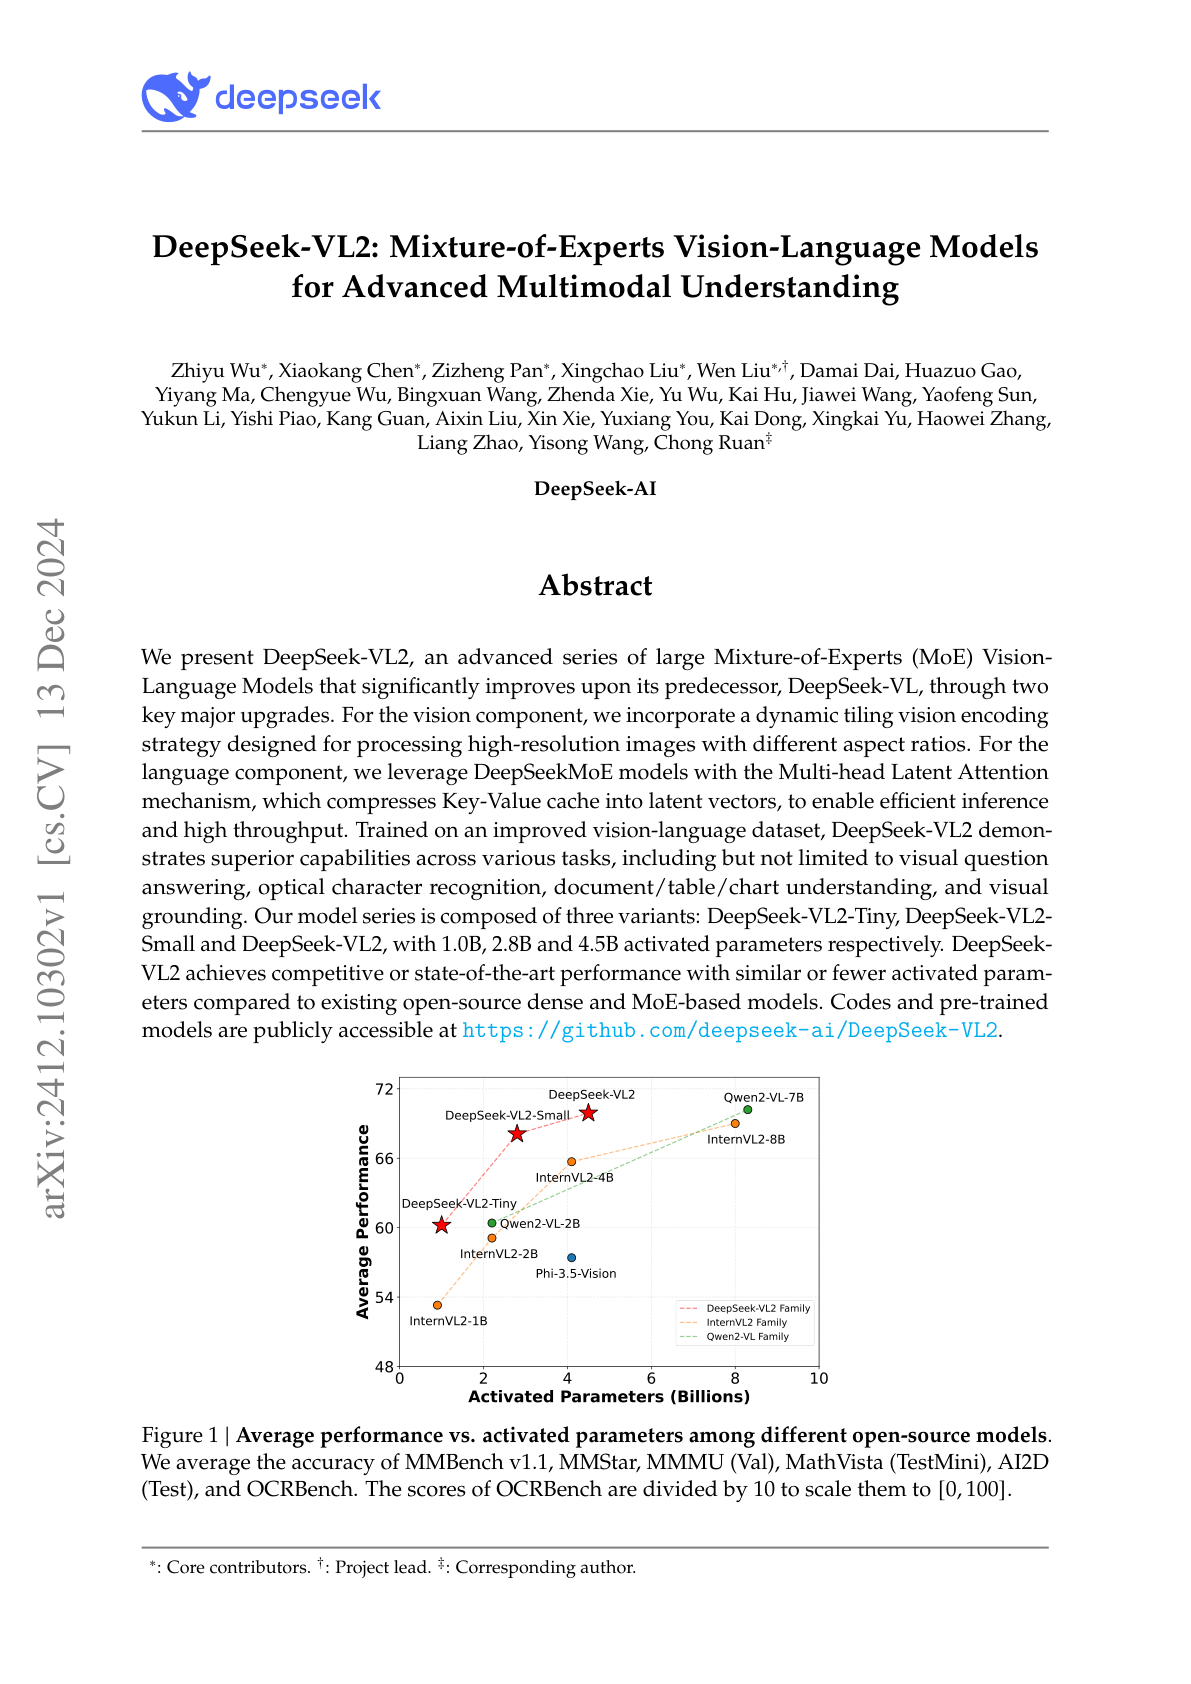
DeepSeek-VL2
a new series of vision-language models featuring dynamic tiling for high-resolution images and efficient MoE architecture, achieving competitive performance across visual tasks; achieves competitive or state-of-the-art performance with similar or fewer activated parameters compared to existing open-source dense and MoE-based models.
AutoFeedback
a two-agent AI system that generates more accurate and pedagogically sound feedback for student responses in science assessments, significantly reducing common errors like over-praise compared to single-agent models.
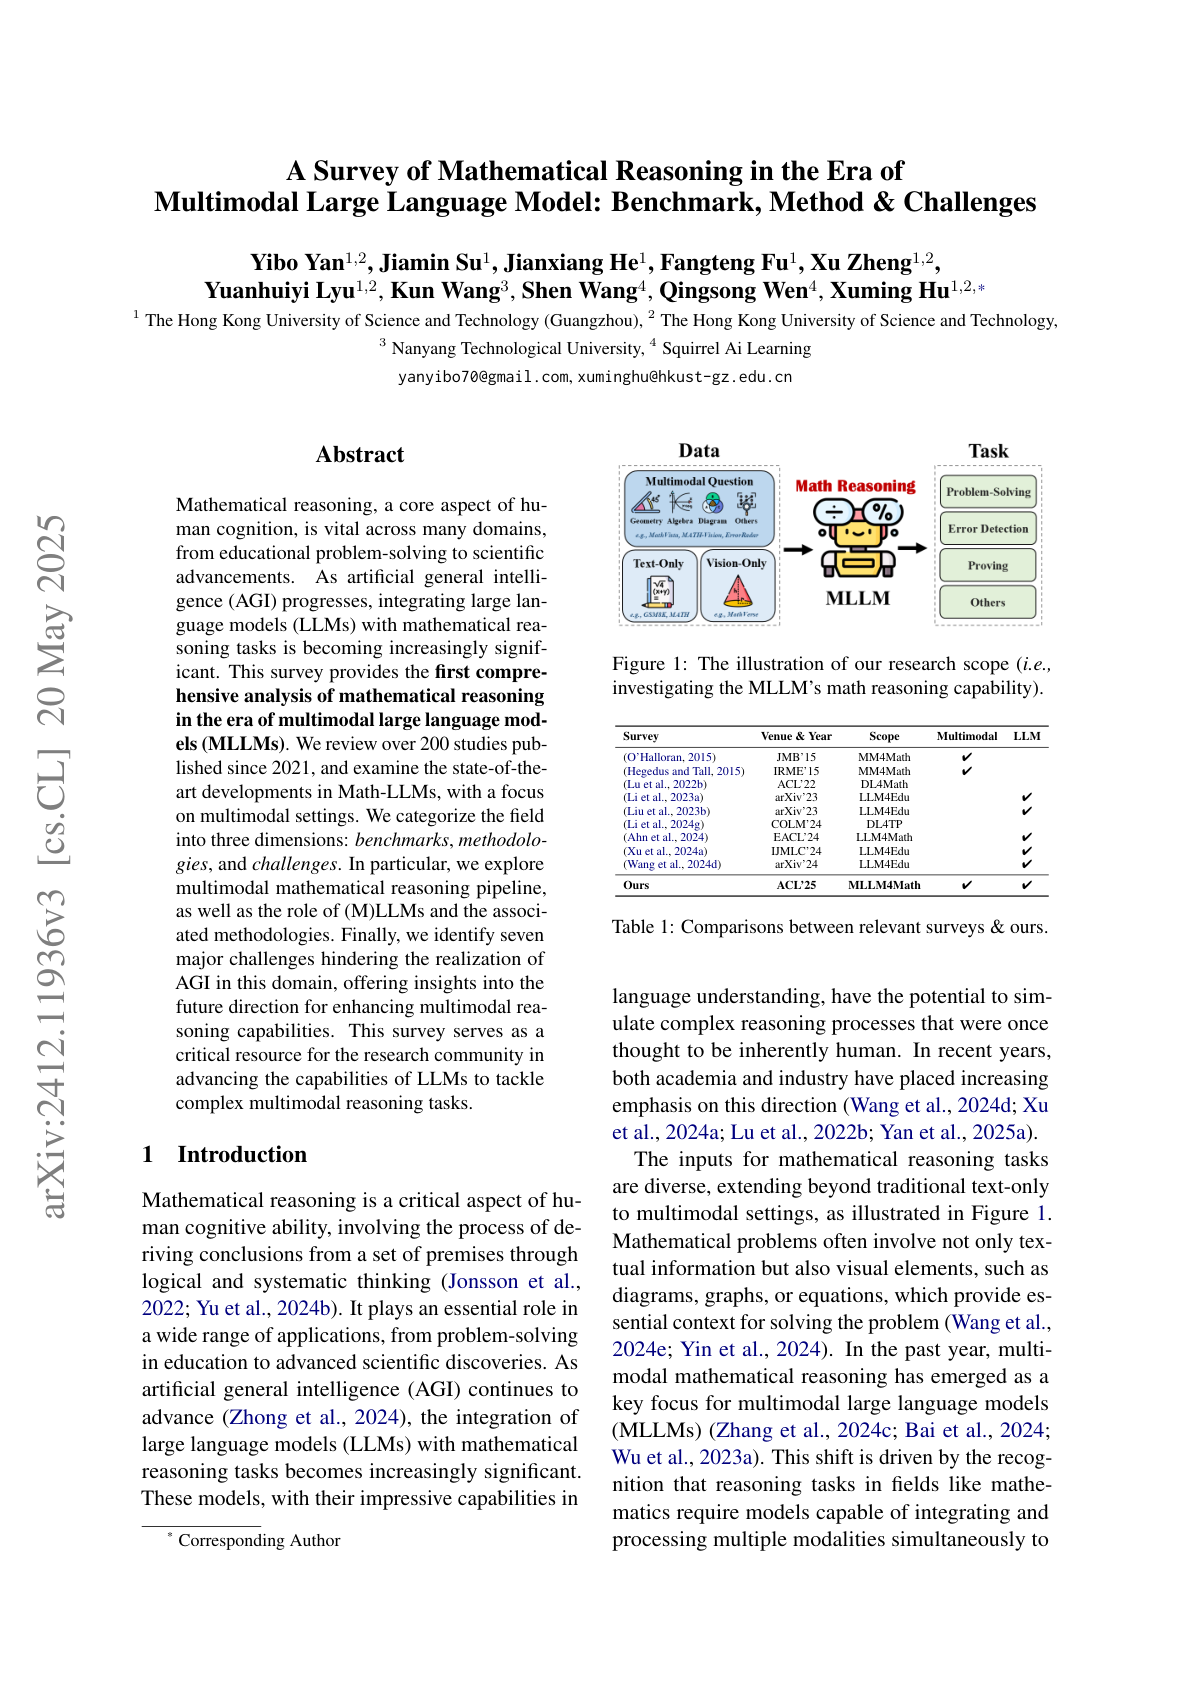
A Survey of Mathematical Reasoning in the Era of Multimodal LLMs
presents a comprehensive survey analyzing mathematical reasoning capabilities in multimodal large language models (MLLMs), covering benchmarks, methodologies, and challenges across 200+ studies since 2021.
Precise Length Control in LLMs
adapts a pre-trained decoder-only LLM to produce responses of a desired length; integrates a secondary length-difference positional encoding into the input embeddings which enables counting down to a user-set response terminal length; claims to achieve mean token errors of less than 3 tokens without compromising quality.
Training LLMs to Reason in a Continuous Latent Space
presents Coconut (Chain of Continuous Thought), a novel paradigm that enables LLMs to reason in continuous latent space rather than natural language; Coconut takes the last hidden state of the LLM as the reasoning state and feeds it back to the LLM as the subsequent input embedding directly in the continuous space; this leads to what the authors refer to as "continuous thought" which augments an LLM's capability on reasoning tasks; it demonstrates improved performance on complex reasoning tasks through emergent breadth-first search capabilities.
Phi-4 Technical Report
presents phi-4, a 14B model that surpasses its teacher model on STEM-QA capabilities. It also reports strong performance on reasoning-focused benchmarks due to improved data, training curriculum, and innovations in the post-training scheme.
Asynchronous Function Calling
proposes AsyncLM, a system for asynchronous LLM function calling; they design an in-context protocol for function calls and interrupts, provide fine-tuning strategy to adapt LLMs to the interrupt semantics, and implement these mechanisms efficiently on LLM inference process; AsyncLM can reduce task completion latency from 1.6x-5.4x compared to synchronous function calling; it enables LLMs to generate and execute function calls concurrently.
MAG-V
a multi-agent framework that first generates a dataset of questions that mimic customer queries; it then reverse engineers alternate questions from responses to verify agent trajectories; reports that the generated synthetic data can improve agent performance on actual customer queries; finds that for trajectory verification simple ML baselines with feature engineering can match the performance of more expensive and capable models.
Clio
proposes a platform using AI assistants to analyze and surface private aggregated usage patterns from millions of Claude.ai conversations; enables insights into real-world AI use while protecting user privacy; the system helps identify usage trends, safety risks, and coordinated misuse attempts without human reviewers needing to read raw conversations.
A Survey on LLMs-as-Judges
presents a comprehensive survey of the LLMs-as-judges paradigm from five key perspectives: Functionality, Methodology, Applications, Meta-evaluation, and Limitations.
AutoReason Improves Multi-step Reasoning
proposes a method to automatically generate rationales for queries using CoT prompting; this transforms zero-shot queries into few-shot reasoning traces which are used as CoT exemplars by the LLM; claims to improve reasoning in weaker LLMs.
The Byte Latent Transformer (BLT)
introduces a byte-level language model architecture that matches tokenization-based LLM performance while improving efficiency and robustness; uses a dynamic method of grouping bytes into patches based on the entropy of the next byte, allocating more compute resources to complex predictions while using larger patches for more predictable sequences; BLT demonstrates the ability to match or exceed the performance of models like Llama 3 while using up to 50% fewer FLOPs during inference.
Does RLHF Scale?
This new paper explores the impacts of key components in the RLHF framework. Summary of main findings: 1) RLHF doesn't scale as effectively as pretraining in LLMs, with larger policy models benefiting less from RLHF when using a fixed reward model, 2) when increasing the number of responses sampled per prompt during policy training, performance improves initially but plateaus quickly, typically around 4-8 samples, 3) using larger reward models leads to better performance in reasoning tasks, but the improvements can be inconsistent across different types of tasks, and 4) increasing training data diversity for reward models is more effective than increasing response diversity per prompt, but policy training shows diminishing returns after the early stages regardless of additional data.
Granite Guardian
IBM open-sources Granite Guardian, a suite of safeguards for risk detection in LLMs; the authors claim that With AUC scores of 0.871 and 0.854 on harmful content and RAG-hallucination-related benchmarks respectively, Granite Guardian is the most generalizable and competitive model available in the space.
OpenAI o1
a model series trained with large-scale reinforcement learning to reason using chain of thought; o1 shows significant improvements across benchmarks related to math, code, and science; o1 is claimed to be 50% faster in generating thinking steps than o1-preview; results demonstrate that o1 is significantly better at reasoning tasks and produces more comprehensive and reliable responses.
Genie 2
a foundation world model that generates playable 3D environments from single prompt images, enabling endless training scenarios for AI agents with features like physics simulation, character animation, and object interactions; Genie 2 is trained on video data using a combination of autoencoder and transformer for generating virtual worlds; the model can create real-time interactive environments, with a faster but lower-quality version available for immediate play.
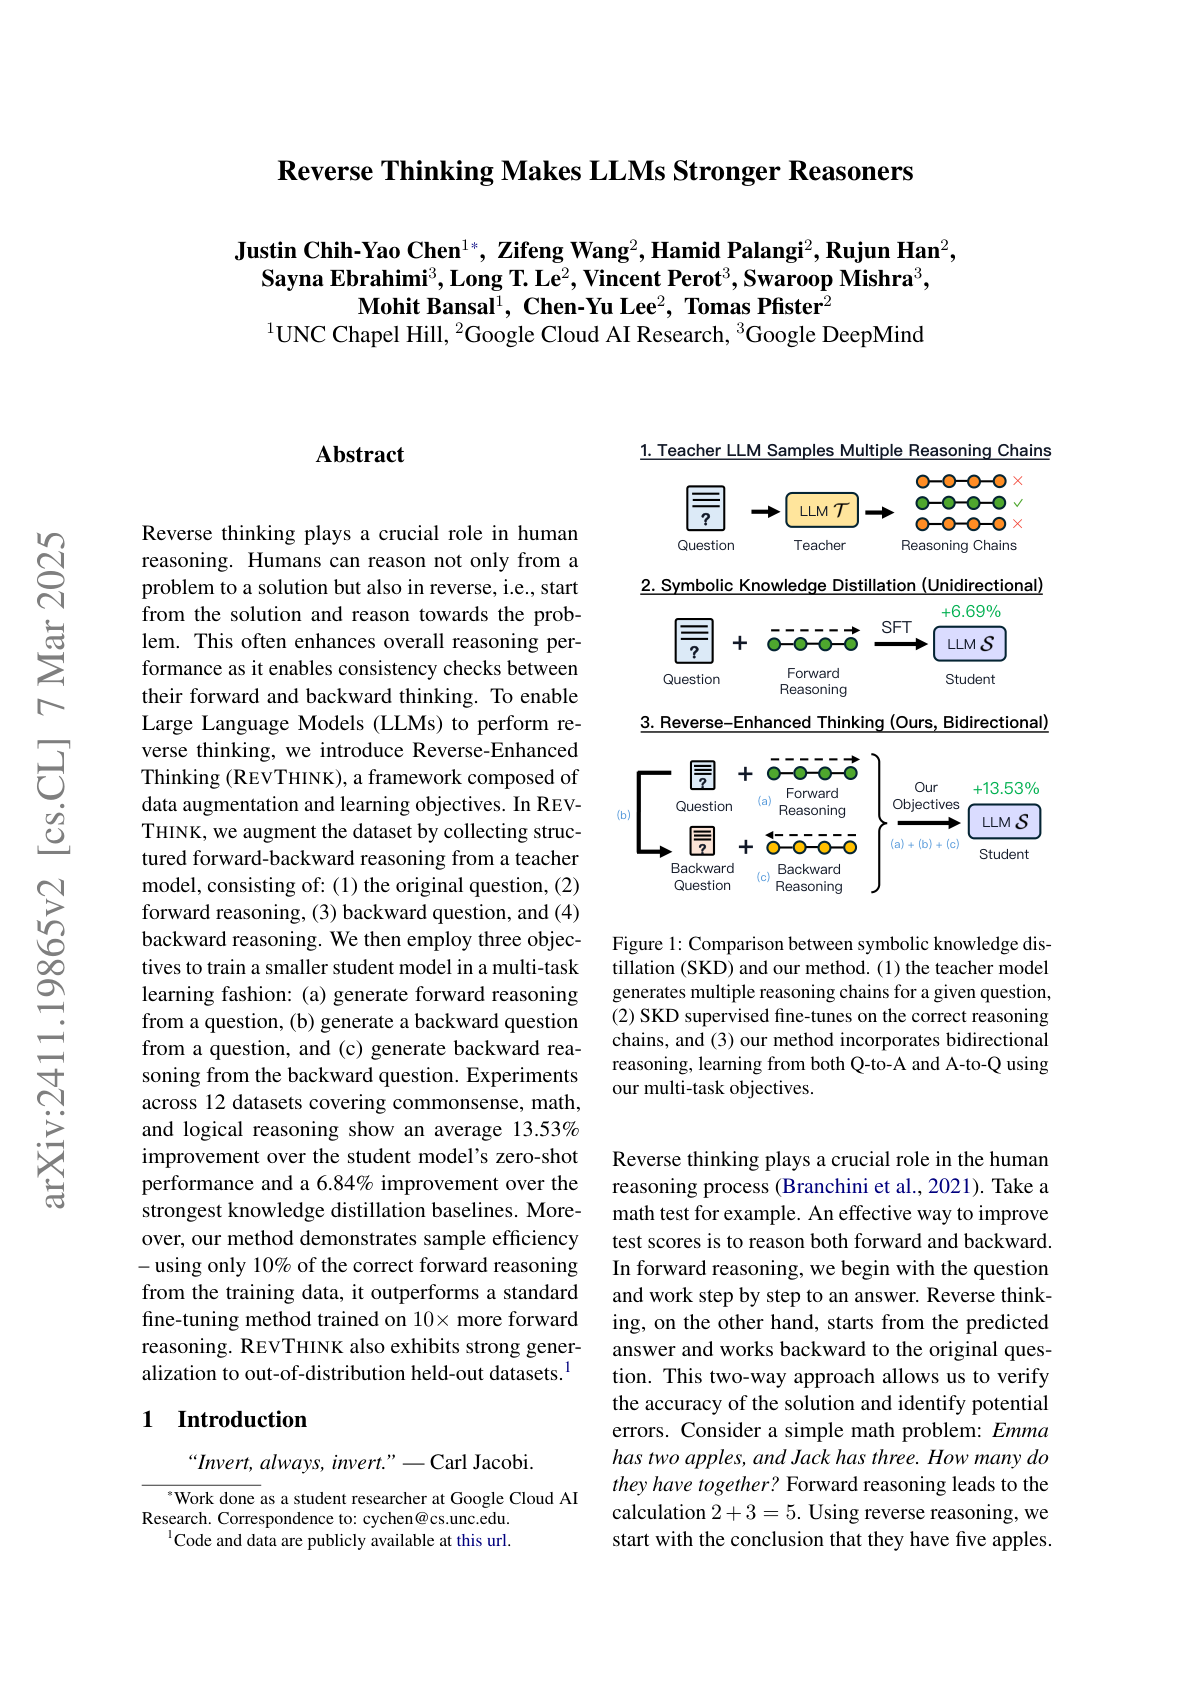
Reverse Thinking
shows that training LLMs to learn "reverse thinking" helps to improve performance in commonsense, math, and logical reasoning tasks. It claims to outperform a standard fine-tuning method trained on 10x more forward reasoning.
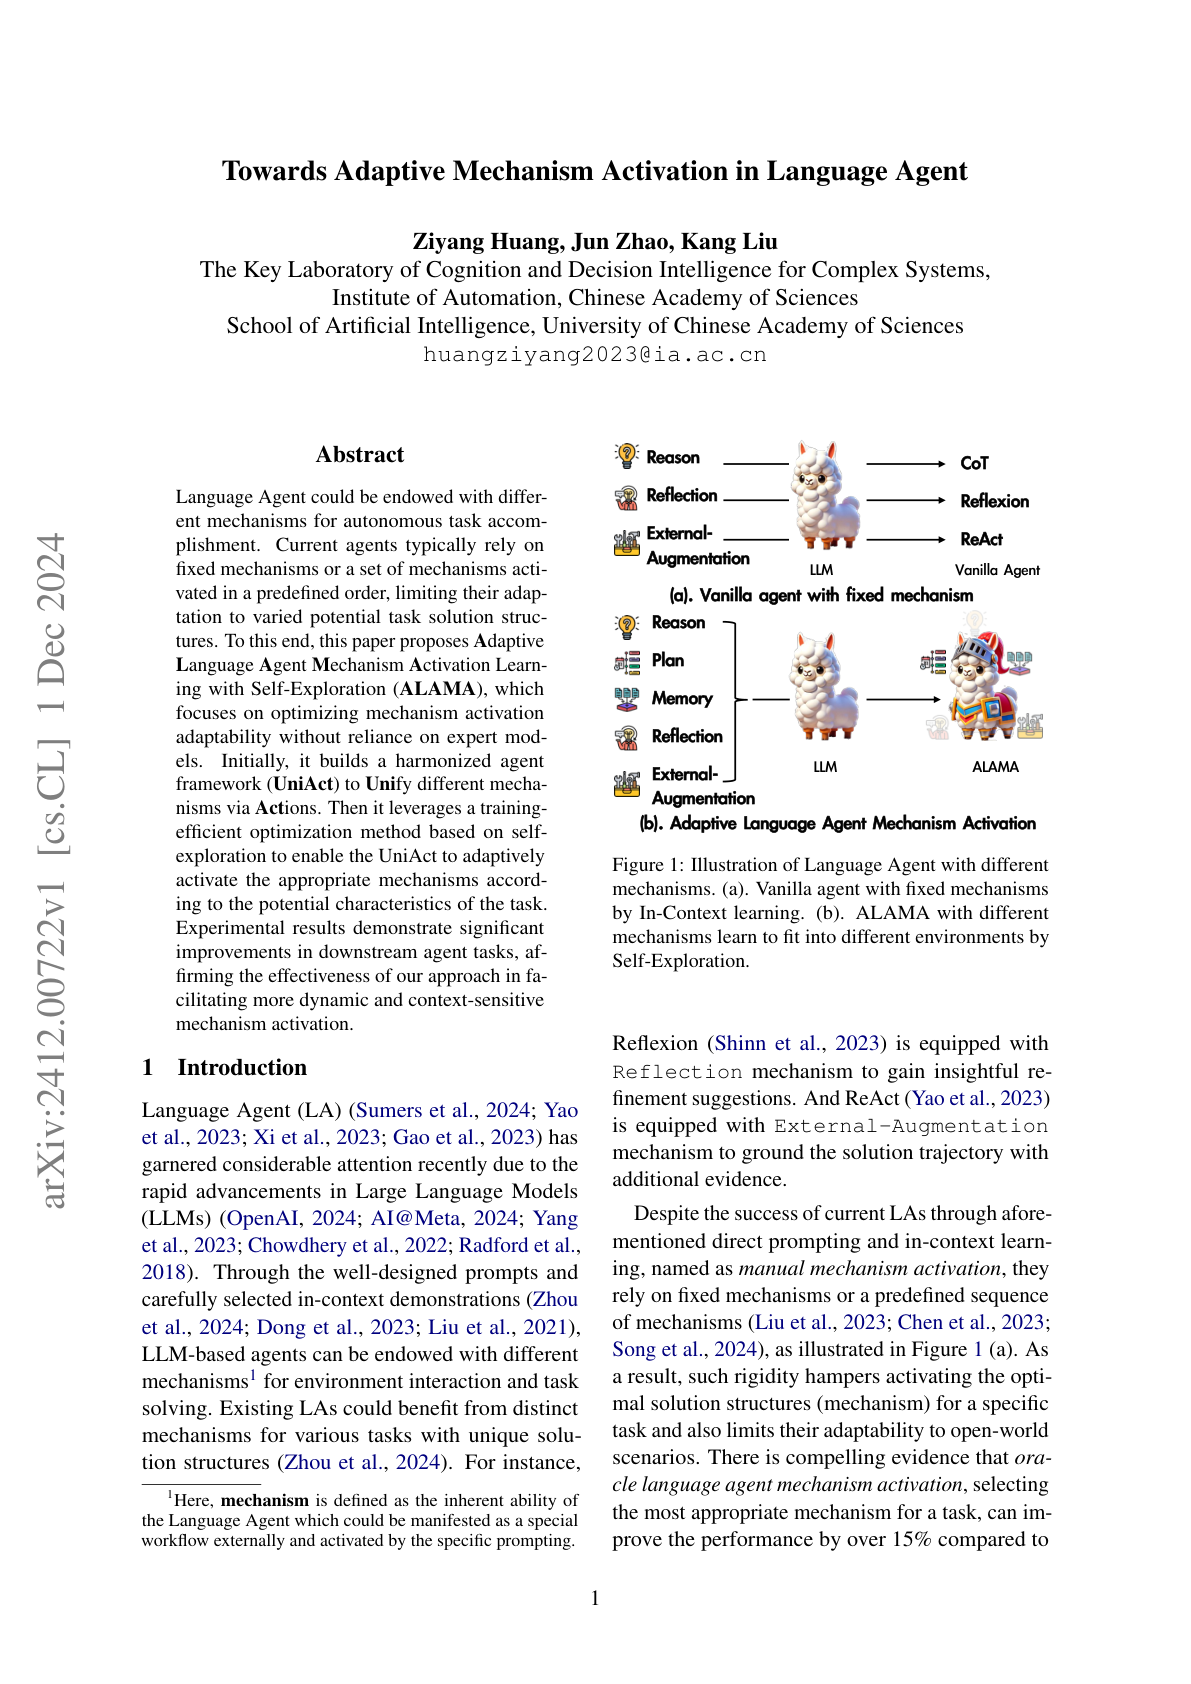
ALAMA
a new framework that helps language agents automatically learn when to use different mechanisms (ReAct, CoT, Reflection, etc.) for automatically completing tasks, improving on current approaches that use fixed or predefined mechanisms; the framework adaptively activates the appropriate mechanisms according to the potential characteristics of the task; experimental results demonstrate significant improvements in downstream agent tasks, including mathematical reasoning and knowledge-intensive reasoning.
Auto-RAG
an autonomous iterative retrieval model with superior performance across many datasets; Auto-RAG is a fine-tuned LLM that leverages the decision-making capabilities of an LLM; it interacts with the retriever through multiturn dialogues, systematically planning retrievals and refining queries to acquire valuable knowledge — it performs this process until sufficient external information is obtained; the authors also show that based on question difficulty, the method can adjust the number of iterations without any human intervention.
GenCast
an ML weather prediction model that outperforms the world's leading operational weather forecasting system (ECMWF's ENS) in both accuracy and speed; it generates probabilistic 15-day global weather forecasts for over 80 variables in just 8 minutes, with better skill than ENS on 97.2% of evaluated targets; GenCast produces an ensemble of forecasts that better capture uncertainty and predict extreme weather events, tropical cyclone tracks, and wind power production.
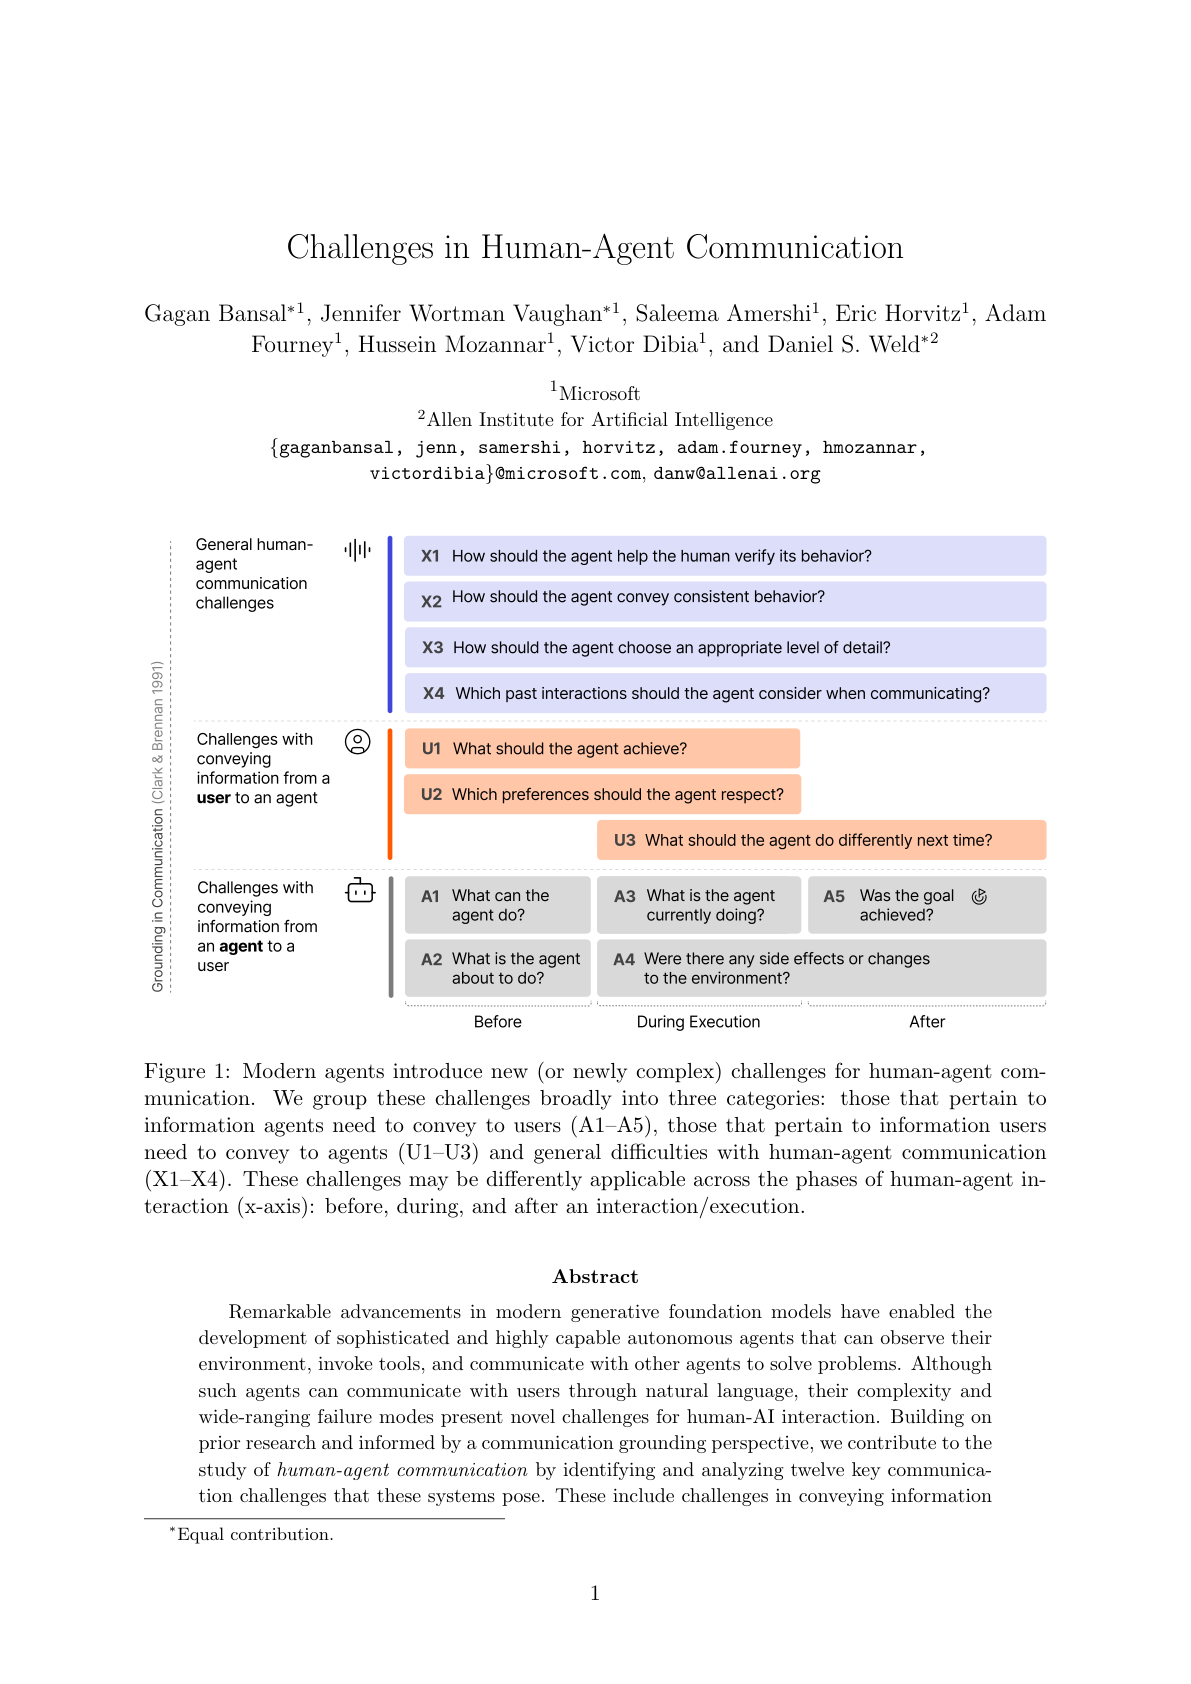
Challenges in Human-Agent Communication
present a comprehensive analysis of key challenges in human-agent communication, focusing on how humans and AI agents can effectively establish common ground and mutual understanding; identifies 12 core challenges across three categories: conveying information from agents to users, enabling users to communicate information to agents, and general communication challenges that affect all interactions.
Retrieval-Augmented Reasoning for LLMs
extends the rStar reasoning framework to enhance reasoning accuracy and factual reliability of LLMs; it leverages a Monte Carlos Tree Search (MCTS) framework with explicit retrieval-augmented reasoning to produce multiple candidate reasoning trajectories; then it leverages a retrieval-augmented factuality scorer to evaluate the factual accuracy of the reasoning trajectories; the trajectory with the highest factuality score is selected as the final answer by the system; on medical reasoning tasks, RARE (which uses Llama 3.1) surpasses larger models such as GPT-4; on commonsense reasoning tasks, RARE outperformed Claude-3.5 Sonnet and GPT-4o-mini, achieving performance competitive with GPT-4o.