AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Procedural Knowledge in Pretraining Drives Reasoning in LLMs
studies what documents in the pertaining influence model outputs; by looking at the pertaining data, it tries to understand better what kind of generalization strategies LLMs use to perform reasoning tasks; when performing reasoning tasks, it finds that influential documents contain procedural knowledge (e.g., demonstrating how to obtain a solution using formulae or code).
LLM Surpass Human Experts in Predicting Neuroscience Results
proposes BrainBench to study how good LLMs are at predicting experimental outcomes in neuroscience; they tuned an LLM, BrainGPT, on neuroscience literature that surpasses experts in predicting neuroscience results; report that when LLMs indicated high confidence in their predictions, their responses were more likely to be correct.
Fugatto
a new generative AI sound model (presented by NVIDIA) that can create and transform any combination of music, voices, and sounds using text and audio inputs, trained on 2.5B parameters and capable of novel audio generation like making trumpets bark or saxophones meow.
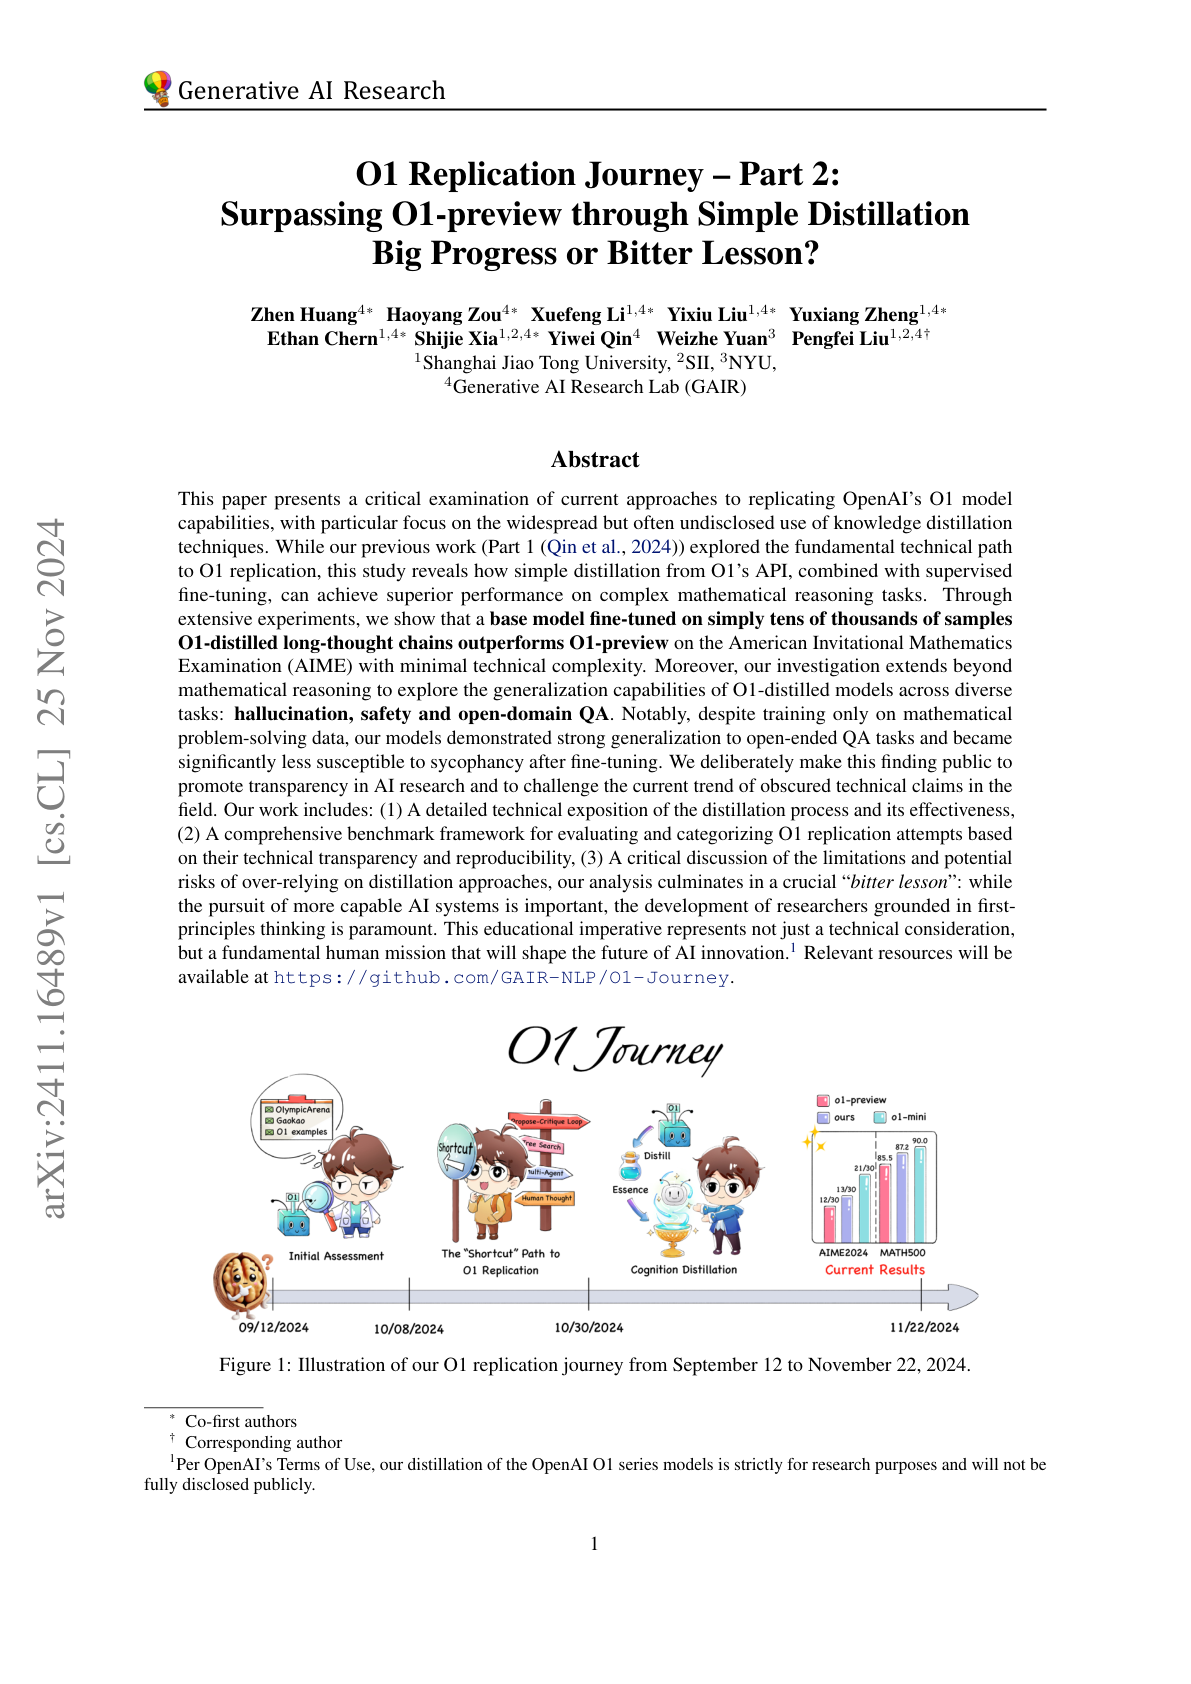
o1 Replication Journey - Part 2
shows that combining simple distillation from o1's API with supervised fine-tuning significantly boosts performance on complex math reasoning tasks; a base model fine-tuned on simply tens of thousands of samples o1-distilled long-thought chains outperform o1-preview on the American Invitational Mathematics Examination (AIME).
LLM-Brained GUI Agents
presents a survey of LLM-brained GUI Agents, including techniques and applications.
High-Level Automated Reasoning
extends in-context learning through high-level automated reasoning; achieves state-of-the-art accuracy (79.6%) on the MATH benchmark with Qwen2.5-7B-Instruct, surpassing GPT-4o (76.6%) and Claude 3.5 (71.1%); rather than focusing on manually creating high-quality demonstrations, it shifts the focus to abstract thinking patterns; it introduces five atomic reasoning actions to construct chain-structured patterns; then it uses Monte Carlo Tree Search to explore reasoning paths and construct thought cards to guide inference.
Star Attention: Efficient LLM Inference over Long Sequences
introduces Star Attention, a two-phase attention mechanism that processes long sequences by combining blockwise-local attention for context encoding with sequence-global attention for query processing and token generation; achieves up to 11x faster inference speeds while maintaining 95-100% accuracy compared to traditional attention mechanisms by efficiently distributing computation across multiple hosts; a key innovation is the "anchor block" mechanism, where each context block is prefixed with the first block, enabling effective approximation of global attention patterns while reducing computational overhead.
Survey on LLM-as-a-Judge
provides a comprehensive survey of LLM-as-a-Judge, including a deeper discussion on how to build reliable LLM-as-a-Judge systems.
TÜLU 3
releases a family of fully-open state-of-the-art post-trained models, alongside its data, code, and training recipes, serving as a comprehensive guide for modern post-training techniques.
Generative Agent Simulations of 1,000 People
introduces a new agent architecture that uses LLMs to create behavioral simulations of real individuals, achieving 85% accuracy in replicating human responses on the General Social Survey and reducing demographic biases compared to traditional approaches.
Measuring Bullshit in Language Games Played by ChatGPT
proposes that LLM-based chatbots play the ‘language game of bullshit’; by asking ChatGPT to generate scientific articles on topics where it has no knowledge or competence, the authors were able to provide a reference set of how this “bullshit” is manifested.
AlphaQubit
a new AI-based decoder that sets a state-of-the-art benchmark for identifying errors in quantum computers; using transformer architecture, AlphaQubit demonstrated 6% fewer errors than tensor network methods and 30% fewer errors than correlated matching when tested on the Sycamore data; shows promising results in simulations of larger systems up to 241 qubits; while this represents significant progress in quantum error correction, the system still needs improvements in speed before it can correct errors in real-time for practical quantum computing applications.
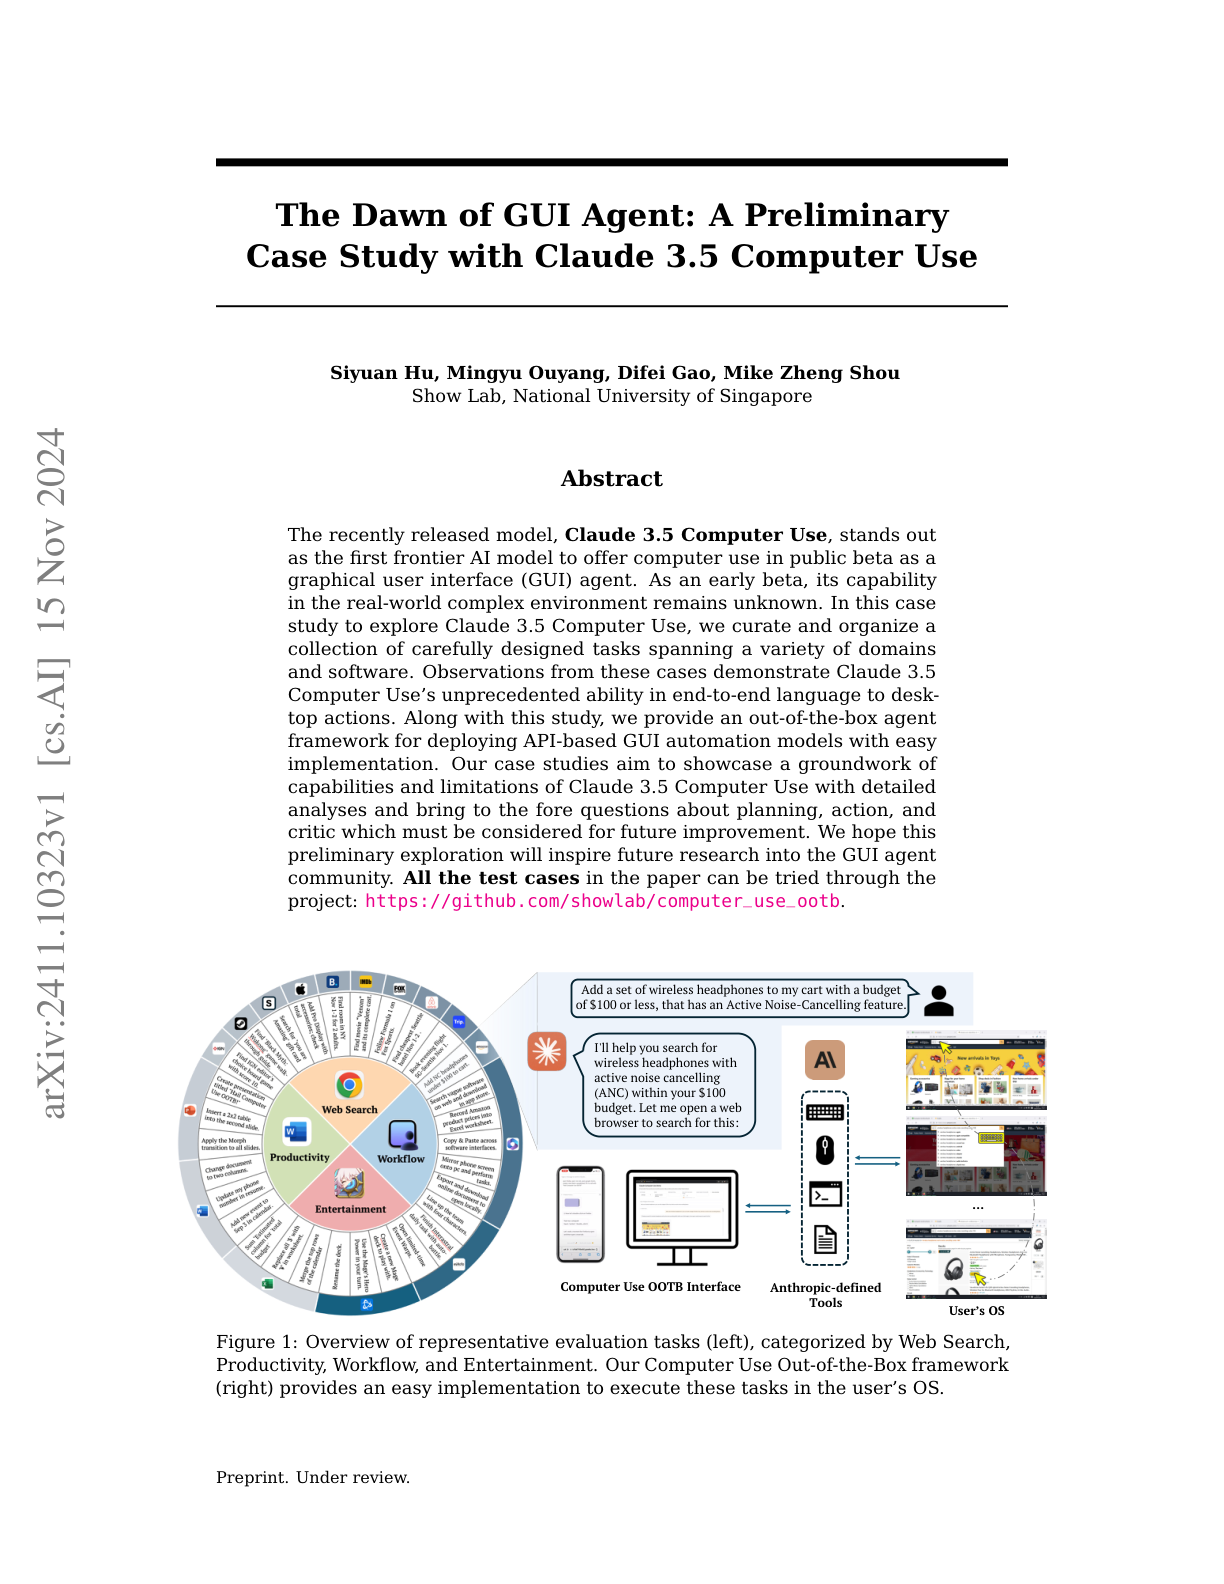
The Dawn of GUI Agent
explores Claude 3.5 computer use capabilities across different domains and software; they also provide an out-of-the-box agent framework for deploying API-based GUI automation models; Claude 3.5 Computer Use demonstrates unprecedented ability in end-to-end language to desktop actions.
A Statistical Approach to LLM Evaluation
proposes five key statistical recommendations for a more rigorous evaluation of LLM performance differences. The recommendations include: 1) using the Central Limit Theorem to measure theoretical averages across all possible questions rather than just observed averages; 2) clustering standard errors when questions are related rather than independent; 3) reducing variance within questions through resampling or using next-token probabilities; 4) analyzing paired differences between models since questions are shared across evaluations, and 5) using power analysis to determine appropriate sample sizes for detecting meaningful differences between models; the authors argue that these statistical approaches will help researchers better determine whether performance differences between models represent genuine capability gaps or are simply due to chance, leading to more precise and reliable model evaluations.
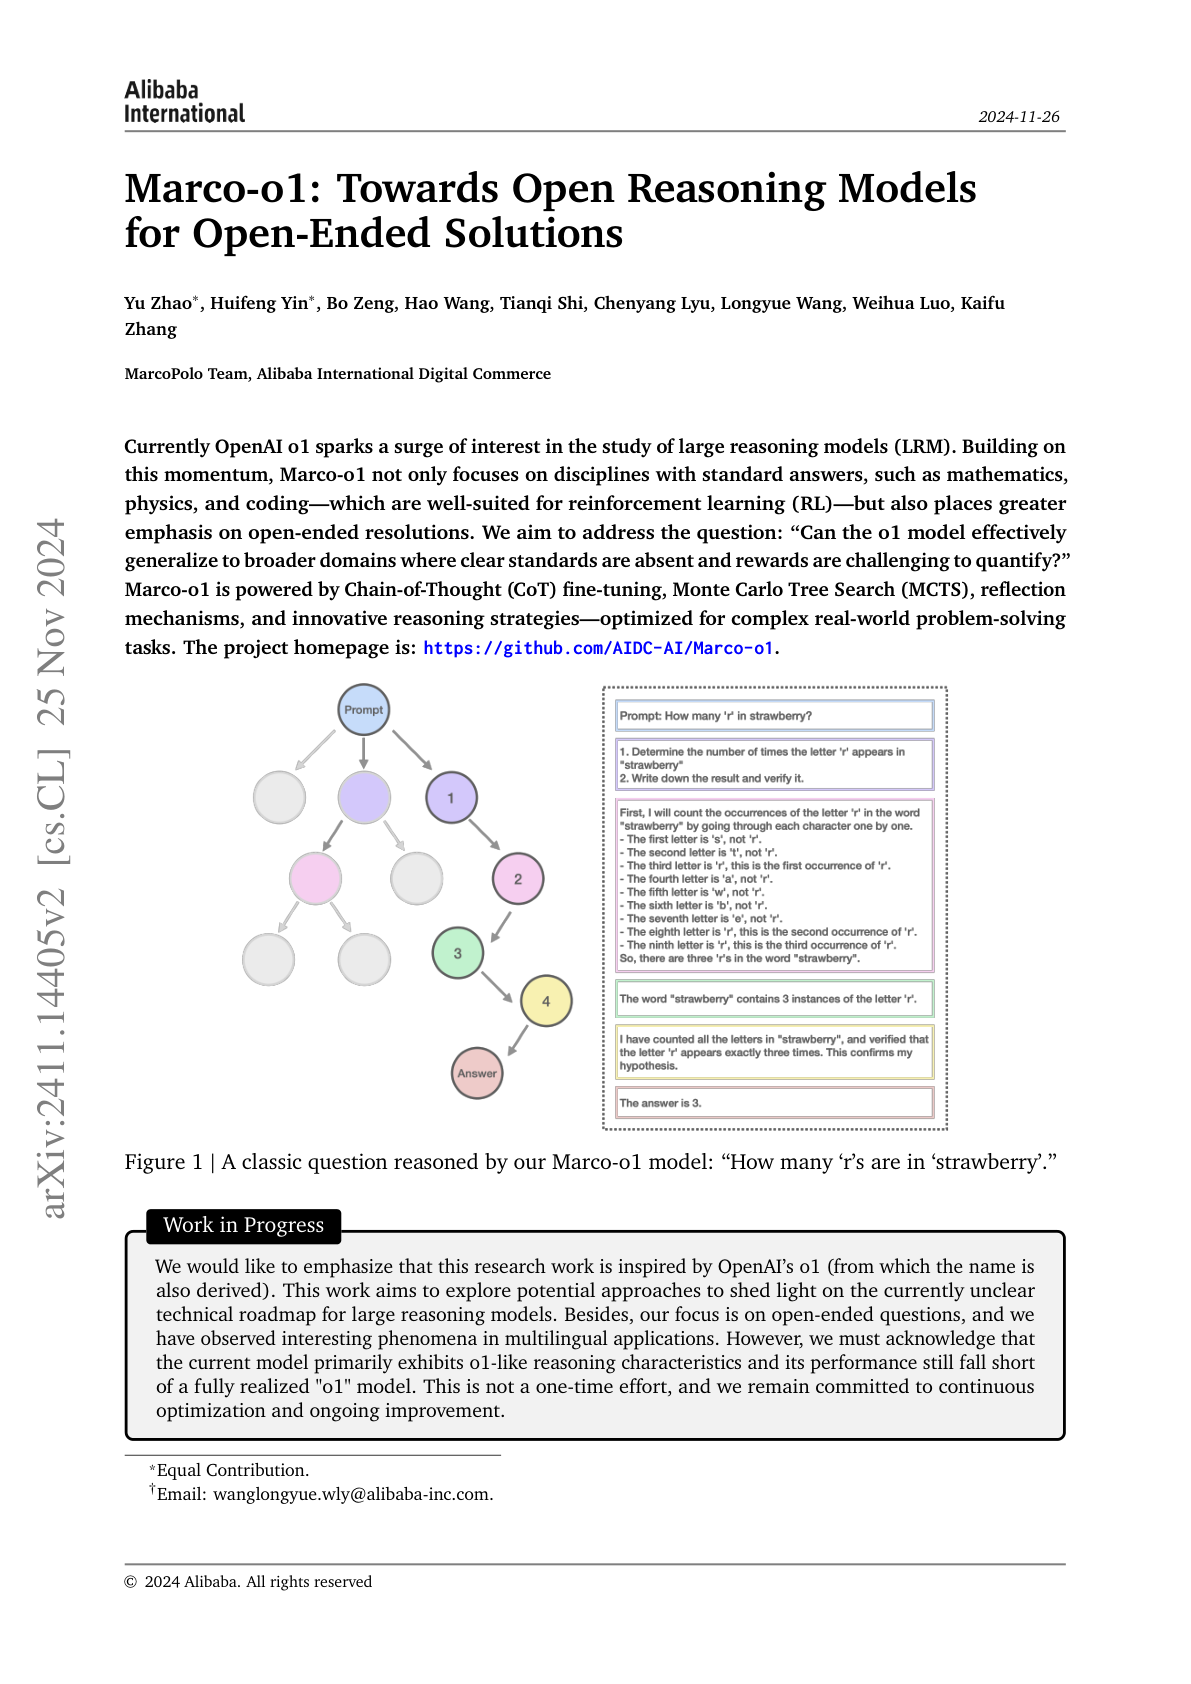
Towards Open Reasoning Models for Open-Ended Solutions
proposes Marco-o1 which is a reasoning model built for open-ended solutions; Marco-o1 is powered by Chain-of-Thought (CoT) fine-tuning, Monte Carlo Tree Search (MCTS), reflection mechanisms, and more recent reasoning strategies; Marco-o1 achieves accuracy improvements of +6.17% on the MGSM (English) dataset and +5.60% on the MGSM (Chinese) dataset.
LLM-based Agents for Automated Bug Fixing
analyzes seven leading LLM-based bug fixing systems on the SWE-bench Lite benchmark, finding MarsCode Agent (developed by ByteDance) achieved the highest success rate at 39.33%; reveals that for error localization line-level fault localization accuracy is more critical than file-level accuracy, and bug reproduction capabilities significantly impact fixing success; shows that 24/168 resolved issues could only be solved using reproduction techniques, though reproduction sometimes misled LLMs when issue descriptions were already clear; concludes that improvements are needed in both LLM reasoning capabilities and Agent workflow design to enhance automated bug fixing effectiveness.
Cut Your Losses in Large-Vocabulary Language Models
introduces Cut Cross-Entropy (CCE), a novel method to significantly reduce memory usage during LLM training by optimizing how the cross-entropy loss is computed; currently, the cross-entropy layer in LLM training consumes a disproportionate amount of memory (up to 90% in some models) due to storing logits for all possible vocabulary tokens. CCE addresses this by only computing logits for the correct token and evaluating the log-sum-exp over all logits on the fly using flash memory; the authors show that the approach reduces the memory footprint of Gemma 2 from 24GB to just 1MB; the method leverages the inherent sparsity of softmax calculations to skip elements that contribute negligibly to gradients; finally, it demonstrates that CCE achieves this dramatic memory reduction without sacrificing training speed or convergence, enabling larger batch sizes during training and potentially more efficient scaling of LLM training.
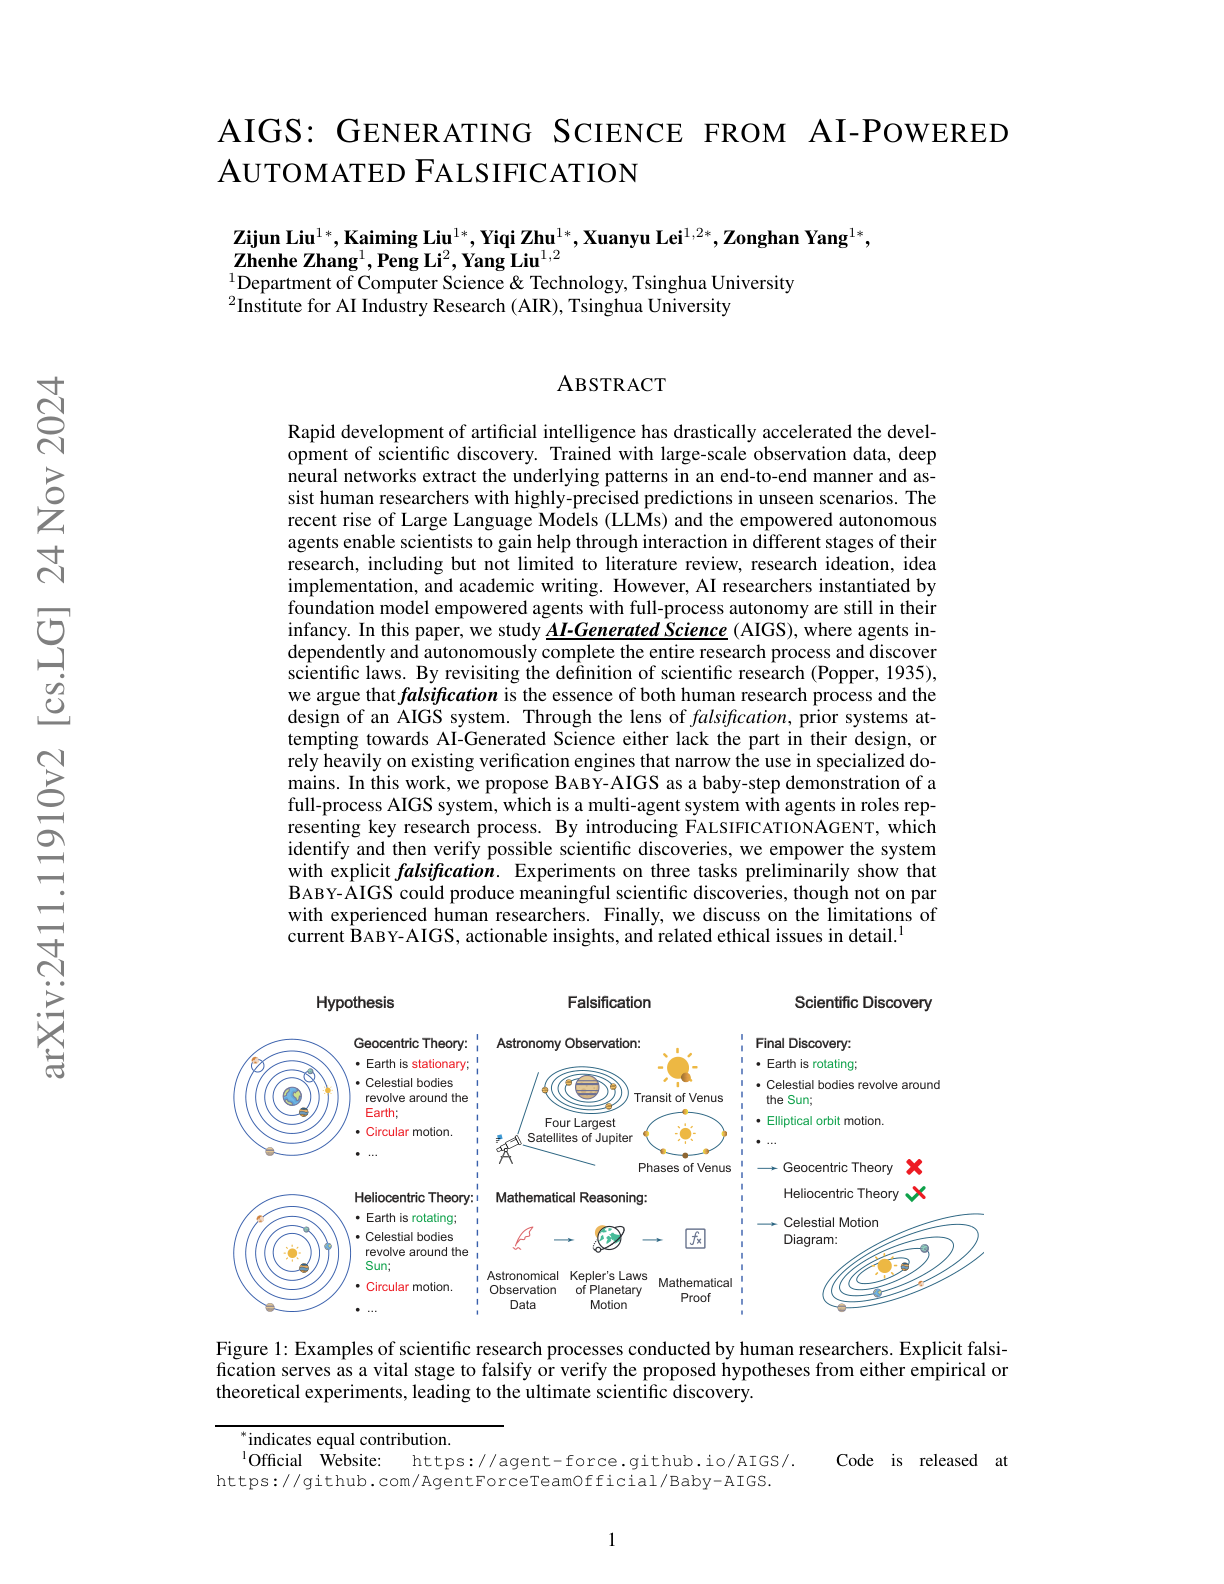
BABY-AIGS
a multi-agent system for automated scientific discovery that emphasizes falsification through automated ablation studies. The system was tested on three ML tasks (data engineering, self-instruct alignment, and language modeling), demonstrating the ability to produce meaningful scientific discoveries. However, the performance is below experienced human researchers.
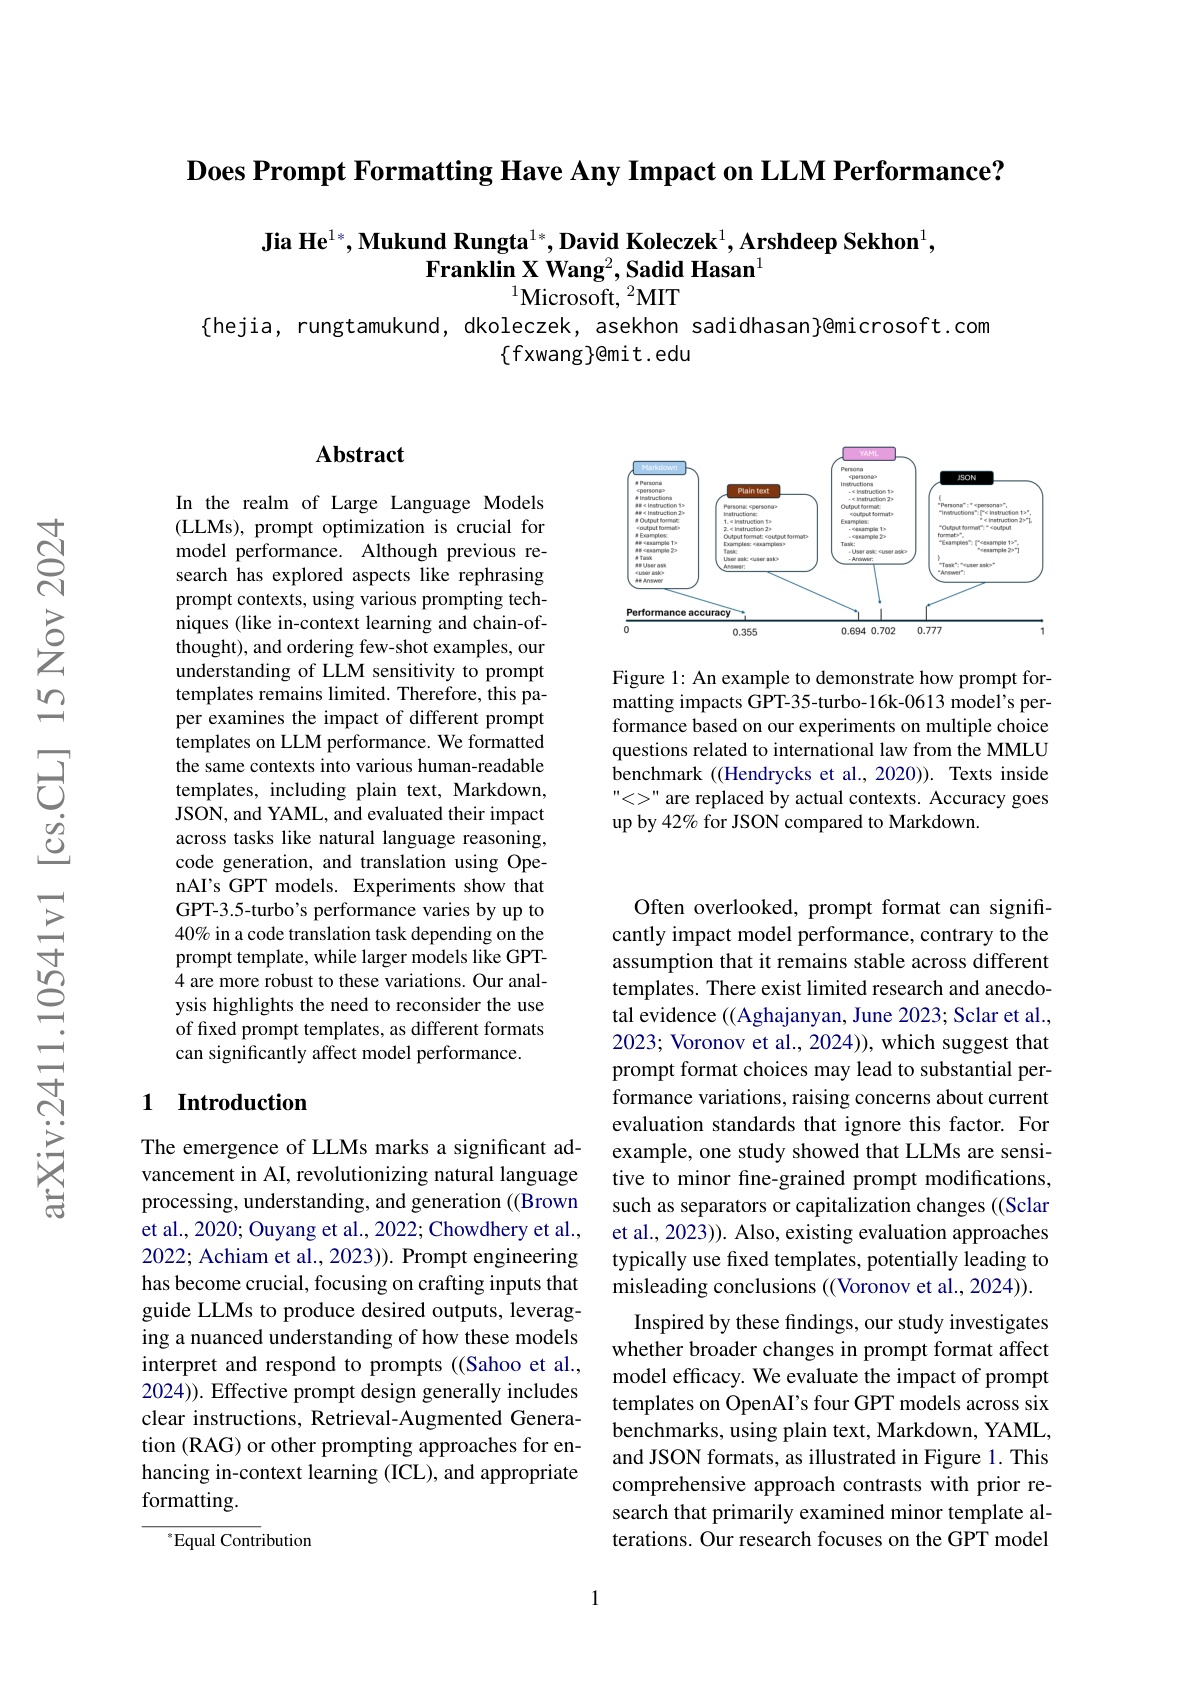
Does Prompt Formatting Impact LLM Performance
examines how different prompt formats (plain text, Markdown, JSON, and YAML) affect GPT model performance across various tasks; finds that GPT-3.5-turbo's performance can vary by up to 40% depending on the prompt format, while larger models like GPT-4 show more robustness to format changes; argues that there is no universally optimal format across models or tasks - for instance, GPT-3.5-turbo generally performed better with JSON formats while GPT-4 preferred Markdown; models from the same family showed similar format preferences, but these preferences didn't transfer well between different model families; suggests that prompt formatting significantly impacts model performance and should be carefully considered when performing prompt engineering and model evaluation, and how to apply it to applications.
FinRobot
an AI agent framework for equity research that uses a multi-agent Chain-of-Thought prompting, combining data analysis with human-like reasoning to produce professional investment reports comparable to major brokerages; it leverage three agents: a Data-CoT Agent to aggregate diverse data sources for robust financial integration; the Concept-CoT Agent, for analyst’s reasoning to generate actionable insights; and the Thesis-CoT Agent to synthesizes these insights into a coherent investment thesis and report.
Bi-Mamba
a scalable 1-bit Mamba architecture designed for more efficient LLMs with multiple sizes across 780M, 1.3B, and 2.7B; Bi-Mamba achieves performance comparable to its full-precision counterparts (e.g., FP16 or BF16); it significantly reduces memory footprint with better accuracy than posttraining-binarization Mamba baselines.
Impacts of AI on Innovation
suggests that top scientists leverage their domain knowledge to prioritize promising AI suggestions, while others waste significant resources testing false positives; finds that implementing AI materials discovery technology leads to substantial increases in productivity, with 44% more materials discovered, 39% more patent filings, and 17% more product innovation; reports that these gains came with concerning tradeoffs, as 82% of scientists reported reduced job satisfaction due to decreased creativity and skill underutilization.
Scaling Laws for Precision
introduces "precision-aware" scaling laws that predict how model performance is affected by both training and inference precision in LLMs; key findings include: 1) post-training quantization becomes more harmful as models are trained on more data, eventually making additional pretraining actively detrimental, 2) training in lower precision requires increasing model size to maintain performance, and 3) when jointly optimizing model size, data, and precision, the compute-optimal training precision is around 7-8 bits and independent of compute; also reports that when the model size is fixed, compute-optimal precision increases approximately logarithmically with data; the authors validate their predictions on models up to 1.7B parameters trained on up to 26B tokens, showing that both very high (16-bit) and very low (sub 4-bit) training precisions may be suboptimal.
Evo
a 7B parameter AI model designed to understand and generate DNA sequences across multiple biological scales; the model, trained on 2.7 million prokaryotic and phage genomes, can process sequences up to 131 kilobases long while maintaining single-nucleotide resolution, enabling it to understand both molecular-level interactions and genome-wide patterns; Evo demonstrates superior performance in predicting and generating functional DNA, RNA, and protein sequences, including the first successful AI-generated CRISPR-Cas complexes and transposable systems that have been experimentally validated.