AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
RAG and Beyond
presents a survey that introduces a RAG task categorization method that helps to classify user queries into four levels according to the type of external data required and the focus of the task; summarizes key challenges in building robust data-augmented LLM applications and the most effective techniques for addressing them.
A Preliminary Study of o1 in Medicine
provides a preliminary exploration of the o1-preview model in medical scenarios; shows that o1 surpasses the previous GPT-4 in accuracy by an average of 6.2% and 6.6% across 19 datasets and two newly created complex QA scenarios; identifies hallucination, inconsistent multilingual ability, and discrepant metrics for evaluation.
Small Language Models Survey
a comprehensive survey on small language models (SLMs) across architectures, training datasets, and training algorithms; analyzes 59 state-of-the-art open-source SLMs and capabilities such as reasoning, in-context learning, maths, and coding; other discussions include on-device runtime costs, latency, memory footprint, and valuable insights.
Minstrel
a multi-generative agent system with reflection capabilities to automate structural prompt generation; it presents LangGPT, an extensible framework for designing prompts; Minstrel is built on top of LangGPT and experiments demonstrate that structural prompts (either generated by Minstrel or written manually) perform better in guiding LLMs to perform tasks.
Moshi
introduces a speech-text foundation model and full-duplex spoken dialogue framework; they present several components of the systems; Helium is a 7B parameter text LLM; Mimi is a semantic-acoustic neural audio code with state-of-the-art performance on audio quality; a hierarchical multi-stream architecture that can generate arbitrary conversation in a speech-to-speech manner.
Training LLMs to Self-Correct via RL
develops a multi-turn online reinforcement learning to improve the capabilities of an LLM to self-correct; it’s based entirely on self-generated data; SFT is shown to be ineffective at learning self-correction and suffers from distribution mismatch between training data and model responses; proposes a two-stage approach that first optimizes correction behavior and then uses a reward bonus to amplify self-correction during training; when applied to Gemini 1.0 Pro and 1.5 Flash models, it achieves state-of-the-art self-correction performance, improving the base models’ self-correction by 15.6% and 9.1% respectively on the MATH and HumanEval benchmarks.
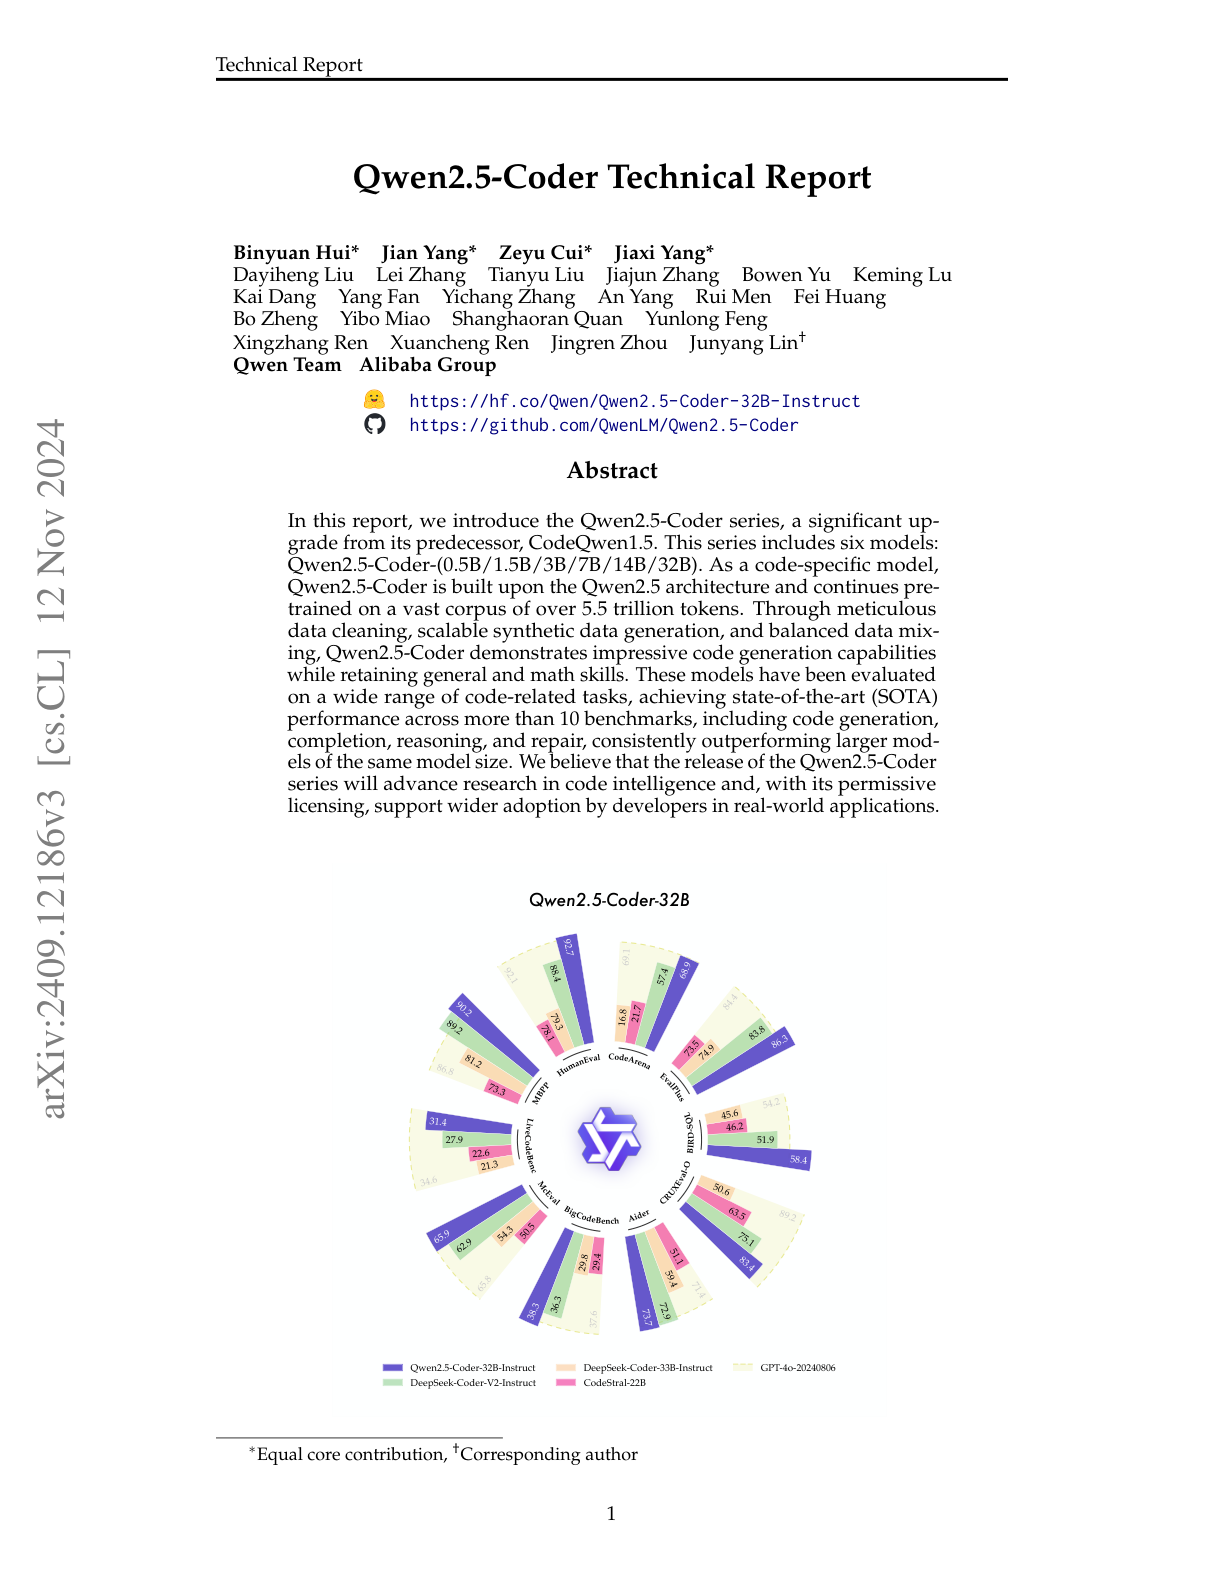
Qwen2.5 Coder
a series of models including 1.5B and 7B parameters; it’s built upon the Qwen2.5 architecture which is continuously pretrained on 5.5 trillion tokens; achieves state-of-the-art performance across more than 10 benchmarks; includes strong capabilities in code generation, completion, reasoning, and repairing.
Diagram of Thought (DoT)
enhances the reasoning capabilities of LLMs through mathematical rigor; DAT models iterative reasoning in LLM as the construction of a directed acyclic graph; it integrates propositions, critiques, refinement, and verification into a unified DAG structure; this allows DoT to capture complex logical deduction beyond linear or tree-based approaches.
Agents in Software Engineering
provides a comprehensive overview of frameworks of LLM-based agents in software engineering.
To CoT or not to CoT?
investigates what kinds of tasks benefit the most from chain-of-thought (CoT) prompting; after a meta-analysis on 100+ papers and several evaluations, it finds that CoT produces strong performance benefits primarily on tasks involving math and logic; they find that most of the CoT gain comes from improving symbolic execution, but a symbolic solver outperforms it.
A Comprehensive Evaluation of Quantized Instruction-Tuned LLMs
evaluates the performance of instruction-tuned LLMs across various quantization methods on models ranging from 7B to 405B; the key findings are 1) quantizing a larger LLM to a similar size as a smaller FP16 LLM generally performs better across most benchmarks, 2) performance varies significantly with different quantization methods, model size, and bit-width, with weight-only methods often yielding better results in larger models, and 3) task difficulty does not significantly impact accuracy degradation due to quantization.
Iteration of Thought
proposes the Iteration of Thought (IoT) framework to enhance the LLM responses and reasoning capabilities with adaptive reasoning paths; it leverages an inner dialogue agent, acting as a guide, to dynamically adjust reasoning paths which allows adaptive cross-path exploration and enhance response accuracy; it's different from CoT and ToT (both rigid processes) in that its prompt generation is a dynamic process that allows it to adapt.
Schrodinger’s Memory
uses the Universal Approximation Theorem to explain the memory mechanism of LLMs. It also proposes a new approach to evaluate LLM performance by comparing the memory capacities of different models; the Transformer architecture functions as a dynamic fitting UAT model, with a strong ability to adaptively fit inputs; this enables LLMs to recall entire content based on minimal input information.
Math Jailbreaking Prompts
uses GPT-4o to generate mathematically encoded prompts that serve as an effective jailbreaking technique; shows an average attack success rate of 73.6% across 13 state-of-the-art; this highlights the inability of existing safety training mechanisms to generalize to mathematically encoded inputs.
Learning to Reason with LLMs
a new family of LLMs trained with reinforcement learning to reason before it responds to complex tasks; it produces a long internal chain of thought and exceeds in science, code, and math-related tasks; ranked in the 49th percentile in the 2024 International Olympiad in Informatics and exceeds human PhD-level accuracy on science-related benchmarks. -
Chai-1
a new multi-modal foundation model for molecular structure prediction that can predict proteins, small molecules, DNA, RNA, and more; it achieves state-of-the-art results on a variety of tasks in drug discovery; achieves a 77% success rate on the PoseBusters benchmark (vs. 76% by AlphaFold 3), as well as an Cα LDDT of 0.849 on the CASP15 protein monomer structure prediction set (vs. 0.801 by ESM3-98B).
Can LLMs Generation Novel Research Ideas
finds that LLM-generated research ideas are judged as more novel (p <0.05) than human expert ideas; however, they were rated slightly weaker in terms of flexibility; they also report that LLM agents lack diversity in the idea generation process and are not reliable evaluators.
DataGemma
includes a series of fine-tuned Gemma 2 models to help LLMs access and incorporate numerical and statistical data; proposes a new approach called Retrieval Interleaved Generation (RIG) which can reliably incorporate public statistical data from Data Commons into LLM responses; RIG is a tool-inspired approach, can interleave statistical tokens with natural language questions suitable for retrieval from Data Commons; to attain such capability, they fine-tune the LLM on an instruction-response dataset generated with the help of Gemini 1.5; the RIG approach improves factuality from 5-7% to about 58%.
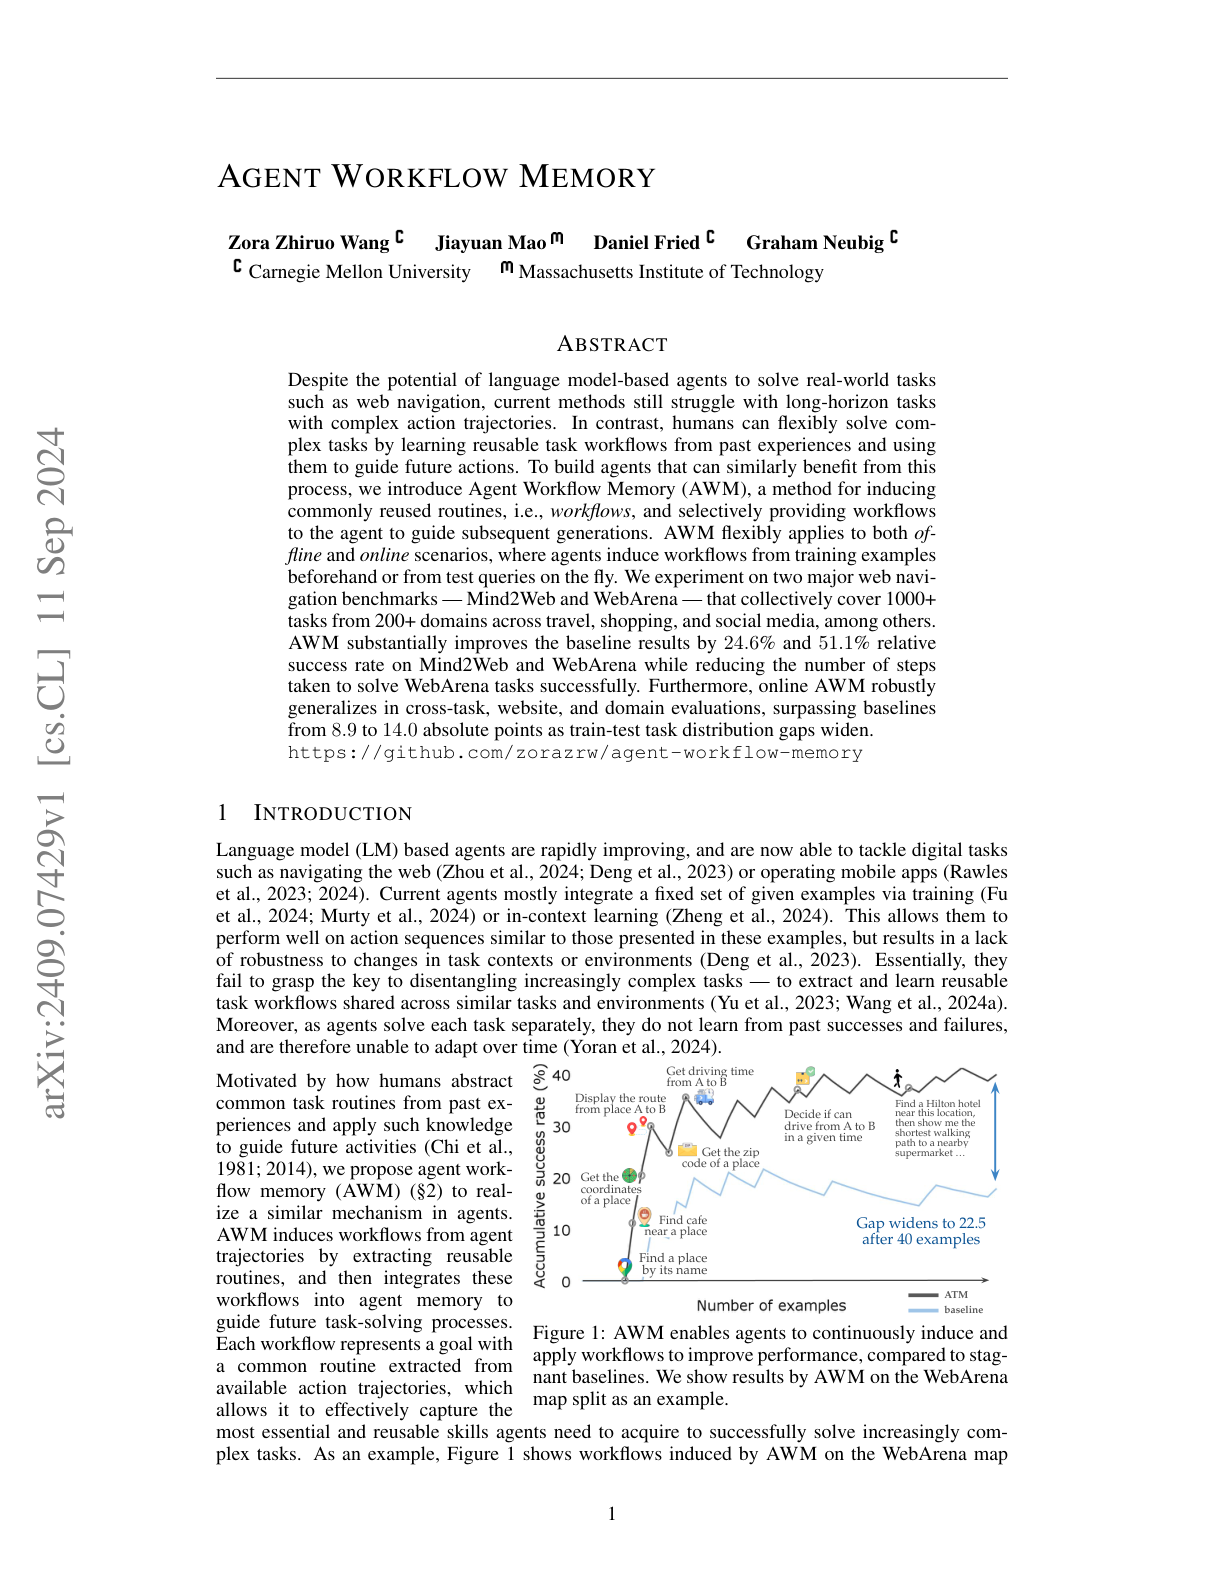
Agent Workflow Memory
introduces Agent Workflow Memory to induce commonly reused workflows and provide these to the agent on demand; works offline and online and is meant to guide the agent's subsequent generations; it’s inspired by how humans learn reusable workflows from past experiences and use them to guide future actions; claims to substantially improve the baseline results by 24.6% and 51.1% relative success rate on Mind2Web and WebArena while doing it in a more efficient way.
The Role of Small Language Models in the LLM Era
closely examines the relationship between LLMs and SLMs; common applications of SLMs include data curation, training stronger models, efficient inference, evaluators, retrievers, and much more; includes insights for practitioners to better understand the value of these SLMs.
LLaMa-Omni
a model architecture for low-latency speech interaction with LLMs; it is based on Llama-3.1-8B-Instruct and can simultaneously generate both text and speech responses given speech instructions; responses can be generated with a response latency as low as 226ms; architecture-wise, it involves a speech encoder (Whispter-large-v3), a speech adaptor, an LLM, and a speech decoder; they also created a dataset of 200K speech interactions and responses.
Can LLMs Unlock Novel Scientific Research Ideas
investigates whether LLM can generate novel scientific research ideas; reports that Claude and GPT models tend to align more with the author's perspectives on future research ideas; this is measured across different domains like science, economics, and medicine.
Theory, Analysis, and Best Practices for Sigmoid Self-Attention
proposes Flash-Sigmoid, a hardware-aware and memory-efficient implementation of sigmoid attention; it yields up to a 17% inference kernel speed-up over FlashAttention-2 on H100 GPUs; show that SigmoidAttn matches SoftwaxAttn in various tasks and domains.
Achieving Peak Performance for LLMs
a systematic review of methods for improving and speeding up LLMs from three points of view: training, inference, and system serving; summarizes the latest optimization and acceleration strategies around training, hardware, scalability, and reliability.