AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
RECOMP (Retrieval-Augmented LMs with Compressors)
Proposes two compression approaches to shrink retrieved documents before in-context use.
Language Modeling Is Compression
DeepMind empirically revisits the theoretical equivalence between prediction and compression, applied to modern LLMs.
Model Compression for LLMs Survey
A survey of recent model-compression techniques applied specifically to LLMs.
Outlines (Efficient Guided Generation)
A library for guided LLM text generation that enforces structural constraints with minimal overhead.
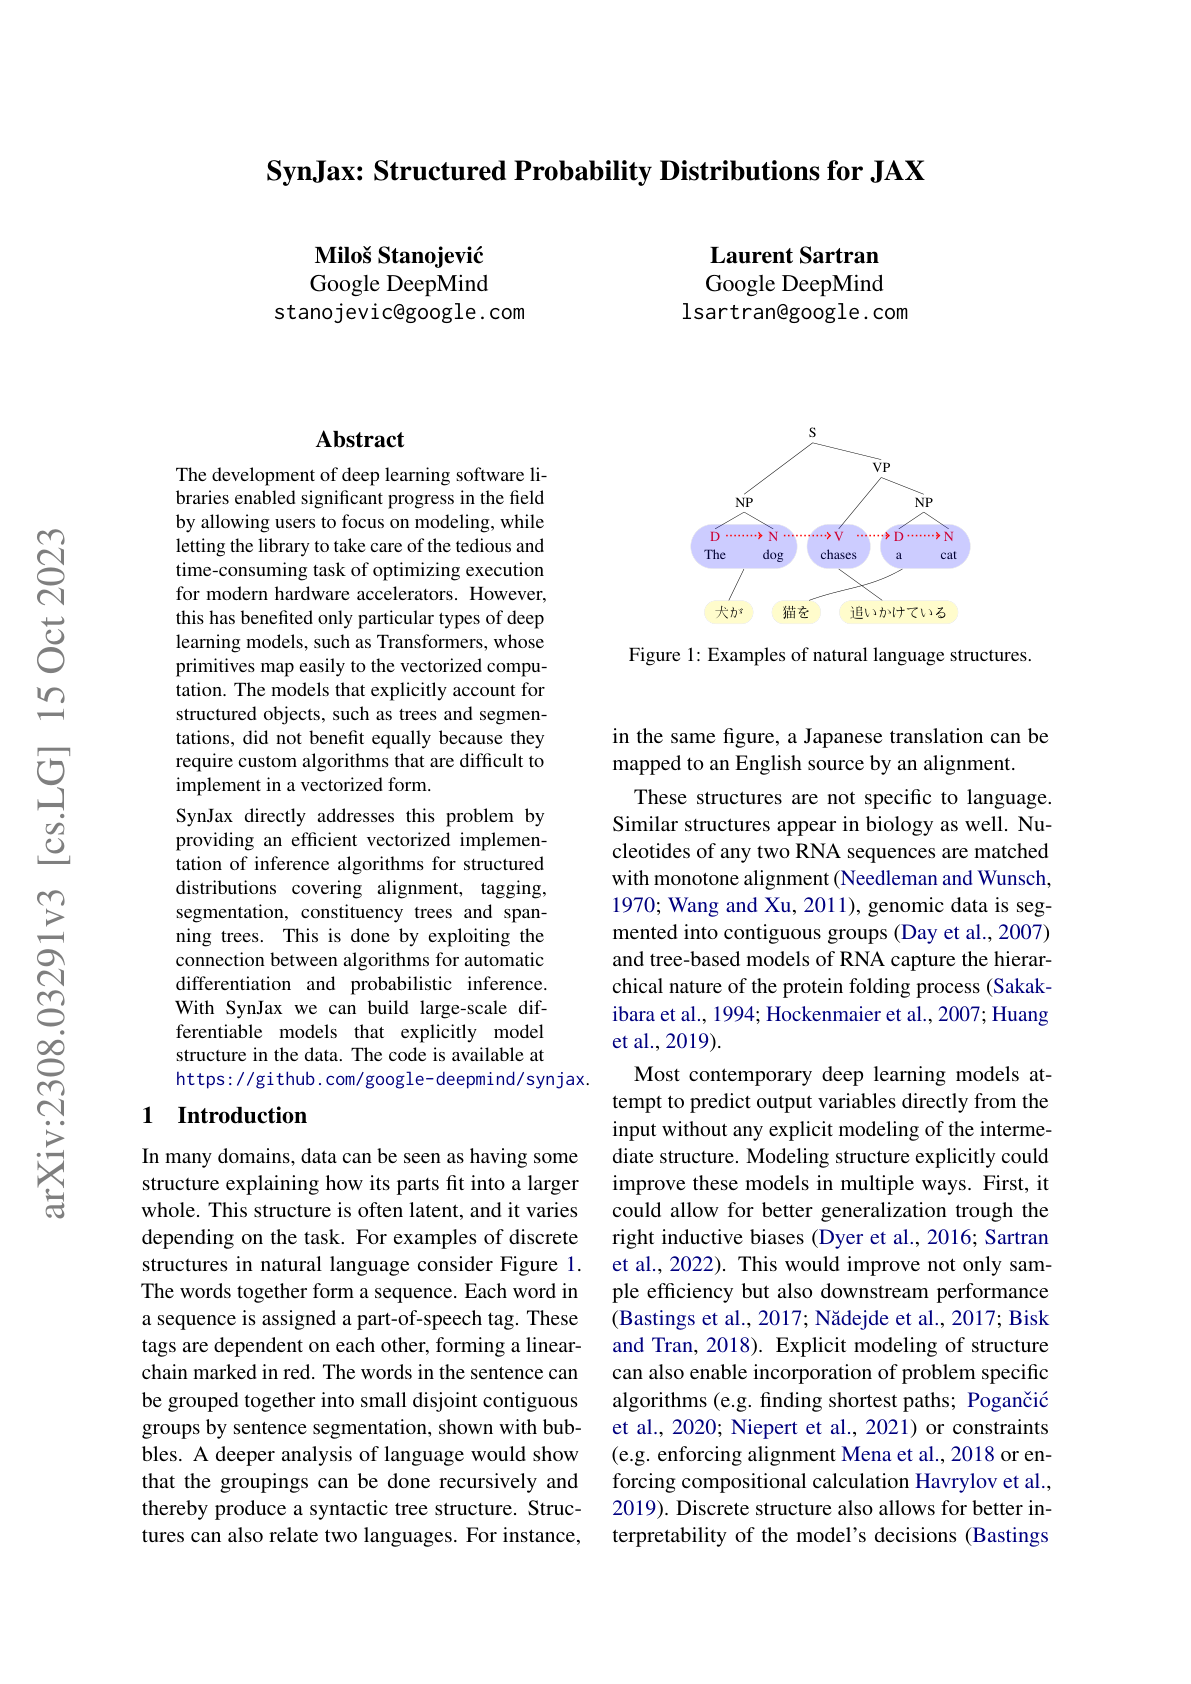
SynJax
DeepMind's SynJax is a JAX-based library for efficient vectorized inference in structured distributions.
Skeleton-of-Thought (SoT)
Microsoft's Skeleton-of-Thought parallelizes LLM generation by first producing an answer skeleton then filling it in concurrently.
FlashAttention-2
Tri Dao's follow-up to FlashAttention, dramatically improving attention throughput on modern GPUs.
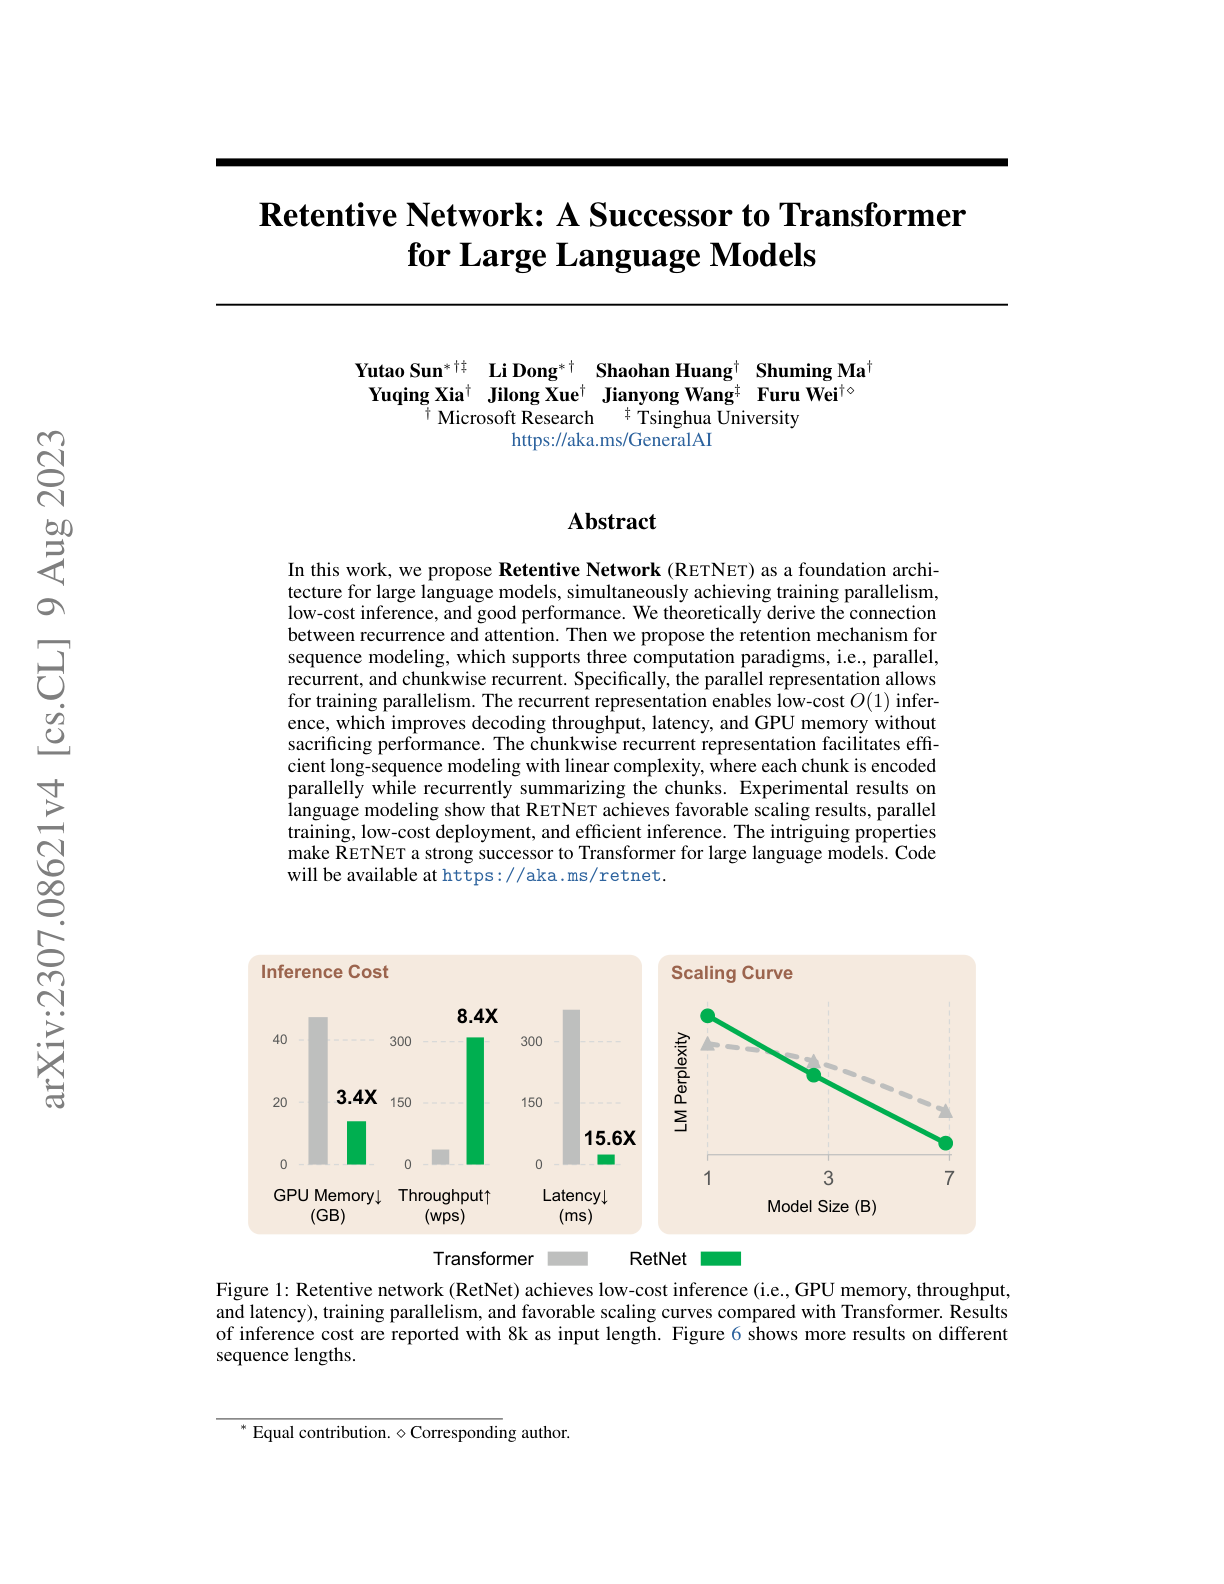
Retentive Network (RetNet)
Microsoft's proposed foundation architecture aiming to replace Transformer attention for LLMs.
Physics-based Motion Retargeting in Real-Time
Uses RL to retarget motions from sparse human sensor data to characters of various morphologies.
LOMO
A memory-efficient optimizer that combines gradient computation and parameter update in one step.
MotionGPT
Generates consecutive human motions from multimodal control signals via LLM instructions.
Wanda
A simple, effective pruning approach for LLMs requiring no retraining.
Sparse-Quantized Representation (SpQR)
Tim Dettmers' near-lossless LLM compression technique.
Fine-Tuning Language Models with Just Forward Passes (MeZO)
A memory-efficient zeroth-order optimizer for LLM fine-tuning.
QLoRA
Tim Dettmers' breakthrough technique enabling 65B LLM fine-tuning on a single 48GB GPU.
Sophia
A simple, scalable second-order optimizer with negligible per-step overhead.
Reinventing RNNs for the Transformer Era (RWKV)
Combines parallelizable training of Transformers with efficient RNN inference.
MEGABYTE
Multiscale Transformers for predicting million-byte sequences.
FrugalGPT
Strategies to reduce LLM inference cost while improving performance.
Learning to Compress Prompts with Gist Tokens
Trains LMs to compress prompts into reusable "gist" tokens.