AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
RLHF Workflow
provides an easily reproducible recipe for online iterative RLHF; discusses theoretical insights and algorithmic principles of online iterative RLHF and practical implementation.
Self-Play Preference Optimization
proposes a self-play-based method for aligning language models; this optimation procedure treats the problem as a constant-sum two-player game to identify the Nash equilibrium policy; it addresses the shortcomings of DPO and IPO and effectively increases the log-likelihood of chose responses and decreases the rejected ones; SPPO outperforms DPO and IPO on MT-Bench and the Open LLM Leaderboard.
Gemma
Google DeepMind releases Gemma, a family of open models (2B and 7B) built from the same research stack as Gemini and shipped with both base and instruction-tuned variants.
Back to Basics: Revisiting REINFORCE in RLHF
Cohere researchers argue that PPO is overkill for RLHF and that a simpler REINFORCE-style estimator works better in practice.
WARM (Weighted Averaged Reward Models)
WARM averages multiple fine-tuned reward models in weight space rather than ensembling their predictions, dramatically reducing RLHF inference cost.
Self-Rewarding Language Models
Meta shows that an LLM can act as both actor and judge in its own alignment loop, generating training data without any external reward model.
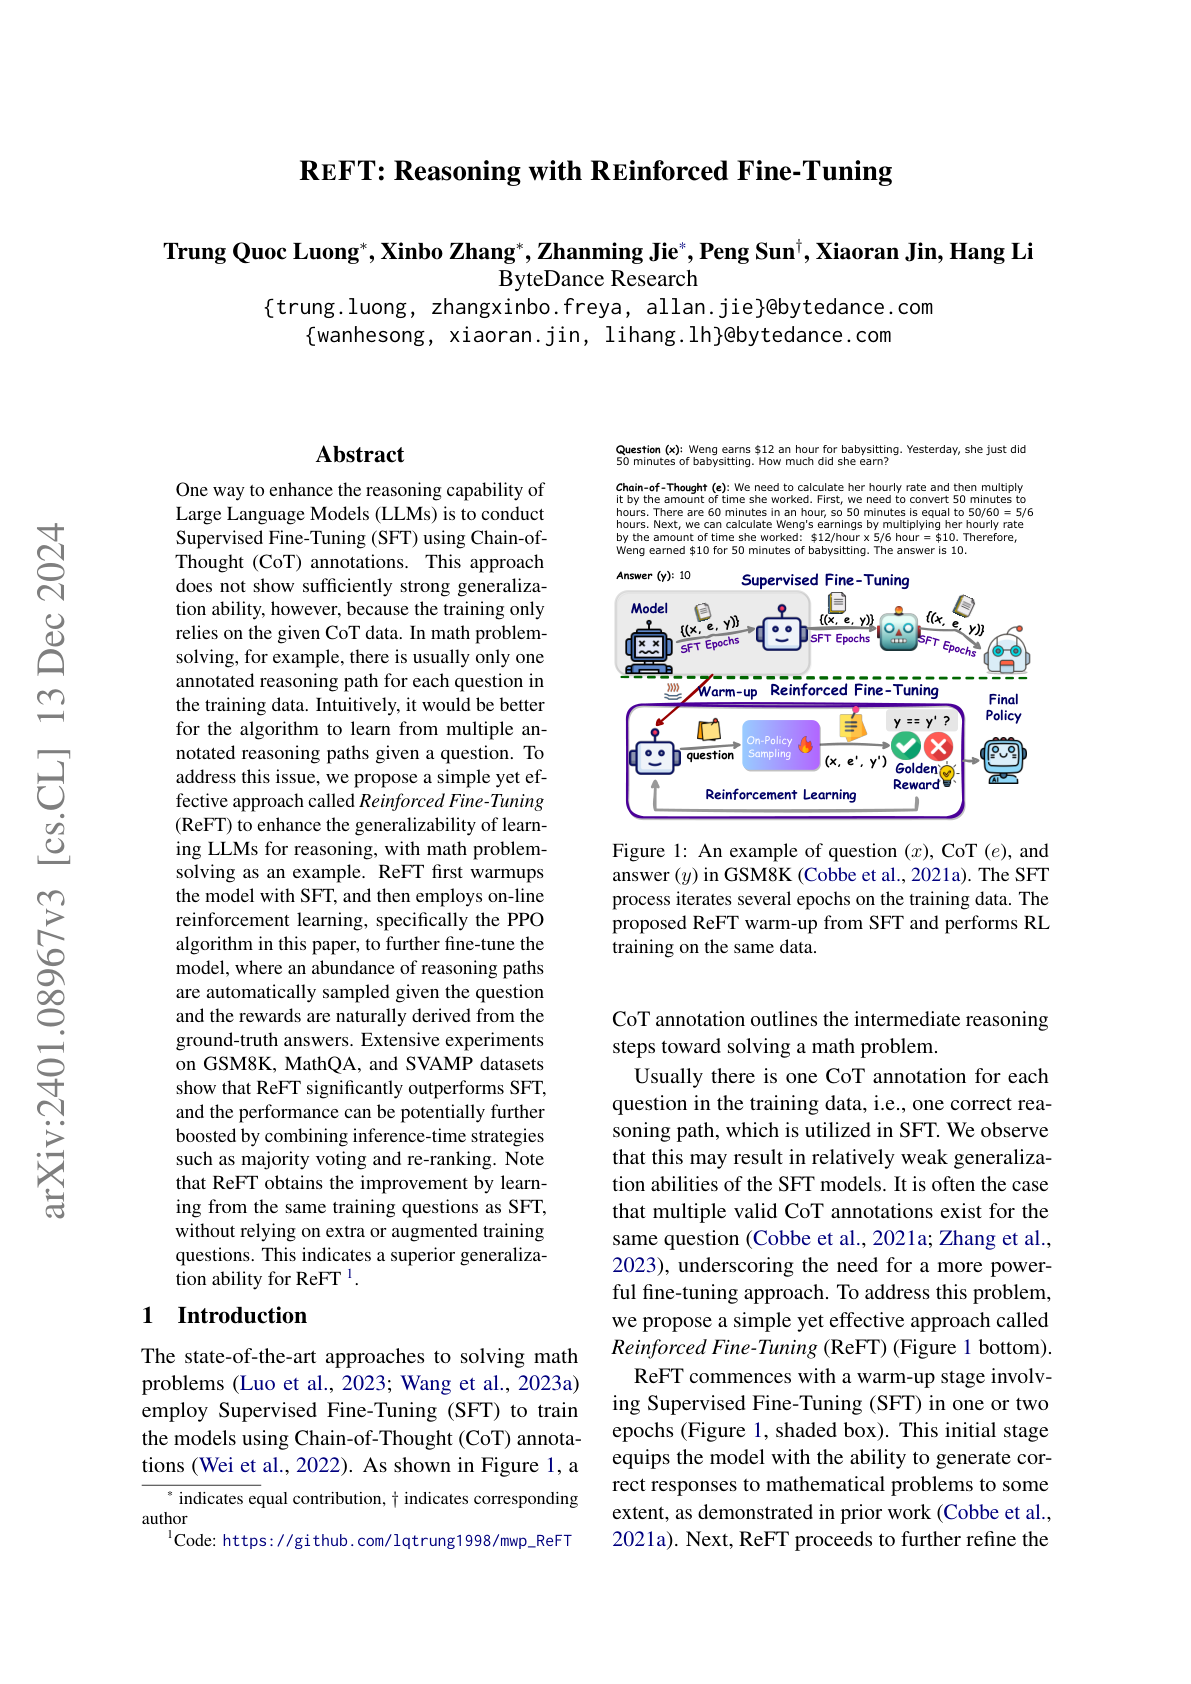
ReFT (Reinforced Fine-Tuning)
ByteDance's ReFT enhances LLM reasoning by combining supervised fine-tuning with online RL that samples alternative reasoning paths, without a learned reward model.
Self-Play Fine-Tuning (SPIN)
SPIN shows that a supervised fine-tuned LLM can keep improving via self-play alone, without any additional human annotations.
Pearl
Meta's Pearl is a production-ready reinforcement learning agent package designed for real-world deployment constraints.
KTO (Kahneman-Tversky Optimization)
Contextual AI introduces KTO, an alignment objective derived from prospect theory that works with binary "good/bad" signals instead of preference pairs.
TÜLU 2
Allen AI's TÜLU 2 is a suite of improved open instruction-tuned LLMs and an accompanying study of adaptation best practices.
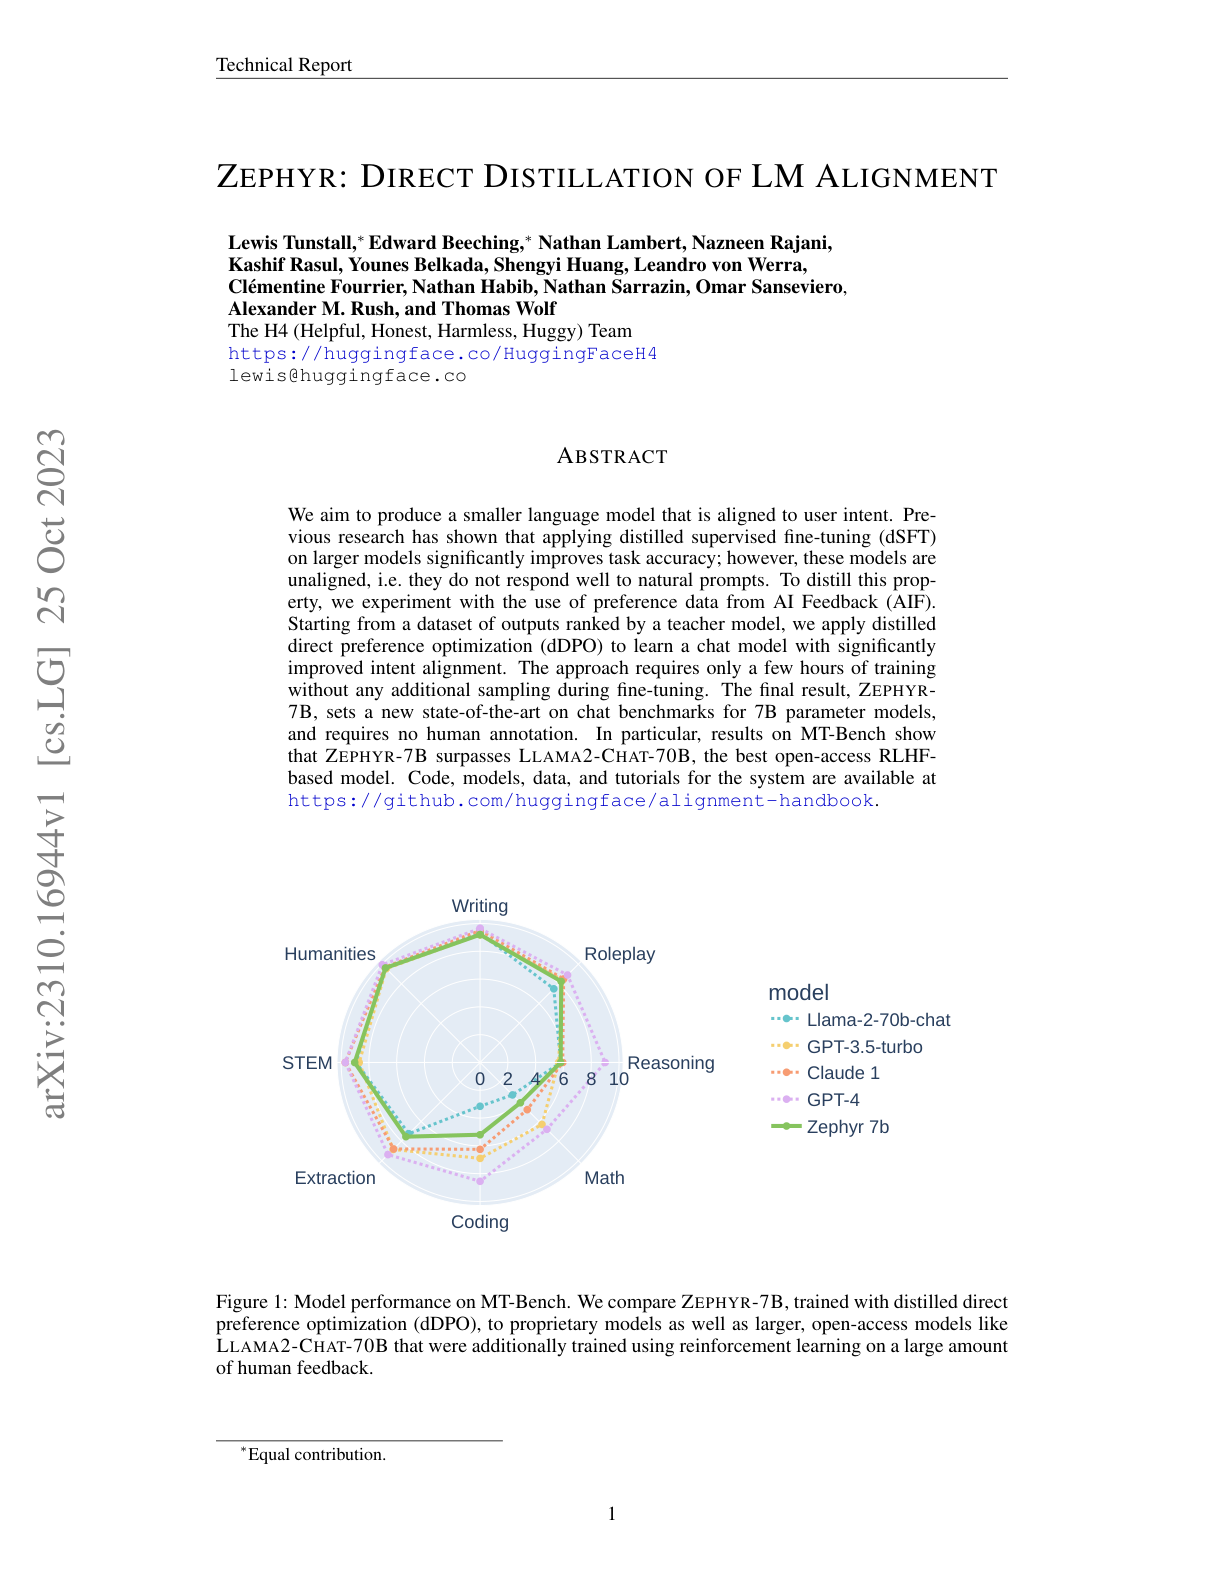
Zephyr
Hugging Face's Zephyr-7B is a 7B parameter LLM whose chat performance rivals much larger chat models aligned with human feedback.
Eliciting Human Preferences with LLMs
Anthropic uses LLMs to guide the task-specification process, eliciting user intent through natural-language dialogue.
LLaVA-RLHF
Adapts factually augmented RLHF to aligning large multimodal models, reducing hallucination without falling into reward-hacking pitfalls.
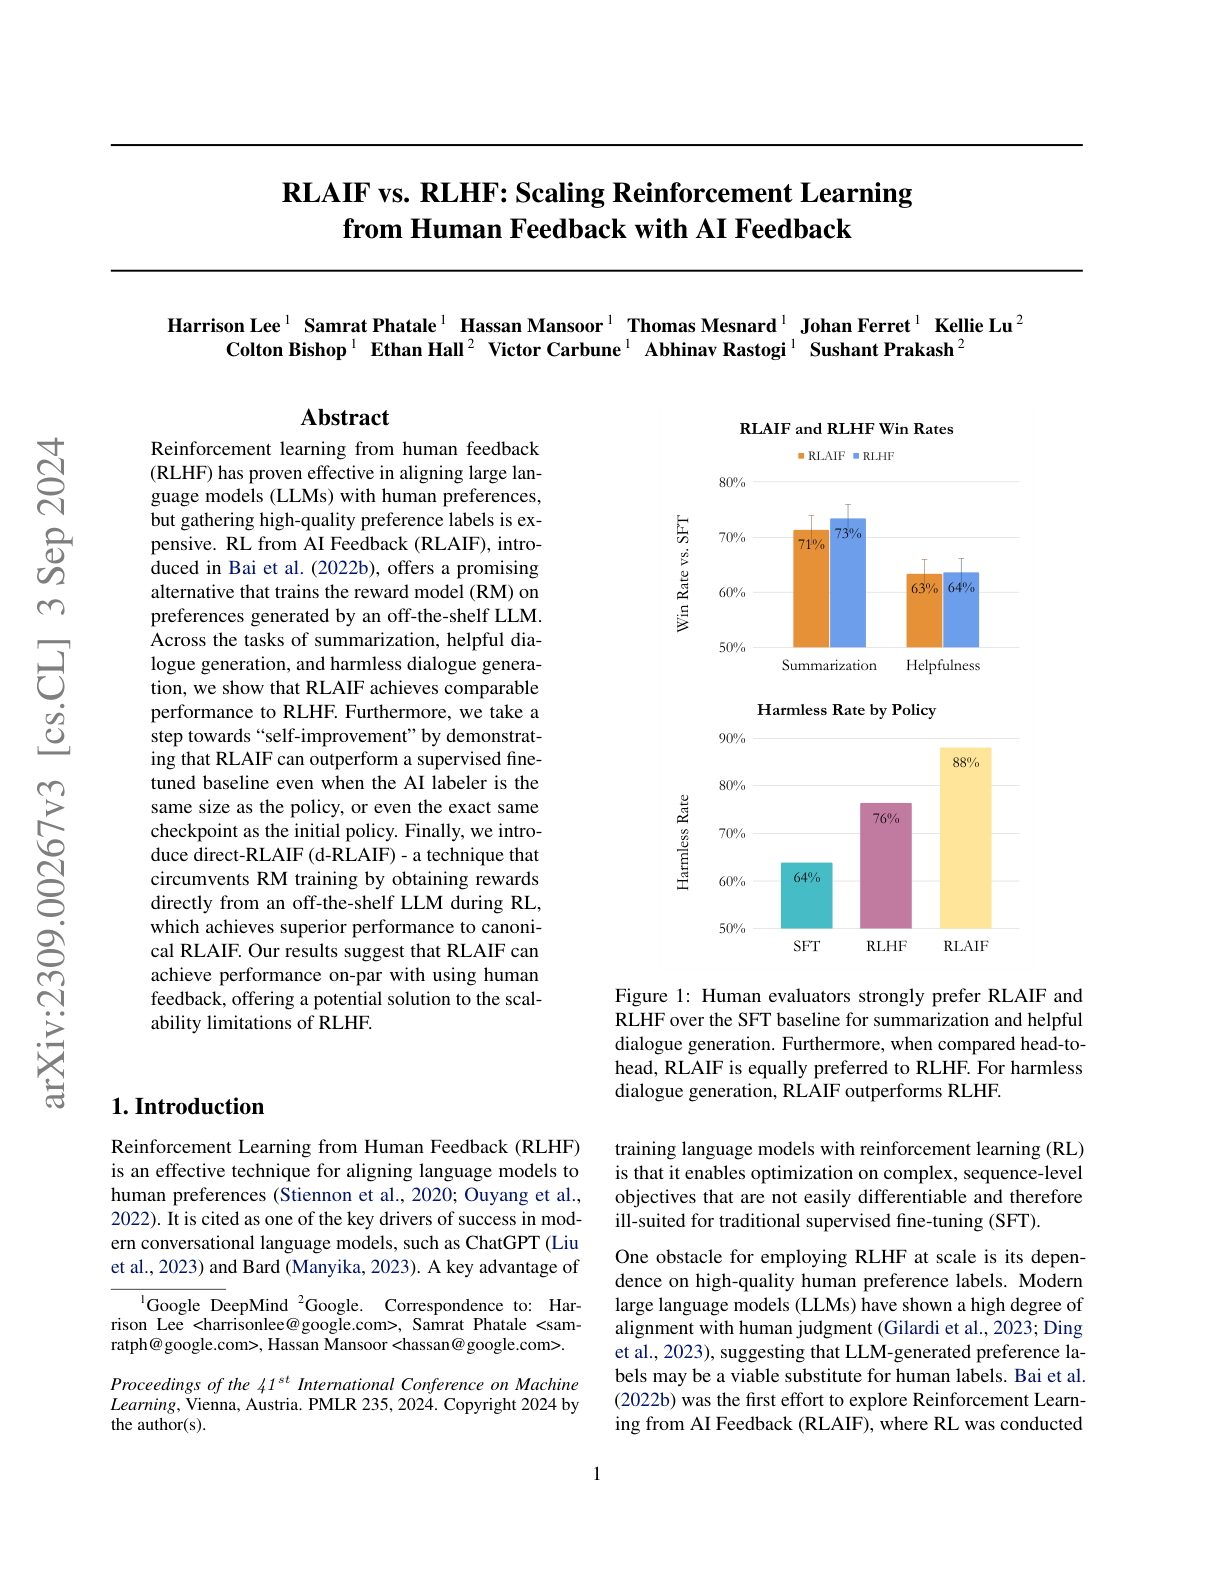
RLAIF (Scaling RLHF with AI Feedback)
Google compares RLHF with RLAIF (Reinforcement Learning from AI Feedback) to test whether AI preferences can replace human preferences.
Open Problems and Limitations of RLHF
A comprehensive survey of open problems and fundamental limitations of RLHF as an alignment approach.
Survey of Aligned LLMs
A comprehensive overview of alignment approaches covering data, training, and evaluation.
Llama 2
Meta's open-weight foundation model family with chat-tuned variants ranging from 7B to 70B parameters.
Secrets of RLHF in LLMs
A deep investigation into RLHF with a focus on the inner workings of PPO, including open-source code.
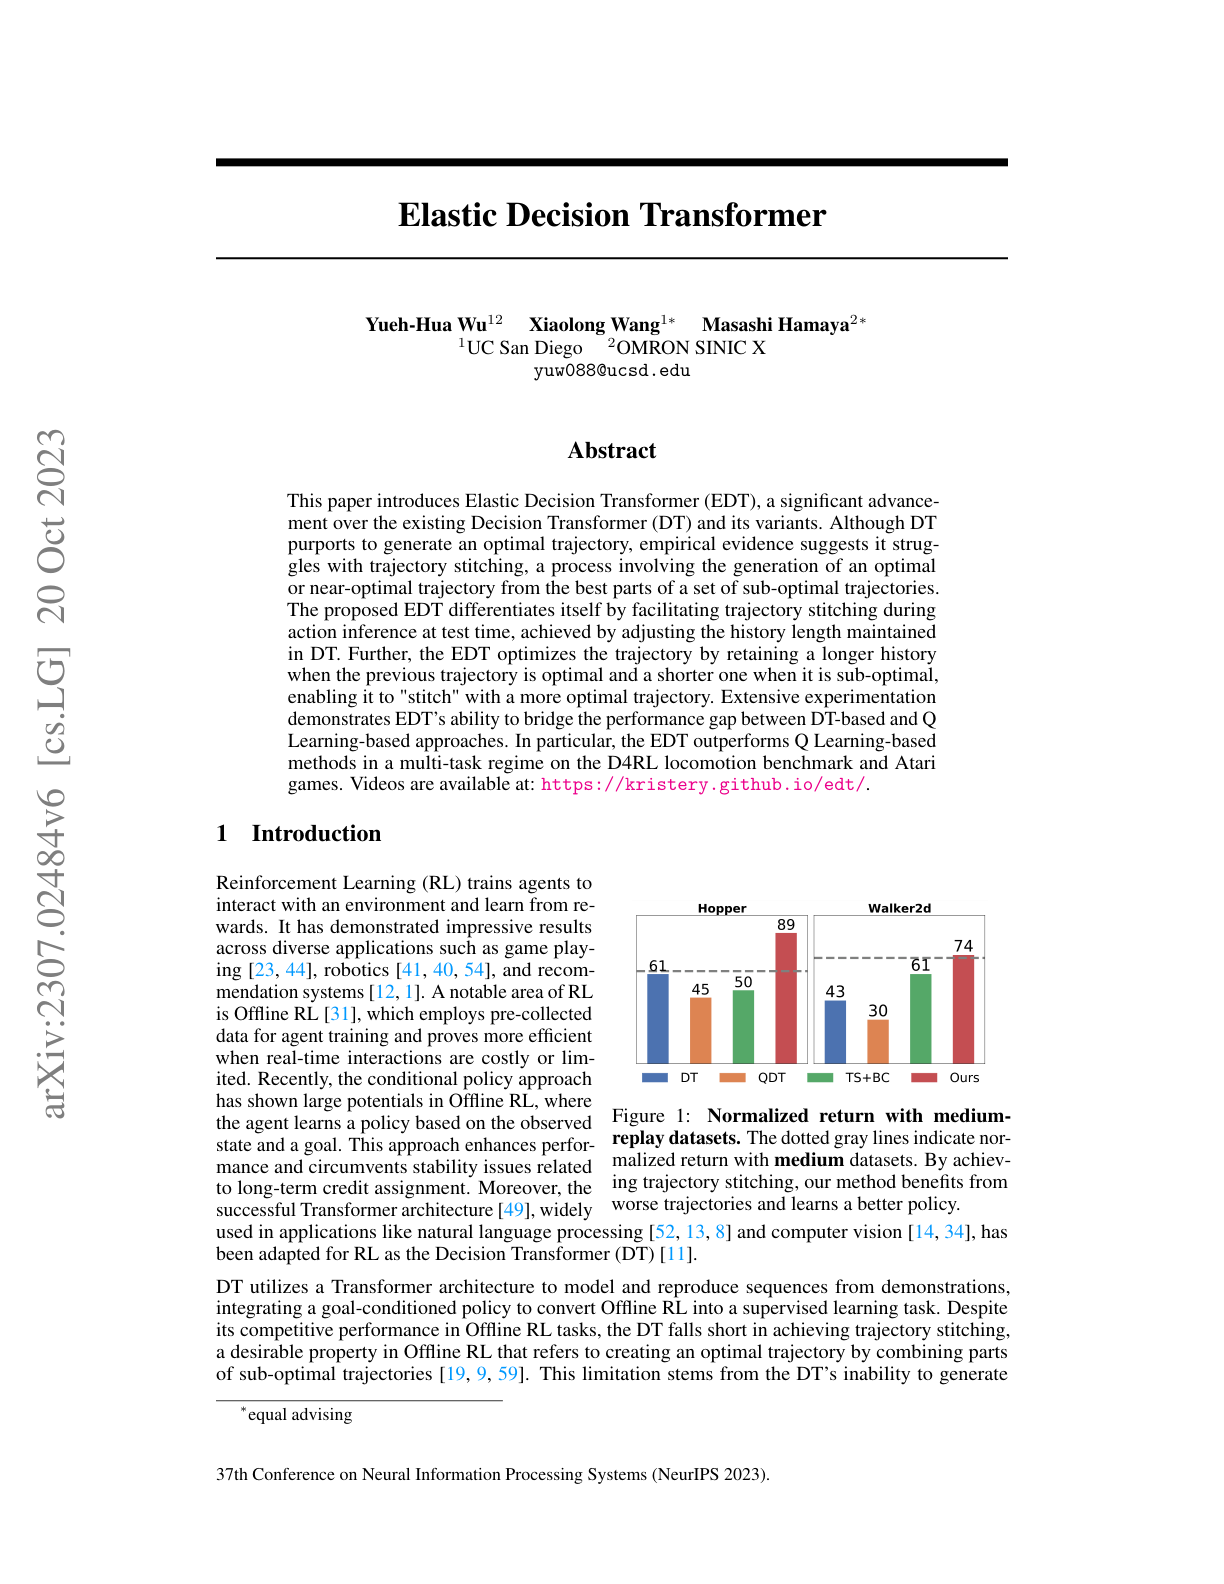
Elastic Decision Transformer
An advance over Decision Transformers that enables trajectory stitching at inference time.
InterCode
A framework treating interactive coding as a reinforcement learning environment.
SequenceMatch
Formulates sequence generation as imitation learning, enabling backtracking via a backspace action.
AlphaDev
DeepMind's deep RL agent discovering faster sorting algorithms from scratch, now in LLVM.
Fine-Grained RLHF
Trains LMs with segment-level human feedback rather than whole-response preferences.