AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
SocioVerse
Researchers from Fudan University and collaborators propose SocioVerse, a large-scale world model for social simulation using LLM agents aligned with real-world user behavior. Key ideas include:
DocAgent
Researchers from Meta AI present DocAgent, a tool‑integrated, dependency‑aware framework that turns large, complex codebases into well‑written docstrings. Key ideas include:
SWE-PolyBench
SWE-PolyBench is a new multi-language benchmark for evaluating coding agents on real-world software tasks across Java, JavaScript, TypeScript, and Python. It introduces execution-based assessments, syntax tree metrics, and reveals that current agents struggle with complex tasks and show inconsistent performance across languages.
A Survey of Frontiers in LLM Reasoning
This survey categorizes LLM reasoning methods by when reasoning occurs (inference-time vs. training) and the system's architecture (standalone vs. agentic or multi-agent). It highlights trends like learning-to-reason (e.g., DeepSeek-R1) and agentic workflows (e.g., OpenAI Deep Research), covering prompt engineering, output refinement, and learning strategies such as PPO and verifier training.
Advances in Embodied Agents, Smart Cities, and Earth Science
This paper surveys how spatial intelligence manifests across disciplines—from embodied agents to urban and global systems—by connecting human spatial cognition with how LLMs handle spatial memory, representations, and reasoning. It offers a unifying framework to bridge research in AI, robotics, urban planning, and earth science, highlighting LLMs’ evolving spatial capabilities and their interdisciplinary potential.
The AI Scientist V2
The AI Scientist-v2 refines and extends its predecessor to achieve a new milestone: autonomously generating a workshop-accepted research manuscript. The system removes dependencies on human-authored code templates, incorporates agentic tree-search methods for deeper exploration, uses Vision-Language Models to refine figures, and demonstrates impressive real-world outcomes by passing the peer-review bar.
Benchmarking Browsing Agents
OpenAI introduces BrowseComp, a benchmark with 1,266 questions that require AI agents to locate hard-to-find, entangled information on the web. Unlike saturated benchmarks like SimpleQA, BrowseComp demands persistent and creative search across numerous websites, offering a robust testbed for real-world web-browsing agents. Key insights:
OLMOTrace
Allen Institute for AI & University of Washington present OLMOTRACE, a real-time system that traces LLM-generated text back to its verbatim sources in the original training data, even across multi-trillion-token corpora.
Concise Reasoning via RL
This new paper proposes a new training strategy that promotes concise and accurate reasoning in LLMs using RL. It challenges the belief that long responses improve accuracy; it offers both theoretical and empirical evidence showing that conciseness often correlates with better performance.
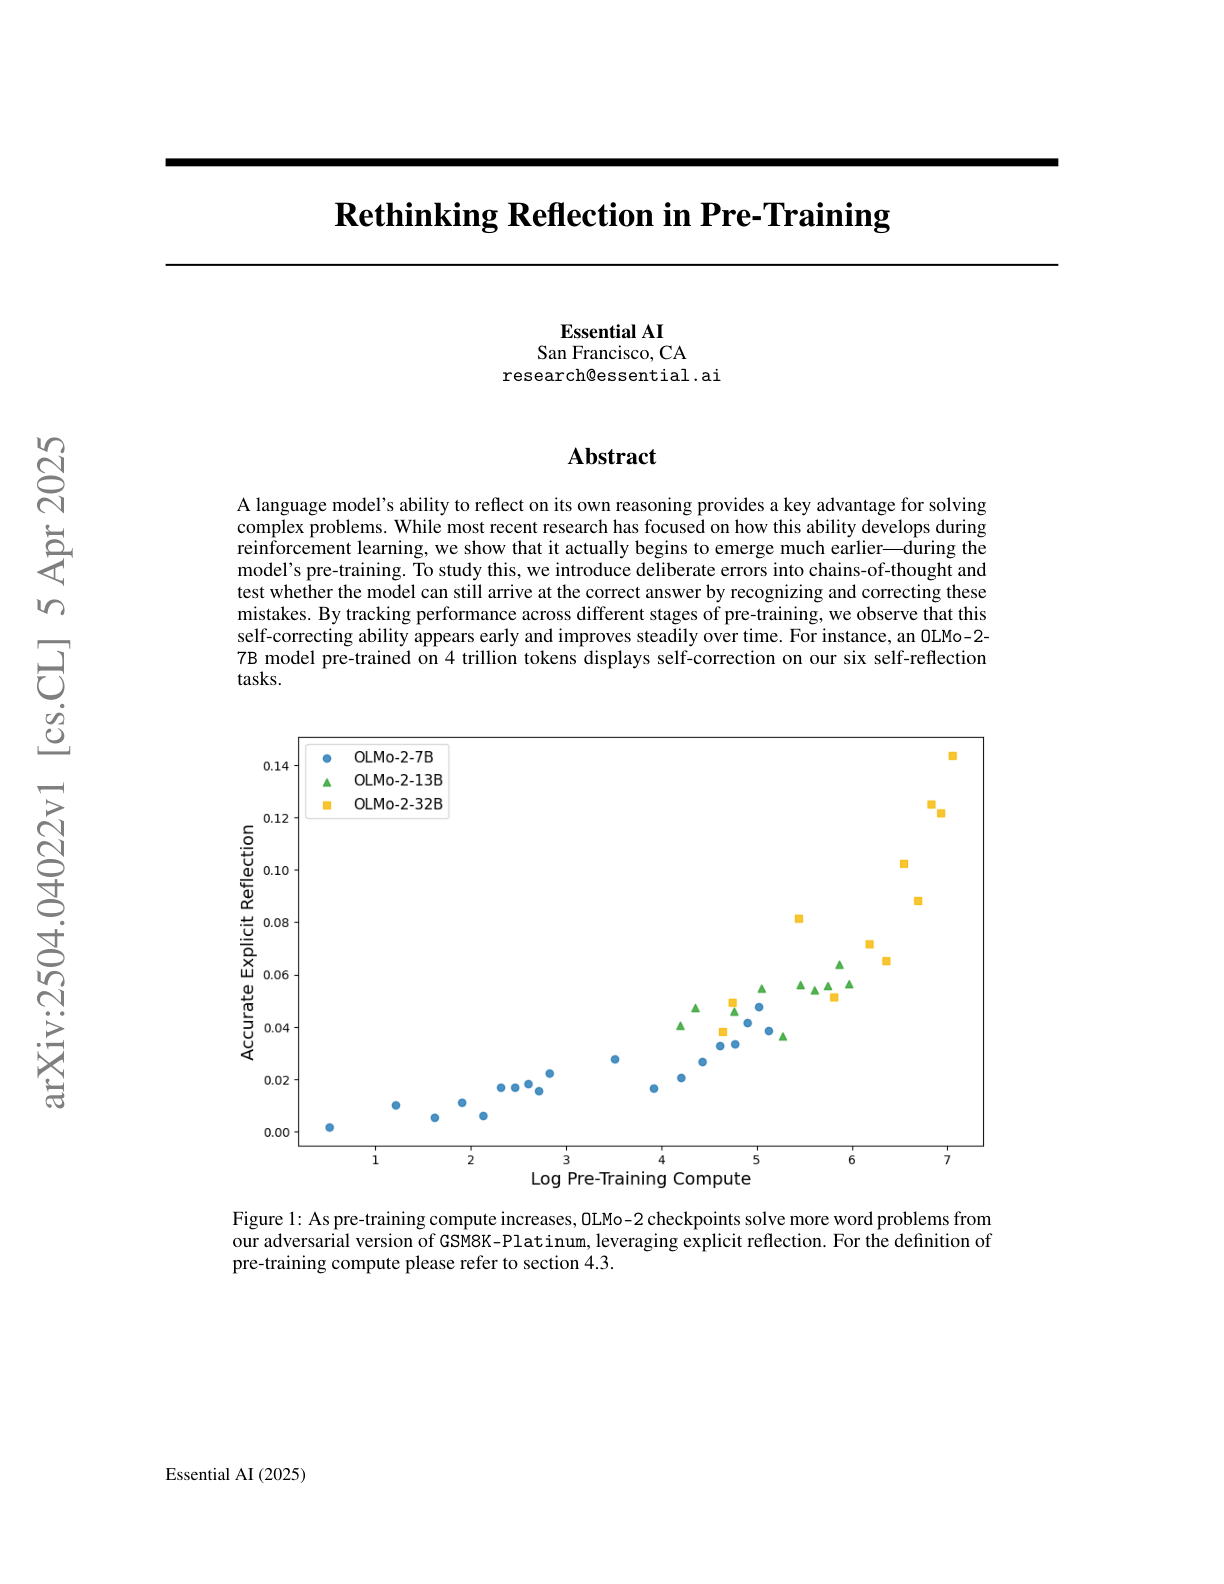
Rethinking Reflection in Pre-Training
Reflection — the ability of LLMs to identify and correct their own reasoning — has often been attributed to reinforcement learning or fine-tuning. This paper argues otherwise: reflection emerges during pre-training. The authors introduce adversarial reasoning tasks to show that self-reflection and correction capabilities steadily improve as compute increases, even in the absence of supervised post-training. Key contributions:
Efficient KG Reasoning for Small LLMs
LightPROF is a lightweight framework that enables small-scale language models to perform complex reasoning over knowledge graphs (KGs) using structured prompts. Key highlights:
Compute Agent Arena
Computer Agent Arena is a new open platform for benchmarking LLM and VLM-based agents on real-world computer-use tasks, like coding, editing, and web navigation, using a virtual desktop environment. Initial results show that OpenAI and Anthropic are leading with modest success rates, while the platform aims to grow through crowdsourced tasks, agent submissions, and open-sourcing of its infrastructure. [Report](https://arena.xlang.ai/blog/computer-agent-arena)
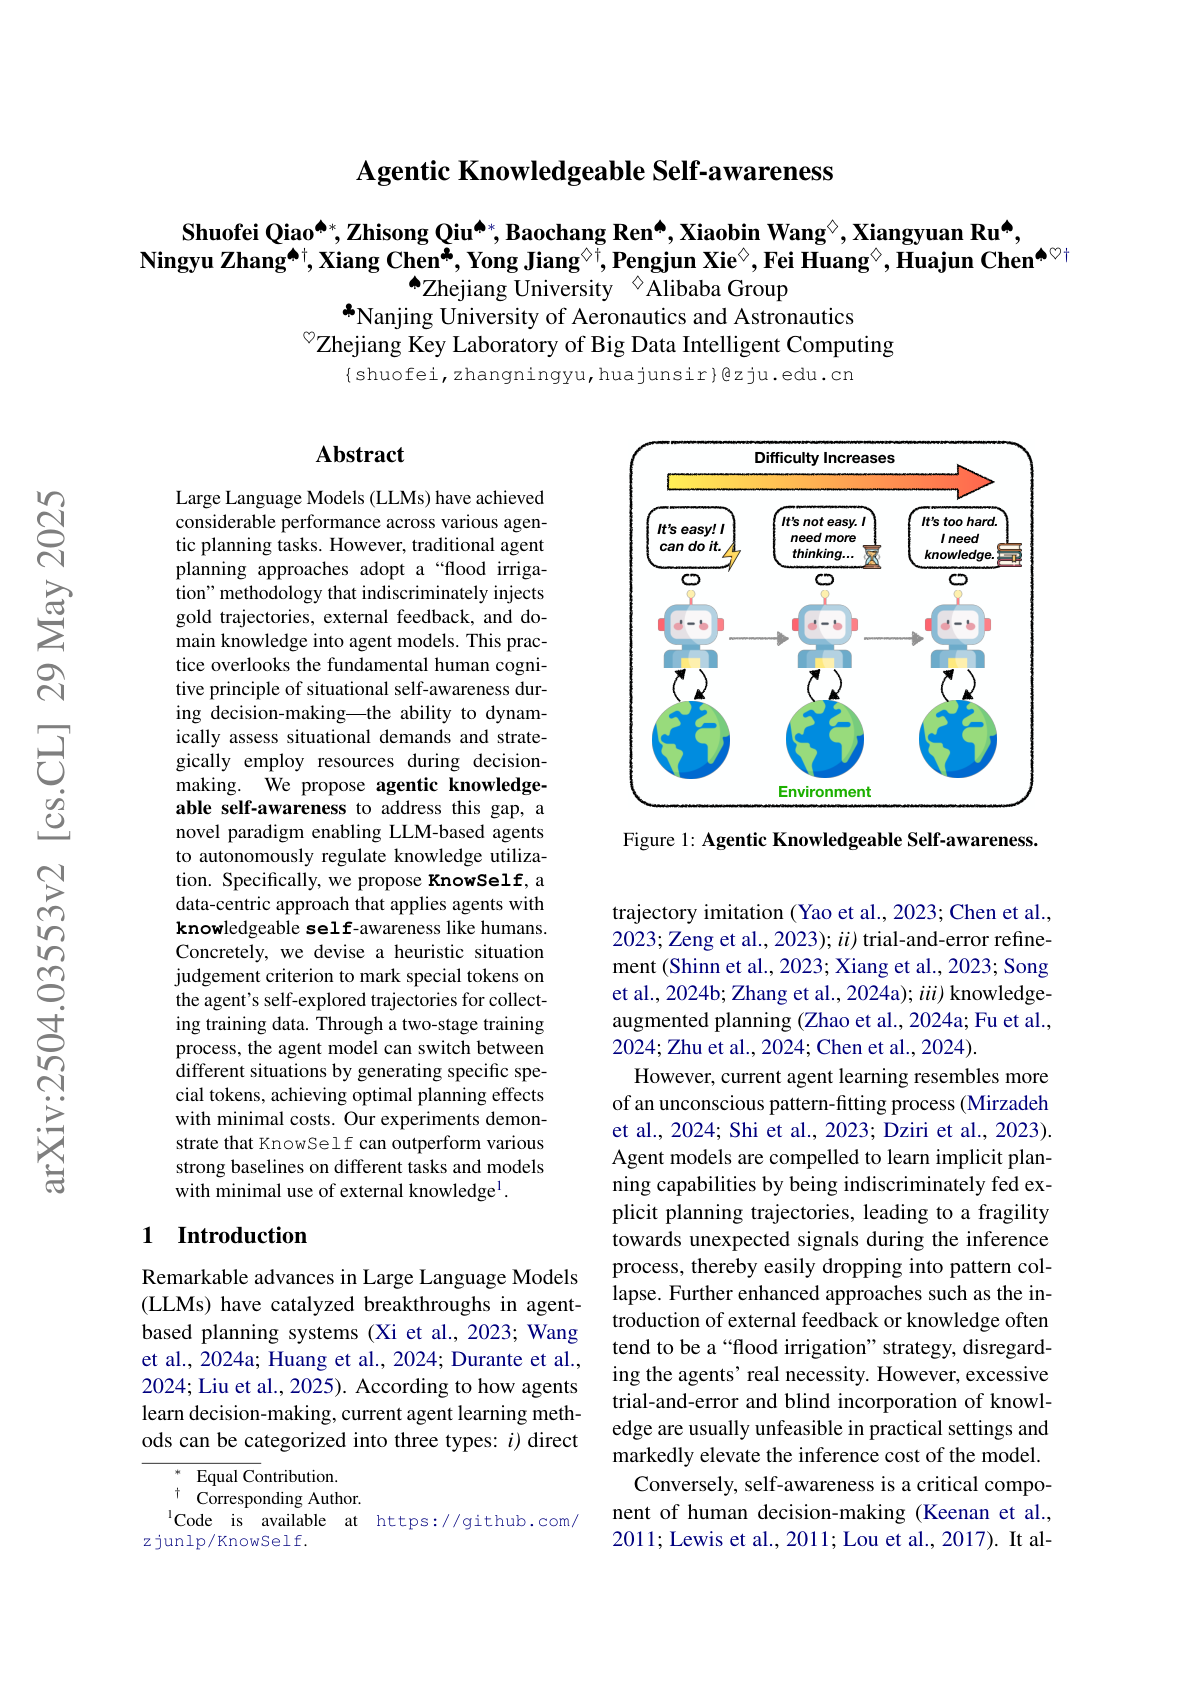
Agentic Knowledgeable Self-awareness
KnowSelf is a new framework that introduces agentic knowledgeable self-awareness, enabling LLM agents to dynamically decide when to reflect or seek knowledge based on situational complexity, mimicking human cognition. Using special tokens for "fast," "slow," and "knowledgeable" thinking, KnowSelf reduces inference costs and achieves state-of-the-art performance on ALFWorld and WebShop tasks with minimal external knowledge.
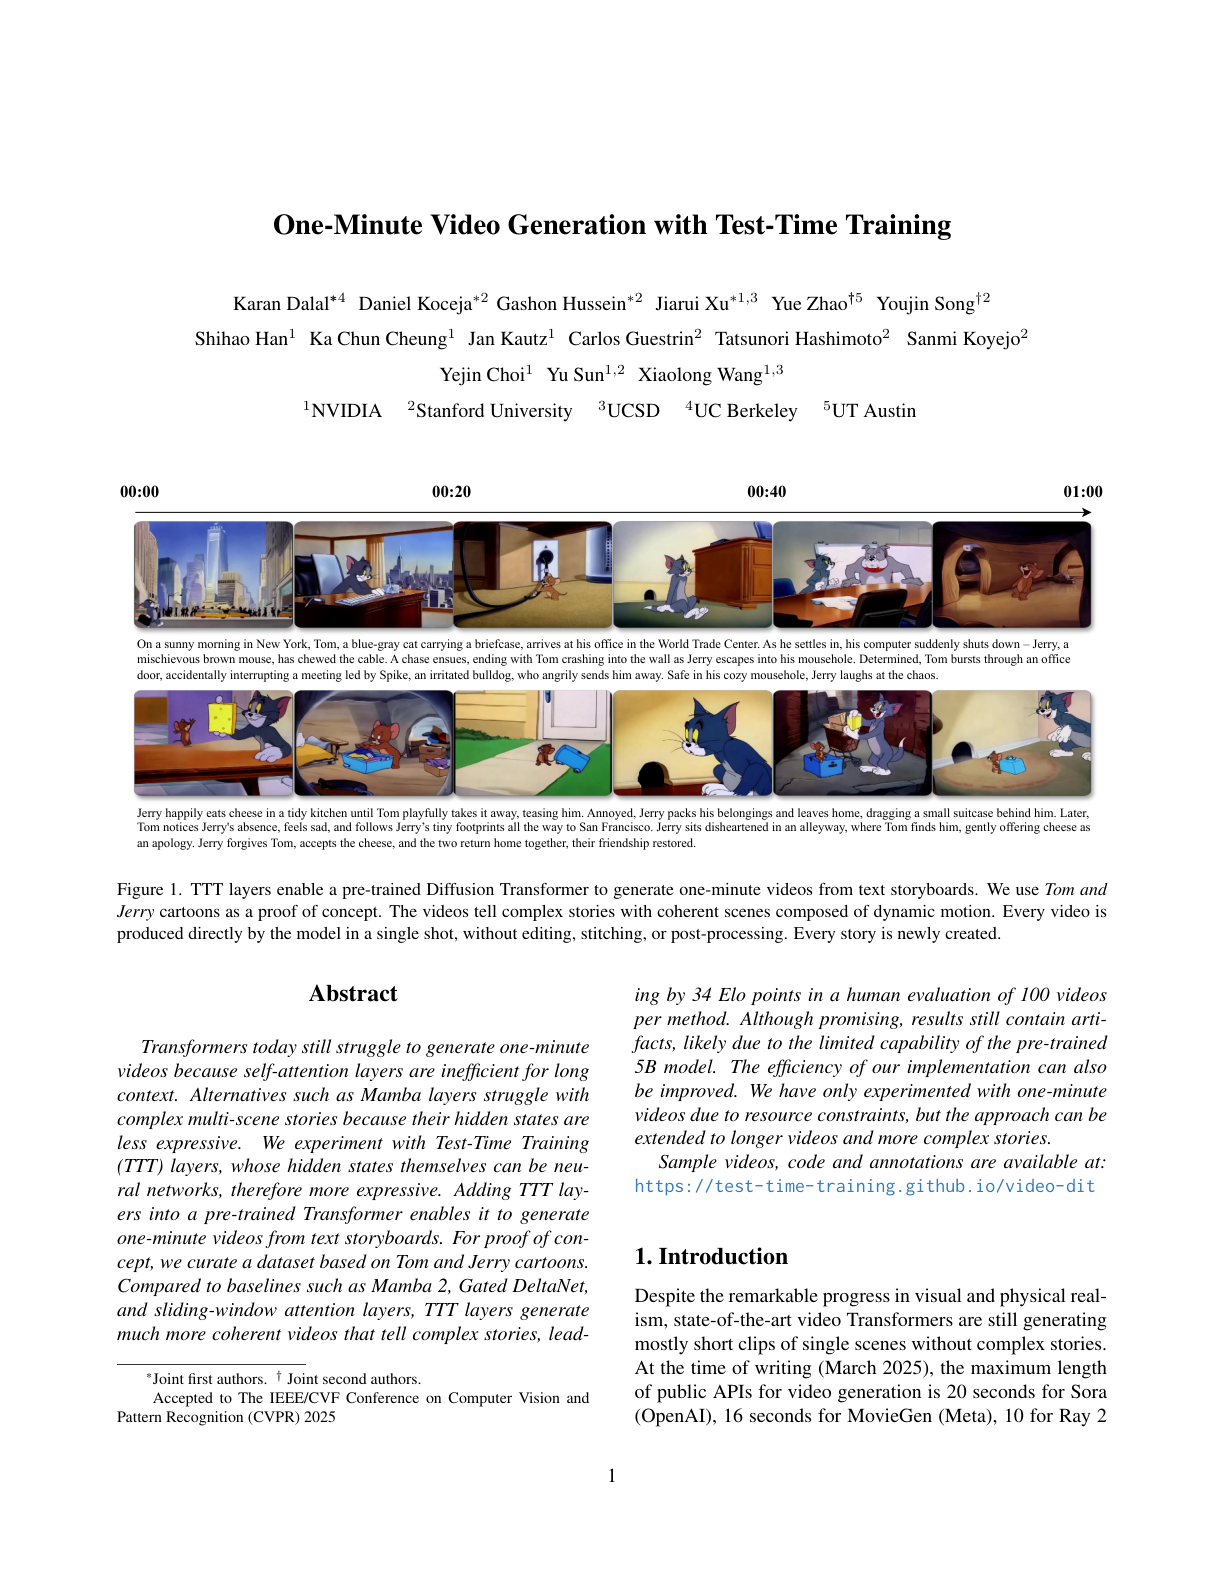
One-Minute Video Generation with Test-Time Training
One-Minute Video Generation with Test-Time Training introduces TTT layers, a novel sequence modeling component where hidden states are neural networks updated via self-supervised loss at test time. By integrating these into a pre-trained diffusion model, the authors enable single-shot generation of one-minute, multi-scene videos from storyboards, achieving 34 Elo points higher than strong baselines like Mamba 2 and DeltaNet in human evaluations
NoProp
NoProp is a novel gradient-free learning method where each neural network layer independently learns to denoise a noisy version of the target, inspired by diffusion and flow matching. Unlike backpropagation, it avoids hierarchical representation learning and achieves competitive performance and efficiency on image classification benchmarks like MNIST and CIFAR.
PaperBench
OpenAI introduces a new benchmark, PaperBench, to test whether AI agents can replicate cutting-edge machine learning research papers, from scratch. ● A rigorous replication challenge – PaperBench evaluates agents on reproducing entire ML papers from ICML 2024 (20 total, across 12 research areas). Agents must understand the paper, build the codebase from scratch, and run experiments to match results. Each paper comes with a fine-grained rubric (~8,316 tasks total) co-designed with the original authors. ● Automatic grading with LLM judges – To make evaluation scalable, the team built a rubric-based judge (o3-mini with scaffolding) that scores replications with high agreement (F1 = 0.83) against human experts. They also release JudgeEval, a benchmark for assessing judge accuracy. ● Frontier model performance is modest – Claude 3.5 Sonnet scored highest with 21.0%, followed by o1 (13.2%) and GPT-4o (4.1%). Even with longer runtimes and prompt tuning (IterativeAgent), no model surpassed a 26.0% score. By contrast, ML PhDs hit 41.4% on a 3-paper subset in 48 hours, showing humans still lead in long-horizon agentic tasks. ● CodeDev variant for lightweight evals – A simplified PaperBench Code-Dev version skips execution and just grades code structure. o1 scored 43.4% there, showing more promise when runtime issues are excluded. ● Failure modes and insights – Models often “gave up early,” lacked strategic planning, and failed to iterate. Claude did better with BasicAgent (freer form), while o1 benefited from IterativeAgent (structured prompts). This highlights how sensitive agents are to prompting and scaffolding. ● Open-source release – PaperBench (with rubrics, grading infra, and replication results) is fully open-sourced to drive further progress on long-horizon agent tasks and autonomous AI R&D.
Command A: An Enterprise-Ready LLM
Cohere announced Command A, a 111B parameter open-weights LLM built for enterprise-grade RAG, agents, code, and multilingual tasks. Key contributions: ● Modular expert merging for domain mastery – Instead of monolithic post-training, Command A uses a decentralized training pipeline. Separate expert models are fine-tuned for specific domains (e.g., math, RAG, multilingual, safety, code), then merged into one model using efficient weighted parameter soup techniques. This preserves most expert performance with just ~1.8% average drop. ● Hybrid architecture for long-context efficiency – Command A interleaves sliding window and full attention layers, achieving 256k context support with drastically lower KV cache memory usage—e.g., only ~33% of LLaMA 3 70B at 128k. It scores 95.0% on RULER, outperforming most long-context peers. ● Superb agentic capabilities – Built for RAG, tool use, and ReAct-style agents, Command A beats GPT-4o and Claude 3.5 on TauBench and BFCL. Tool use is trained via a blend of human-annotated and synthetic data, then aligned with CoPG and SRPO (self-improving preference optimization). ● Best-in-class enterprise evaluations – On real-world generative tasks (e.g., chat summarization, FAQ generation) and RAG use cases (long workplace policy documents), Command A tops the leaderboard with 94.2% pass rate, 4.73 correctness, and 91% unanswerable QA accuracy. ● Multilingual excellence – Command A is trained in 23 global languages with heavy data curation and preference tuning. It scores #1 in dialect alignment (ADI2), 90.3% average LPR (language consistency), and outperforms LLaMA 3.3, GPT-4o, and DeepSeek in manual Arena-style win rates across all languages. ● Polishing for human alignment – Final alignment used a ping-pong loop of offline SRPO and online CoPG with RLHF. This yielded +17pt human win rate gains on code, +10pt on reasoning, and lifted Command A’s win rate over GPT-4o to parity (~50.4%). ● Fast, efficient, and open – Despite its power, Command A runs on just 2×A100s or H100s and generates 156 tokens/sec—faster than GPT-4o and DeepSeek. Model weights are released (CC-BY-NC) on Hugging Face.
CodeScientist
Researchers at AI2 release CodeScientist, a system that autonomously generates and tests scientific hypotheses via code-based experimentation. It’s among the first to produce validated discoveries with minimal human input. Key ideas: ● Code-first scientific agent – CodeScientist reviews research papers and assembles experiments using vetted Python code blocks (e.g., for analysis, simulation). It follows a five-step pipeline: Ideation → Planning → Code Execution → Reporting → Meta-Analysis. ● Validated AI discoveries – From 50 AI research papers on agents and virtual environments, CodeScientist proposed 19 findings. Of these, 6 were judged scientifically sound and novel. Examples: ● Human-guided autonomy – Full automation is possible, but brief human feedback (e.g., ranking ideas) significantly boosts output quality. Human-in-the-loop interaction improves idea selection and experiment debugging. ● Challenges remain – Despite successes, over half the generated experiments fail due to code errors, not scientific flaws. Peer review is still needed to verify results, and current systems lack deep methodological rigor.
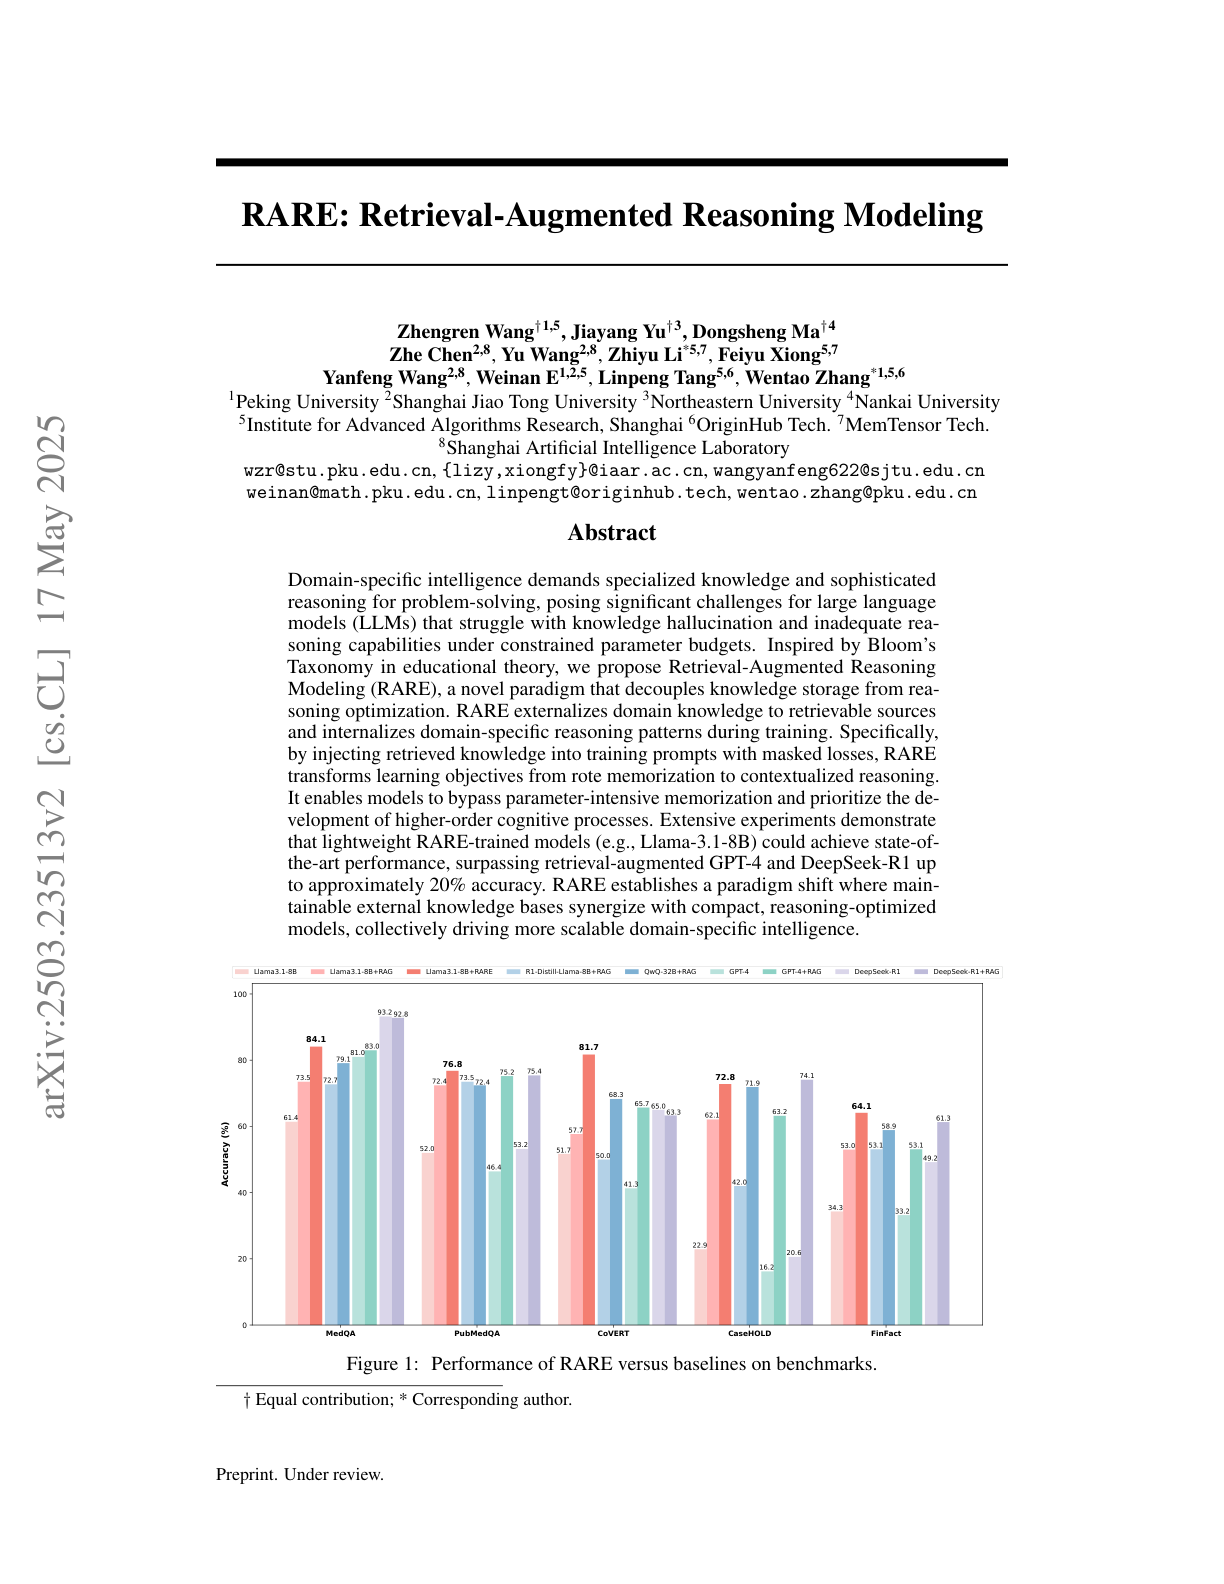
Retrieval-Augmented Reasoning Model
Introduces RARE, a new paradigm for training domain-specific LLMs that focuses on reasoning, not memorization. Key ideas: ● Inspired by Bloom’s Taxonomy – RARE shifts LLM training from memorizing knowledge (“Remember”) to applying and evaluating it (“Analyze”, “Create”). It separates domain knowledge (retrieved externally) from domain thinking (learned during training), enabling better performance under tight parameter budgets. ● Open-book prepared training – RARE injects retrieved knowledge into training prompts, letting models learn reasoning patterns instead of rote facts. This open-book, reasoning-first setup beats both standard SFT and RAG approaches, especially in medicine. ● Massive accuracy gains with small models – On five medical QA benchmarks, RARE-trained Llama-3.1-8B and Qwen-2.5-7B outperformed GPT-4 + RAG, with up to +20% accuracy boosts (e.g., PubMedQA: 78.63% vs. GPT-4’s 75.2%, CoVERT: 74.14% vs. GPT-4’s 65.67%). ● Training via distillation + adaptive retries – RARE distills answers (and reasoning paths) from a strong teacher (e.g., QwQ-32B), refining outputs until a correct answer is found. This creates a high-quality dataset that teaches contextualized, case-based thinking. ● New role for retrieval – Unlike standard RAG (used only at inference), RARE uses retrieval during training to shape reasoning. It models knowledge integration (p(kx, R(x))) and reasoning (p(rx, R(x), k)) as separate steps, replacing memorization with application. Overall, this work reframes LLM training for domain-specific intelligence: externalize facts, internalize reasoning. It unlocks strong performance from small models without overfitting or hallucination.
Why do LLMs Attend to First Token?
This new paper explains why LLMs obsessively focus attention on the first token — a phenomenon known as an attention sink. Their theory: it’s a useful trick to prevent representational collapse in deep Transformers. ● Sinks = over-mixing shields – LLMs with long contexts and deep layers tend to over-mix information, causing similar embeddings for all tokens (i.e., rank collapse or over-squashing). Attention sinks—where many heads fixate on the ⟨bos⟩ token—act as no-ops that reduce token interaction and preserve representation diversity across layers. ● Sharp experiments on Gemma & LLaMa – Perturbation tests in Gemma 7B show ⟨bos⟩ significantly slows the spread of changes through the model. Meanwhile, in LLaMa 3.1 models, over 80% of attention heads show strong sink behavior in the 405B variant, supporting the theory that larger models need stronger sinks. ● Sinks emerge naturally – Even without special pretraining, sinks tend to form at the first position, not because of the ⟨bos⟩ token itself, but due to its location. However, if ⟨bos⟩ is fixed during training and later removed, performance collapses, showing that sink formation is data-dependent. ● Theoretical grounding – The authors connect sink emergence to Jacobian norm bounds, proving that sinks reduce sensitivity to token perturbations. Their math shows that deeper models and longer contexts require stronger sinks. ● Layerwise dynamics insight – Some attention heads use ⟨bos⟩ as a “default” target, unless a special pattern (e.g., apostrophe) triggers real computation. This supports a conditional attention mechanism—attend to ⟨bos⟩ unless needed elsewhere.
Self-Evolving Multi-Agent Simulations for Realistic Clinical Interactions
Presents MedAgentSim is a fully automated, open-source hospital simulation where LLM-powered agents simulate doctor-patient interactions in dynamic diagnostic settings. Unlike previous static QA benchmarks, MedAgentSim mimics real-world clinical workflows with multi-turn dialogue, test requests, and self-improvement. More about this paper: ● Active doctor agents – MedAgentSim requires LLM doctor agents to engage in multi-turn consultations, request labs and imaging (e.g., ECG, X-ray), and iteratively refine diagnoses, making it far more realistic than pre-filled medical QA datasets. ● Self-improvement via memory + reflection – The system maintains buffers of successful and failed diagnoses. It uses retrieved past cases (via kNN), chain-of-thought reasoning, and ensembling to improve performance over time. Misdiagnoses trigger a reflection phase before inclusion in memory. ● Fully autonomous or human-in-the-loop – Users can optionally take control of the doctor or patient agents. Simulation assets are built using a 2D game engine (Phaser), and the agents can navigate, converse, and interact with virtual medical tools. ● Big performance boost across benchmarks – On NEJM, MedQA, and MIMIC-IV, MedAgentSim (with LLaMA 3.3) outperforms baseline setups by +6–37%, especially in vision-language tasks using LLaVA for interpreting medical images. ● Bias analysis & fairness focus – The team studied diagnostic accuracy under cognitive and implicit bias conditions. Models like GPT-4o and LLaMA proved more robust than Mixtral/Mistral, highlighting the importance of bias-aware evaluation.
Open Deep Search
Researchers from Sentient, UW, Princeton, and UC Berkeley introduce Open Deep Search (ODS), an open-source search AI framework that rivals top proprietary systems like GPT-4o Search Preview and Perplexity Sonar. Key insights: ● Two open components: search + reasoning – ODS has two modular parts: (1) Open Search Tool, which retrieves and refines high-quality web results using query rephrasing, snippet reranking, and site-specific logic; and (2) Open Reasoning Agent, a controller that orchestrates tool usage (search, calculator, etc.) to answer queries. Two variants are offered: ODS-v1 (ReAct) and ODS-v2 (CodeAct). ● SOTA open-source performance – With DeepSeek-R1 as the base LLM, ODS-v2 scores 88.3% on SimpleQA and 75.3% on FRAMES, beating GPT-4o Search Preview by +9.7% on the latter. ODS adapts the number of searches per query (avg. 3.39 on FRAMES), balancing cost and accuracy more efficiently than fixed-query baselines. ● Better than Perplexity Sonar – On both FRAMES and SimpleQA, ODS+DeepSeek-R1 outperforms Perplexity’s flagship search models, even in complex reasoning tasks involving multi-hop questions, time/date calculations, and name disambiguation. ● Code-based agents enhance reasoning – ODS-v2 builds on CodeAct, allowing it to write and run Python code to perform symbolic reasoning and tool calls. This results in sharper numerical precision and task flexibility compared to CoT-based ReAct in ODS-v1.
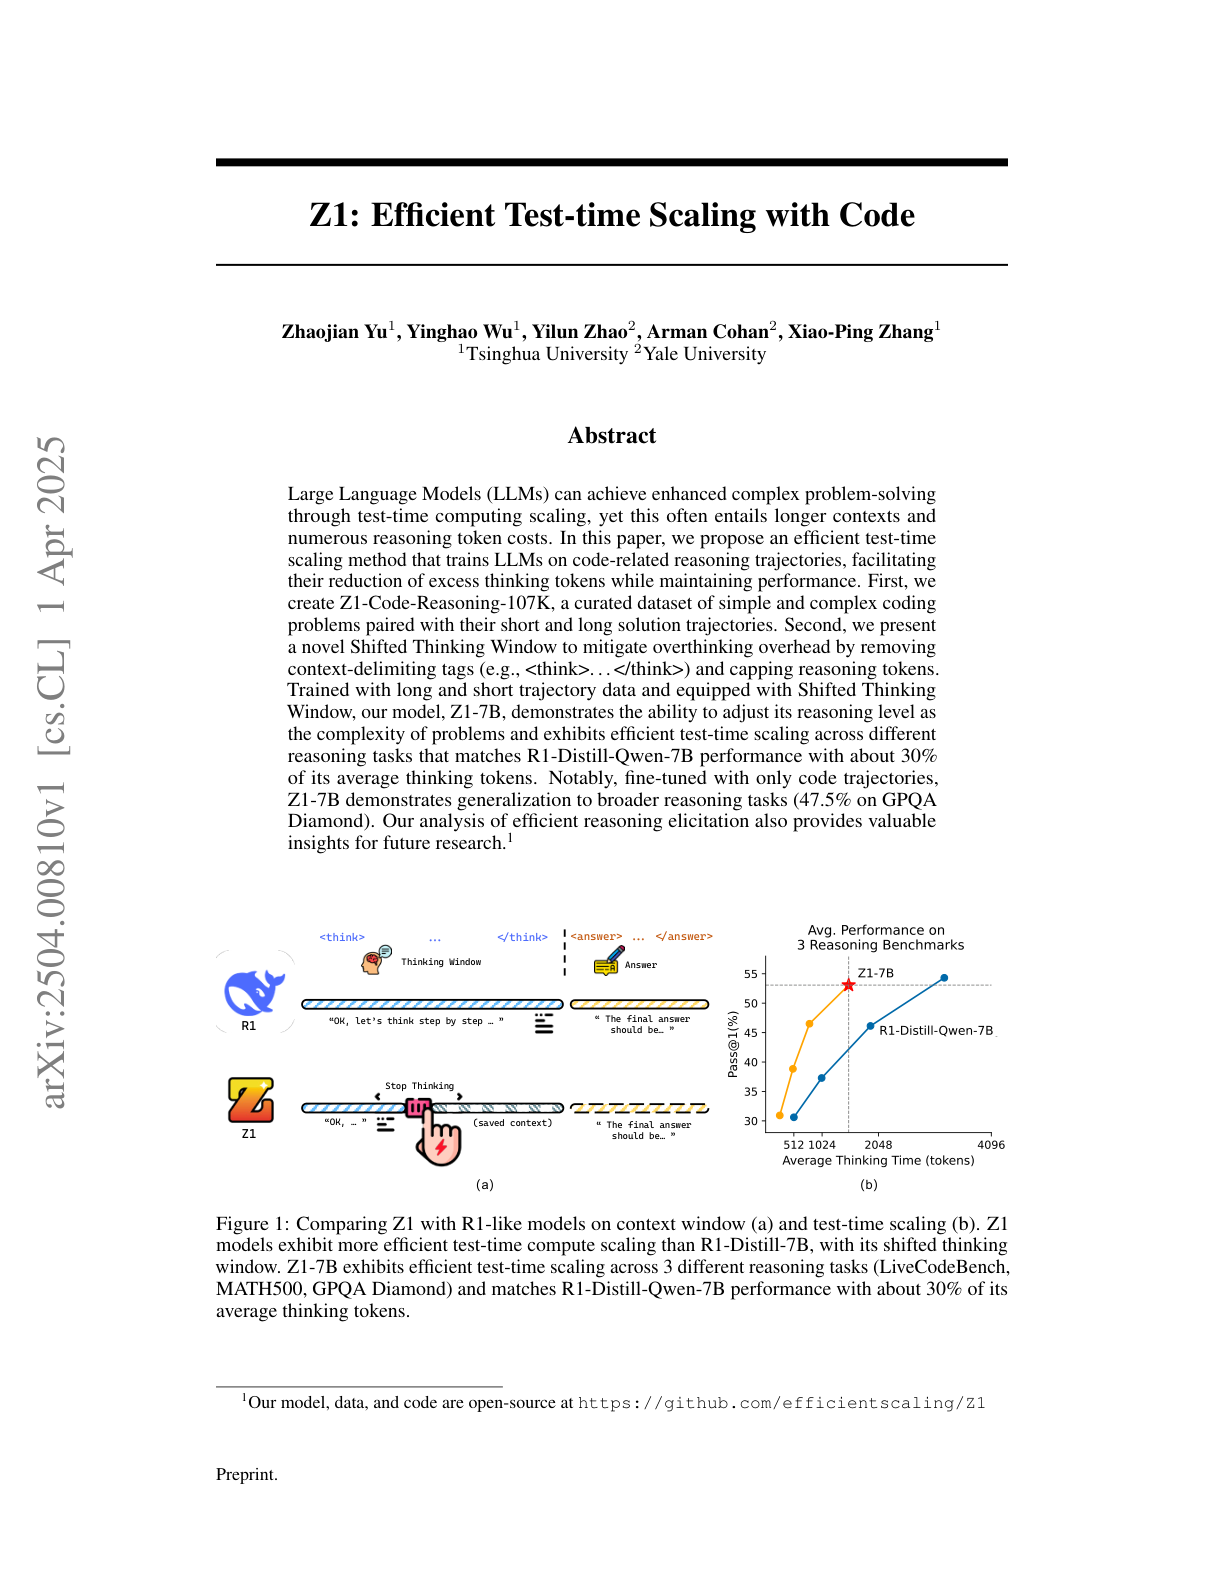
Efficient Test-time Scaling with Code
Z1 is a new method for making large language models more compute-efficient at test time, especially during reasoning. The core idea is to train LLMs with short and long code-based reasoning trajectories, and then dynamically adjust reasoning depth during inference. Key contributions: ● Z1-Code-Reasoning-107K dataset – They construct a 107K-sample dataset with short and long reasoning paths for simple and complex coding problems. Trajectories are distilled from QwQ-32B and paired to help the model learn when to stop thinking. ● Shifted Thinking Window – A new test-time strategy that eliminates explicit <think delimiters. Instead, the model adapts reasoning token budget based on problem difficulty. Simple problems invoke shallow reasoning; complex ones get capped (e.g., 4096 tokens max), with hints nudging the model to finalize the answer. ● Big efficiency gains – The 7B-scale model Z1-7B matches R1-Distill-Qwen-7B across multiple reasoning tasks (MATH500, LiveCodeBench, GPQA Diamond) but with ~30% of the reasoning tokens. For instance, on GPQA Diamond, Z1-7B achieves 47.5% while using less than half the tokens. ● Code reasoning transfers to general tasks – Despite being trained only on code-based CoT data, Z1 generalizes well to broader domains like science and math, outperforming other 7B reasoning models (e.g., OpenThinker-7B, s1.1-7B) across multiple benchmarks. ● What makes reasoning data effective? – Ablation studies reveal two key dataset design levers: (1) longer reasoning trajectories improve inference quality; (2) larger training sample sizes boost average thinking time and accuracy, even without altering trajectory length.
A Survey of Efficient Reasoning for LLMs
This survey focuses on reasoning economy in LLMs, analyzing how to balance deep reasoning performance with computational cost. It reviews inefficiencies, behavioral patterns, and potential solutions at both post-training and inference stages.