AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
MedBrowseComp
MedBrowseComp is a new benchmark designed to evaluate LLM agents’ ability to perform complex, multi-hop medical fact-finding by browsing real-world, domain-specific web resources. Testing over 1,000 clinically grounded questions, the benchmark reveals major capability gaps in current models, with top systems achieving only 50% accuracy and GUI-based agents performing even worse.
ARC-AGI-2
ARC-AGI-2 is a new benchmark designed to push the boundaries of AI reasoning beyond the original ARC-AGI. It introduces harder, more unique tasks emphasizing compositional generalization and human-like fluid intelligence, with baseline AI models performing below 5% accuracy despite strong ARC-AGI-1 results.
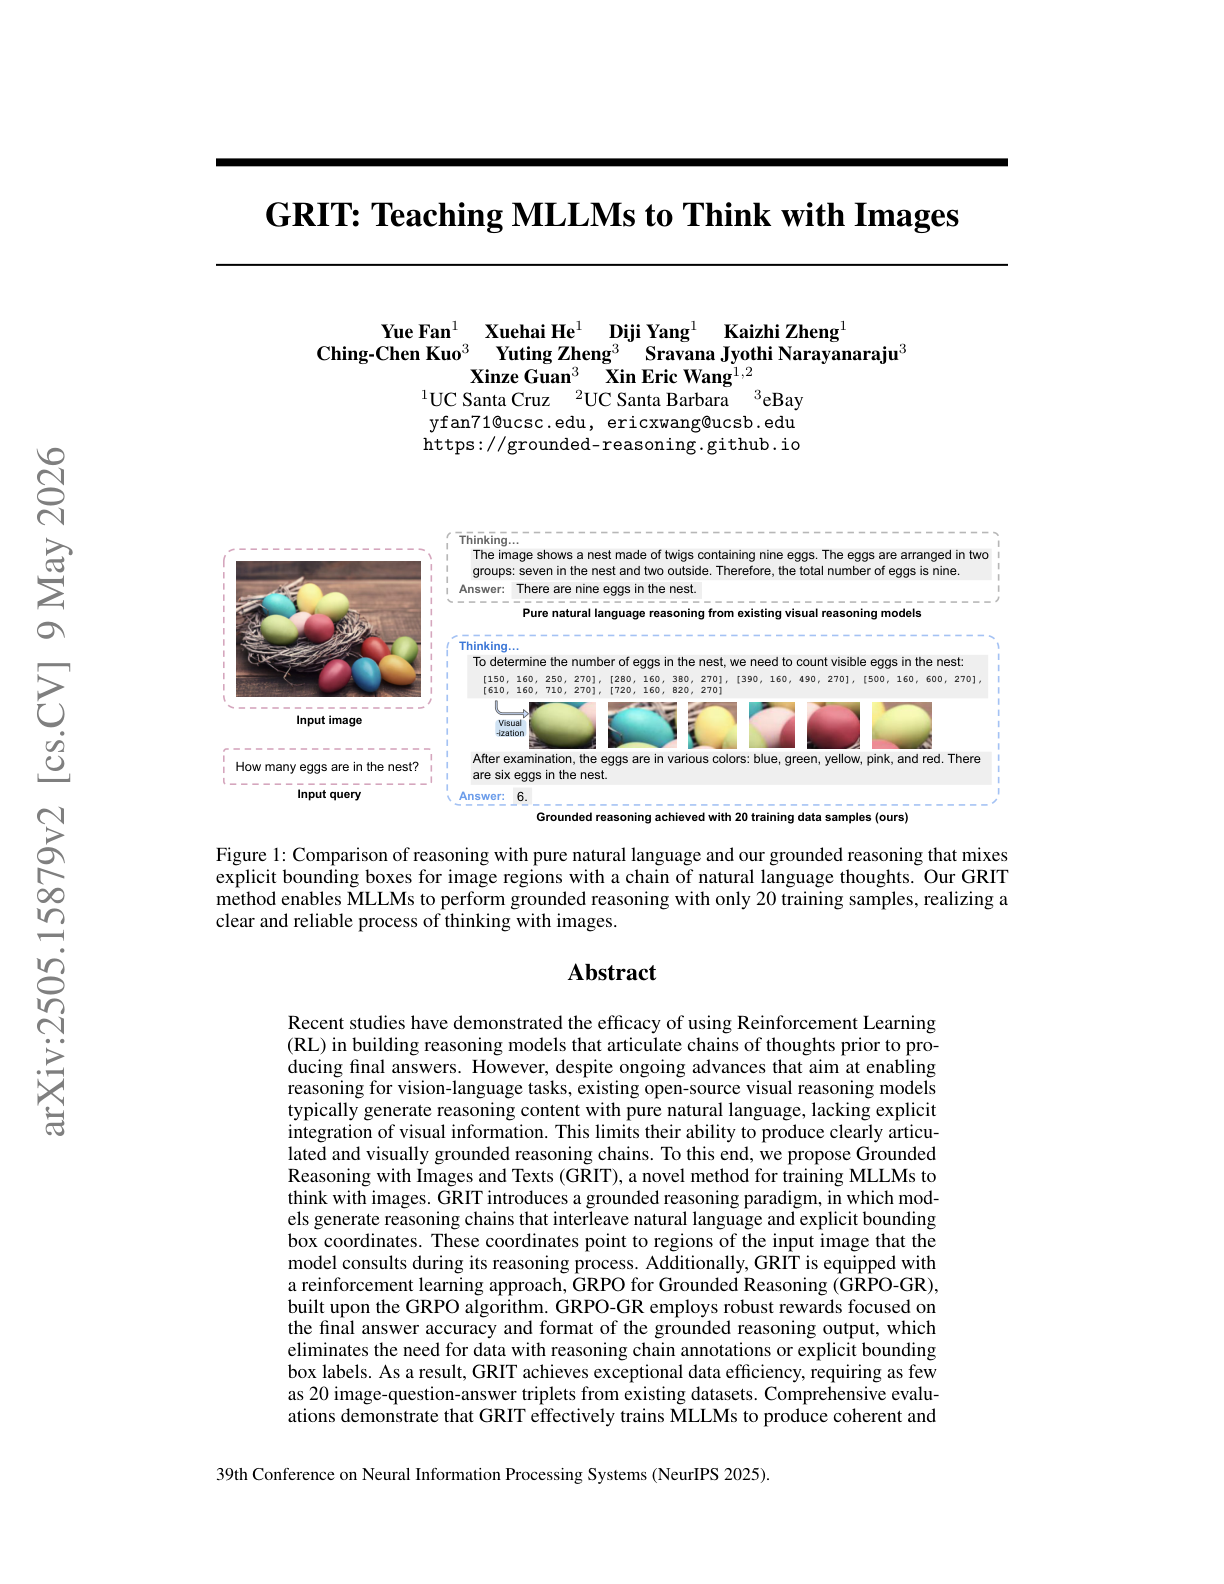
Teaching MLLMs to Think with Images
GRIT is a new method that enables MLLMs to perform grounded visual reasoning by interleaving natural language with bounding box references. Using a reinforcement learning approach (GRPO-GR), GRIT achieves strong reasoning and grounding performance with as few as 20 image-question-answer triplets, outperforming baselines in both accuracy and visual coherence.
AlphaEvolve
AlphaEvolve is a coding agent developed by Google DeepMind that uses LLM-guided evolution to discover new algorithms and optimize computational systems. It orchestrates a pipeline where LLMs generate code changes, evaluators provide feedback, and an evolutionary loop iteratively improves solutions. AlphaEvolve shows that LLMs can go beyond conventional code generation and assist in scientific and algorithmic discovery. Key highlights:
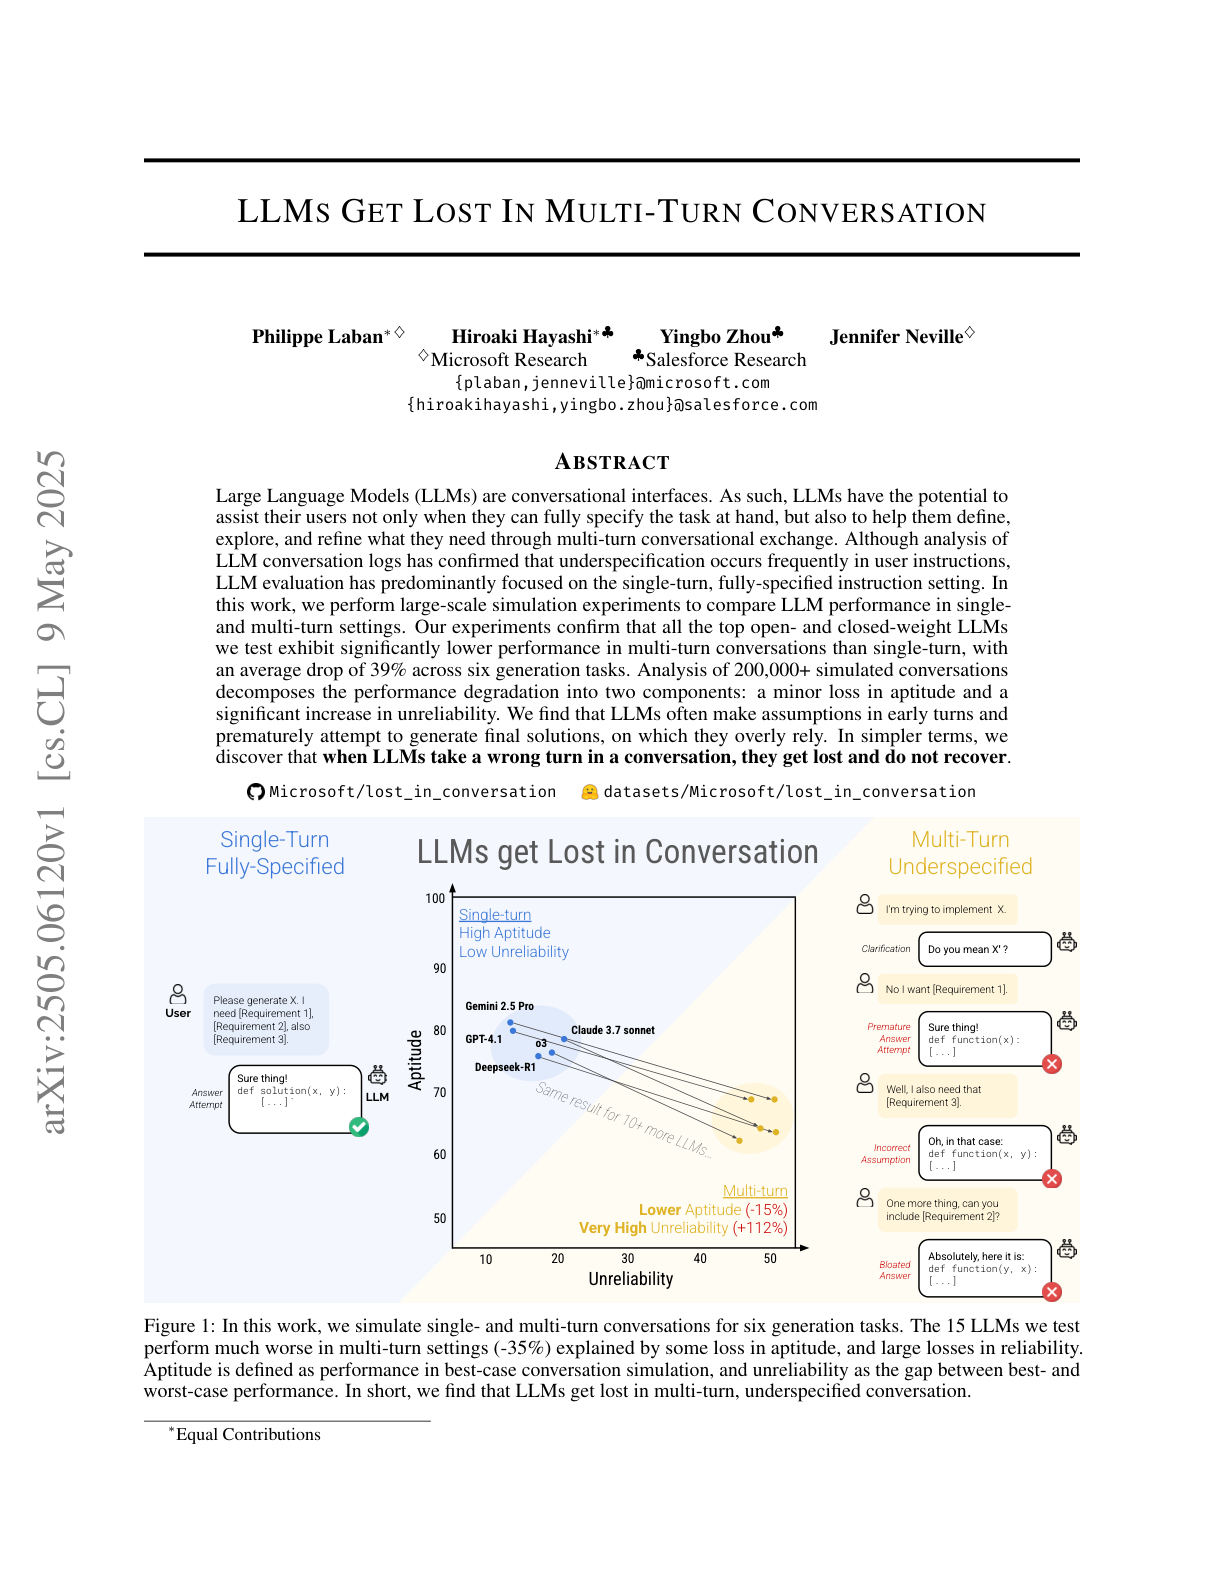
LLMs Get Lost in Multi-Turn Conversation
Investigates how top LLMs degrade in performance during underspecified, multi-turn interactions, common in real-world usage but rarely evaluated. The authors introduce a novel "sharded simulation" framework that breaks down fully-specified instructions into gradual conversation shards, simulating how users naturally provide information over time. Key findings:
RL for Reasoning in LLMs with One Training Example
This paper shows that Reinforcement Learning with Verifiable Rewards (RLVR) can significantly improve mathematical reasoning in LLMs even when trained with just a single example. On the Qwen2.5-Math-1.5B model, one-shot RLVR improves accuracy on the MATH500 benchmark from 36.0% to 73.6%, nearly matching performance achieved with over 1,200 examples. Two-shot RLVR (with two examples) even slightly surpasses that, matching results from full 7.5k example training.
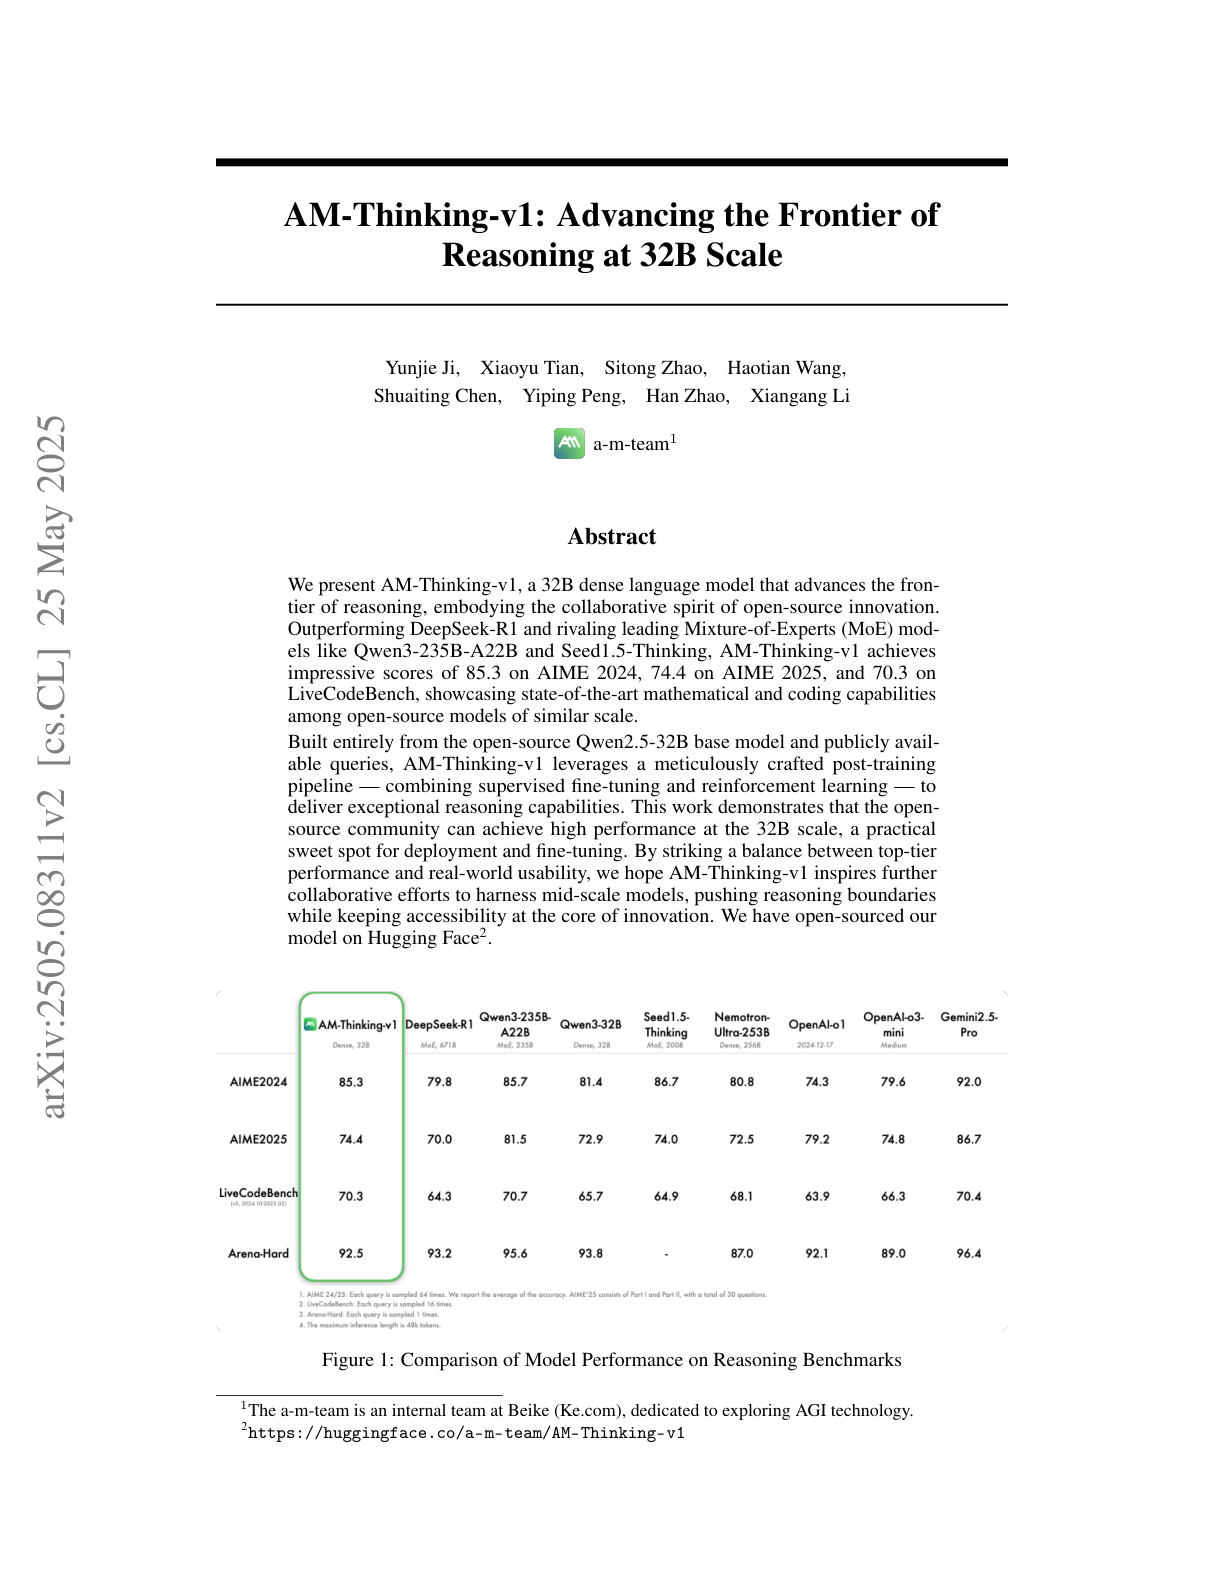
AM-Thinking-v1
Introduces a dense, open-source 32B language model that achieves state-of-the-art performance in reasoning tasks, rivaling significantly larger Mixture-of-Experts (MoE) models. Built upon Qwen2.5-32B, the model is trained entirely with public data and showcases how a meticulously crafted post-training pipeline can unlock competitive performance at mid-scale sizes. Key points:
HealthBench
HealthBench is a benchmark of 5,000 multi-turn health conversations graded against 48,562 rubric criteria written by 262 physicians across 60 countries. Unlike prior multiple-choice evaluations, HealthBench supports open-ended, realistic assessments of LLM responses across diverse health themes (e.g., global health, emergency care, context-seeking) and behavioral axes (accuracy, completeness, communication, context awareness, instruction following).
Nemotron-Research-Tool-N1
Introduces Tool-N1, a family of tool-using LLMs trained using a rule-based reinforcement learning (R1-style RL) approach, without reliance on supervised reasoning trajectories. The key idea is to enable models to learn to invoke external tools correctly through binary feedback based on functional correctness and format adherence, rather than step-by-step imitation.
RL for Search-Efficient LLMs
Proposes a new RL-based framework (SEM) that explicitly teaches LLMs when to invoke search and when to rely on internal knowledge, aiming to reduce redundant tool use while maintaining answer accuracy. Key points:
Cost-Efficient, Low-Latency Vector Search
Integrates DiskANN (a vector indexing library) inside of Azure Cosmos DB NoSQL (an operational dataset) that uses a single vector index per partition stored in existing index trees. Benefit: It supports < 20ms query latency over an index spanning 10 million vectors, has stable recall over updates, and offers nearly 15× and 41× lower query cost compared to Zilliz and Pinecone serverless enterprise products. It can further scale to billions of vectors with automatic partitioning.
AI Agents vs. Agentic AI
This review paper distinguishes AI Agents from Agentic AI, presenting a structured taxonomy and comparing their architectures, capabilities, and challenges. AI Agents are defined as modular, task-specific systems powered by LLMs and tools, while Agentic AI represents a shift toward multi-agent collaboration, dynamic task decomposition, and orchestrated autonomy, with applications and challenges mapped out for both paradigms, along with proposed solutions like RAG, orchestration layers, and causal modeling.
CellVerse
Introduces a benchmark to evaluate LLMs on single-cell biology tasks by converting multi-omics data into natural language. While generalist LLMs like DeepSeek and GPT-4 families show some reasoning ability, none significantly outperform random guessing on key tasks like drug response prediction, exposing major gaps in biological understanding by current LLMs.
The Leaderboard Illusion
The Leaderboard Illusion investigates systemic distortions in how the Chatbot Arena leaderboard evaluates LLMs, arguing that current practices undermine fair model comparison and scientific progress. Through extensive data analysis covering 2M Arena battles, the authors identify four key issues distorting rankings:
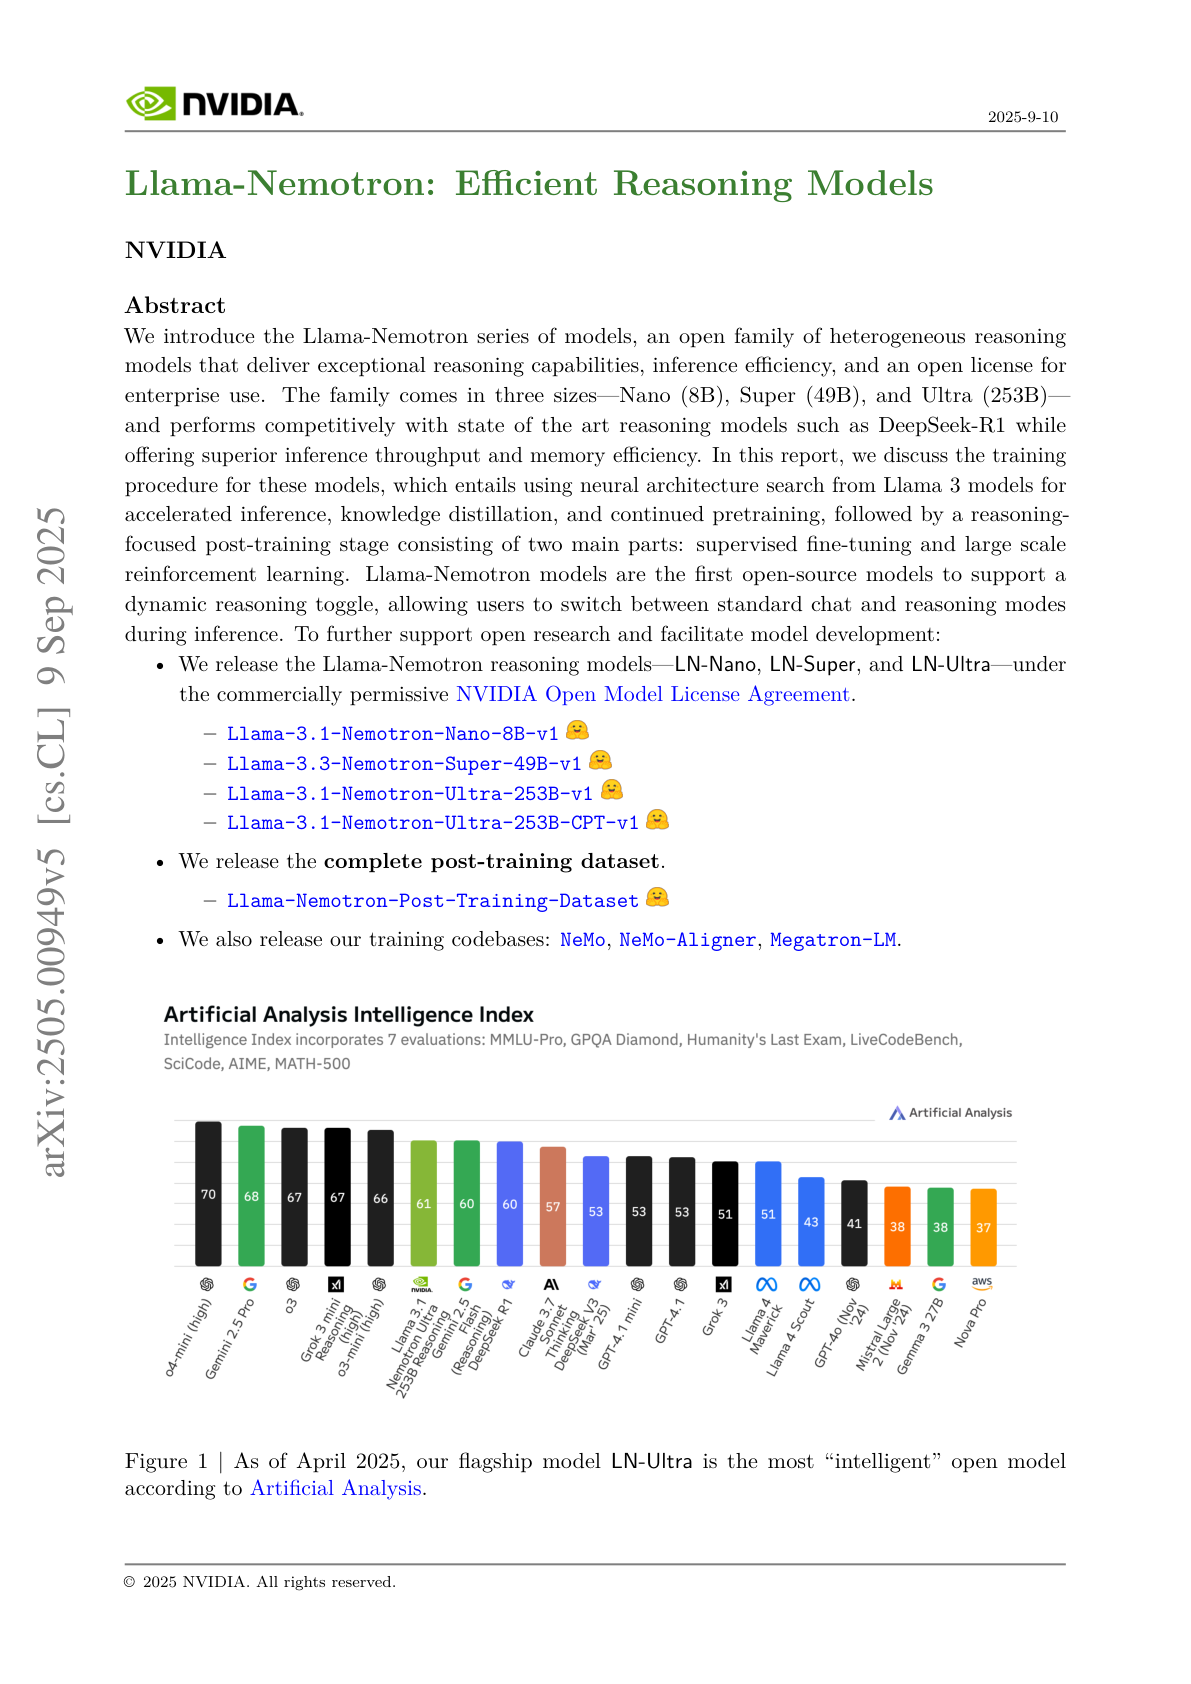
Llama-Nemotron
NVIDIA introduces the Llama-Nemotron model series, LN-Nano (8B), LN-Super (49B), and LN-Ultra (253B), a family of open, efficient, and high-performing reasoning models. These models rival or outperform DeepSeek-R1 on various benchmarks while offering significantly better inference throughput and memory efficiency. LN-Ultra is noted as the most "intelligent" open model by Artificial Analysis. A key innovation is a dynamic reasoning toggle ("detailed thinking on/off") that allows users to control reasoning behavior at inference time. Highlights:
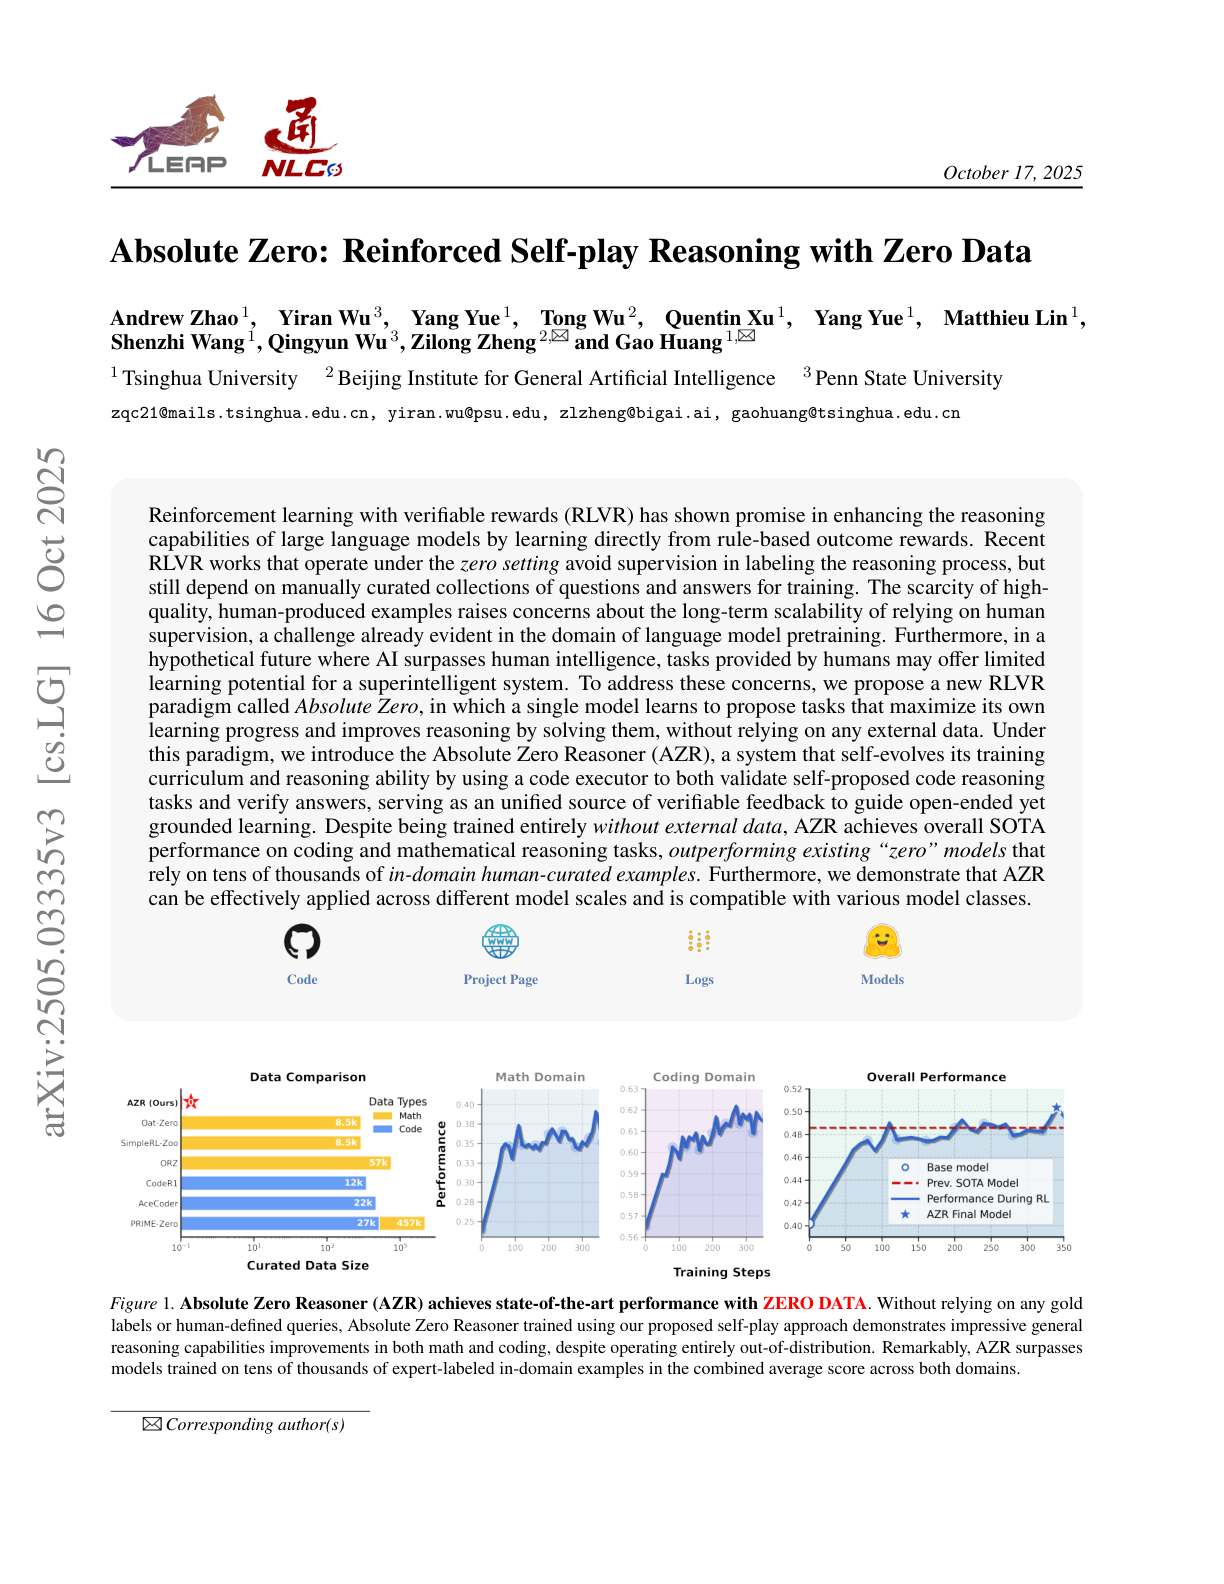
Absolute Zero
Introduces an LLM training framework that eliminates the need for human-curated data. Key highlights:
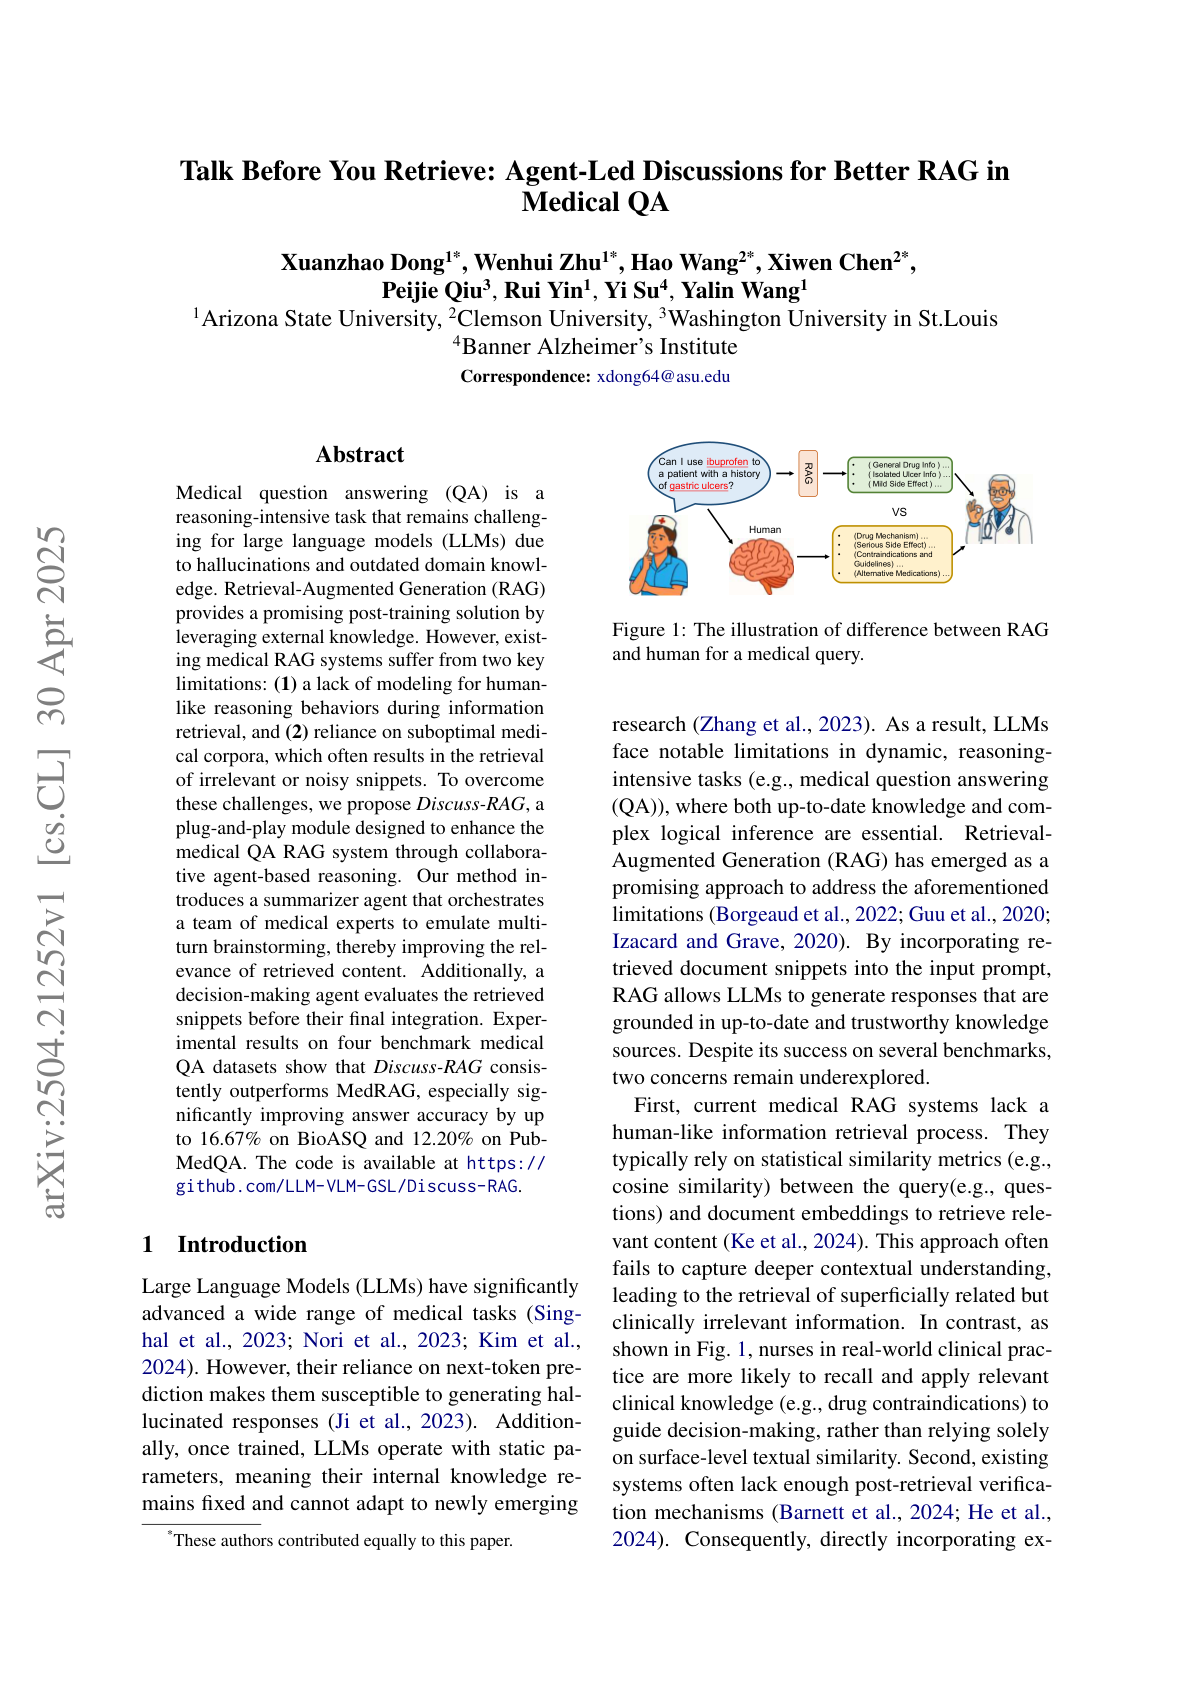
Discuss-RAG
This paper introduces Discuss-RAG, a plug-and-play agent-based framework that enhances retrieval-augmented generation (RAG) for medical question answering by mimicking human-like clinical reasoning. Standard RAG systems rely on embedding-based retrieval and lack mechanisms to verify relevance or logical coherence, often leading to hallucinations or outdated answers. Discuss-RAG addresses these gaps via a modular agent setup that simulates multi-turn medical discussions and performs post-retrieval verification. Key ideas:
The Value of RL in Fine-Tuning
This work shows that, in theory, every popular preference-fine-tuning objective collapses to maximum-likelihood estimation (MLE), yet experiments show a consistent RL advantage on real tasks. They reconcile this gap with a generation-verification complexity hypothesis.
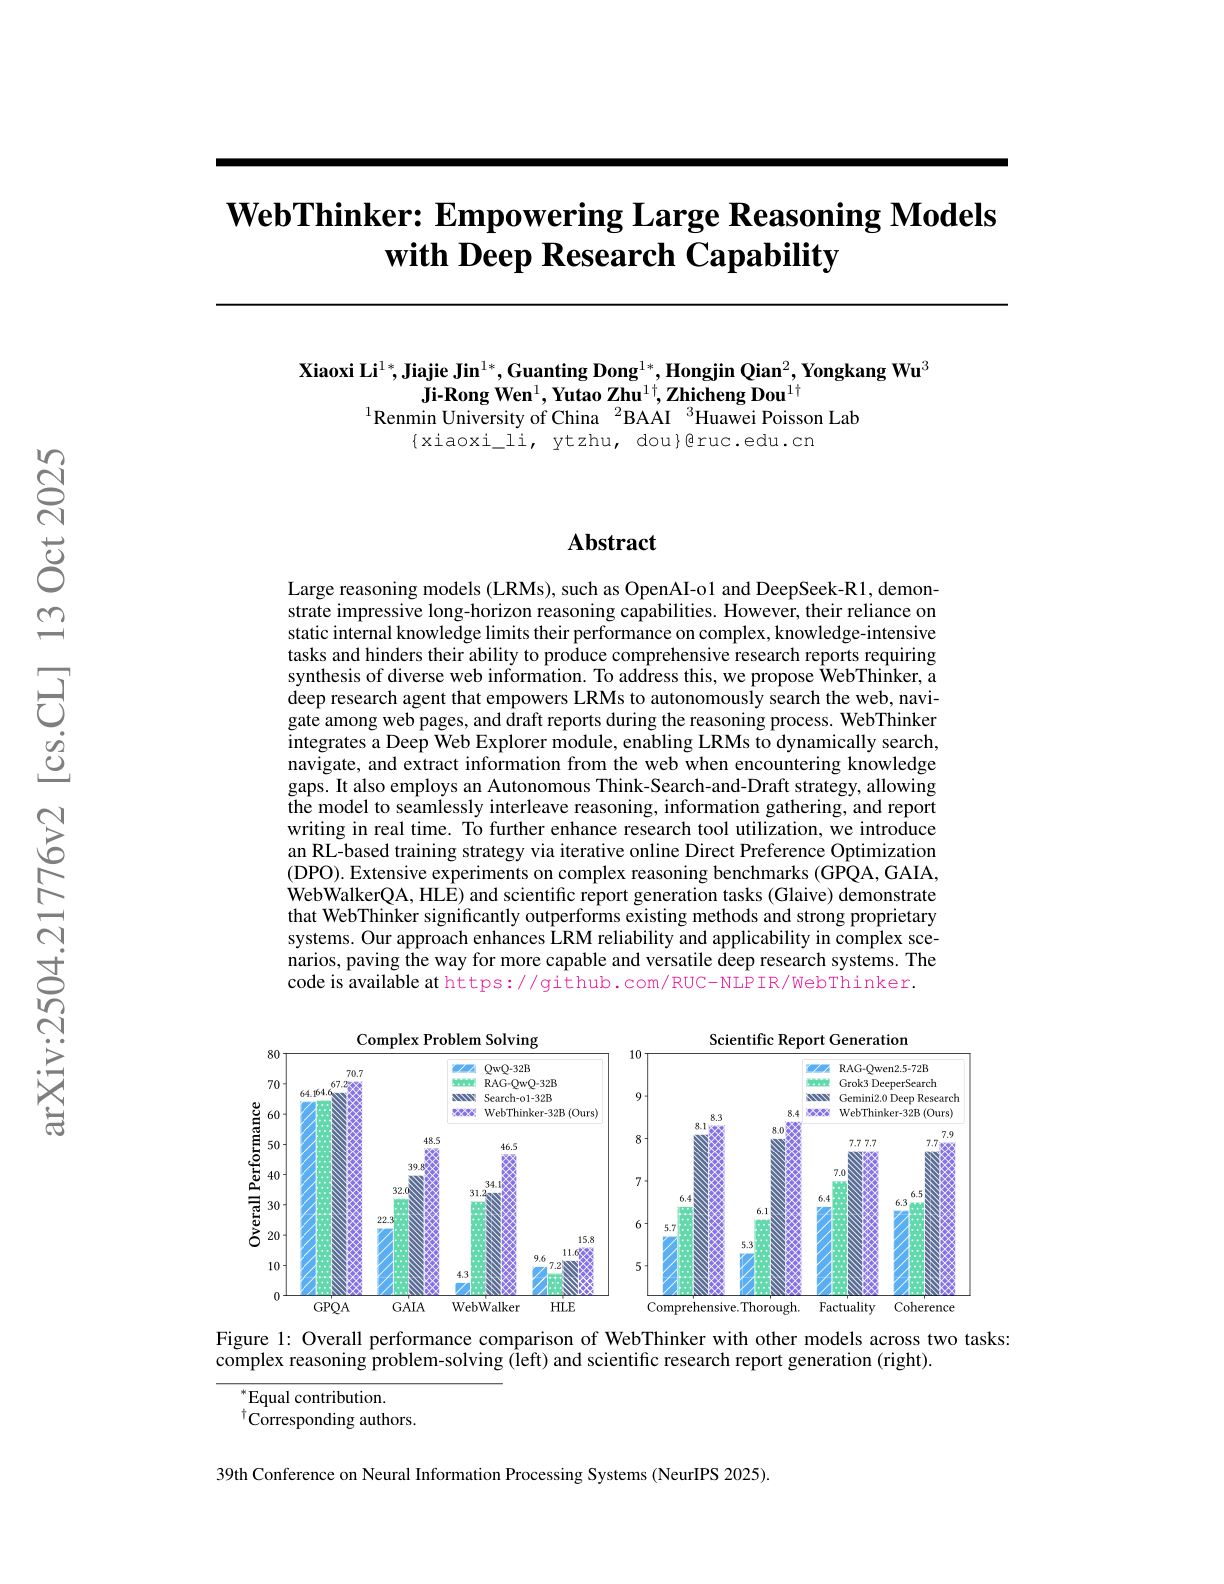
WebThinker
This paper introduces a reasoning agent framework that equips large reasoning models (LRMs) with autonomous web exploration and report writing abilities to overcome limitations of static internal knowledge. WebThinker integrates a Deep Web Explorer module and an Autonomous Think-Search-and-Draft strategy that lets models search the web, reason through tasks, and generate comprehensive outputs simultaneously. It also incorporates an RL-based training loop using online DPO to improve tool usage. The system supports two modes: complex problem solving and scientific report generation. Key points:
Reward Modeling as Reasoning
This work proposes a new class of reward models, called ReasRMs, that reformulate reward modeling as a reasoning task. The authors introduce RM-R1, a family of generative reward models that produce interpretable reasoning traces and rubrics during preference judgments. Instead of relying on scalar scores or shallow generation, RM-R1 models leverage structured reasoning and reinforcement learning to improve both interpretability and performance across benchmarks.
Paper2Code
Introduces PaperCoder, a multi-agent LLM framework that transforms ML papers into full code repositories without relying on pre-existing implementations.
ZeroSearch
ZeroSearch is an RL framework that trains LLMs to develop search capabilities without using real search engines. It uses simulated LLM-generated documents with a curriculum-based degradation strategy and outperforms real-search methods like Search-R1 in both performance and cost, achieving better QA accuracy across multiple benchmarks.
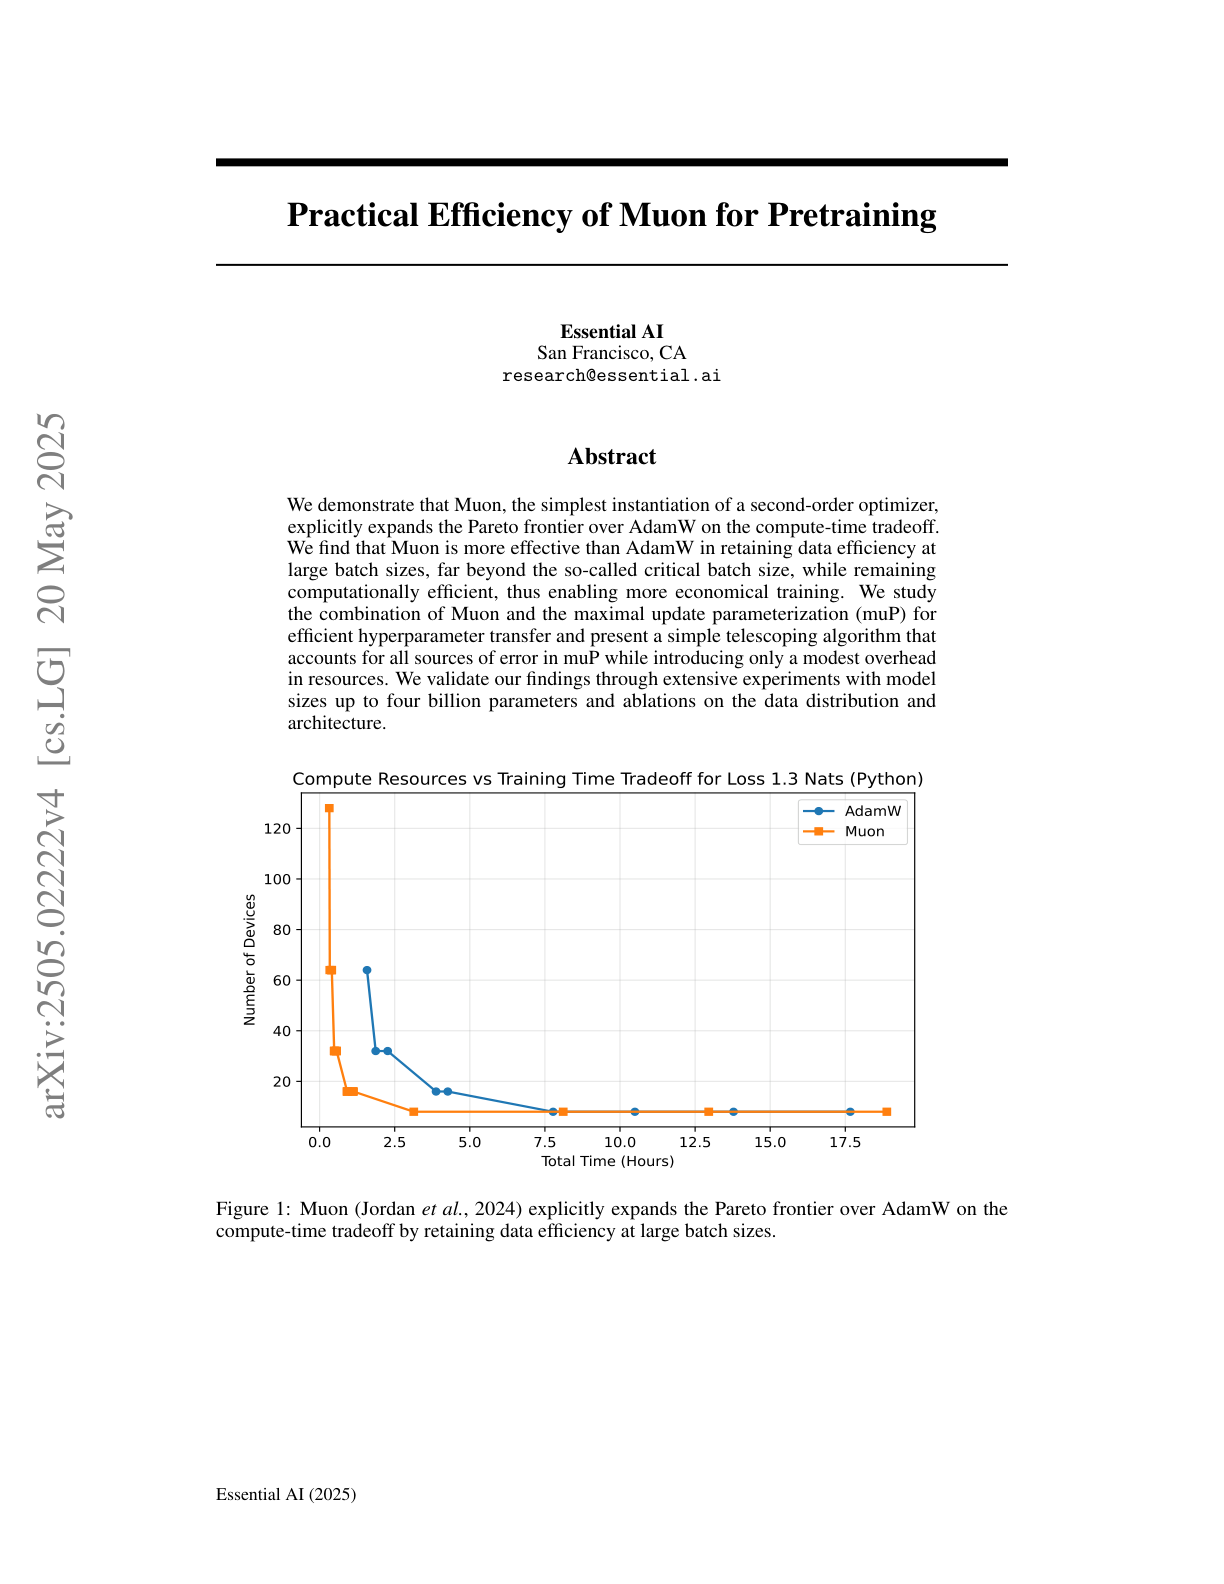
Practical Efficiency of Muon for Pretraining
Discusses how Muon, a simple second-order optimizer, outperforms AdamW in large-batch pretraining by expanding the compute-time Pareto frontier and maintaining better data efficiency. Combined with muP scaling and a novel telescoping algorithm for hyperparameter transfer, it enables faster training with minimal tuning overhead up to 4B parameter models.
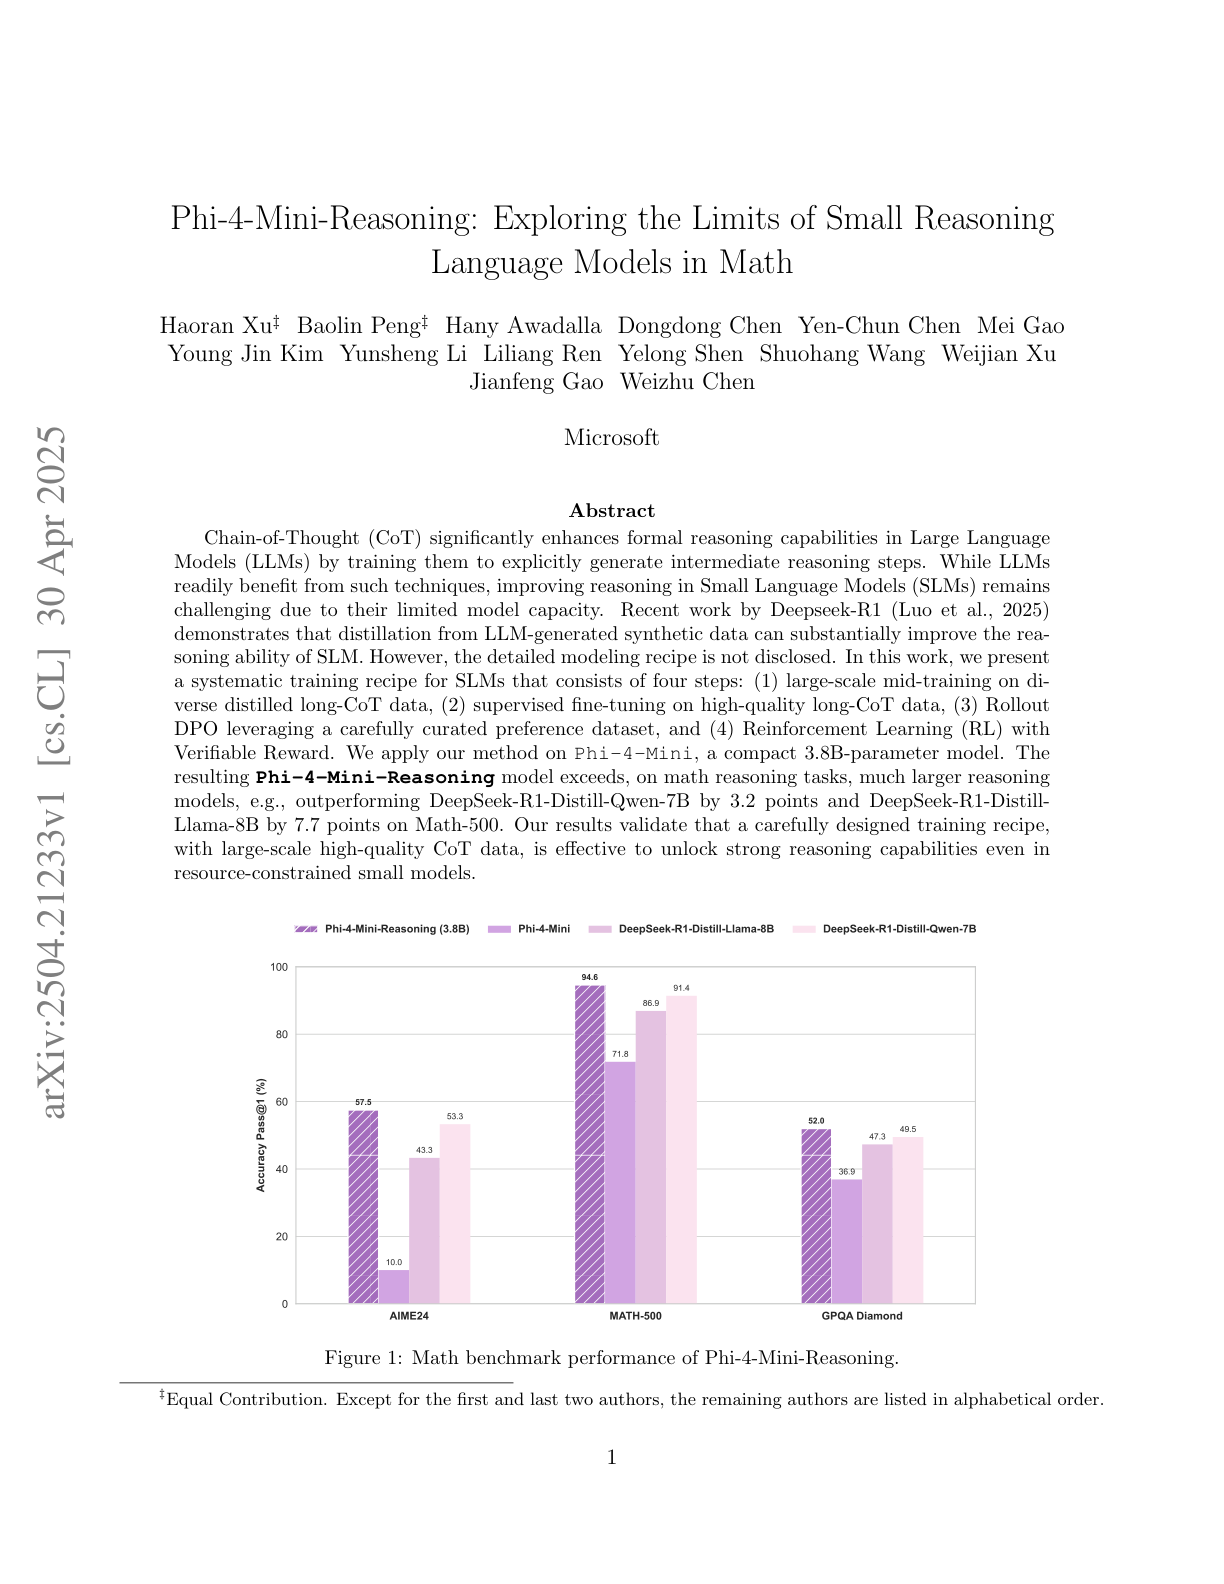
Phi-4-Mini-Reasoning
Microsoft released Phi-4-Mini-Reasoning to explore small reasoning language models for math. Highlights: