AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
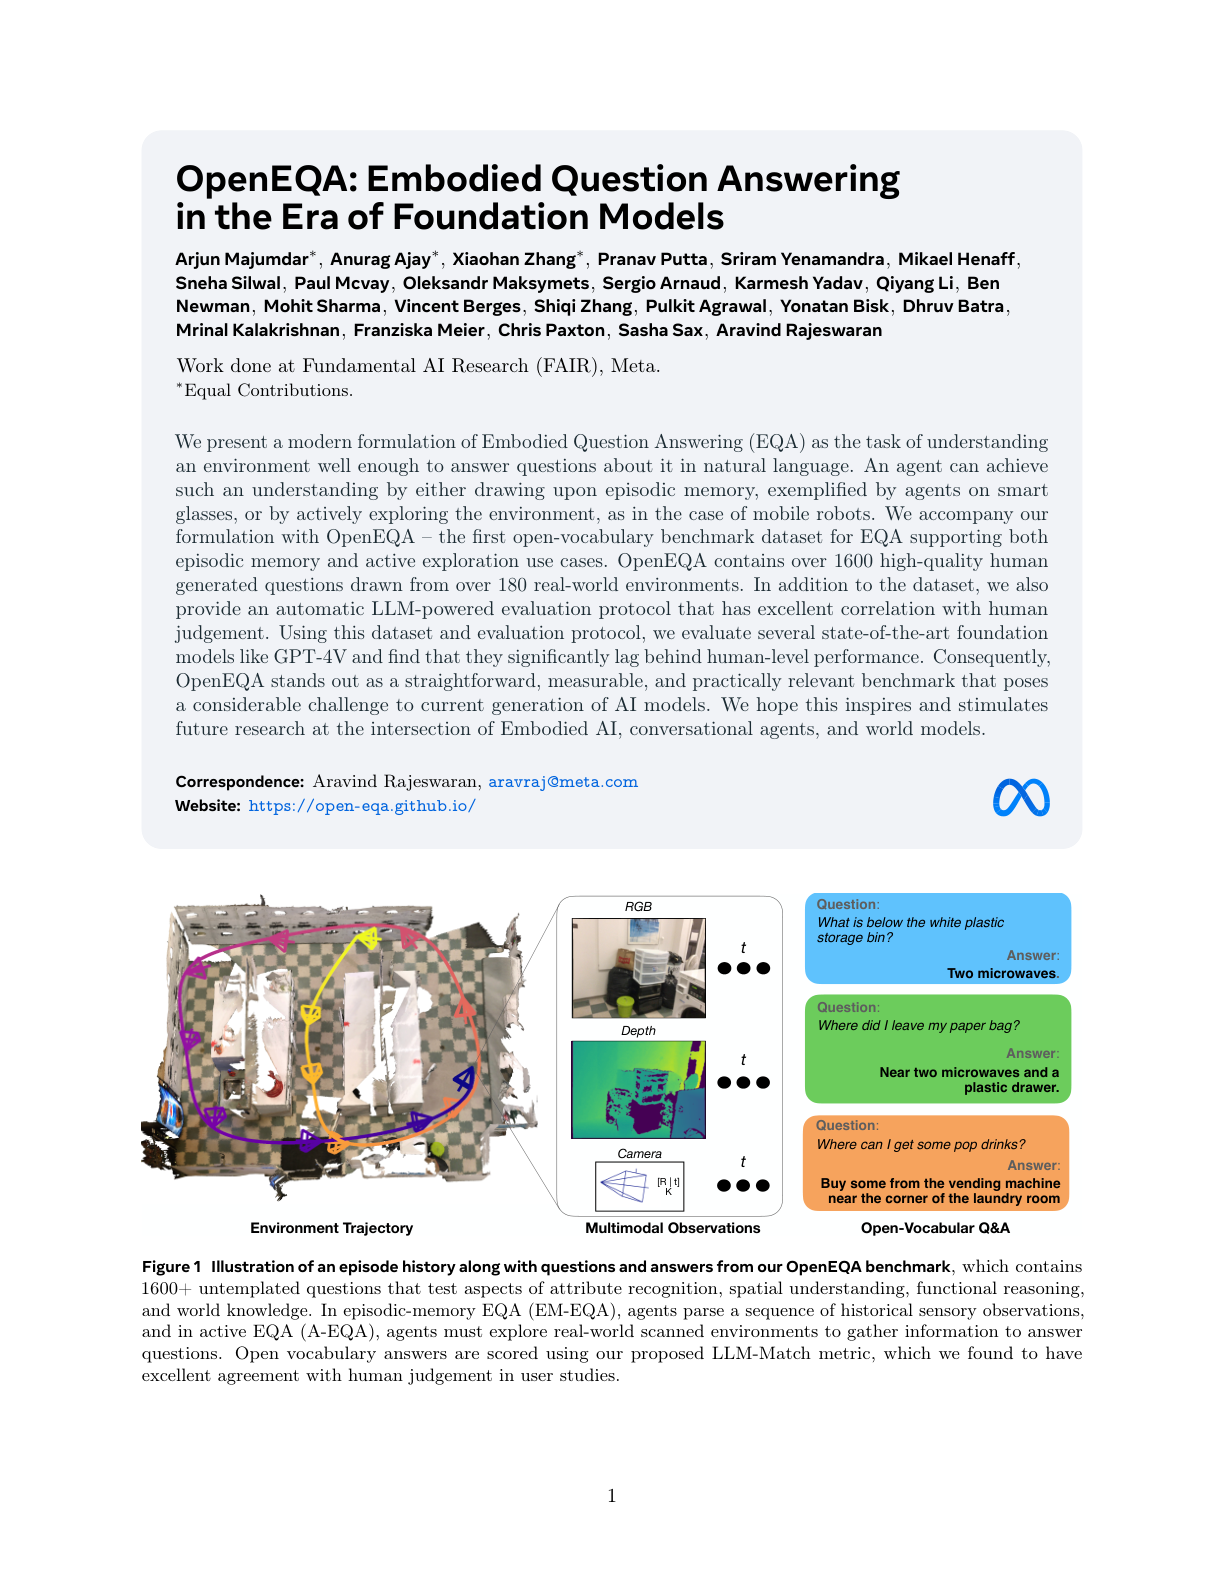
OpenEQA
Meta's OpenEQA is an open-vocabulary benchmark for embodied question answering: 1,600+ human-written questions across 180+ real-world environments, with a calibrated LLM-as-judge metric that tracks human agreement closely.
CodeGemma
CodeGemma is a family of open code LLMs built on Gemma, released in 2B (pretrained), 7B (pretrained), and 7B-IT (instruction-tuned) variants. The 2B model is optimized for low-latency code completion, and the 7B-IT model leads its weight class on HumanEval.
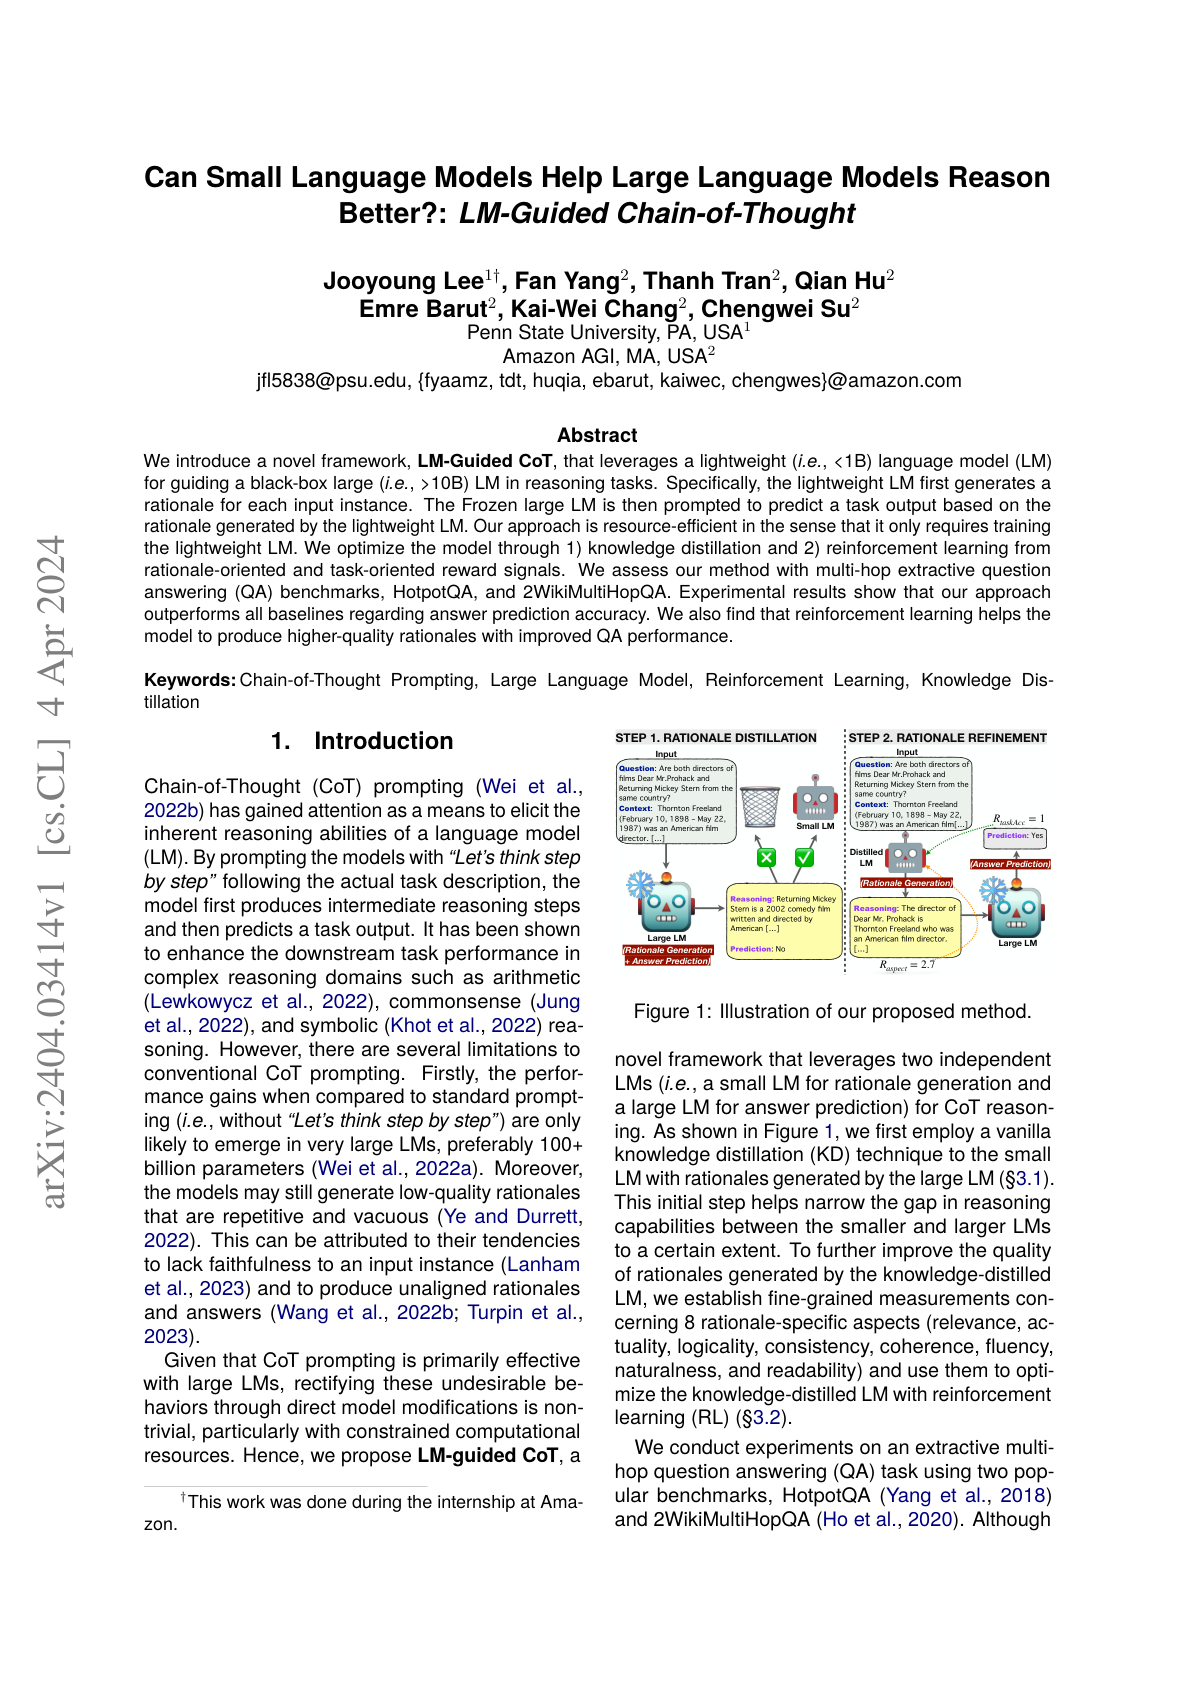
LM-Guided Chain-of-Thought
This paper offloads rationale generation to a small, trained LM while keeping a frozen large LM as the answer predictor. The small model is optimized with knowledge distillation and reinforcement learning so it produces rationales that steer the large model more effectively.
Best Practices and Lessons on Synthetic Data
Google DeepMind's survey-style position paper on synthetic data for LLMs. It covers applications, quality-assurance principles, and the open challenges of factuality, fidelity, bias, and privacy.
Reasoning with Intermediate Revision and Search (THOUGHTSCULPT)
THOUGHTSCULPT is a graph-based reasoning framework that combines Monte Carlo Tree Search with an explicit revision action, letting an LLM iteratively rewrite earlier thoughts instead of only extending them.
Overview of Multilingual LLMs
A first-of-its-kind survey on multilingual LLMs, organized by multilingual alignment principles rather than model-family hierarchy. The authors propose a unified taxonomy and collect open resources to accelerate future research.
The Physics of Language Models
This paper measures how many bits of factual knowledge a language model can store per parameter and finds a remarkably stable 2-bits-per-parameter ceiling, even after int8 quantization. A 7B model can therefore hold ~14B bits - more than the English Wikipedia and textbooks combined.
Aligning LLMs to Quote from Pre-Training Data (Quote-Tuning)
Quote-Tuning aligns LLMs to quote verbatim from trusted pre-training sources, turning the attribution step from post-hoc fact-checking into a built-in model behavior.
The Influence Between NLP and Other Fields
This EMNLP 2023 analysis quantifies NLP's cross-disciplinary engagement using a Citation Field Diversity Index across 23 academic fields. The headline: NLP has become dramatically more insular over four decades.
Many-shot Jailbreaking
Anthropic shows that long-context windows enable a new attack where hundreds of fake user/assistant dialogues are packed into a single prompt, coaxing frontier LLMs to answer the final harmful question despite safety training.
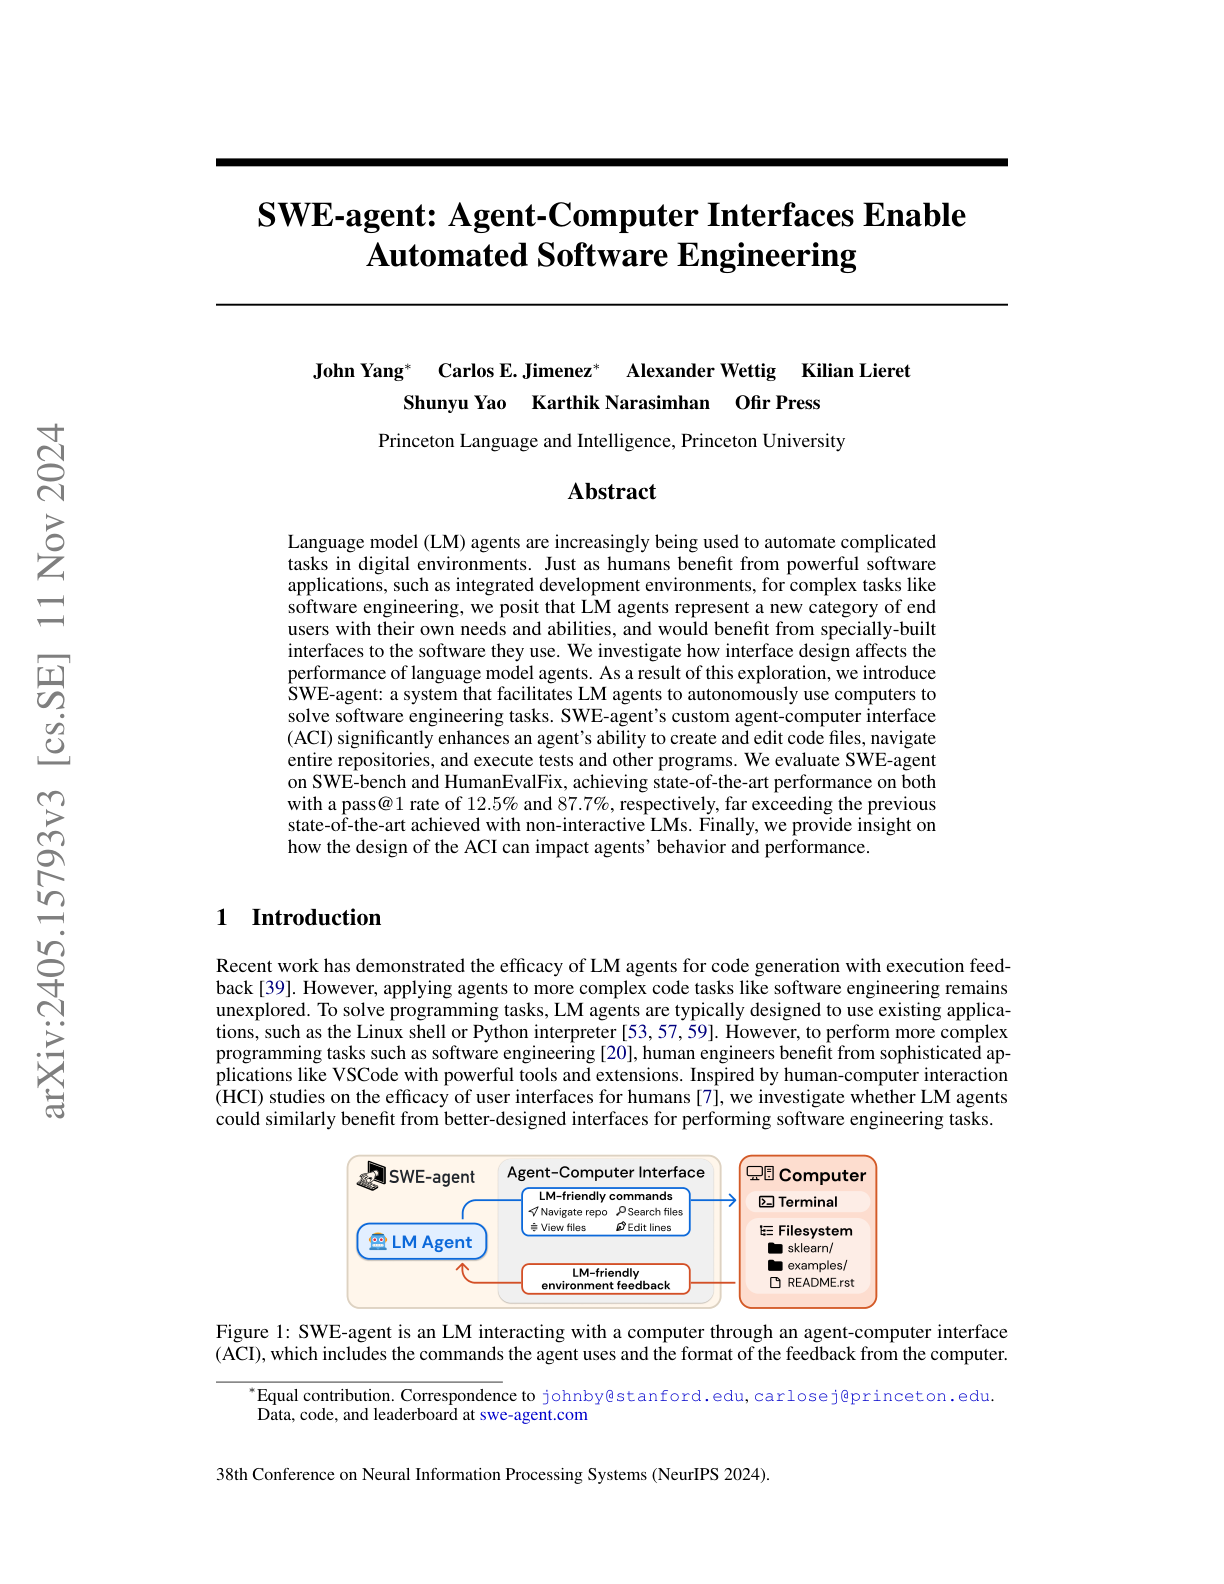
SWE-Agent
Princeton's SWE-agent pairs a language model with a custom agent-computer interface (ACI) that exposes file navigation, editing, and test execution as discrete tools, letting the agent autonomously resolve real GitHub issues.
Mixture-of-Depths
DeepMind proposes dynamically allocating transformer FLOPs across sequence positions via a top-k router, so "easy" tokens skip expensive blocks while "hard" tokens get full computation.
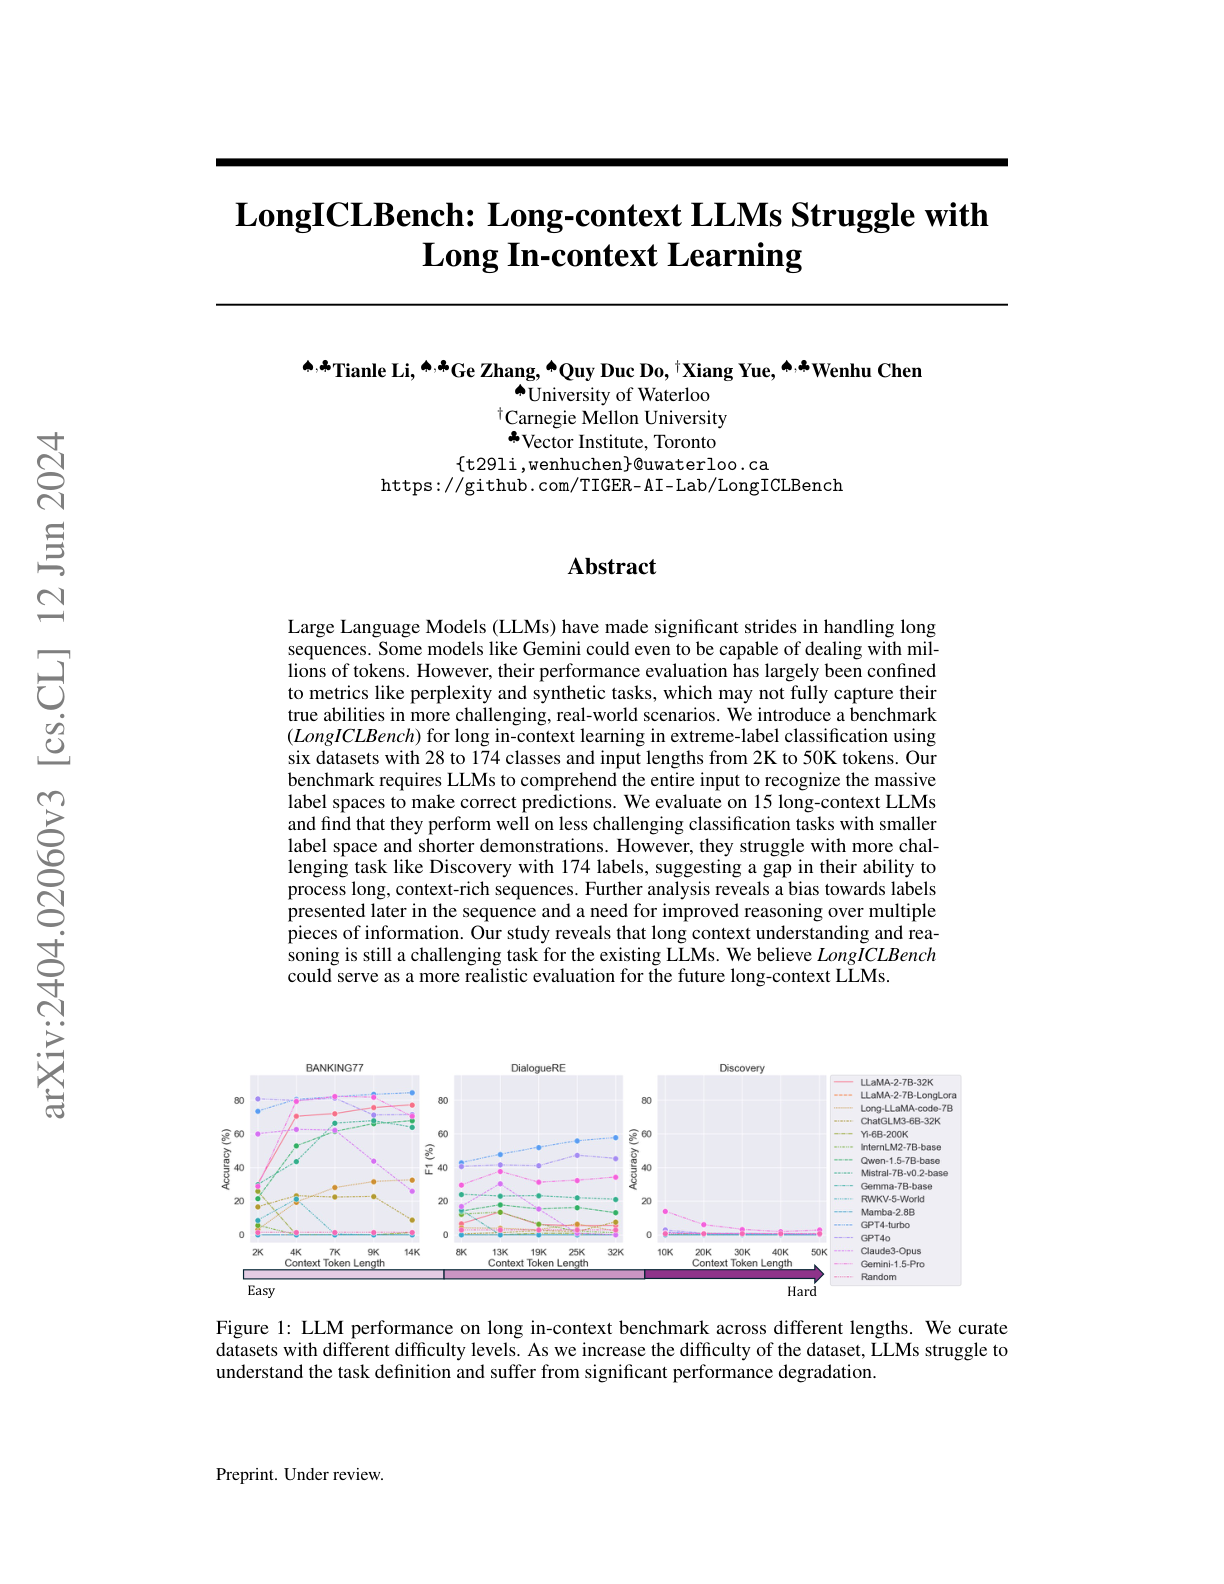
Long-context LLMs Struggle with Long In-Context Learning
LongICLBench stress-tests 13 long-context LLMs on extreme-label classification with up to 174 classes and 50K-token prompts, exposing sharp quality cliffs beyond 20K tokens.
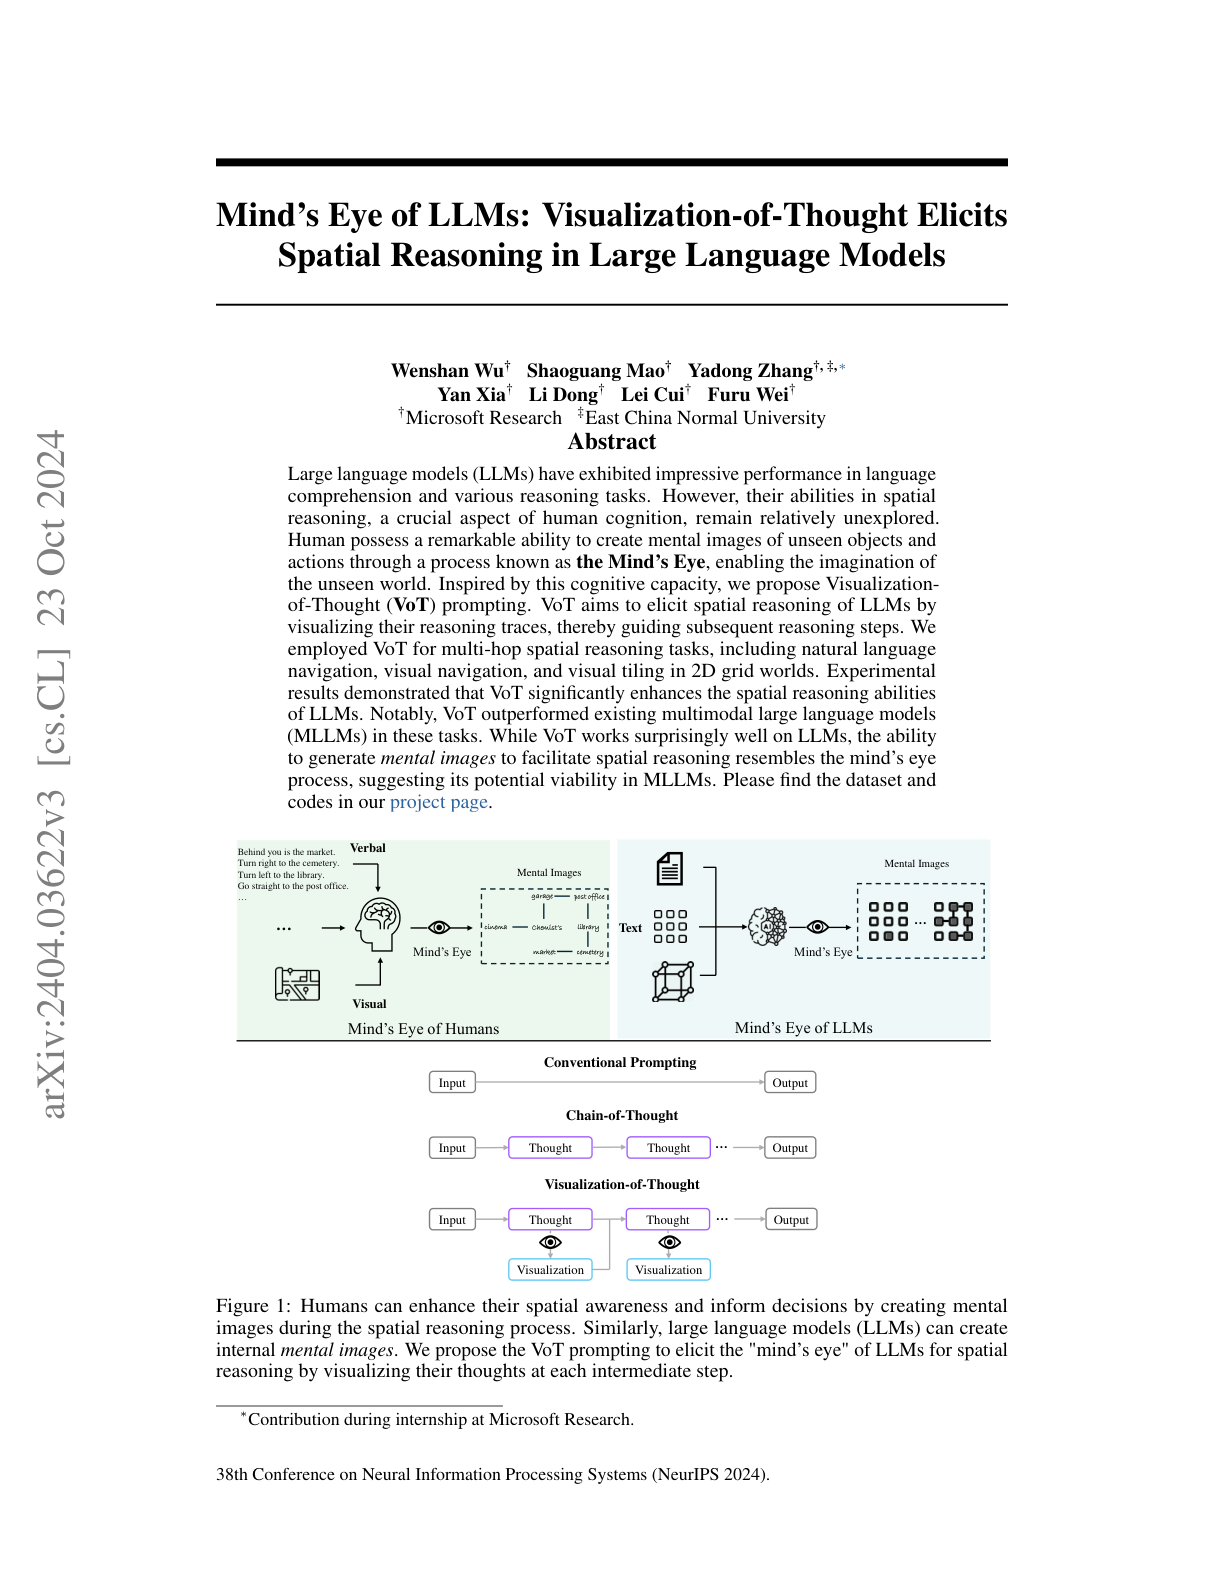
Visualization-of-Thought
Microsoft's Visualization-of-Thought (VoT) prompts LLMs to emit intermediate "mental images" of their reasoning state, lifting spatial-reasoning accuracy on grid-world tasks and beating multimodal baselines that actually see images.
The Unreasonable Ineffectiveness of the Deeper Layers
The paper shows that open-weight LLMs tolerate removing up to half of their transformer blocks with only minor degradation, provided a short QLoRA pass is used to heal the damage afterwards.
JetMoE
MyShell's JetMoE-8B is an open MoE model trained for under $100K that matches or beats LLaMA2-7B, showing that competitive LLM training can be achieved on modest budgets with public data.
ReFT: Representation Finetuning for LMs
Stanford's ReFT freezes the base model and instead learns small interventions on hidden representations at selected layers, offering a more parameter-efficient alternative to LoRA-style PEFT.
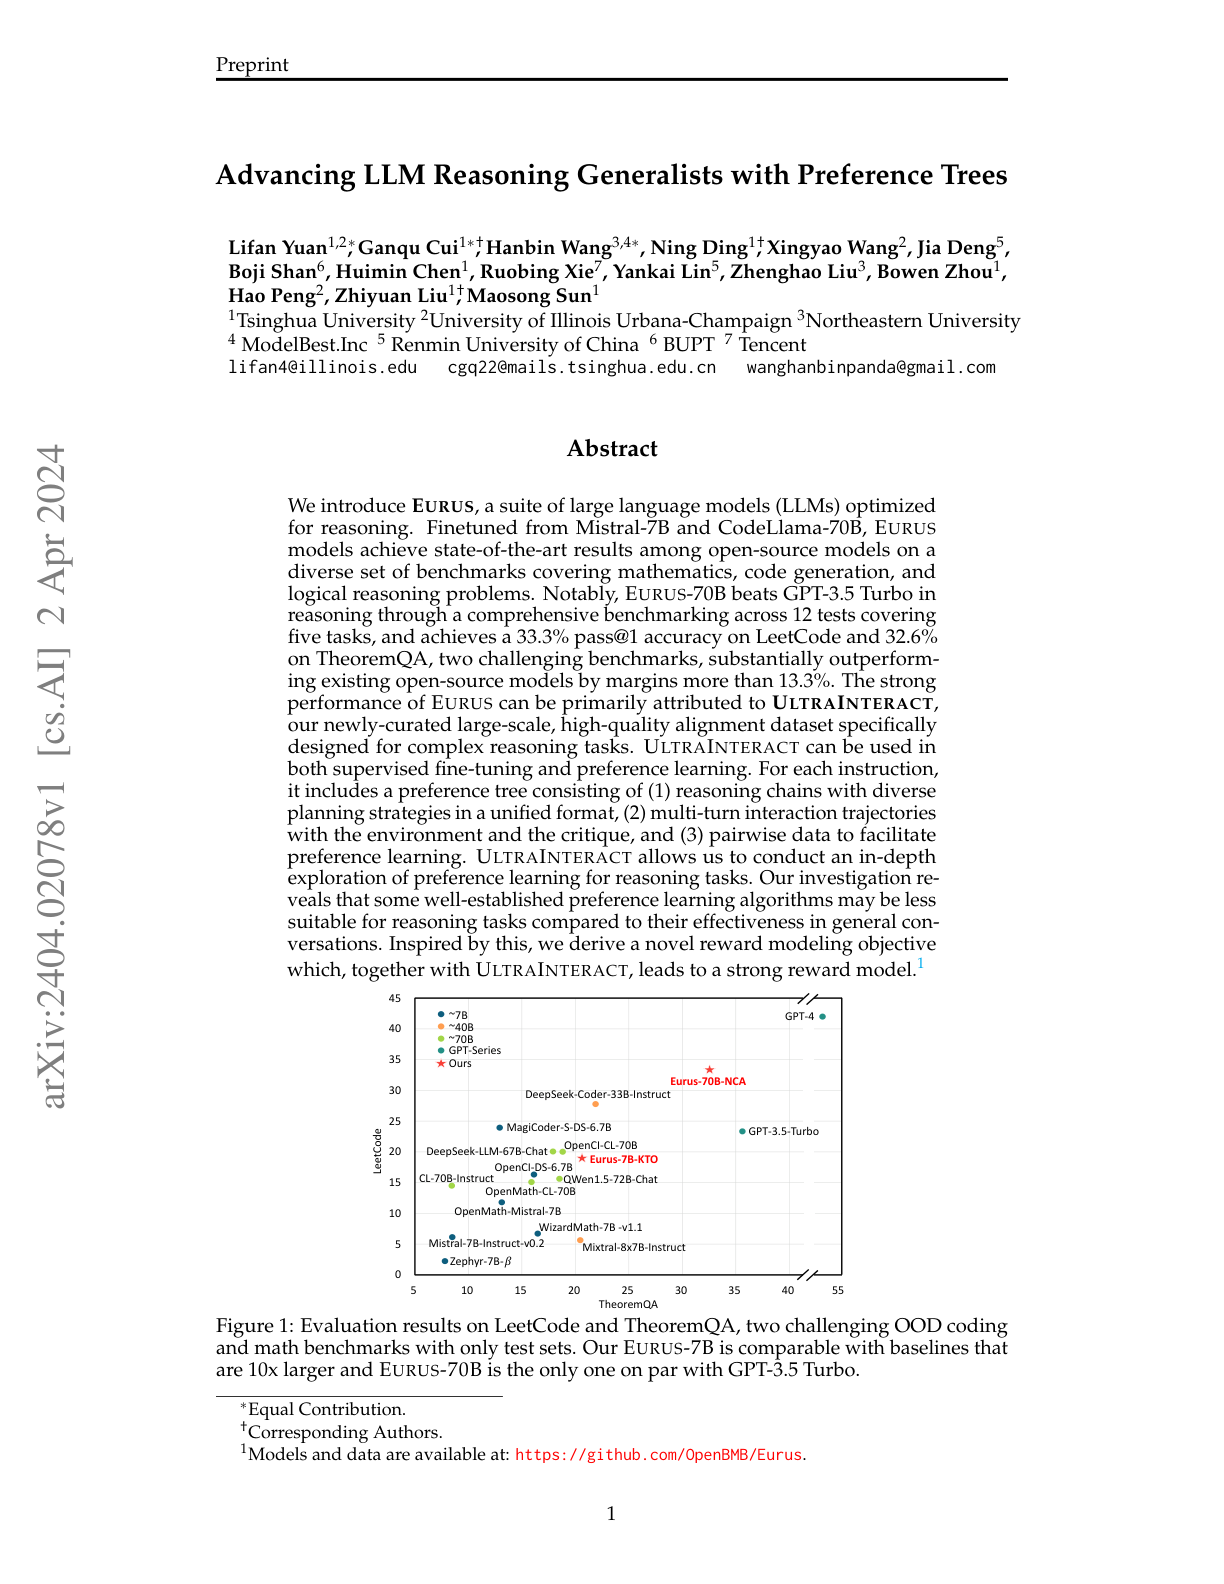
Advancing LLM Reasoning (Eurus)
OpenBMB's Eurus is a suite of reasoning-specialized LLMs (7B and 70B) fine-tuned on UltraInteract, a new alignment dataset built around preference trees for complex math, code, and logical tasks.
Training LLMs over Neurally Compressed Text
The paper proposes Equal-Info Windows, a neural compression scheme that segments text into equal-bit-length blocks so an LLM can train directly on compressed bytes without losing learnability.
DBRX
Databricks releases DBRX, a 132B-total / 36B-active open Mixture-of-Experts LLM that beats established open models on MMLU, HumanEval, and GSM8K while delivering 2x faster inference than LLaMA2-70B.
Grok-1.5
xAI's Grok-1.5 is the successor to the open-weight Grok-1, emphasizing long-context understanding and substantially stronger math, code, and reasoning performance.
SEEDS
Google's Scalable Ensemble Envelope Diffusion Sampler (SEEDS) uses diffusion models to generate very large, physically plausible weather-forecast ensembles conditioned on only one or two operational forecasts.
LLMs on University-Level Physics Coding
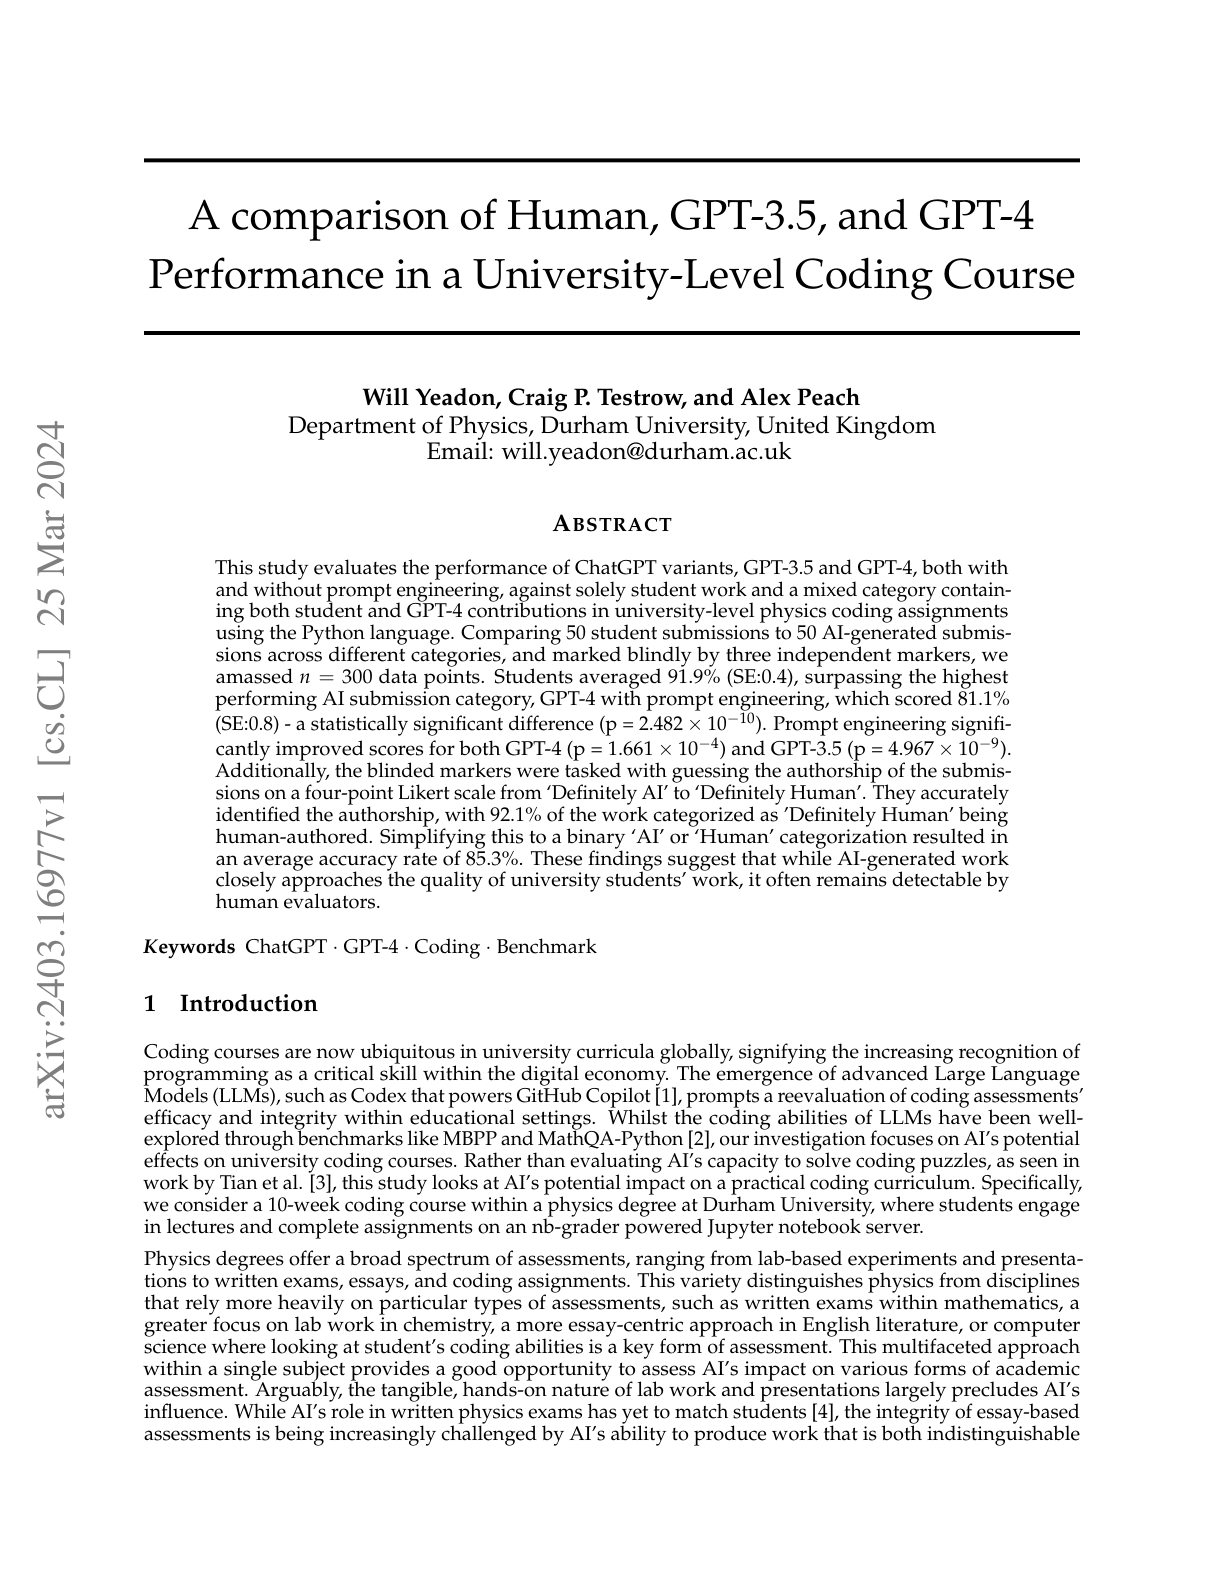
A controlled study pits ChatGPT variants against University of Durham physics students on Python coding assignments, finding that humans still outperform even the strongest prompt-engineered GPT-4.
Mini-Gemini
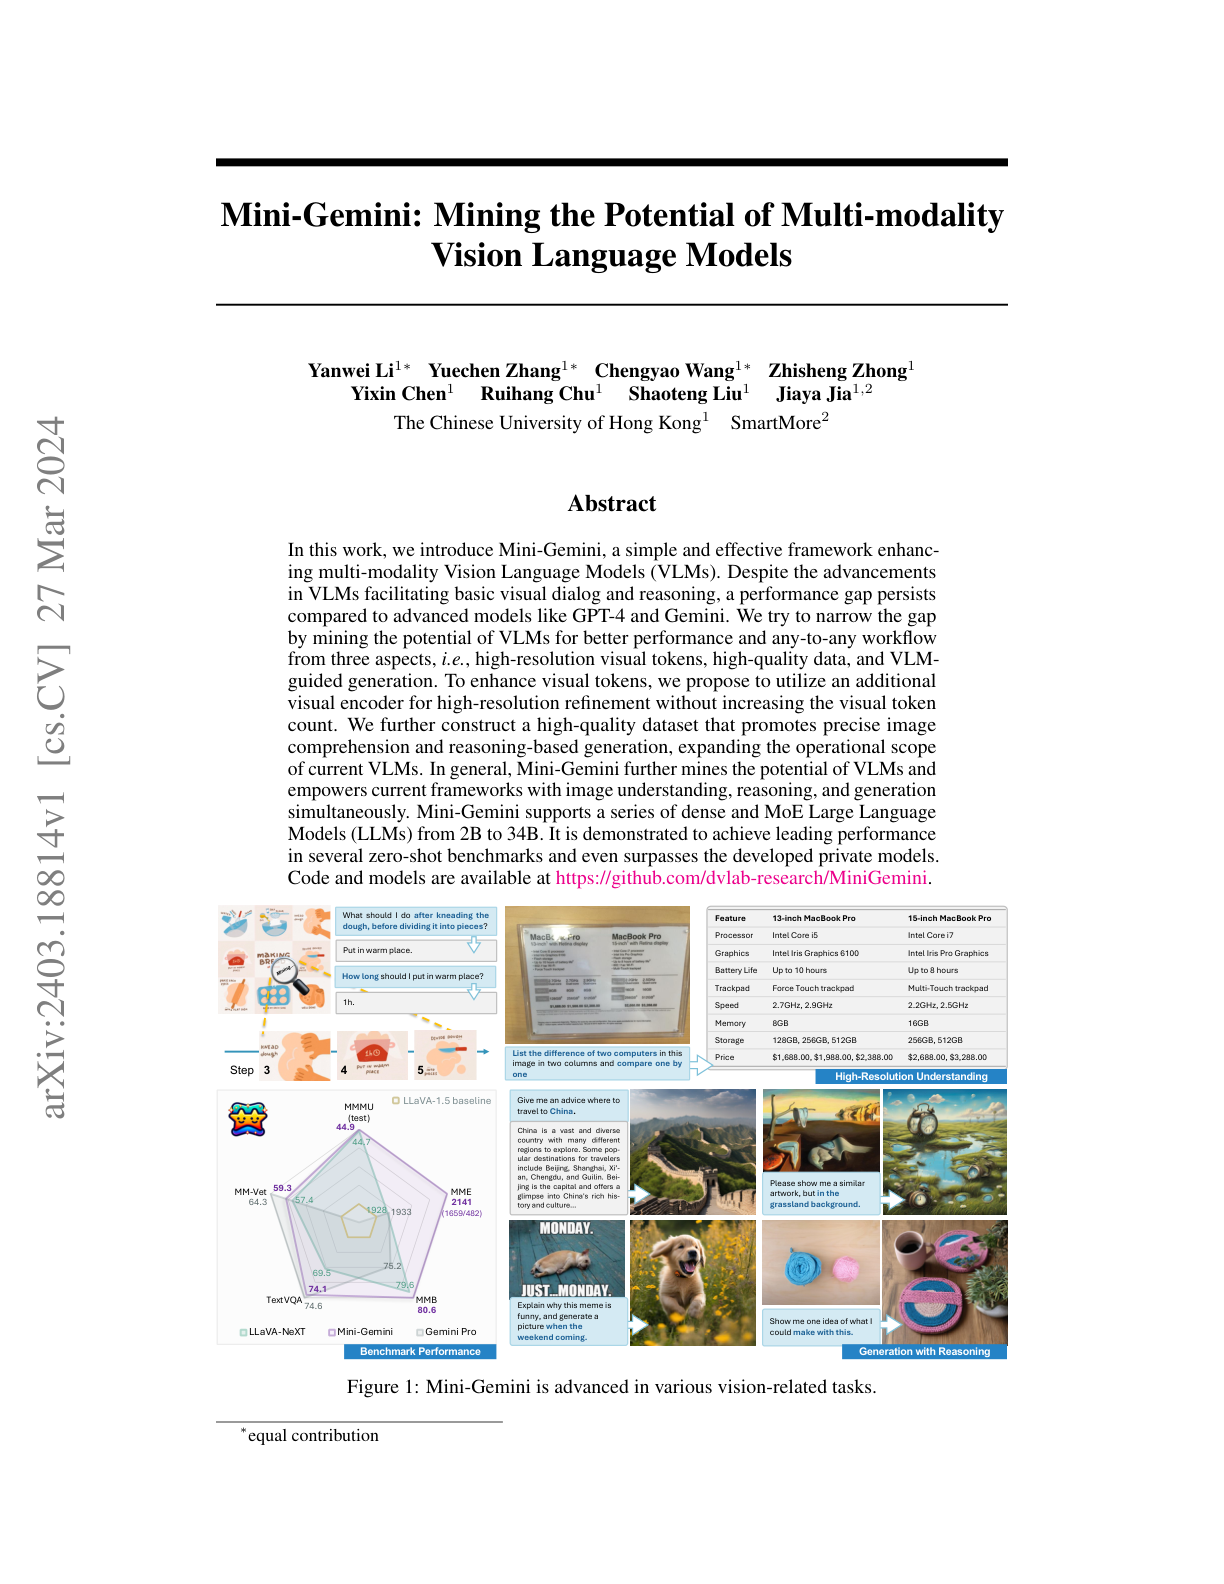
Mini-Gemini enhances vision-language models by adding a second high-resolution visual encoder that refines details without increasing the number of visual tokens consumed by the LLM.