AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
RECOMP (Retrieval-Augmented LMs with Compressors)
Proposes two compression approaches to shrink retrieved documents before in-context use.
InstructRetro
NVIDIA introduces Retro 48B, the largest LLM pretrained with retrieval at the time.
MemWalker
MemWalker treats the LLM as an interactive agent that traverses a tree-structured summary of long text.
FireAct (Language Agent Fine-tuning)
Explores fine-tuning LLMs specifically for language-agent use, demonstrating consistent gains over prompting alone.
LLMs Represent Space and Time
MIT researchers find that LLMs internally encode linear representations of space and time across multiple scales.
Retrieval Meets Long-Context LLMs
NVIDIA's study comparing RAG and long-context LLMs, with the punchline that the two are complementary rather than substitutes.
StreamingLLM
MIT's StreamingLLM enables efficient streaming inference by preserving "attention sinks" - early-sequence tokens that most attention mass flows to.
Neural Developmental Programs (NDPs)
Proposes neural networks that self-assemble through a developmental process inspired by biological embryonic development.
The Dawn of LMMs (GPT-4V Deep Dive)
Microsoft's exhaustive 166-page analysis of GPT-4V's capabilities and limitations.
Training LLMs with Pause Tokens
CMU shows that adding a learnable `<pause>` token during both pretraining and fine-tuning gives the model extra "thinking time" and improves reasoning.
Self-Taught Optimizer (STOP)
Proposes recursively self-improving code generation where an LLM-scaffolded program improves itself.
RA-DIT (Retrieval-Augmented Dual Instruction Tuning)
Meta's RA-DIT is a lightweight recipe that retrofits LLMs with retrieval capabilities through dual fine-tuning.
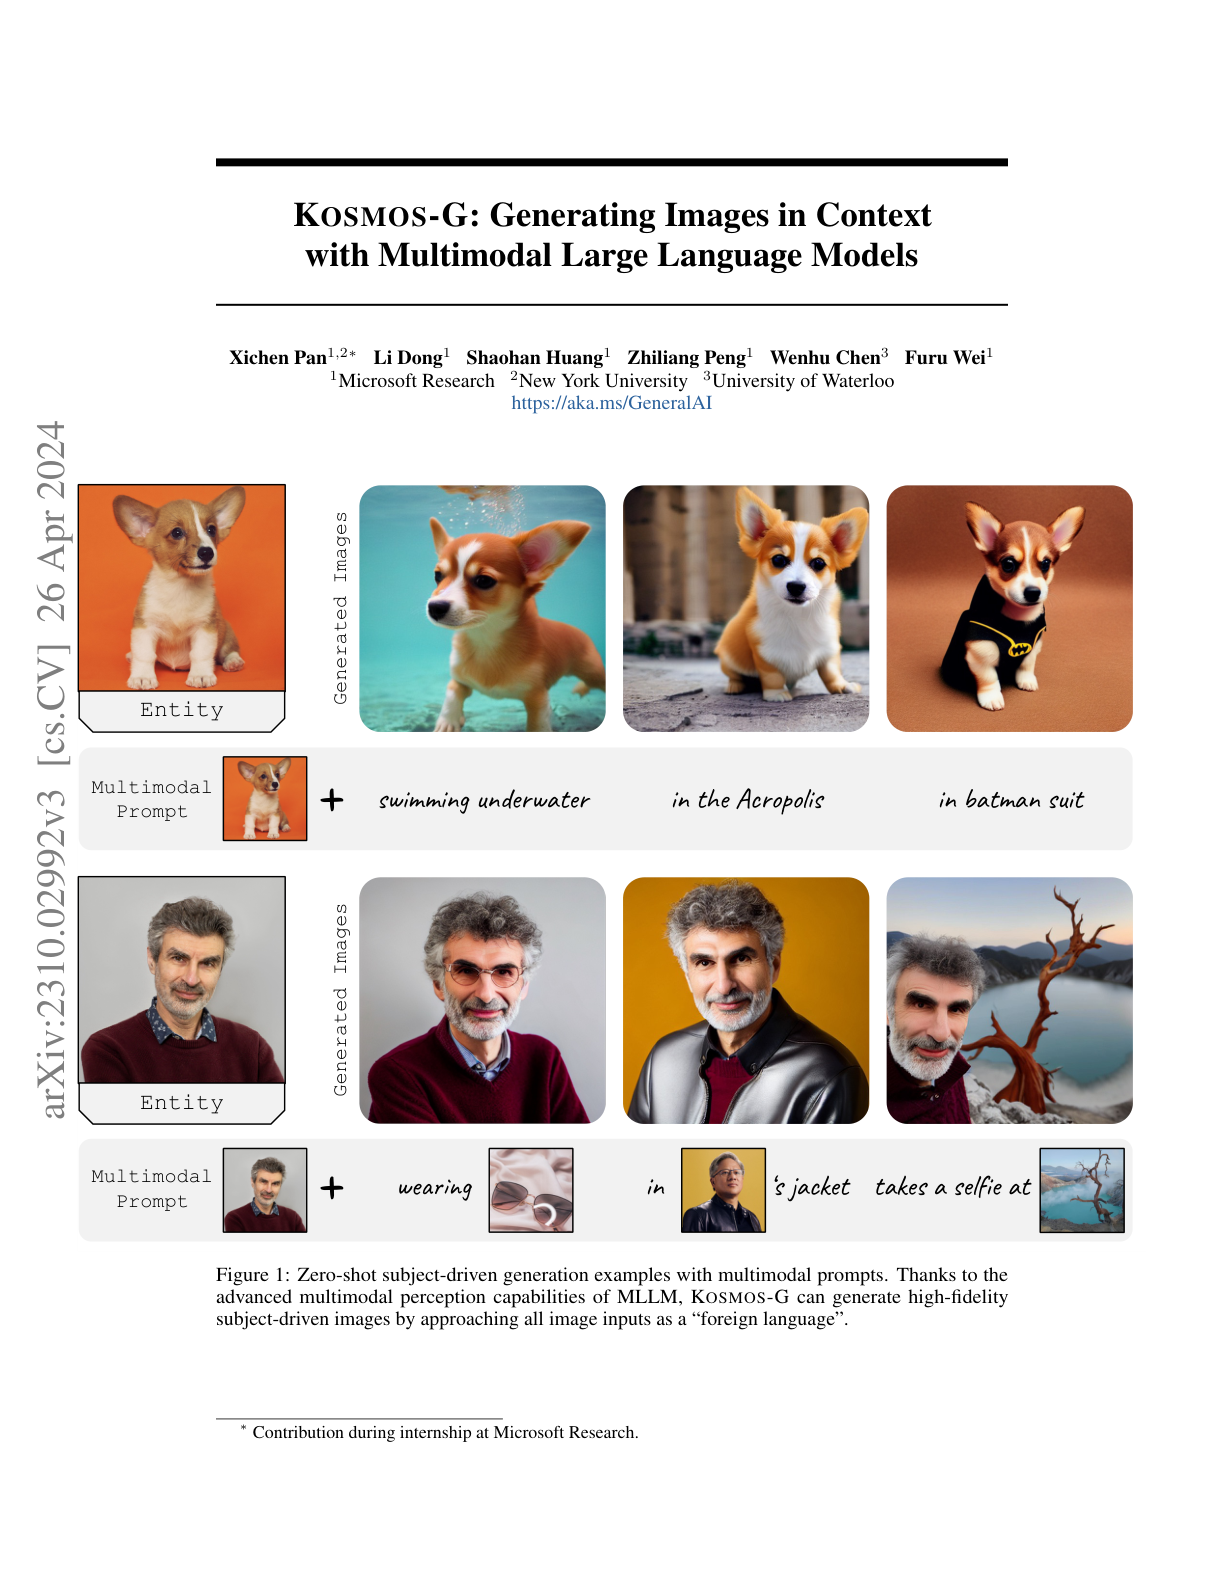
KOSMOS-G
Microsoft's KOSMOS-G extends zero-shot image generation to multi-image vision-language input.
Analogical Prompting
Google's Analogical Prompting guides LLM reasoning by having the model self-generate relevant exemplars on the fly.
The Reversal Curse
Finds that LLMs trained on "A is B" fail to generalize to "B is A" - a surprisingly deep failure of learning.
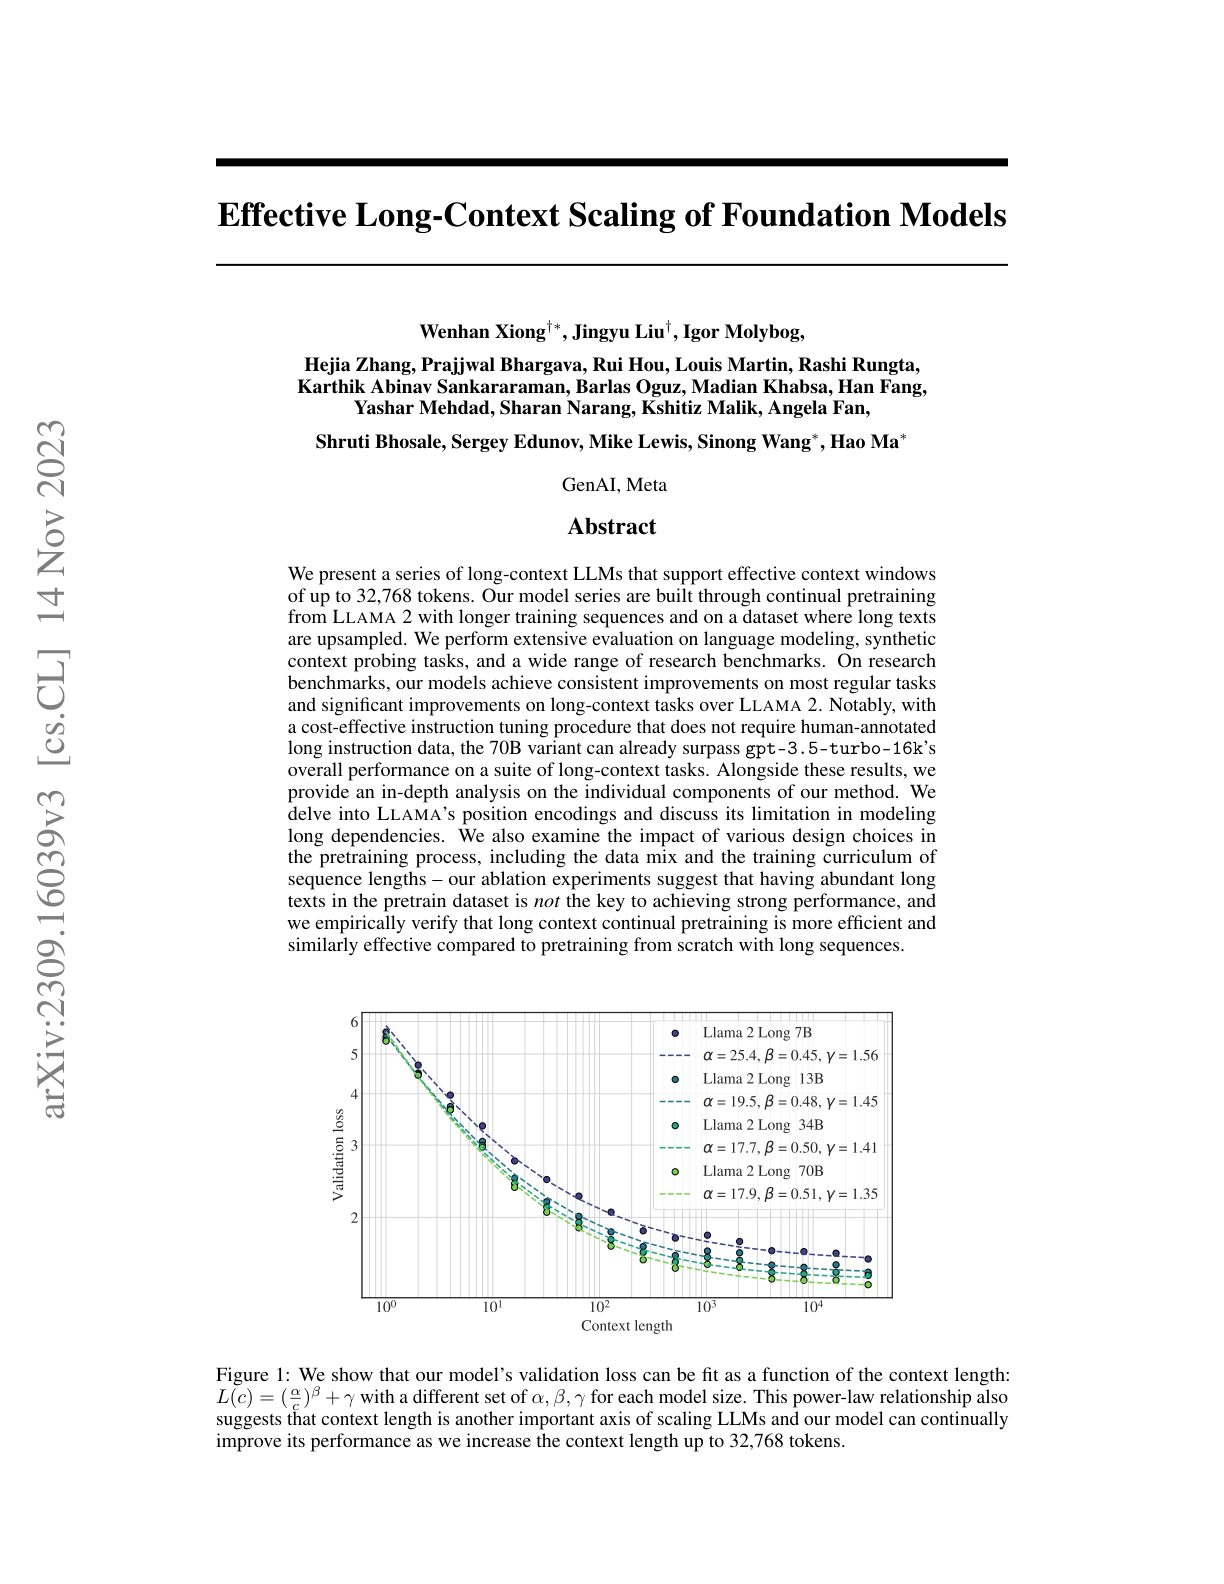
Effective Long-Context Scaling (Meta)
Meta proposes a 70B long-context LLM that surpasses GPT-3.5-turbo-16k on long-context benchmarks.
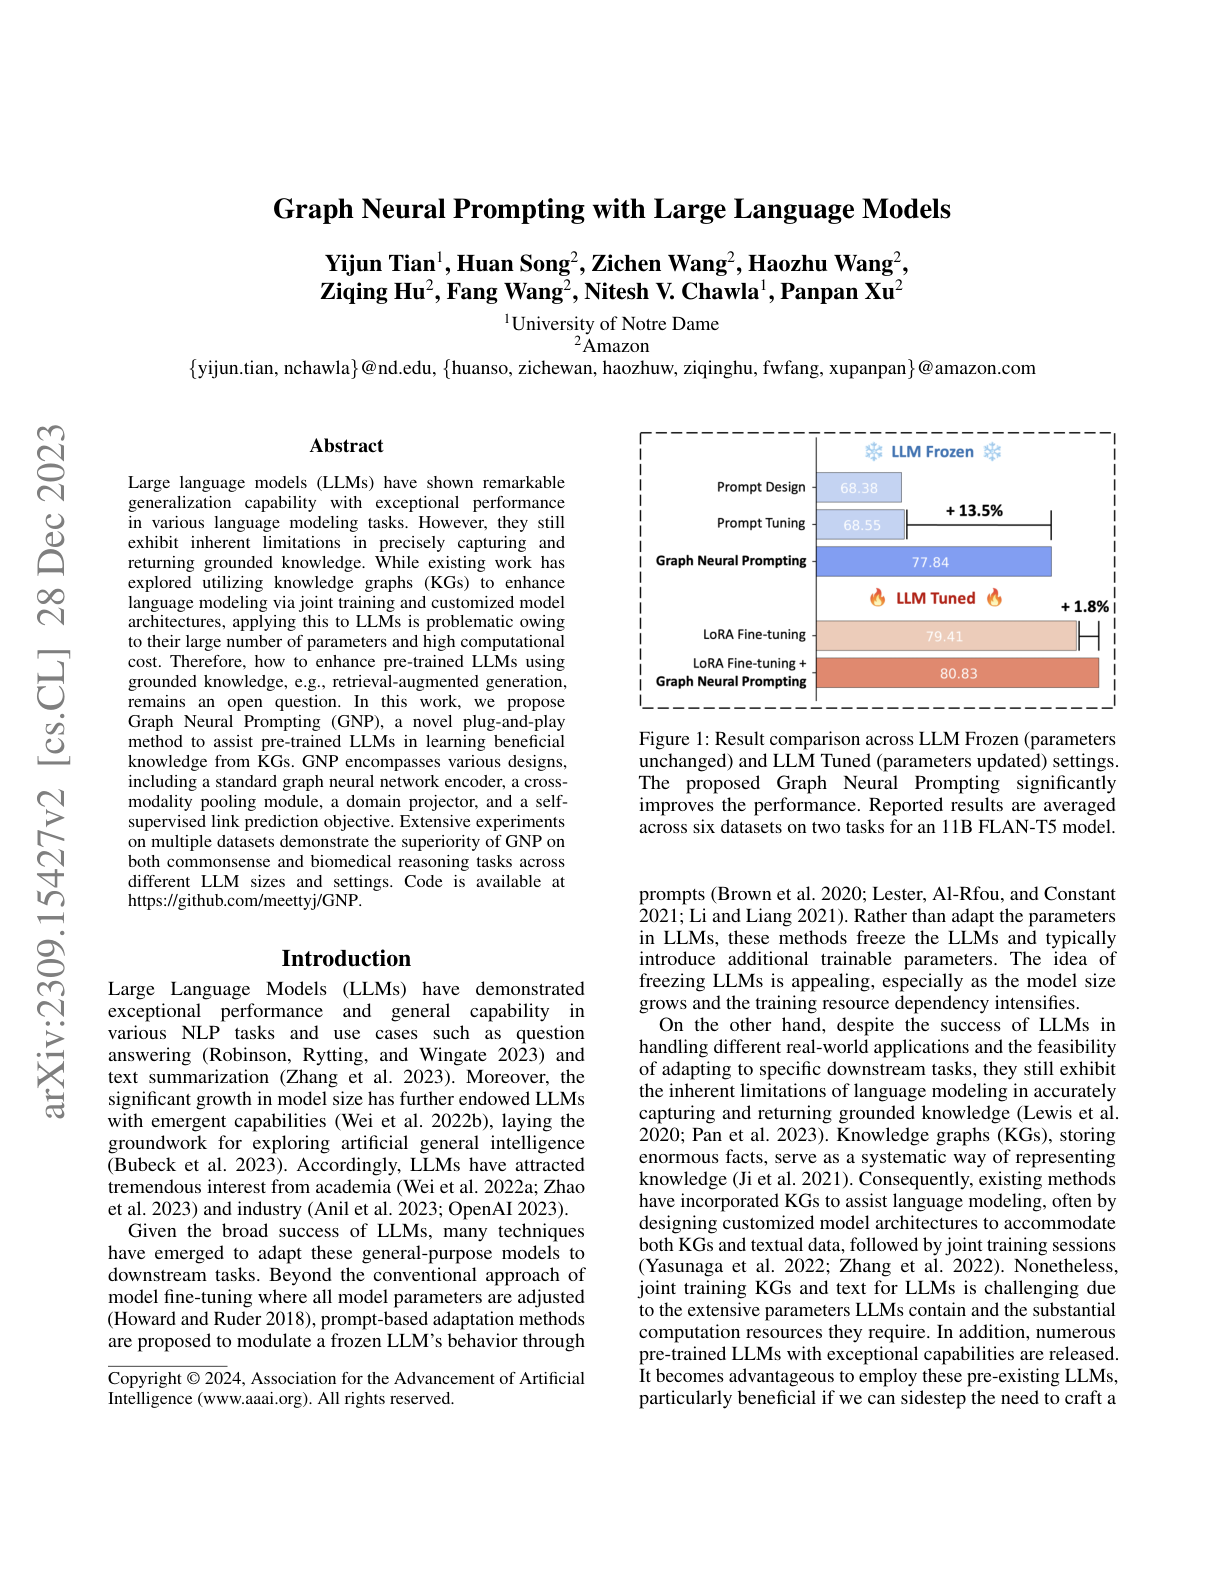
Graph Neural Prompting (GNP)
A plug-and-play method that injects knowledge-graph information into frozen pretrained LLMs.
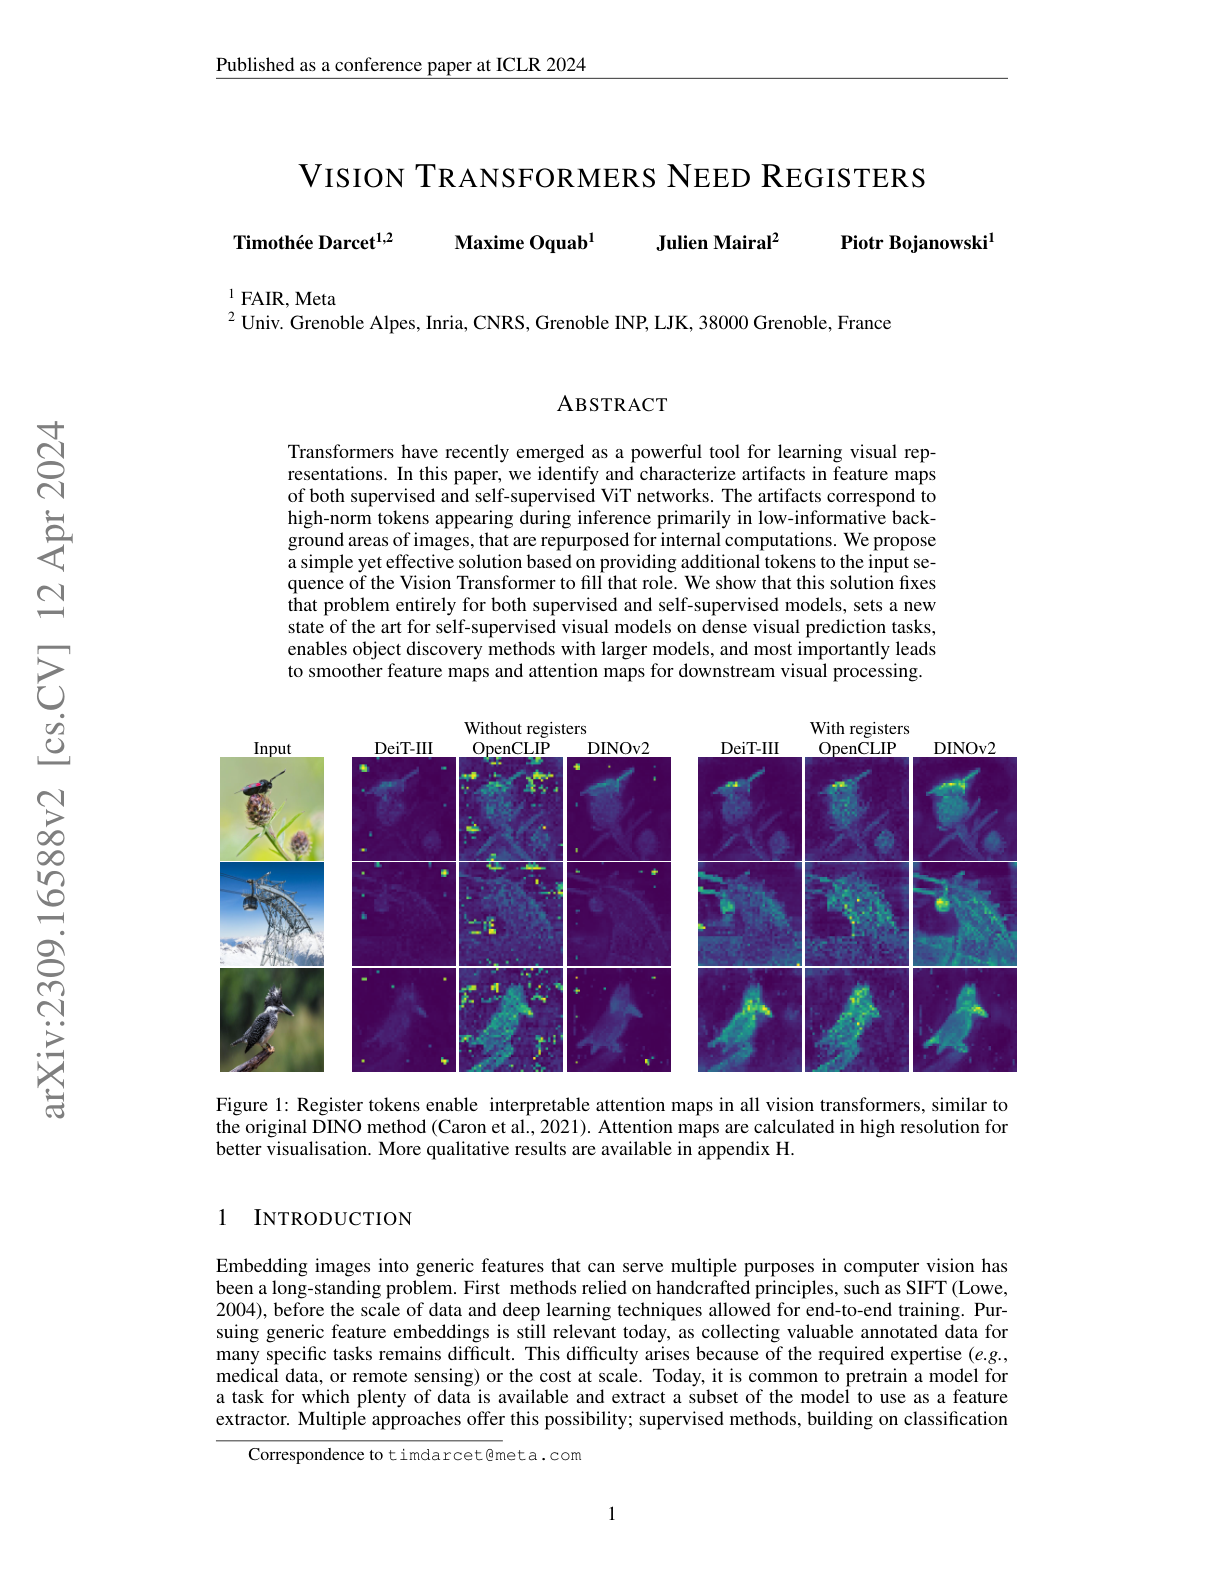
Vision Transformers Need Registers
Meta researchers identify artifact tokens in ViT feature maps and propose a trivial fix: add dedicated register tokens.
Boolformer
The first Transformer trained to perform end-to-end symbolic regression of Boolean functions.
LLaVA-RLHF
Adapts factually augmented RLHF to aligning large multimodal models, reducing hallucination without falling into reward-hacking pitfalls.
LLM Alignment Survey
A comprehensive survey of LLM alignment research spanning theoretical foundations to adversarial pressure.
Qwen
Alibaba releases the Qwen family of open LLMs with strong tool-use and planning capabilities for language agents.
MentaLLaMA
An open-source LLM family specialized for interpretable mental-health analysis on social media.
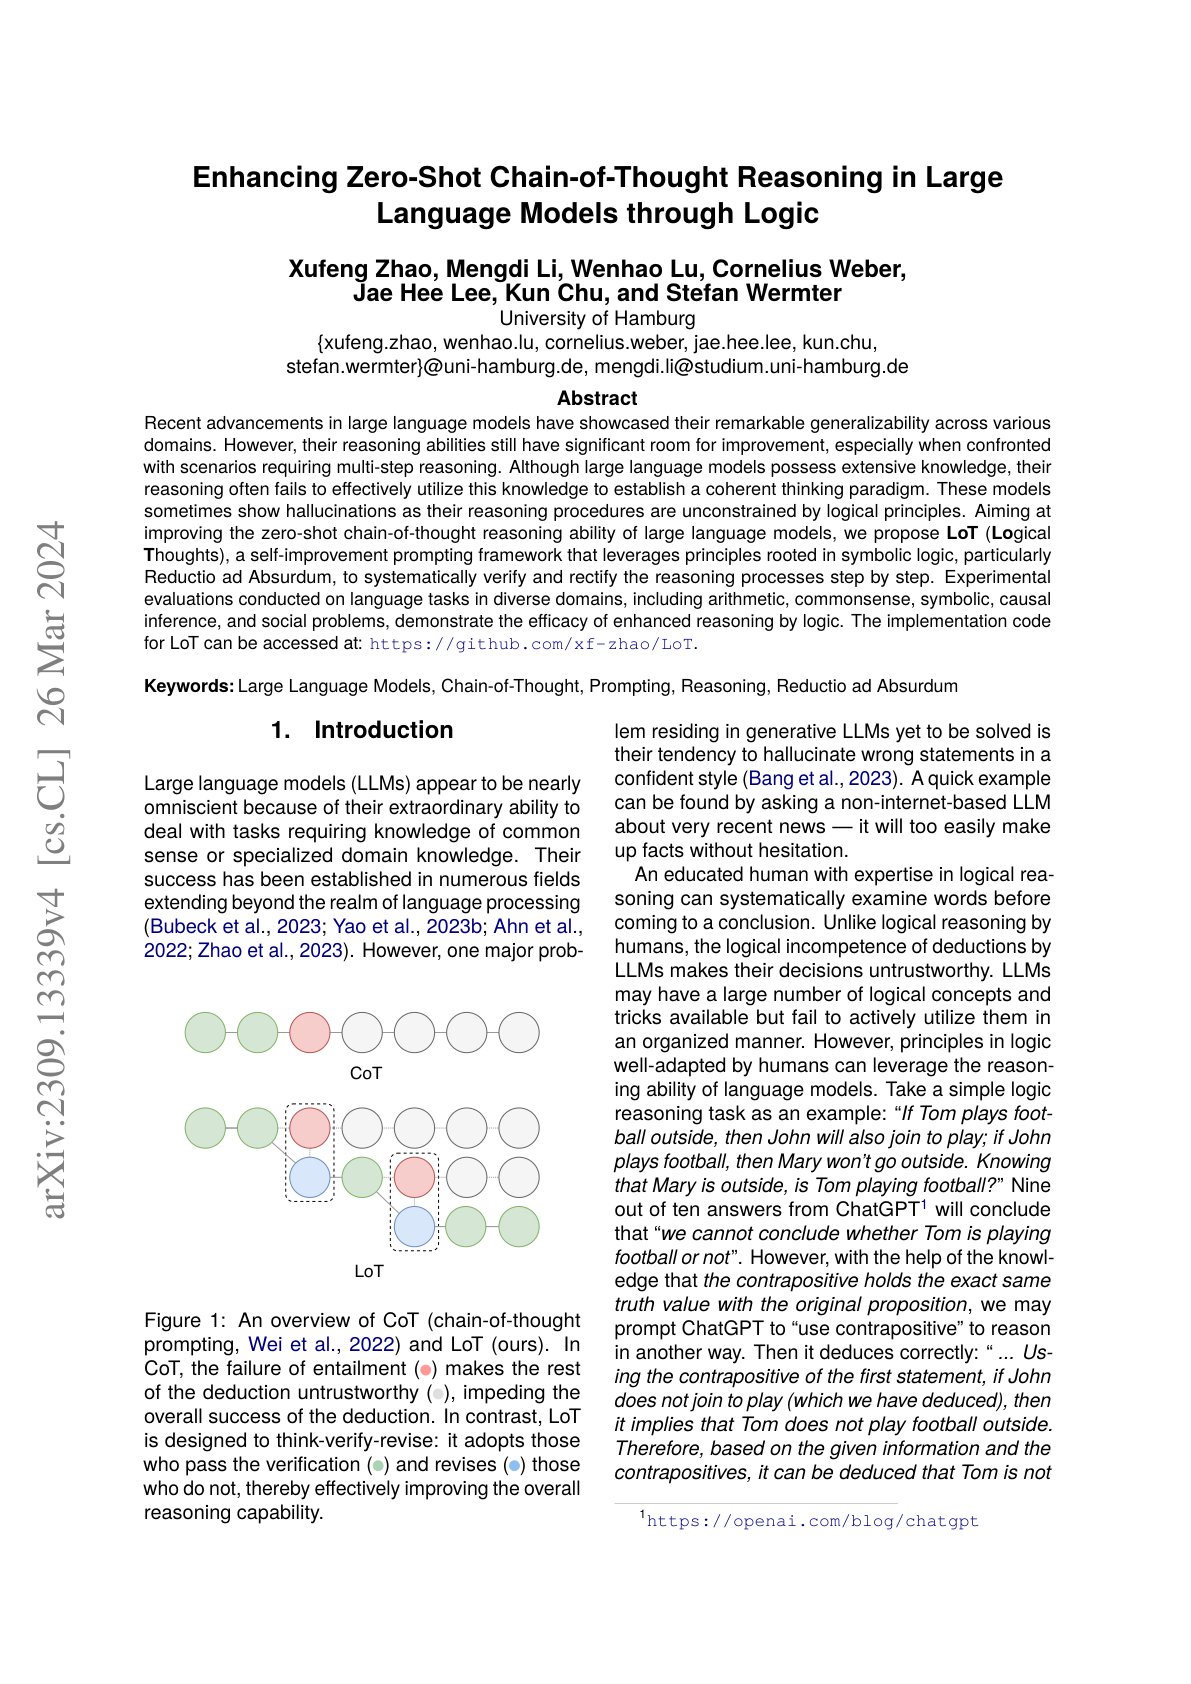
Logical Chain-of-Thought (LogiCoT)
A neurosymbolic framework that verifies and revises zero-shot CoT reasoning using symbolic-logic principles.