AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup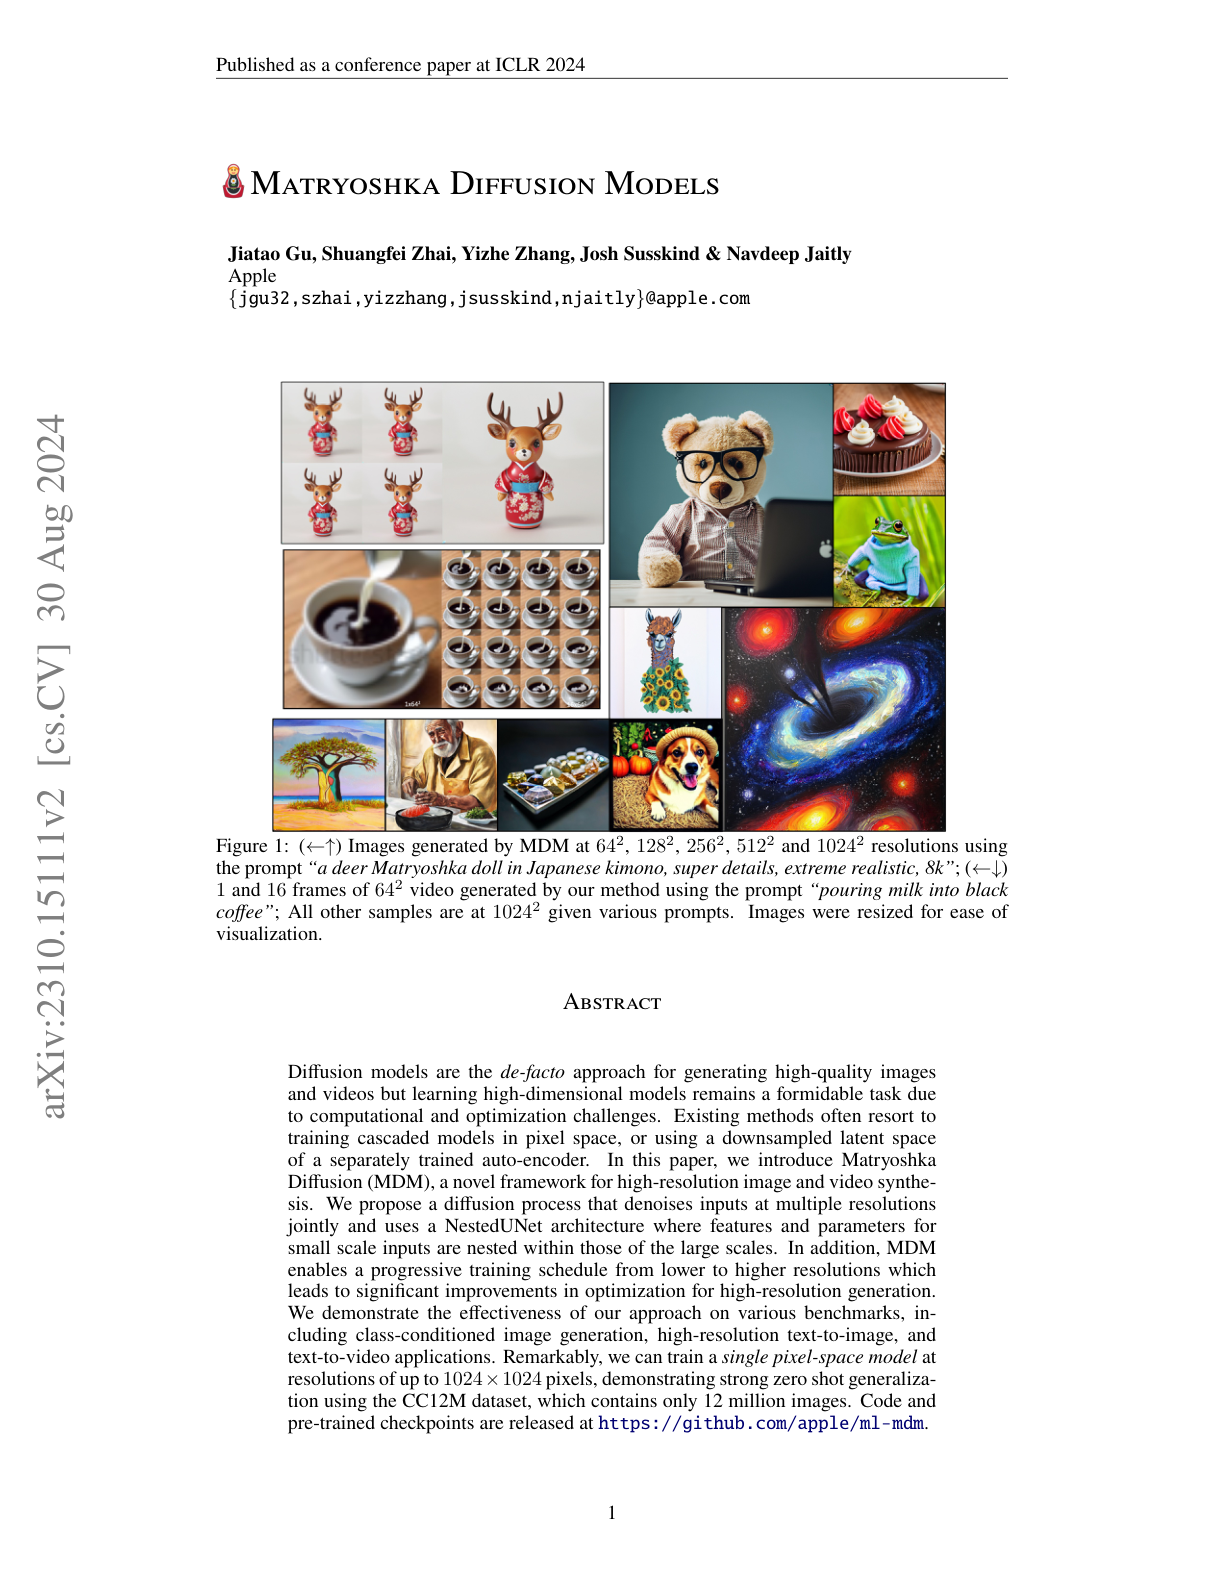
Matryoshka Diffusion Models
Apple introduces an end-to-end framework for high-resolution image and video synthesis that denoises across multiple resolutions jointly.
Spectron
Google's Spectron is a spoken-language model trained end-to-end on raw spectrograms rather than text or discrete audio tokens.
LLMs Meet New Knowledge
A benchmark that evaluates how well LLMs handle new knowledge beyond their training cutoff.
Min-K% Prob (Detecting Pretraining Data)
Proposes Min-K% Prob as an effective detection method for determining whether specific text was in an LLM's pretraining data.
ConvNets Match Vision Transformers
DeepMind shows that strong ConvNet architectures pretrained at scale match ViTs on ImageNet performance at comparable compute.
CommonCanvas
Releases CommonCanvas, a text-to-image dataset composed entirely of Creative-Commons-licensed images.
Managing AI Risks (Bengio, Hinton, et al.)
A high-profile position paper by leading AI researchers laying out risks from upcoming advanced AI systems.
Branch-Solve-Merge (BSM)
BSM decomposes LLM tasks into parallel sub-tasks via three LLM-programmed modules: branch, solve, and merge.
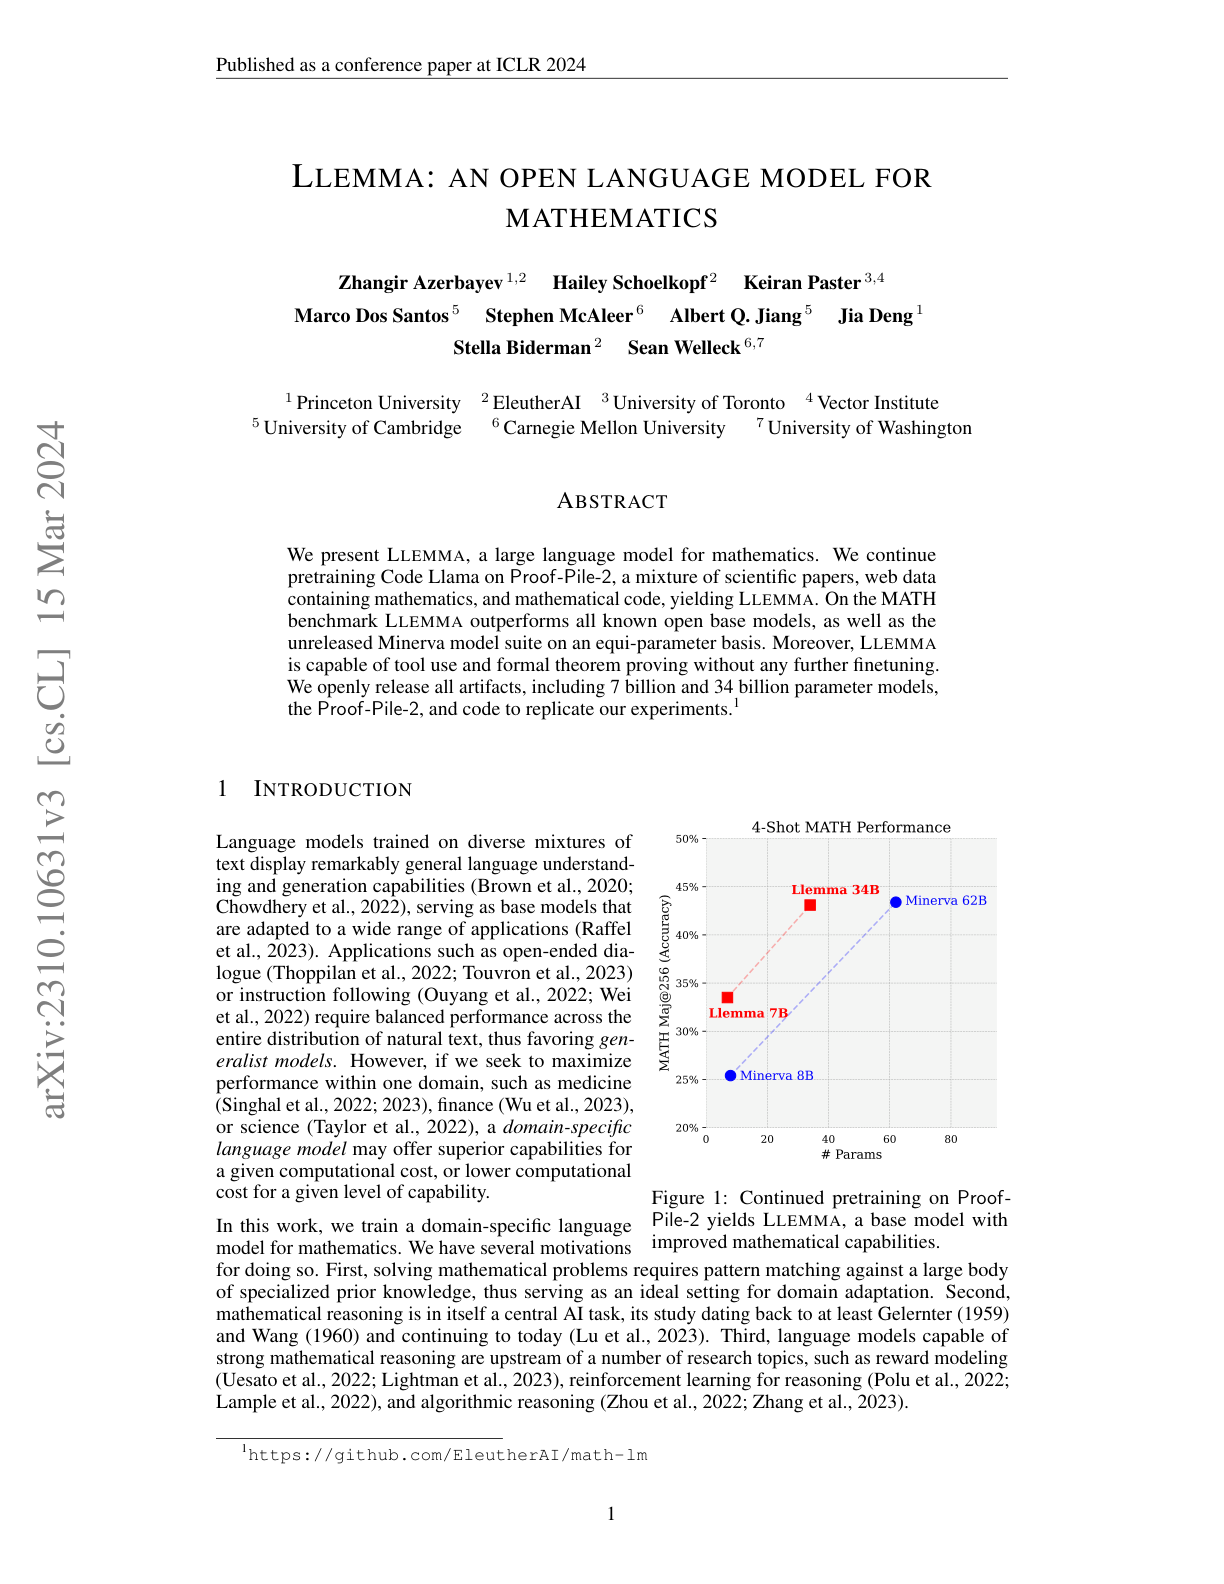
Llemma
Llemma is an open LLM for mathematics built via continued pretraining of Code Llama on the Proof-Pile-2 dataset.
LLMs for Software Engineering
A comprehensive survey of LLMs for software engineering covering models, tasks, evaluation, and open challenges.
Self-RAG
Self-RAG trains an LM to adaptively retrieve, generate, and self-critique using special reflection tokens.
RAG for Long-Form QA
Explores retrieval-augmented LMs specifically on long-form question answering, where RAG failures are more subtle.
GenBench
A Nature Machine Intelligence paper framework for characterizing and understanding generalization research in NLP.
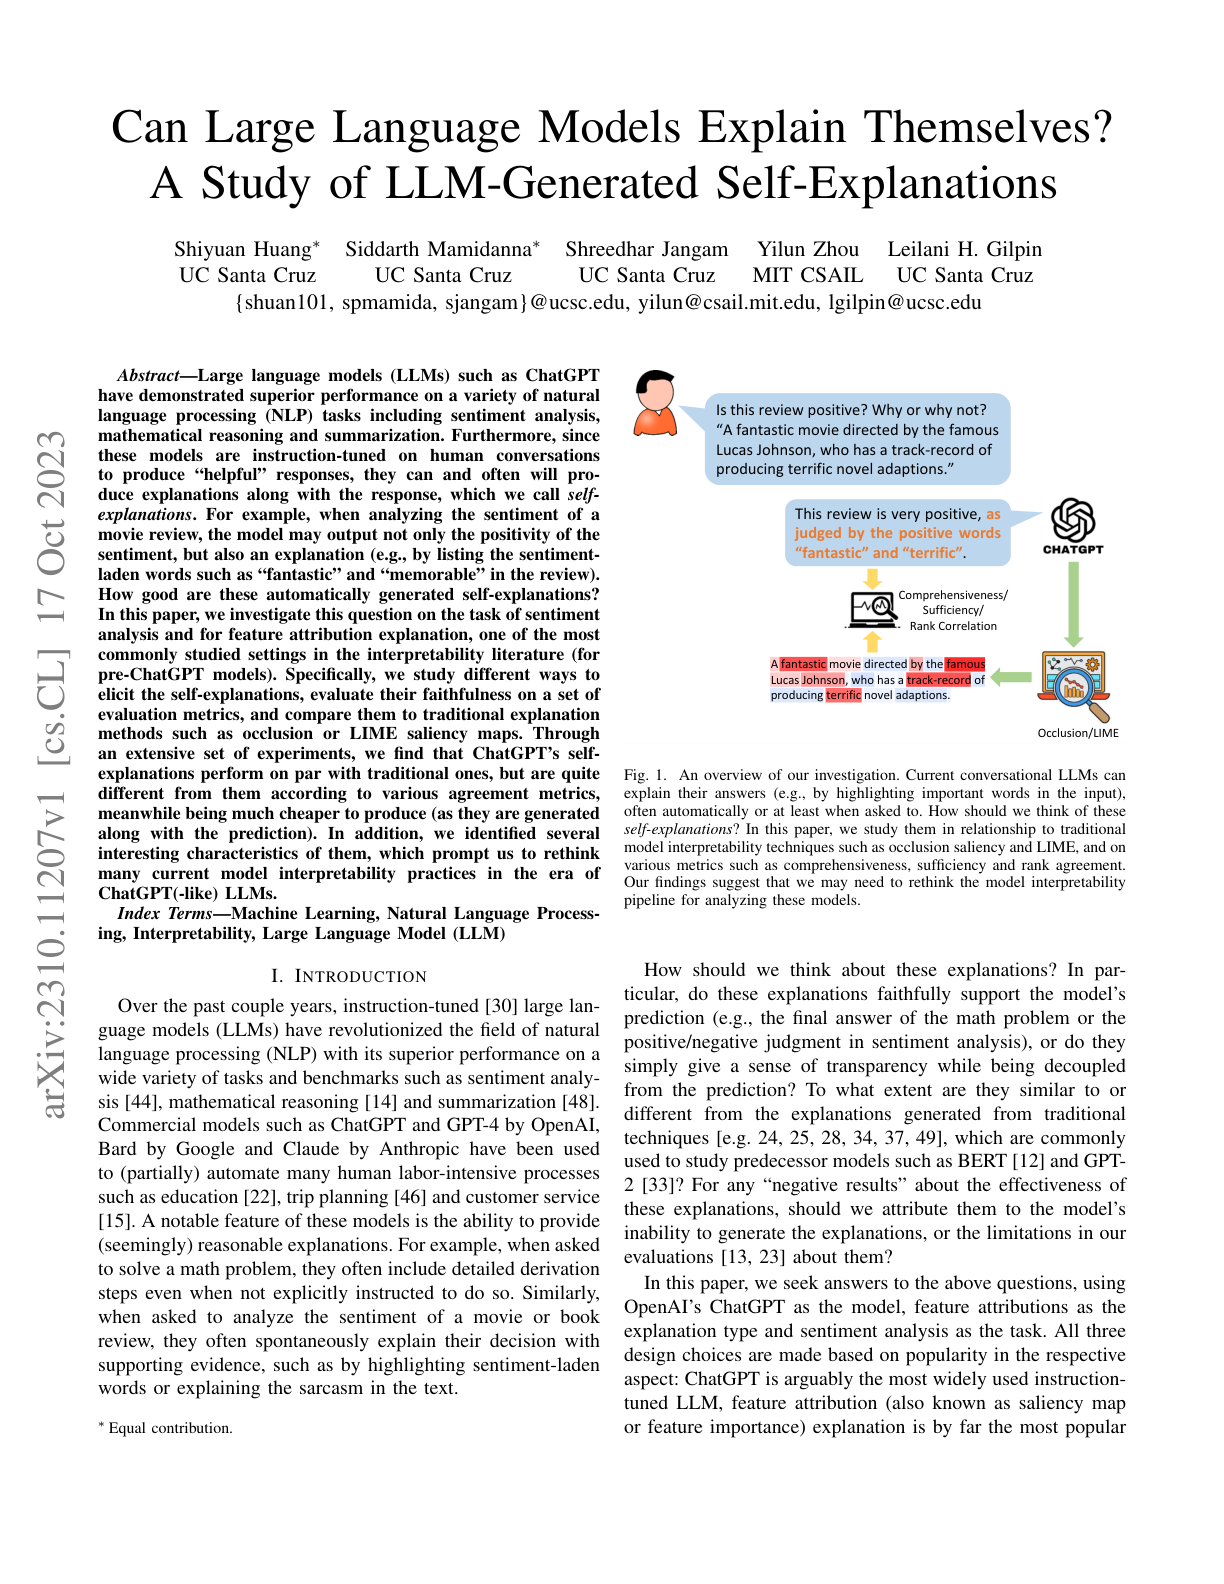
LLM Self-Explanations
Investigates whether LLMs can generate useful feature-attribution explanations for their own outputs.
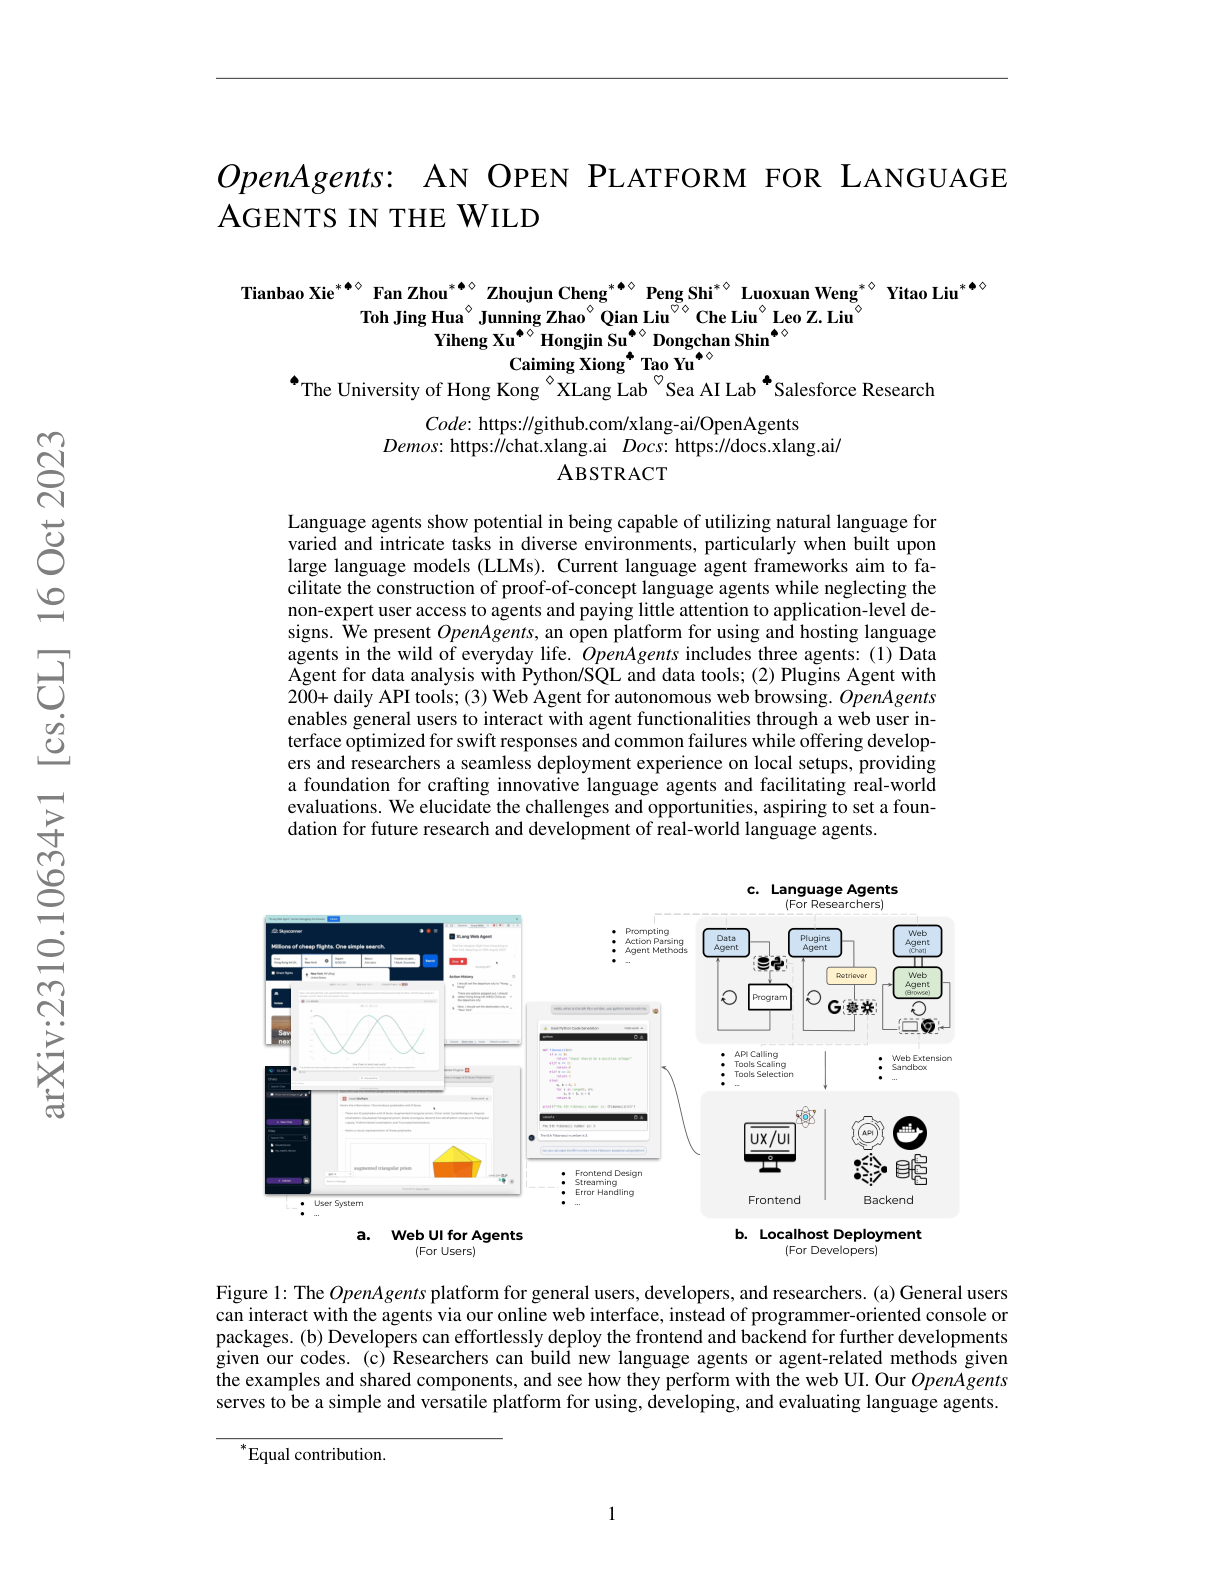
OpenAgents
An open platform for running and hosting real-world language agents, including three distinct agent types.
Eliciting Human Preferences with LLMs
Anthropic uses LLMs to guide the task-specification process, eliciting user intent through natural-language dialogue.
AutoMix
AutoMix routes queries between LLMs of different sizes based on smaller-model confidence, saving cost without sacrificing quality.
Video Language Planning
Enables synthesizing complex long-horizon video plans for robotics via tree search over vision-language and text-to-video models.
Ring Attention
UC Berkeley's Ring Attention scales transformer context to 100M+ tokens by distributing blockwise self-attention across devices in a ring topology.
UniSim (Universal Simulator)
Google's UniSim learns a universal generative simulator of real-world interactions from diverse video + action data.
Survey on Factuality in LLMs
A survey covering evaluation and enhancement techniques for LLM factuality.
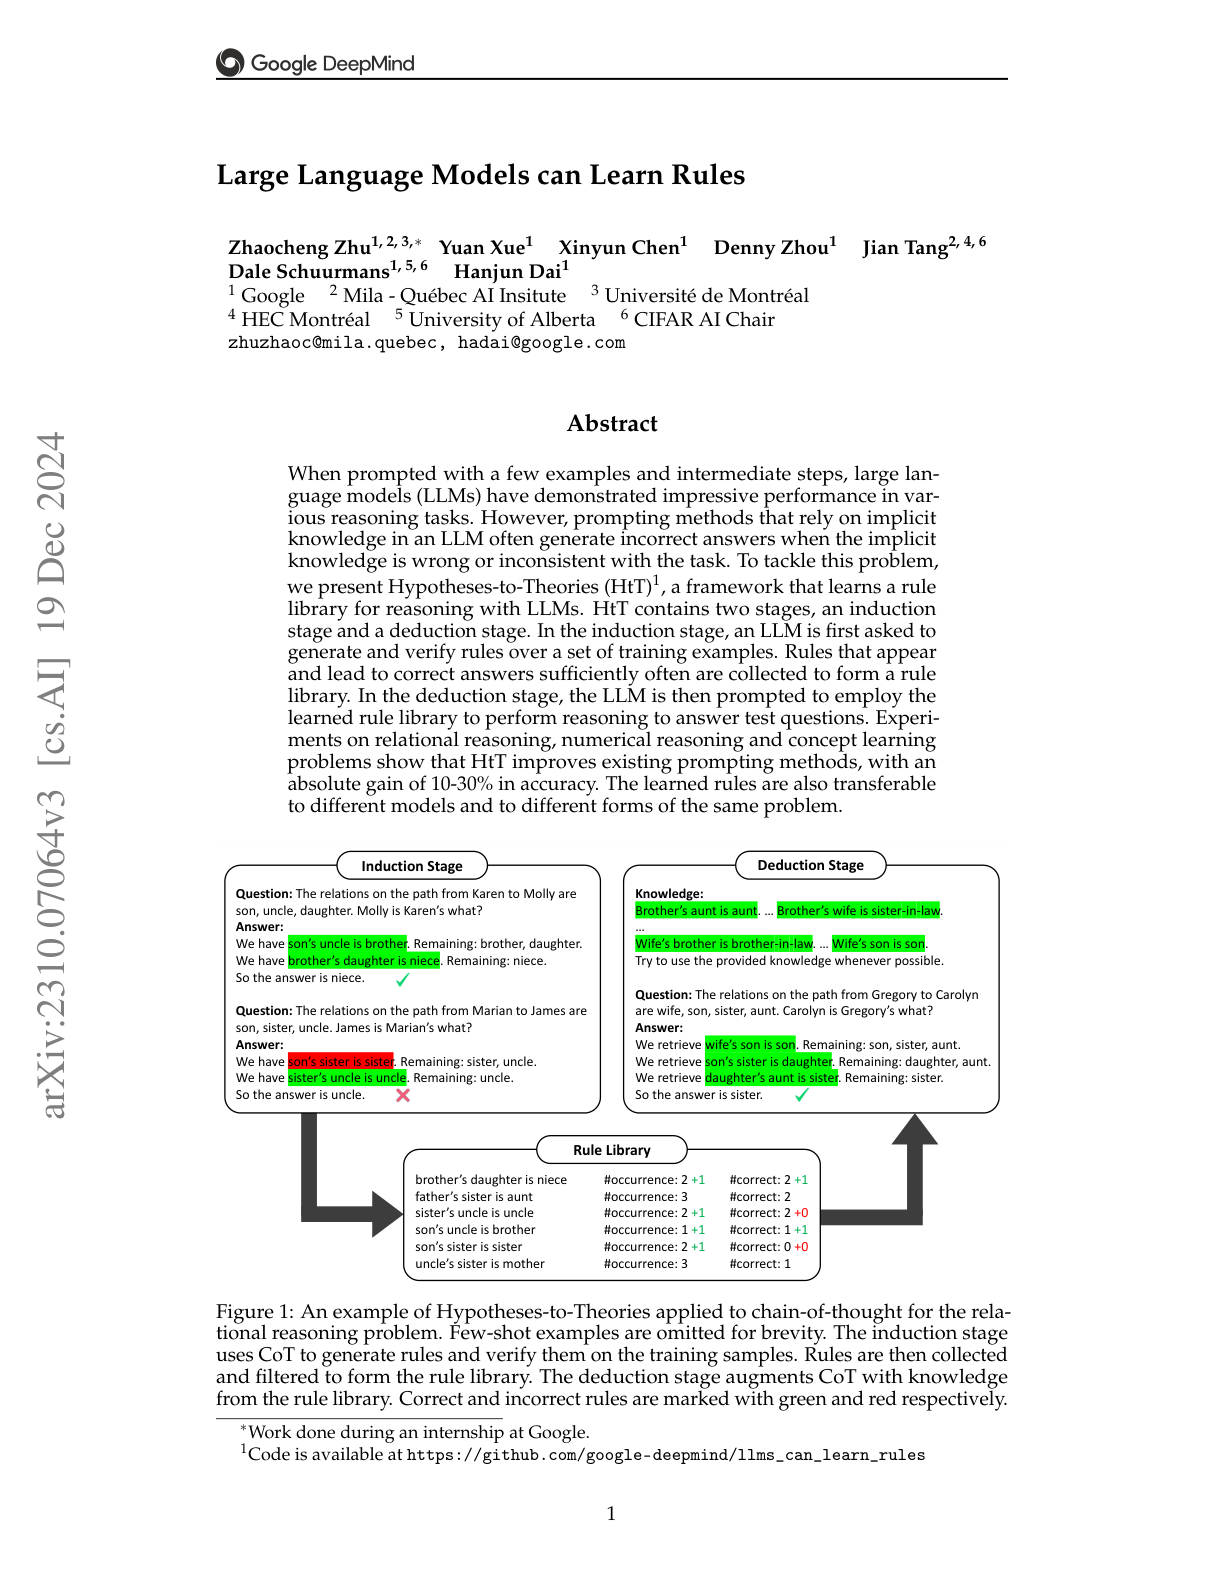
Hypothesis Search (LLMs Can Learn Rules)
A two-stage framework where the LLM learns a rule library for reasoning.
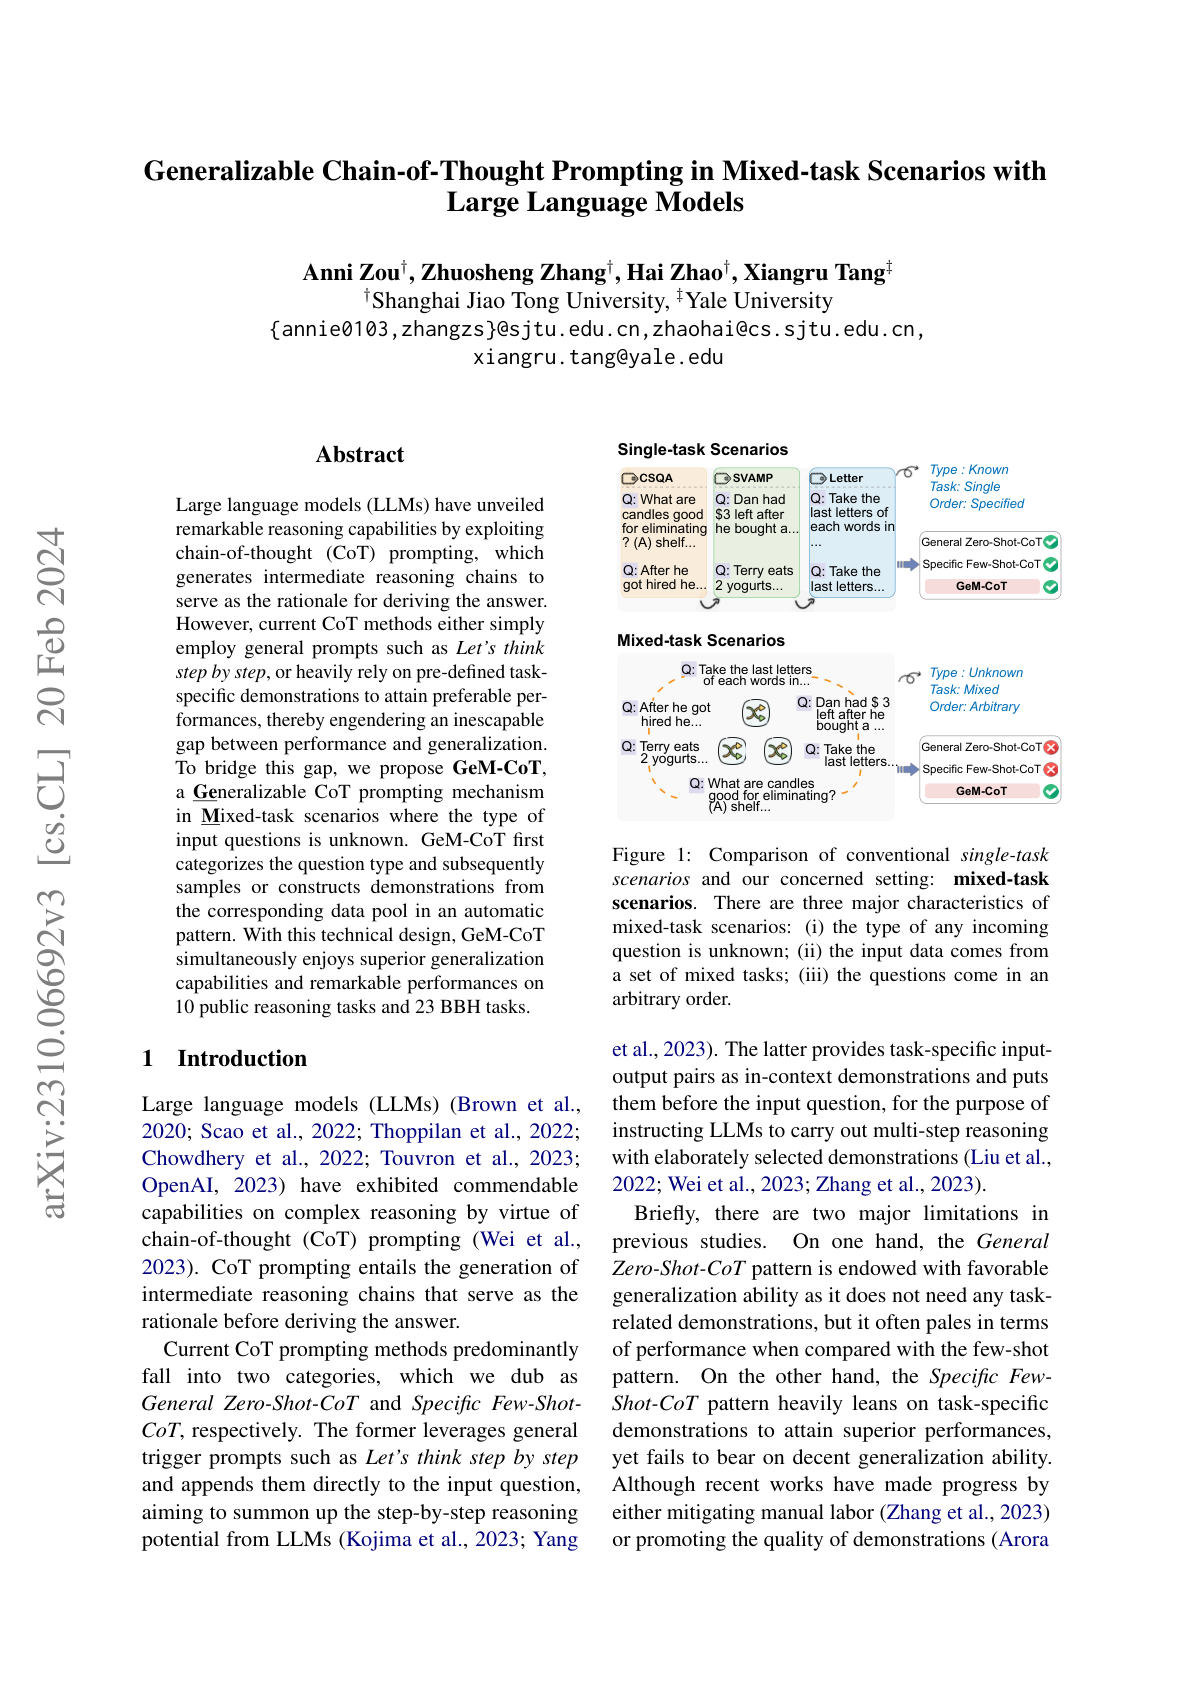
Meta Chain-of-Thought Prompting (Meta-CoT)
A generalizable CoT framework that selects domain-appropriate reasoning patterns for the task at hand.
LLMs for Healthcare Survey
A comprehensive overview of LLMs applied to the healthcare domain.