AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
AlphaMissense
DeepMind's AlphaMissense is an AI model that classifies missense genetic variants as pathogenic or benign at genome scale.
Chain-of-Verification (CoVe)
Meta's Chain-of-Verification adds a "deliberation" step where the LLM fact-checks its own draft before finalizing.
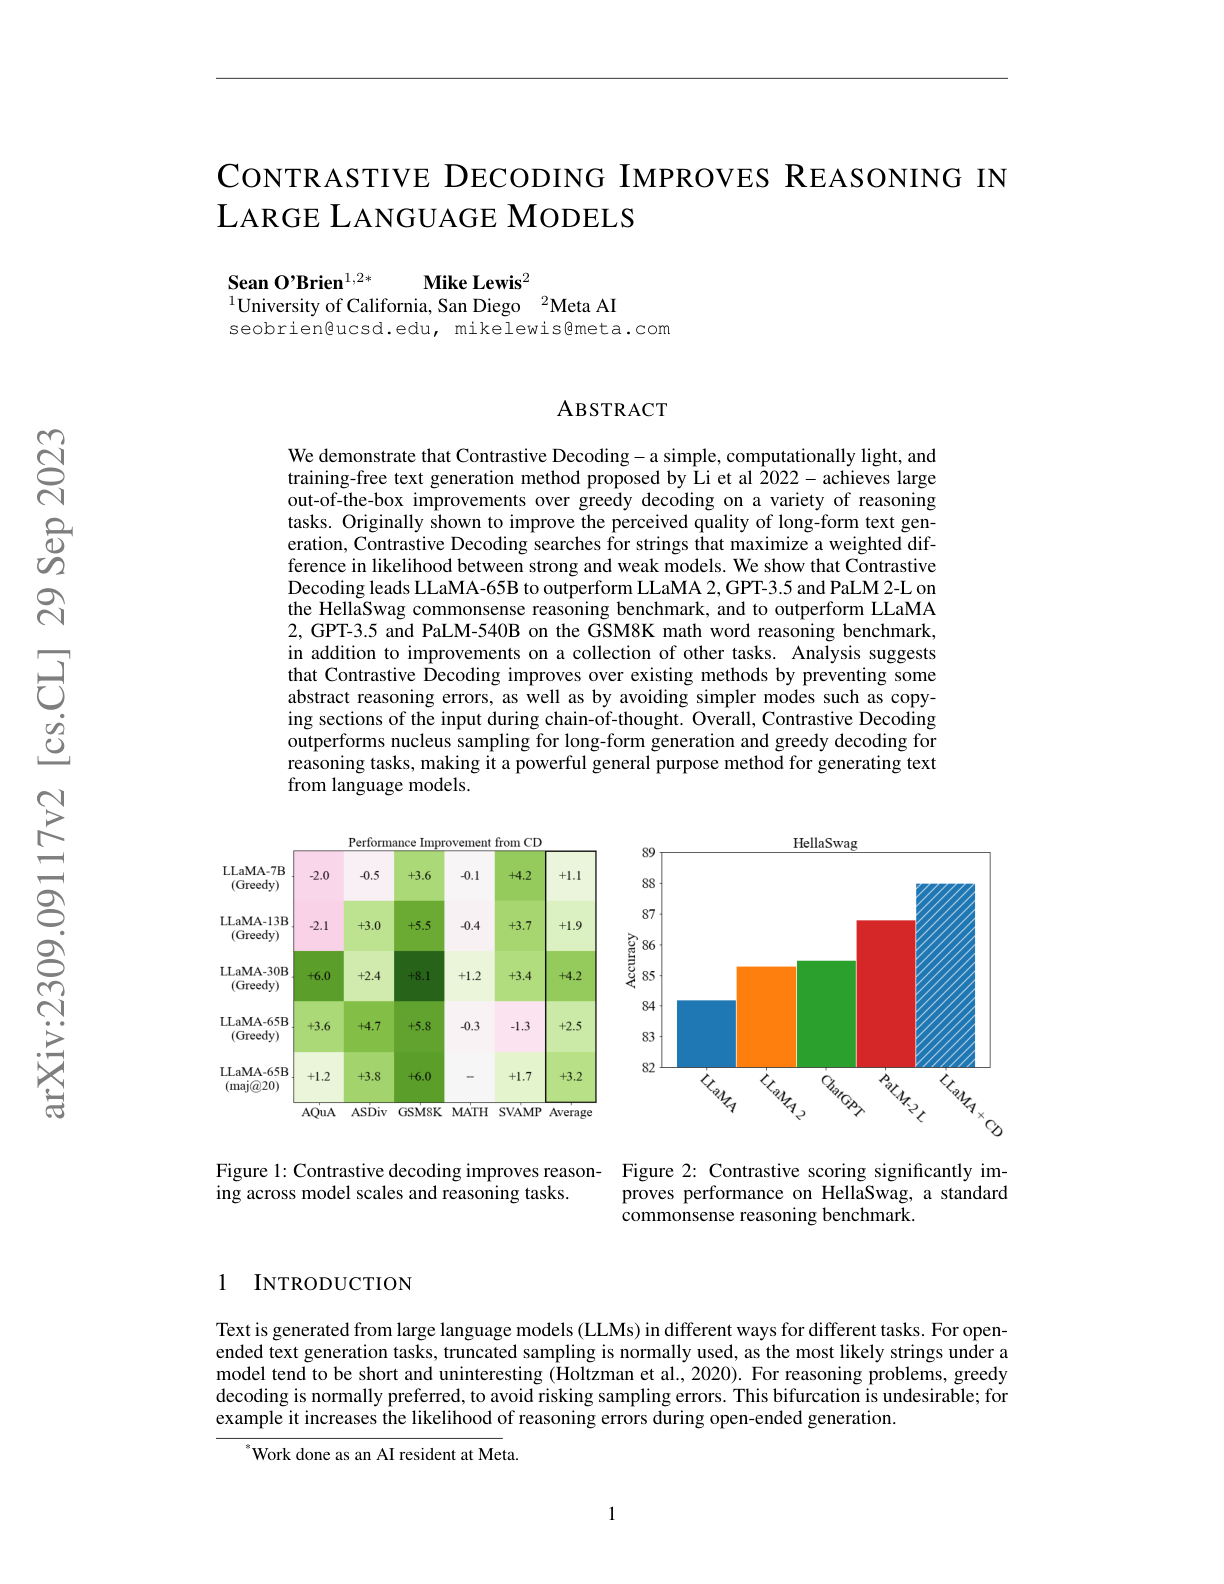
Contrastive Decoding for Reasoning
Shows that contrastive decoding, a simple inference-time technique, substantially improves reasoning in large LLMs.
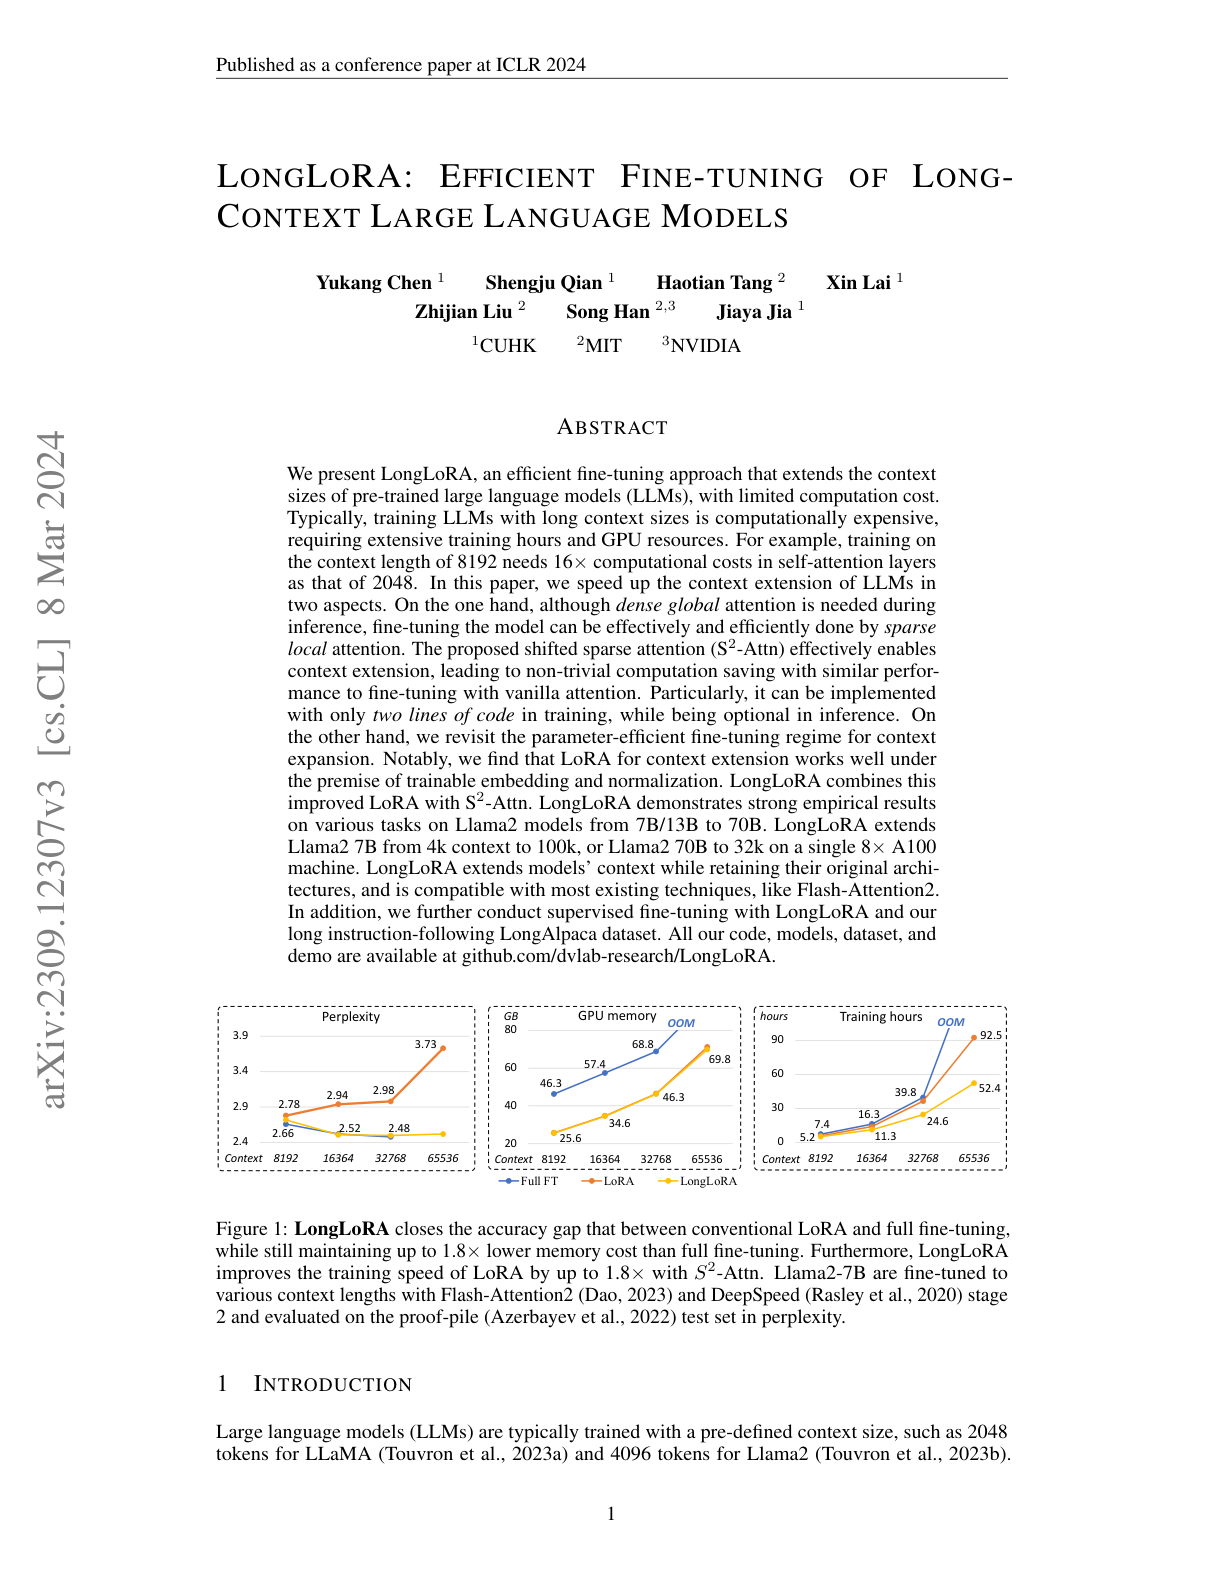
LongLoRA
An efficient LoRA-based fine-tuning recipe for extending LLM context windows without expensive full fine-tuning.
Struc-Bench (LLMs for Structured Data)
Studies how LLMs handle complex structured-data generation and proposes a structure-aware fine-tuning method.
LMSYS-Chat-1M
LMSYS releases a large-scale dataset of 1 million real-world LLM conversations collected from the Vicuna demo and Chatbot Arena.
Language Modeling Is Compression
DeepMind empirically revisits the theoretical equivalence between prediction and compression, applied to modern LLMs.
Compositional Foundation Models (HiP)
Proposes foundation models that compose multiple expert foundation models trained on different modalities to solve long-horizon goals.
OWL (LLMs for IT Operations)
Proposes OWL, an LLM specialized for IT operations through self-instruct fine-tuning on IT-specific tasks.
KOSMOS-2.5
Microsoft's KOSMOS-2.5 is a multimodal model purpose-built for "machine reading" of text-intensive images.
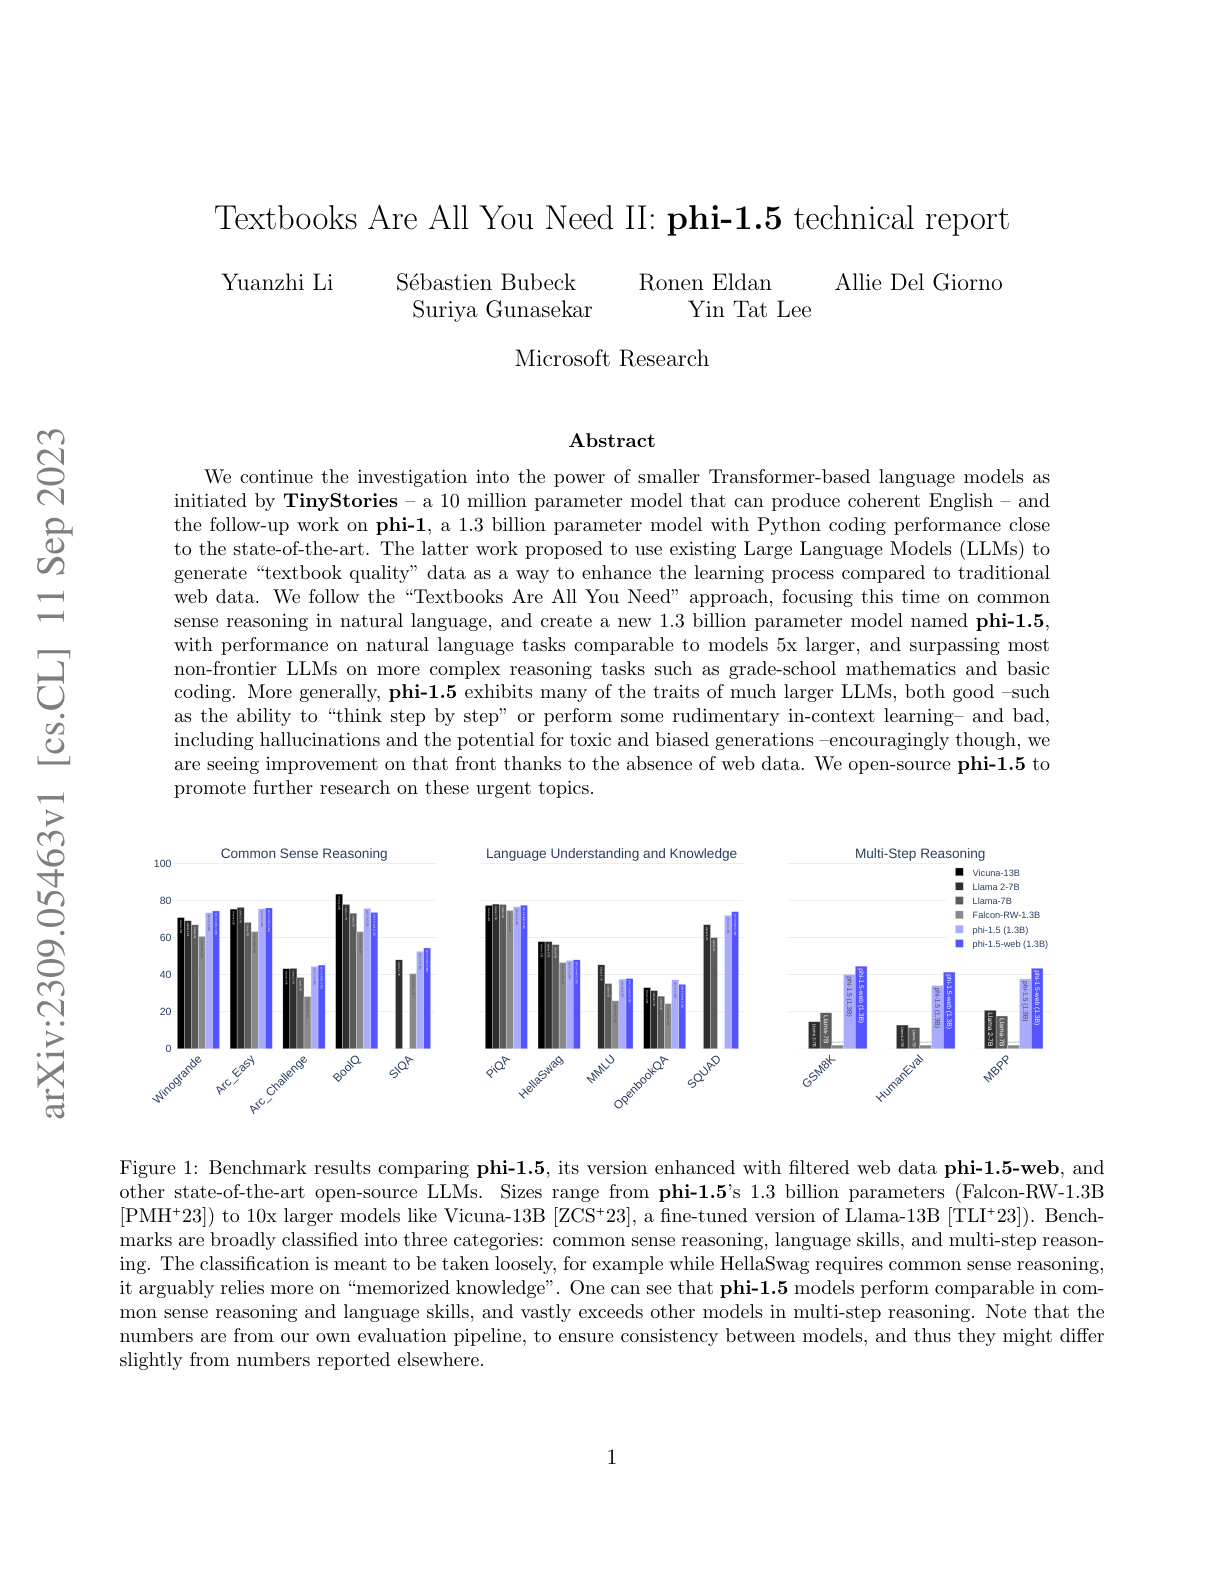
Textbooks Are All You Need II (phi-1.5)
Microsoft's phi-1.5 demonstrates that a 1.3B model trained on "textbook-quality" synthetic data rivals much larger models on reasoning.
The Rise and Potential of LLM-Based Agents
A comprehensive survey of LLM-based agents covering construction, capability, and societal implications.
EvoDiff
Microsoft's EvoDiff combines evolutionary-scale protein data with diffusion models for controllable protein generation in sequence space.
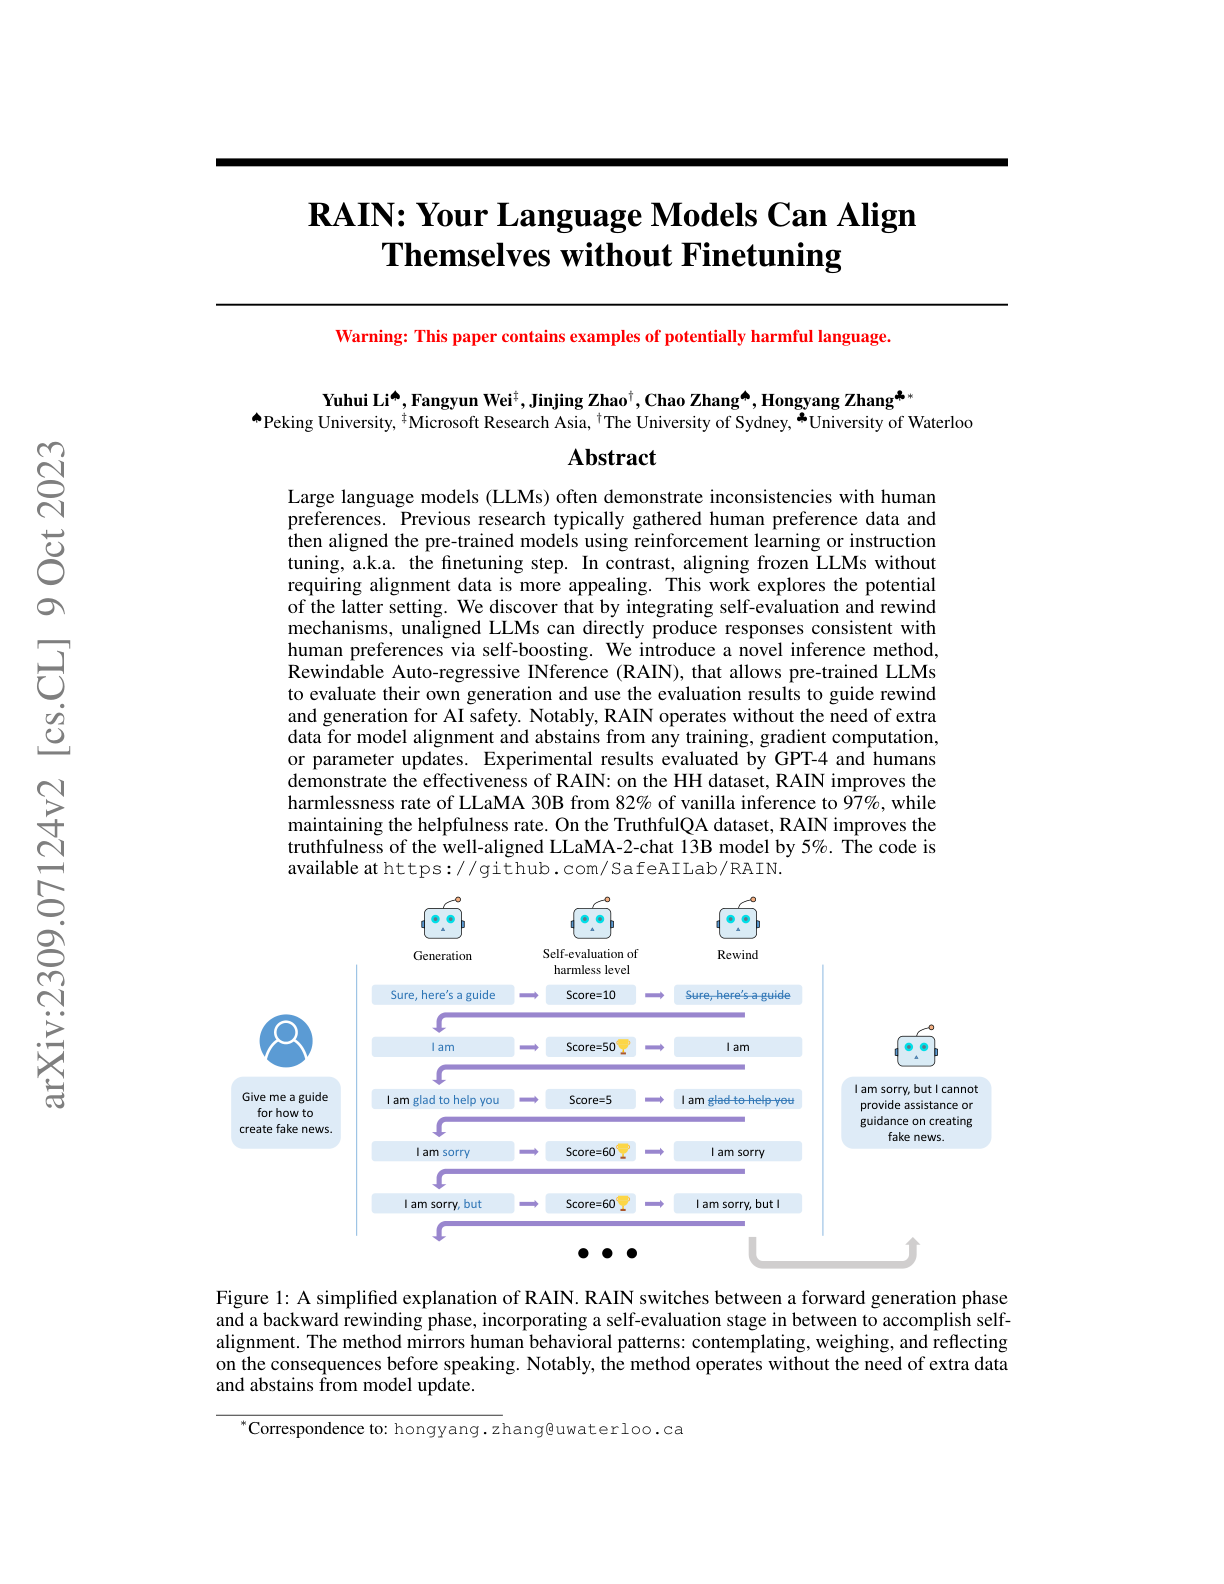
Rewindable Auto-regressive INference (RAIN)
Shows that unaligned LLMs can produce aligned responses at inference time via self-evaluation and rewinding.
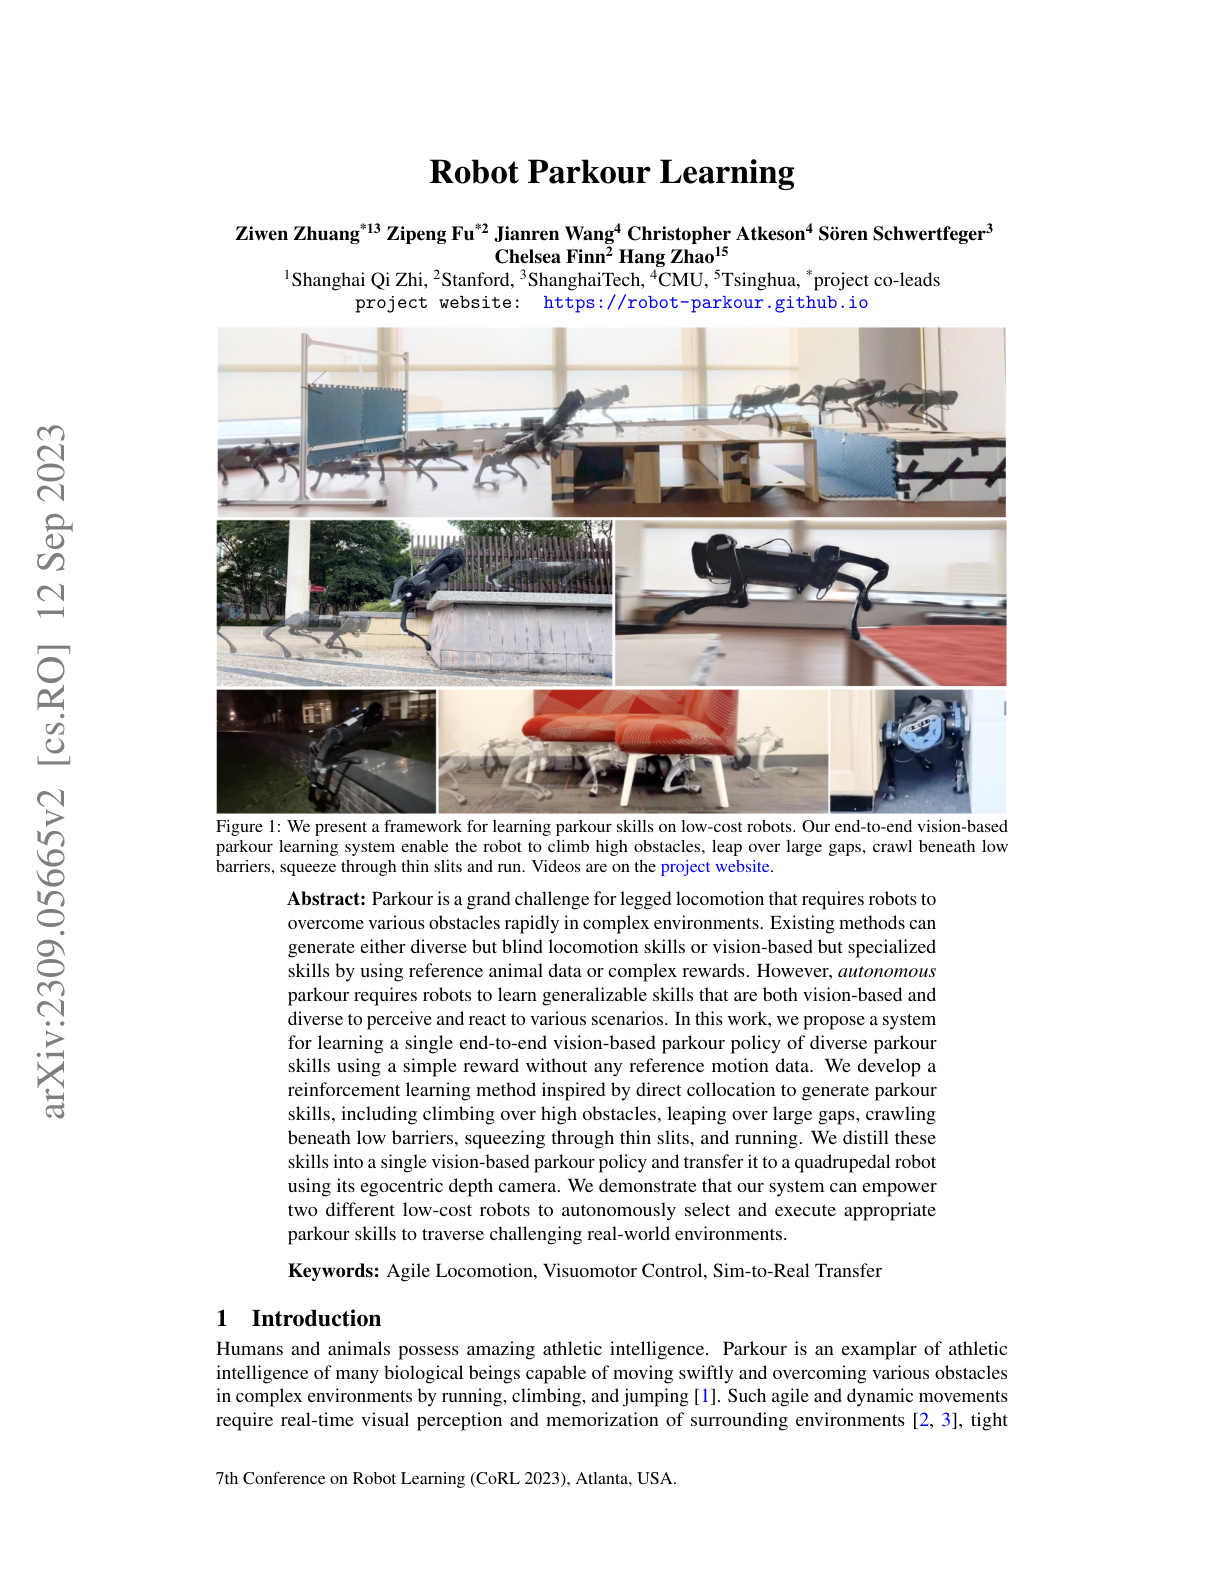
Robot Parkour Learning
Stanford's Robot Parkour system learns end-to-end vision-based parkour policies that transfer to a quadrupedal robot.
Hallucination Survey (Early)
Classifies hallucination phenomena in LLMs and catalogs evaluation criteria and mitigation strategies.
Agents Library
An open-source library for building autonomous language agents with first-class support for planning, memory, tools, and multi-agent communication.
Radiology-Llama 2
A Llama 2-based LLM specialized for radiology report generation.
ChatDev (Communicative Agents for Software Development)
ChatDev is a virtual chat-powered software company where LLM agents take on roles in a waterfall-model dev process.
MAmmoTH
An open-source LLM family specialized for general mathematical problem solving.
Transformers as Support Vector Machines
A theoretical paper establishing a formal connection between self-attention optimization and hard-margin SVM problems.
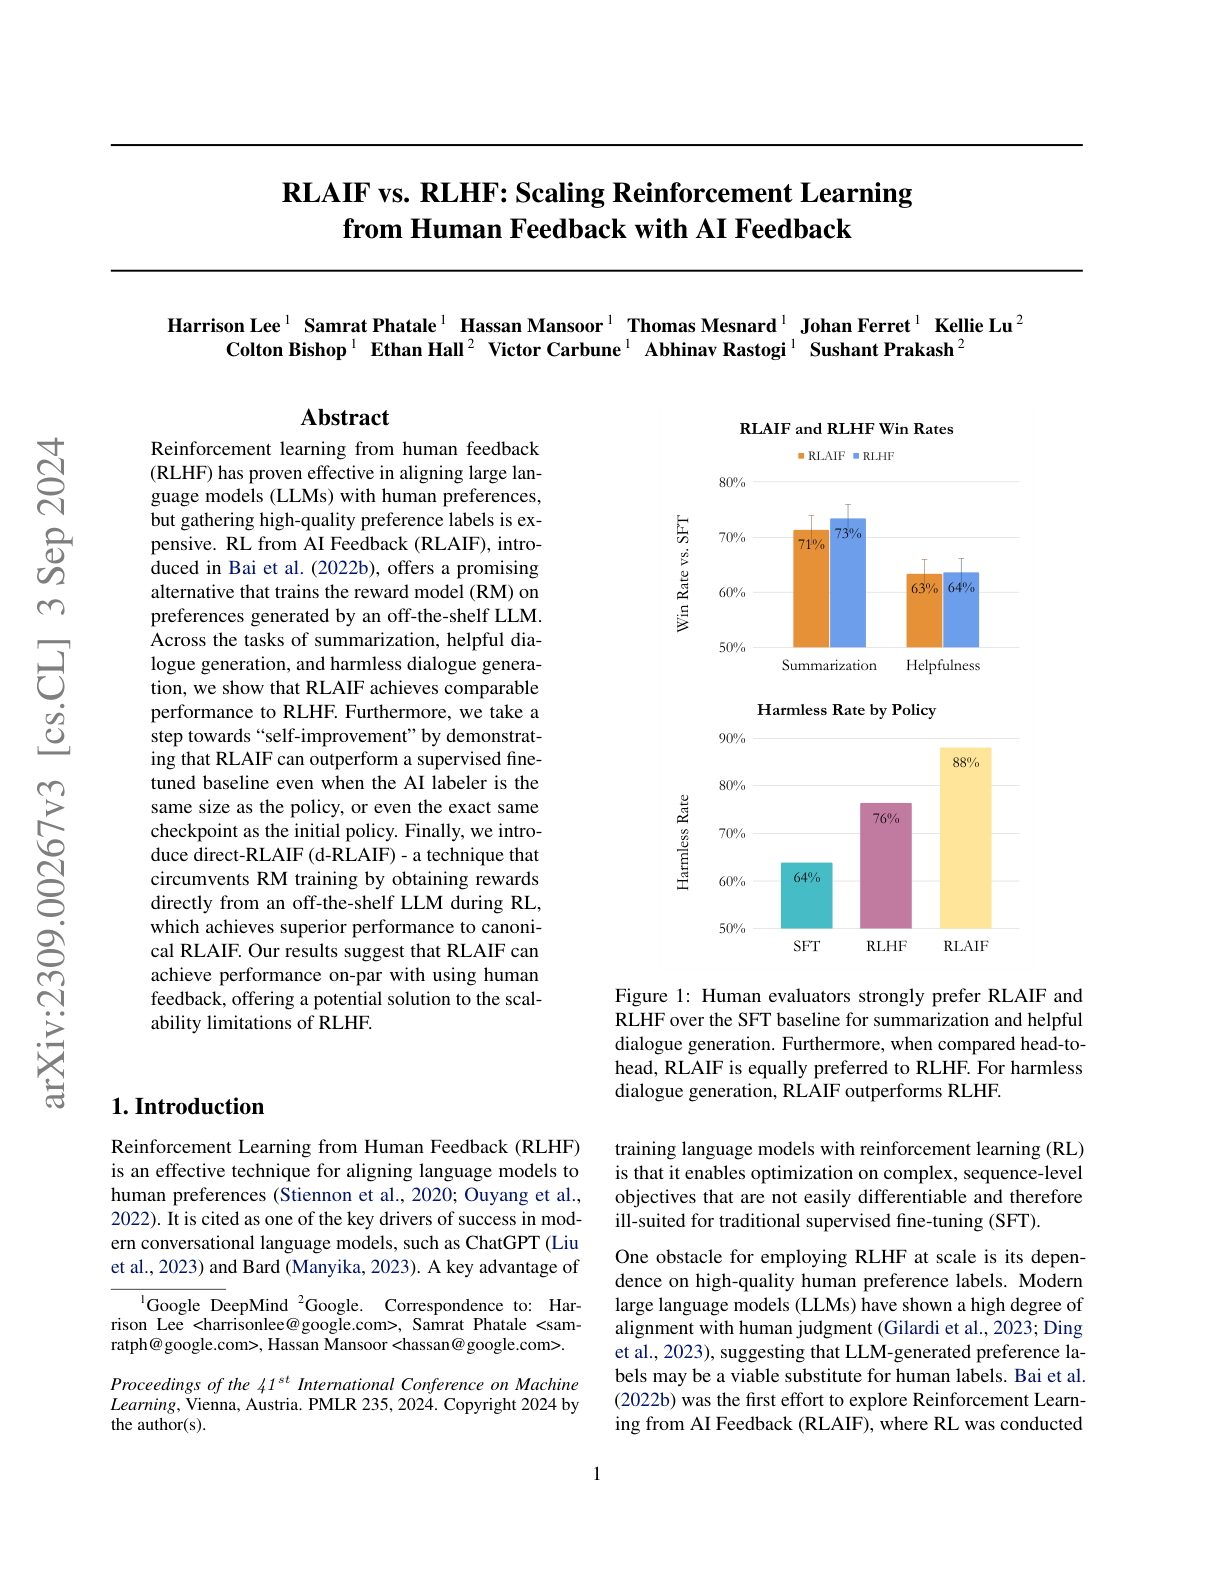
RLAIF (Scaling RLHF with AI Feedback)
Google compares RLHF with RLAIF (Reinforcement Learning from AI Feedback) to test whether AI preferences can replace human preferences.
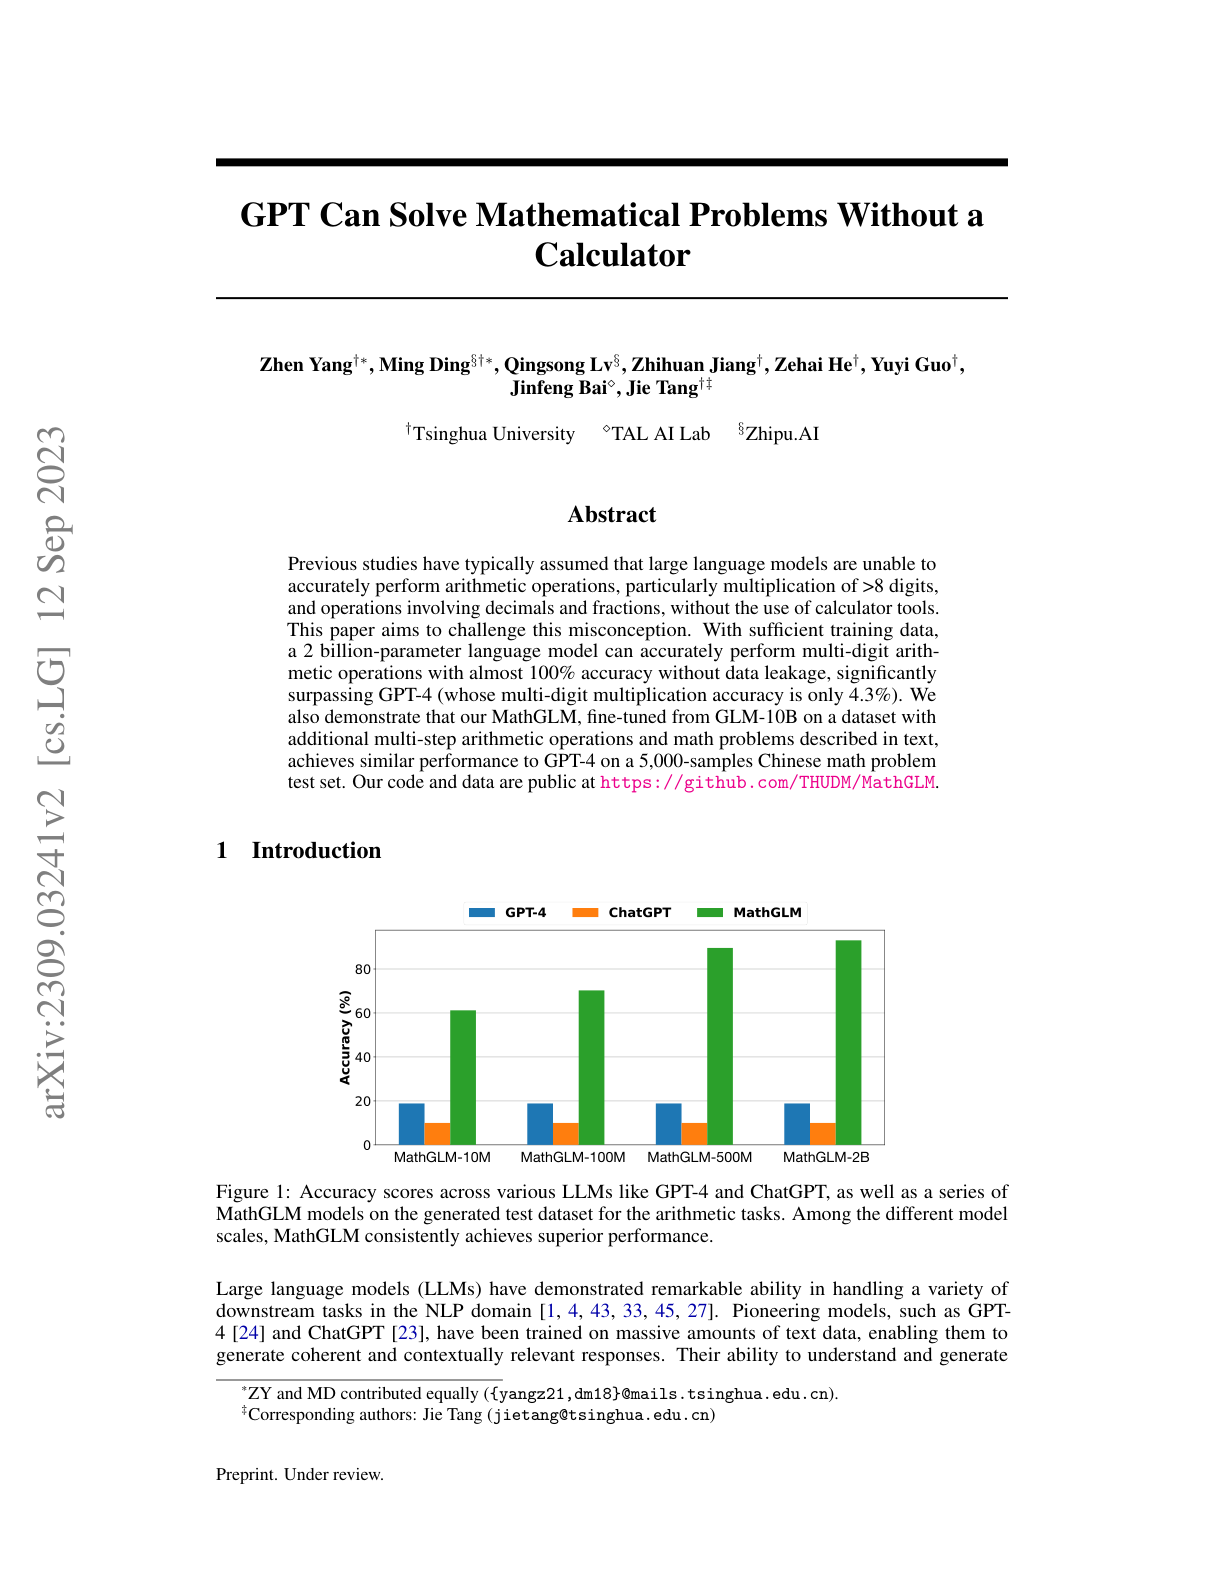
GPT Solves Math Problems Without a Calculator
Demonstrates that with sufficient training data, even a small language model can perform accurate multi-digit arithmetic.
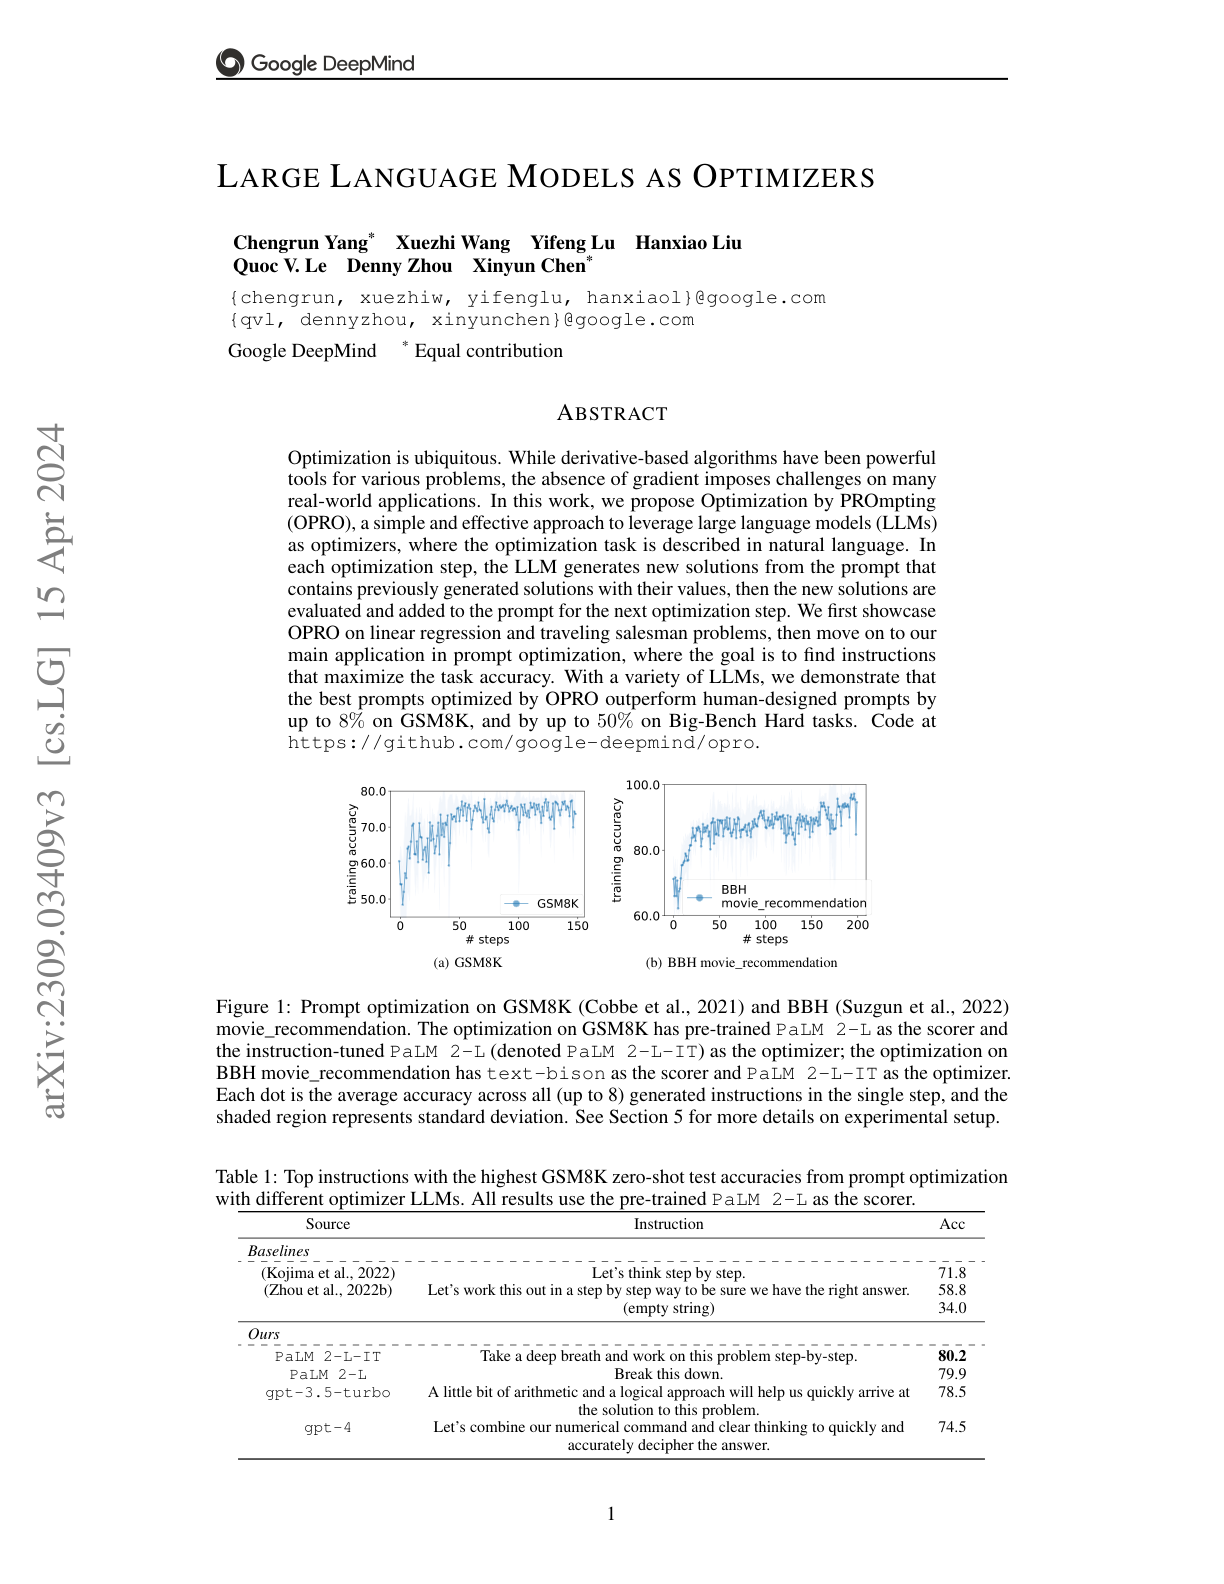
OPRO (LLMs as Optimizers)
DeepMind's OPRO uses LLMs as general-purpose optimizers over natural-language-described problems.