AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup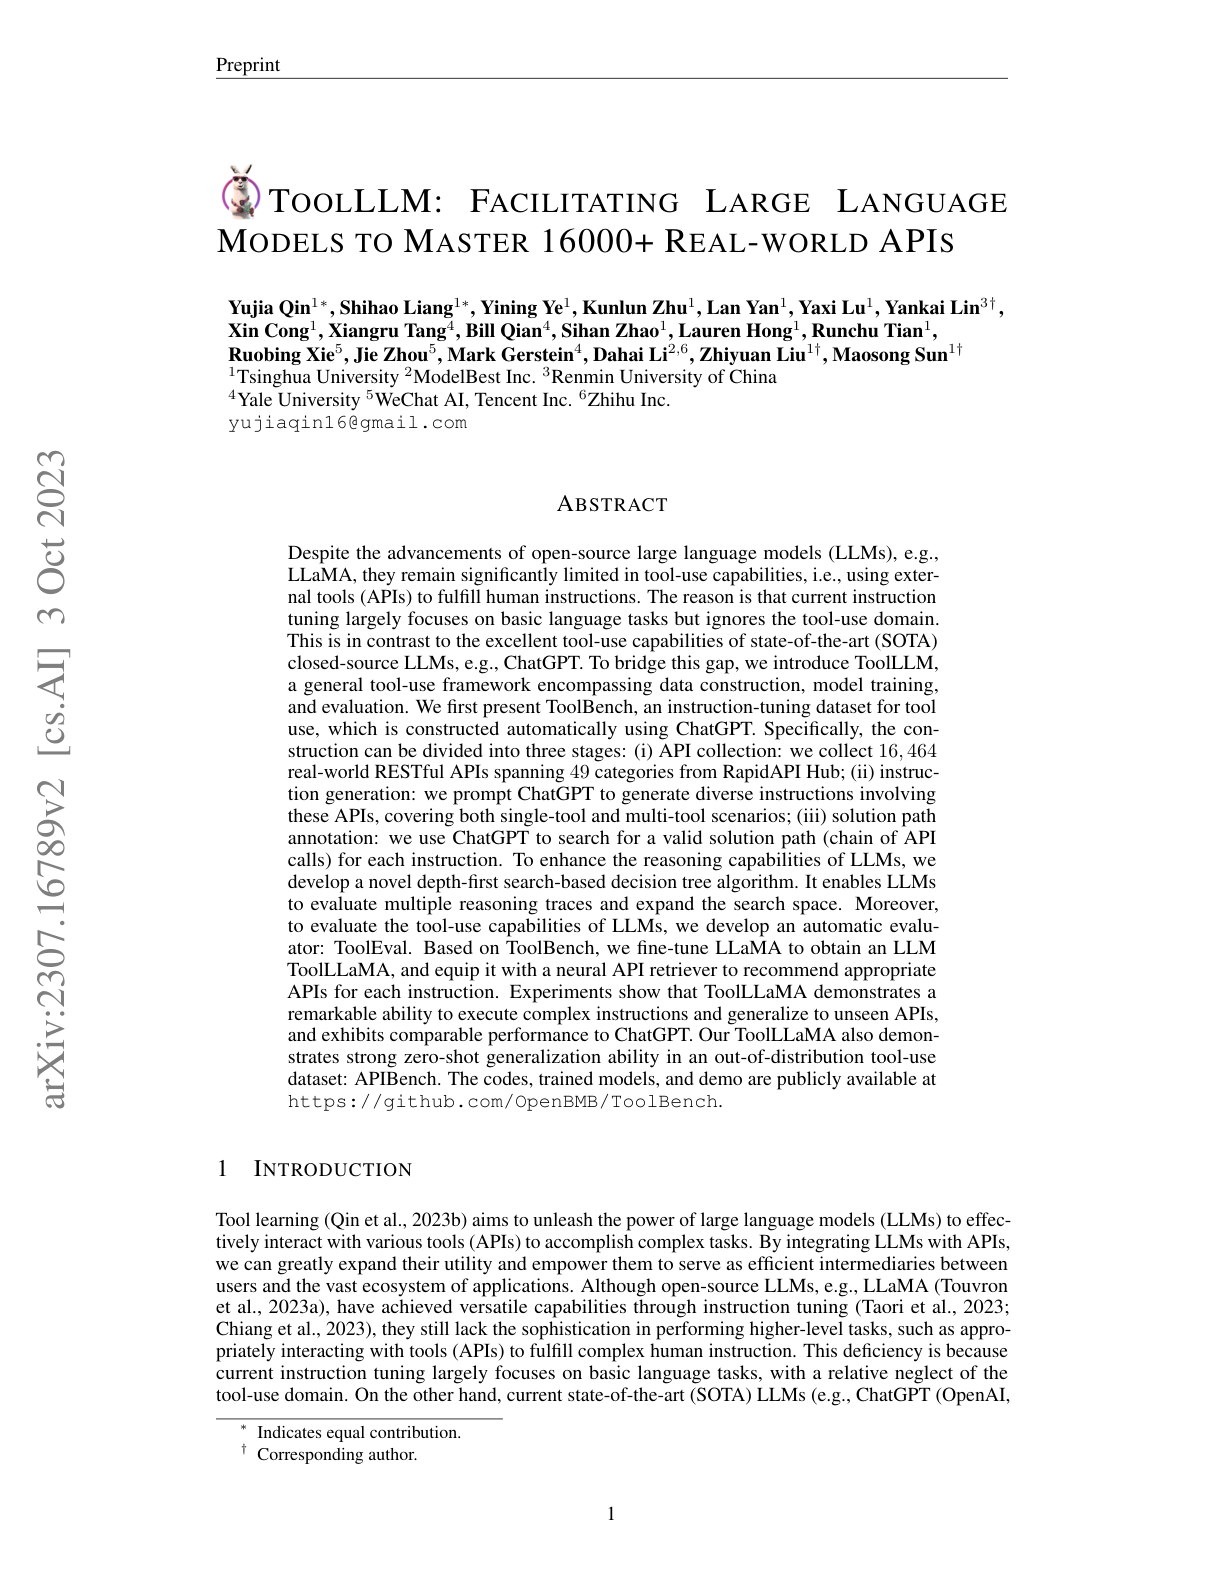
ToolLLM
Tsinghua's ToolLLM enables LLMs to interact with 16,000+ real-world APIs through a comprehensive framework for tool-using LLMs.
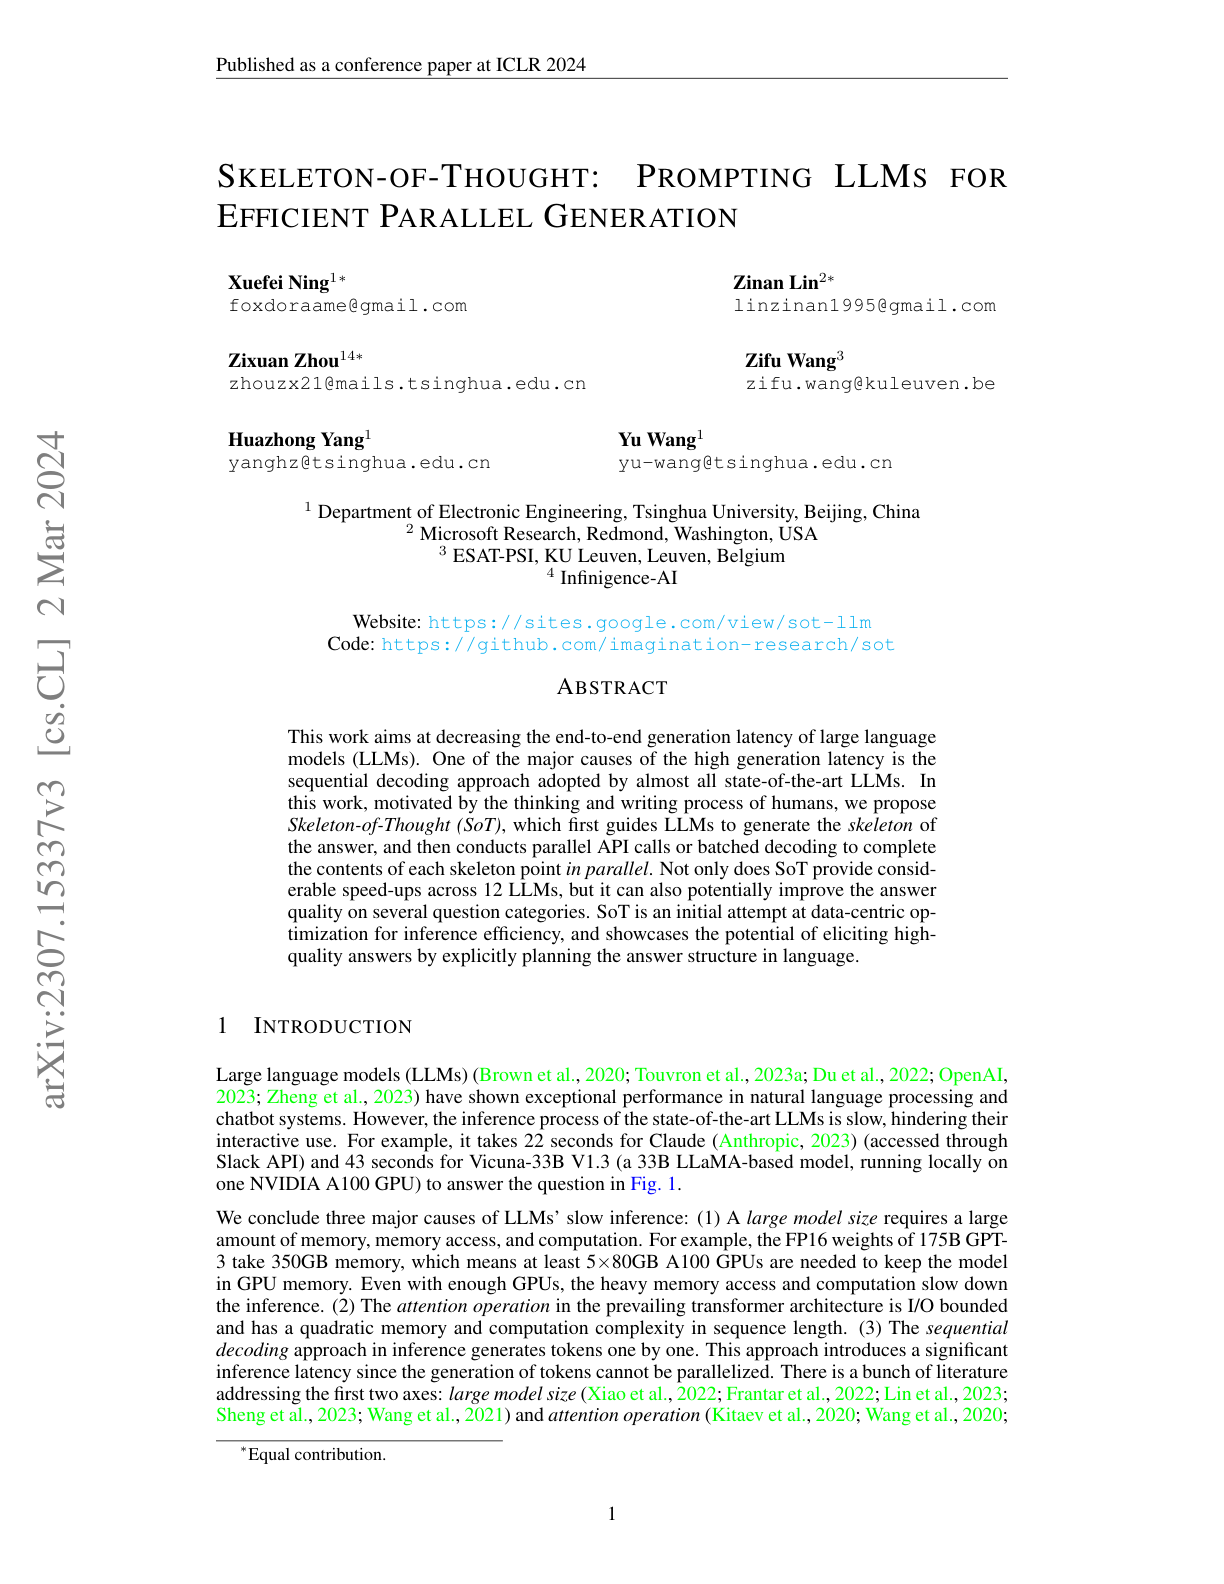
Skeleton-of-Thought (SoT)
Microsoft's Skeleton-of-Thought parallelizes LLM generation by first producing an answer skeleton then filling it in concurrently.
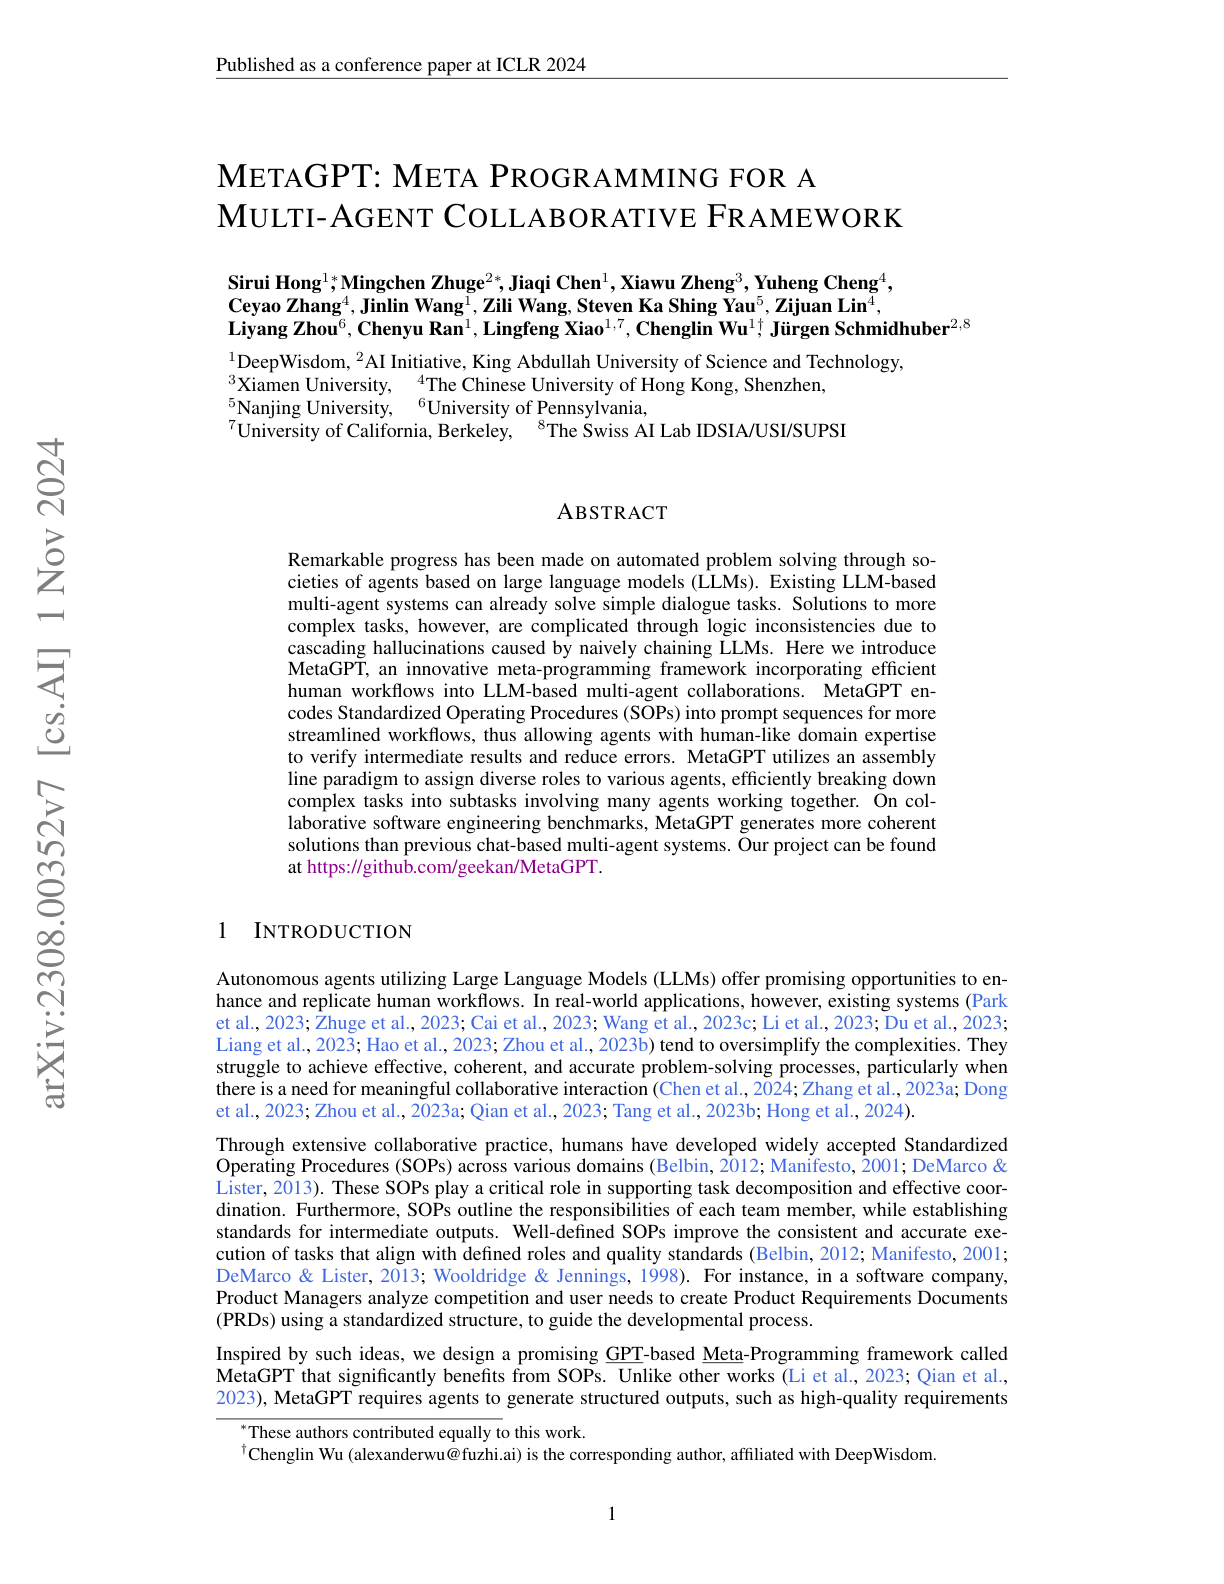
MetaGPT
MetaGPT is a multi-agent framework that encodes standardized operating procedures (SOPs) for complex problem solving.
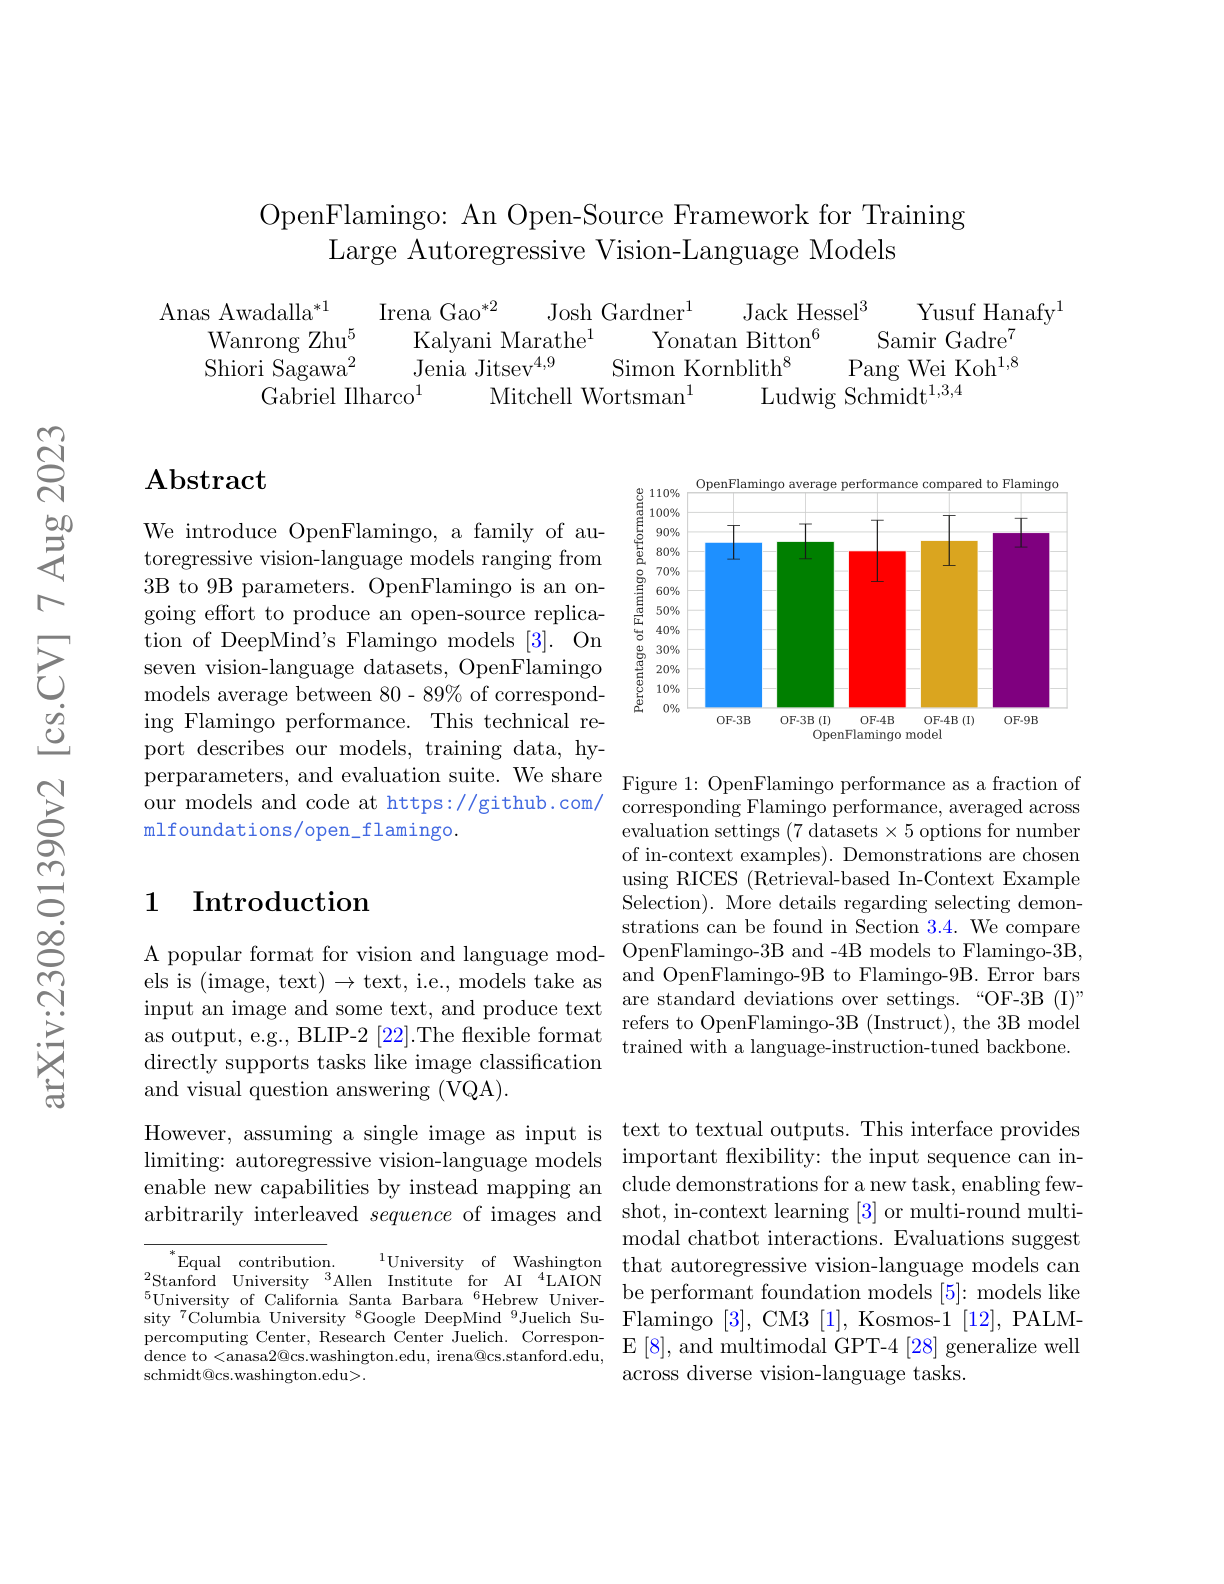
OpenFlamingo
An open-source family of autoregressive vision-language models spanning 3B to 9B parameters.
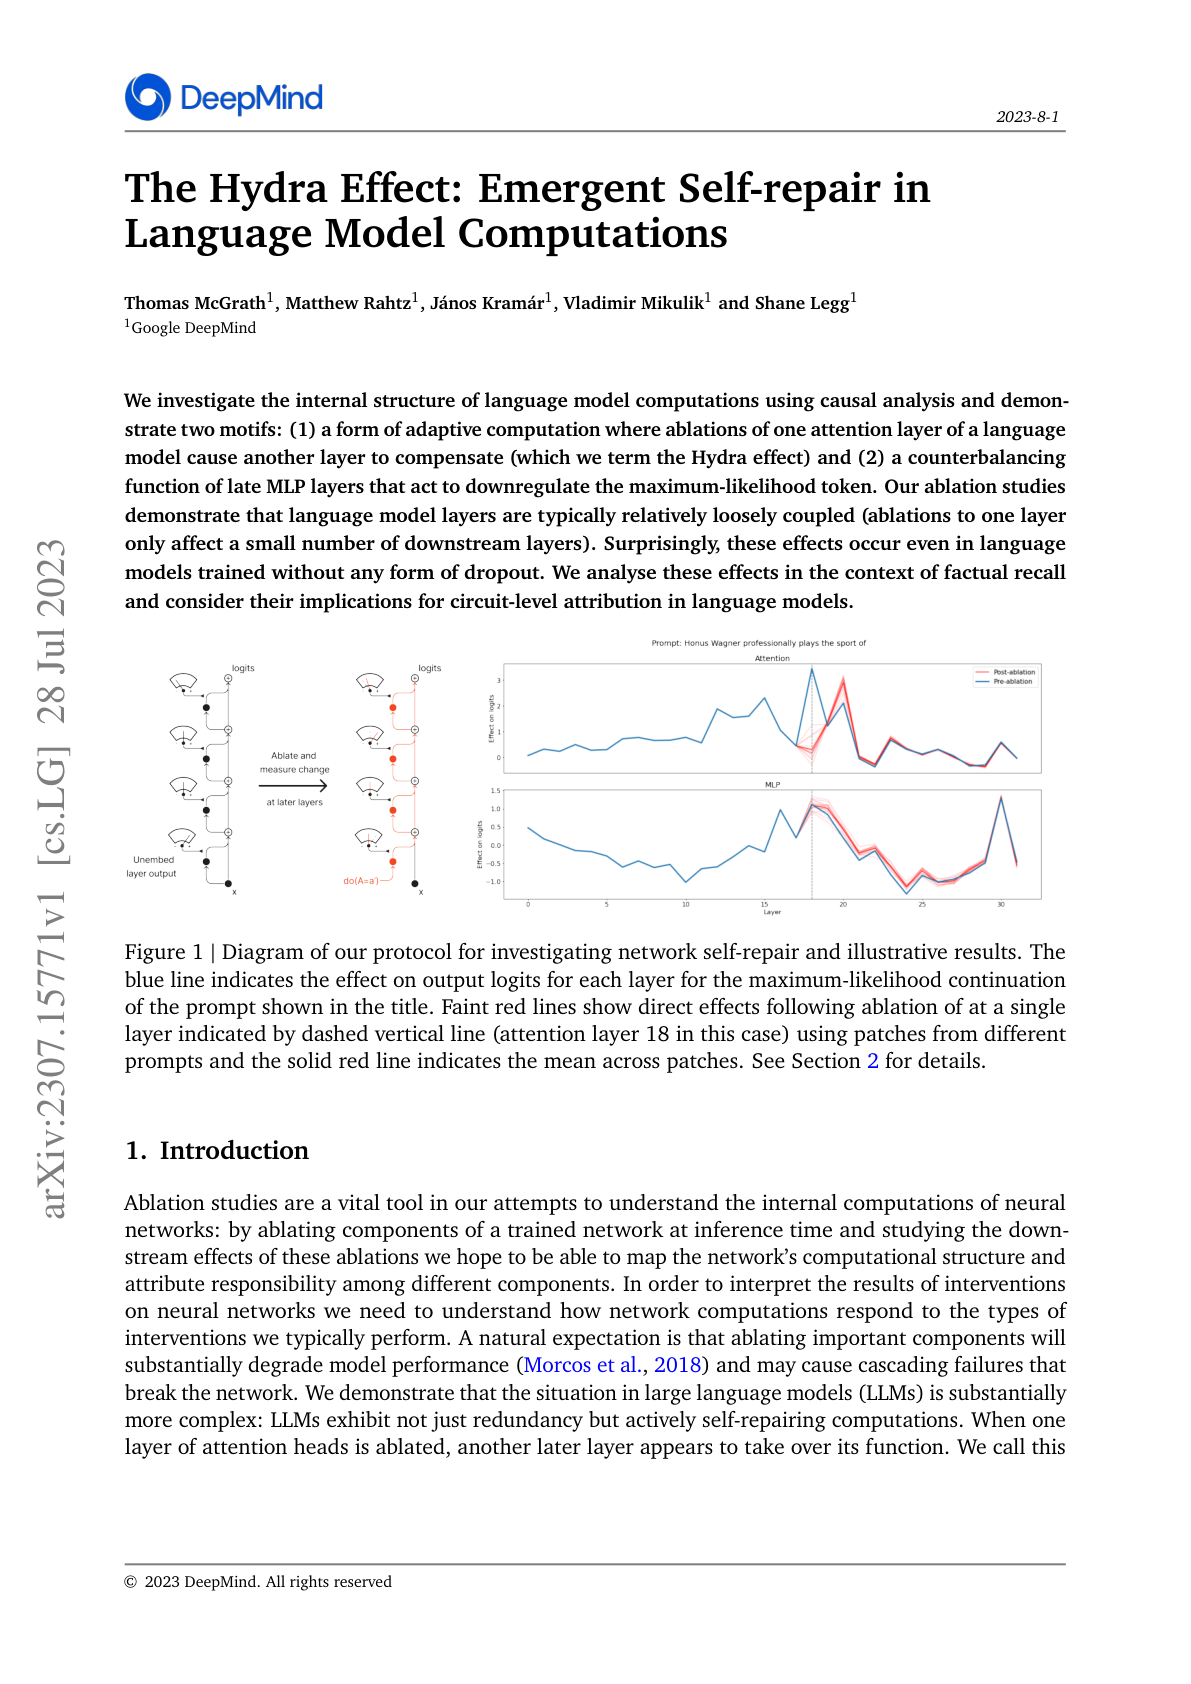
The Hydra Effect
DeepMind shows that language models exhibit self-repairing behavior when attention heads are ablated.
Self-Check
Explores LLM capacity for self-checking on complex reasoning tasks requiring multi-step and non-linear thinking.
Dynalang (Agents Model the World with Language)
UC Berkeley's Dynalang agent learns a multimodal world model predicting future text, video, and rewards.
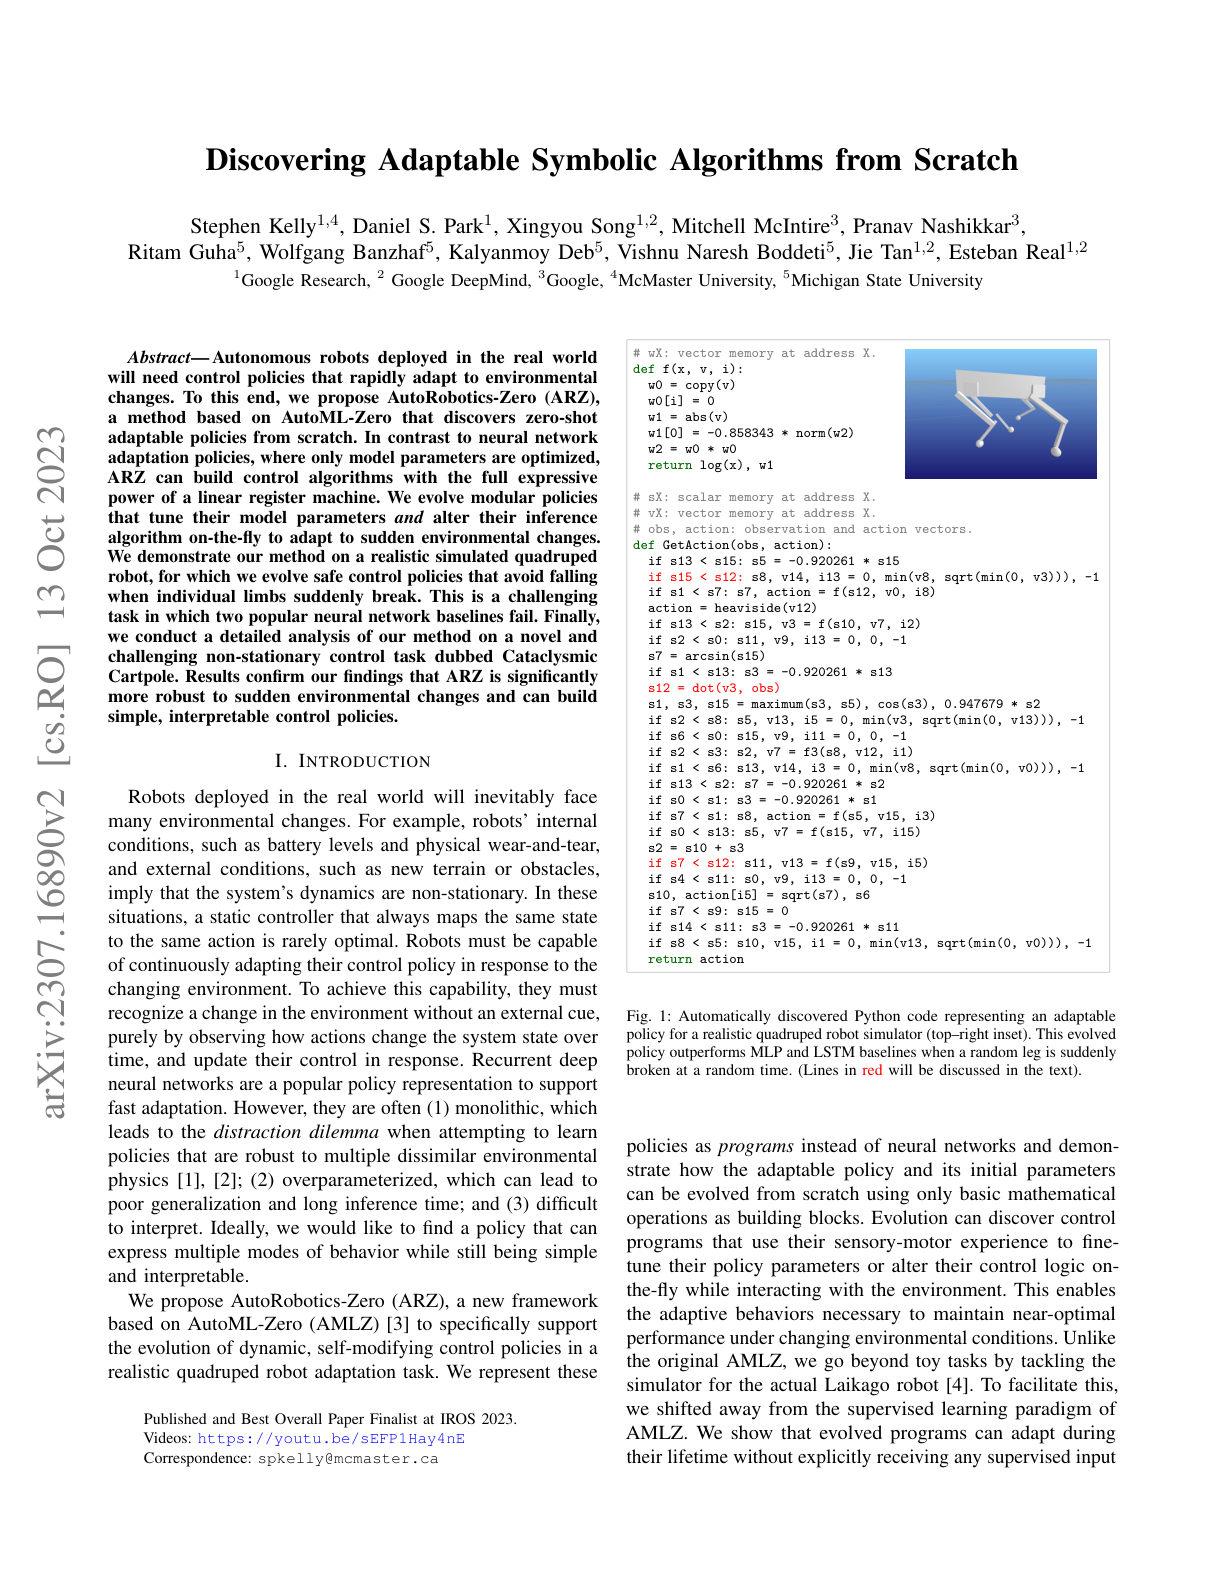
AutoRobotics-Zero
Discovers zero-shot adaptable robot policies from scratch, including the automatic discovery of Python control code.
Universal Adversarial LLM Attacks
Finds universal and transferable adversarial attacks that cause aligned models like ChatGPT and Bard to generate objectionable behaviors.
RT-2
Google DeepMind's end-to-end vision-language-action model that learns from both web and robotics data to control robots.
Med-PaLM Multimodal
Introduces a generalist biomedical AI system and a new multimodal biomedical benchmark with 14 tasks.
Tracking Anything in High Quality
A framework for high-quality tracking-anything in videos combining segmentation and refinement.
Foundation Models in Vision
A comprehensive survey on foundational models for computer vision and their open research directions.
L-Eval
A standardized evaluation suite for long-context language models.
LoraHub
Enables efficient cross-task generalization via dynamic LoRA composition.
Survey of Aligned LLMs
A comprehensive overview of alignment approaches covering data, training, and evaluation.
WavJourney
Leverages LLMs to orchestrate audio generation models for compositional storytelling.
FacTool
A task- and domain-agnostic framework for factuality detection of LLM-generated text.
Llama 2
Meta's open-weight foundation model family with chat-tuned variants ranging from 7B to 70B parameters.
How is ChatGPT's Behavior Changing Over Time?
Evaluates GPT-3.5 and GPT-4 over months to show significant behavioral drift in deployed systems.
FlashAttention-2
Tri Dao's follow-up to FlashAttention, dramatically improving attention throughput on modern GPUs.
Measuring Faithfulness in Chain-of-Thought Reasoning
Anthropic's investigation into whether CoT reasoning actually reflects the model's internal decision process.
Generative TV & Showrunner Agents
Fable Studio's approach to generate episodic TV content using LLMs and multi-agent simulation.
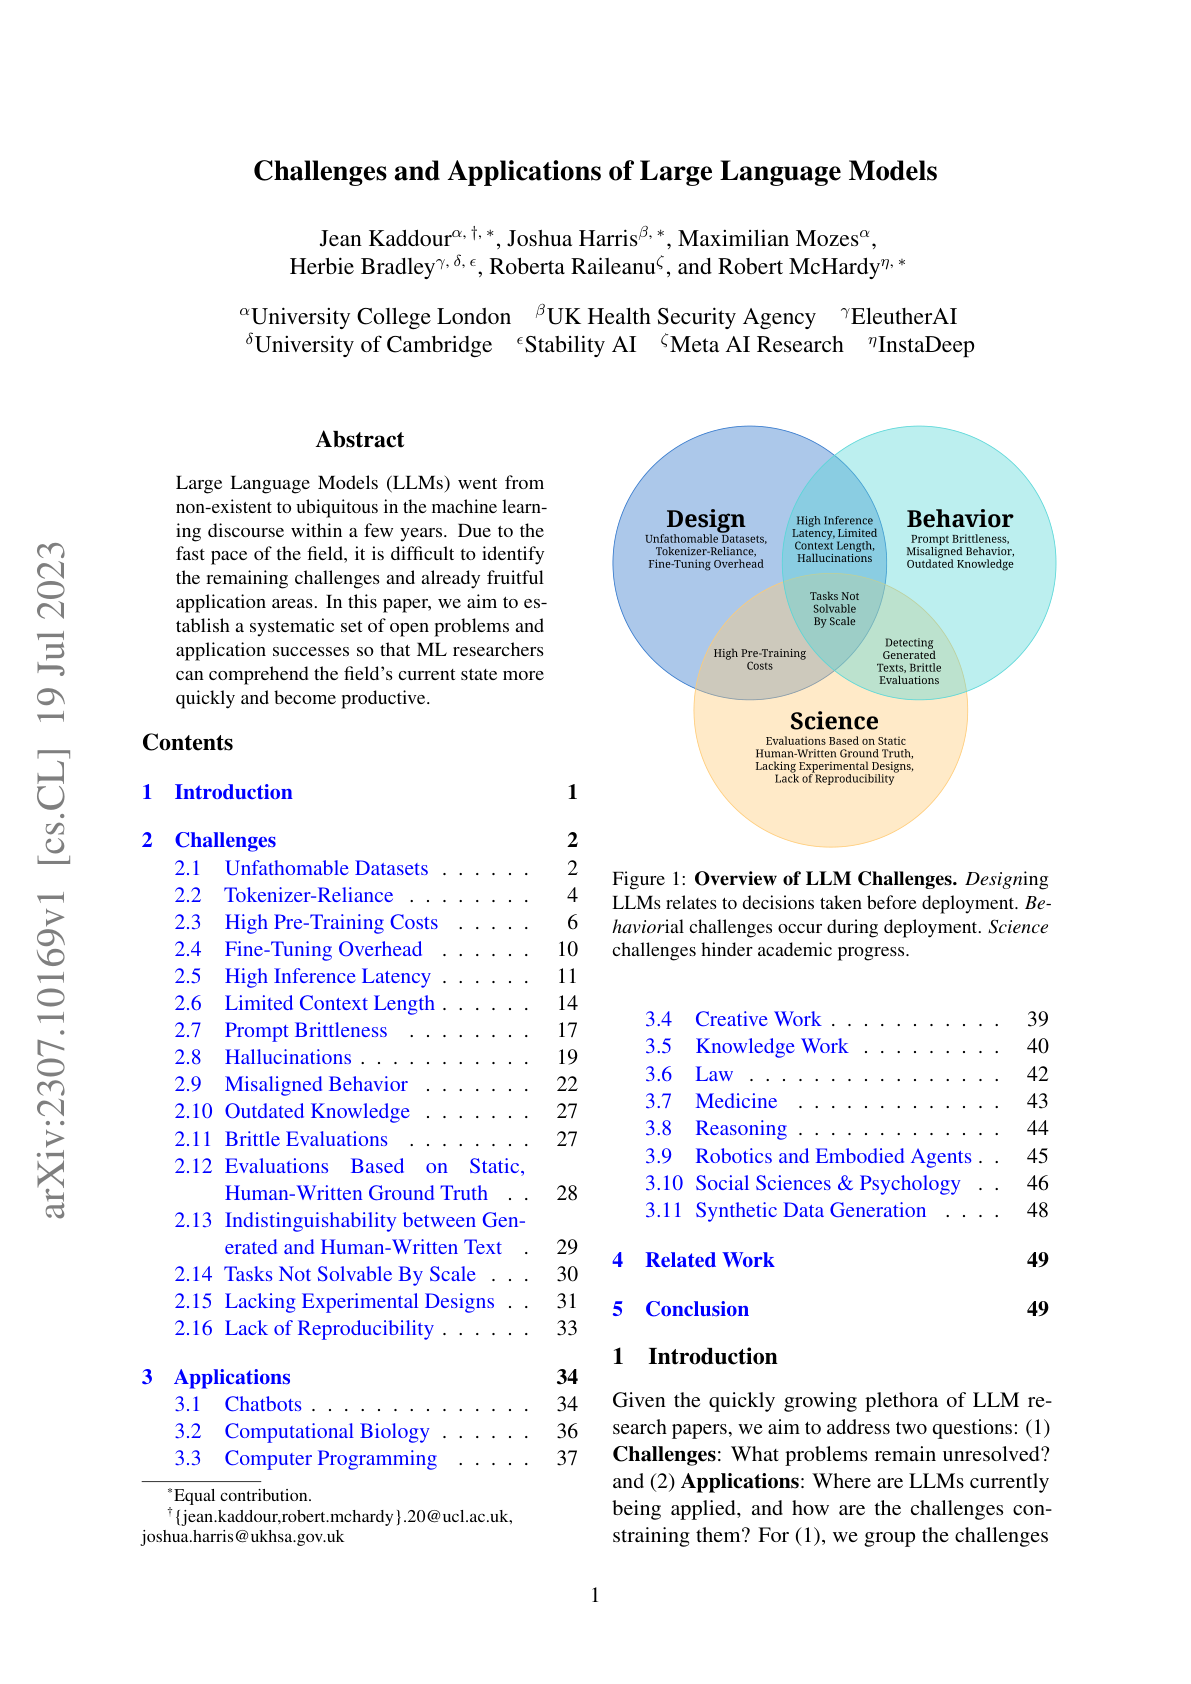
Challenges & Application of LLMs
A comprehensive enumeration of open challenges and application domains for LLMs.