AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
Discover and explore top AI papers with Claude Code or Codex
npx @dair-ai/mcp setup
LegalBench
A collaboratively constructed benchmark for measuring legal reasoning in LLMs.
Language to Rewards for Robotic Skill Synthesis
Google's Language-to-Rewards uses LLMs to define reward parameters for robotic RL.
Humpback (Self-Alignment with Instruction Backtranslation)
Meta's Humpback automatically generates instruction-tuning data by back-translating web text into plausible instructions.
Platypus
Platypus is a family of fine-tuned and merged LLMs that topped the Open LLM Leaderboard in August 2023.
Model Compression for LLMs Survey
A survey of recent model-compression techniques applied specifically to LLMs.
GEARS
Stanford's GEARS predicts cellular responses to genetic perturbation using deep learning + a gene-relationship knowledge graph.
Shepherd
Meta's Shepherd is a 7B language model specifically tuned to critique model outputs and suggest refinements.
GPT-4 Code Interpreter for Math
A zero-shot prompting technique for GPT-4 Code Interpreter that dramatically boosts math-reasoning accuracy via code self-verification.
Teach LLMs to Personalize
A multitask-learning approach for personalized text generation without relying on predefined user attributes.
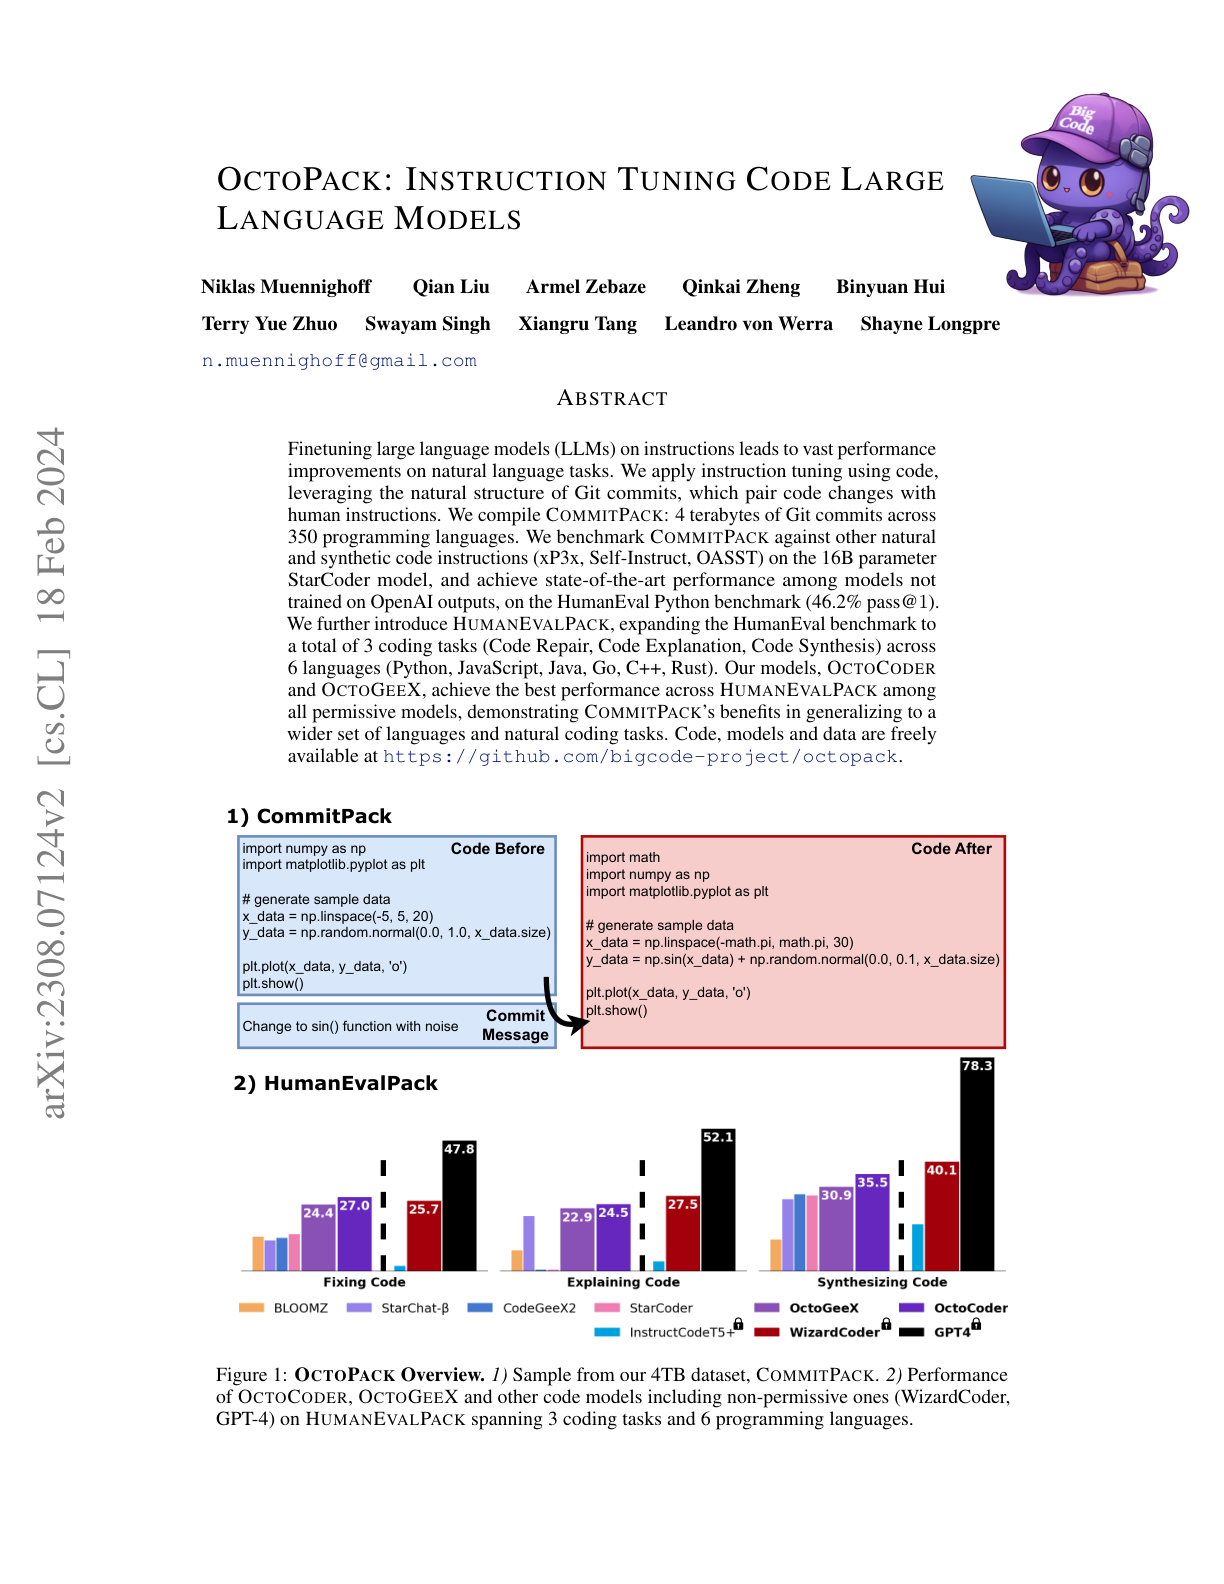
OctoPack
Hugging Face releases OctoPack, a 4TB dataset of Git commits across 350 programming languages for instruction-tuning code LLMs.
Outlines (Efficient Guided Generation)
A library for guided LLM text generation that enforces structural constraints with minimal overhead.
Bayesian Flow Networks (BFN)
Introduces a new class of generative models that combine Bayesian inference with deep learning.
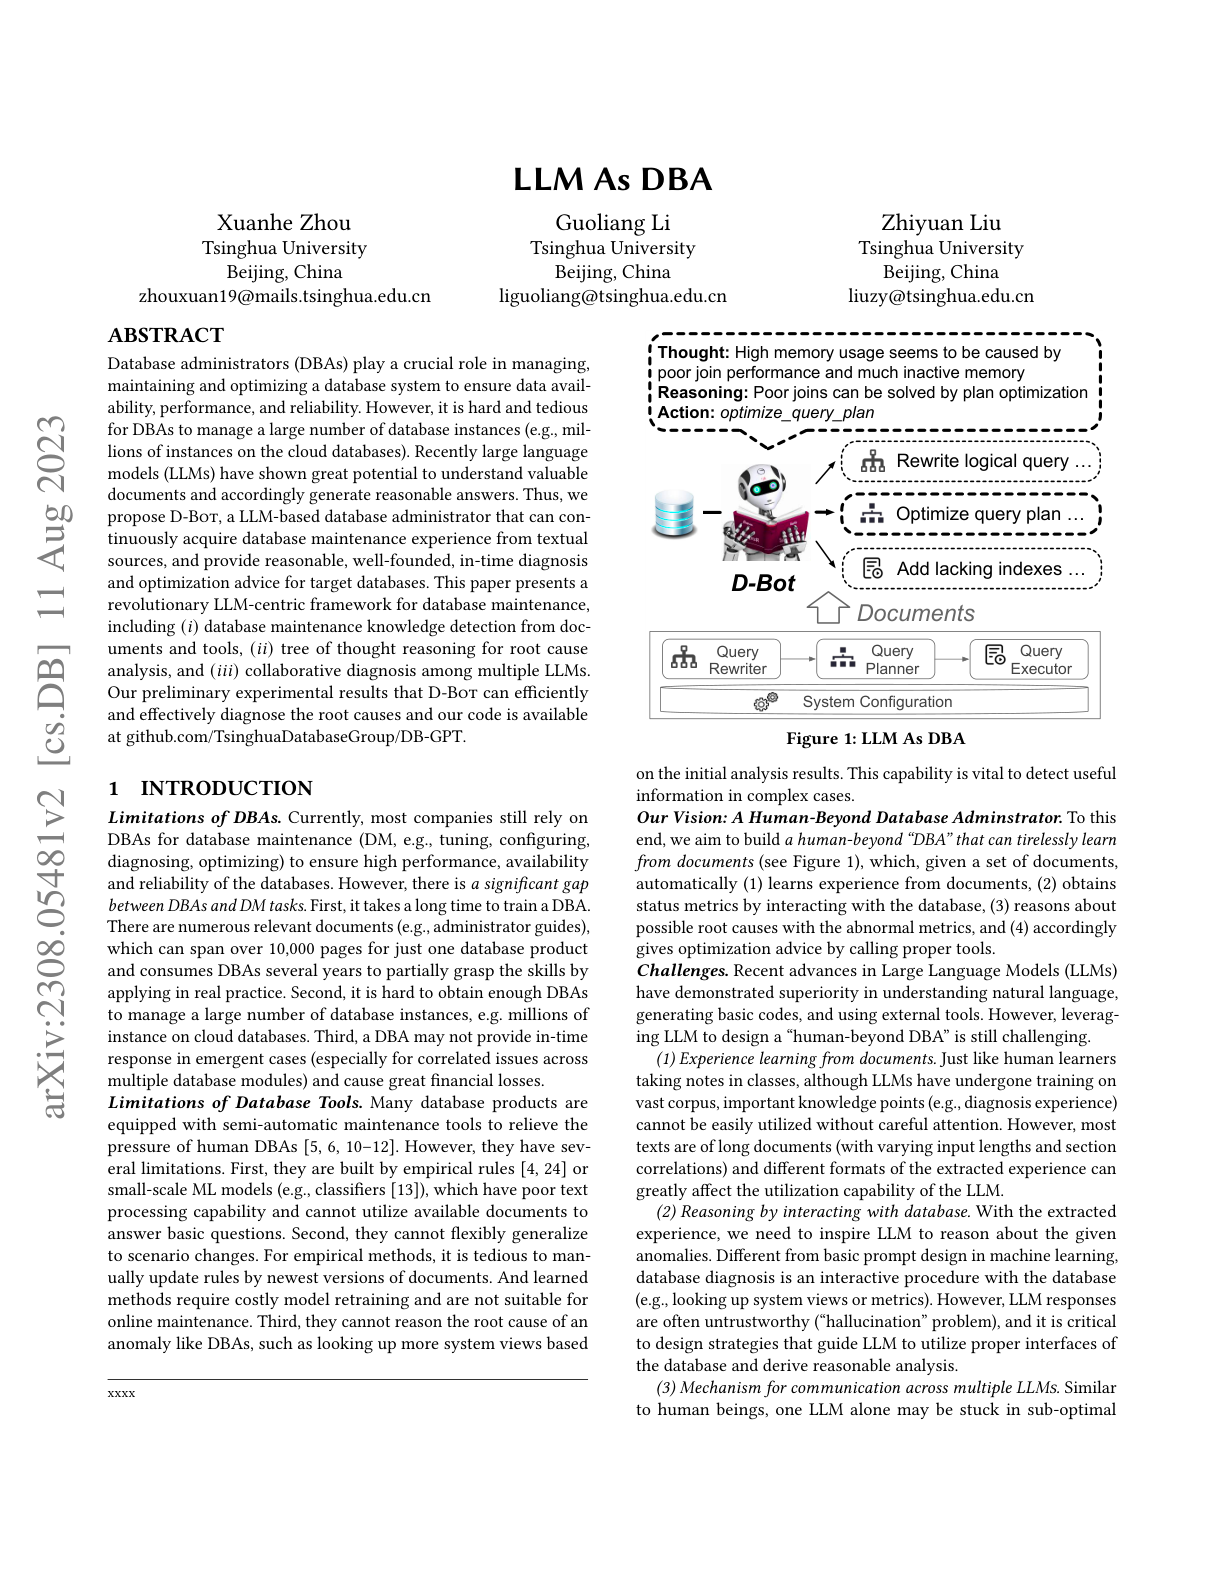
D-Bot (LLMs as Database Administrators)
Introduces D-Bot, an LLM-based framework that continuously acquires database-administration knowledge from textual sources.
Political Biases in NLP Models
Develops methods to measure political and media biases in LLMs and their downstream effects.
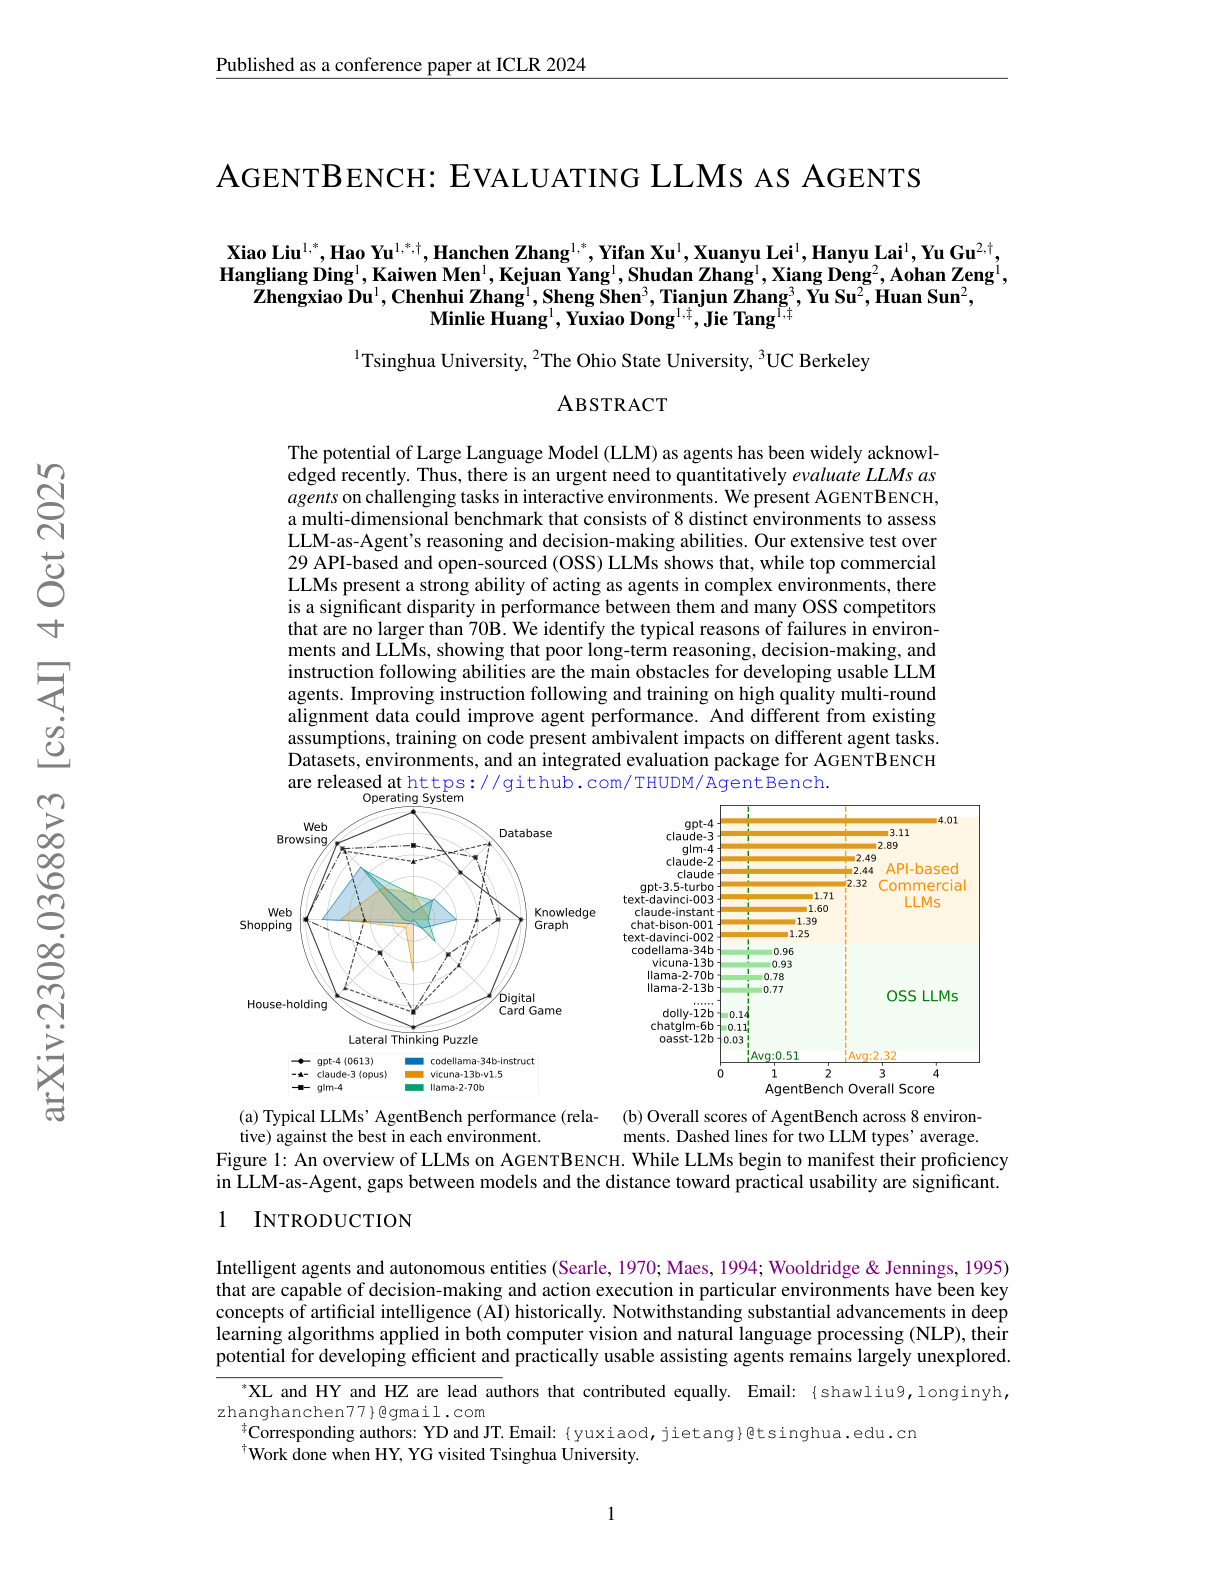
AgentBench
Tsinghua's AgentBench is a multidimensional benchmark for LLM-as-Agent reasoning and decision-making across 8 environments.
Studying LLM Generalization with Influence Functions
Anthropic scales influence functions to LLMs up to 52B parameters to investigate generalization patterns.
NeuroImagen
Reconstructs visual stimuli images from EEG signals using latent diffusion, opening new windows into visually-evoked brain activity.
SynJax
DeepMind's SynJax is a JAX-based library for efficient vectorized inference in structured distributions.
Synthetic Data Reduces Sycophancy
Google shows that fine-tuning on simple synthetic data can significantly reduce LLM sycophancy.
PUG (Photorealistic Unreal Graphics)
Meta's PUG uses Unreal Engine to generate photorealistic, semantically controllable synthetic datasets for vision research.
LLMs for HVAC Control
Microsoft applies LLMs to industrial control tasks (HVAC for buildings), comparing against RL baselines.
Trustworthy LLMs
Presents a comprehensive framework of categories for assessing LLM trustworthiness.
Open Problems and Limitations of RLHF
A comprehensive survey of open problems and fundamental limitations of RLHF as an alignment approach.
Med-Flamingo
Stanford's Med-Flamingo is a multimodal medical model supporting in-context learning for few-shot medical visual QA.