AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
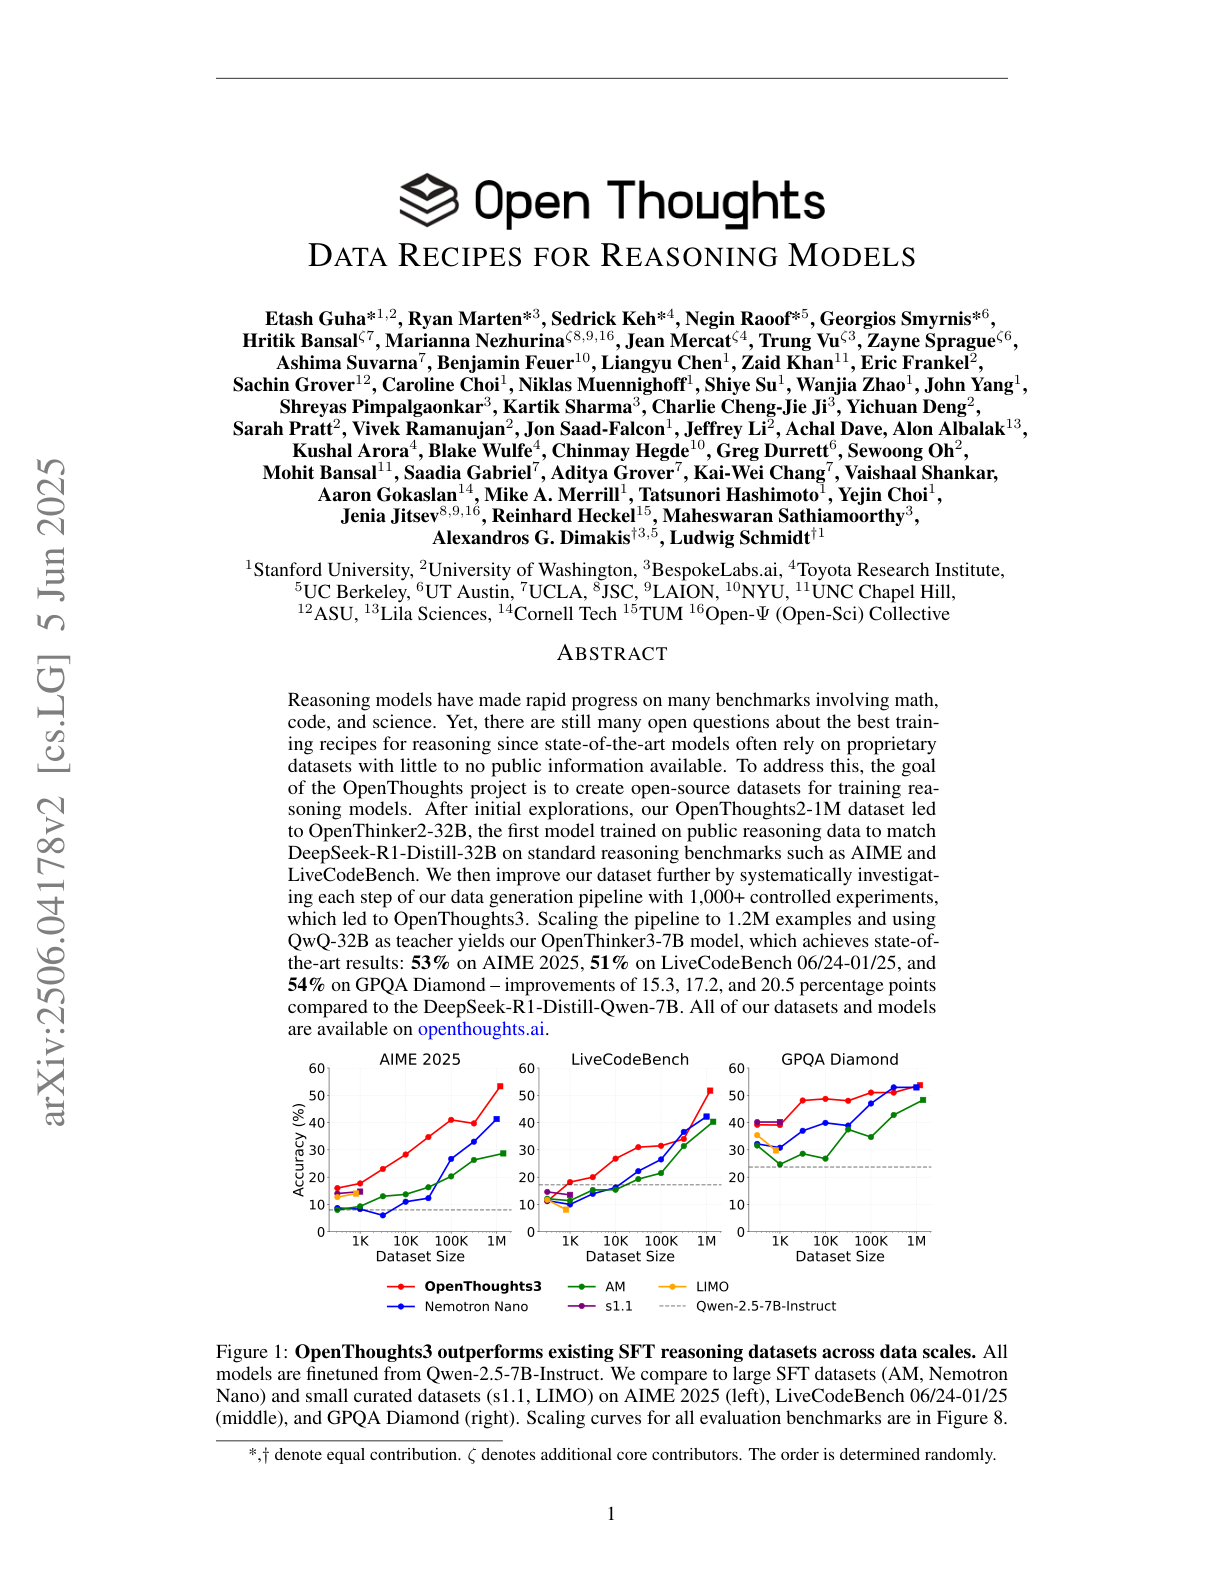
Open Thoughts
This paper presents OpenThoughts3, a systematic recipe for curating supervised fine-tuning (SFT) data that advances the performance of open-source reasoning models. The authors develop OpenThinker3-7B, a 7B parameter model trained on their new 1.2M example dataset (OpenThoughts3-1.2M) derived from over 1,000 controlled experiments. Despite using no reinforcement learning, OpenThinker3-7B outperforms all other open-data 7B and 8B models on standard math, code, and science reasoning benchmarks, even beating models trained with larger-scale or mixed SFT+RL pipelines. Key insights and contributions:
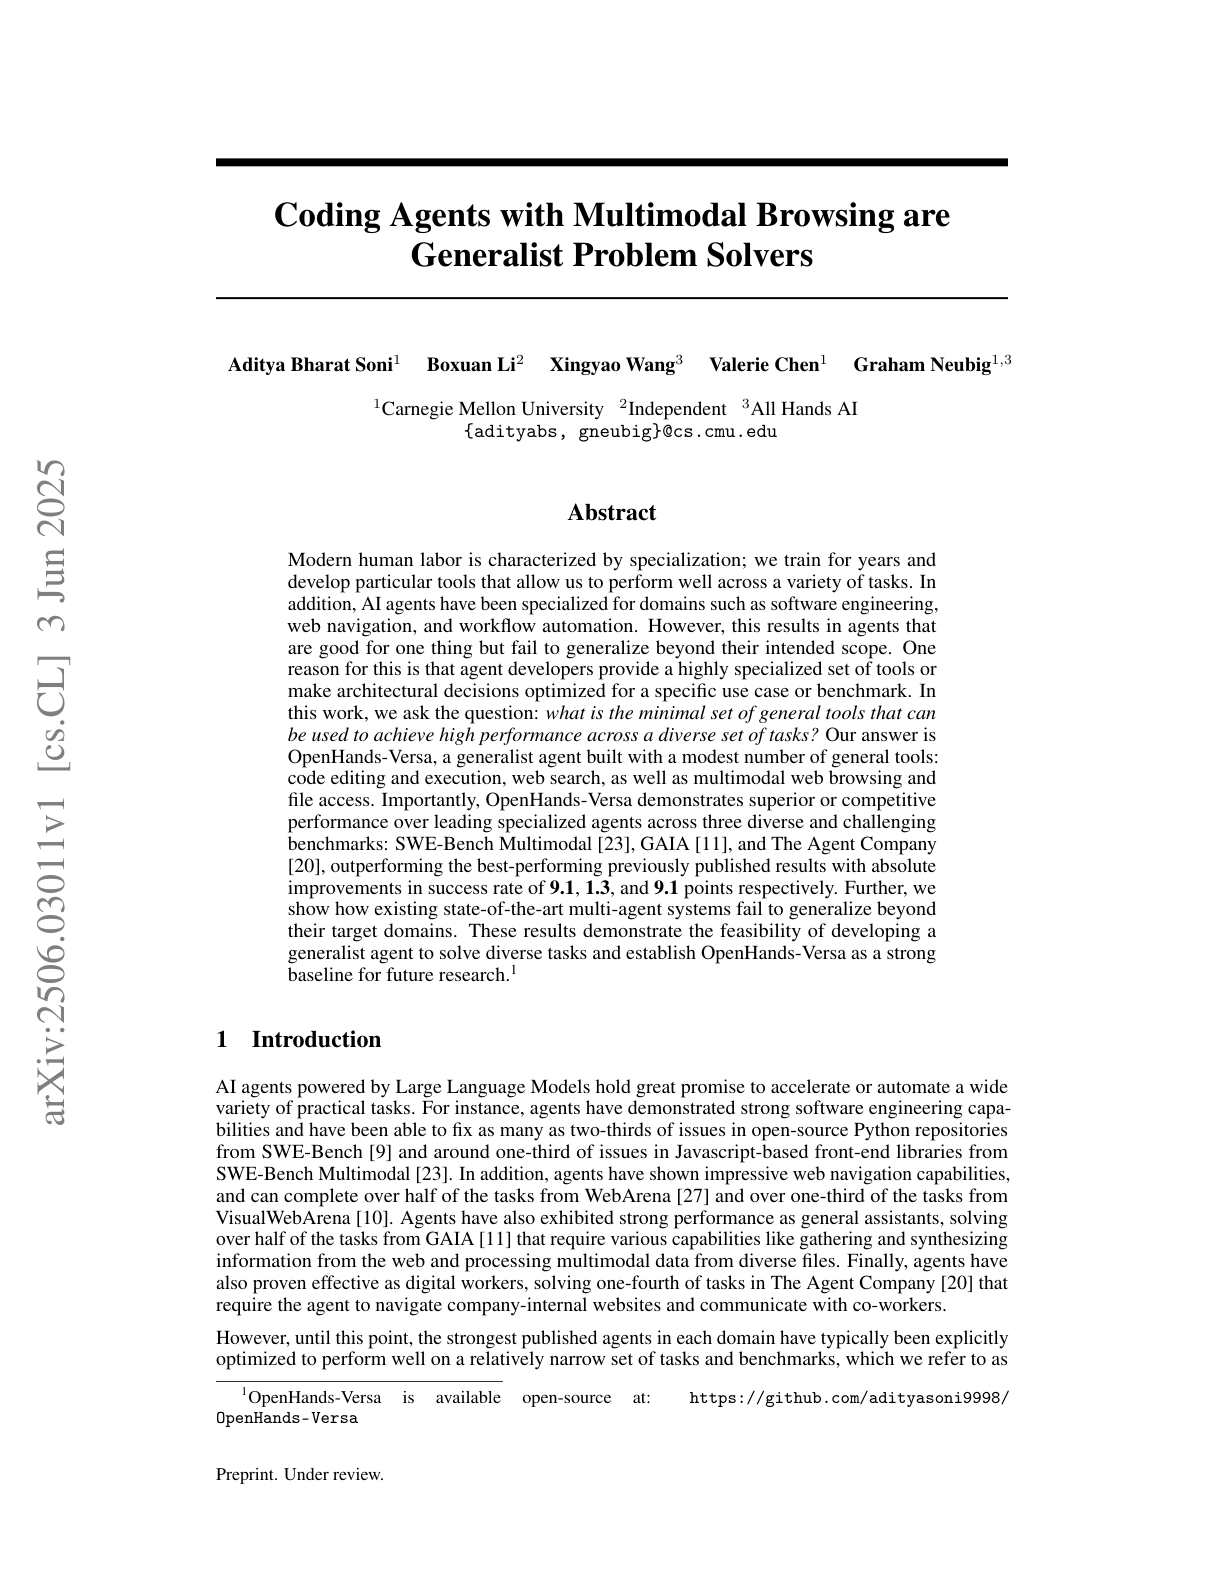
Coding Agents with Multimodal Browsing
Introduces OpenHands-Versa, a unified agent designed to perform strongly across diverse domains, coding, web browsing, and multimodal information access, by equipping a single agent with three general capabilities: code execution, multimodal web browsing, and file/search access. In contrast to specialist or multi-agent systems optimized for narrow domains, OpenHands-Versa aims to solve a wide variety of real-world tasks with minimal architectural complexity. Key highlights:
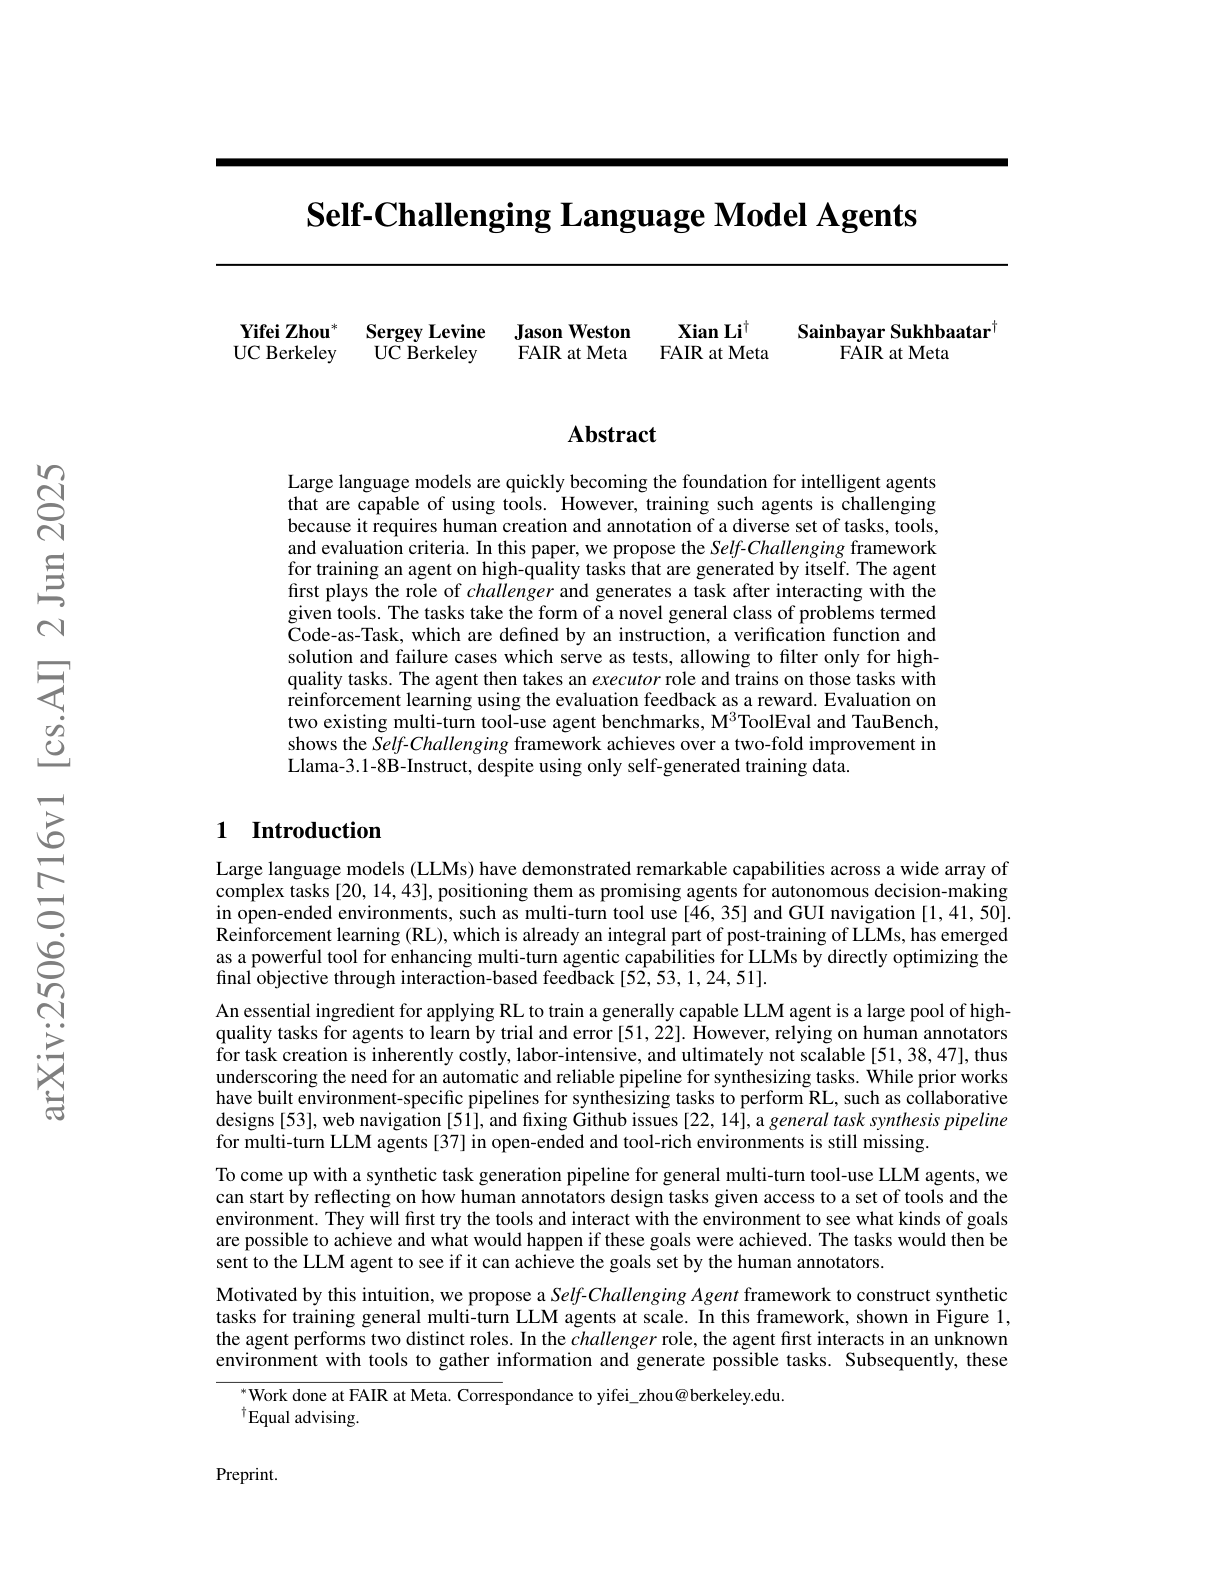
Self-Challenging Language Model Agents
Proposes a novel self-improvement method for multi-turn tool-use LLM agents, called the Self-Challenging Agent (SCA). It trains LLMs entirely from tasks they generate themselves, avoiding the need for human-annotated tasks or evaluations. The framework introduces a new task format called Code-as-Task (CaT), ensuring generated tasks are feasible, verifiable, and challenging. SCA is shown to double performance in a self-improvement setting and significantly boost performance in distillation. Key contributions and findings:
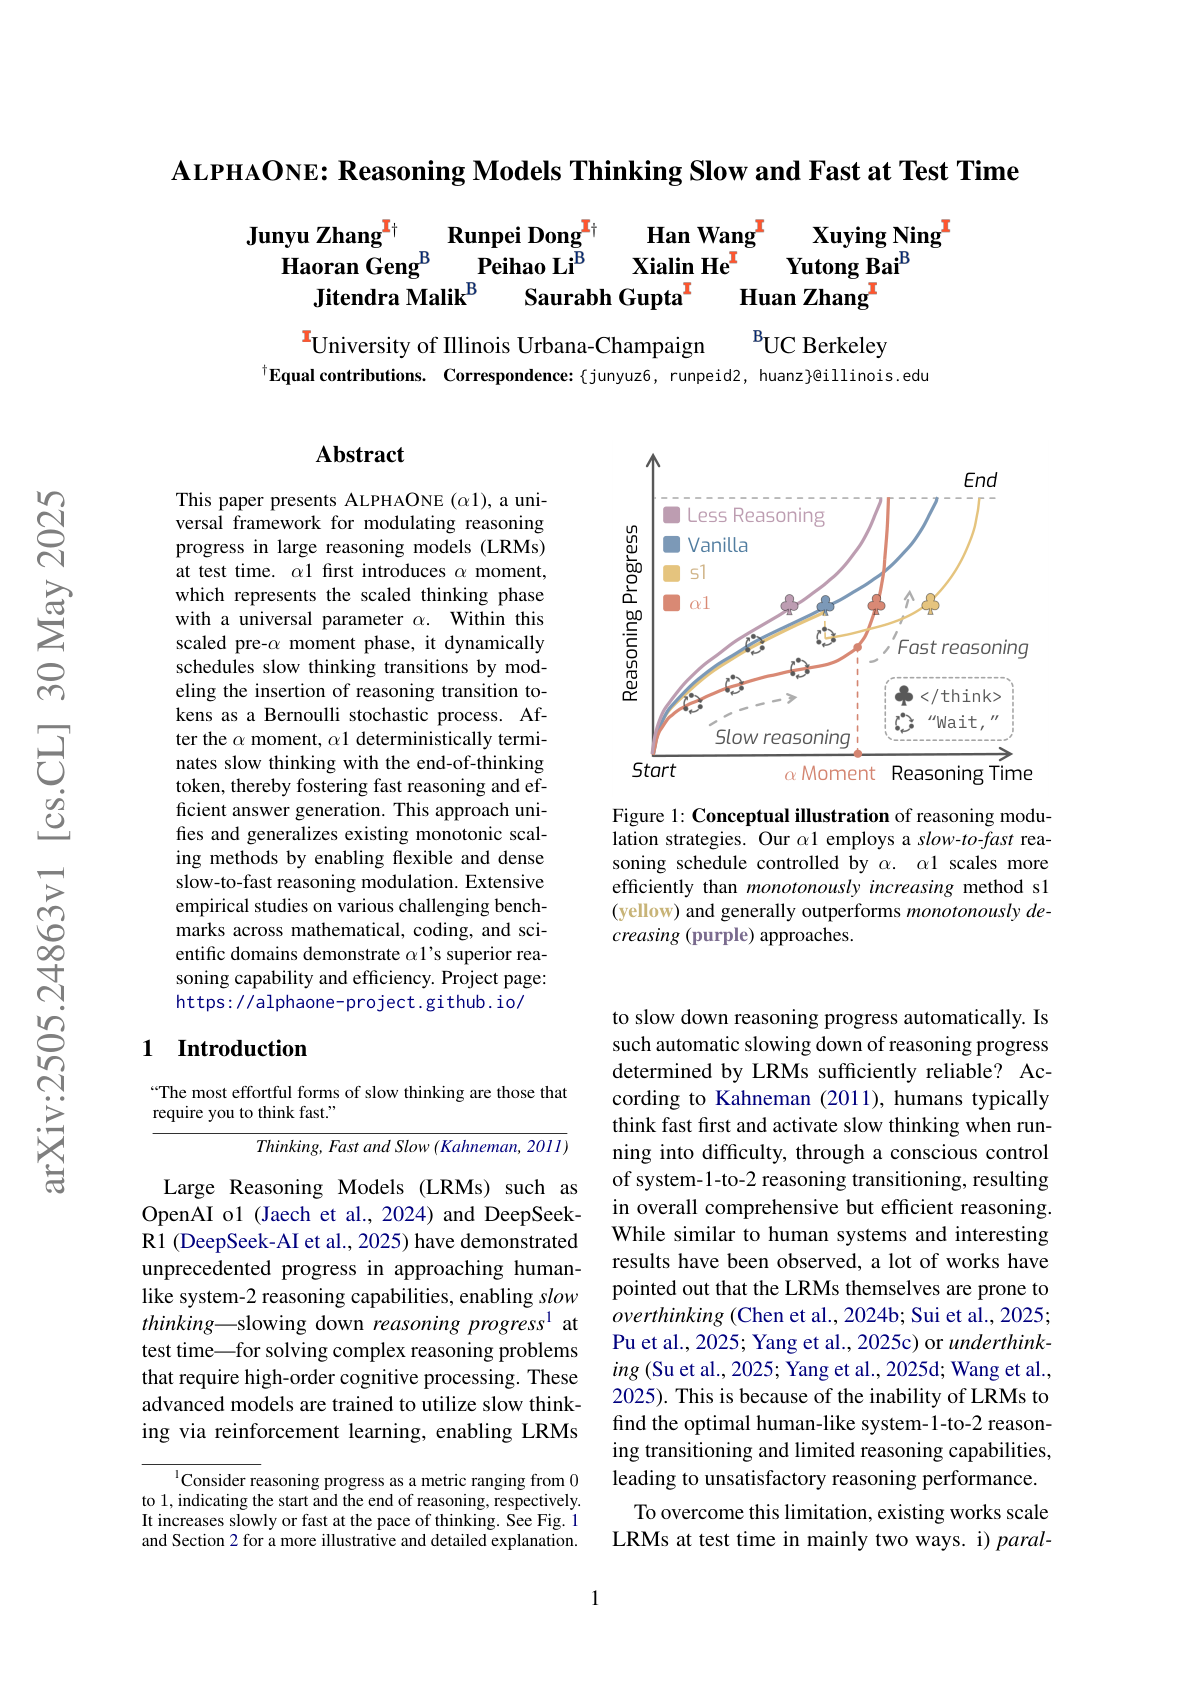
AlphaOne
Introduces a universal framework, α1, for modulating the reasoning progress of large reasoning models (LRMs) during inference. Rather than relying on rigid or automatic schedules, α1 explicitly controls when and how models engage in “slow thinking” using a tunable parameter α. The method dynamically inserts “wait” tokens to encourage deeper reasoning and then deterministically ends slow thinking with a “</think>” token to prompt efficient answer generation. This yields better accuracy and efficiency than previous test-time scaling approaches. Key insights:
Common Pile v0.1
The Common Pile v0.1 is an 8TB dataset of openly licensed text designed for LLM pretraining, addressing legal and ethical concerns of unlicensed data use. Two 7B parameter models trained on it, Comma v0.1-1T and 2T, achieve performance comparable to LLaMA 1 and 2, and the dataset, code, and model checkpoints are all publicly released.
RewardBench 2
RewardBench 2 is a new multi-skill benchmark for evaluating reward models with more challenging human prompts and stronger correlation to downstream performance. It highlights gaps in the current reward model's effectiveness and aims to support more rigorous evaluation, showing existing models score ~20 points lower than their predecessor.
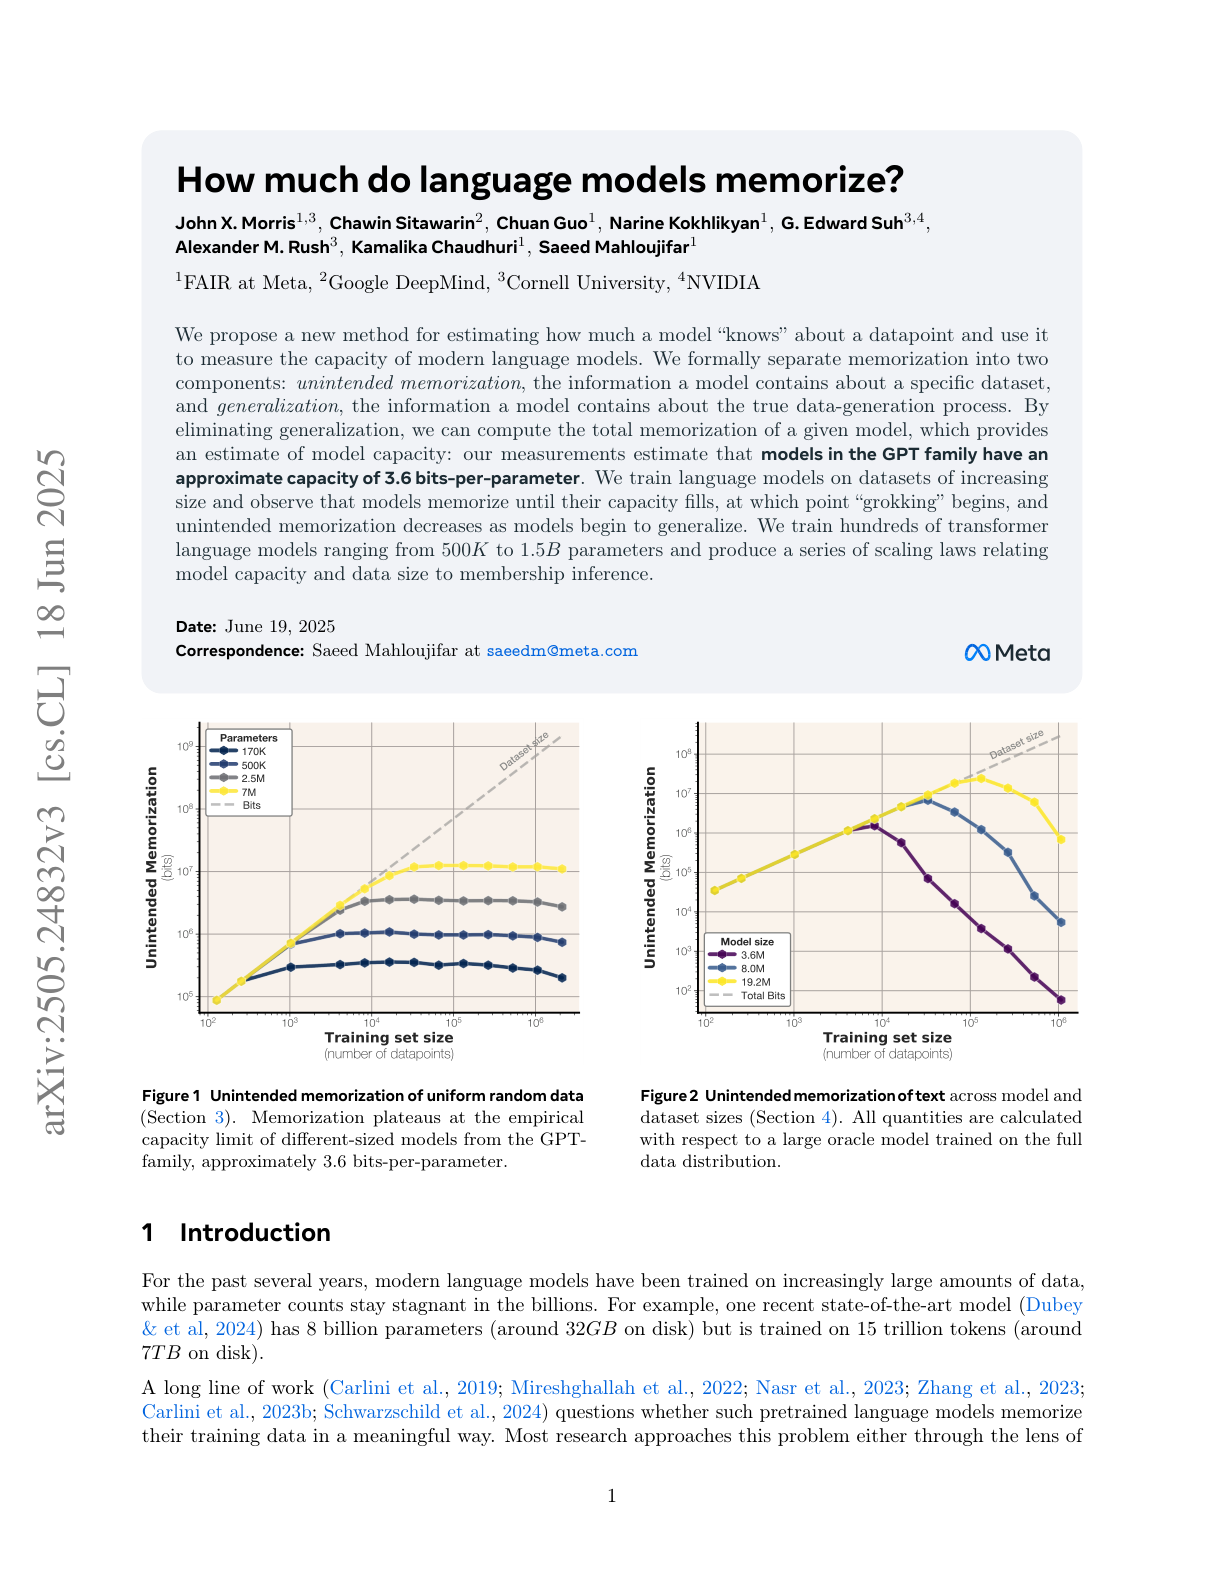
Memorization in LLMs
This study introduces a method to quantify how much a model memorizes versus generalizes, estimating GPT models have a capacity of ~3.6 bits per parameter. By training hundreds of models, the authors show that memorization saturates with data before generalization (“grokking”) kicks in, and derive new scaling laws linking capacity, data size, and membership inference.
New Lens on RAG Systems
Introduces a new conceptual and empirical framework for analyzing RAG systems through the lens of sufficient context, whether the retrieved content alone enables answering a query. This notion helps decouple retrieval failures from generation errors in LLMs, providing clarity on model behavior under different contextual adequacy. Key findings:
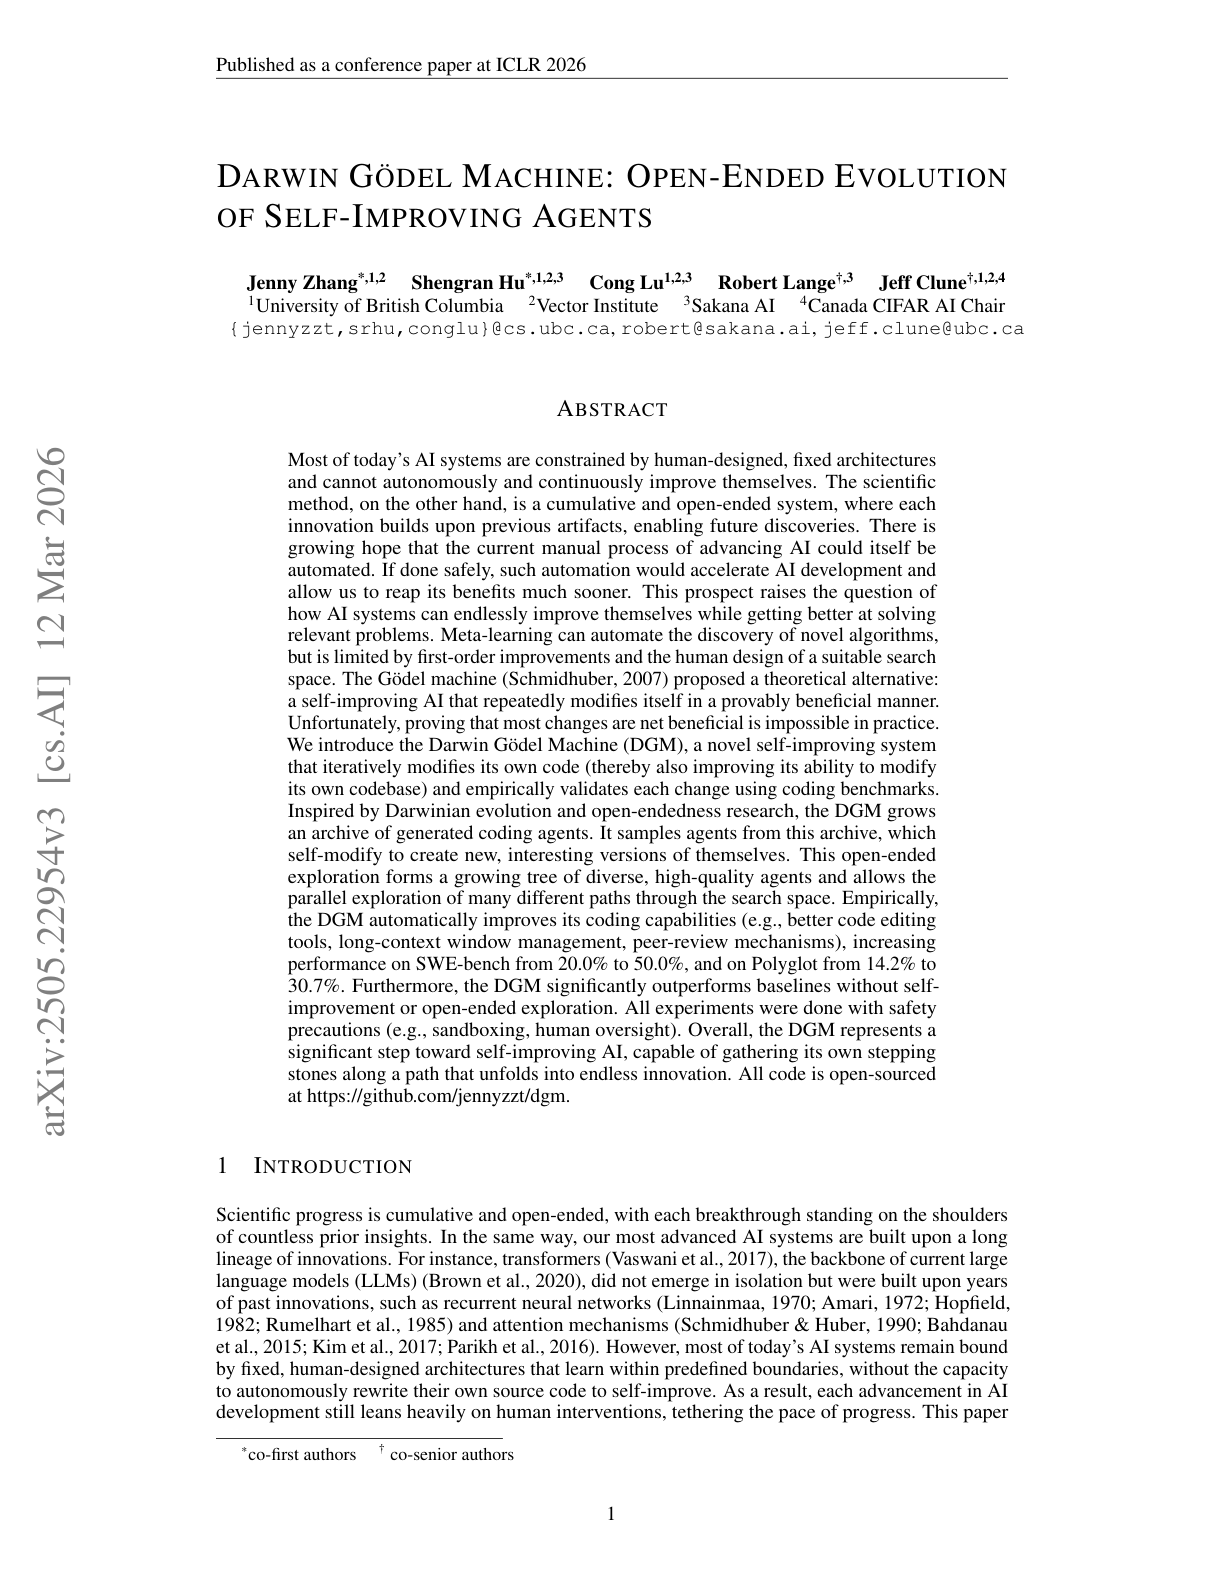
Open-Ended Evolution of Self-Improving Agents
This work presents the Darwin Gödel Machine (DGM), a system that advances the vision of self-improving AI by combining self-referential code modification with open-ended evolutionary search. Unlike the original Gödel machine, which requires provable benefits for code changes (a practically intractable constraint), the DGM adopts an empirical approach: it modifies its own codebase and evaluates improvements on coding benchmarks. Key contributions and findings:
An Operating System for Memory-Augmented Generation in LLMs Introduces a unified operating system for managing memory LLMs, addressing a key limitation in
current architectures: their lack of structured, persistent, and governable memory. While today's LLMs rely primarily on parametric memory (model weights) and limited short-term context, MemOS proposes a comprehensive memory lifecycle and management infrastructure designed to support continual learning, behavioral consistency, and knowledge evolution. Key contributions and components include:
Building Production-Grade Conversational Agents with Workflow Graphs This paper presents a pragmatic, production-ready framework for building LLM-powered conversational agents using workflow graphs, with a specific focus on e-commerce scenarios. Instead of relying solely on end-to-end generation, the authors design agents using a directed acyclic graph (DAG), enabling flexible yet controllable interactions that adhere to strict business rules and format constraints.
Key contributions and findings include:
Spurios Rewards
This work challenges prevailing assumptions about reinforcement learning with verifiable rewards (RLVR) in mathematical reasoning tasks. The authors show that Qwen2.5-Math models can improve significantly under RL, even when trained with spurious or flawed rewards.
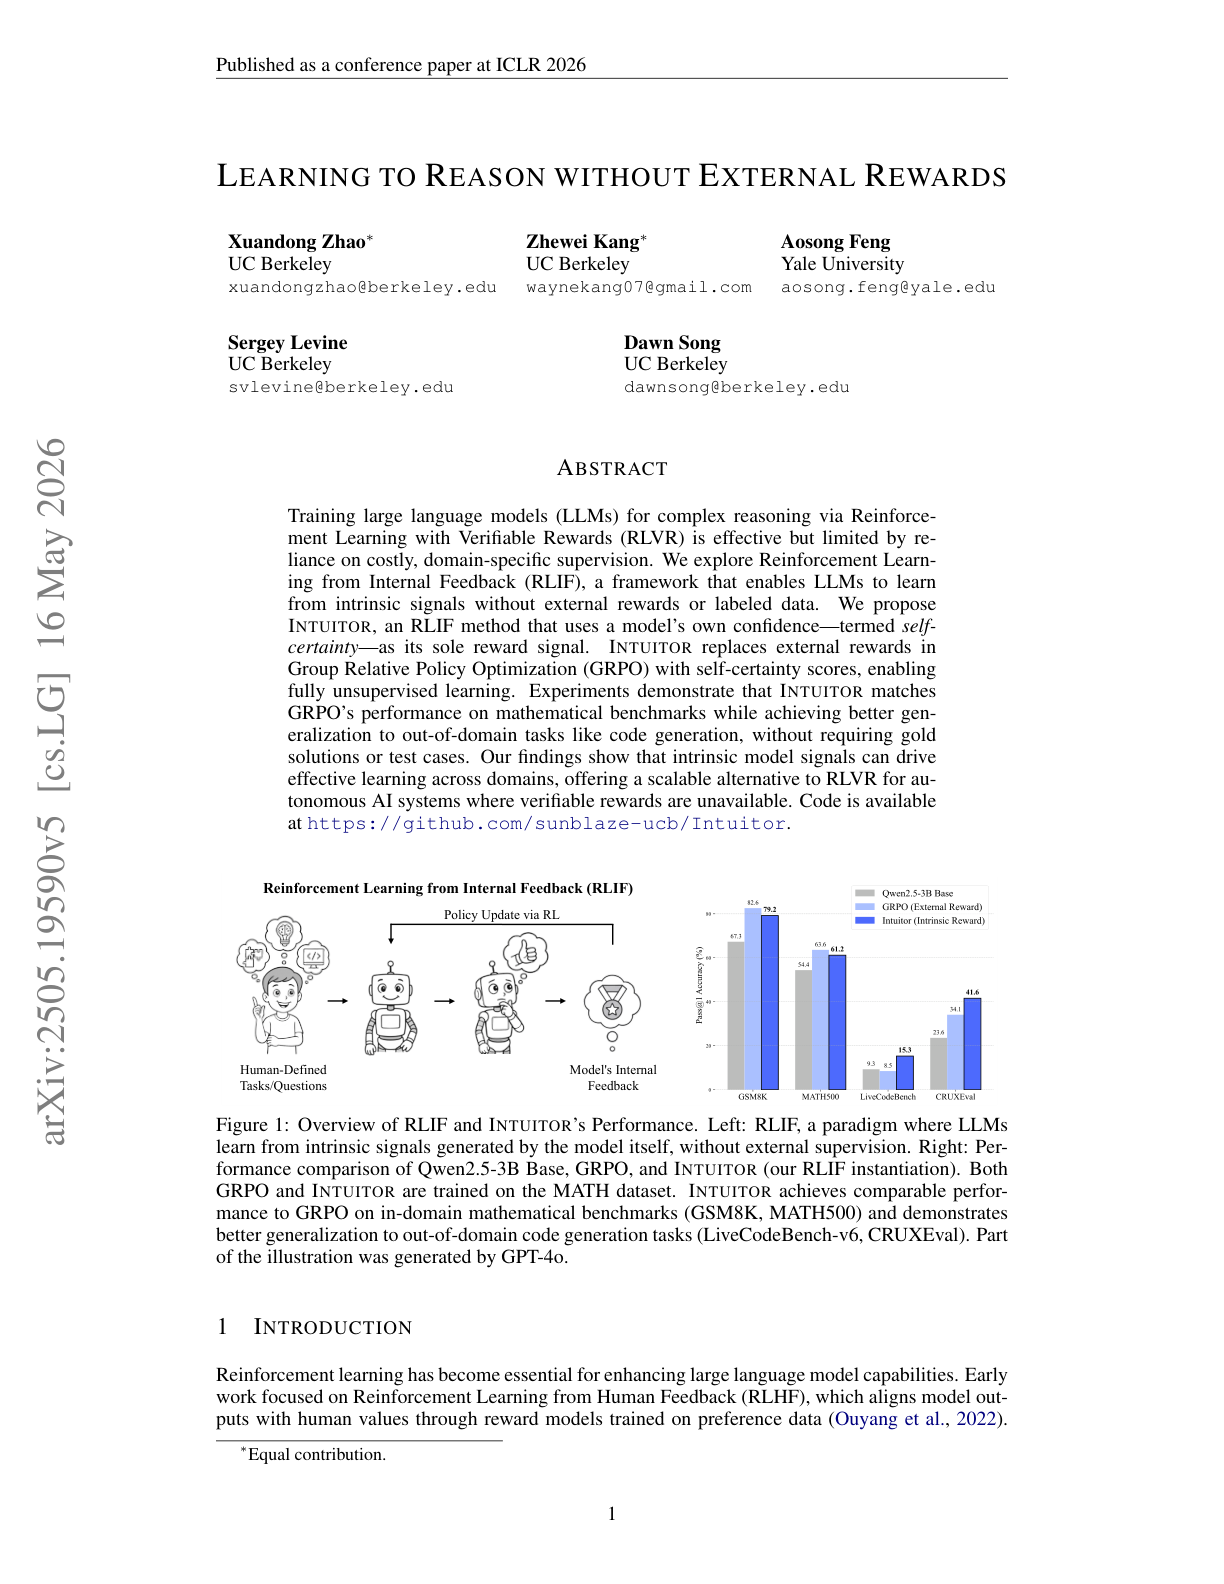
Learn to Reason without External Rewards
Proposes a method for training LLMs via reinforcement learning without any external rewards or labeled data. Instead, it uses the model’s own self-certainty, a confidence measure based on KL divergence from uniform, as the sole intrinsic reward. This self-improvement strategy, part of the broader Reinforcement Learning from Internal Feedback (RLIF) paradigm, bypasses the limitations of Reinforcement Learning with Verifiable Rewards (RLVR), which requires domain-specific verifiers and gold-standard outputs. Key highlights:
Learn to Reason via Mixture-of-Thought
While most prior approaches train with a single modality and only ensemble during inference, this work introduces Mixture-of-Thought (MoT) to jointly train and infer across modalities, resulting in notable gains in logical reasoning performance. Key findings:
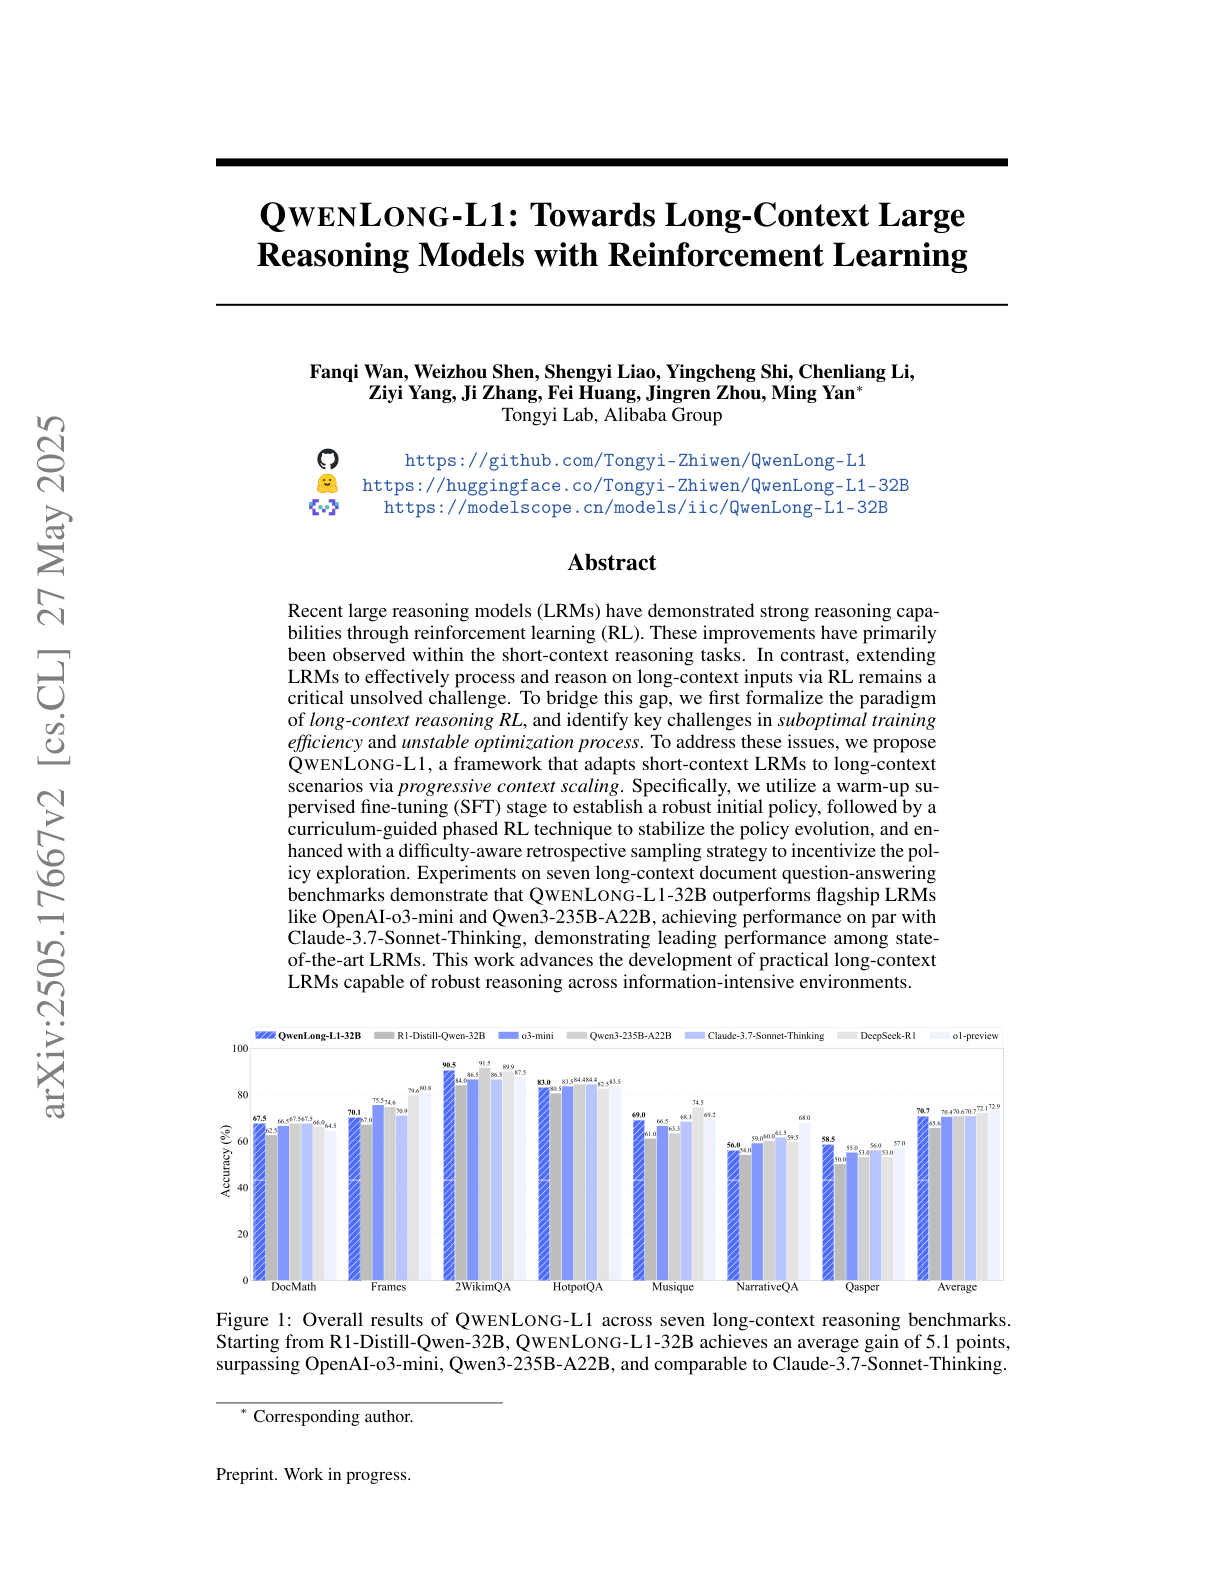
QwenLong-L1
A new reinforcement learning framework that scales large reasoning models (LRMs) from short to long contexts using progressive context scaling and hybrid rewards. It achieves top performance on seven long-context benchmarks, surpassing models like OpenAI-o3-mini and Qwen3-235B-A22B, and matching Claude-3.7-Sonnet-Thinking, demonstrating strong reasoning with up to 120K token inputs.
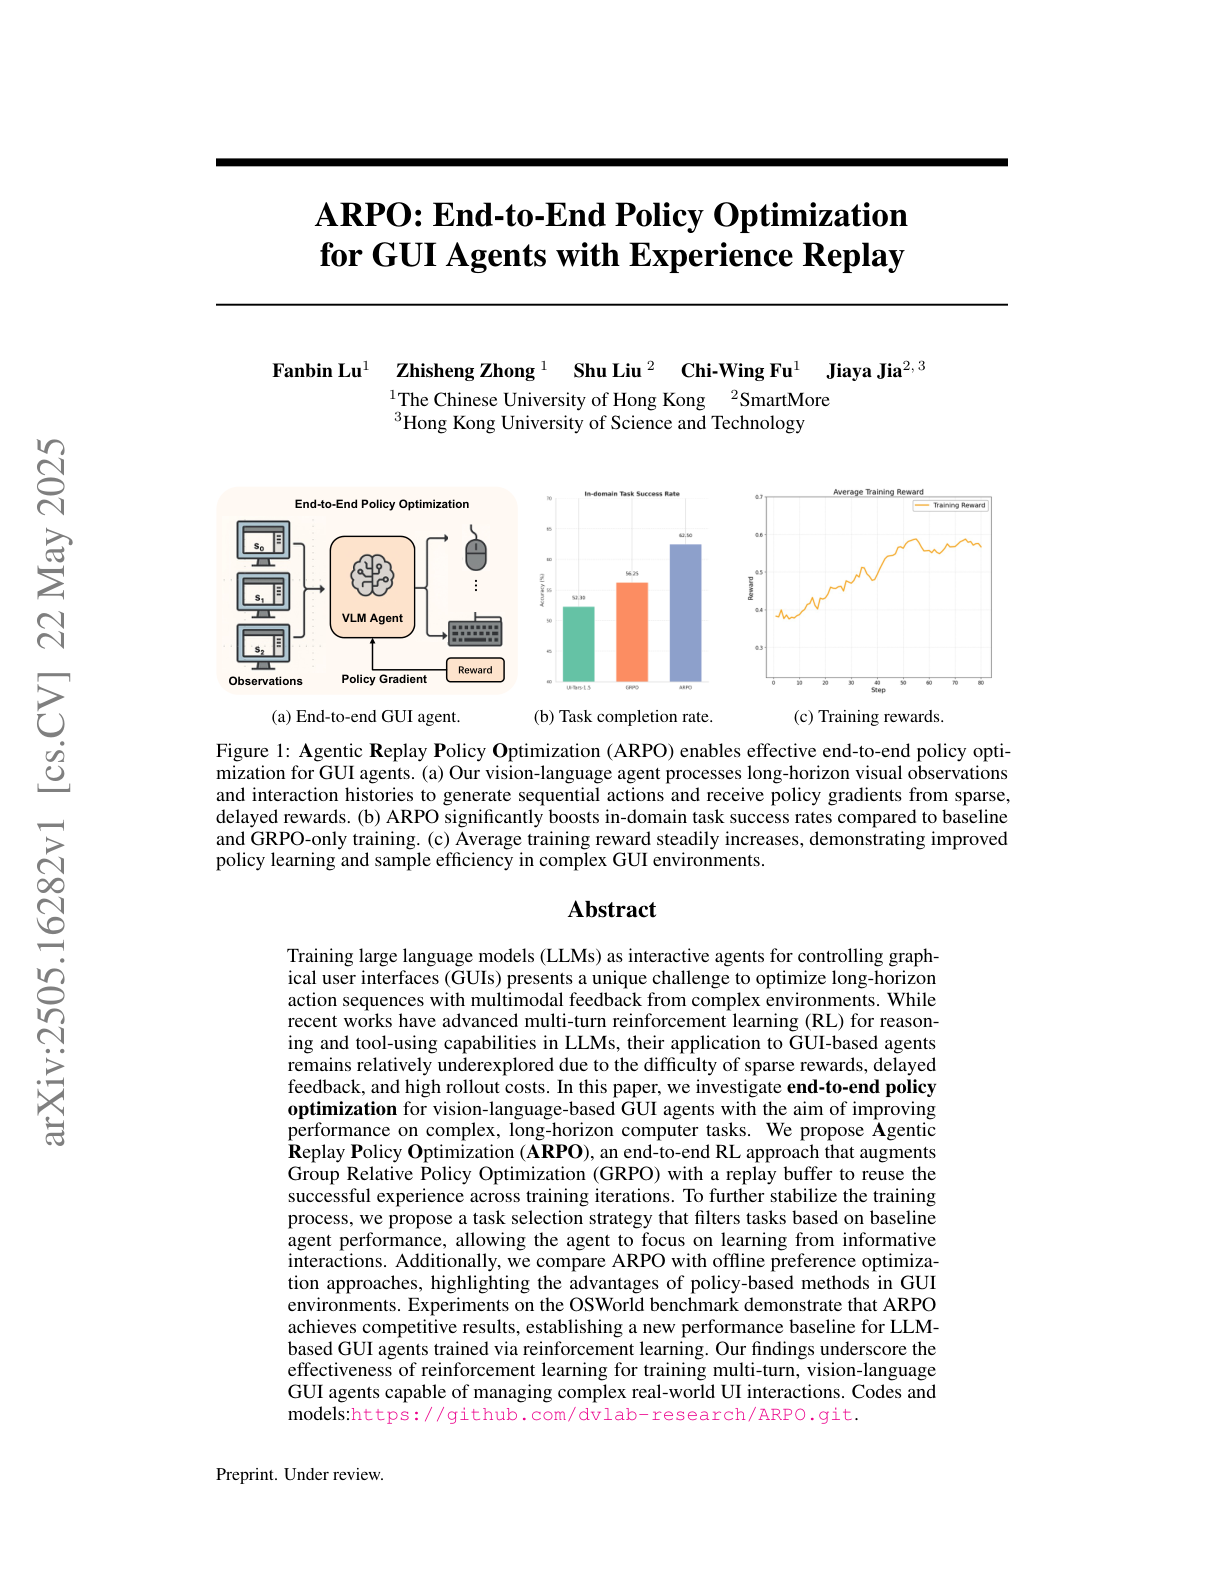
End-to-End Policy Optimization for GUI Agents
ARPO introduces an end-to-end reinforcement learning method for training GUI agents using Group Relative Policy Optimization (GRPO) with experience replay. It significantly improves in-domain performance on the OSWorld benchmark, outperforming baselines by up to 6.7%, while offering modest gains on out-of-domain tasks and enabling self-corrective behaviors through structured reward feedback.
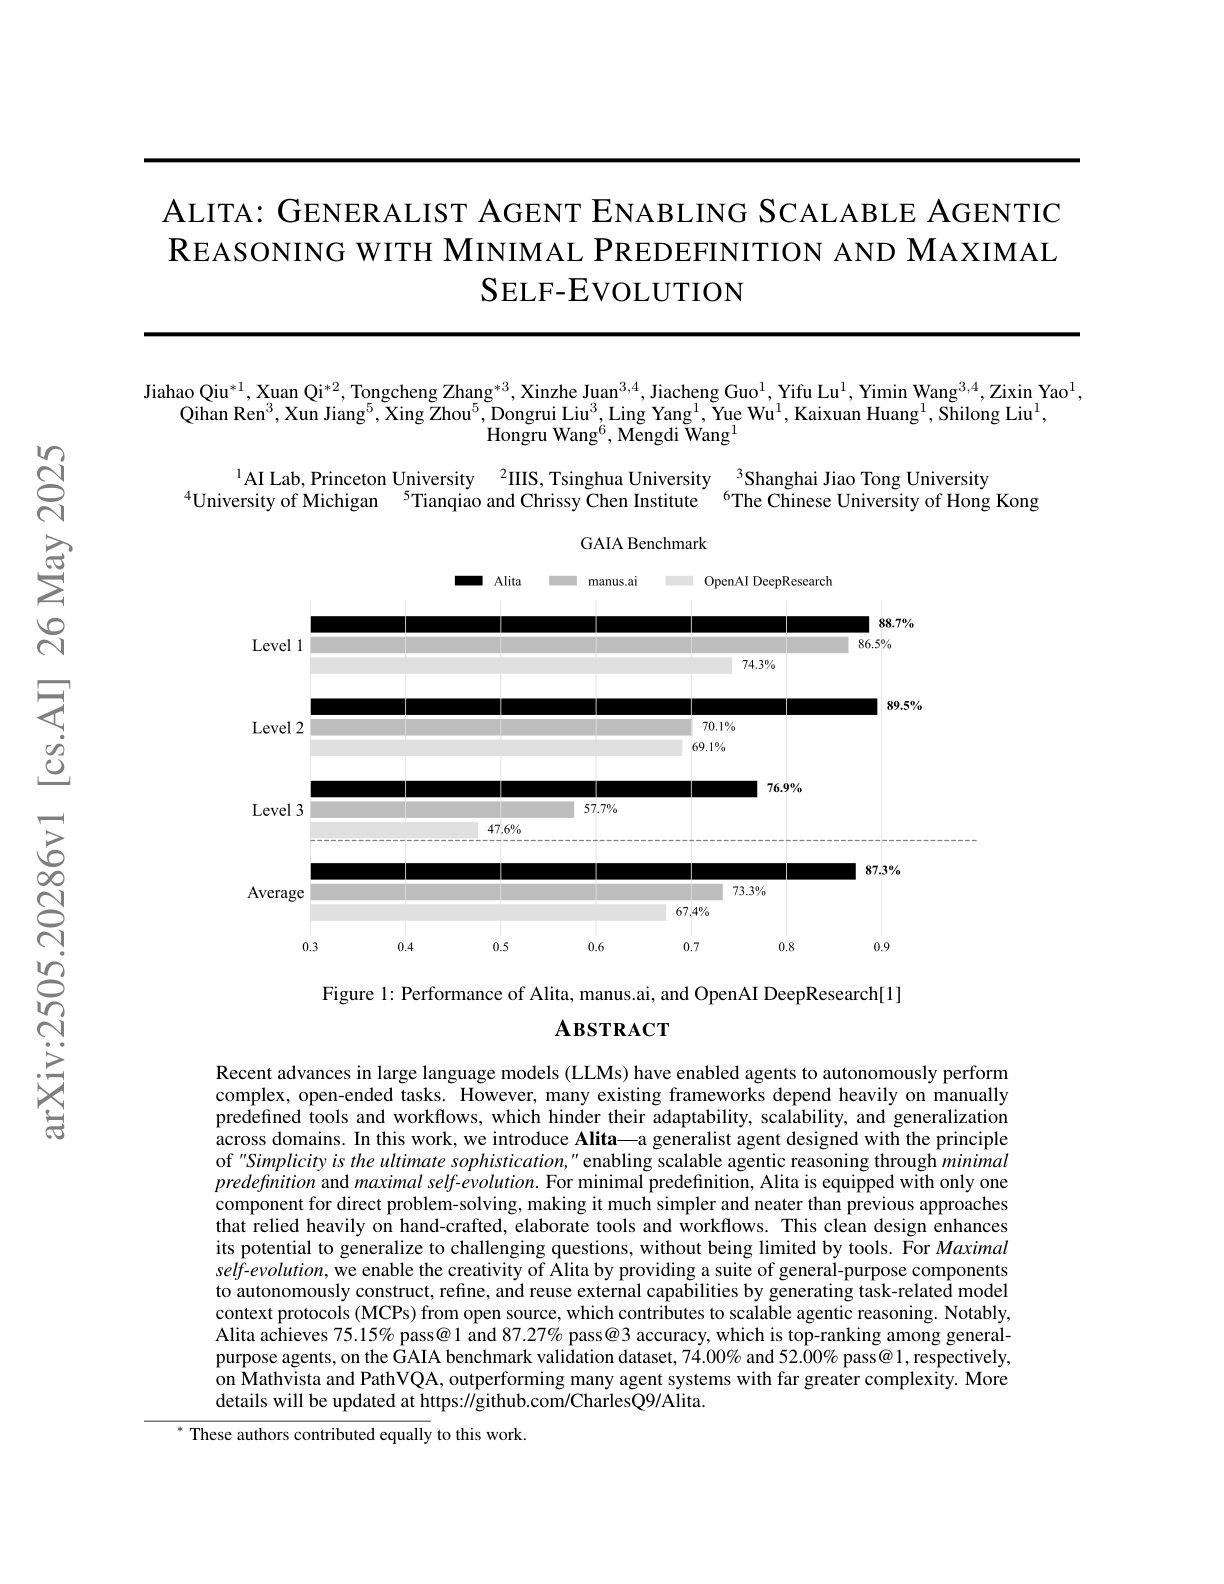
Generalist Agent Enabling Scalable Agentic Reasoning
Proposes Alita, a generalist agent framework that enables scalable agentic reasoning through minimal predefinition and maximal self-evolution. Unlike traditional agents reliant on handcrafted tools, Alita autonomously constructs reusable MCPs (Model Context Protocols) using web search and code synthesis, outperforming more complex systems like OpenAI DeepResearch and OctoTools on GAIA, MathVista, and PathVQA benchmarks.
Visual Planning
Proposes a novel reasoning paradigm that replaces language-based planning with image-based reasoning. The authors argue that language is not always the optimal medium for tasks involving spatial or physical reasoning. They introduce Visual Planning, where reasoning is executed as a sequence of visual states (images) without any text mediation, allowing models to “think” directly in images. This is realized through a reinforcement learning framework called VPRL (Visual Planning via Reinforcement Learning), which trains a vision-only model (LVM-3B) to plan using images. Key contributions and findings:
EfficientLLM
Introduces the first large-scale, empirical benchmark for evaluating efficiency trade-offs in LLMs across architecture, fine-tuning, and inference. Conducted on a high-performance cluster (48×GH200, 8×H200 GPUs), the study evaluates over 100 model–technique pairs spanning 0.5B–72B parameters, using six metrics: memory utilization, compute utilization, latency, throughput, energy consumption, and compression rate. Key insights include:
J1
Introduces a novel training approach for LLMs to act as evaluators (LLM-as-a-Judge) by explicitly incentivizing thoughtful reasoning during judgment. Instead of relying solely on prompting or preference fine-tuning, J1 employs online reinforcement learning with verifiable rewards to teach models to think through evaluations systematically. Key insights:
The Pitfalls of Reasoning for Instruction- Following in LLMs
Explores an unexpected flaw in reasoning-augmented large language models (RLLMs): while chain-of-thought (CoT) prompting often boosts performance on complex reasoning tasks, it can degrade instruction-following accuracy. The authors evaluate 15 models (e.g., GPT, Claude, LLaMA, DeepSeek) on two instruction-following benchmarks and find that CoT prompting consistently reduces performance across nearly all models and datasets. Key findings:
Generalizable AI Predicts Immunotherapy Outcomes Across Cancers and Treatments
Introduces COMPASS, a concept bottleneck-based foundation model that predicts patient response to immune checkpoint inhibitors (ICIs) using tumor transcriptomic data. Unlike prior biomarkers (TMB, PD-L1, or fixed gene signatures), COMPASS generalizes across cancer types, ICI regimens, and clinical contexts with strong interpretability and performance. Key contributions:
Towards a Deeper Understanding of Reasoning in LLMs
This paper investigates whether LLMs can adapt and reason in dynamic environments, moving beyond static benchmarks. Using the SmartPlay benchmark—a suite of four interactive games that require diverse cognitive skills—the authors evaluate three prompting strategies: self-reflection, heuristic mutation (via an Oracle), and planning. They test these methods across models of varying size (Llama3-8B to Llama3.3-70B) and draw several conclusions on how model scale and prompting interact with task complexity. Key findings:
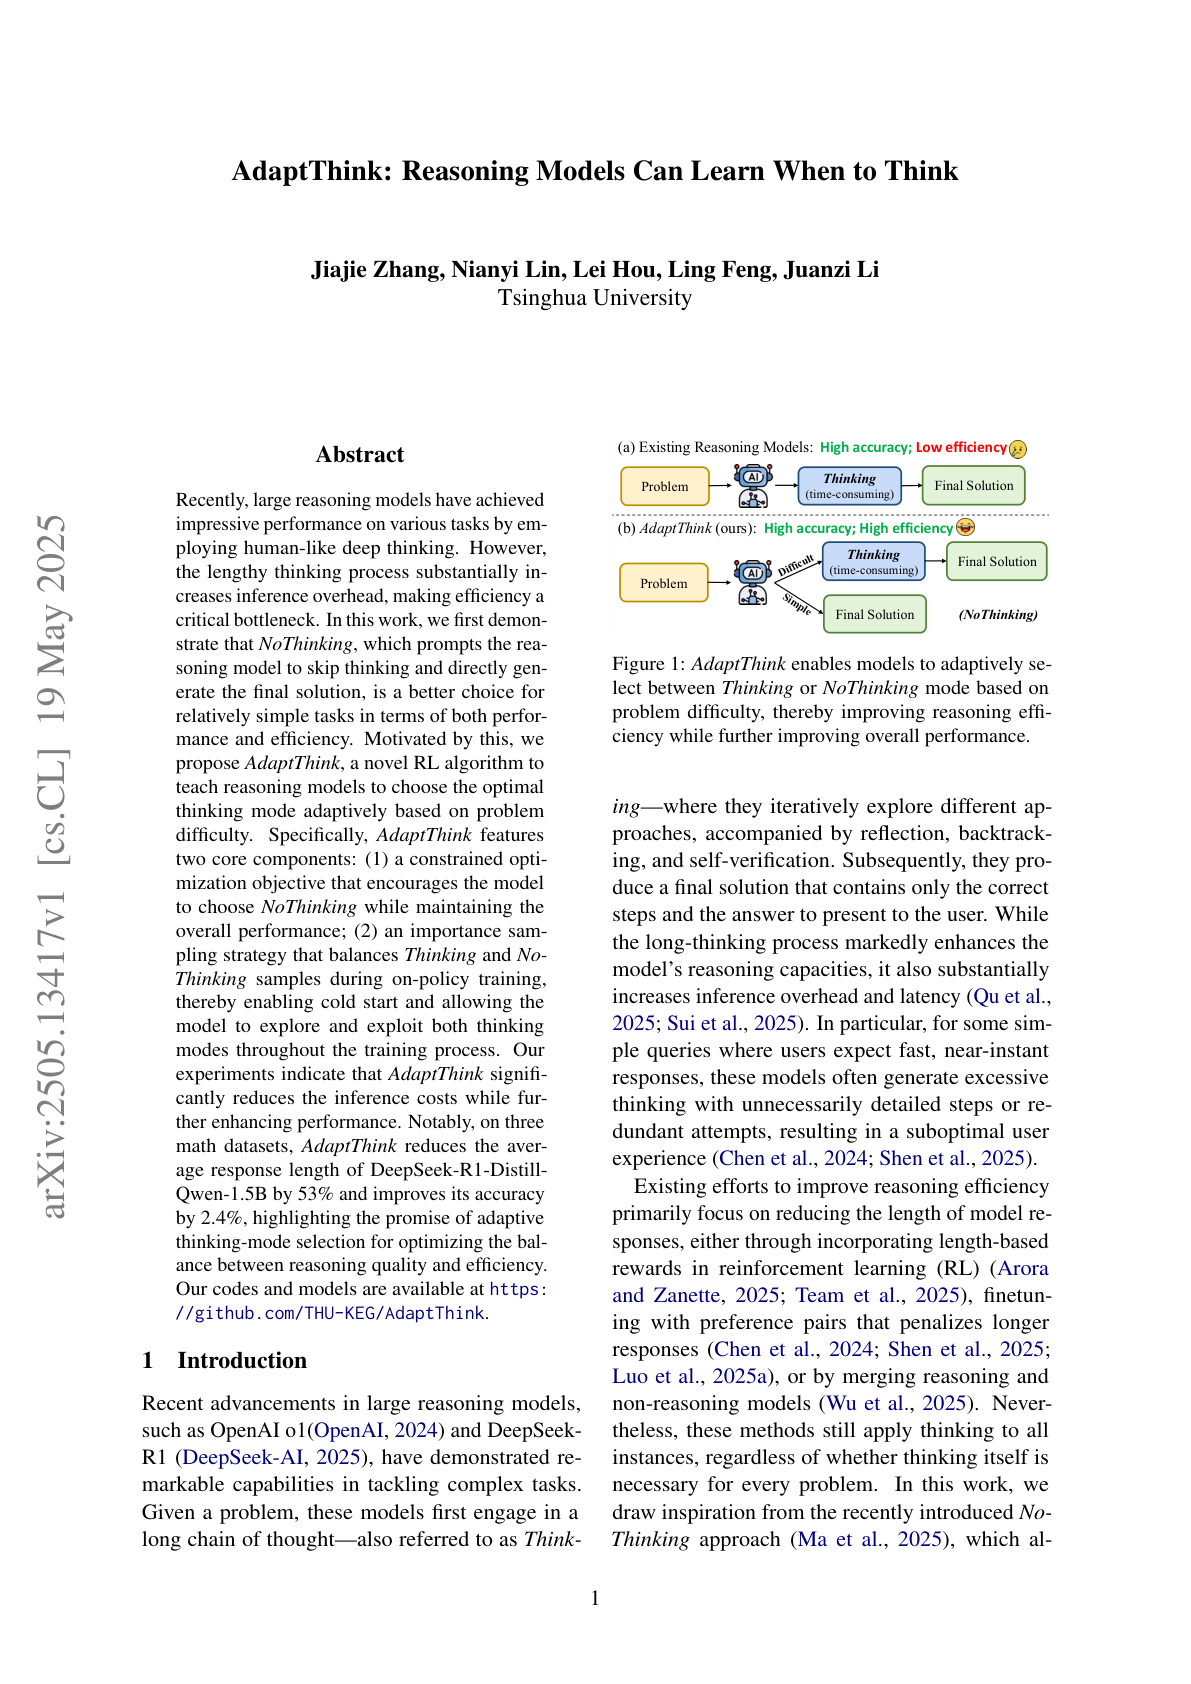
AdaptThink
This paper introduces AdaptThink, an RL framework designed to help reasoning models decide when to use detailed chain-of-thought reasoning (“Thinking”) versus directly producing an answer (“NoThinking”), based on task difficulty. This approach challenges the prevailing assumption that deep reasoning should be applied uniformly across all problems, showing that skipping the “thinking” step often yields better efficiency and even higher accuracy on simpler tasks. Key insights: