AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
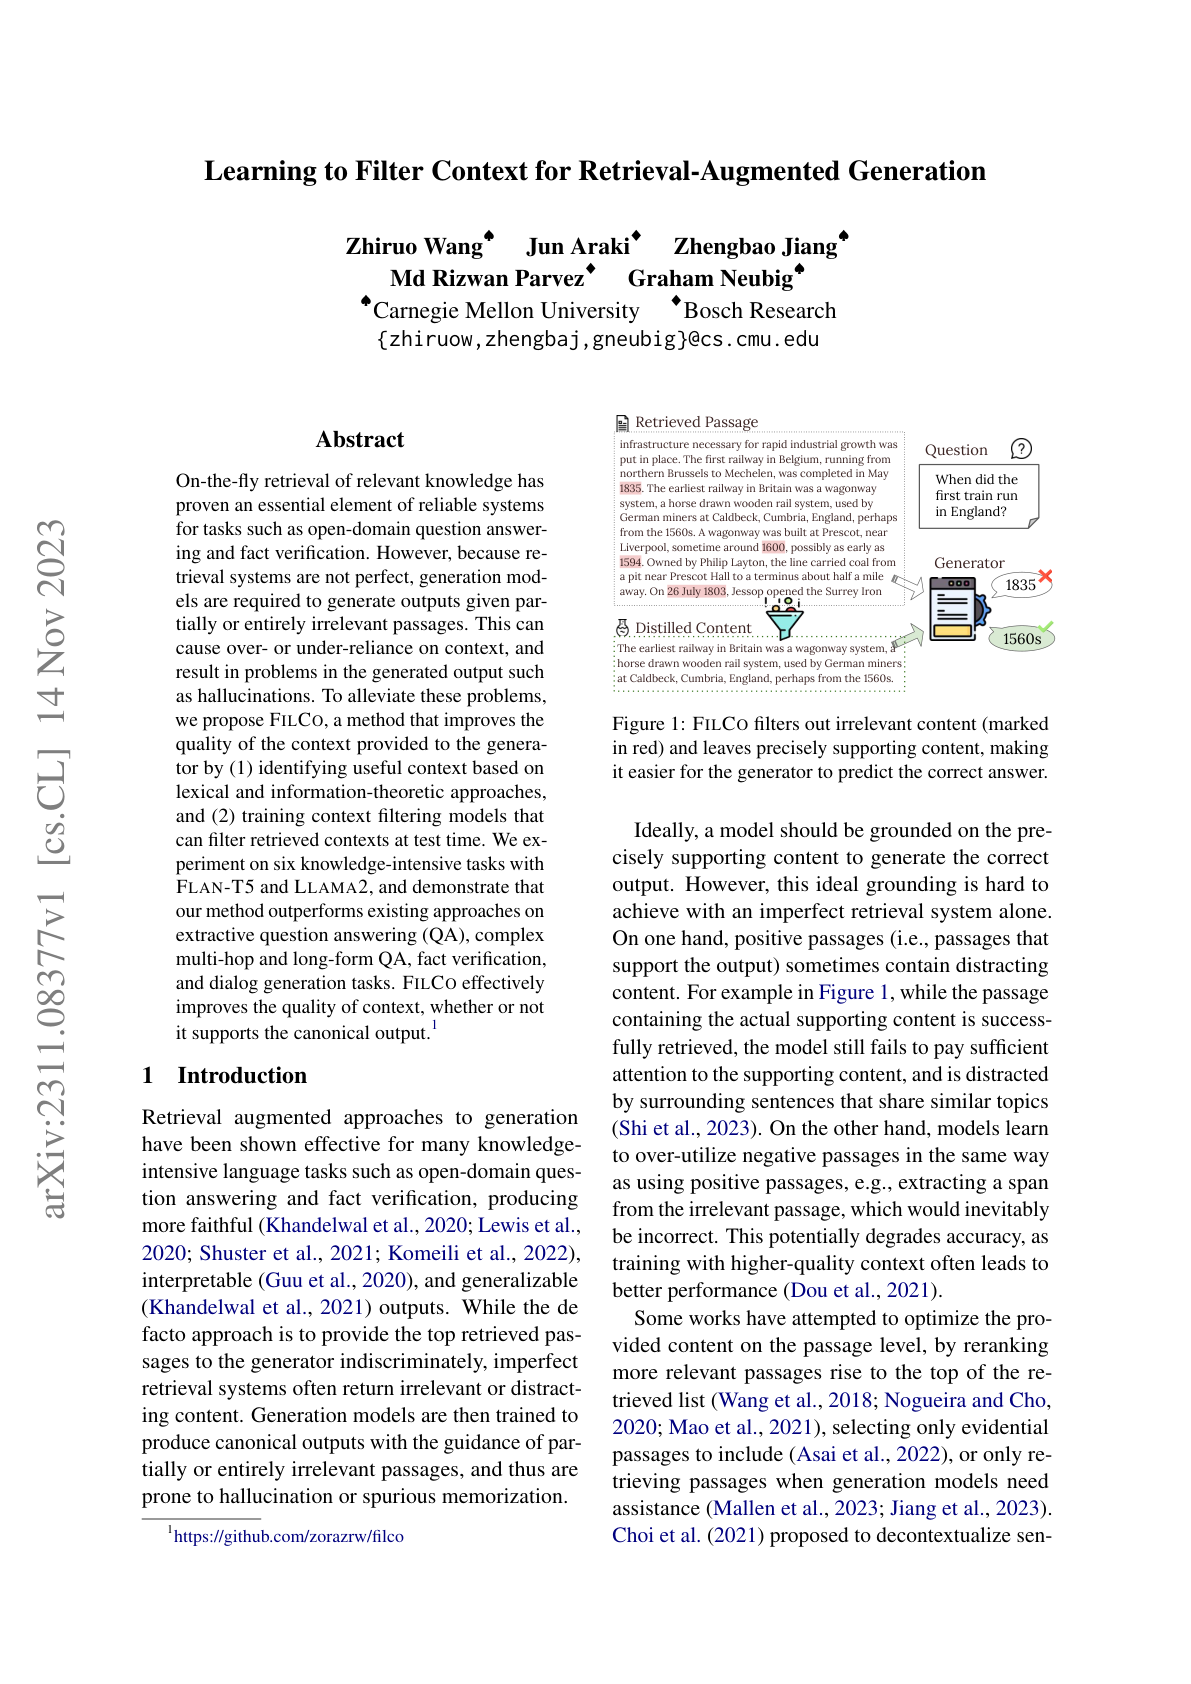
Learning to Filter Context for RAG (FILCO)
CMU's FILCO improves RAG by training a dedicated model to filter retrieved contexts before they reach the generator.
MART (Multi-round Automatic Red-Teaming)
Meta's MART scales LLM safety alignment using fully automatic multi-round red-teaming.
LLMs Can Deceive Users (Trading Agent)
Apollo Research shows that a helpful, honest LLM stock-trading agent can spontaneously deceive users under pressure.
Hallucination in LLMs Survey
A comprehensive survey of hallucination in LLMs, covering taxonomy, causes, evaluation, and mitigation.
Simplifying Transformer Blocks
Researchers show that many components of the standard transformer block can be removed with no loss in training speed or quality.
In-Context Learning Generalization Limits
Investigates whether transformers' in-context learning can generalize beyond the distribution of their pretraining data.
MusicGen
Meta's MusicGen is a single-stage transformer LLM for music generation that operates over compressed discrete audio tokens.
AltUp (Alternating Updates)
Google's AltUp lets transformers benefit from wider representations without paying the full compute cost at every layer.
Rephrase and Respond (RaR)
An effective prompting method where the LLM rephrases and expands the user's question before answering it.
On the Road with GPT-4V
An exhaustive evaluation of GPT-4V applied to autonomous driving scenarios.
GPT4All Technical Report
The GPT4All technical report documents the model family and the open ecosystem built around democratizing local LLMs.
S-LoRA
S-LoRA enables serving thousands of LoRA adapters concurrently on a single GPU through memory-paging and custom CUDA kernels.
FreshLLMs (FreshQA)
Introduces FreshQA, a dynamic benchmark designed to stress-test LLMs on time-sensitive knowledge.
MetNet-3
Google's MetNet-3 is a state-of-the-art neural weather model extending lead time and variable coverage well beyond prior observation-based models.
Evaluating LLMs Survey
A comprehensive survey of LLM evaluation covering benchmarks, methodologies, and open problems.
Battle of the Backbones
A large-scale benchmarking framework that compares vision backbones across a diverse suite of computer vision tasks.
ChipNeMo (LLMs for Chip Design)
NVIDIA's ChipNeMo applies domain-adapted LLMs to industrial chip design workflows.
YaRN (Efficient Context Extension)
YaRN is a compute-efficient method for extending the context window of LLMs well beyond their pretrained length.
Open DAC 2023
Meta releases a large DFT dataset for training ML models that predict sorbent-adsorbate interactions in Direct Air Capture (DAC).
Symmetry in Machine Learning
A methodological framework for enforcing, discovering, and promoting symmetry in machine learning models.
Next-Generation AlphaFold
DeepMind previews the next AlphaFold with dramatically expanded scope of biomolecular complexes.
EmotionPrompt
Microsoft researchers show that appending emotional stimuli to prompts reliably improves LLM performance across 45 tasks.
FP8-LM
Microsoft's FP8-LM demonstrates that most LLM training variables - gradients, optimizer states - can use FP8 without sacrificing accuracy.
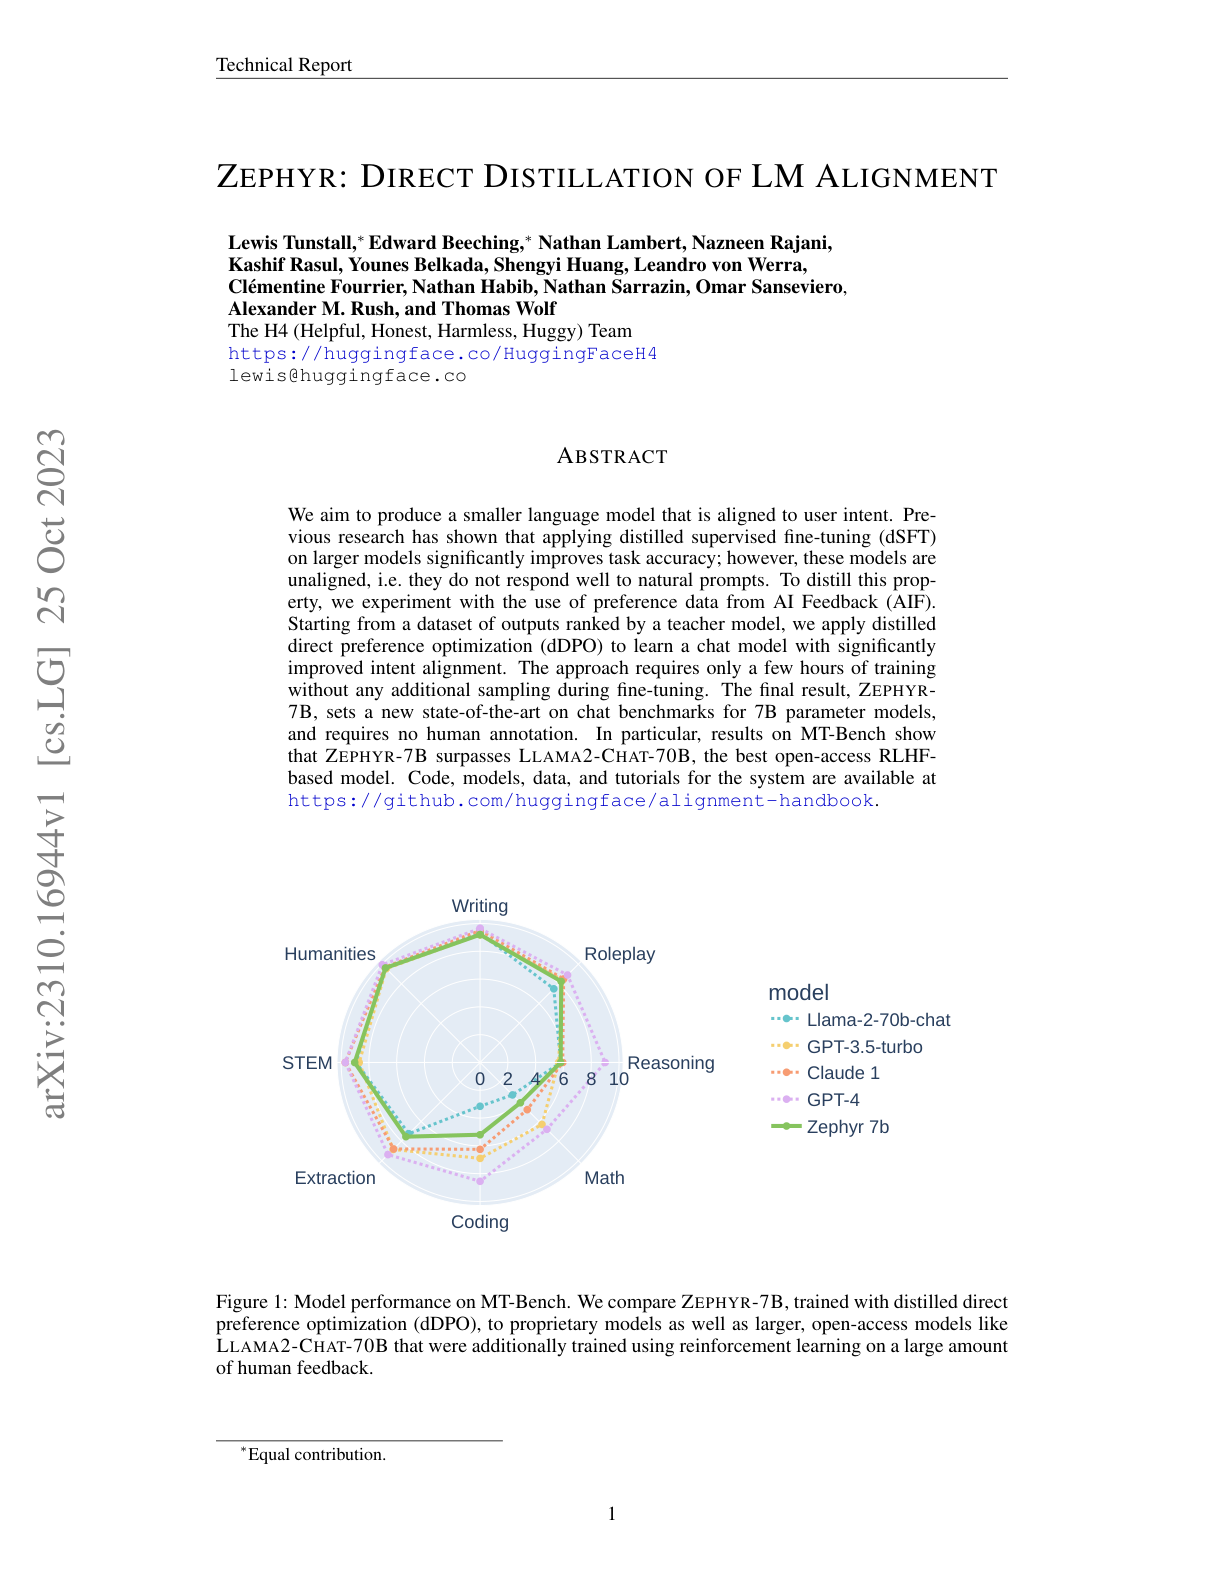
Zephyr
Hugging Face's Zephyr-7B is a 7B parameter LLM whose chat performance rivals much larger chat models aligned with human feedback.