AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
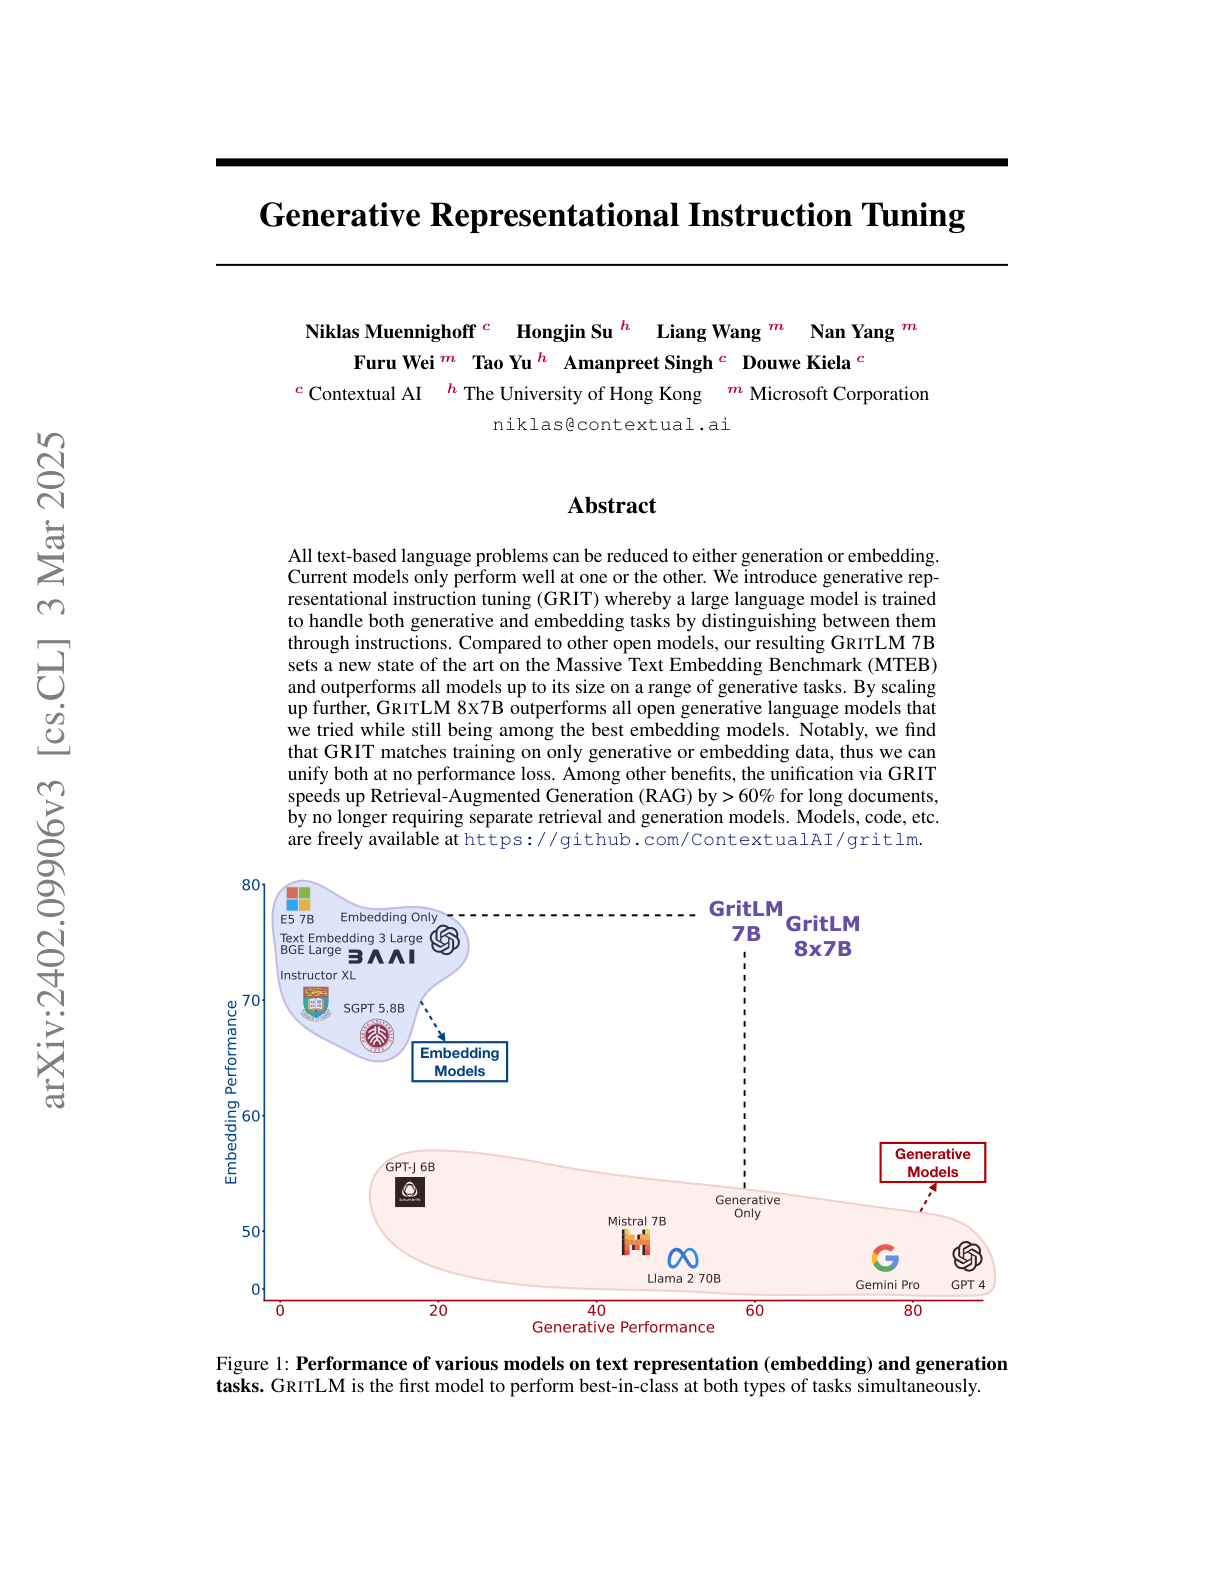
GRIT
GRIT (Generative Representational Instruction Tuning) trains a single LLM to handle both generative and embedding tasks, switching behavior based on instructions.
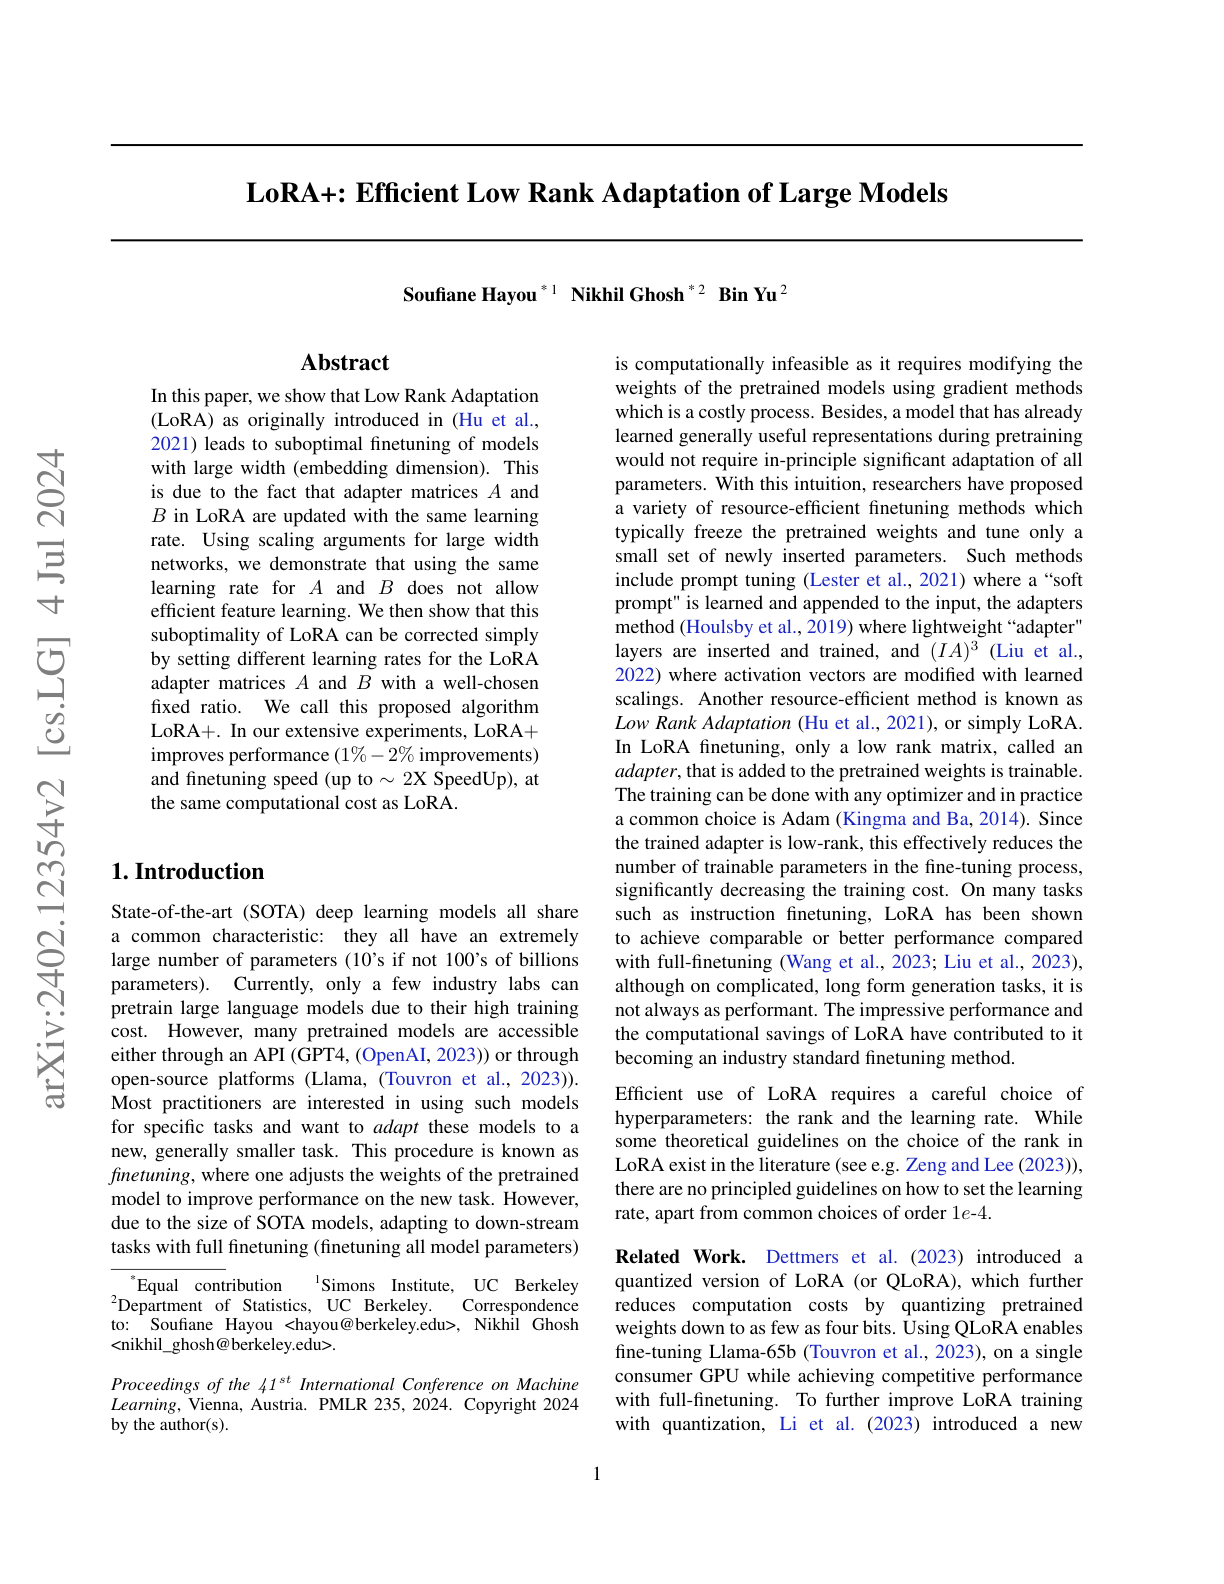
LoRA+
LoRA+ is a minimal one-line change to LoRA: use different learning rates for the down-projection (A) and up-projection (B) matrices to restore feature learning at large width.
Back to Basics: Revisiting REINFORCE in RLHF
Cohere researchers argue that PPO is overkill for RLHF and that a simpler REINFORCE-style estimator works better in practice.
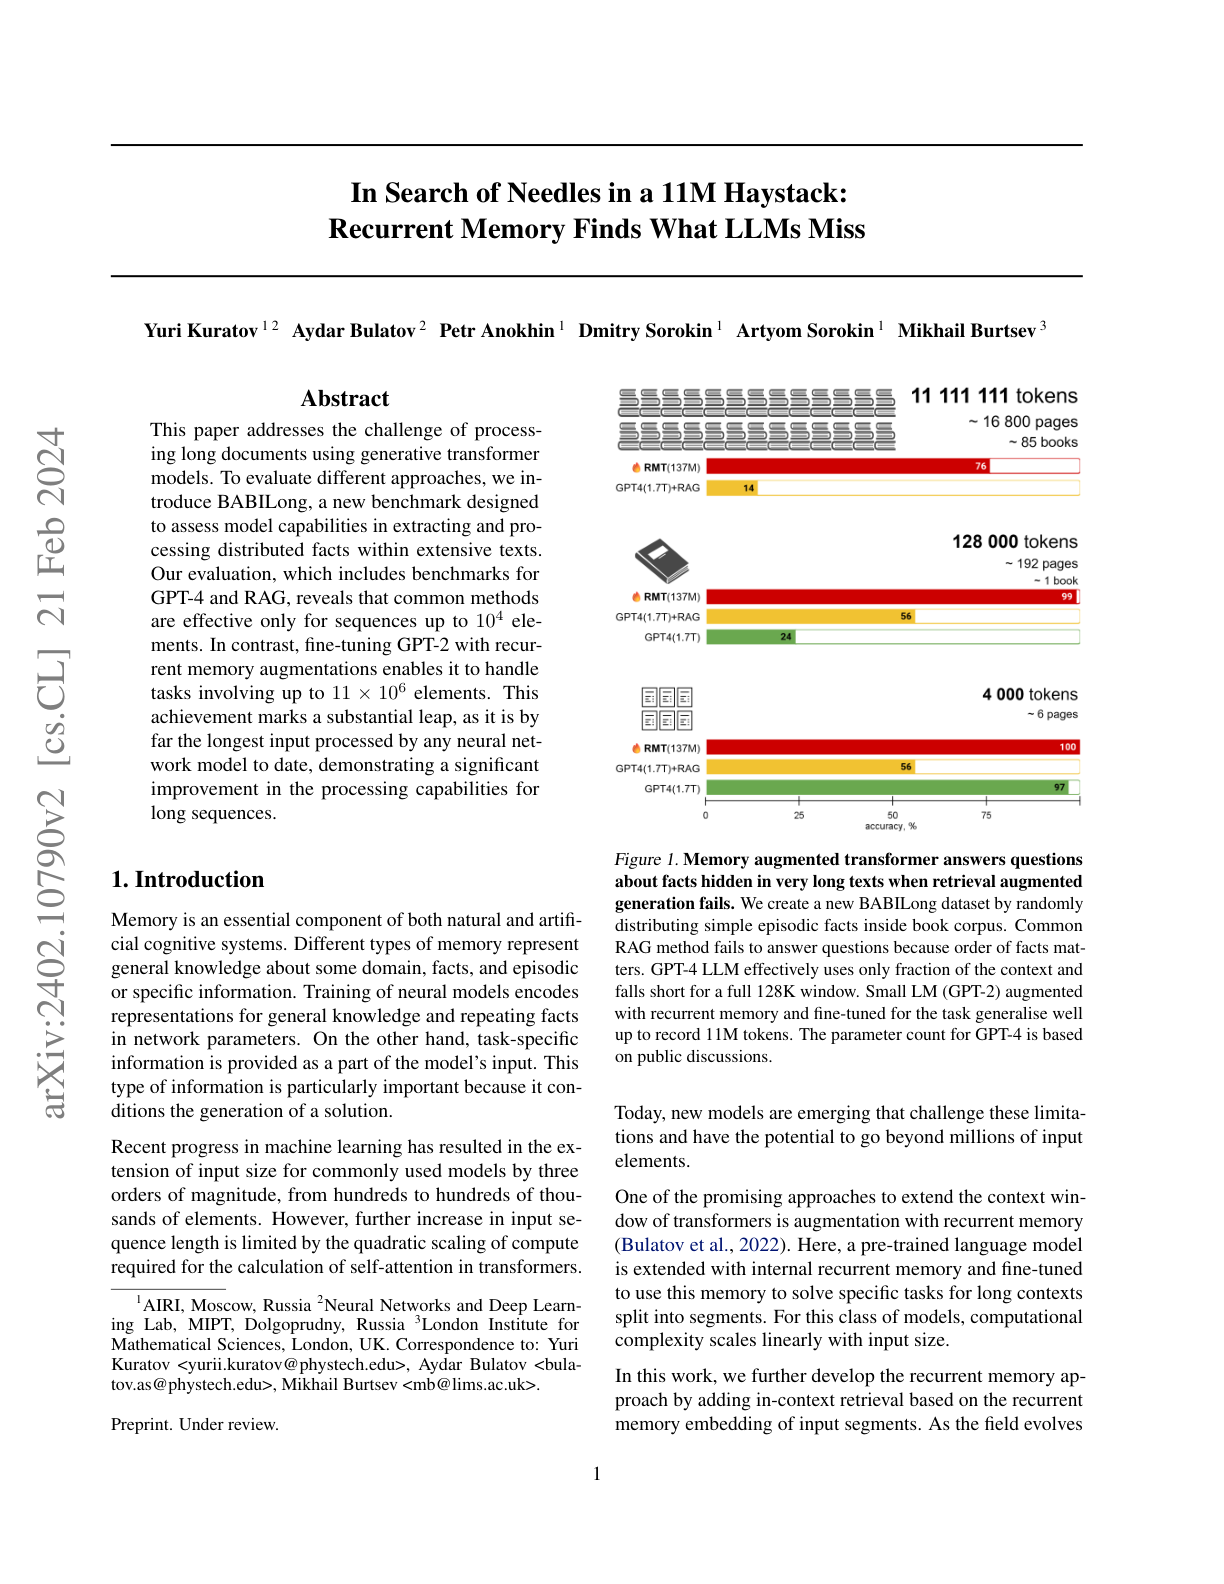
Recurrent Memory Finds What LLMs Miss
Introduces BABILong, a new long-context benchmark, and shows that transformers with recurrent memory can handle sequences far beyond vanilla LLMs.
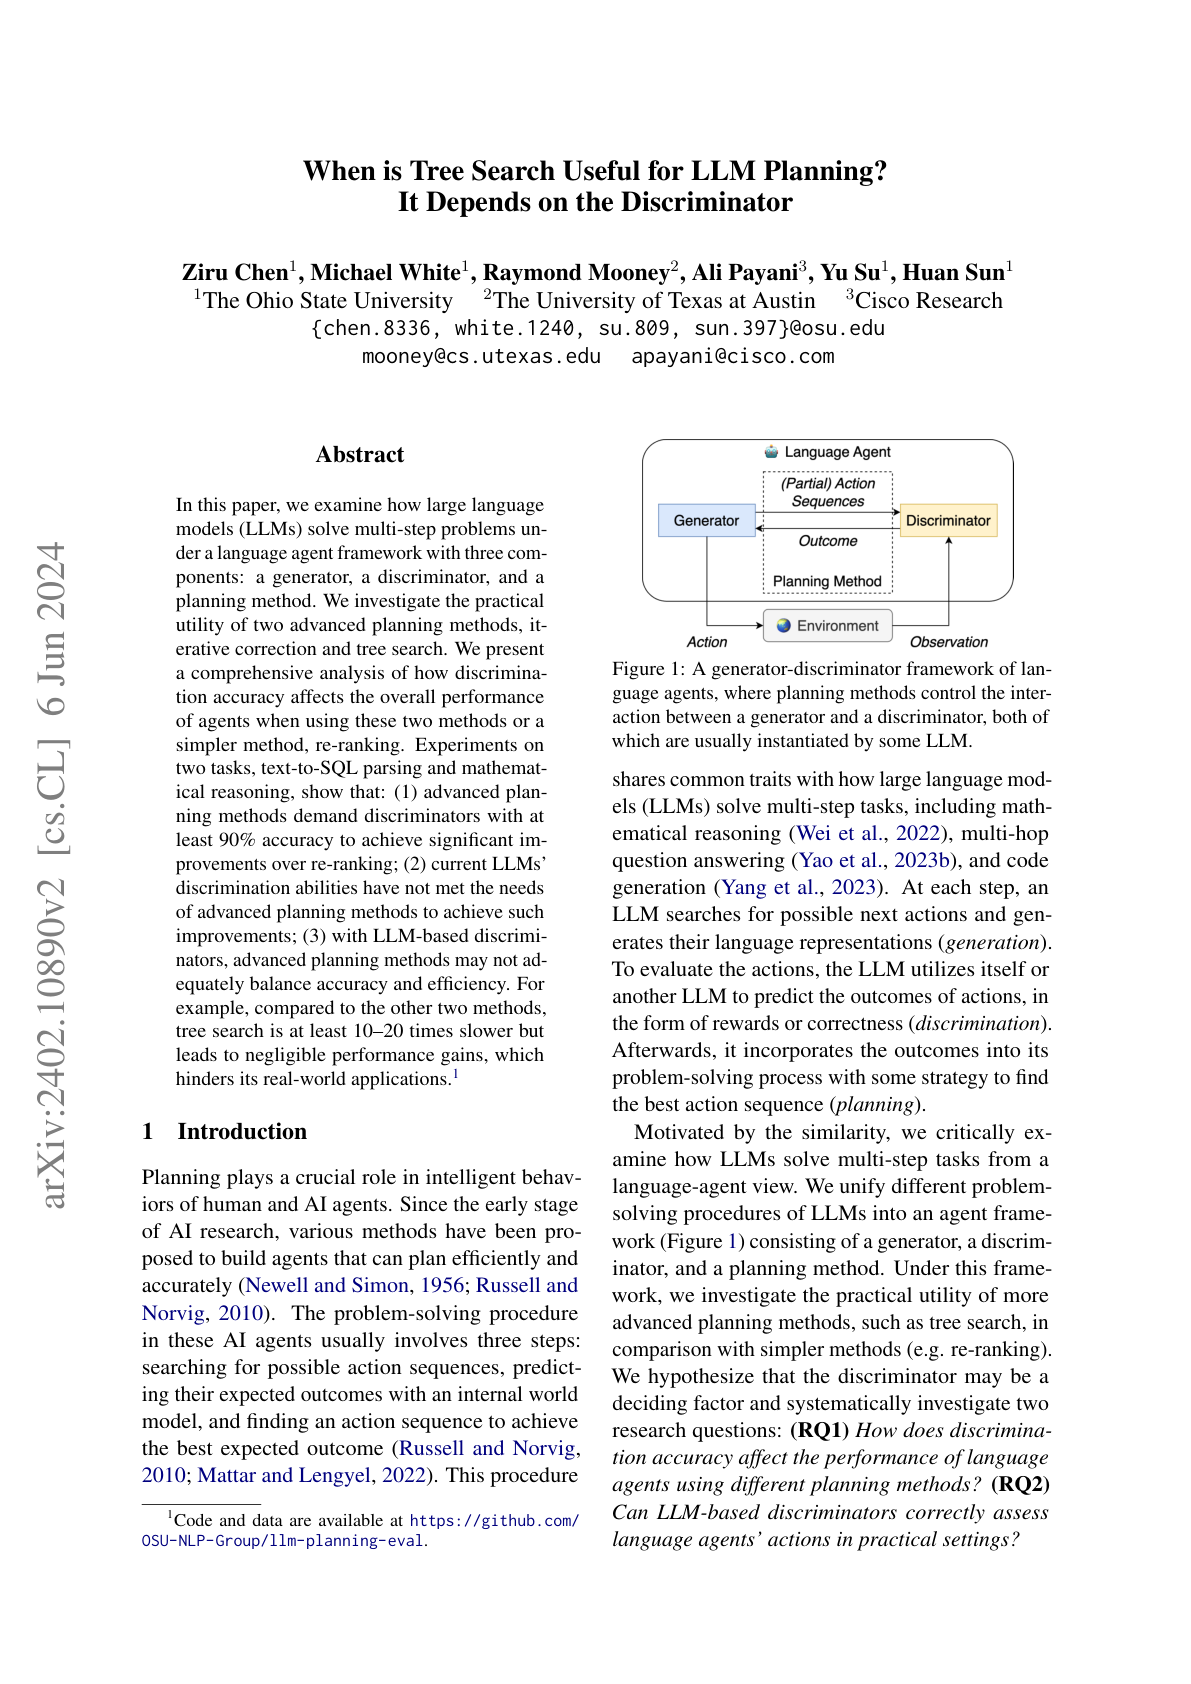
When is Tree Search Useful for LLM Planning?
Ohio State + OSU analyze multi-step LLM planning as a generator/discriminator/planner system and argue that current LLM discriminators make tree search a poor choice in practice.
Chain-of-Thought Reasoning Without Prompting
DeepMind shows that LLMs often *already* emit chain-of-thought reasoning in alternative decoding paths, and that selecting those paths via confidence lifts reasoning accuracy with no prompt engineering.
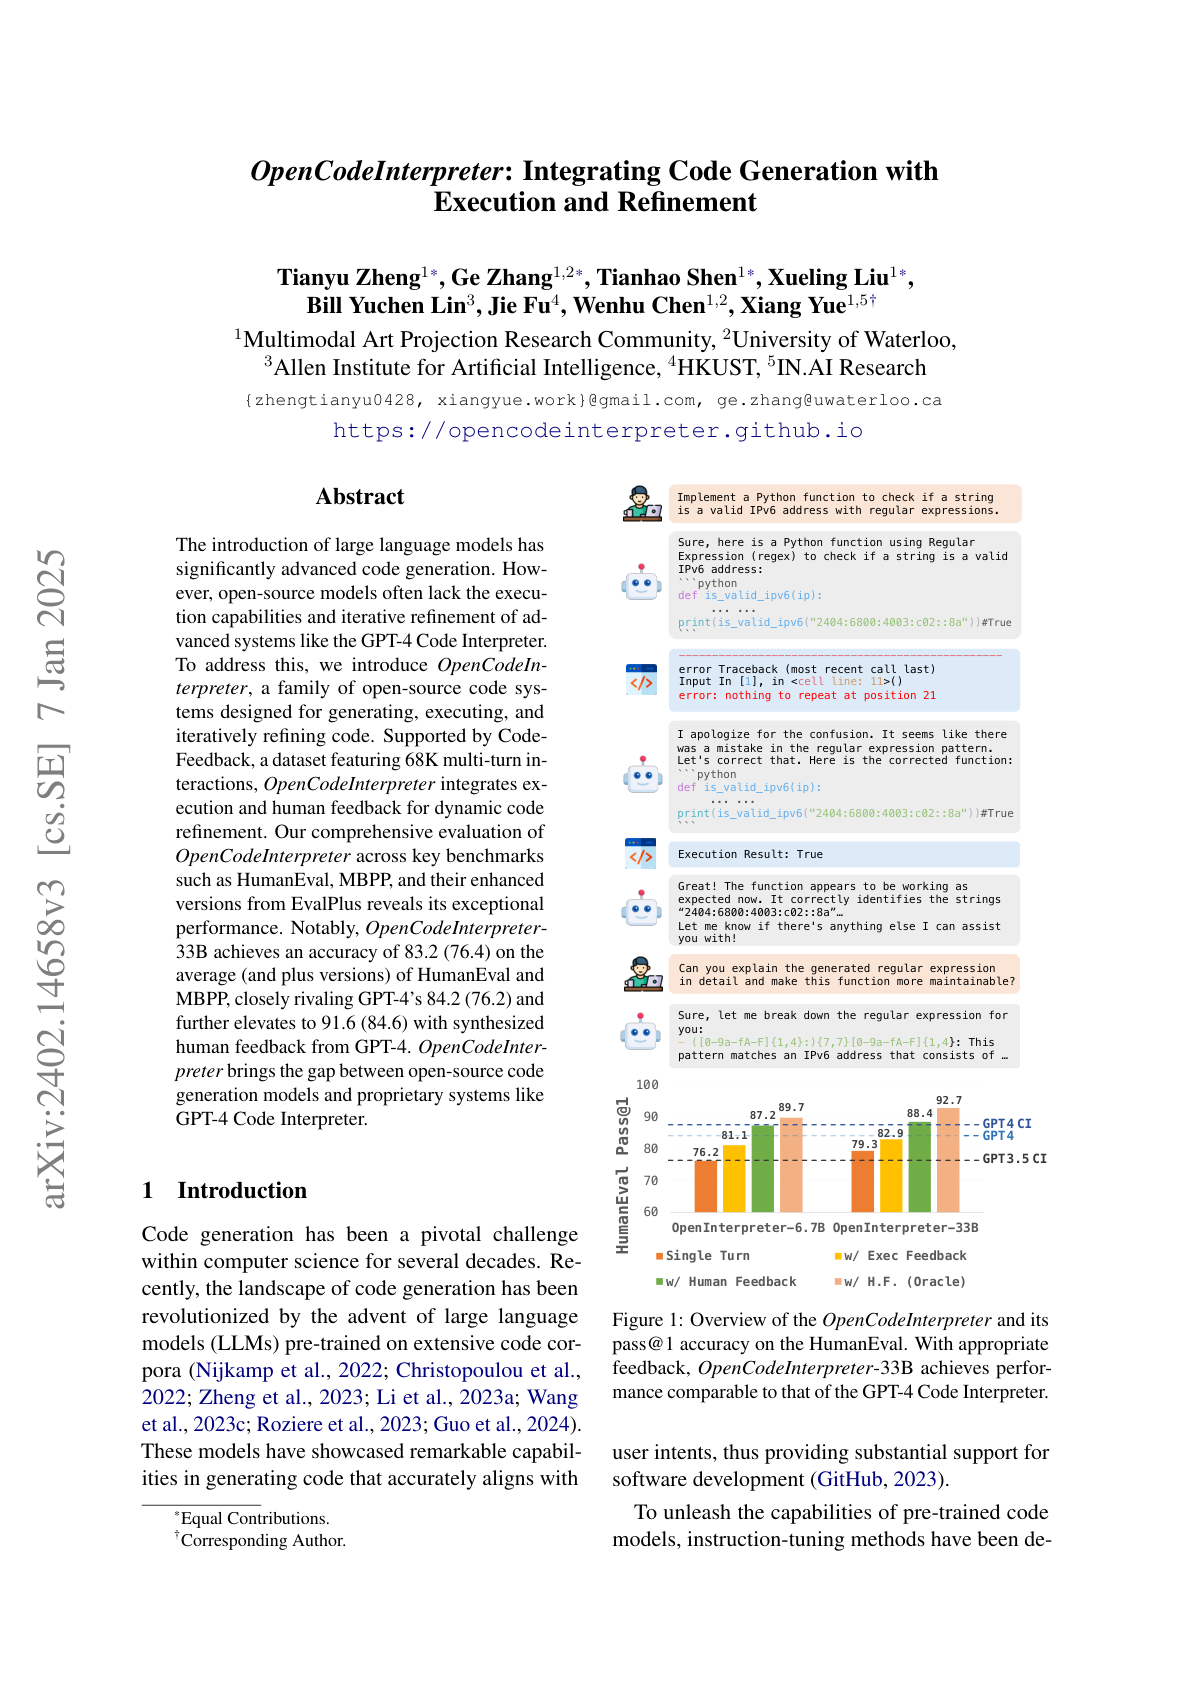
OpenCodeInterpreter
OpenCodeInterpreter is an open-source family of code-execution LLM systems that iteratively refine code using runtime feedback, closing the gap with GPT-4's proprietary Code Interpreter.
Sora
OpenAI unveils Sora, a text-to-video diffusion-transformer that generates coherent, minute-long 1080p videos from natural-language prompts.
Gemini 1.5
Google DeepMind's Gemini 1.5 is a multimodal MoE LLM that scales context to 1M tokens (10M in research settings) while matching or surpassing Gemini 1.0 Ultra on standard benchmarks.
V-JEPA
Meta's V-JEPA learns visual representations by predicting features in masked video regions, without pretrained image encoders, text, negatives, or reconstruction.
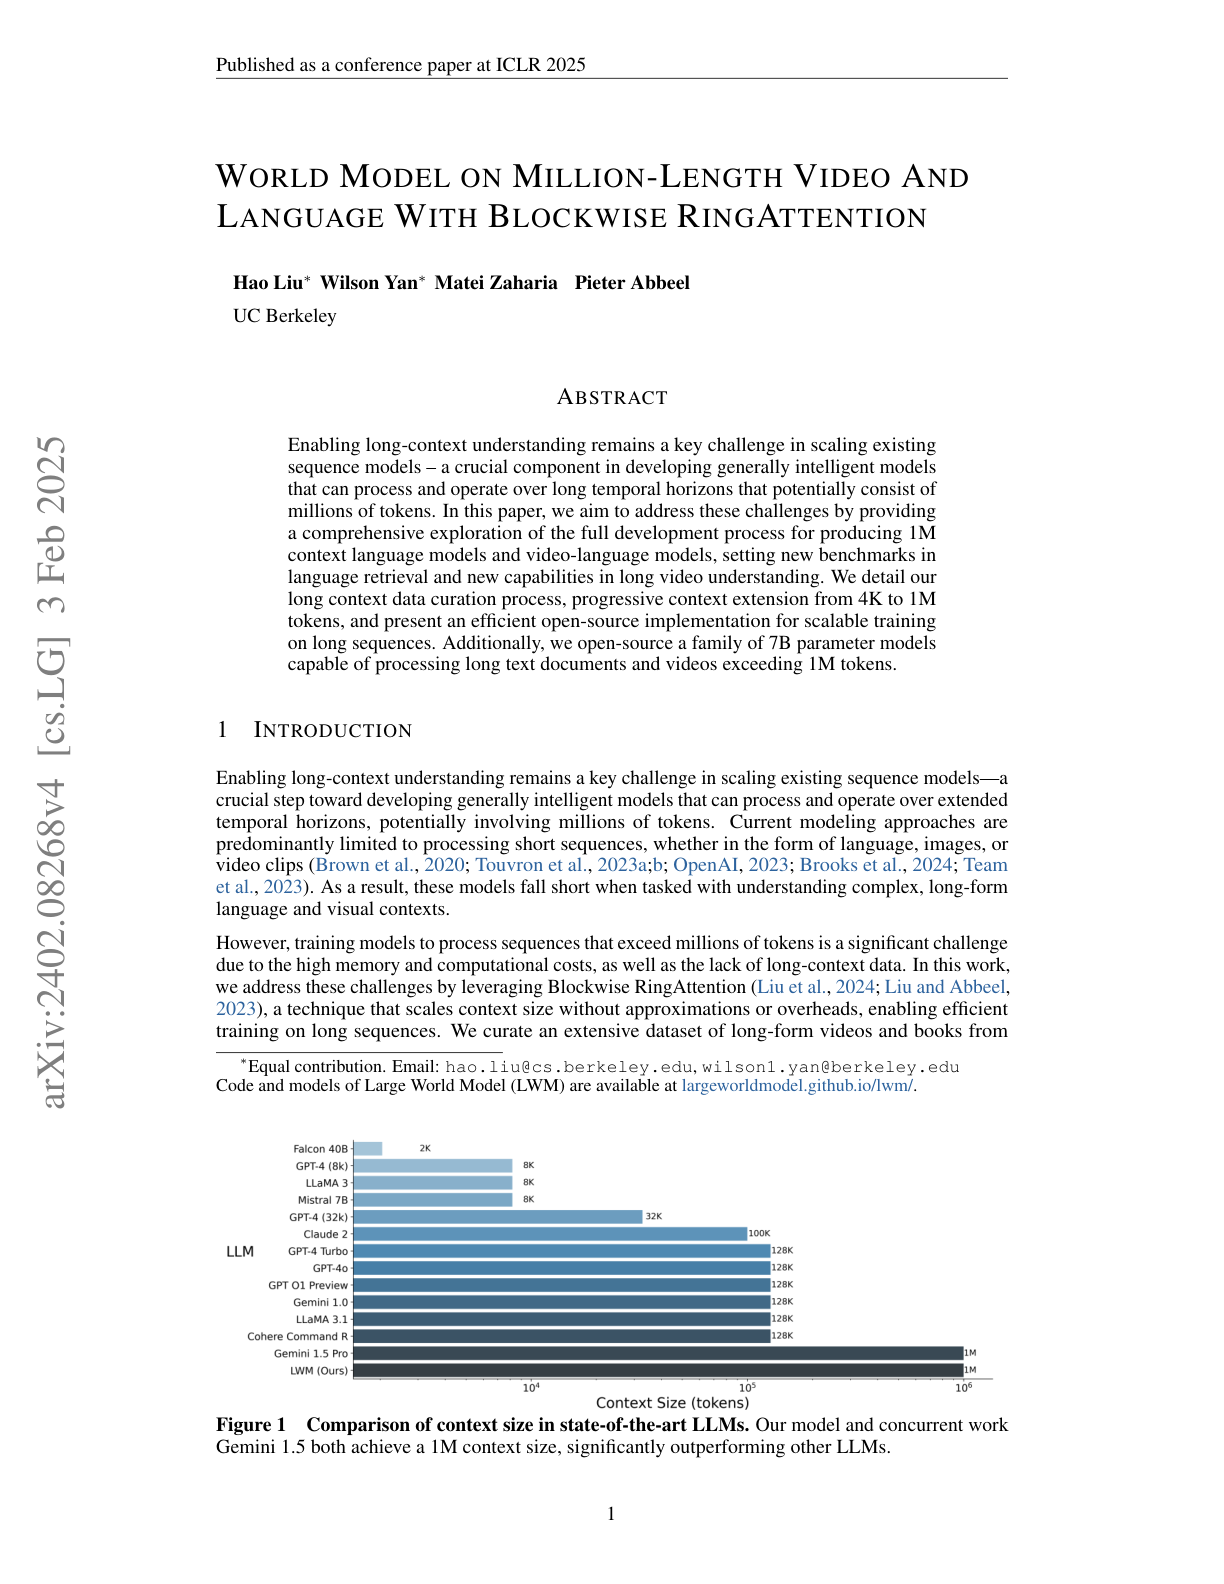
Large World Model (LWM)
UC Berkeley's LWM is an open 7B multimodal model trained on long videos and books that handles context windows up to 1M tokens via RingAttention.
The Boundary of Neural Network Trainability is Fractal
Sohl-Dickstein finds that the boundary between trainable and untrainable hyperparameter configurations looks like a Mandelbrot-style fractal across many architectures.
OS-Copilot
OS-Copilot is a framework for building generalist computer agents that use full OS primitives (browser, terminal, files, multimedia, third-party apps) rather than just web DOMs.
TestGen-LLM
Meta's TestGen-LLM uses LLMs to improve existing human-written tests - augmenting coverage rather than generating tests from scratch - while rigorously filtering LLM output for quality.
ChemLLM
ChemLLM is a chemistry-specialized LLM with a matched dataset (ChemData) and benchmark (ChemBench) for evaluating chemistry-specific capability.
Survey of LLMs
A survey that maps the landscape of the three dominant LLM families - GPT, Llama, and PaLM - and the shared toolbox used to build and augment them.
LLM Agents Can Autonomously Hack Websites
The paper shows GPT-4 agents with tool use and long context can autonomously exploit real websites, including performing blind SQL injection and schema extraction.
Grandmaster-Level Chess Without Search
DeepMind shows that a 270M-parameter transformer trained purely with supervised learning on Stockfish-generated data reaches grandmaster-level chess without any search at inference time.
AnyTool
AnyTool is a training-free LLM agent that scales tool-use to 16K+ Rapid APIs through a hierarchical retriever and a self-reflective solver.
Phase Transition in Dot-Product Attention
A theoretical paper that analyzes a solvable low-rank tied-QK attention model and uncovers a data-driven phase transition between positional and semantic attention regimes.
Indirect Reasoning with LLMs (DIR)
Direct-Indirect Reasoning augments standard CoT with contrapositive and proof-by-contradiction templates, giving LLMs an explicit way to attack problems they can't solve forward.
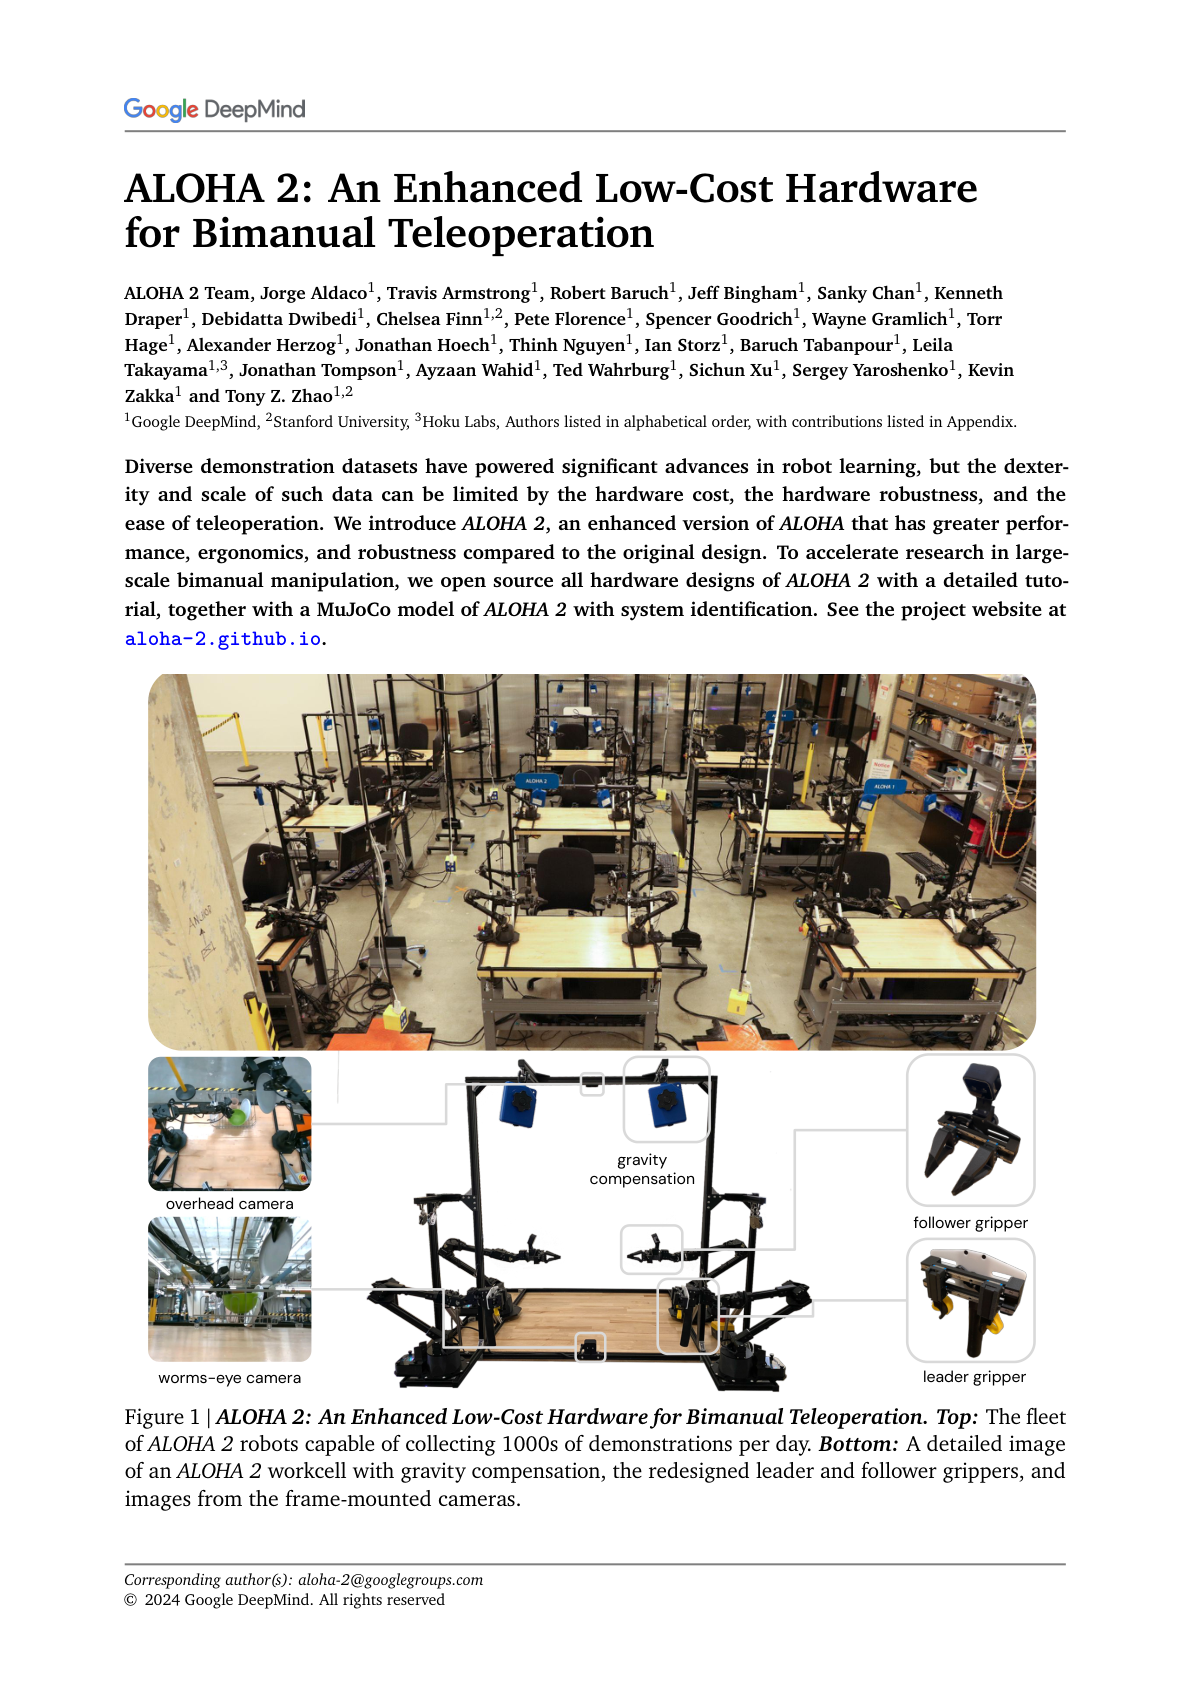
ALOHA 2
ALOHA 2 is a refreshed low-cost bimanual teleoperation platform from Stanford/DeepMind, designed for large-scale robot-learning data collection.
More Agents Is All You Need
The paper shows that simply running more independent LLM agents and voting produces reliable scaling gains across tasks, without any method changes.
Self-Discover
Google's Self-Discover lets LLMs compose their own task-specific reasoning strategies from a small library of atomic reasoning modules, at dramatically lower inference cost than self-consistency.