AI Papers of the Week
Every paper worth reading in AI, hand-picked one week at a time.
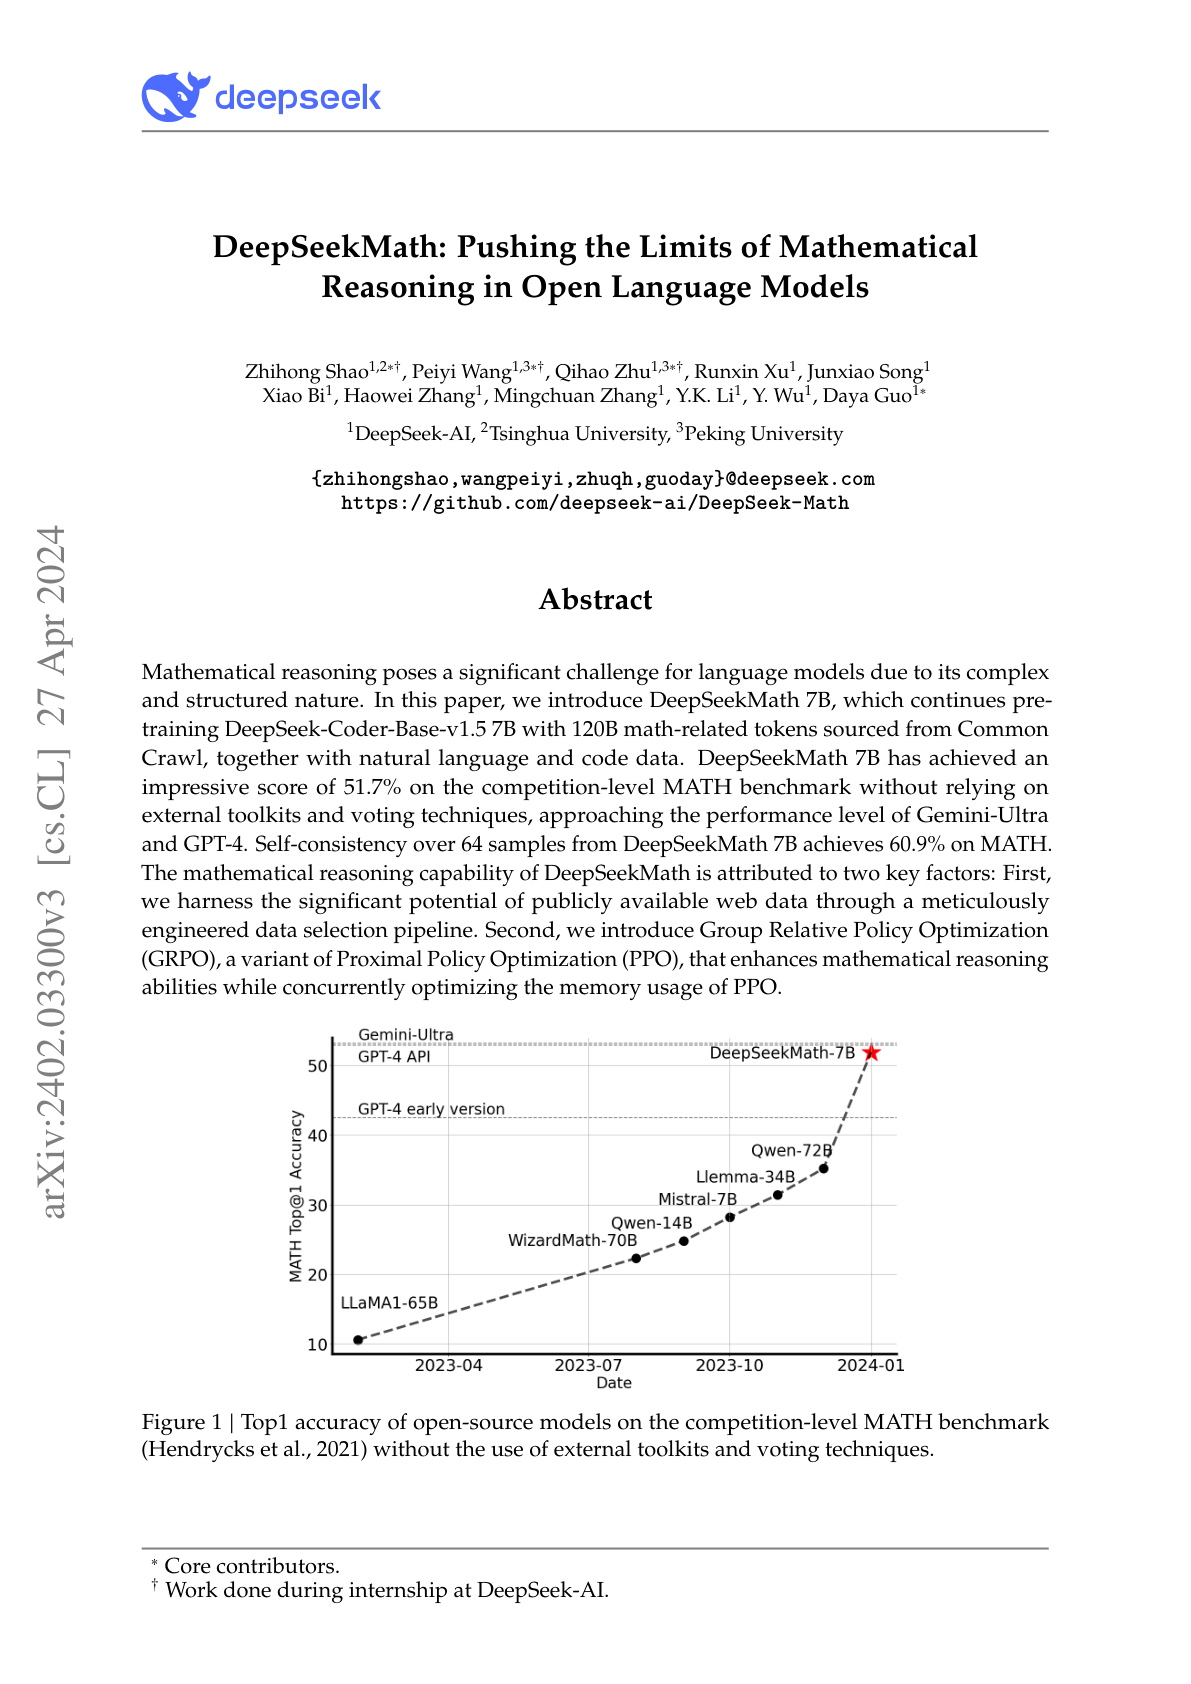
DeepSeekMath
DeepSeek releases DeepSeekMath 7B, a math-specialized LLM that closes much of the gap to GPT-4 and Gemini-Ultra on MATH by combining better data and a new RL objective.
LLMs for Table Processing: A Survey
A survey covering how LLMs and VLMs are used across the full spectrum of table-processing tasks, from classic TableQA to spreadsheet manipulation.
LLM-based Multi-Agent Systems Survey
A survey of the fast-growing LLM-based multi-agent systems space, covering both problem-solving applications and "world simulation" research.
OLMo
Allen AI releases OLMo, a truly open 7B-parameter LLM shipped with training code, pretraining data, full weights, evaluation tooling, and fine-tuning recipes - an answer to the "open-weights but closed-pipeline" releases dominating the space.
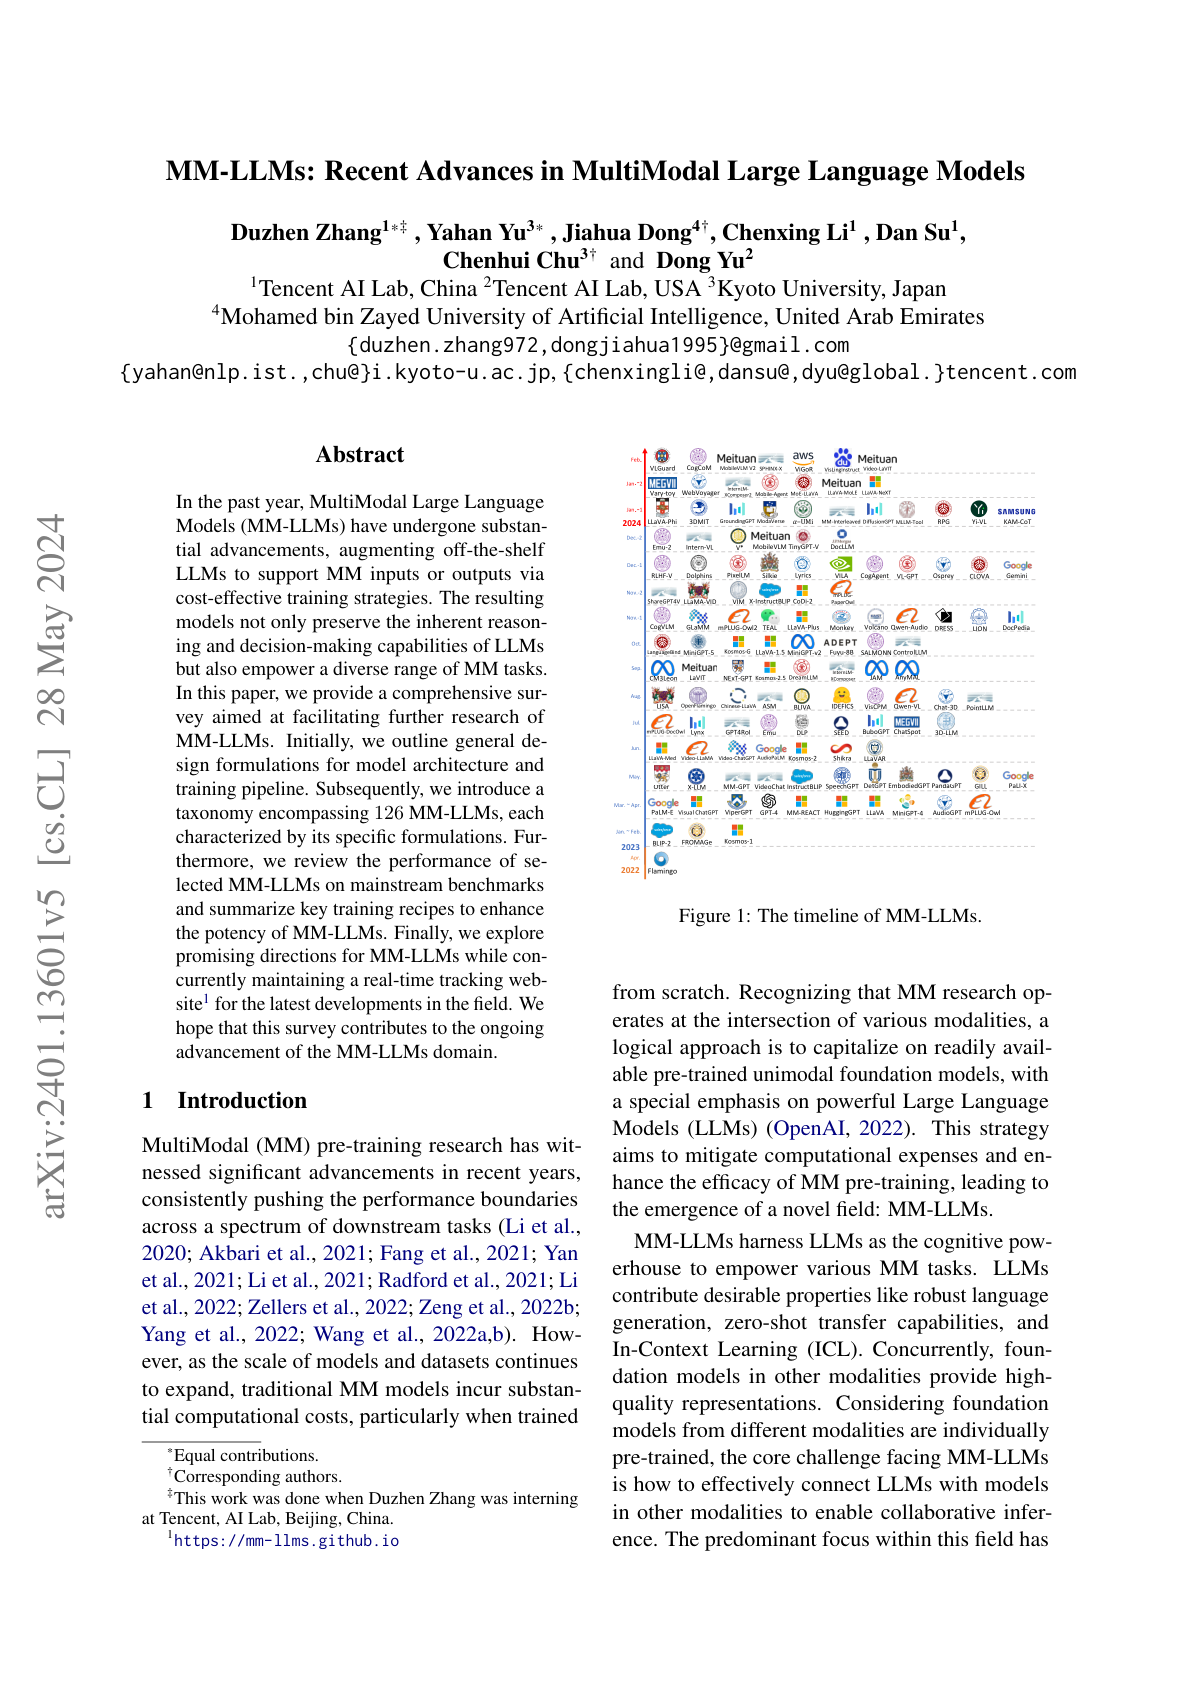
Advances in Multimodal LLMs
A comprehensive survey mapping design choices for architecture and training pipeline around multimodal large language models (MLLMs).
Corrective RAG (CRAG)
CRAG adds a self-correcting loop around retrieval so a RAG system can detect and repair bad retrievals instead of feeding them straight into generation.
LLMs for Mathematical Reasoning
A survey of the fast-growing literature on using LLMs for mathematical reasoning, from arithmetic word problems to theorem proving.
Compression Algorithms for LLMs
A survey covering the main families of LLM compression techniques and when each one is appropriate.
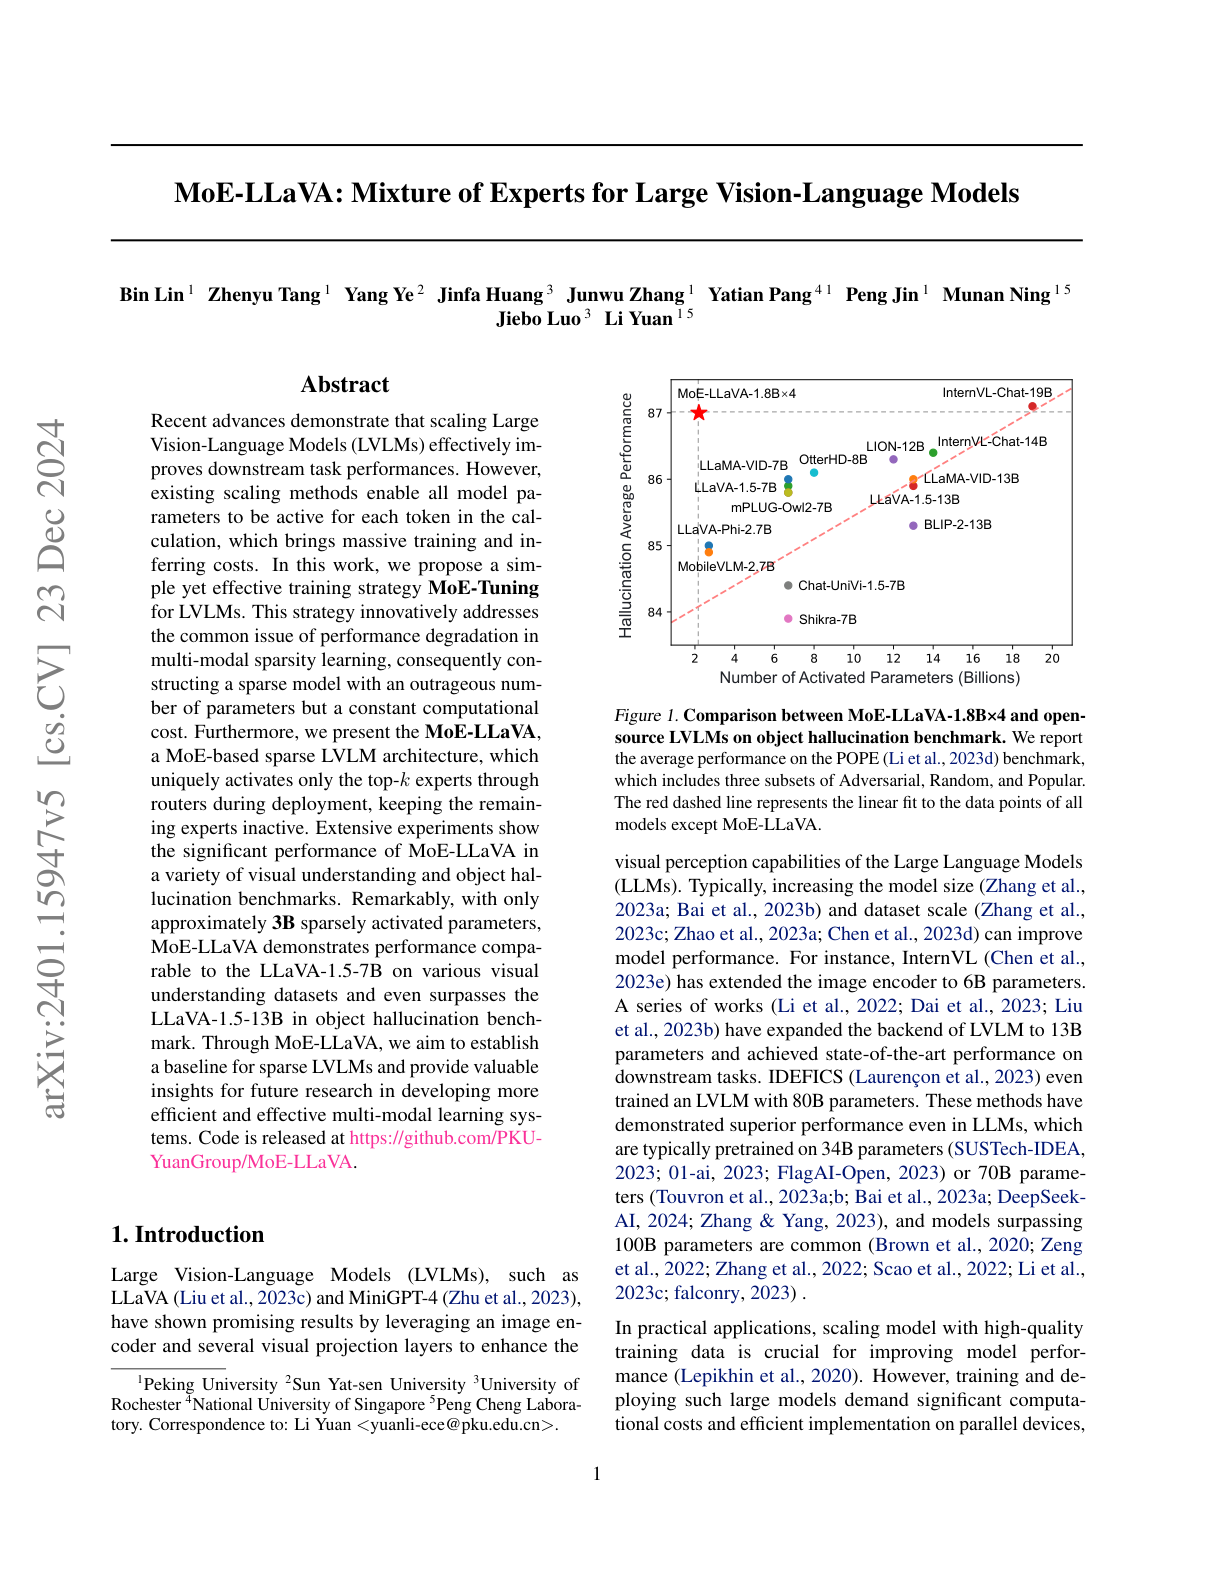
MoE-LLaVA
MoE-LLaVA applies Mixture-of-Experts tuning to the LLaVA vision-language architecture, getting a sparse model with dramatically fewer active parameters at the same compute cost.
Rephrasing the Web (WRAP)
WRAP uses an off-the-shelf instruction-tuned model to paraphrase web documents into styles like "Wikipedia" or "question-answer format" and trains on the mixture of real + synthetic rephrases.
The Power of Noise: Redefining Retrieval in RAG
A study stress-testing the retriever component of RAG systems with surprising results about what actually helps generation.
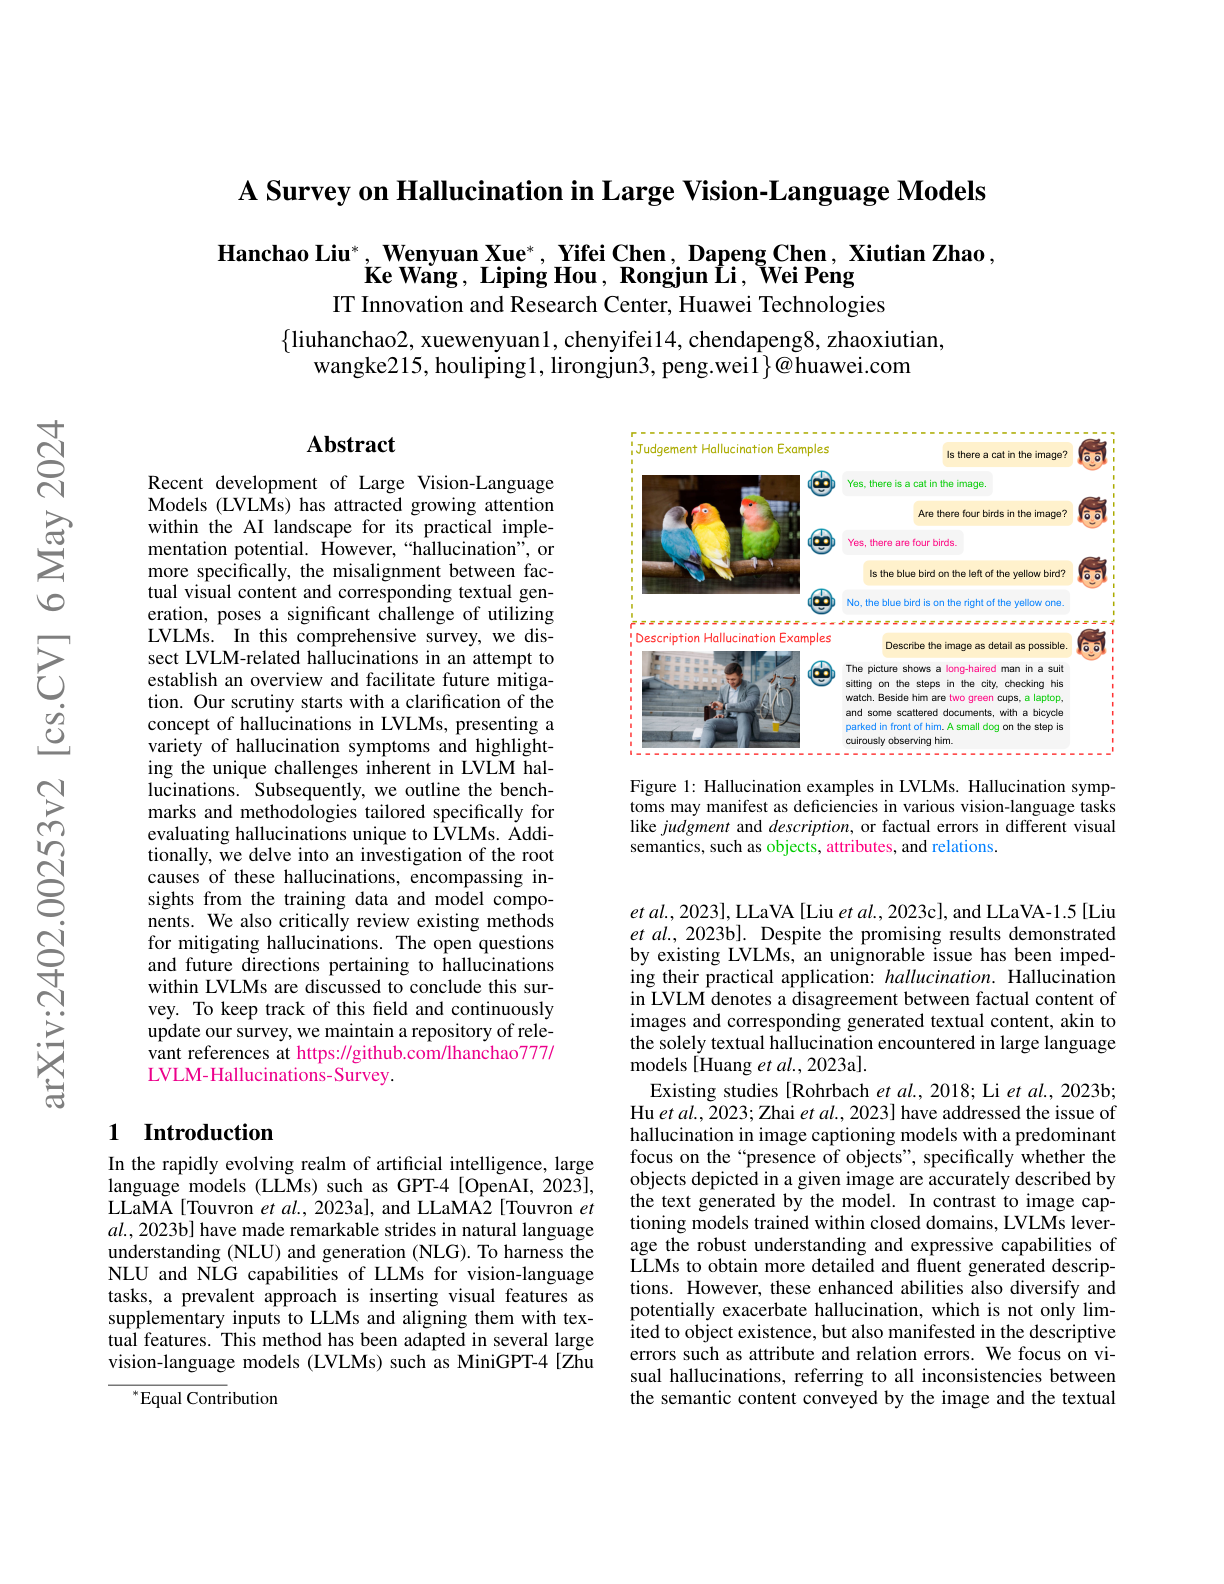
Hallucination in LVLMs
A survey specifically scoped to hallucination in Large Vision-Language Models, a phenomenon that differs substantially from text-only LLM hallucination.
SliceGPT
Microsoft's SliceGPT is a post-training LLM compression technique that literally slices rows and columns out of weight matrices while preserving zero-shot quality.
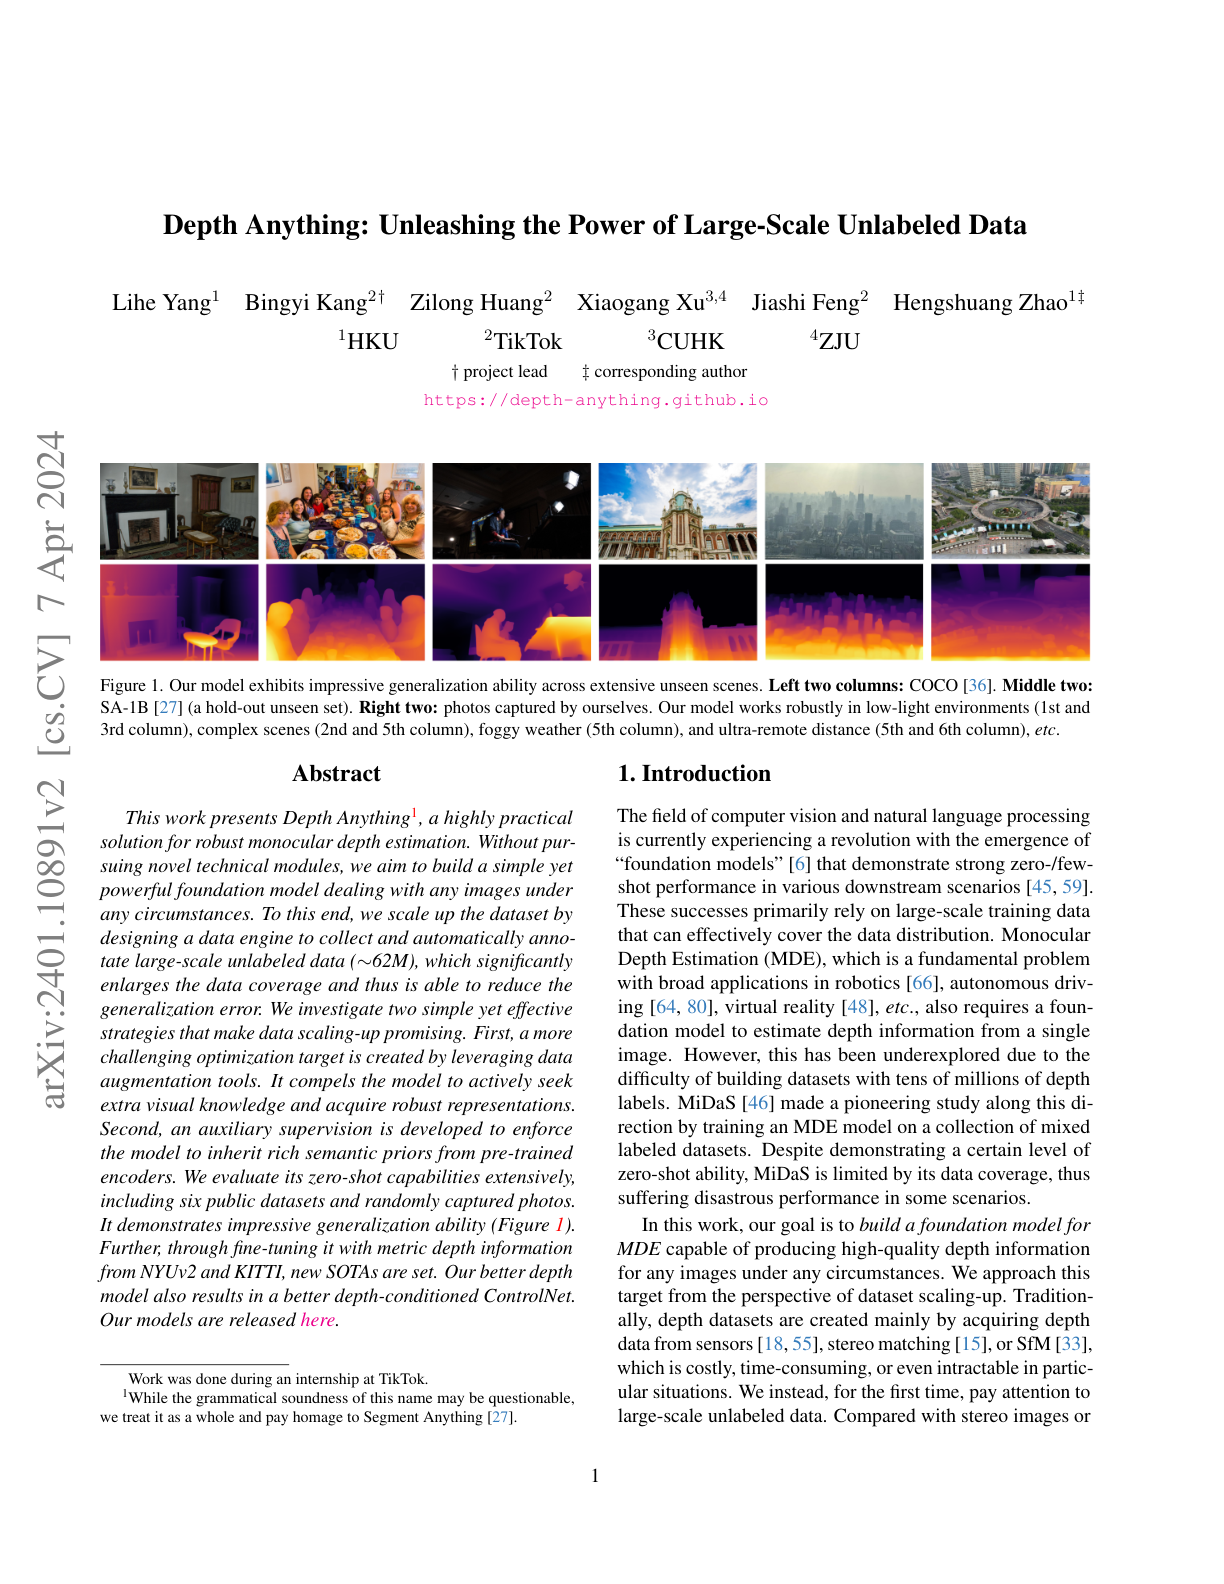
Depth Anything
A robust monocular depth estimator designed to handle "any image under any circumstance" by scaling self-training on unlabeled data rather than hunting for bigger labeled sets.
Knowledge Fusion of LLMs (FuseLLM)
FuseLLM proposes fusing the capabilities of multiple existing LLMs into a single target model by distilling their output distributions rather than retraining from scratch.
MambaByte
MambaByte adapts the Mamba state-space architecture to learn directly from raw bytes, bypassing tokenization and all its well-known failure modes.
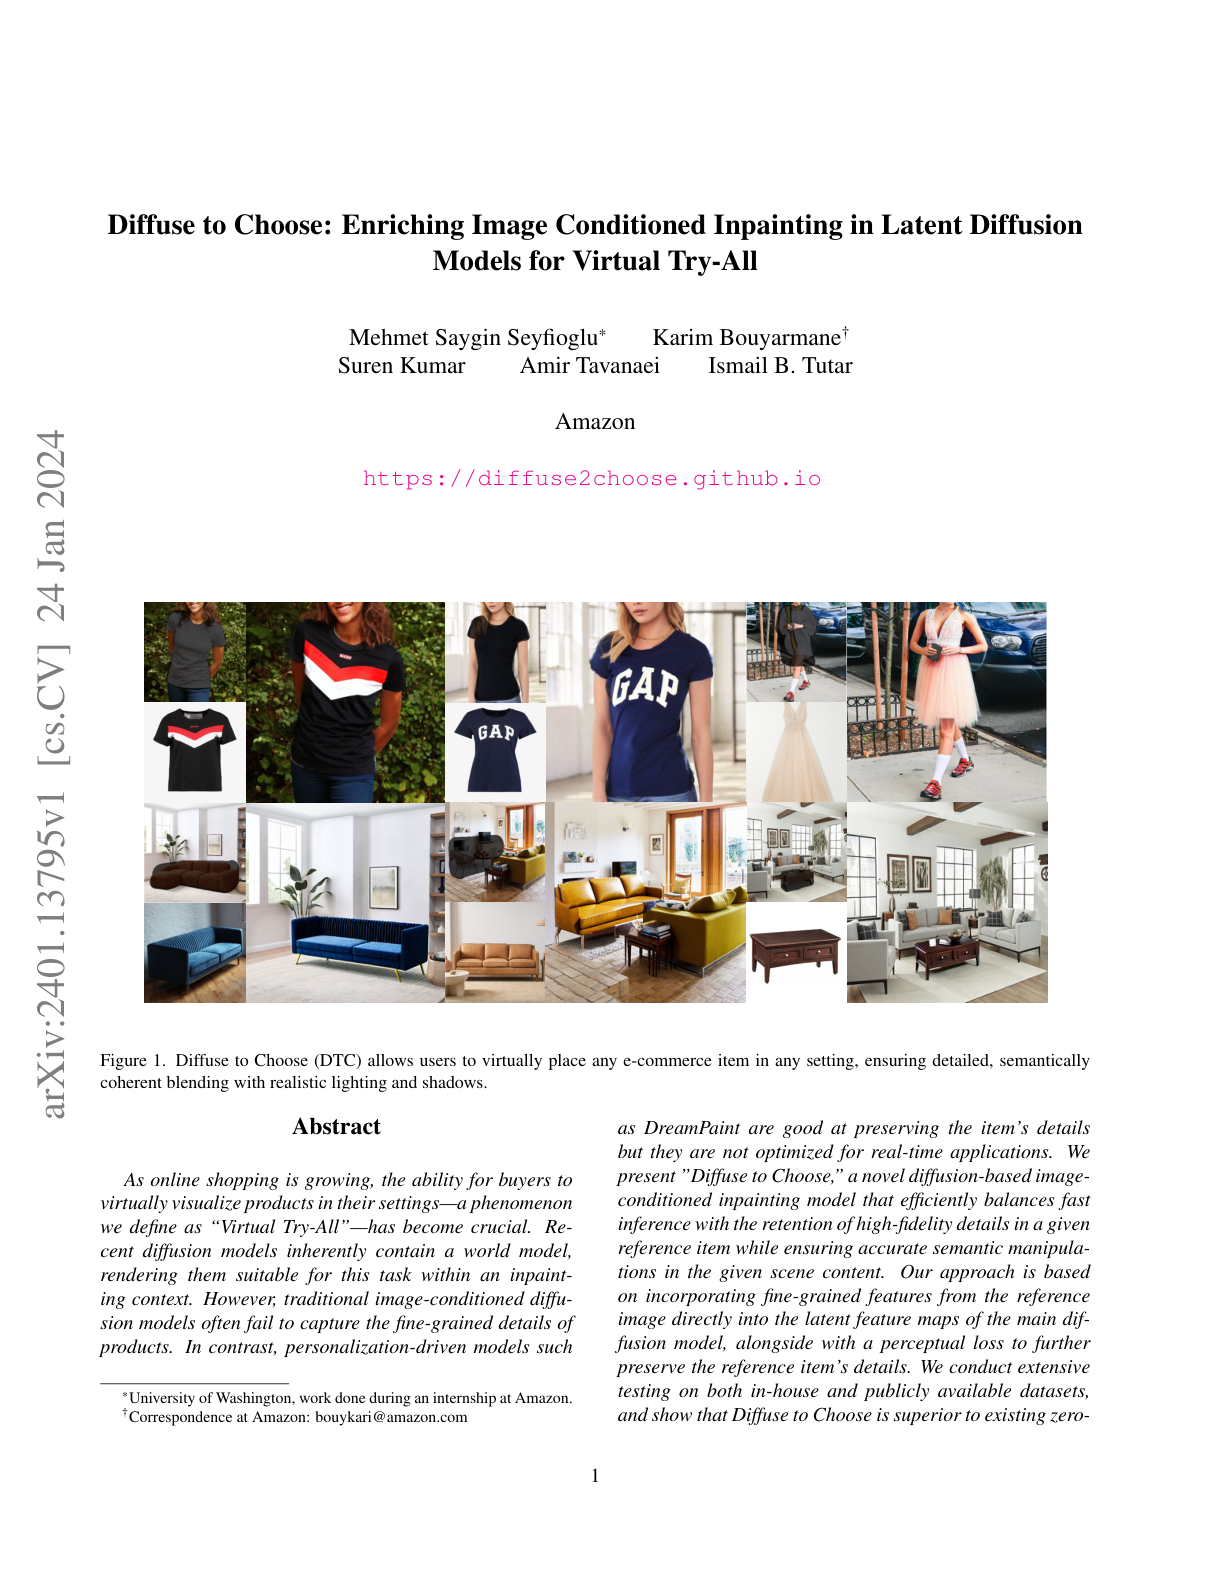
Diffuse to Choose
Amazon's Diffuse to Choose is a diffusion-based image-conditioned inpainting model built for "virtual try-on" scenarios where product images must be placed naturally into user scenes.
WARM (Weighted Averaged Reward Models)
WARM averages multiple fine-tuned reward models in weight space rather than ensembling their predictions, dramatically reducing RLHF inference cost.
Resource-efficient LLMs & Multimodal Foundation Models
A wide-ranging survey of efficiency techniques for LLMs and multimodal foundation models, spanning architecture, algorithms, and system design.
Red Teaming Visual Language Models
Introduces the first dedicated red-teaming benchmark for VLMs, covering vulnerabilities unique to multimodal inputs.
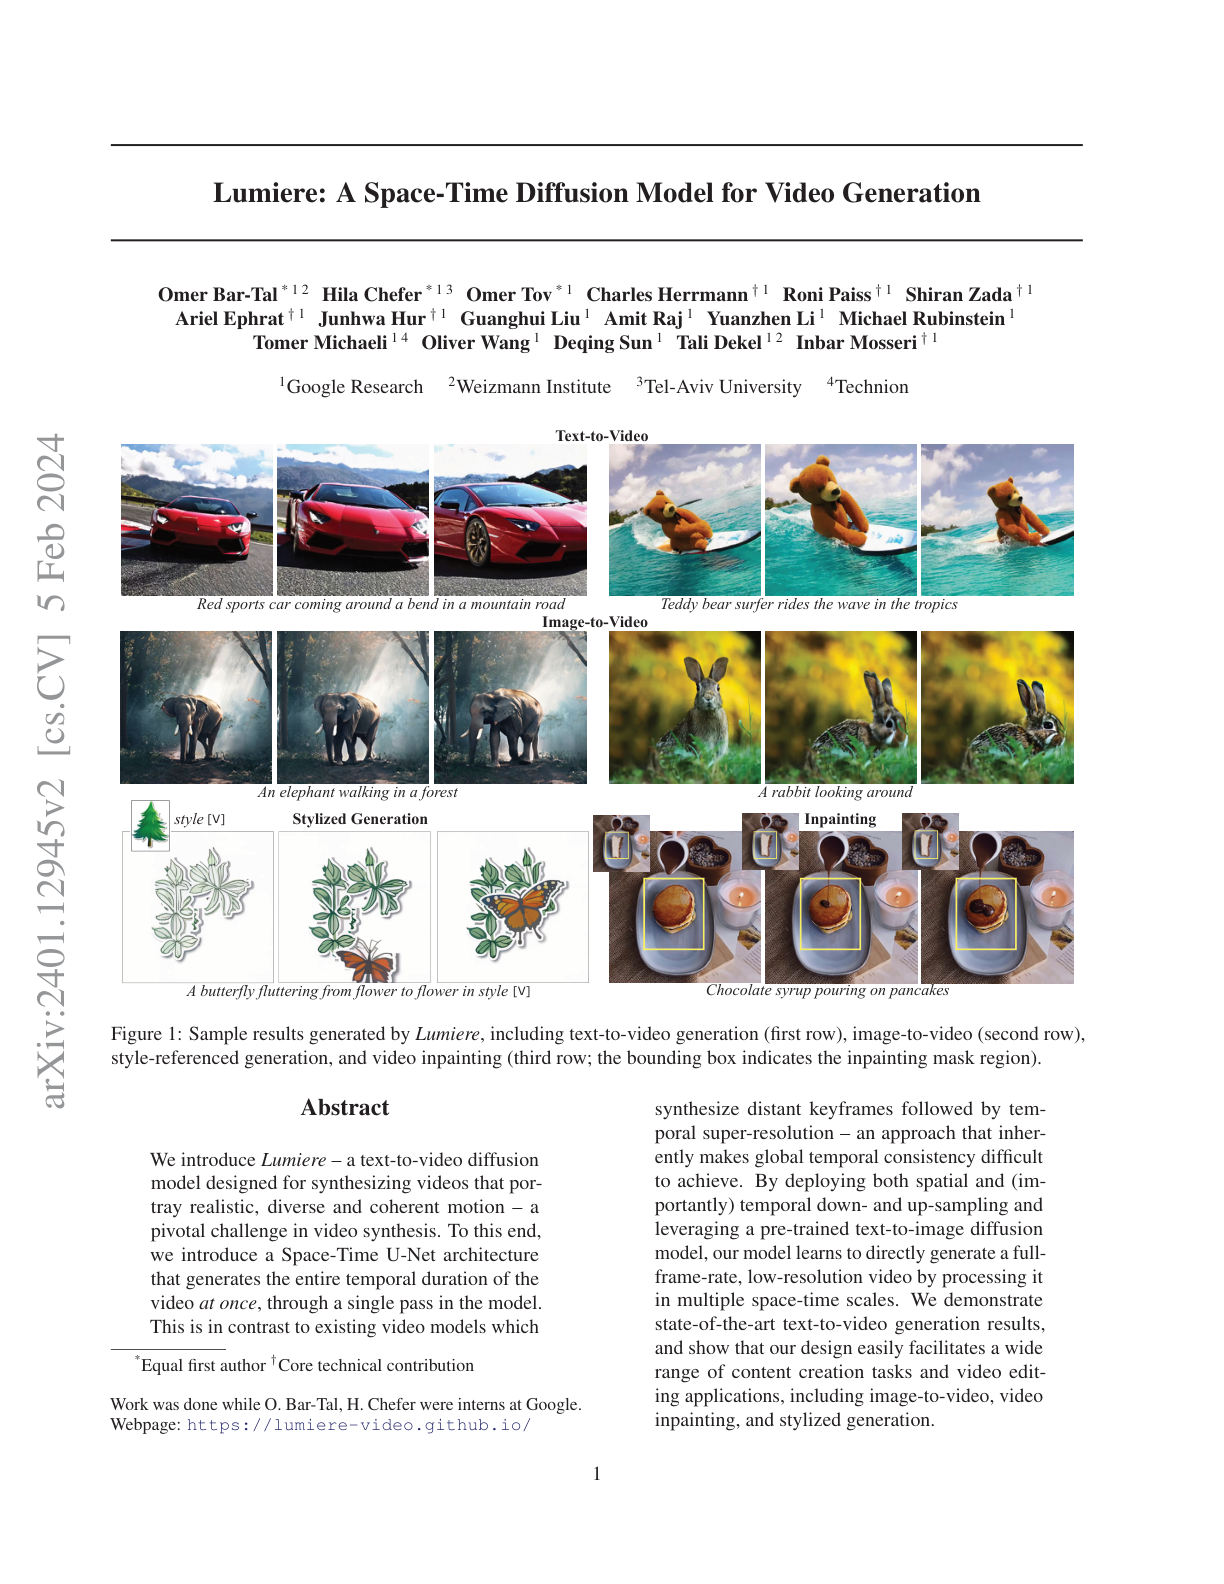
Lumiere
Google's Lumiere is a space-time diffusion model for text-to-video that generates the entire video duration in a single forward pass rather than cascading short clips.
Medusa
Medusa accelerates LLM inference by bolting on multiple decoding heads that predict several future tokens in parallel, dramatically reducing decoding steps.
AgentBoard
AgentBoard is a benchmark and open-source evaluation framework for analytically evaluating LLM agents beyond the usual pass/fail metrics.
AlphaGeometry
DeepMind's AlphaGeometry is a theorem prover that solves Olympiad-level geometry problems at near gold-medallist performance, and crucially, without needing any human demonstrations.